OpenAI and Anthropic lower their LLM costs by as much as 80% inside a number of months. Why?
Let’s take a look at a fast timeline of the main LLM mannequin bulletins from each OpenAI and Anthropic over the previous few months. All pricing numbers offered are enter MTok / output MTok / cache learn MTok.
June 26, 2026#
OpenAI announced GPT-5.6 Sol and Luna. Sol is the direct successor to GPT 5.5 on the identical worth of $5 / $30 / $0.50, whereas Luna is a small mannequin particularly designed for cheaper use circumstances at $1 / $6 / $0.10. They additionally introduced a Terra mannequin that’s in between these two fashions, however few cared about it.
June 30, 2026#
Anthropic announced Claude Sonnet 5, which Anthropic claimed to be nearer to their Opus fashions, however suggestions was blended. Notably, it had launch pricing of $2 / $10 / $0.20 which was initially imagined to be short-term however would go up.
July 24, 2026#
Anthropic announced Claude Opus 5, which was a long-awaited major-version replace given the impact Opus 4.5 had on the rise of agentic coding, at a worth of $5 / $25 / $0.50 (just like GPT-5.6 Sol). Although a number of the offered benchmark outcomes surprisingly exceeded these of the a lot bigger Fable 5, real-world suggestions was extra blended.
July 30, 2026#
OpenAI announces that they lower the value of GPT-5.6 Luna by 80% (???) to $0.20 / $1.20 / $0.02.
Model high quality vs. Cost-per-task for GPT-5.6 Luna after the huge worth discount. Top-and-left is healthier, and if OpenAI didn’t do the 80% worth lower, it might have misplaced to DeepSeek V4 Pro. by way of OpenAI
August 10, 2026#
Anthropic announces the short-term Sonnet 5 worth lower for the launch is now everlasting.
August 21, 2026#
OpenAI announces that they’re chopping the value for GPT-5.6 Sol by ~20% ($4 / $20 / $0.40) for the subsequent three months.
September 1, 2026#
Anthropic announced Fable 5.1 at a worth of $10 / $50 / $0.25, which, along with having strictly higher benchmark efficiency in all areas than Fable 5 from June at $10 / $50 / $1, lower the cache learn value by 75%.
When utilizing brokers for coding, cache learn prices are the overwhelming majority (96% – 99%) of the overall token expenditure because the cache is what incorporates all the earlier dialog every flip. Additionally, the cache tends to be hit round 90 – 100% of the time (varies by the development projects of the LLM inference supplier). Taken collectively, a 75% discount within the cache learn value correlates to a 70-75% discount in the price of utilizing the mannequin—clearly notable, even when cache prices are sometimes a footnote!
September 3, 2026#
OpenAI announced GPT-6 Astra, which has similarities in measurement to Fable 5.1 and has related pricing at $10 / $50 / $1 however with out the decrease cache learn value. Astra’s mannequin efficiency is certainly akin to Fable.
September 22, 2026#
OpenAI announced GPT-6 Sol at at a surprising worth of $2 / $10 / $0.20 that halves the enter and output worth relative to the temporarily-discounted GPT-5.6 Sol! They concurrently launched GPT-6 Luna additionally at half the enter and output worth ($0.10 / $0.50 / $0.01) of the earlier model.
On the identical precise day, Anthropic announced Claude Opus 5.5, the place it’s explicitly acknowledged “Opus 5.5 requires much less compute to serve than Opus 5, and its pricing displays that”. Its worth of $4 / $20 / $0.20 is far decrease in whole than Opus 5’s because of a 20% enter/output value lower and a bigger cache learn lower, leading to a complete value discount of 40-60% for a mannequin that’s even higher than Fable 5.1 (I’ve various issues to say about Opus 5.5, however that’s for an additional submit).
September 29, 2026#
It turned out that GPT-6 Sol was a dud performancewise, so per week later OpenAI announced GPT-6.1 Sol, which surprisingly has comparable efficiency to Astra (can verify after private use), however OpenAI casually lower the cache worth in half ($2 / $10 / $0.10) matching Anthropic’s 5%-of-input cache learn value, making this mannequin household cumulatively 75% cheaper.
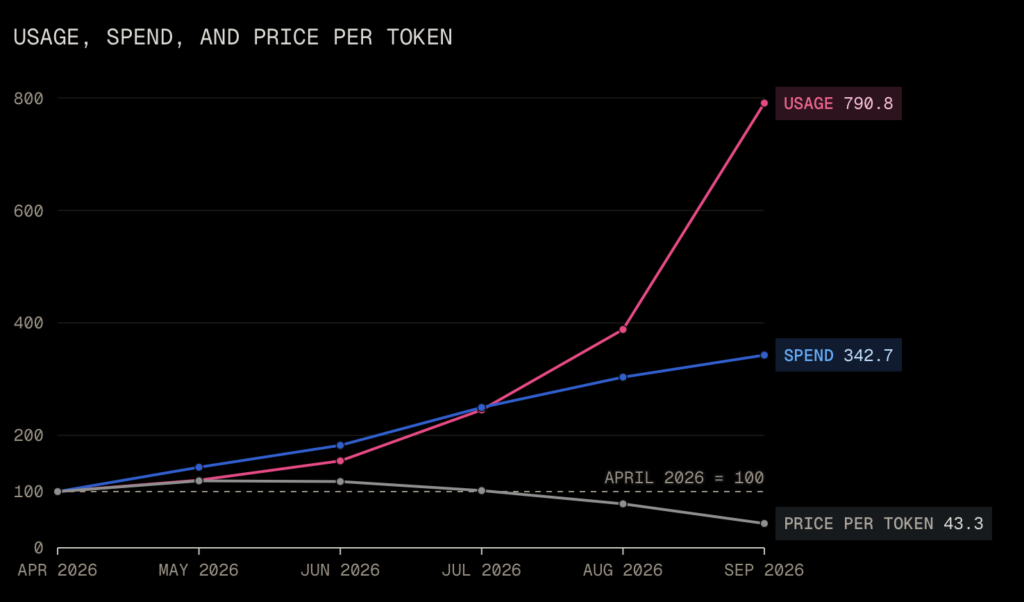
Overall, ranging from the discharge of the GPT-5.6 mannequin households in June to now, the price of utilizing these well-liked LLMs has cratered, which isn’t one thing I might have anticipated a 12 months in the past. These worth cuts additionally apply to mannequin utilization from subscription agentic harnesses resembling Codex and Claude Code. More importantly, these fashions don’t seem to have lower any corners by way of output high quality to realize their worth cuts.

Data from Vercel’s AI mannequin gateway supporting the lowering cost-per-token development to 43.3% of the April 2026 value. However, combination spend has been rising as a result of the fashions are getting higher quicker than they’re getting cheaper! via Vercel
From the timeline above, there’s a clear tit-for-tat between Anthropic and OpenAI, and it’s cheap to imagine that these specific worth cuts from OpenAI and Anthropic are in response to one another. However, nobody cuts costs by 80% except there’s some externality in play. So, what provides?
The Behavioral Economics of LLMs and Competitor Pricing Pressure#
If you have got been testing brokers with new LLMs as they’re launched, it may be very troublesome to distinguish them outdoors of subjective vibes. Since final November that launched the hypergrowth of agentic LLMs, fashions have turn out to be extra of a commodity the place it’s trivial to attempt a brand new mannequin in your codebase with only a toggle in a harness like OpenCode and Zed Agent, or a distinct API endpoint string by way of OpenRouter, and in consequence there’s little moat. Additionally, there are many rivals—not simply massive corporations like Google and Meta—who can present fashions that are sufficient substitutes and subsequently permit pricing stress.
For open weight fashions, let’s take one other take a look at DeepSeek Flash V4.1, which additionally just lately launched an updated 1017 variant.

OpenRouter at this level is the place you go for open-weight fashions. Retrieved October twenty fourth, 2026.
The unique DeepSeek V4 Flash 0420 was released in April 2026 at a worth of $0.14 / $0.28 / $0.0028 and went megaviral in consequence, particularly as OpenAI didn’t have a small-class mannequin for easy duties on the time. That $0.0028 turned out to be the important thing, as a cache learn proportion of two% is considerably decrease than the 5%-10% of the OpenAI and Anthropic fashions above, which makes the efficient value even decrease than what’s marketed. I think the 80% GPT-5.6 Luna worth lower in July was meant to particularly compete with these smaller open-weight fashions. Now, the brand new DeepSeek Flash V4.1 1017 mannequin performs considerably higher than DeepSeek Flash V4 benchmark-wise (45 on the Artificial Analysis index vs. 24) and the price from DeepSeek stays related at $0.15 / $0.60 / $0.003. Note the operative phrases “from DeepSeek”.
On OpenRouter, any inference supplier can record a mannequin that they host, and when a consumer hits the OpenRouter API, the request is routed to a kind of fashions—it’s routed to any obtainable mannequin by default for load balancing however the developer can specify preferences resembling “lowest worth” within the API request. Back in May, I noted that there have been 13 distinct suppliers internet hosting DeepSeek V4 Flash on OpenRouter. For the up to date 1017 variant, there at the moment are 29 distinct providers.

Providers for DeepSeek V4.1 Flash 1017 sorted by cache learn value. Retrieved October twenty fourth, 2026.
However, trying on the efficient enter prices (which account for the interplay between cache learn prices and cache hit charges), many distinct suppliers are shut costwise.

Effective prices by endpoint, with Cloudflare and DeepInfra inside 10% of DeepSeek’s value. Despite the truth that these fashions are the most affordable, word that these fashions solely have a minority of the overall token share. Retrieved October twenty fourth, 2026.
OpenAI and Anthropic must differentiate from these open weight fashions with higher-quality fashions—they’re at the moment doing a superb job with that significantly with Opus 5.5—however they should preserve doing that, which is why billions of {dollars} are being invested into R&D. Open-weight fashions are catching up quick: just some days in the past, Moonshot AI introduced Kimi K3.1 Pro which has comparable efficiency to Opus 5.5 (Kimi at 55 vs. Opus 5.5 at 58) at half the enter/output worth and the identical cache learn value ($2 / $10 / $0.20). It’s the identical measurement and structure as Kimi K3 which is at the moment being hosted by over 20 distinct inference suppliers: as soon as the weights drop on November 4th, you may subsequently anticipate most of them to assist the brand new Kimi K3.1 Pro mannequin at a roughly equal worth. Notably, Moonshot AI itself is becoming a member of the value lower enjoyable and priced Kimi K3.1 Pro at lower than the unique Kimi K3 ($3 / $15 / $0.30).
One recurring development amongst vocal AI detractors is that the value of tokens has been saved artificially low to hook folks into the LLM ecosystem, however then the costs will improve to “the true value of a token” and the AI boosters will likely be screwed as soon as the free trip ends. The concept is that OpenAI and Anthropic are loss-leading similar to what Uber and Lyft did to the ridesharing industry in the 2010s, however in contrast to then, OpenAI and Anthropic should not a duopoly who’ve the only energy to set costs within the ecosystem and the barrier to entry for the inference trade shouldn’t be as excessive. As lengthy as these many inference suppliers can proceed to serve fashions at the same worth and the same high quality to what OpenAI and Anthropic can present, and switching value is negligible, then the costs could proceed to lower extra. It’s no shock each corporations try to construct moats to defend in opposition to this development, resembling a deal with enterprise commitments
and private agentic assistants like OpenAI Dots and Claude Duet.
The concept that token costs will abruptly rise is extra a fantasy that isn’t supported by each behavioral economics and the precise traits of LLM costs taking place considerably over the previous few months for higher fashions, and never simply from OpenAI and Anthropic. As lengthy as scalers can worth at a cost-per-token decrease than the revenue-per-token, then these inference suppliers will scale back token prices to compete with one another to some extent that OpenAI/Anthropic must decrease their costs to compete too. The 29 distinct suppliers on OpenRouter have little incentive to serve an unprofitable mannequin (they might simply cease serving it and use the compute capability for a worthwhile mannequin as a substitute) and “the true value of a token” could find yourself being the place worth equals marginal value.
On that word, each OpenAI and Anthropic are certainly near IPOing, which raises additional questions in regards to the worth cuts.
IPO Pumping#
The timing of those worth cuts is notable as a result of each OpenAI and Anthropic are rumored to be IPOing quickly—OpenAI in 2027, and Anthropic within a couple months. So far, leaked financials from each OpenAI and Anthropic
present unsurprisingly that they’re dropping billions because of R&D/scaling, albeit in each circumstances these reviews don’t account for the hyperexpansion of agentic LLM use over the previous few months. Investors will scrutinize the huge unfavourable income and demand that they’ve a plan to show issues again round.
So, why did they lower their main income supply by as much as 80%? That’s the reverse of what you’d need to do to look good on an S-1 prospectus! The revenue margins on inference themselves probably inform a distinct story, with some reviews saying the profit-per-token margins are as healthy as 80% with caveats. How a lot of a revenue margin have they got after these main cuts?
Speaking personally, the value cuts have certainly affected how I spend on LLM brokers, however not in the best way I anticipate OpenAI/Anthropic need their typical buyer to behave. I used to have a $100/month subscription to Codex (the 5x Pro plan) when GPT-5.6 Sol was the highest mannequin, and I managed to only absolutely exhaust all of the utilization included within the subscription regardless of getting irritated with random usage resets. Once GPT-6.1 Sol launched and I observed that the price of utilizing it was successfully lower by 75%, you already know what I did?

I lower the max utilization quota to 1/fifth after getting 4x extra environment friendly utilization of the identical mannequin, so it finally ends up roughly impartial and the plain selection.
In equity, the revenue margins for subscriptions resembling Claude Code and Codex are unsure given their immense worth relative to the API utilization, and if there are capital crunches I think subscription worth will likely be lower earlier than the bottom worth of the fashions. For instance, on the identical time GPT-6.1 Sol was introduced, OpenAI cut the usage allowance by 50% for the $200/month tier in Codex below the argument “to replicate our more and more environment friendly fashions”—which is technically appropriate however it’s humorous to place in writing.
I will likely be very curious to see the Anthropic IPO prospectus and the inference revenue margins as soon as it turns into public quickly.
I additionally query whether or not it’s good for OpenAI/Anthropic in the event that they deliberately out of date their costlier fashions. After Opus 5.5 launched a month in the past, there hasn’t been any dialogue about both Fable 5.1 or GPT-6 Astra as a result of Opus 5.5 is simply that good.

Top-and-left. via Anthropic
I absolutely anticipate a Fable 5.2/GPT-6.1 Astra to launch in a pair weeks and show me improper, and I will likely be very curious to see how will probably be priced.
Another less-cynical issue that might clarify the value cuts is that LLM development projects has improved over the previous few months—when Anthropic stated “Opus 5.5 requires much less compute to serve than Opus 5, and its pricing displays that,” I consider it. One consequence that might be genuinely ironic is that if these fashions are extra compute environment friendly, it reduces the necessity for these huge information middle buildouts, which may trigger cascading financial failures. However, that probably received’t occur since inference is just one a part of the compute combine and people information facilities are nonetheless wanted for different components of the pipeline.
Overall, the value lower is bizarre, however as a consumer I’m definitely not complaining! Open-weight fashions and secondary inference suppliers will proceed to function an financial test on the costs of LLMs and different industry shenanigans the massive labs could concoct. Even if Anthropic’s and OpenAI’s IPOs are catastrophic and trigger each corporations to fold, it won’t abruptly trigger LLMs and brokers as an trade to die.