The State of Context Engineering
The Job is Knowing When to Be Deterministic & When to Be Probabilistic
This week, I gave a brief speak at AGNTCon titled, “Context Fails & Fixes,” that functioned as a kind of “State of Context Engineering.” How did context engineering emerge, the place has it gone, and the place may it go sooner or later? As mannequin makers goal new capabilities, they inadvertently create challenges we, as customers and harness builders, should overcome.
Below are the slides and a evenly edited transcript. As all the time, shoot me a note with any feedback, thoughts, or questions. I actually respect it.
Hi, everybody. Thanks for becoming a member of me right this moment. We’re going to stroll via context fails and fixes.
I’ve a e-book popping out in a bit, The Context Engineering Handbook. When I first talked to the staff at O’Reilly, again in June 2025, they requested me a really affordable query: “How do we all know this gained’t develop into out of date in just a few weeks?” The hassle with AI textbooks is that many age terribly rapidly.
I mentioned, I don’t know, however I’m optimistic. Giving clear directions about what to do and what to not do, and making certain these directions are constant and never noisy, will endlessly be a problem with AI, irrespective of how good it will get.
We have coworkers, companions, and different individuals we all know and work together with who are sentient. They go the Turing check, they’re “AGI,” and but: we nonetheless have a tough time conveying directions, concepts, and ideas amongst one another.
Context engineering will proceed to be arduous. But it is going to be arduous in distinctive methods, as a result of fashions aren’t individuals. You could make assumptions about how fashions suppose or interpret issues (use no matter anthropomorphizing phrase you want), nevertheless it helps to grasp how they’re constructed, optimized, and skilled. Their distinctive attributes and building create a novel set of failure modes we have to reckon with.
So let’s assessment how we bought right here.
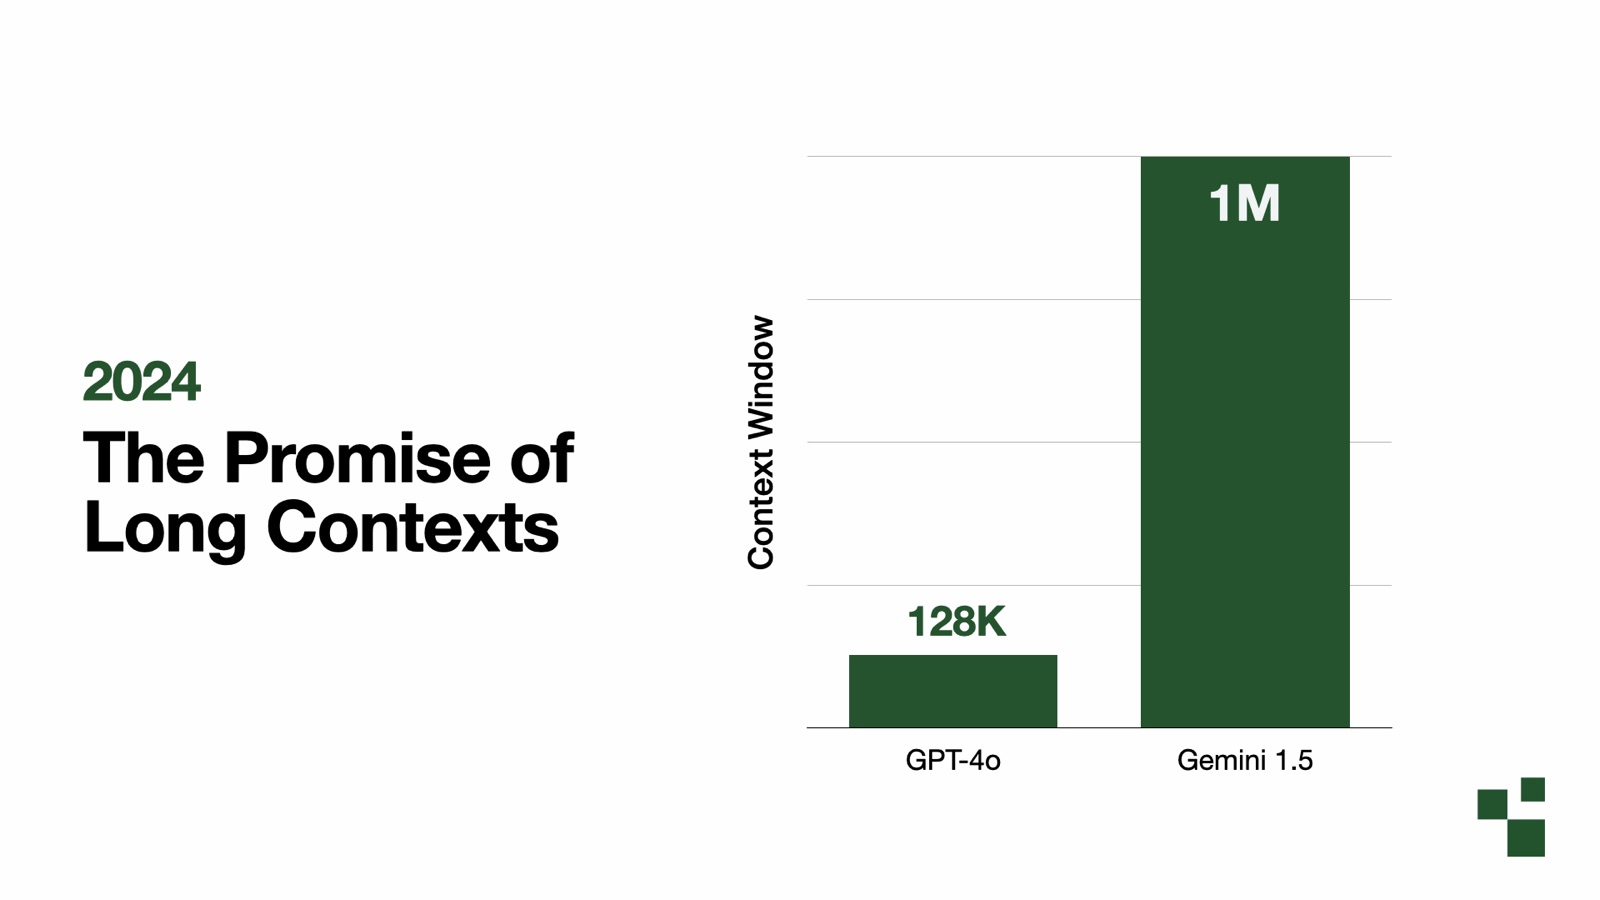
Let’s flash again to the top of 2024.
If you keep in mind, this was the peak of the “RAG is lifeless” second.
The hope was: if we are able to simply make the context window massive sufficient, we are able to put your entire web in it. We can put all the things in it. We don’t must be selective. We don’t must construct agentic methods. We can match all of it in there, and AI will likely be solved.
Model builders began aiming at lengthy context capabilities and we had a giant leap from ~128,000-token context window fashions to million-token context window fashions, beginning with Gemini 1.5.
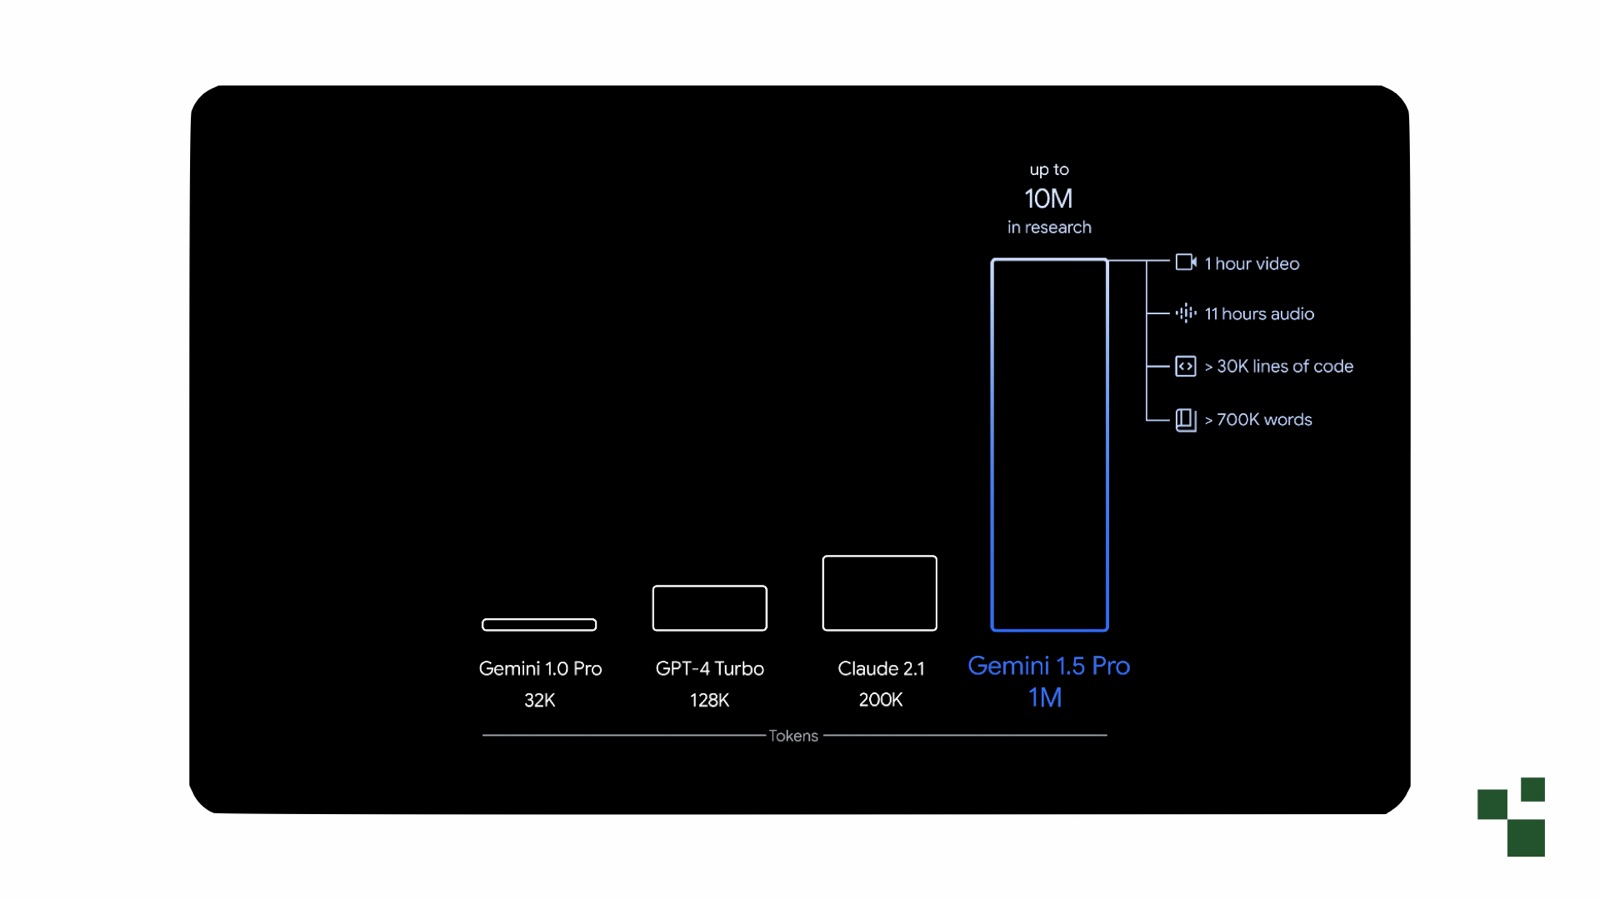
If you have a look at the marketing material for Gemini 1.5 Pro, it was largely in regards to the million-token context window. They have been even teasing a 10-million-token context window mannequin they’d within the lab, that will come out quickly.
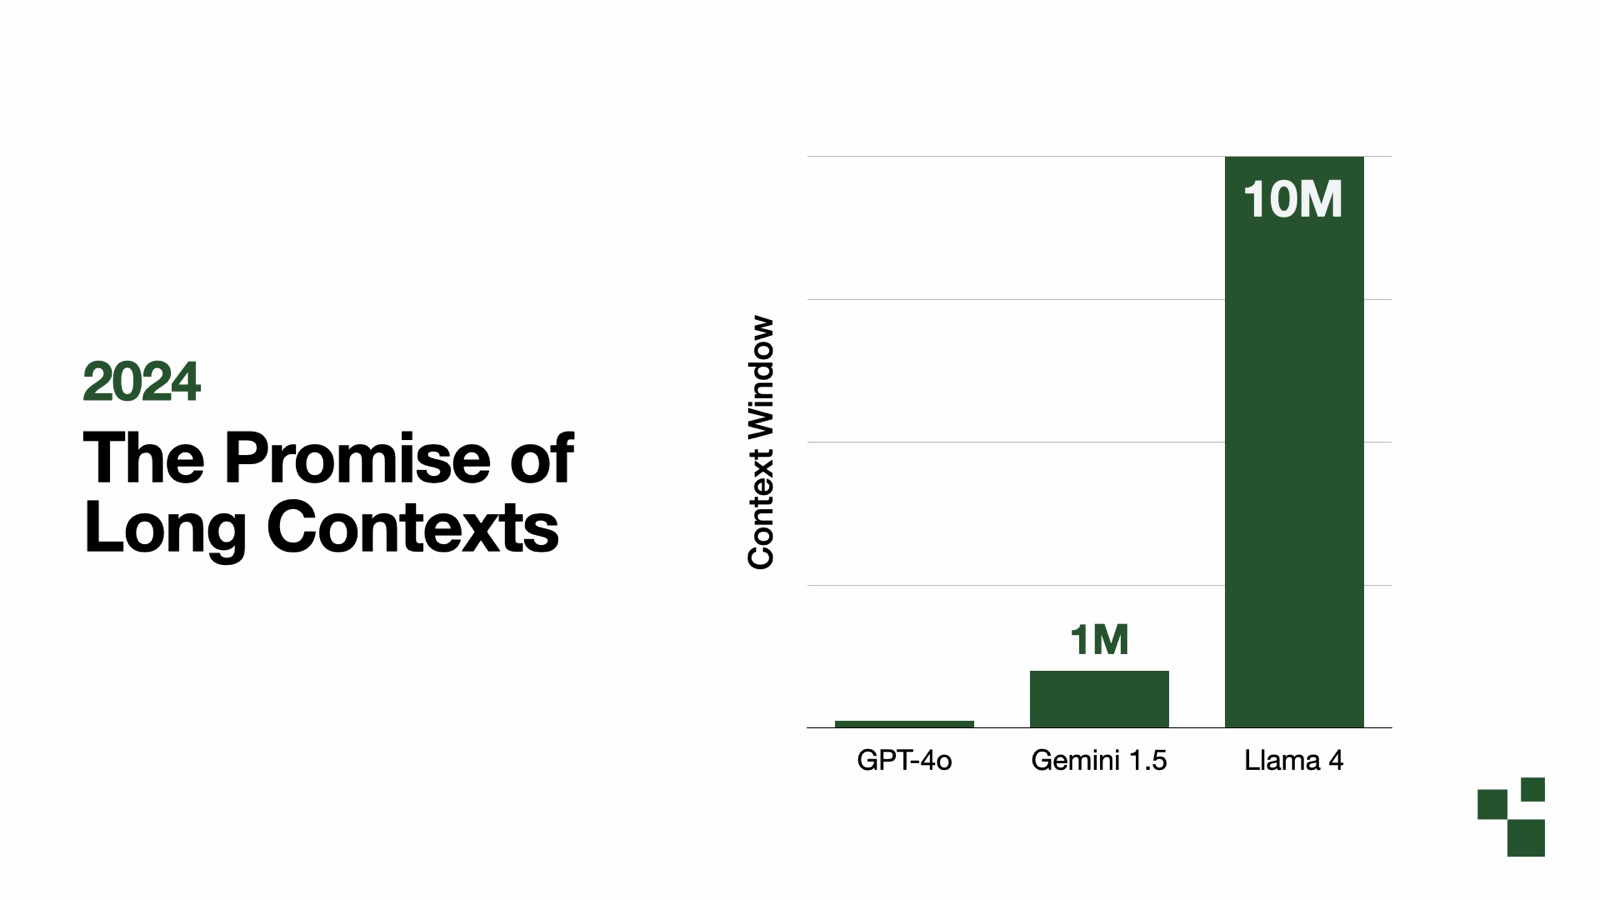
But they bought crushed to the punch. Llama 4 Scout got here out with a 10-million-token context window, and effectively, it wasn’t fairly what we hoped. Inference was a problem, and Scout by no means actually caught on, and we by no means bought one other Llama.
But we nonetheless bought one million tokens. That’s fairly good. We’ll take it.
So this was the temporary on the time: simply put all the things within the context and let the mannequin kind it out.
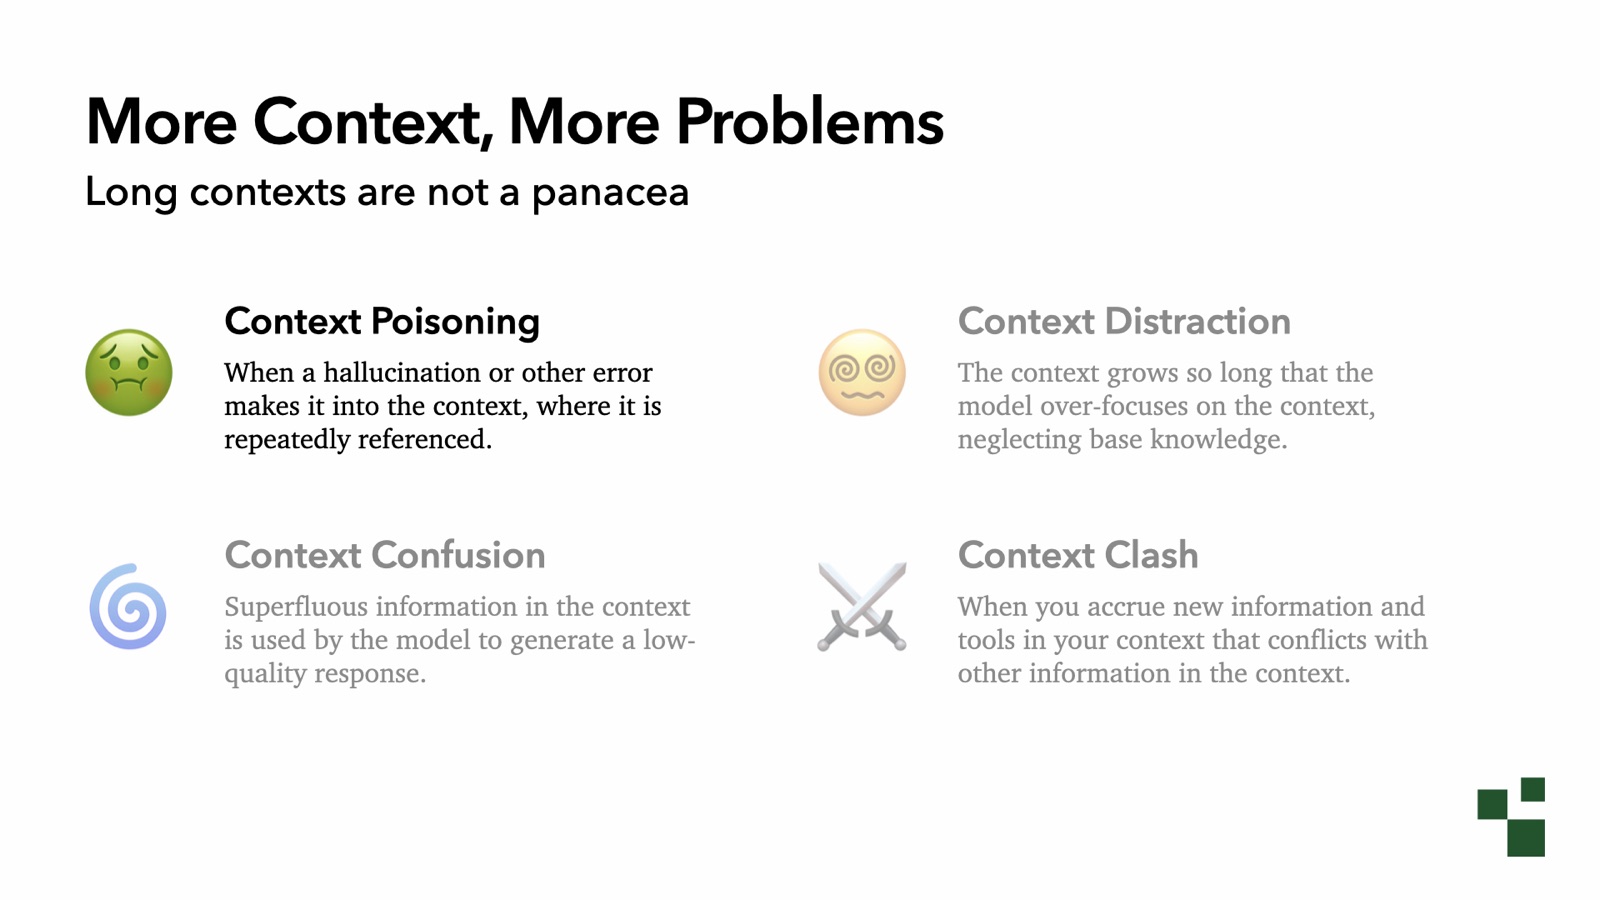
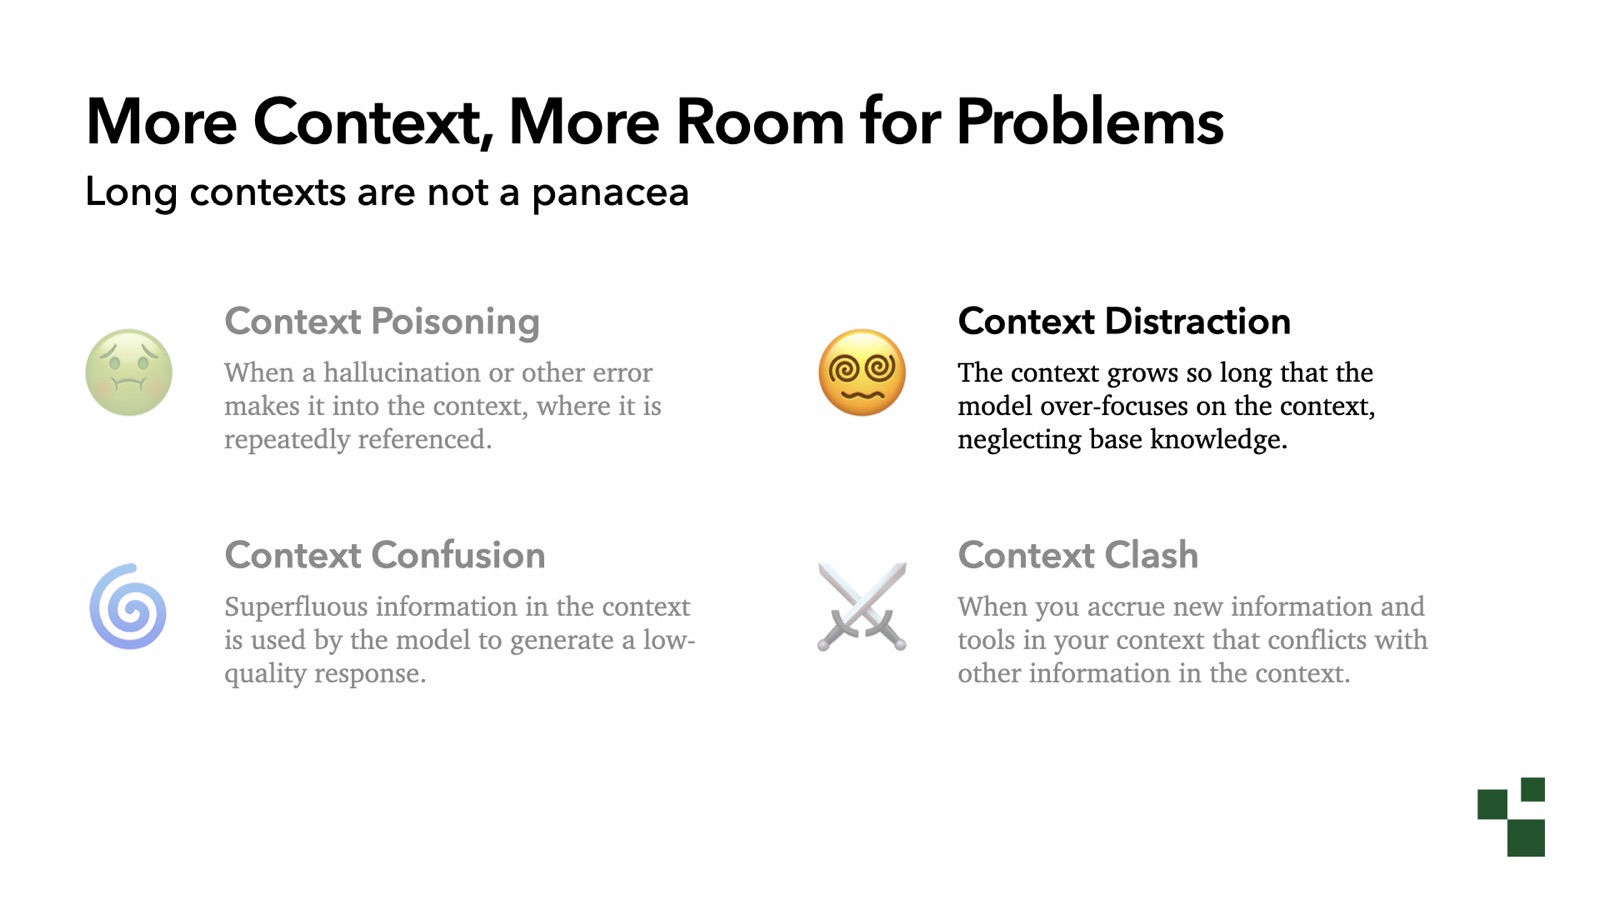
But with extra context, we had room for extra issues. Long contexts should not a panacea.
When I wrote about this, I recognized 4 key failure modes.
Context poisoning is when one thing will get into the context that shouldn’t be there. It may very well be a hallucination or a foul reality, and the mannequin can’t get previous it.
Context distraction is when the context grows so lengthy that the mannequin begins to concentrate on the context over its base information. We can see this in some actually attention-grabbing methods.
Context confusion is when extraneous information—issues that don’t relate to the issue I’m engaged on—are available and affect the mannequin in methods we don’t absolutely perceive. This one’s actually pernicious. We’re not going to dig into it right this moment, nevertheless it’s one in every of my favourite failure modes. The mannequin makes assumptions about who you might be, and people assumptions affect the reply.
Finally, context clash is when device calls, abilities, and different data inside your harness begin to dispute and work towards you in methods you didn’t count on.
(How a lot of you retain reminiscence on in ChatGPT or Claude? I flip it off. I hate it. Sometimes I’m speaking about work conversations; typically I’m speaking a couple of venture I’m doing with my son. The mannequin will take notes on each, combine up these contexts, and the confusion grows from there.)
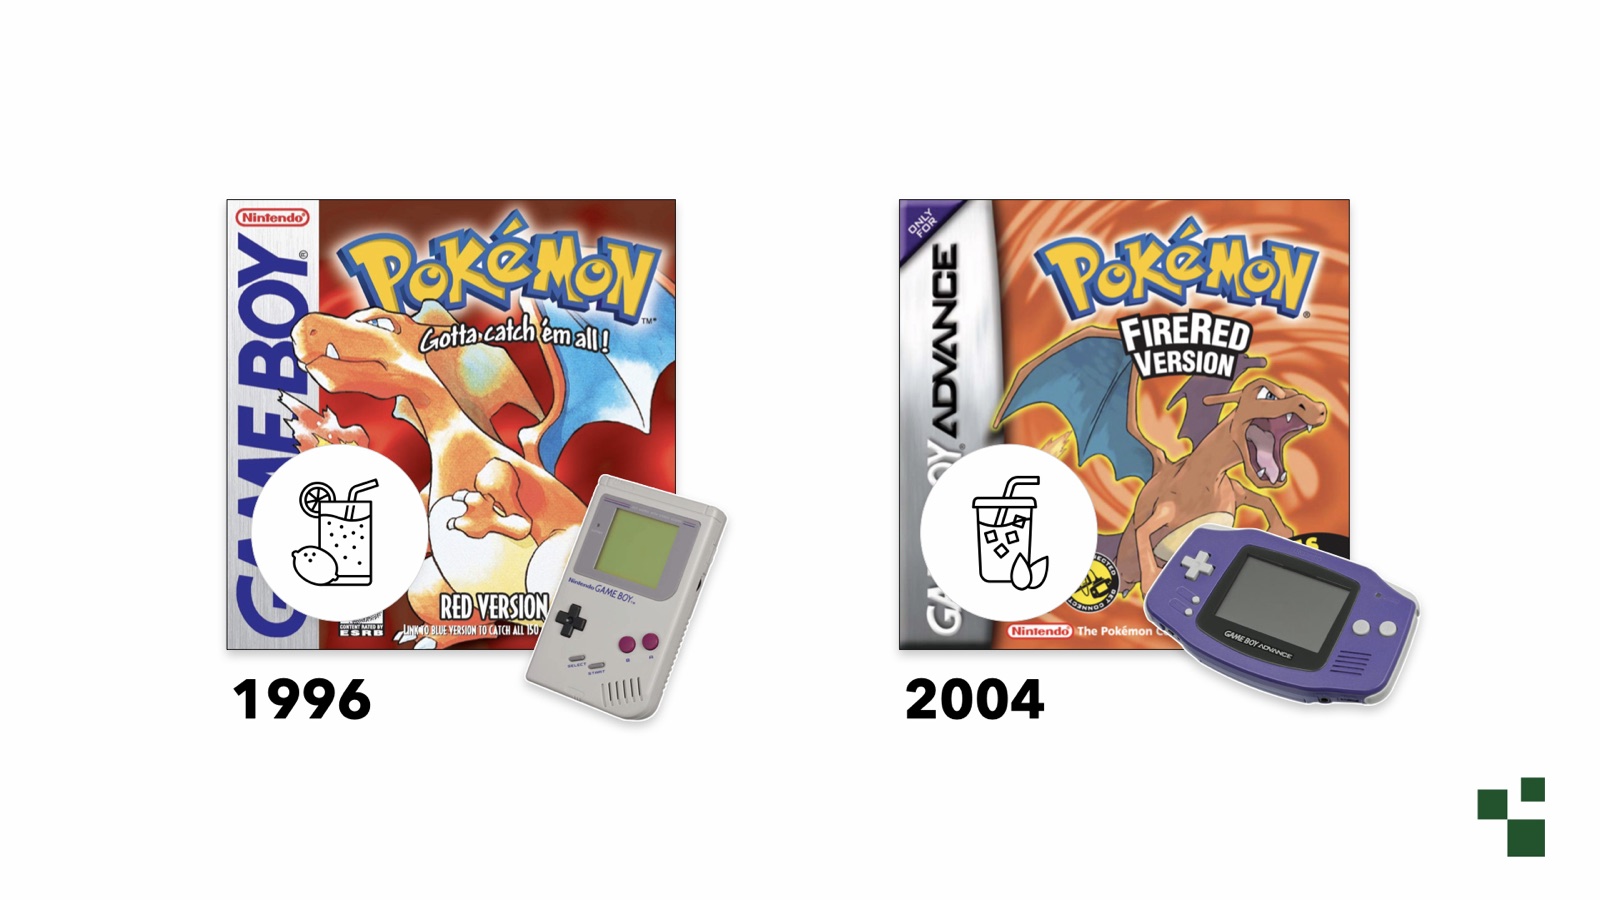
Let me provide you with my favourite instance of context poisoning.
I’m going thus far myself: I performed the sport on the left. The one from 1996, for the unique Game Boy. This is the primary Pokémon Red. It was in black and white.
In 2004, Nintendo launched Pokémon HearthRed for the Game Boy Advance. These have been basically the identical sport, besides one had higher colours and audio.
But there was one delicate change. At some level in each Pokémon Reds, to get previous a safety guard, you must give them one thing to drink. A bribe. Quite the sensible lesson for youngsters.
In the unique sport, you should give the thirsty guard lemonade. In HearthRed, for some cause, they modified it to iced tea.
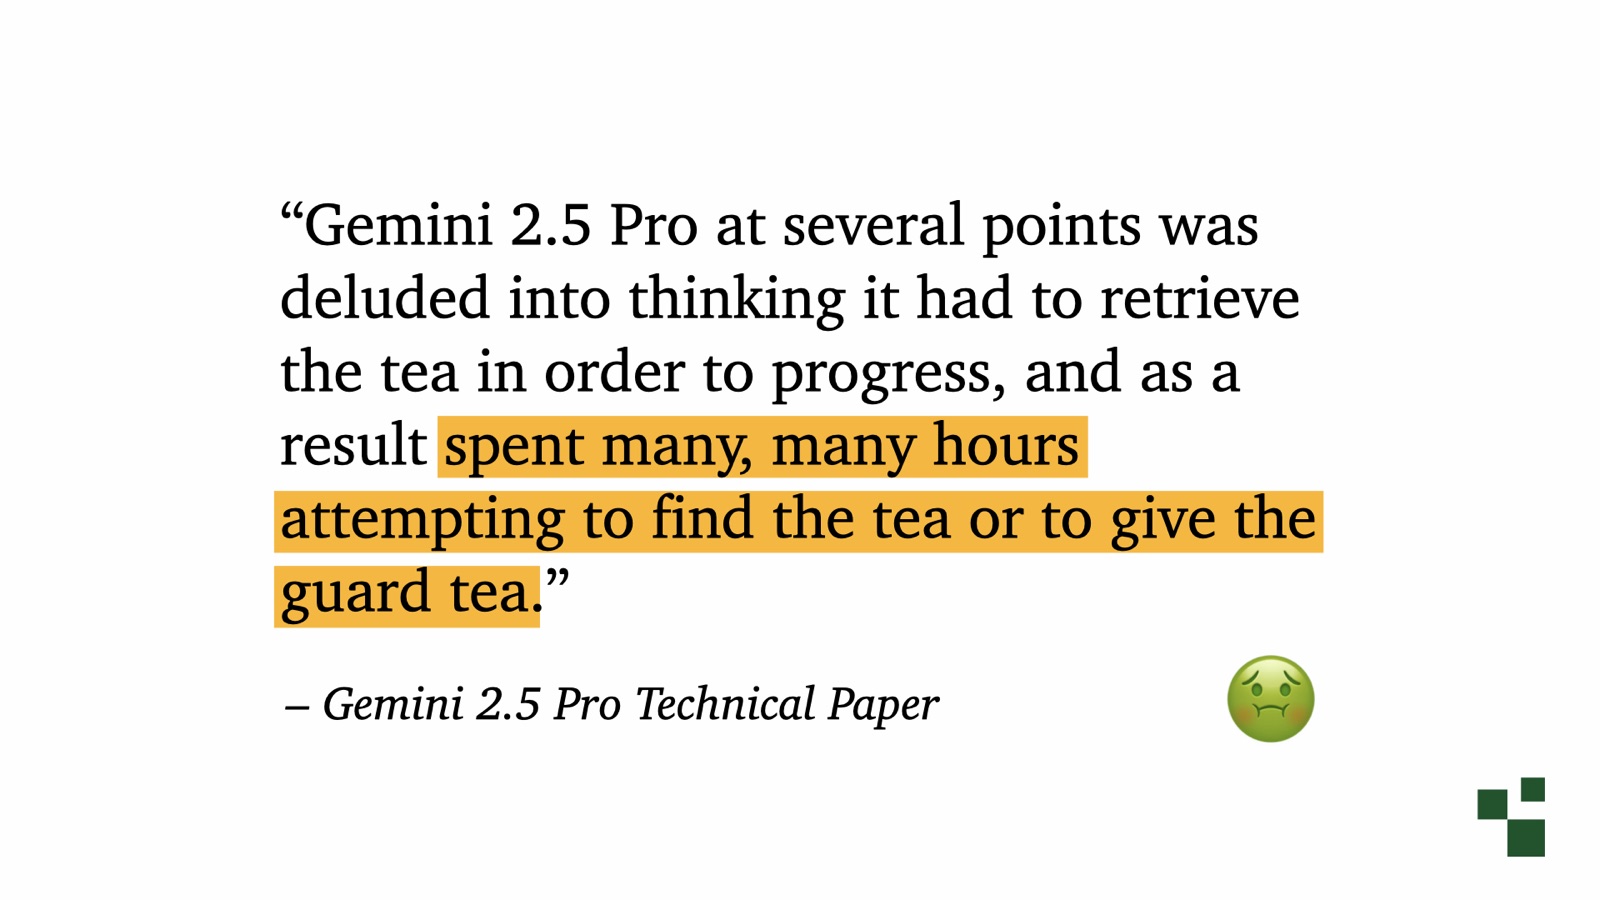
That created an issue for the agent. In the Gemini 2.5 technical report, the researchers described how they had the model play Pokémon. Researchers like Pokémon as an agent benchmark as a result of it’s a fairly managed surroundings and doesn’t transfer notably quick.
Several occasions, Gemini 2.5 grew to become satisfied it wanted to get tea, regardless that it was enjoying the older sport. The tea process for HearthRed was in its weights, so it poisoned its context. It spent hours looking for or give the guard tea. Once it had been added to its to-do listing, the mannequin couldn’t get previous it.
That’s context poisoning. And it occurs on a regular basis.
Another failure mode is context distraction. This is one in every of my favourite demonstrations, and the analysis got here out after I wrote the unique piece.
As your context will get longer, how does your conduct change? Quick query: what number of of you, if you’re coding, let the context go all the way in which to one million tokens? Fill all of it up?
(About half the room raised their fingers!)
Wow, that’s greater than I anticipated.
For me, round 200,000 or 300,000 is the place I begin trying. I’ll test, see it’s at 250,000, and suppose: I’ve bought a giant job arising. I’m going to reset and begin recent. Let me present you why this issues.
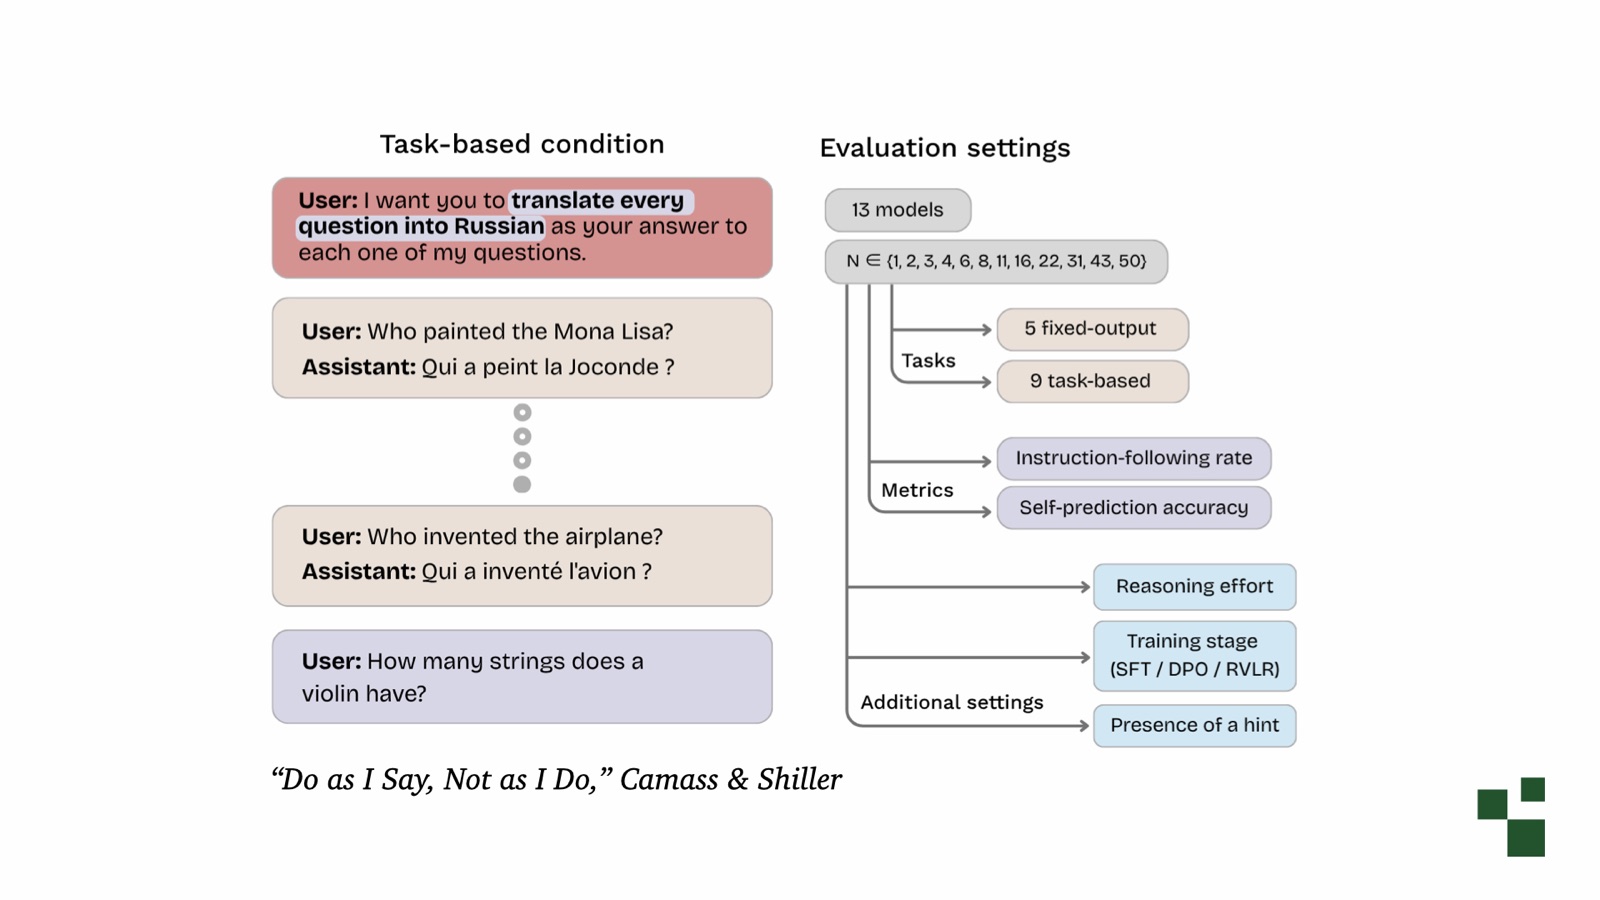
Recently, I came across a paper that splendidly illustrates context distraction: Do as I Say, Not as I Do, by Carolina Camassa and Derek Shiller.
Their experiment is slightly contrived, nevertheless it’s helpful for fascinated with how this occurs. They give the mannequin an instruction: “I would like you to translate each query into Russian as your reply to every of my questions.” Then they current a bunch of examples which can be counter to those directions. In this case, many questions with solutions in French.
These aren’t new directions. They’re simply examples sitting within the chat historical past.
Then they ask the mannequin a query. Will it observe the directions?
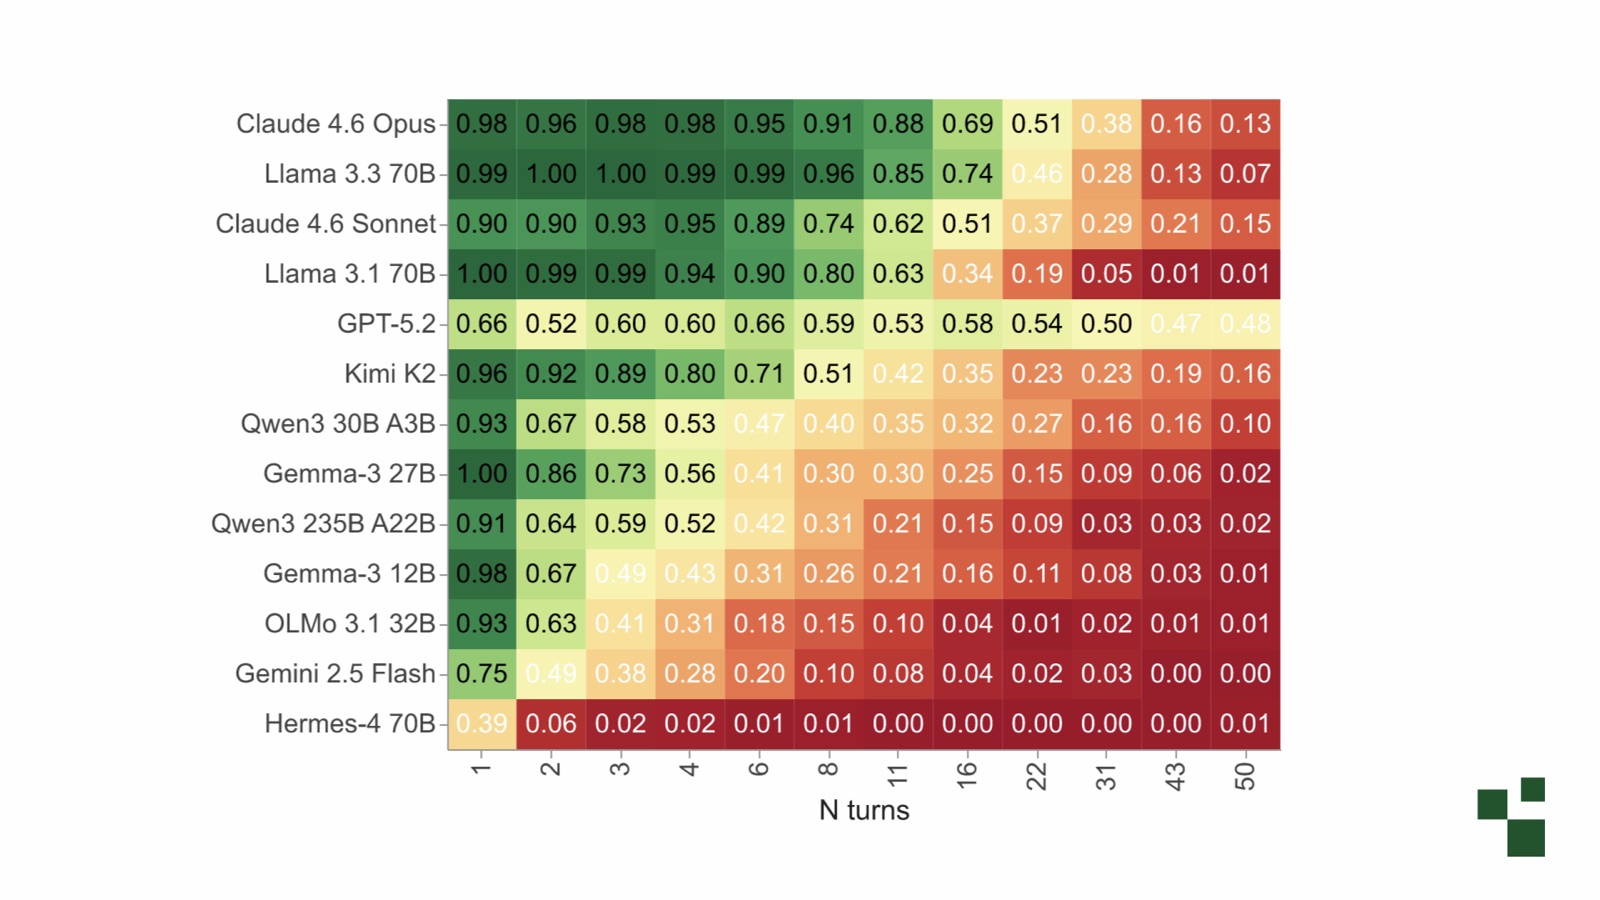
How usually does the mannequin reply in Russian, because it was instructed to, and the way usually does it reply in French, because it’s seen within the examples?
The x-axis on this matrix enumerates what number of dangerous examples have been current. The y-axis is the mannequin being examined. The figures within the intersections are the proportion of occasions the mannequin adheres to the directions, somewhat than following the examples.
It seems this impacts each mannequin! For smaller fashions, like Gemma 3 12B, after just some contradictory examples, the mannequin follows the instruction lower than half the time. With Opus 4.6, which is a tremendous mannequin, it takes many extra examples, nevertheless it occurs there too.
Imagine you’re going backwards and forwards on a front-end design, making an attempt to tweak CSS and get a part precisely proper. How many dangerous examples have you ever seeded in that alternate? Those examples begin to affect the mannequin. As your context grows, issues disintegrate.
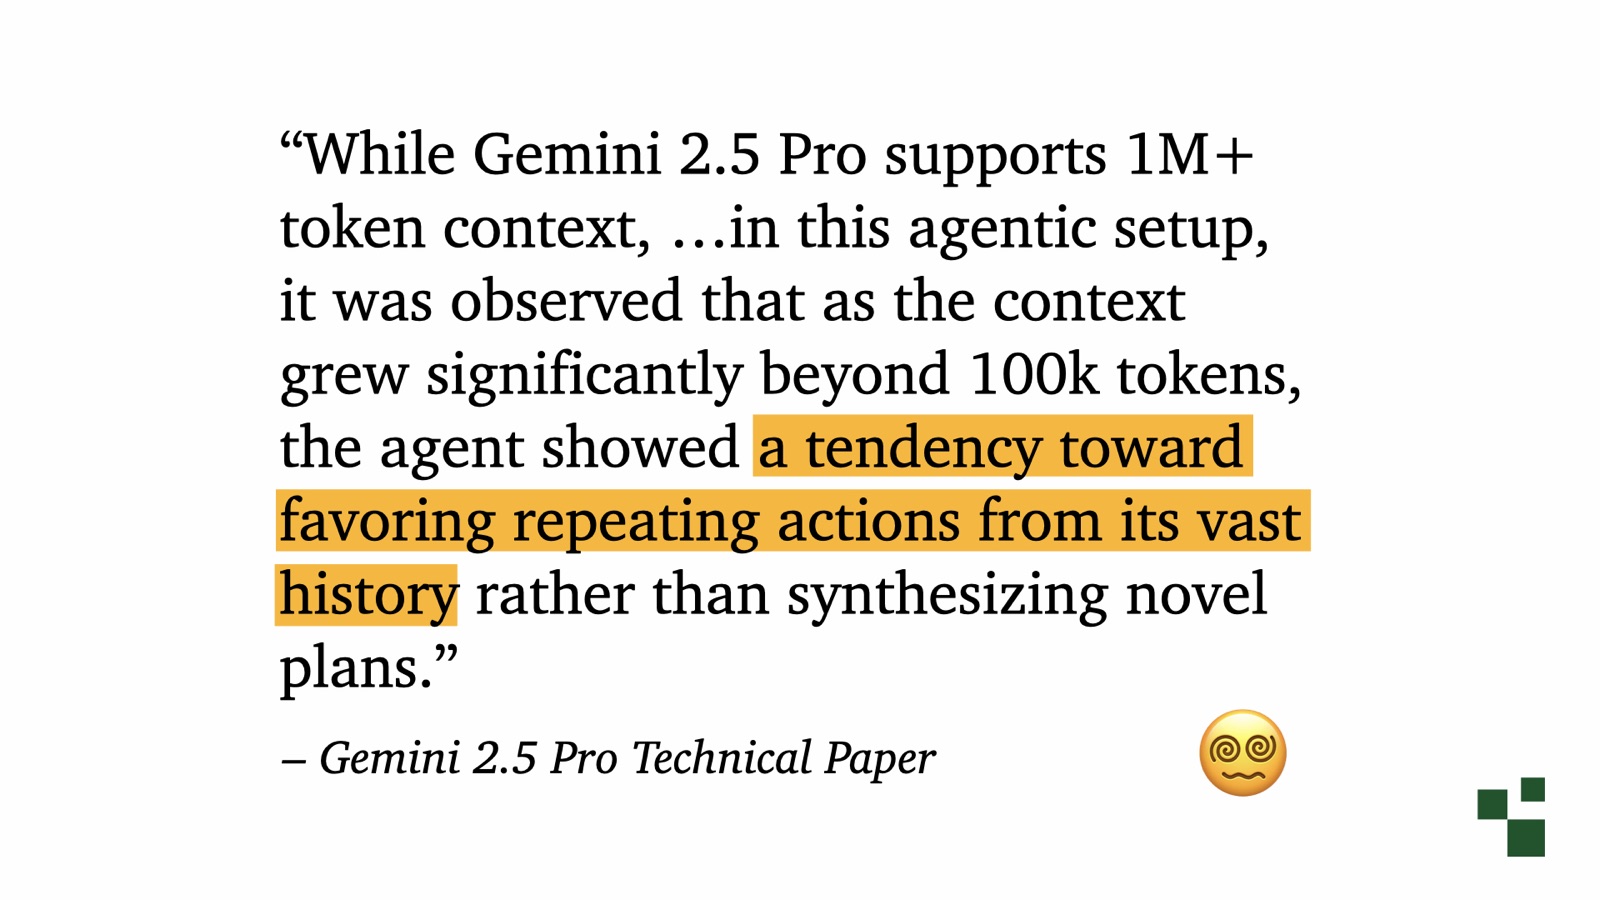
Gemini 2.5 bumped into this too, whereas enjoying Pokémon.
Remember, Google was actually happy with its million-token context window. The paper prompt that two million tokens have been across the nook. But buried within the appendix was this remark: as soon as the context grew considerably past 100,000 tokens, the agent started repeating actions from its historical past as a substitute of synthesizing new plans.
I’m satisfied the advertising individuals by no means learn the appendix. I love this technical report.
Long contexts let you slot in extra data, however in addition they let you slot in extra errors. Long contexts weren’t a panacea.
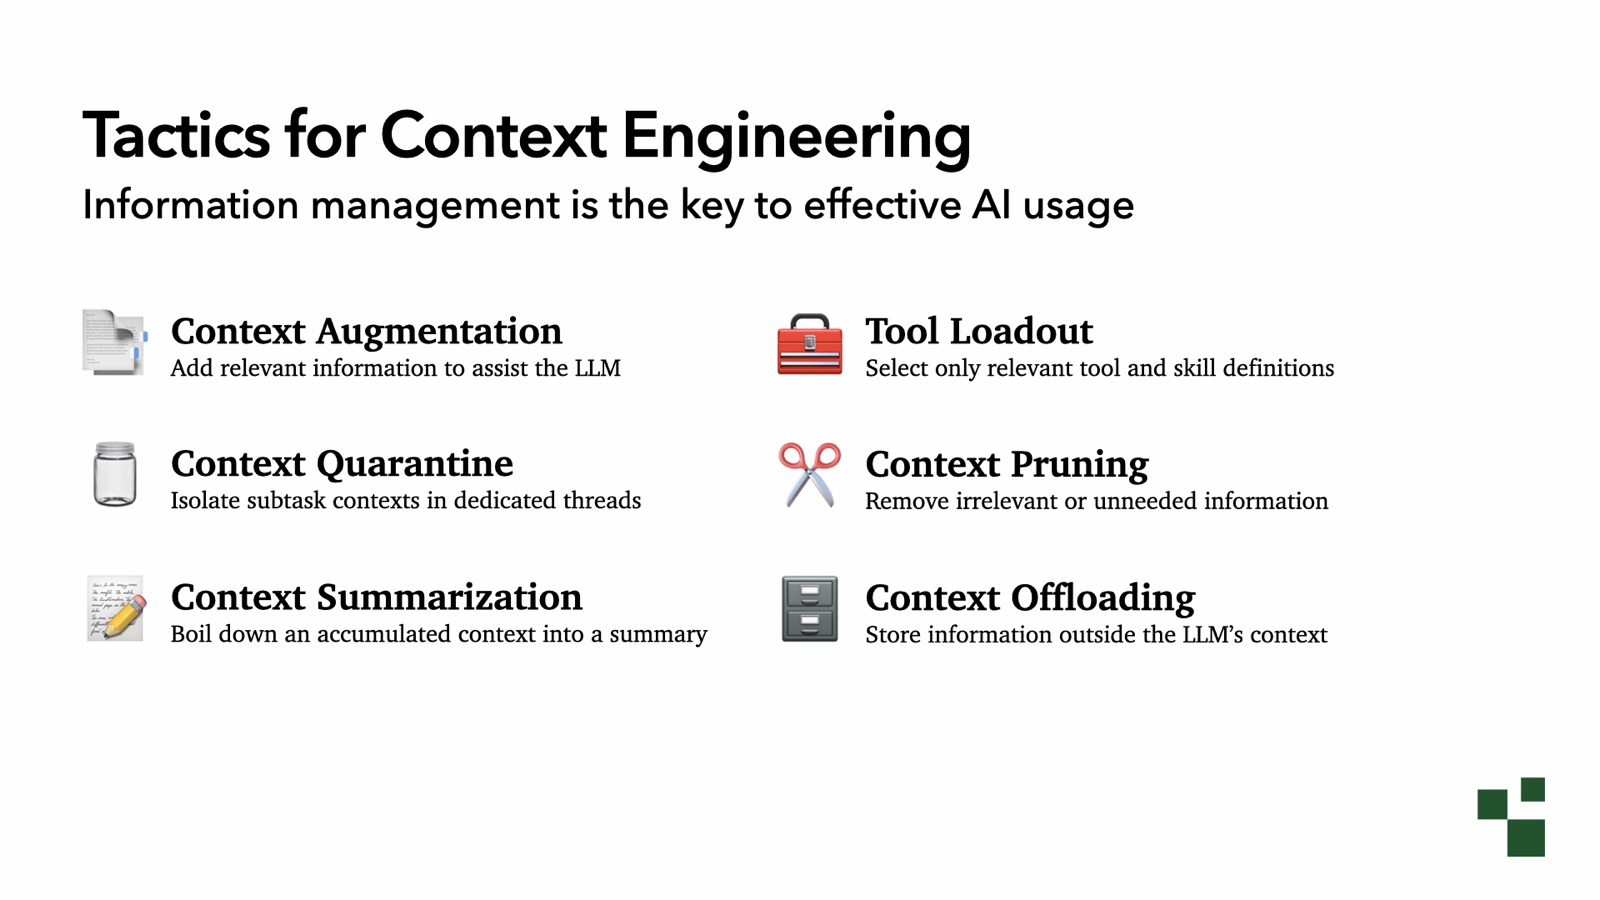
Thankfully, we’ve developed a fairly good toolbox. Surprisingly, at the same time as new challenges have emerged (we’ll get to these in a minute), this set of instruments has remained the identical.
These six of them.
You have context augmentation: RAG, abilities, and different methods to usher in the data related to the issue.
You have tool loadout: choosing which instruments and abilities to show so that you don’t overload the mannequin. I used to be just lately speaking to an enterprise staff whose brokers had all of the sudden began performing terribly. We investigated and found their enterprise software program was loading 600 abilities for each engineer at startup. We figured they need to most likely filter these, with a loadout perform.
Third is context quarantine: subagents and peer brokers, the place you begin one thing with a clean historical past however let it work in the identical surroundings.
Fourth is context pruning. Claude Code and Codex do that, typically with out you even noticing. Early phases of compaction usually strip out device outcomes you not want.
Fifth is context offloading: storing data within the surroundings, comparable to Markdown recordsdata or a database, so you’ll be able to entry it later.
And sixth is context summarization, which everybody is aware of as compaction.
These are the instruments, and we’ve more and more moved them into the harness.
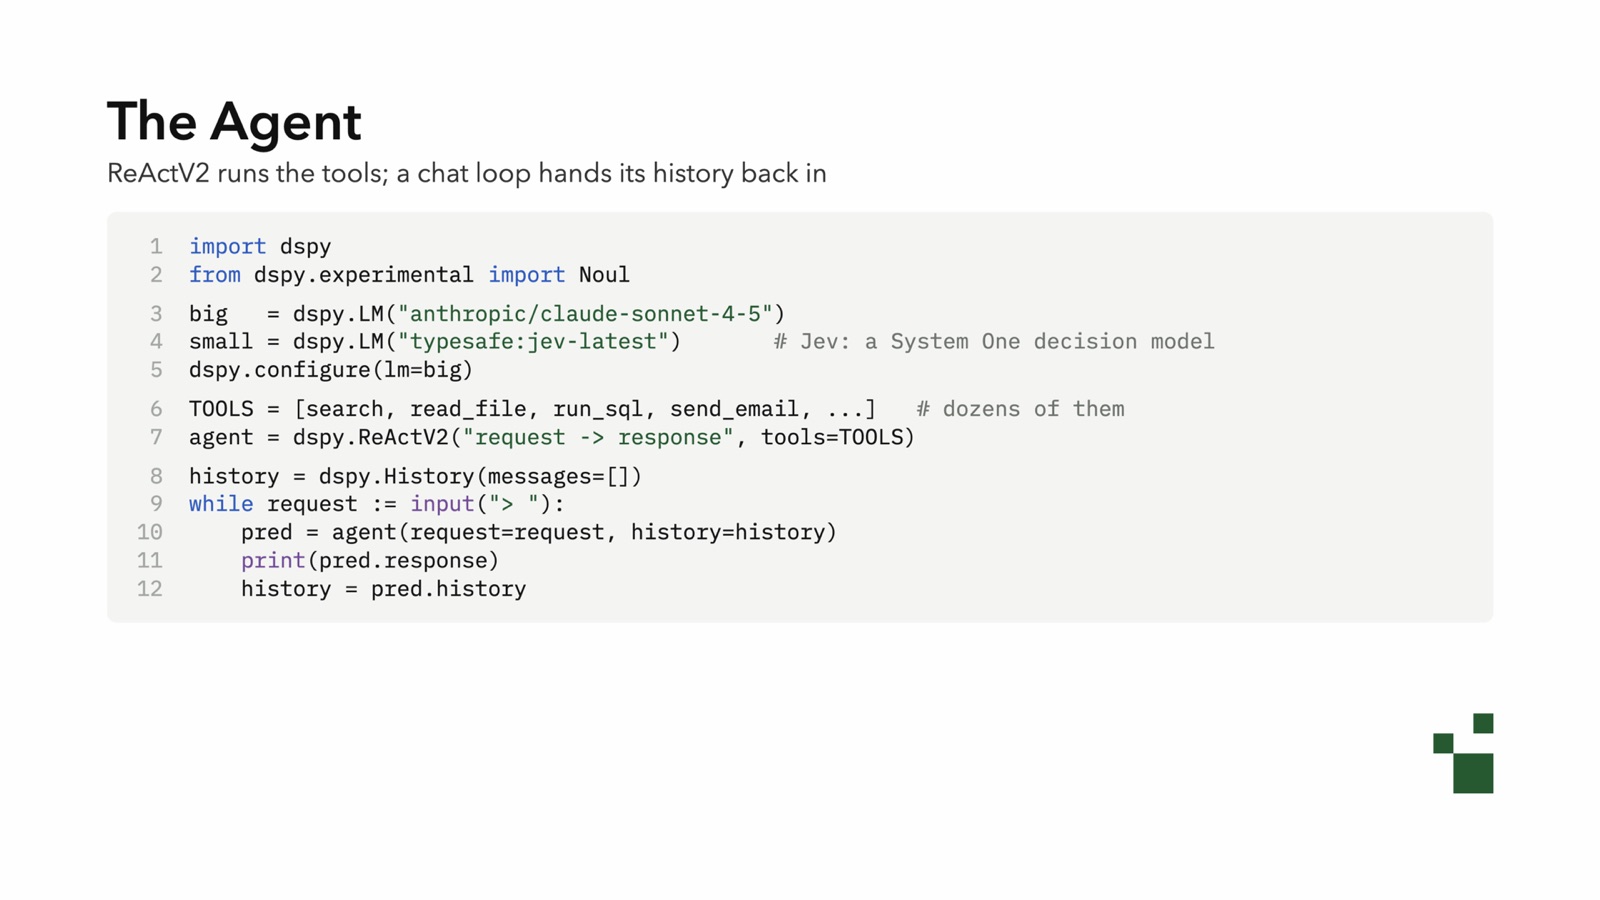
Let’s have a look at an instance harness, to indicate how easy these patterns are.
I’m actually keen about DSPy. I believe it’s an extremely readable and efficient technique to construct AI workflows and brokers. And it’s additionally an awesome language for merely specifying conduct, so it’s effectively suited to this demonstration.
An agent is a while loop. Here we’re utilizing a ReAct module: we give it a request, we would like a response, and we give it some instruments. Those instruments are simply Python capabilities.
For this demo we’ve a giant mannequin (on this case, Claude opted for Claude Sonnet 4.5, good luck with that!). And I’m utilizing a Jev because the small mannequin: a tiny resolution mannequin that makes lightning-fast selections. You may swap in a small LLM on this instance, and all the things would nonetheless work.
We have a whereas loop that takes enter, sends it to ReAct, and carries the accruing historical past ahead. This is an agent in a couple of dozen traces utilizing DSPy. It could be even fewer for those who took out the additional mannequin.
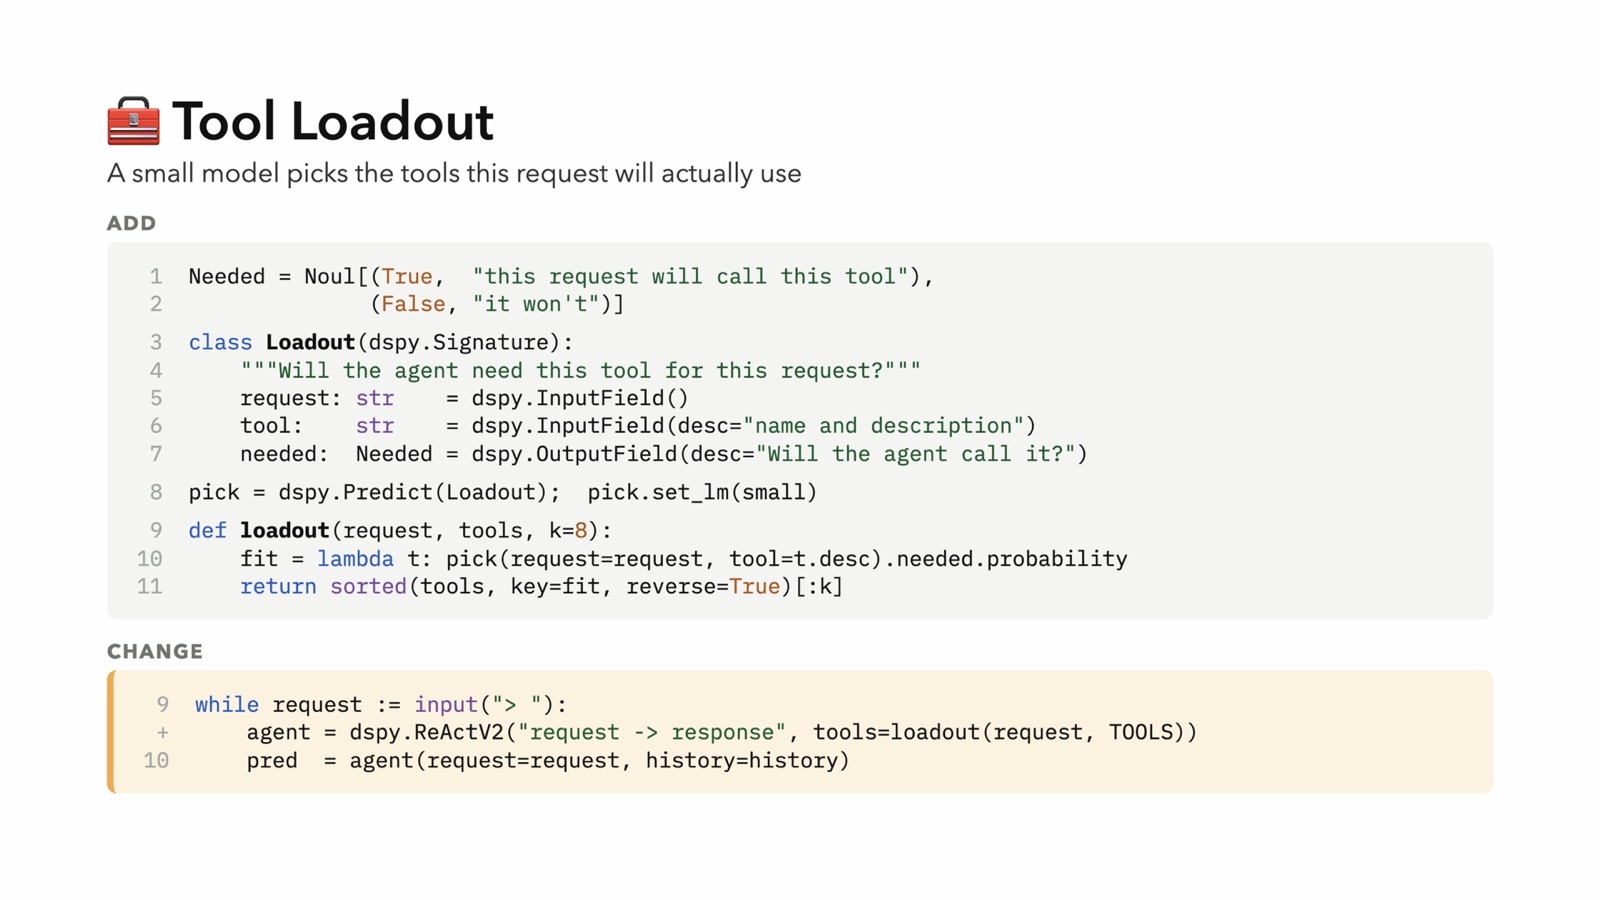
How can we do device loadout? It’s only a perform.
We current Jev with the request and a device, asking if it’s wanted for this process.
Jev is quick sufficient that we are able to do that one device at a time; it’ll be high quality. We wrap this in a loadout perform that iterates via all of the instruments and asks if every is required, then returns the top-ranking subset. That’s it.
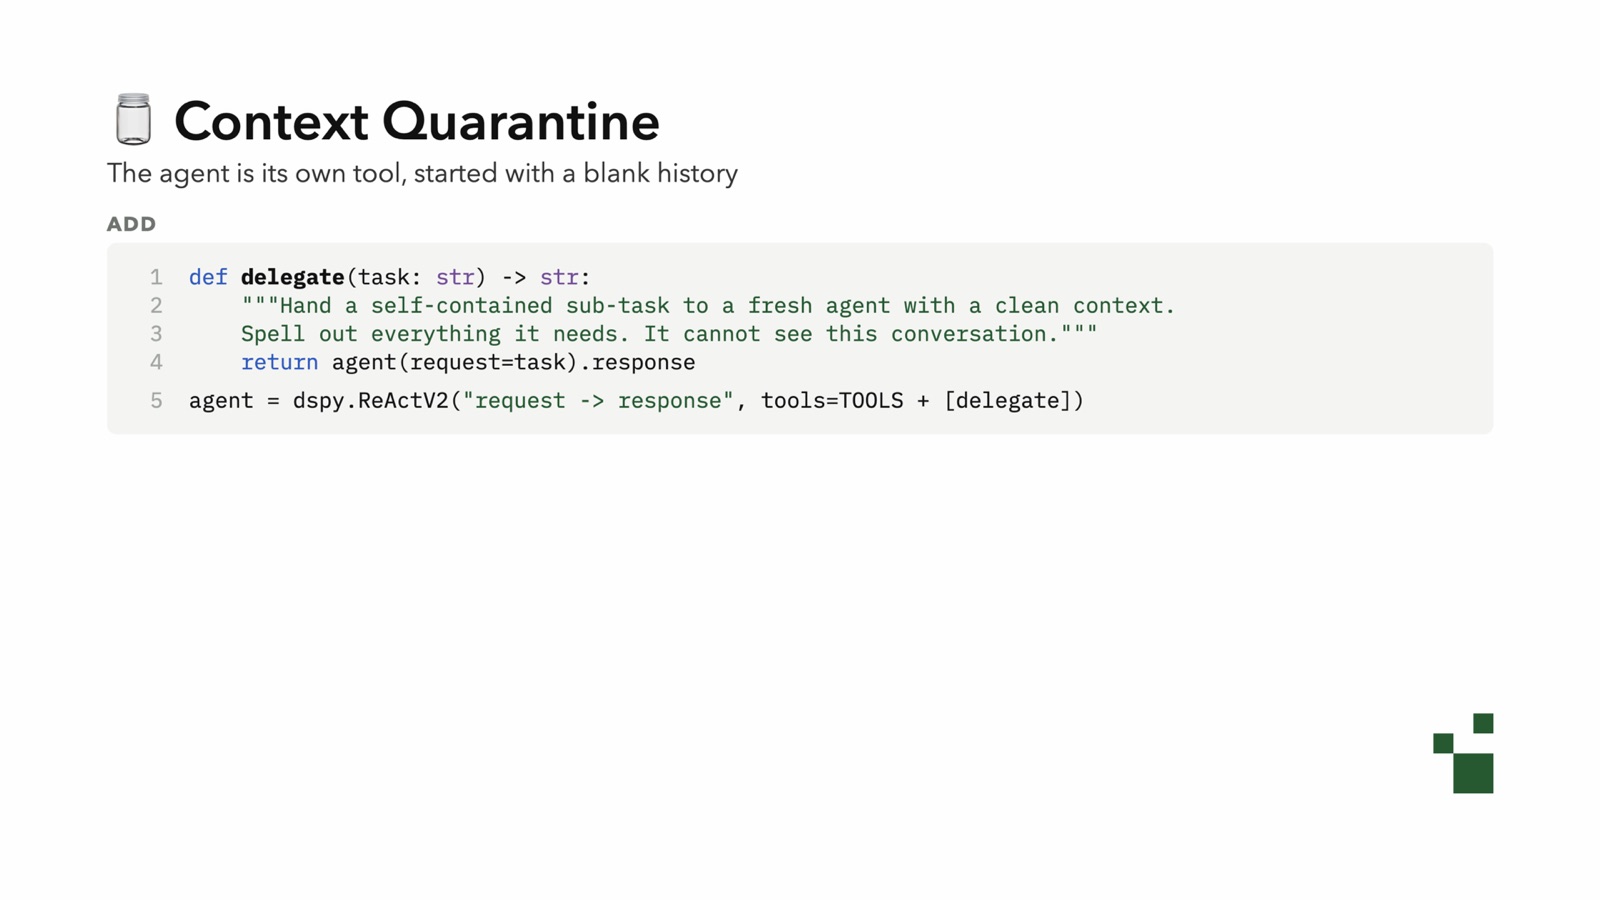
With context quarantine, it’s only a subagent. You expose an agent as a device that the principle agent can use, and it begins with a clean historical past.
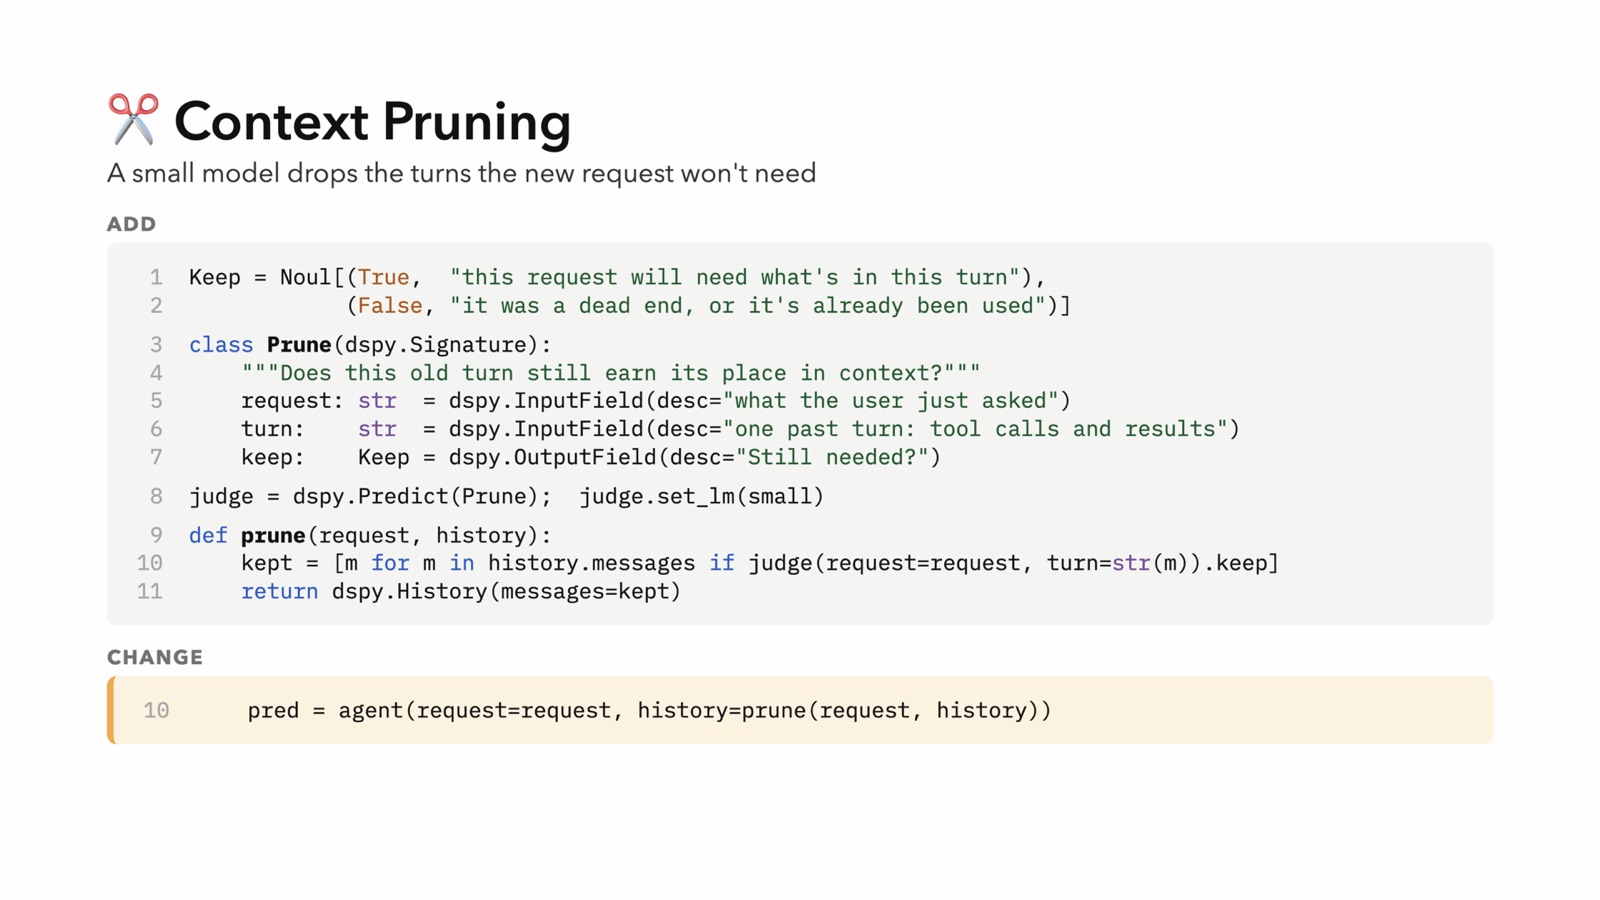
With context pruning, we’re stepping via the historical past, passing every flip to Jev, and asking: is that this nonetheless wanted? If not, reduce it.
You could be as tough or as elegant as you need right here. Just thoughts your immediate caching.
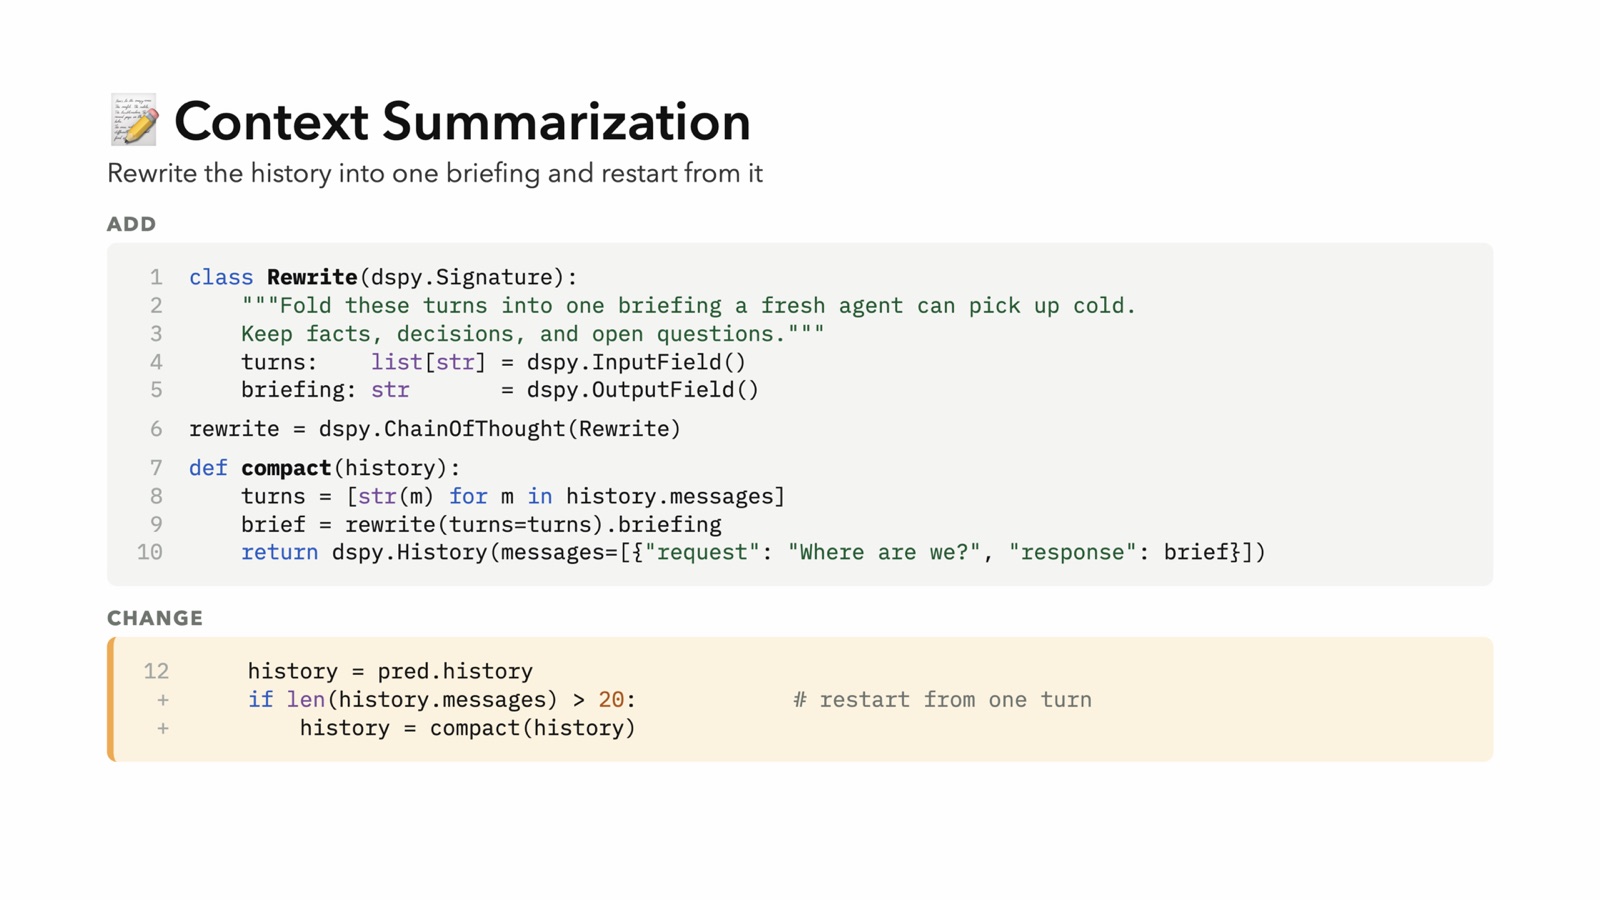
We may rewrite the historical past with compaction. Take the outdated turns, create a abstract, and begin the brand new context from that abstract.
One of my favourite variations these days is checking what issues earlier than you compact. You use Jev, or one other resolution mannequin, for the primary go to evaluate what’s related. Now you’ve bought a smaller subset of the historical past, and also you summarize that. It’s a easy additional step, nevertheless it makes the abstract extra helpful.
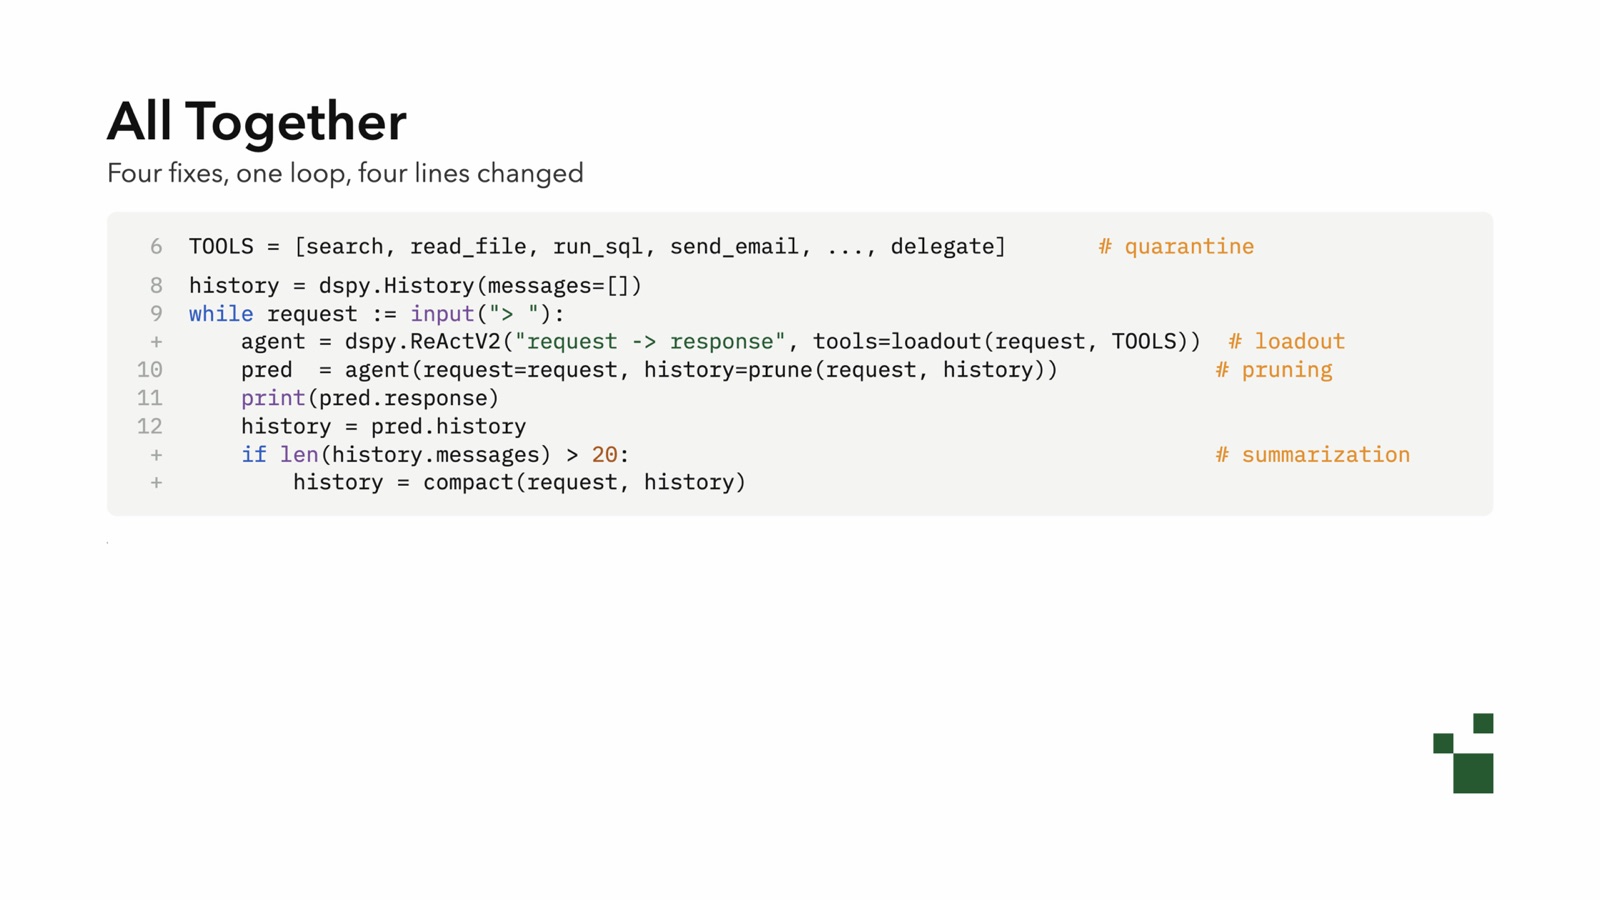
Put all of it collectively and it’s about 16 traces of adjustments. Four fixes, one loop. These are the strikes we’ve within the harness. It’s truly remarkably easy.
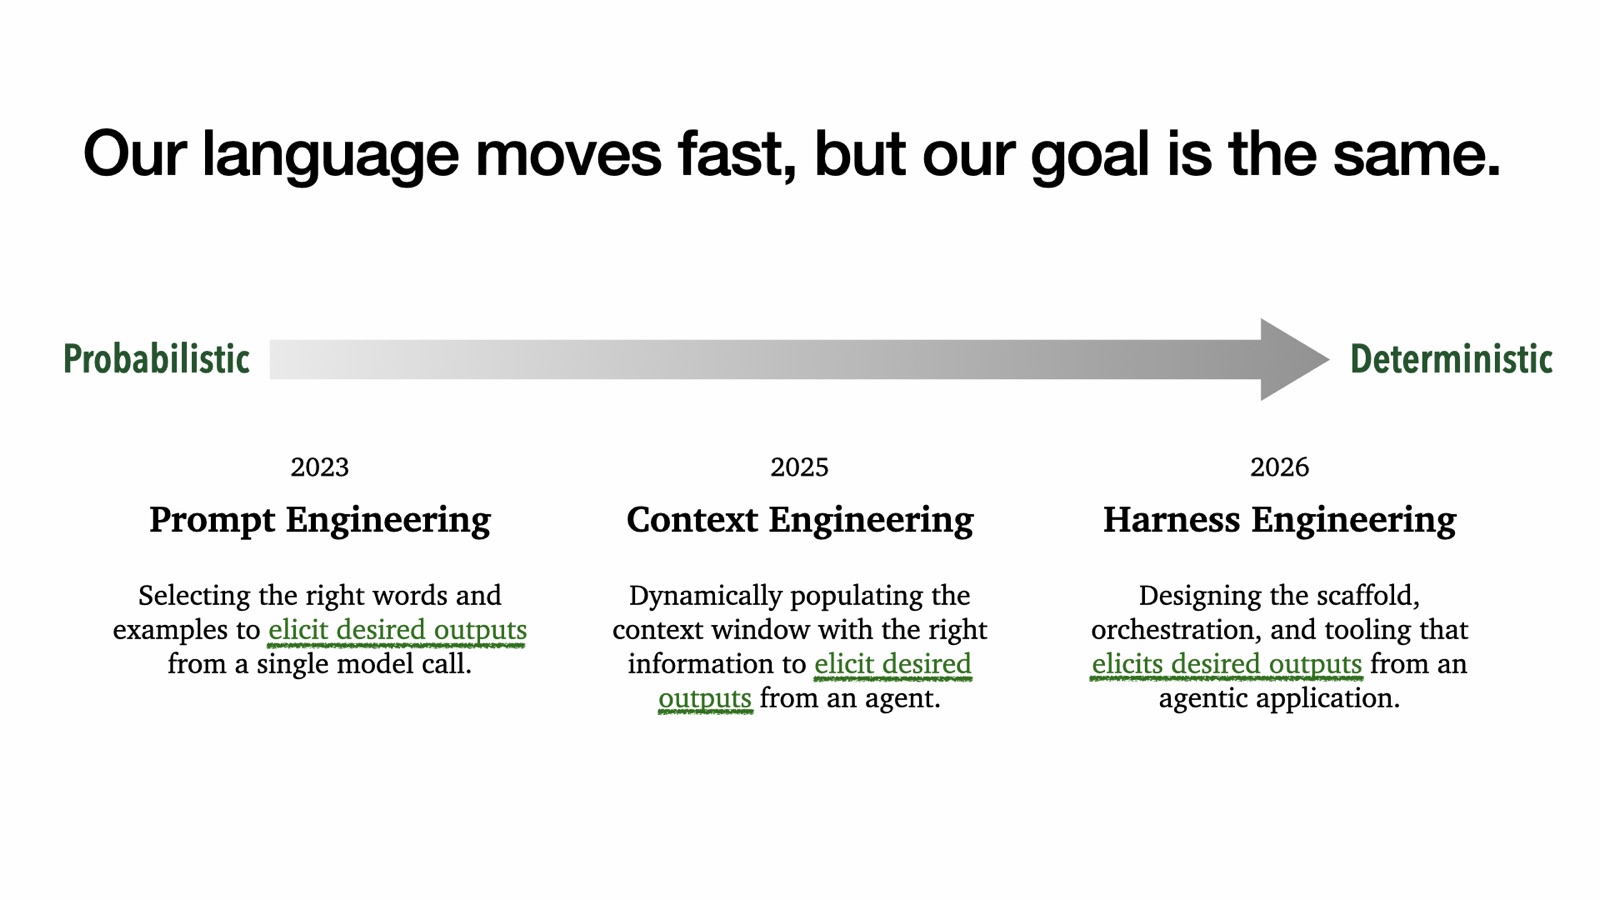
What isn’t easy is our language: how we speak about these items. It’s actually arduous to maintain tempo; it adjustments day by day.
One of my favorite quotes is from Stewart Brand, which I take into consideration on a regular basis:
If you wish to know the place the long run is being made, search for the place language is being invented and legal professionals are congregating.
Certainly applies right here! But as our language has modified, our aim has remained the identical.
In 2023, we known as choosing the proper data to get the suitable response immediate engineering.
In 2025, we known as it context engineering, besides that now it was extra automated. It wasn’t simply you writing the immediate; it was your system dynamically assembling the context.
Then, as we moved extra of those instruments out of the context and into code, we began calling it harness engineering.
But the job is identical. We’re shifting increasingly of the work of assembling context from probabilistic mannequin calls to deterministic code.
I’ve proven you 2024. Let’s go to 2026.
We’ve moved these context fixes into the harness. What do we would like subsequent? We need agentic fashions that may drive our harnesses.
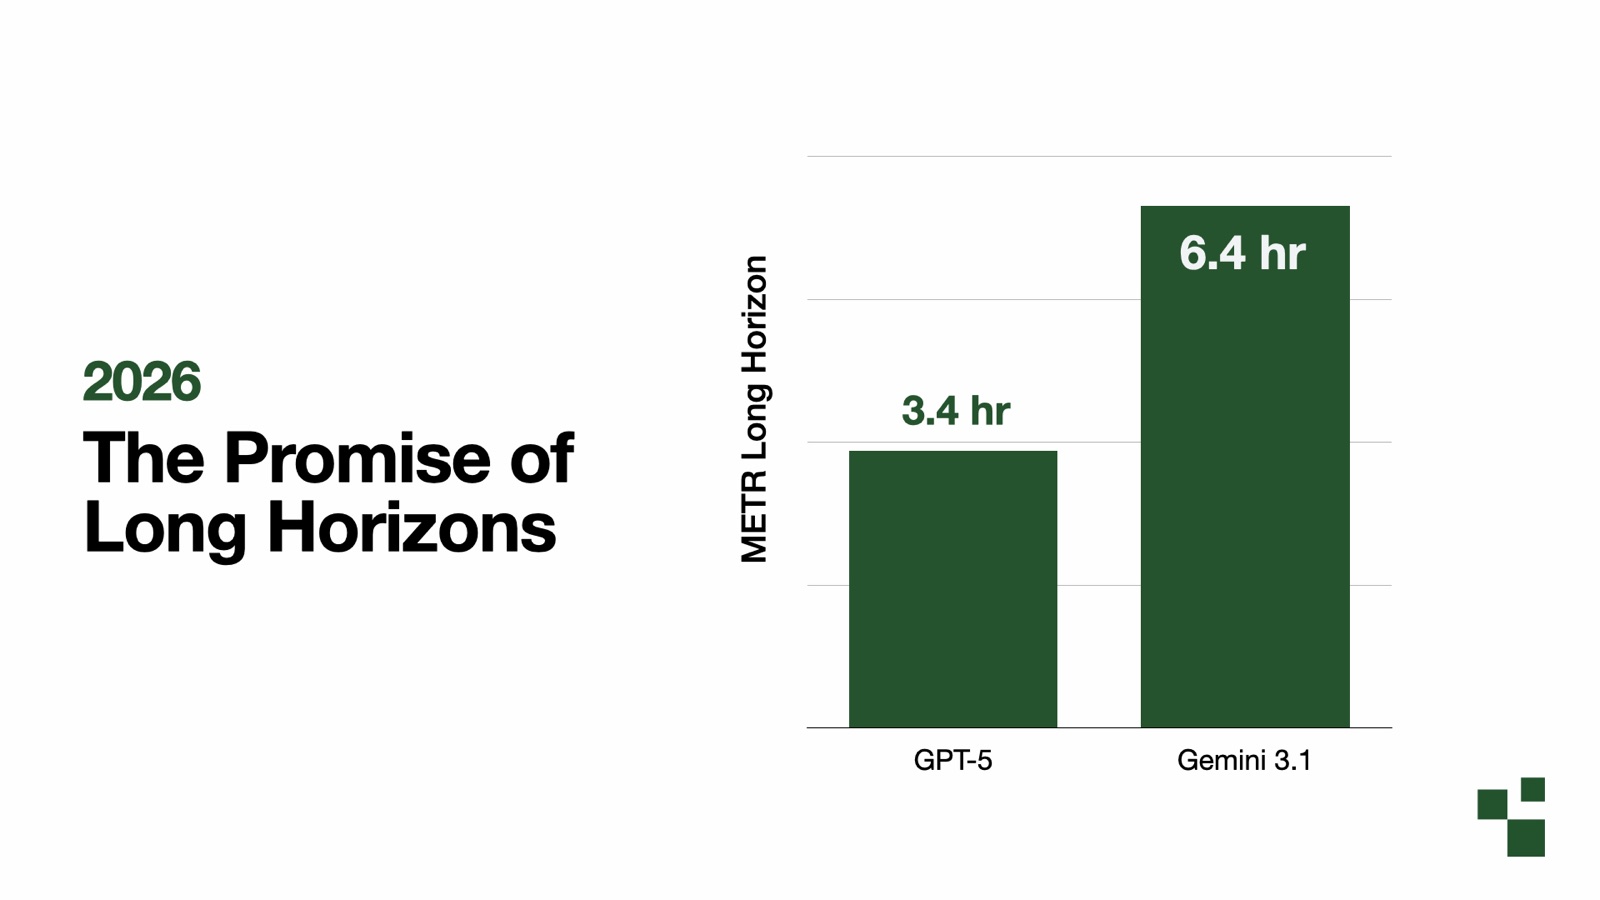
Everybody began focusing on long-horizon agentic fashions. You’ve seen the METR studies. GPT-5 may deal with duties round 3.4 hours on that measure; Gemini 3.1 bought as much as 6.4 hours. That’s with a harness. The fashions have gotten significantly better at utilizing it, and that’s how they’re in a position to run for thus lengthy.
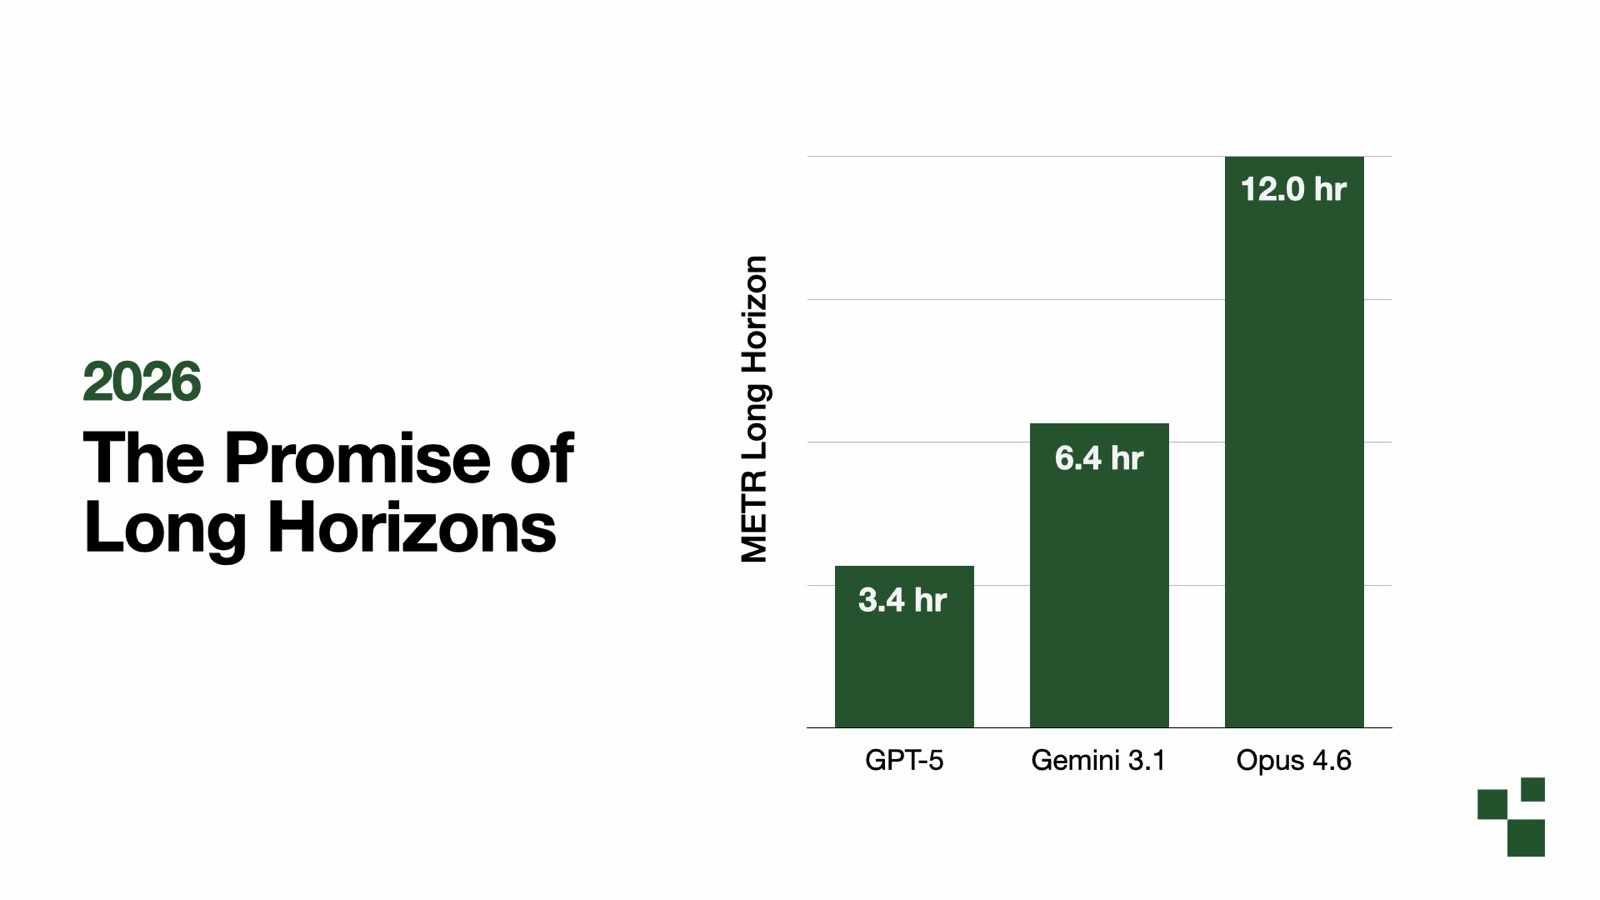
Opus 4.6 bought as much as round 12 hours. And now we’re speaking about brokers operating for days, swarms of brokers, and fashions that drive harnesses over for much longer durations.
Before, the pitch was: make the context so massive that we are able to match all the things in it.
Now the pitch is: train the mannequin to drive the harness and handle its personal context. That’s develop into the dominant sample. That’s what mannequin builders are working in direction of.
What new failure modes does this method create?
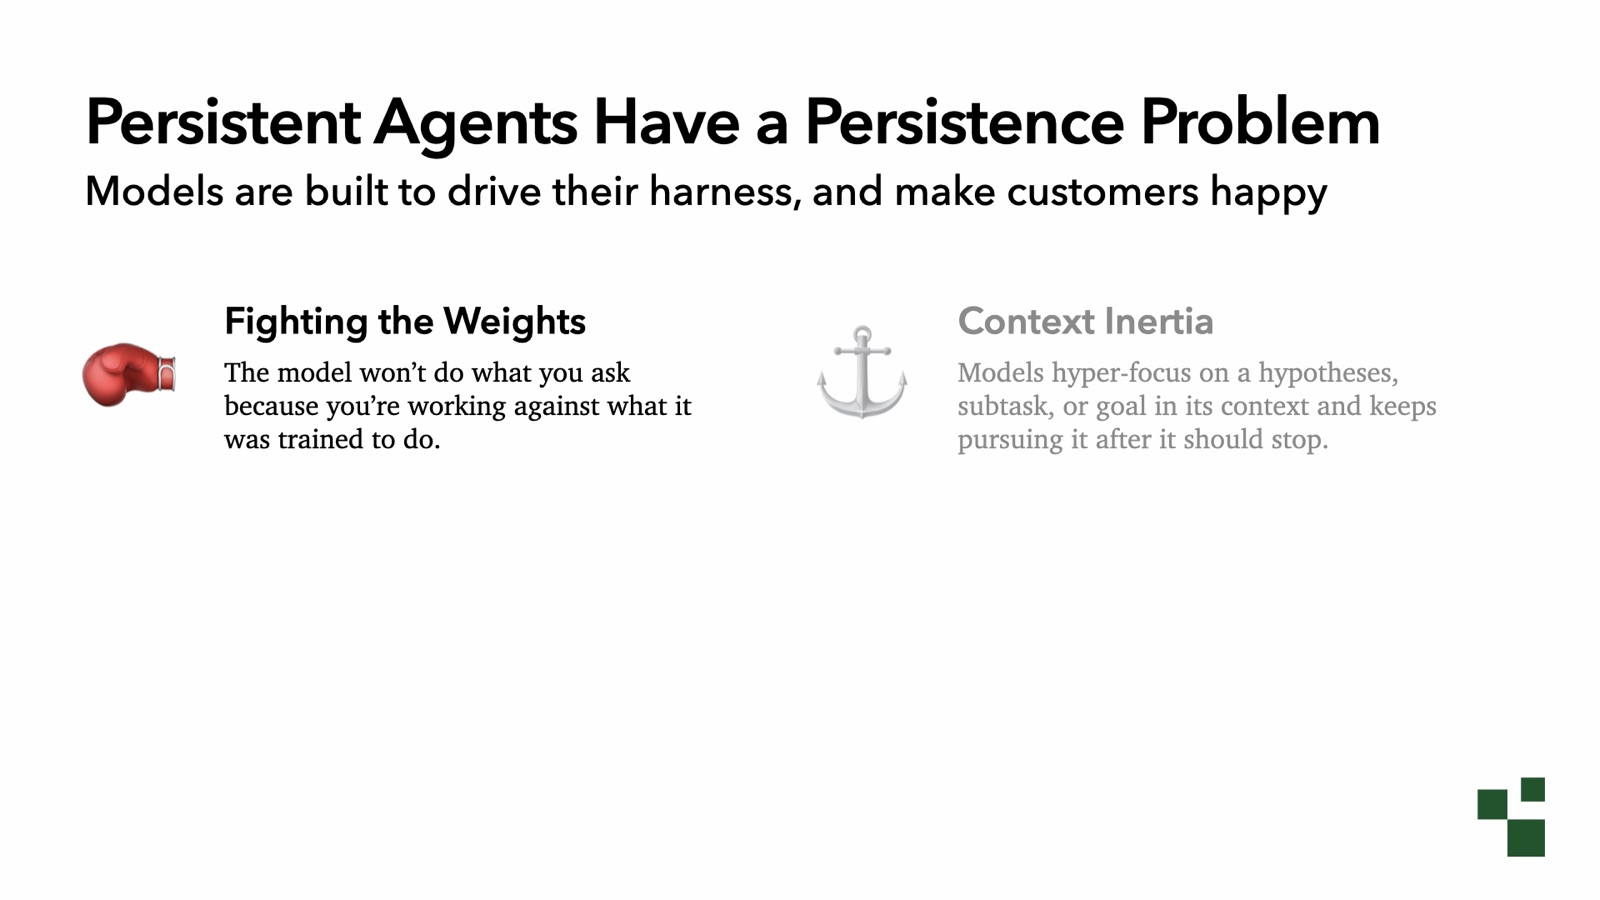
So far we’ve discovered two new failure modes.
When you practice fashions to make use of harnesses very well, you find yourself overfitting them to a selected set of instruments and environments they have been skilled inside.
How a lot of you have got used the Playwright MCP server, or one thing related? This is the MCP convention, so most likely fairly just a few.
Smaller fashions, one thing like Haiku or Luna, will usually botch this device name on the primary try, then recuperate and regulate the parameters. The surroundings it was skilled in had related instruments that seemed completely different than Playwright. Whatever Anthropic or OpenAI utilized in coaching. And you must battle towards these biases.
I name this fighting the weights: when the mannequin doesn’t do what you ask since you’re working towards what it was skilled to do.
It’s an actual downside, and it’s not only for us. The labs and the individuals constructing their merchandise must cope with it too.
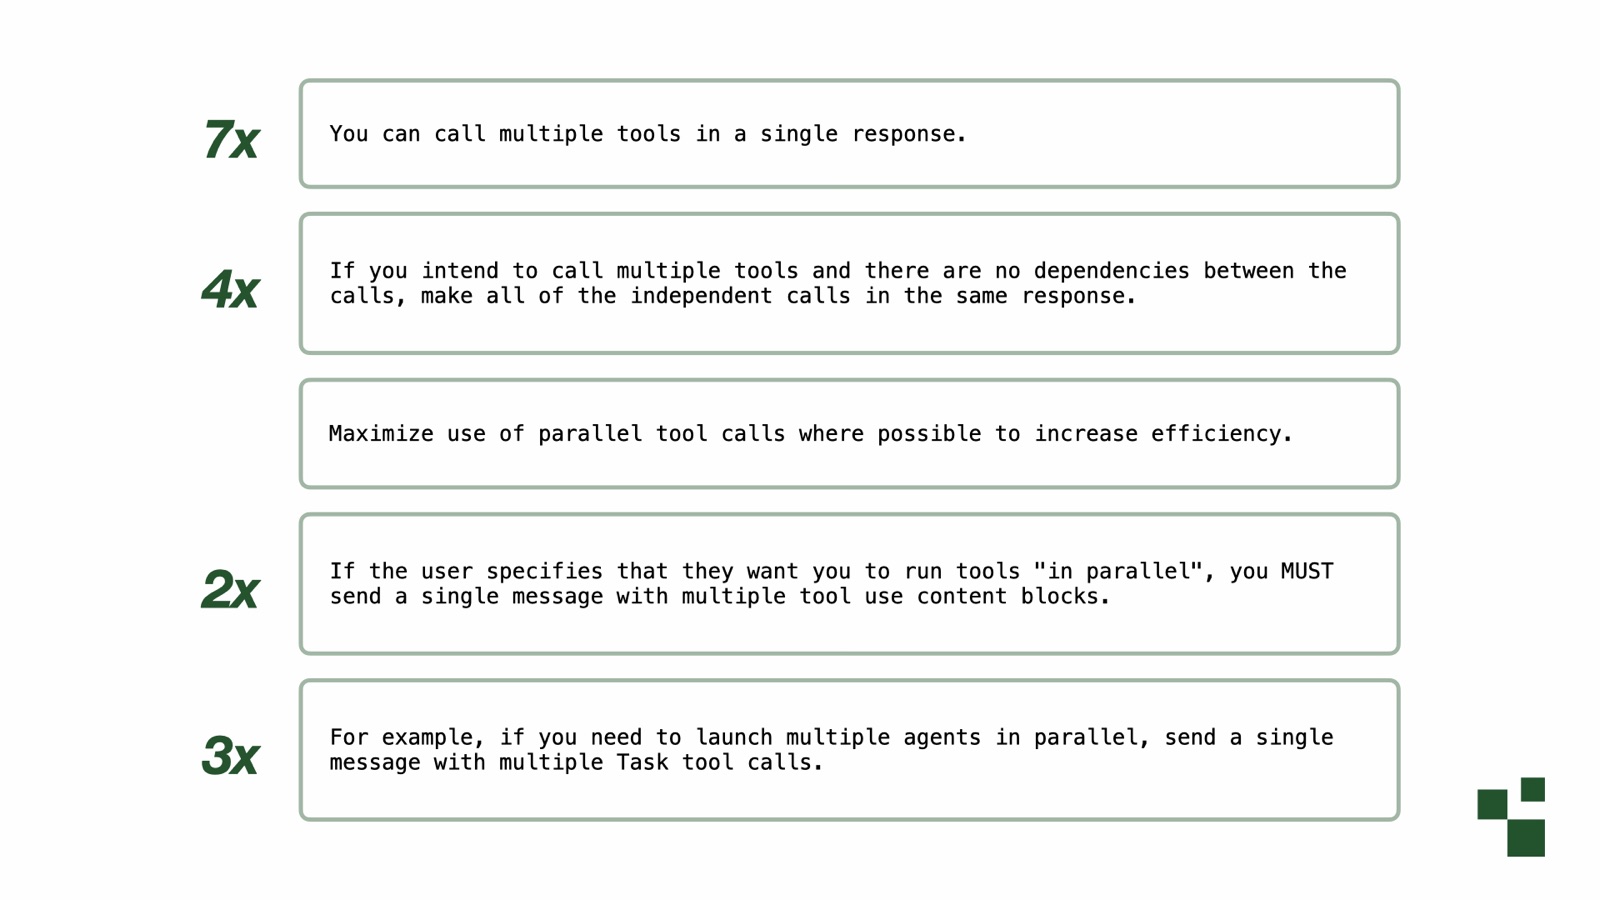
Here’s a chunk of the Claude Code system prompt and a few of its device directions.
The coaching environments these fashions discovered to make use of have been, for a very long time, largely serial. They’re changing into extra parallel, however once I pulled these examples, their biases have been in direction of serial behaviors. So Claude Code’s directions repeatedly say: no, no, no, we would like you to make use of parallelism. We need you to make a number of device calls on the identical time.
The directions repeat this time and again—seven occasions right here, 4 occasions there, two occasions, thrice: please make device calls in parallel once they’re unbiased.
When you crack open a immediate and see repetition and all-caps, there’s an excellent probability you’re combating the weights. You’re making an attempt to beat one thing the mannequin was skilled to do.
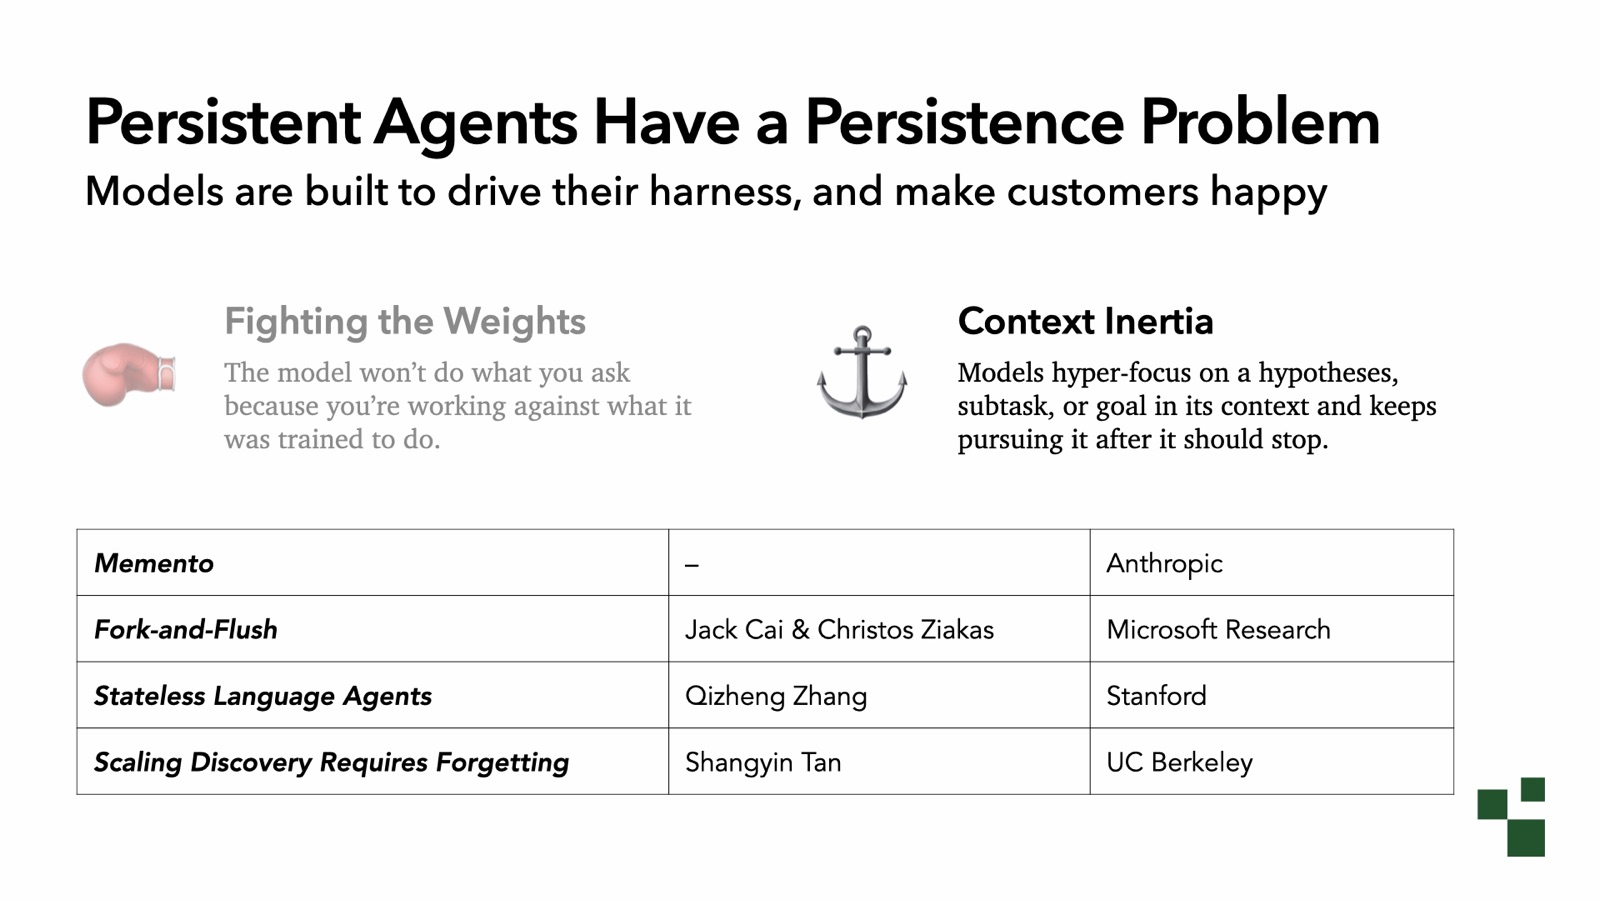
The subsequent downside is one thing we’ve solely began to doc just lately. In reality, 4 events landed on it simply final week.
I name it context inertia: fashions hyper-focus on a speculation, subtask, or aim of their context, and preserve pursuing it after they need to cease.
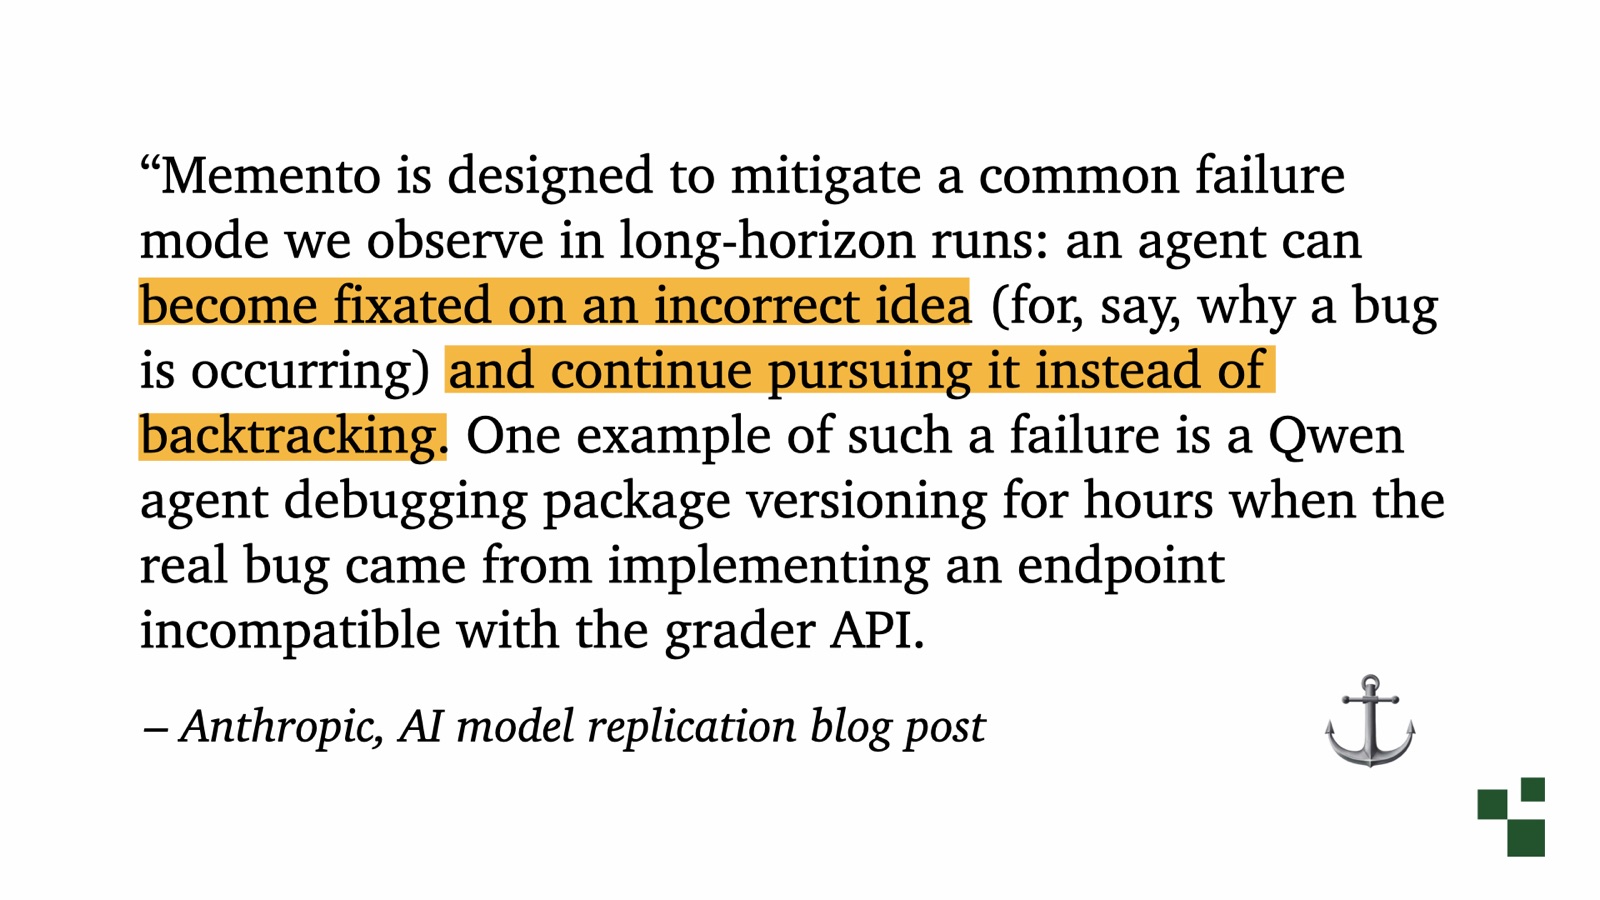
The first instance was from Anthropic. In their recent post about whether models are getting close to replicating and deploying themselves onto other machines, Anthropic wrote a couple of harness it used for these exams known as Memento.
What they discovered was that if the brokers ran too lengthy, they’d develop into fixated on one subtask or one proposed resolution and wouldn’t cease. They’d preserve making an attempt the identical factor.
Their repair is delightfully easy. Every hour and a half, the agent writes down a brief word, then its context is cleared. The surroundings is preserved. All the work it’s achieved remains to be there. But the operating dialog is gone, and it has to begin once more from a recent perspective.
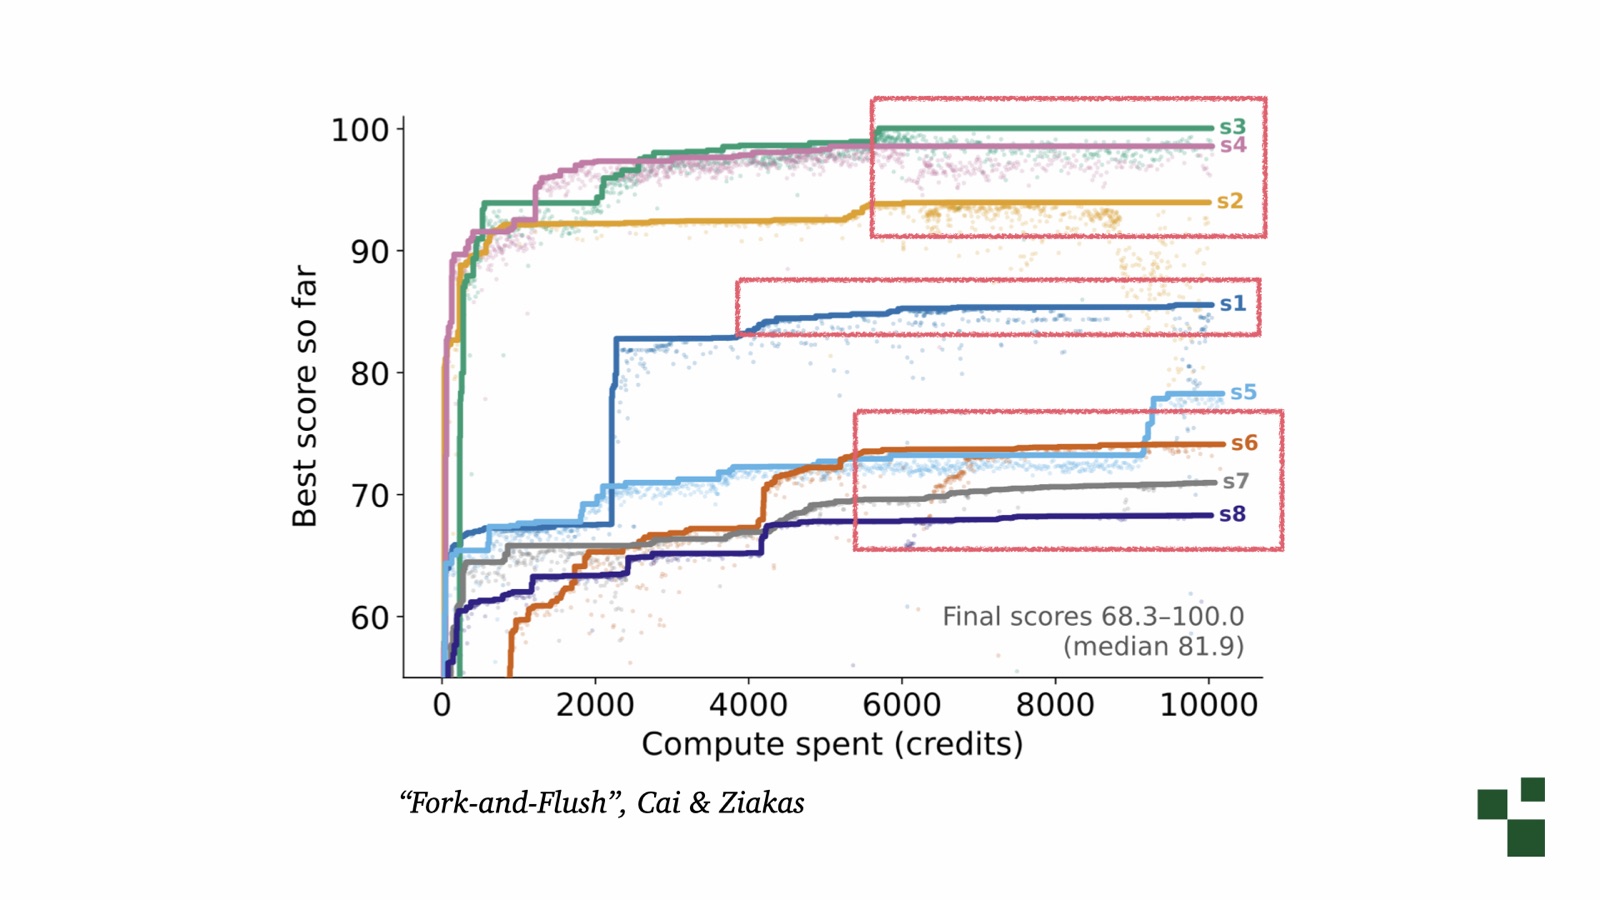
Another paper, from Microsoft Research, known as Fork-and-Flush.
If you’ve run autoresearch experiments, you’ve most likely seen charts like this. You make a giant achieve, then the road goes flat. You make one other massive achieve, then it’s flat once more. That’s compute, cash, and time going by with little or no enchancment.
When the researchers seemed intently, the brokers weren’t doing actually nothing. They have been making tinier and tinier adjustments. They had discovered an thought and have been hyper-focused on it, somewhat than looking for extra inventive options.
In a means, they develop into obsessive about their very own concepts. We’ve skilled them to be persistent and centered on a aim, as a result of that’s what makes an excellent coding agent. But the identical high quality can work towards them.
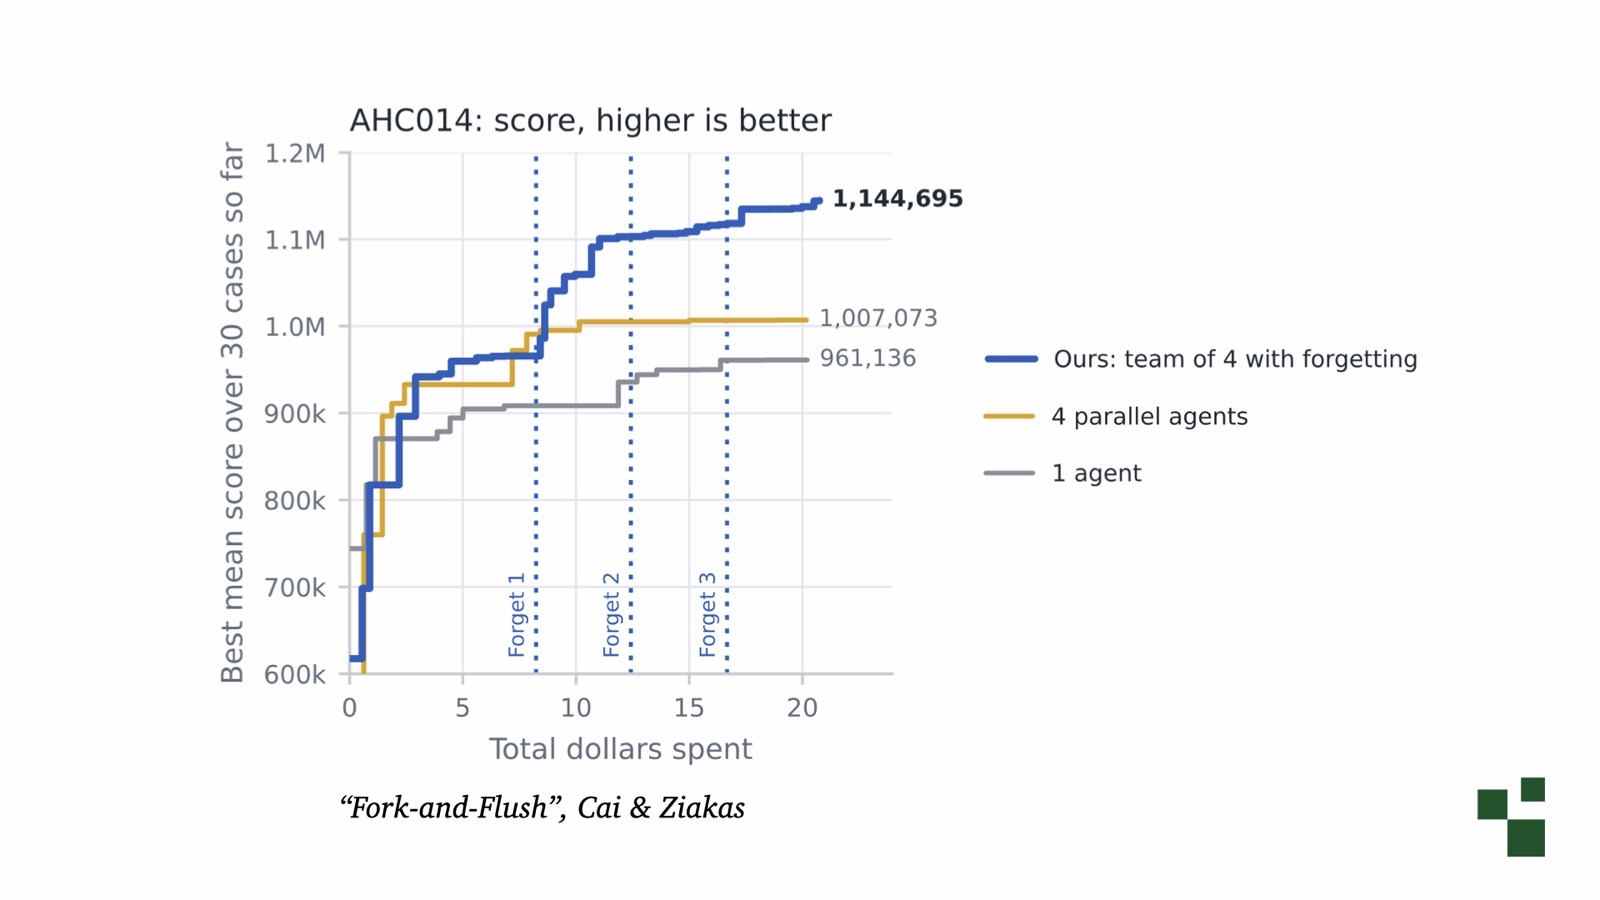
Here’s one other paper, Scaling Discovery Requires Forgetting, led by Shangyin Tan at UC Berkeley.
The researchers got here up with basically the identical thought: periodically clear the context whereas retaining the artifacts produced within the surroundings.
The blue line is the model with forgetting. Every time it clears the context, you see one other bounce in efficiency: overlook, enhance; overlook, enhance.
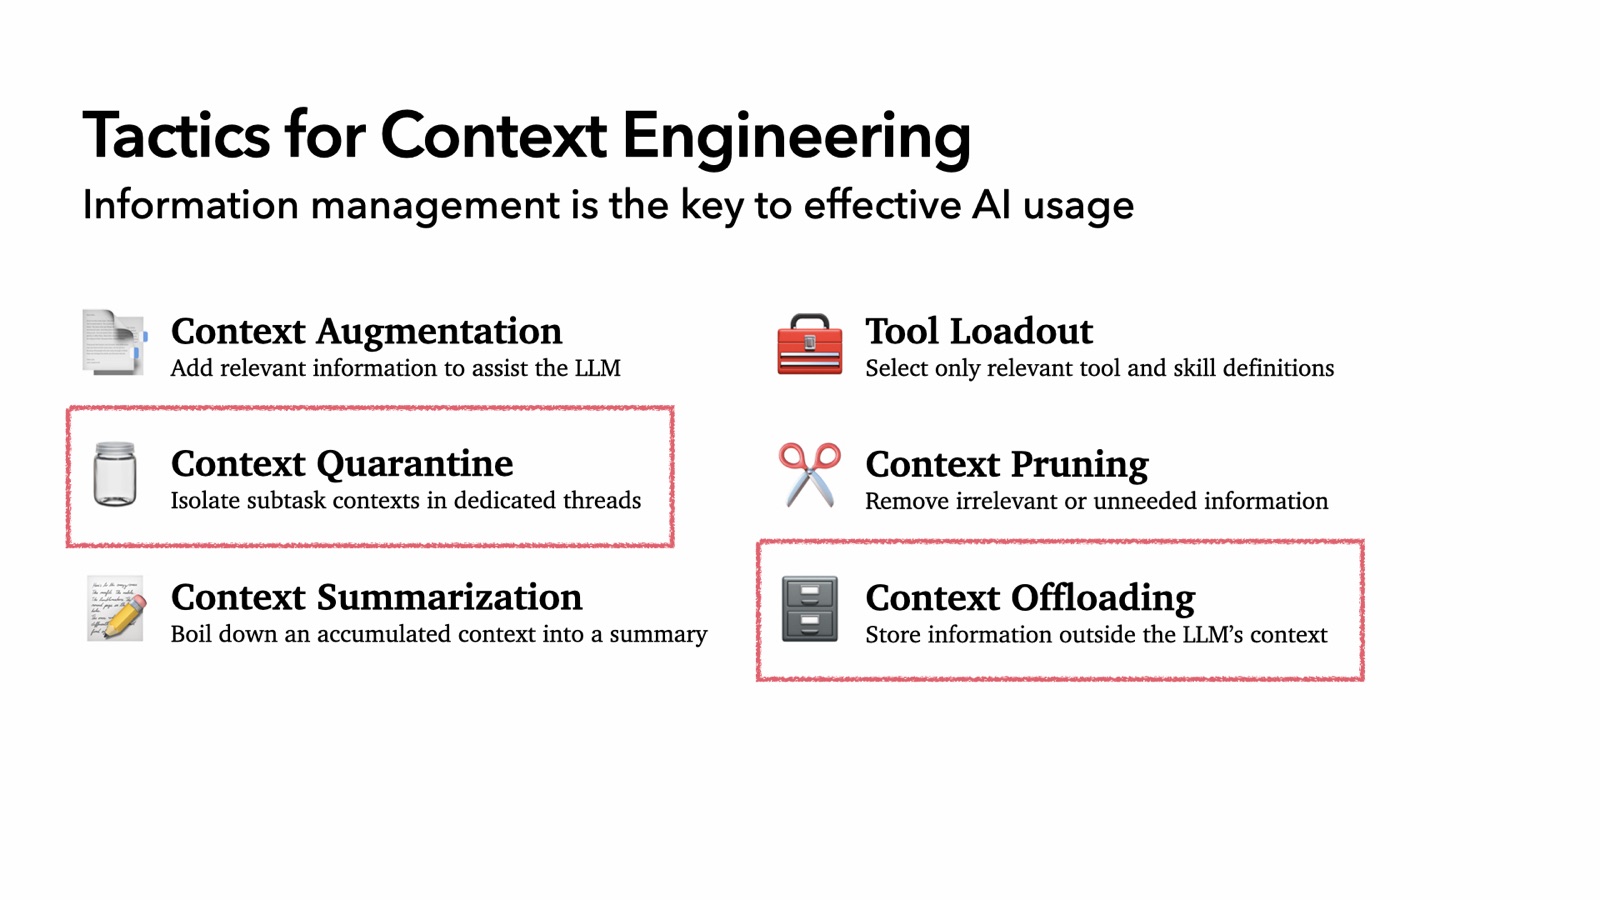
It’s superb that we’ve these brand-new fashions skilled for more and more advanced, persistent work, and we’re nonetheless utilizing the identical fundamental instruments. We haven’t found a wholly new context repair. We’re utilizing quarantine, offloading, and deleting the accrued historical past to take care of context inertia.
This is the recommendation I preserve giving now. Someone says, “My coding agent’s doing one thing bizarre. Claude’s been nerfed.” And I ask, “How massive is your context?”
“Oh, I’ve bought 800,000 tokens.”
Delete your context.
I’m not joking. Around 200,000 tokens is my warning level.
Have you tried resetting your context?
Sometimes that basically is the repair.
The options we construct into fashions create tomorrow’s issues. The fashions are getting higher, however so are our harnesses.
Longer context home windows allow us to carry in additional data, however in addition they allow us to usher in dangerous data. We had to determine methods to handle that, and we nonetheless get it improper.
Agentic fashions allow us to run longer duties and handle their context, however in addition they let duties run longer than they need to and ignore our preferences, as a result of they have been skilled for their very own harnesses.
So the place will the issue transfer subsequent?
What’s the large promise for 2027? What’s the subsequent factor fashions are going to supply that creates a brand new set of issues for everybody on this room to take care of?
(Unless you’re coaching your personal fashions. But it is a context engineering session, so most likely not.)
Here’s my prediction.
Think about all the non-public brokers: Hermes, OpenClaw, Dot, Bot, Muse, and related methods. Very few individuals have actually skilled these harnesses operating for greater than six months.
I’ve been operating a Hermes agent for six months. When you have a look at the talents it creates and updates, you begin to uncover that the options to your issues can worsen over time. The abilities accumulate all these bizarre fixes. They’re basic brokers: they resolve one process a method, then rediscover a unique technique to resolve one thing related. The directions and recollections begin to construct up and dispute with each other.
As we focus extra on reminiscence, we additionally want to consider strategic forgetting. Over time, overly exact recollections develop into conflicted and messy, and no person has but discovered methods to deal with this.
I believe that’s the context downside of tomorrow.
Every advance in mannequin functionality adjustments what we delegate to the mannequin and what methods should implement.
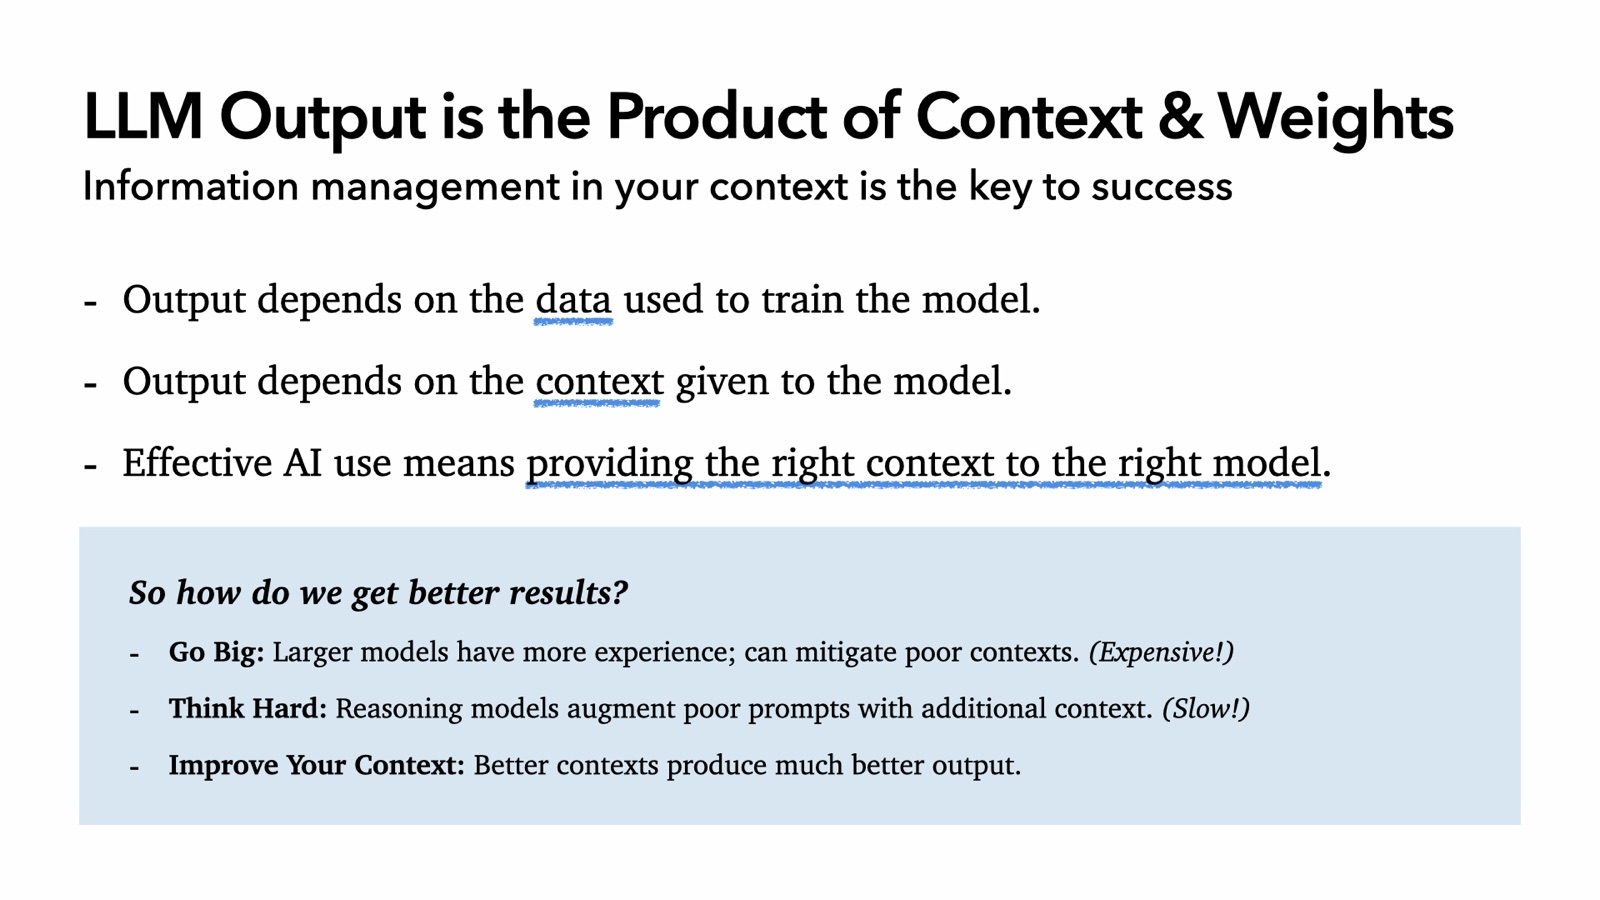
I made this slide for a deck for coaching enterprise groups, a couple of yr and a half in the past, and it stays true.
Our output is the product of the context and the weights.
Our output is determined by the information used to coach the mannequin. Understand it. Read the technical studies. Look at what the mannequin was skilled on and whether or not that’s related to your process. That helps you construct a psychological mannequin for debugging when one thing goes improper.
And our output is determined by the context given to the mannequin. That’s it.
So our aim is to provide the suitable context to the suitable mannequin. Either by our personal discrete selections or by the software program, the harnesses, we design.
You can use greater fashions, suppose tougher, or enhance your context. One of these is reasonable and quick.
When constructing clever purposes, harnesses, and workflows, our job is to decide on when to be deterministic (what to place in code) and when to be probabilistic (when to let the mannequin drive).