Qwenputer: a totally functioning, deterministic RISC-V CPU inside Qwen3.5
I am unable to imagine it is not silicon
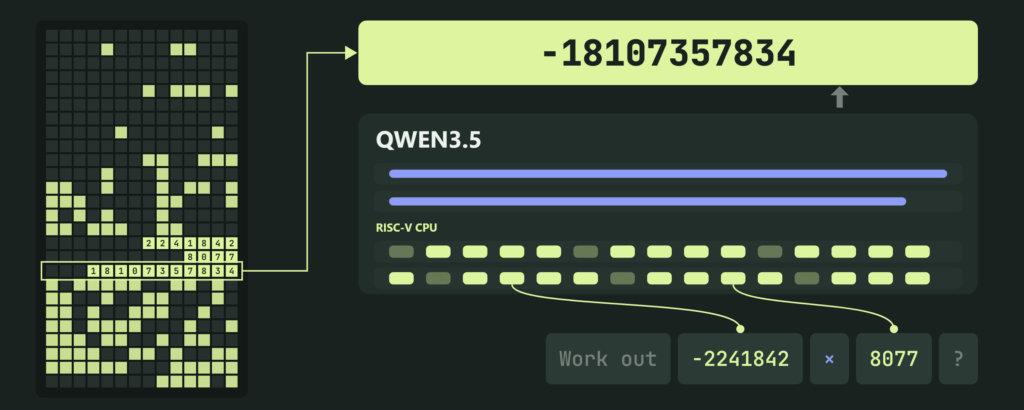
Qwenputer is a fairly enjoyable experimental mannequin. It’s a inventory Qwen 3.5 4B with one addition: a RISC-V CPU embedded inside the weights that makes use of the mannequin’s personal Gated DeltaNet consideration layers as RAM. (To find out how GDN works, here’s a handy guide.) This ‘CPU’ runs utterly inside the ahead passes of the mannequin, and might run arithmetic operations, C and MicroPython code with none exterior runtime or instrument utilization by any means.
To be very clear, it isn’t a plugin, a instrument or a sandbox. This weblog will clarify precisely how this mannequin works, and the way the mannequin utilises GDN layers as RAM, and the way I additionally slotted in an experimental in-model file storage.
I additionally wrote up two follow-ups constructed on prime of Qwenputer: how hybrid models can learn to hide their reasoning in their RNN state and evade CoT monitoring, and the way compiled weights like these can work as inbuilt monitoring tools that the model itself can’t tamper with.
You can seize Qwenputer from Hugging Face or ModelScope, and the code is on GitHub.
The RNN inside Qwen3.5 might be actual RAM
Qwen3-Next and Qwen 3.5 (the mannequin Qwenputer is constructed on) use a fairly neat trick. 3 out of 4 consideration layers within the mannequin use Gated DeltaNet, a linear RNN, as the eye mechanism (more on that here). Each head retains a state matrix, and the delta rule retains this up to date.
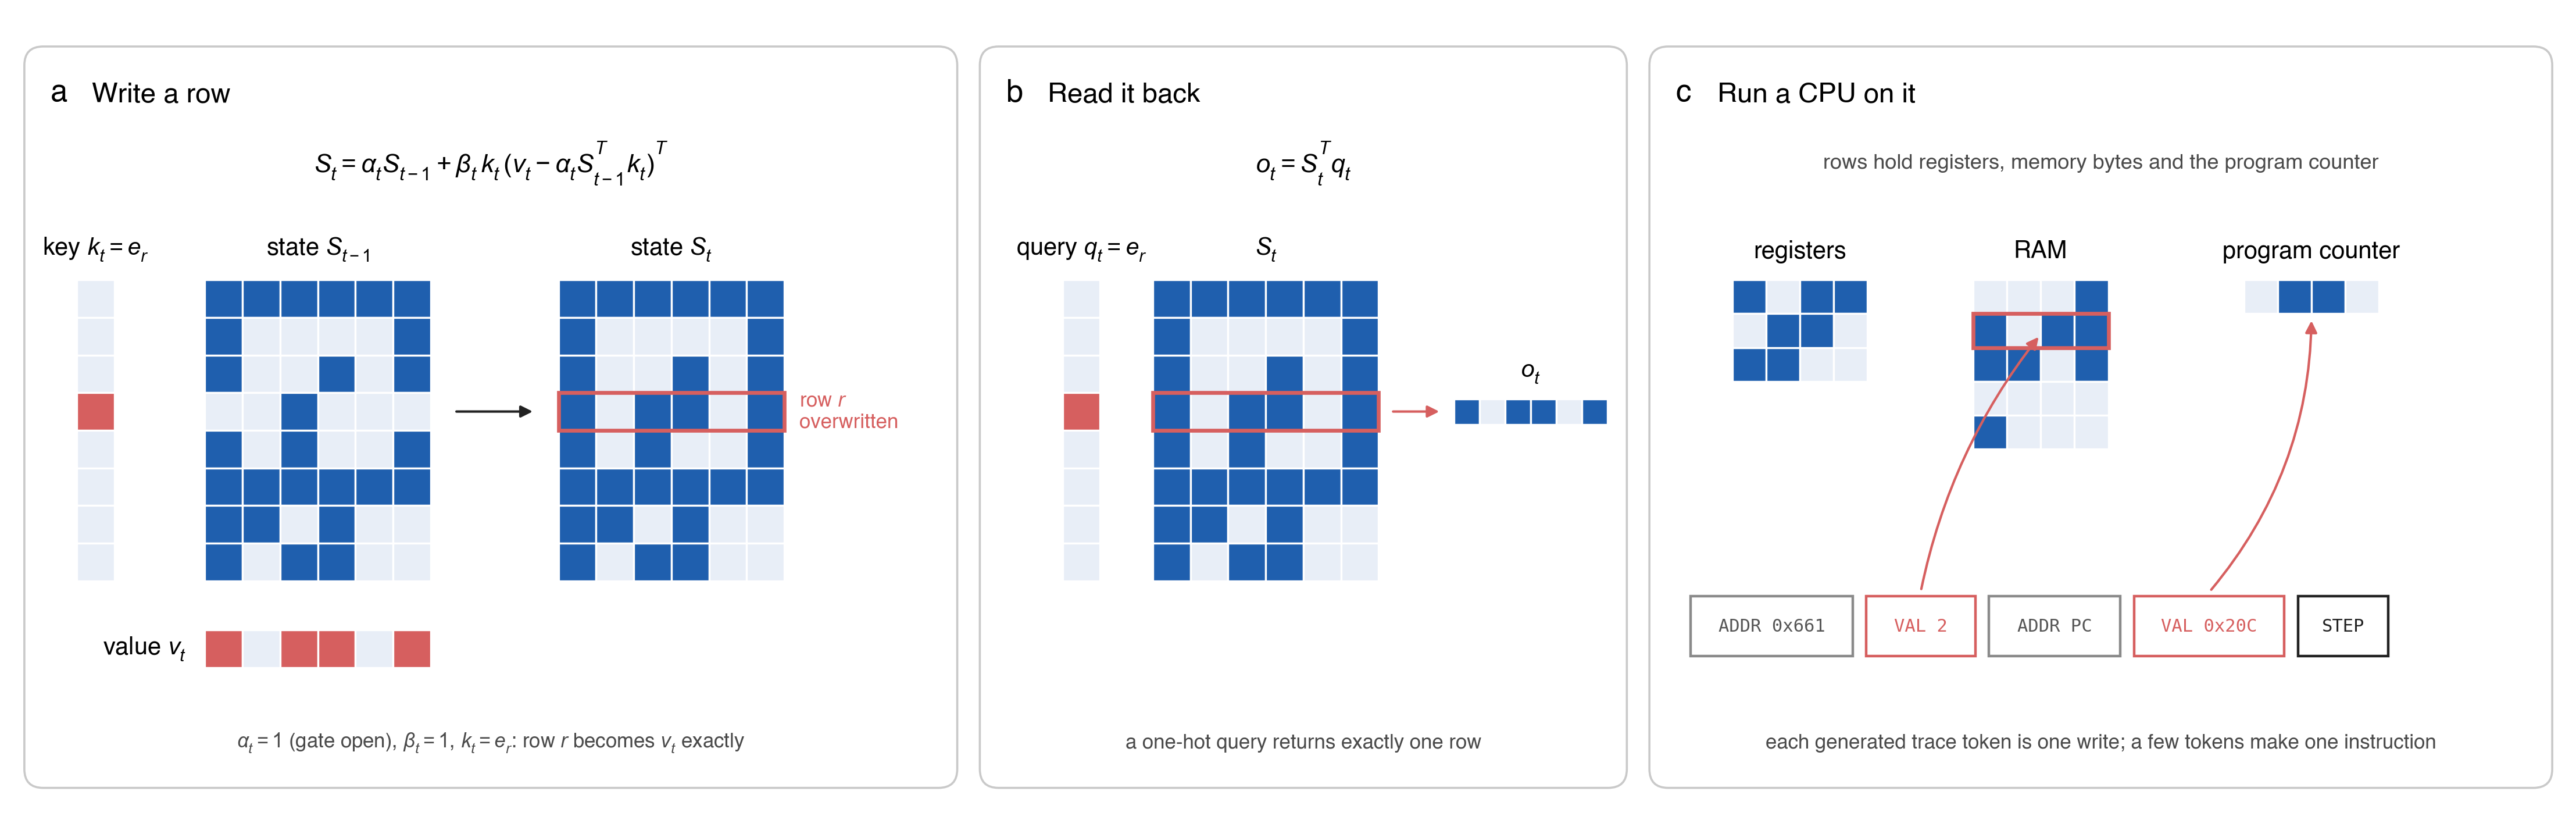
Now, this is the place our enjoyable experiment begins. I came upon that by setting the gate to 1,1 Each Gated DeltaNet head retains a state matrix, its reminiscence. At each token, earlier than writing something new, it multiplies the entire state by the gate, a quantity between 0 and 1. That’s how the RNN forgets: a gate of 0.9 fades every thing saved a bit on each token, and a gate of 1 means nothing ever fades. the write energy (beta) to 1,2 After the gate, the top nudges one route of the state in the direction of a brand new worth, and the write energy beta units how far. A beta of 1 means the outdated worth alongside that route is changed utterly as an alternative of blended. and utilizing one-hot key encoding,3 A one-hot secret’s a vector of zeros with a single 1 in it, so it factors at precisely one row of the state, the best way a reminiscence tackle factors at one cell. each write we carry out will overwrite precisely one row, and each one-hot question can retrieve an actual worth. This signifies that the GDN layers themselves can work precisely as RAM, at a far decrease price than utilizing regular consideration as RAM, since a GDN head’s state stays the identical dimension nevertheless lengthy the dialog will get, not like consideration’s KV cache.
The concept that the delta rule acts as a reminiscence is not new: Schlag et al. (2021) confirmed that linear consideration with the delta rule works as an associative reminiscence, or “quick weights”.4 Imanol Schlag, Kazuki Irie and Jürgen Schmidhuber, “Linear Transformers Are Secretly Fast Weight Programmers“, ICML 2021. The new factor right here is making it actual and addressable, inside a manufacturing mannequin, reliably sufficient to run a complete CPU on it.
This is the bottom on which this whole mannequin is constructed. As it stands, default Qwen 3.5 doesn’t hold actual values within the GDN. With this modification, we unlock the following a part of this experiment.
Compiling a pc into layers
Since we’ve got a totally useful, low-cost and quick RAM now, we are able to go forward with compiling a working CPU into the mannequin weights. Luckily, there isn’t any coaching concerned: a compiler units each weight straight. You describe the CPU as a circuit, an extended record of small steps like “learn this register”, “add these two numbers” or “bounce if zero”, and the compiler turns every step into a chunk of a transformer layer: consideration heads that look issues up, feed-forward models that do the arithmetic, and DeltaNet heads that maintain the RAM. The CPU then runs because the mannequin decodes.
Each instruction turns into a number of generated tokens: one names the reminiscence row to put in writing (ADDR), the following carries the worth (VAL), and a STEP token ends the instruction. Those tokens are the CPU’s execution hint, so whereas Qwen is producing them, the CPU is definitely operating.
The CPU
The CPU is a 32-bit RISC-V core (RV32IM, plus the Zba extension and a small bignum unit for big-number arithmetic), and it takes up 11 layers in entrance of Qwen’s 32. As it stands, it passes the official riscv-tests, its packages match qemu, and it has run 18 million directions free-running with out a single error.5 Free-running means the CPU retains going by itself outputs for the entire run, with no reference machine correcting it between steps.
This CPU can even run C and MicroPython code within the ahead passes fairly nicely (though a bit slowly). It shouldn’t be a Linux-class chip but, nevertheless it implements the total RV32IM instruction set.
How Qwen makes use of it
Qwen 3.5 4B is ready to use this CPU fairly nicely, with none post-training required. The CPU is used utterly internally, and never invoked by any exterior instrument calls.
In order to make the mannequin use this reliably, I made a decision to go a budget approach: by piggybacking on the instrument name format that fashions are fairly well-trained on, Qwen sends the CPU its directions and reads again the outcomes. No exterior instrument calls or runtime are used. Once our CPU receives the directions, the pc layers run, after which write the instrument response. We use a small driver known as RvChat to load the firmware into the GDN state, and this retains the hint tokens out of Qwen’s layers.
Qwen’s authentic weights keep precisely as they’re. The laptop weights are added on prime of them, in additional dims and layers.
Does it work?
I feel the principle query right here in your thoughts after studying by my incessant ranting will probably be: does this truly work?
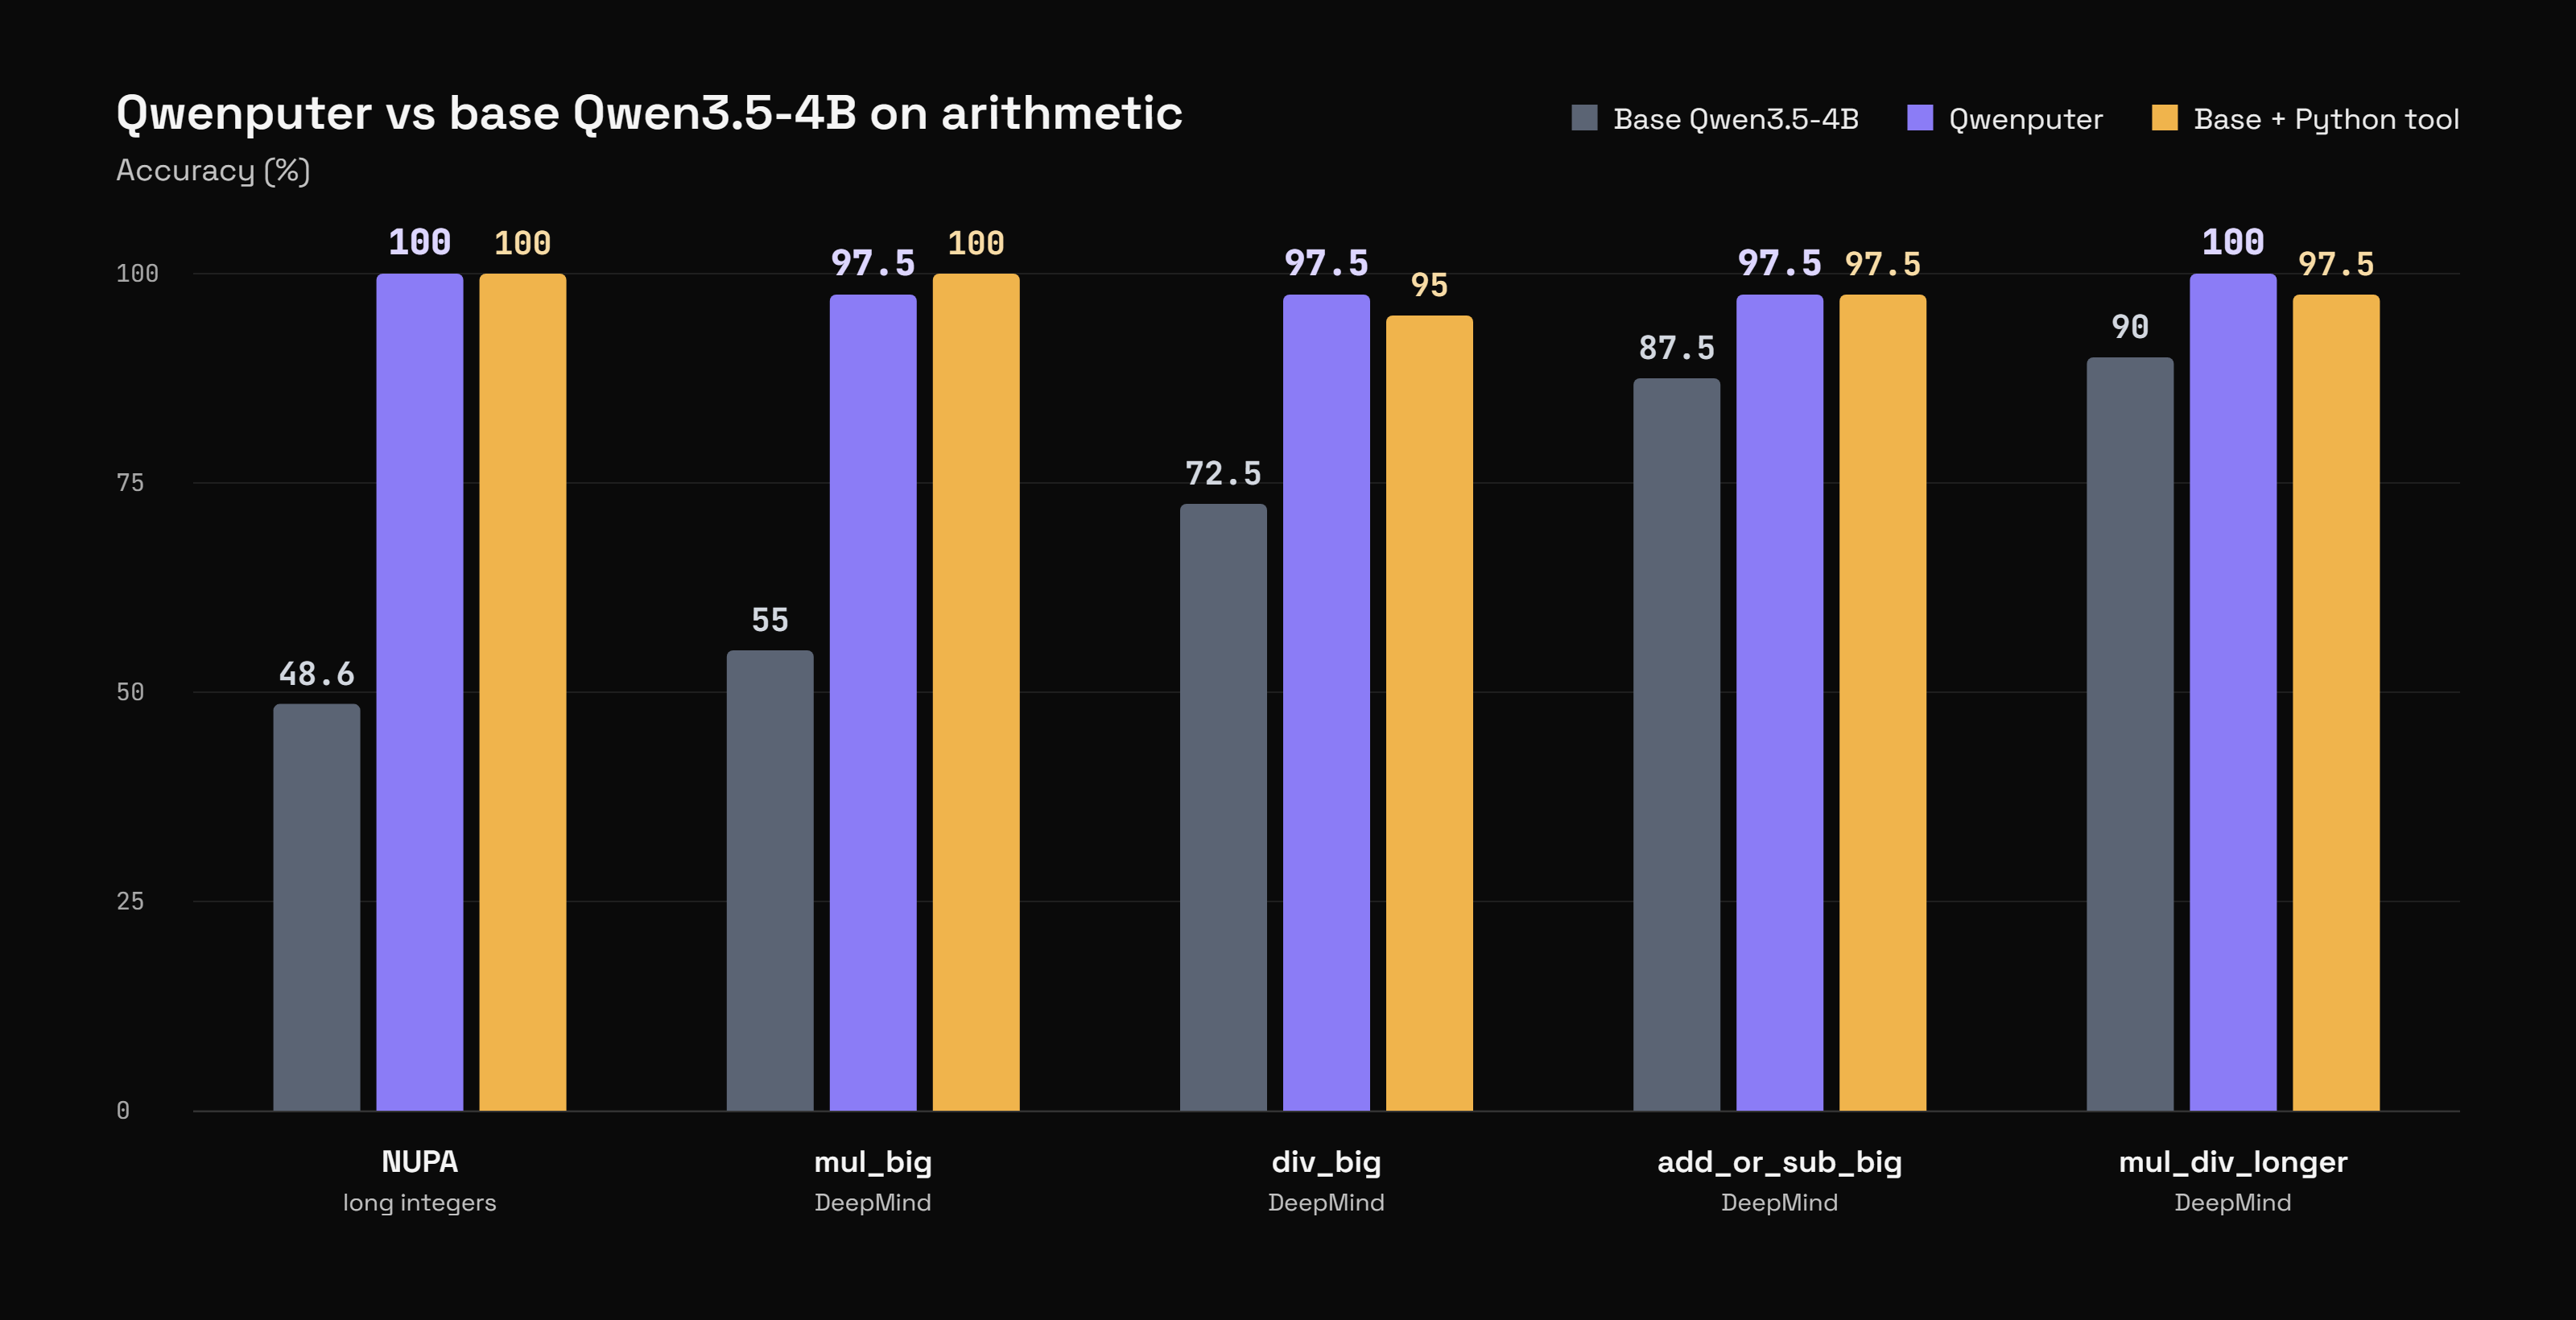
On the DeepMind units:
- div_big: Qwenputer scores 97.5%, versus 95% by giving Qwen 3.5 4B a Python instrument and 72.5% for base Qwen.
- mul_big: Qwenputer scores 97.5%, versus 100% with a Python instrument and 55% for base Qwen.
- mul_div_multiple_longer: Qwenputer scores 100%, versus 97.5% with a Python instrument and 90% for base Qwen.
- add_or_sub_big: Qwenputer scores 97.5%, the identical as with a Python instrument, and 87.5% for base Qwen.
On NUPA’s long-integer arithmetic, Qwenputer goes from 48.6% to 100%, the identical as giving Qwen a Python instrument.
The numbers the CPU prints are actual, too: I replayed about 230,000 of its output positions towards a reference machine and located zero mismatches. And bolting a pc onto Qwen would not change the way it talks: its regular textual content stays inside noise of base Qwen (KL 6e-4, towards a noise flooring of 5e-4).
A tough drive? In this financial system?
Because a CPU inside a language mannequin clearly wasn’t cursed sufficient, I made a decision the prudent factor can be to offer it a filesystem too.
Since we have already got a useful RAM, this was principally trivial. On the mannequin aspect, it is uncovered through inner put / append / get / record / delete operations. Once once more, no precise instrument calls. When Qwen ‘saves’ a file, the compiled layers hash its title into one in all 1,024 slots in a listing saved within the DeltaNet state, and retailer the textual content itself in different heads, with eight tokens per row, chained collectively. In situations the place two names find yourself touchdown on the identical slot, it simply checks the following one. Finding a file once more takes roughly two or three steps as an alternative of a scan, and it holds as much as 512 recordsdata, which comes out to about 53,000 tokens of textual content.
Fun factor is, that is fairly persistent. You can save the state on the finish of a dialog, load it into the following one, and the recordsdata are nonetheless there. Using this filesystem, Qwen will get details that modified between chats proper 90% of the time, towards 30% whenever you paste the outdated chats again in, and it is on par with giving Qwen reminiscence instruments run by Python (83.3% vs 78.9%). This one continues to be experimental, and its code lives on the rv-store branch, with the mannequin on Hugging Face and ModelScope.
Limits and what’s subsequent
Qwenputer could be very a lot an experiment, so a number of limitations. The additional layers and wider hidden dimension make the checkpoint 18.8 GB, roughly double base Qwen, though most of it’s zero padding. It additionally wants a small driver (RvChat) as well the firmware and hold the hint tokens out of Qwen’s layers, so it would not run with a plain generate() name but. And it is a bit sluggish, with each CPU instruction costing a number of decoded tokens, so a giant calculation takes seconds somewhat than milliseconds. The batched executor I used for the benchmarks runs about 3,200 CPU tokens a second on an L4.
Next up, I need Qwen to put in writing Python and run it on the MicroPython inside its personal weights, by a python() instrument that works the identical approach calc does. Making the CPU quicker is the opposite massive one.
Beyond arithmetic
Exact management over the RNN layers is helpful for a lot greater than arithmetic. It additionally makes Qwenputer a very nice testbed for AI security analysis, and I wrote up two follow-ups: how hybrid models like Qwen 3.5 can learn to hide their reasoning in their RNN state and evade CoT monitoring, and the way compiled weights can work as monitorability tools, like an in-weight monitor the mannequin cannot swap off, or reply keys for interpretability.
Try it
If you wish to play with it your self, the mannequin runs on a single 24 GB GPU. You’ll want uv and the Hugging Face CLI. You do not want a instrument server or a Python sandbox for the calculations: the CPU runs them contained in the mannequin.
git clone https://github.com/divagr18/qwenputer && cd qwenputer/experimental/riscv && uv sync --extra hf
hf obtain divagr1925/Qwen3.5-4B-Qwenputer --local-dir qwenputer-rv
uv run python -m chipformer.rv.chat qwenputer-rv --firmware checks/information/rv/calc-bridge.elf
    --ask "Use calc: what's 123456789 * 987654321?"
Everything is open: the code on GitHub, and each fashions on Hugging Face (Qwenputer, Filesystem) and ModelScope (Qwenputer, Filesystem).
If you employ it in your work, you’ll be able to cite it as:
@software program{agrawal2026qwenputer,
  writer  = {Agrawal, Divyansh},
  title   = {{Qwenputer}: a pc compiled into the weights of a pretrained language mannequin},
  yr    = {2026},
  url     = {https://github.com/divagr18/qwenputer}
}