Jalapeño Exhibits Energy of LLMs for Chip Design
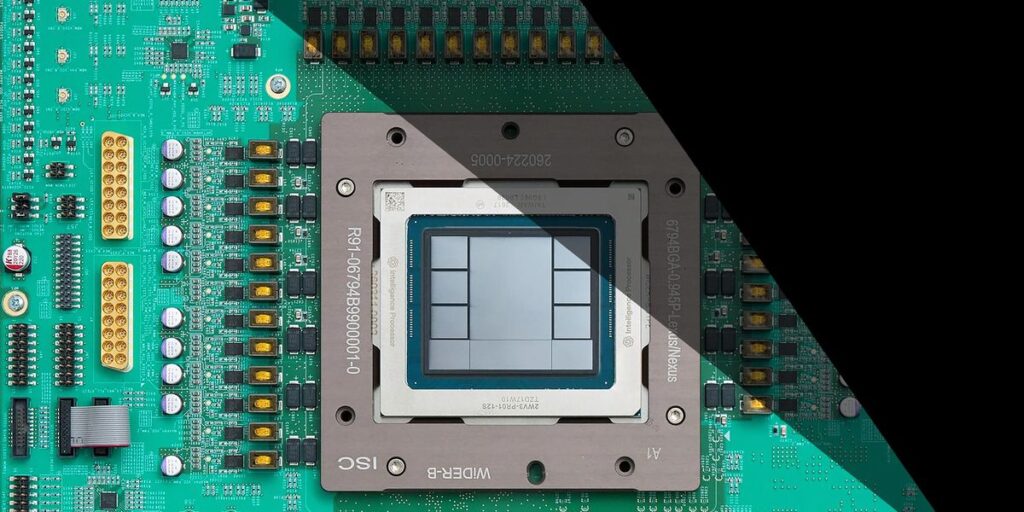

On 25 August, OpenAI absolutely unveiled Jalapeño, the corporate’s debut AI accelerator chip. Jalapeño delivers as much as 13.4 petaflops of 4-bit compute and accesses 232 gigabytes of essentially the most superior reminiscence accessible, linking to it at a blazing 15.4 terabytes per second. Benchmarks cited by OpenAI present that Jalapeño can cut back end-to-end latency (the time between immediate to final token) by as much as 3.6 instances when in comparison with Nvidia’s GB300—a chip the corporate at the moment depends on—and accomplish that whereas consuming much less energy.
Whether these figures translate into real-world features as soon as Jalapeño enters widespread service in OpenAI’s inference fleet stays to be seen, however efficiency is just half the story. The different half is how the chip was designed—a course of which, as you would possibly count on, was accelerated by OpenAI’s large language models (LLMs). Jalapeño moved from first structure idea to first silicon in underneath 20 months. Only 9 months separated the primary RTL—the register-transfer stage code defining the chip’s logic—from tape-out, when the completed design goes to manufacturing.
That’s a fast timeline, but consultants imagine it might quickly look gradual as LLMs enhance and develop into extra deeply built-in into chip design instruments. OpenAI, unsurprisingly, is bullish in regards to the alternatives. “The fashions are giving superpowers to our engineers,” says Richard Ho, vp of {hardware} at OpenAI. “Our engineers are nonetheless driving the work. They’re nonetheless the ultimate arbiter of what’s occurring. But they’ll do issues loads quicker. They can discover much more paths.”
OpenAI achieved quick outcomes with a small design group
Ho says the group that designed Jalapeño averaged fewer than 100 folks over the course of the venture and continues to face at roughly 100 right now because the group pursues second and third-generation designs. That quantity features a broad swath of roles throughout the {hardware} group, from system design to software program and provide chain, however not these at Broadcom, which partnered with OpenAI on the venture.
The division of labor between OpenAI and Broadcom was usually break up between design and implementation. OpenAI’s group was chargeable for end-to-end system design together with the inference accelerator, the reminiscence hierarchy, and networking. Broadcom dealt with “bodily design from the gates onward,” Ho says.
The partnership with Broadcom dampened some opinions on OpenAI’s pace. David Chin, co-founder at agentic chip design startup Verkor.io, says “the schedule they gave us is sort of credible,” however believes that Broadcom’s assist was important to Jalapeño’s fast timeline. “If you may have any person else begin from scratch, it gained’t be potential,” he says. Ravi Krishna, additionally a co-founder at Verkor, referred to as OpenAI’s pace “a comparatively spectacular outcome,” however added that he expects that enhancements within the capabilities of LLMs might end in even faster timelines if the venture began right now.
Andrew Kahng, distinguished professor on the University of California, San Diego, additionally discovered OpenAI’s pace notable, saying it’s “possible greatest at school right now.” Kahng remembers a 2016 IEEE Design Automation Futures workshop, which he co-organized. The workshop included Richard Ho, on the time an engineer at Google, as a keynote speaker. Ho had sturdy opinions on design automation and framed the time required to finish a chip’s design as a perform of the variety of iterations a group might full in a day.
How OpenAI’s LLMs accelerated Jalapeño’s design
“Automation itself has existed in chip design for a lot of a long time. It’s not a brand new drawback,” says Ankur Srivastava, director of semiconductor initiative and innovation on the University of Maryland, in College Park. Where LLMs differ from prior automation instruments, nonetheless, is their capability to know language and code. He says this makes them notably suited to chip design duties that “are nonetheless within the linguistic area of the issue.”
The group at OpenAI designed a workflow that takes benefit of this energy. OpenAI’s front-end workflow was constructed round Accelerated Hardware Synthesis (XLS), an open-source high-level synthesis chain of instruments initially developed at Google. High-level synthesis is a type of chip design automation that permits engineers to design a chip in a extra acquainted programming atmosphere. In the case of XLS, chip designers can write in languages equivalent to DSLX (a domain-specific language impressed by Rust) and C++. XLS then converts these to Verilog, a {hardware} description language used to explain digital methods.
“We have been interested by easy methods to leverage AI to make the venture quicker, and the AI was a lot better at software-looking issues,” says Chris Leary, member of technical employees at OpenAI. “XLS in some methods seems like software program, so it obtained that profit.” It helped, too, that Leary was extraordinarily conversant in how XLS ought to perform, as he began it throughout his time at Google.
Kahng agrees that the choice to make use of AI to speed up high-level synthesis, equivalent to XLS, is smart, because it’s “extra pure for the LLM to work with” and gives the chance for quick iteration. “I see this as a usually helpful workflow, and it’s one which ‘has legs’ going into the long run,” he says.
The identical logic led the Jalapeño group to deal with software program optimization. When the primary chips got here again from the foundry in May, the group pointed its inside AI models at designing software program to run benchmarks equivalent to SemiAnalysis’s InferenceX. On DeepSeek’s multi-head latent consideration kernel benchmark, efficiency climbed from 0.31 p.c of the theoretical ceiling (set by the chip’s compute and reminiscence bandwidth) to 88.94 p.c in roughly 40 hours. Ho says this result’s repeatable, so the time between when foundries ship the primary chips and when manufacturing ramps up might be decreased. “All our schedule assumptions are going to be based mostly on the very fact we’ve this functionality now,” he says.
Jalapeño is designed for deployment in pods that embrace 2,048 chips.OpenAI
While the broad strokes of the Jalapeño groups’ AI-assisted workflow have been guessed by Ho and Leary up entrance, enhancements in OpenAI’s fashions did supply a couple of surprises.
Leary says that the venture started with help from fashions like OpenAI’s o3, which was launched to the general public in April of 2025 (however accessible to the Jalapeño group earlier). By the time the venture had wrapped up, nonetheless, the group had entry to fashions that have been precursors to GPT-6 Astra, which wasn’t publicly launched till 3 September 2026. The newer mannequin can work immediately in Verilog without having XLS’s translation from extraordinary programming languages, and it’s near with the ability to function proprietary design instruments by itself, Leary says.
Ho additionally confirmed that the group had entry to inside LLMs fine-tuned for chip design that aren’t accessible to the general public. He declined to element the fashions used. However, he added that the Jalapeño group partnered with OpenAI’s analysis group. While not all particular fashions used to design Jalapeño are publicly accessible, Ho says the aim is to carry classes discovered from the venture into the corporate’s industrial LLMs. “It’s protected to say that Astra and following fashions will likely be excellent at chip design,” he says.
AI was much less helpful for backend optimization, however that might change
As talked about, the majority of OpenAI’s work on Jalapeño targeted on the “entrance finish” of chip design, which spans the duties that take a chip from preliminary idea, via writing RTL code to outline the design, and thru verification that the design will work when bodily carried out. Much of the “backend” design—which incorporates duties like routing interconnects, finishing and verifying the clock and energy specs, and sending the required design data to the foundry—was handed off to Broadcom, which carried the chip via manufacturing.
That’s to not say OpenAI’s workflow ignored the backend, although. The Jalapeño group consists of bodily design engineers who work with their counterparts at Broadcom to supply steering on the chip’s floor plan and routing, amongst different issues.
At IEEE Hot Chips 2026, Ho and Leary put numbers on the features from AI-guided bodily design optimization, together with an space discount of 10 p.c for the matrix multiplication items as measured in opposition to an optimized human baseline. In different phrases, OpenAI claims AI-guided optimization helped design extra circuits into the identical space of silicon than would have been potential earlier than.
Broadcom used its personal inside workflow. The firm’s group didn’t have entry to the inner fashions OpenAI used to assist design Jalapeño, nevertheless it did have entry to OpenAI’s public, industrial fashions.
Verkor’s Ravi Krishna says that OpenAI’s strategy to backend design already feels a bit conservative. He believes that to be an artifact of when the venture, which started in October of 2024, passed off. “The fashions from the final 4 to 5 months have improved. From April [2026] onwards…is once they actually began to have the ability to deal with these duties higher,” he says. Verkor co-founder Suresh Krishna agreed, saying “there’s no motive you couldn’t have an agentic loop that largely accelerates the backend of the method as nicely.”
Ho and Leary additionally hinted that the workflow used to design Jalapeño could look old style in comparison with the group’s subsequent efforts.
“As you’ll be able to think about with [Jalapeño], we have been making an attempt to go as quick as we might. So there’s a trade-off between ‘will we wish to take time to do some innovation, or will we wish to do issues that we all know work traditionally?’” Leary says. “With the second technology, we’ve a form of reset alternative to ask about all of the issues we wish to get arrange for.”
Ho says the second-generation chip’s workflow has “a variety of locations that we’re introducing [AI].” He mentions alternatives to do extra with AI in verification and bodily design. Leary provides that the group now has instruments for automated waveform manipulation and viewing. This automates evaluation to determine chip clock indicators related to failures and will enhance debugging the {hardware} whereas it’s nonetheless being designed.
Despite these anticipated enhancements, Ho and Leary have been clear that they don’t imagine chip design might be absolutely automated. “We’re not saying that anybody can come and simply construct state-of-the-art, frontier AI/ML accelerator chips utilizing simply [OpenAI’s coding platform] Codex,” Ho explains. “We are saying some very particular issues about easy methods to be higher at Codex and the way we’re specializing in a small group and quick timelines to achieve high quality outcomes.”
From Your Site Articles
Related Articles Around the Web