Could a modern chess engine on a Pentium have defeated Kasparov in 1996?
On February 10th, 1996, a computer program (IBM’s Deep Blue)
defeated the reigning chess champion (Garry Kasparov) in a game of chess for the first time.
Deep Blue would go on to lose the match,
but a year later, would get its revenge in a 3.5-2.5 rematch.
In order to achieve this feat, IBM spent several million dollars on research and
development building a special-purpose computer specifically for this purpose.
Deep Blue itself (the victorious, upgraded version)
was powered by 30 P2SC processors each running at roughly 120 MHz,
and (most importantly) 480 custom VLSI chess co-processors used to perform chess-specific
operations like move generation and position evaluation.
When it was built, Deep Blue was the 259th most powerful supercomputer in the world,
and could analyze over 200 million chess positions per second.
But was Deep Blue necessary to beat Kasparov?
Or could we have gotten away with an off-the-shelf 1996 desktop
running a smarter chess engine?
As it turns out, we could easily have beaten Kasparov without building Deep Blue, using only commodity hardware,
and it (almost certainly) wouldn’t have even been close.
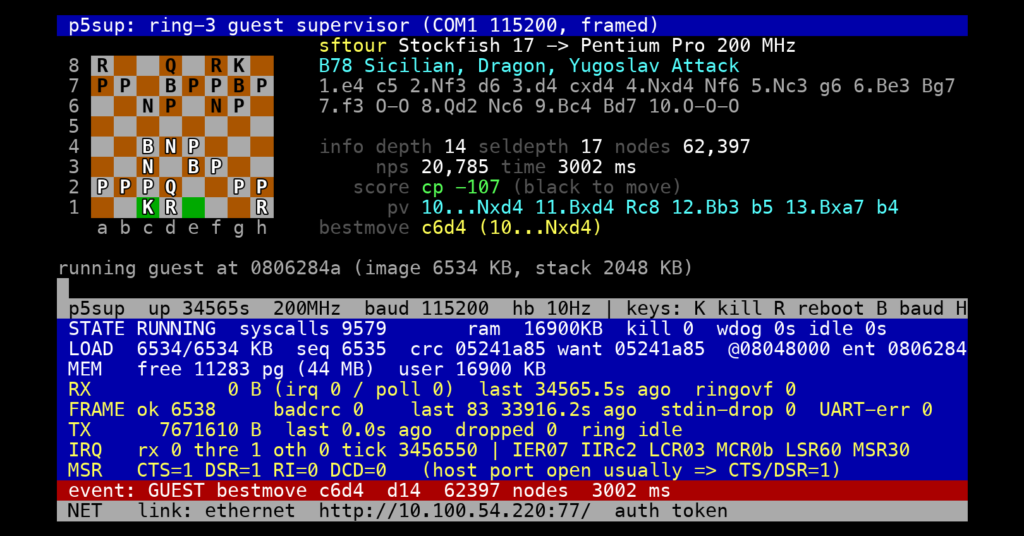
I know this because, as I write this very sentence, I have sitting next to me a
200 MHz Intel Pentium Pro (released exactly 31 years ago—November 1st, 1995) with 64MB of RAM
running a custom port of Stockfish that plays at an estimated Elo of
3300 ± 87 at classical time controls—far beyond the strength of any human, or indeed Kasparov’s Elo of just under 2800.
But wait, there’s more! I’ve hooked this machine up to the internet with a Realtek RTL8139C Ethernet card,
so you can play it below!
Connecting to the Pentium…
wait, what?! how??
There are three ways to get stronger at chess: you can
analyze more moves, analyze better moves, or analyze moves better.
Famously, humans improve by doing the latter two:
the average chess grandmaster during a classical game will analyze roughly the same number
of moves as an amateur player, but they analyze only the most critical moves and
do a better job with that analysis.
Chess engines like Stockfish, running on silicon instead of our human brains,
dominate us at the first of these
and analyze millions of positions per second.
And because there's not that much room for micro-optimizations on modern engines that will let a given
CPU process more positions per second,
most progress in chess AI also tends to follow how humans improve and finds better methods
for selecting moves and analyzing boards.
Skill in chess is measured by an Elo score.
A difference of 200 Elo means that you should expect the stronger
player to win three out of every four games, and multiplicatively from there: a 400 Elo gap corresponds
to a 90% expected score and a 1000 Elo gap gives a 99.7% expected score.
The best chess engines that you could run on commodity 1996 hardware were rated roughly 2300 Elo.
Deep Blue was rated 2700.
In contrast, modern Stockfish is rated closer to 3700.
This raises the question: how much of the advantage of a modern chess engine comes down
to the fact that a modern desktop computer is extremely fast, and how much of the
advantage comes down to the fact that we've just gotten better at programming chess engines?
As it turns out, the majority of the Elo gains (+720 of the +1335 gained) can be attributed to better programming,
and not better hardware.
To test this, I ran two experiments.
The first experiment uses Crafty, a competitive engine from 1996
whose source code is now available.
On my Pentium Pro, the 1996 build of Crafty version 11.13 has an Elo of 1999 ± 90 at 1 second per move, and 2383 ± 77 at 10 seconds per move.
On modern hardware (a Ryzen 7) this engine's Elo jumps massively to 2614 ± 97 at the same 1 second per move.
But if I take this engine and slowly start to add all the knowledge we have about
how to design better chess engines---adding modern search algorithms like fail-soft, LMR, correction history; adding better quiescence methods; and adding neural-net evals (NNUE)---then you can
increase the Elo up to 2718 ± 34 on the Pentium Pro at 1 second per move, and 2974 ± 74 at 10 seconds per move.
In the second experiment I go somewhat further: instead of trying to update Crafty, let's just try to get Stockfish---the
best chess engine today---running on 1996 hardware and see how it does.
This takes some work
and is mainly a matter of rewriting the
code so that it uses 32-bit arithmetic (a PPro is a 32-bit machine) and doesn't
use more than 64MB of RAM.
This naive port has an Elo of roughly 2496 ± 64 at 1 second per move (2940 ± 76 at 10 seconds per move).
But we can do better! A modern Stockfish engine is designed to run on a modern CPU.
By making a number of adjustments to the algorithm and tuning it to the Pentium,
we can increase its Elo to 2846 ± 35 at 1 second per move,
3109 ± 79 at 10 seconds per move,
and 3180 ± 80 at 30 seconds per move.
The most concise way to summarize all of the above is just to have them play a match of 100 games against each other.
And when I do this, I find that a modern chess engine running on a 1996 Pentium Pro
wins 78, draws 17, and loses 5 games against
the 1996 Crafty engine running on modern hardware.
The remainder of this article provides the details.
Technical details: Hardware & OS
There's not much to say about the hardware, to be honest.
I bought a used ("vintage" said the listing; I feel old.) desktop PC with standard period-appropriate hardware.
The desktop is running a 200 MHz Intel Pentium Pro connected
to an Intel VS440FX motherboard with 64MB of SIMM RAM clocked at 66 MHz.
The operating system boot off of a 1.44MB 3.5 inch floppy disk,
and connect to the Internet via a Realtek RTL8139C.
I also have a 1MB Trio64V+ graphics card connected over VGA to my monitor,
with input coming from a PS/2 keyboard---but I don't much use either of those and instead
communicate with it over a serial port connected to my modern desktop.
For those readers who may not be able to appropriately contextualize this hardware,
a 200 MHz Pentium Pro sold for $1,325 at launch in November 1995,
and four 16 MB SIMMs would have cost about $2,000.
Add on the other peripherals, and this machine would likely have gone for about four or five thousand dollars.
So it's a nice workstation, but by no means a supercomputer.
However, given the rate of depreciation and the exponential rate of improvements to hardware,
this same machine in 1997, when the second match occurred,
would likely go for just a thousand dollars (because who would want to buy
a Pentium Pro when the better-in-almost-every-way Pentium MMX was now available for just $400?)
The interface between the chess engine and the internet is a custom-built "operating system"
whose sole job is to spin up the chess engine and connect it directly to the networking card.
(Throughout this article, when I say "I wrote", what I really mean is "I asked an LLM to write".
I used a combination of Fable 5.1, Opus 5.5, and GPT-6.)
It's designed to be as compact as possible: the operating system (which, in fact, is more like
a hypervisor, or something) is sitting on a bootable floppy disk.
Its sole job is to boot the Pentium Pro into 32-bit protected mode,
initialize the networking card,
and await further instructions.
I can then send it any arbitrary "userspace" guest program that I want into RAM and it'll
boot that up and start running it.
The chess program I wrote starts up a custom-built HTTP server which waits for
incoming HTTP requests with a given position (as a FEN string)
and maximum run time, and on each request runs the engine until the timer expires, and returns a response.
Technical details: Software
As mentioned earlier I (again: a language model) actually modified two engines.
The stronger of the two is powered by Stockfish adapted to run efficiently
on a thirty-year-old processor.
It plays at an estimated Elo of 3300 at classical time controls
, high enough above Kasparov's 2800 Elo that we should expect Stockfish-1996
to come out ahead with a score of roughly 9/10.
The (only slightly) weaker engine starts with the source code to Crafty 11.13,
and is brought forward in time by adding all the lessons we've learned about how to
write a better chess engine over the past thirty years.
Updating Crafty 11.13 (1996) with modern tricks
The first engine I (read: my LLM) worked on was Crafty 11.13, its 1996 release.
On this engine the LLM had to do the most work to backport ideas we've learned over
the last 30 years. Below is a breakdown of where the Elo gains come from,
when evaluating either at 1 second per move or 10 seconds per move.
| 1 s/move | 10 s/move | Change |
|---|---|---|
| 1999 ± 90 | 2383 ± 77 | Crafty 11.13, released December 1996, as shipped. The initial alpha-beta engine as written. It has a custom evaluation function, with standard 90's-era search algorithms. |
| 2063 ± 73 (+64 ± 116) |
2323 ± 75 (−60 ± 107) |
The first improvement is mostly micro-optimizations. It replaces two 64K-entry lookup tables with calls to the bsf/bsr instructions; and sliding-piece attacks are migrated away from the older rotated-bitboard function call. In total these changes make the engine 15% faster, but it uses the same algorithms. |
| 2022 ± 73 (−41 ± 103) |
2420 ± 76 (+97 ± 106) |
The next improvement goes for the search algorithms. This includes techniques like fail-soft (which returns the real score instead of clipping), futility and late-move pruning (which skips quiet moves near the leaves), late move reduction (which searches later moves one ply shallower), and orders moves by counter-move and history tables. |
| 2224 ± 72 (+202 ± 103) |
2520 ± 74 (+100 ± 106) |
The next change tunes the search and the evaluation function. It first runs SPSA to tune all search constants based on several thousand games of self-play. It then gives evaluation terms separate middlegame and endgame values (blended by remaining material) and re-fits all the evaluation weights (Texel tuning). Finally the evaluation function introduces mobility terms rewarding the safe squares that pieces attack. |
| 2192 ± 72 (−32 ± 102) |
2565 ± 74 (+45 ± 104) |
From here, the evaluation function is rewritten and replaced with a neural network evaluation with a small network trained on 11 million positions of self-play, labeled by its own searches. This step doesn't do much by itself but it prepares the next step... |
| 2420 ± 82 (+228 ± 109) |
2712 ± 74 (+147 ± 104) |
Updates the NNUE that was just generated with a stronger teacher instead of self-play. In principle, I could have used the same engine itself as the teacher, but just to save on wall clock time I used Stockfish. This reduced the wall-clock time from ~4000 1996-core-years (something entirely doable in 1996---but sadly not something I can do with my single lonely desktop) to just a few days on a modern desktop running a modern engine. |
| 2630 ± 82 (+210 ± 116) |
2810 ± 75 (+98 ± 105) |
With a much stronger evaluation function, the search can now actually rely on it. It adds reverse futility pruning to early-return when the evaluation says the position is already won. It also adds some performance improvements to the evaluator (with an evaluation cache, and accumulators shared with null moves). This lets it widen the network 6x. It also cleans up some code, for example by getting rid of some of Crafty's special cases that mattered with weaker evaluation functions but don't matter any more with the NNUE. |
| 2720 ± 82 (+90 ± 116) |
2938 ± 74 (+128 ± 105) |
The parameters are again re-tuned with SPSA given the new evaluation function. It also fixes some bugs in the code, amusingly. And finally it adds some changes to the NNUE: it adds more output heads and picks based on the number of pieces on the board, adds some hidden units, and doubles the training data with more self-play. |
Porting Stockfish 17 onto a Pentium Pro
On the second engine, as mentioned above, I did the inverse. I (again, read: my LLM) ported
Stockfish to run on 1996 hardware, and then tweaked the parameters so that it would be better
suited to lower search depth. The gains here are thus somewhat more modest, because there
are no large algorithm wins that remain.
| 1 s/move | 10 s/move | Change |
|---|---|---|
| 2496 ± 64 | 2940 ± 76 | Stockfish 17 squeezed onto the machine. The first naive port rewrites Stockfish 17 for a 1996 machine: single core, no SIMD, no 64-bit registers and no C++ standard library. It removes the threading, the endgame tablebases, and the 71 MB NNUE replacing it with a much smaller one. It rewrites bitboards as a pair of 32-bit ints, and it evaluates the small NNUE with plain integer arithmetic. |
| 2590 ± 67 (+94 ± 93) |
2961 ± 74 (+21 ± 106) |
Faster accumulator upkeep. The second fix makes sure the NNUE running sums are better kept up to date, and improves the performance of the evaluator. |
| 2752 ± 68 (+162 ± 95) |
3006 ± 74 (+45 ± 105) |
Cheaper evaluation function, use a PeSTO blend, change the compiler flags. Next it again changes the NNUE and reduces the size and tunes it to run faster on the Pentium Pro, reducing the evaluation time by 3x. Combined with a few more optimization changes this pass gains the most of any step at 1 second per move, where raw speed matters most, and much less at 10 seconds per move. |
| 2780 ± 67 (+28 ± 95) |
3070 ± 72 (+64 ± 103) |
Fine-tune the NNUE on-policy. Basically repeats the prior work but on Stockfish, scoring several million positions with Stockfish to re-derive the NNUE weights. |
| 2784 ± 65 (+4 ± 93) |
3070 ± 72 (+0 ± 101) |
SPSA to re-tune the search, remove PeSTO given the improved NNUE. The original Stockfish assumed that it would run at several million nodes per second, so on the slower CPU it's necessary to re-tune the parameters with another pass of SPSA. These changes also make it so the PeSTO pass is no longer needed. |
| 2819 ± 65 (+35 ± 92) |
3074 ± 72 (+4 ± 101) |
Add correction history, jointly tune other parameters and the NNUE. The next pass brings back Stockfish's non-pawn correction history, jointly optimizes (again via SPSA) the parameters, and re-fits the NNUE. |
| 2846 ± 35 (+27 ± 74) |
3109 ± 79 (+35 ± 107) |
The final step changes no code and just changes the compiler, adds some link-time optimization, and adds 32-byte code alignment. |
So would this have beaten Kasparov?
I think it's overwhelmingly likely to be the case,
but it's actually a little bit more tricky of a situation than you might hope.
You see, I've done a bit of sleight of hand throughout this article.
The problem is that Elo scores are relative, and I've been comparing my engine's Elo to that of various Stockfish engines
that have known strengths on the Computer Chess Rating Lists (CCRL).
But because humans don't play against engines very frequently, there can be some small divergences between scores on the
FIDE Elo ladder and the CCRL ladder, in the same way a player's FIDE Elo doesn't directly translate to their Elo on online chess.
Fortunately, because I've gotten these engines to play at an Elo rating of 3200-3300,
and Kasparov was rated just under 2800, there should be more than sufficient buffer
to absorb any discrepancy.
But if you happen to know a 2700+ Super GM who wants to try and defeat a 2026 chess engine playing on 1996 hardware,
I'd be happy to accept the challenge!
Conclusion
The first time we humans do anything, we rarely do it efficiently.
Once we see a path that would clearly work if only we scaled it up, we do just that.
Only later, after we've had the time to better understand the problem at hand,
do we come to recognize that we could have achieved the same feat much more efficiently
by being clever.
I mostly did this for fun, because whether I could have beaten Kasparov with commodity hardware
sounded like a fun question to answer,
but I also hoped it would provide a tiny bit of insight
into the rate of algorithmic progress in "AI".
Chess engines in 1997 were already quite advanced;
after all, Alan Turing helped write the first chess program nearly fifty years earlier.
So I suppose at the time it seemed plausible that maybe there weren't that many more ideas left to find.
And with hindsight it's easy to see that's wrong.
Which leads to the question: just how much are we leaving on the table with modern-day "AI"---that is to say, language models.
Will the advances we accrue over the next few years from software outpace the advances in hardware scale?
Clearly this toy experiment doesn't answer that question definitively, but it does gesture at a potential future.
(There's also probably some kind of meta-lesson about using LLMs---"AI"---to speed up our
ability to answer weired research questions like this.)
(Also, uh, if anyone has any ideas for projects I could do with a Pentium Pro in a few weeks
once I no longer need it to host this chess engine ... do let me know!)
if that's more of your thing.