AI On Your Gaming PC
If you need to experiment with LLMs, you usually have a alternative of sending your requests to another person’s laptop or fielding a really giant GPU and CPU setup to run fashions domestically. However, a current crop of tasks goals to convey larger fashions to rather more modest {hardware}.
One instance is Strata, a undertaking from [Niko1221], which helps you to run a 125-billion-parameter LLM on {hardware} you may have already got for gaming. It gained’t run in your previous Pentium laptop computer, but it surely doesn’t require a supercomputer-like farm of graphics playing cards, both.
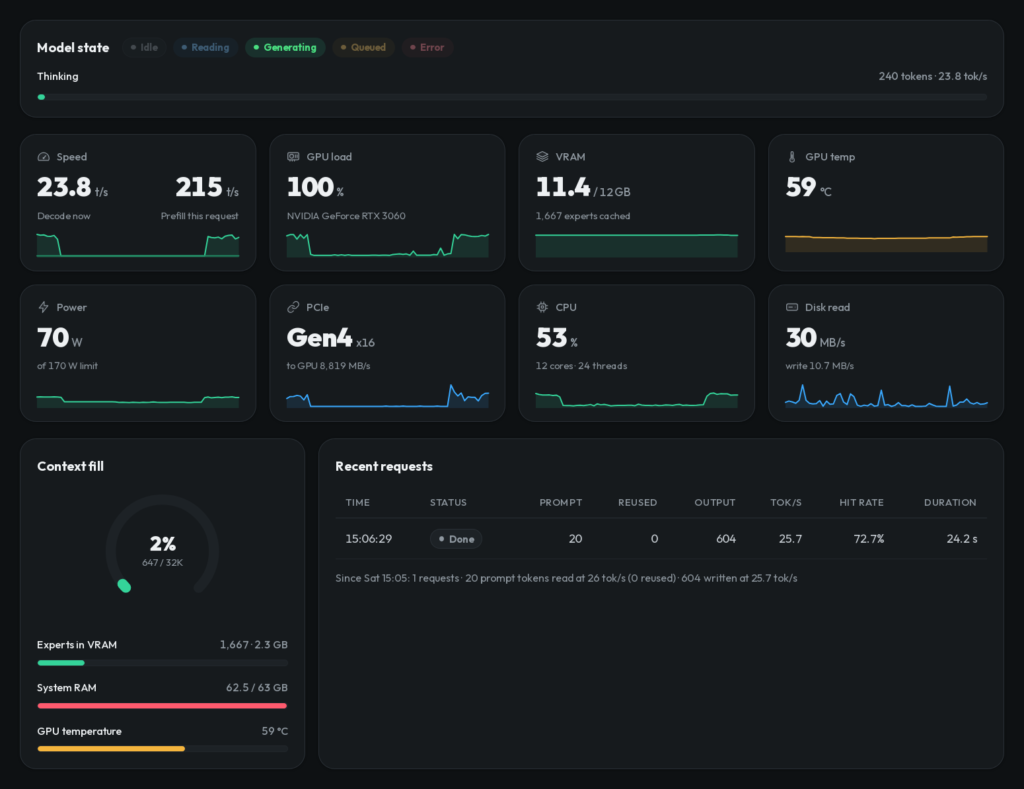
Strata can use several Qwen3.8 model variants, together with completely different quantizations of the unique mannequin in addition to coding and different specialised variations. Qwen3.8-Flash-Next is a mixture-of-experts mannequin containing 24,576 small specialists, of which solely ten are wanted for every token. The intelligent half is that Strata successfully treats VRAM as a cache for the a lot bigger mannequin. Frequently used specialists keep on the GPU, whereas the entire assortment usually stays in system RAM. The mannequin additionally features a roughly 29 GB lookup desk that stays on the SSD and is accessed as wanted.
The software program additionally makes use of the mannequin’s multi-token prediction equipment for speculative decoding, permitting a number of candidate tokens to be checked in a single go. According to the undertaking, an RTX 5070 with 12 GB of VRAM can produce roughly 50 to 90 tokens per second, relying on quantization. Tokens, in fact, aren’t normally whole phrases, however it’s nonetheless a decent clip, as soon as every little thing will get arrange.
We did have some bother setting every little thing up as a result of some incompatibility with the NVIDIA C compiler, our gcc model, and a few headers, however your issues will certainly be completely different. The setup.sh file asks you a couple of questions on the primary run. After that, it simply handles your chosen startup choices, which may take a couple of minutes whereas every little thing hundreds.
Once working, Strata enables you to work together by an internet browser. It additionally exposes OpenAI- and Anthropic-compatible APIs on localhost, so present chat entrance ends, coding assistants, and different instruments can use the native mannequin with out a lot particular dealing with. Of course, you may’t anticipate its solutions to compete with the large fashions on the market for each activity. When asking about Hackaday, for instance, it acquired a variety of it proper but additionally acquired confused about who based the location and our authors (until we forgot that [Tom Nardelli] as soon as wrote some posts). Turning up the “pondering stage” and turning down the temperature didn’t assist a lot, though it did transfer its confusion to completely different info. It did higher when requested to determine some downside code or define learn how to port a specific C compiler to a brand new goal.
You’ll nonetheless need at the very least 32 GB of system RAM, 12 GB of VRAM, and round 80 GB of storage, so “modest” is relative. Still, it’s a neat demonstration of how mixture-of-experts fashions and a few intelligent reminiscence administration can stretch odd PC {hardware} surprisingly far.
These economical LLMs may even run on older hardware, simply slower.