Why harnesses matter for power effectivity — Neuralwatt
By Chad Gibson, Co-founder & CEO
Key findings
- Harnesses cache otherwise. We noticed 1.6% to 11.1% uncached enter throughout purchasers. “Cached” is the share of enter tokens served from the immediate cache as an alternative of computed once more. At 92% cached, 8 tokens per 100 are uncached, versus 3 at 97%: about 2.7 instances the prefill work.
- A cache miss roughly doubles a request’s power. Here, a miss means a request with little or none of its immediate cached (underneath 10%). On GLM-5.3, it is about 2.5 instances as a lot.
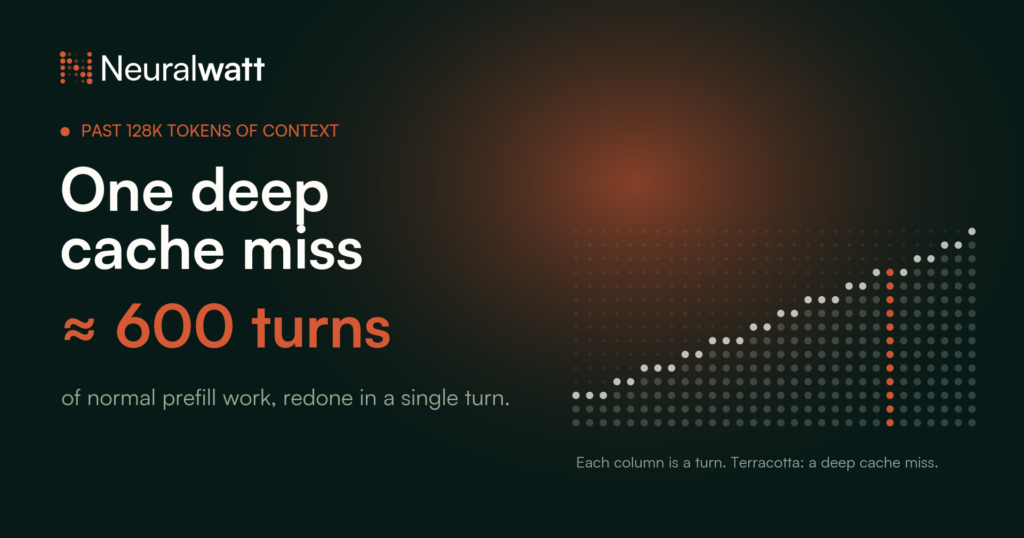
- Deep periods make misses costly. A re-read means recomputing that a part of the immediate from scratch. Past 128k tokens, one flip that re-reads greater than half its immediate prices as a lot prefill as about 600 regular turns at that depth.
- Most of that is fixable. Every cache break in our lab checks got here from a harness enhancing what it had already despatched, forcing a re-read from the primary distinction onward.
At Neuralwatt, we are able to see how the agent harness calling a mannequin impacts the power it makes use of. I’ve been wanting by means of a month of site visitors on our cloud, and the harness appears to determine a stunning share of how a lot work our GPUs do. We often discuss inference effectivity by way of the mannequin (what number of lively parameters, its consideration mechanism) or the {hardware} (H200 vs B200 vs B300). The shopper deserves a better look.
Almost all of our site visitors is agentic, with much more enter than output. A typical coding-agent flip sends 100k tokens or extra of dialog and will get again a couple of hundred tokens. Most of that enter is the earlier flip’s immediate with somewhat added on the finish. If the sooner textual content is unchanged, the server already has its key-value (KV) cache and solely has to course of the brand new half. This is immediate caching, our greatest supply of effectivity. Serving a cached token is way cheaper than computing it once more.
Caching wants an actual prefix. A cache break occurs when the harness modifications one thing it already despatched. We then recompute all the pieces from the primary distinction onward. A change close to the start, even a timestamp, means recomputing practically the entire immediate. A change close to the top prices little. The harness controls how the immediate is constructed.
Same mannequin, similar worth, totally different cache charges
Every request tells us which shopper despatched it. In the 30 days from September 8 to October 7, 2026, we noticed a whole bunch of various purchasers, together with open-source coding brokers comparable to OpenCode, Oh My Pi (omp) and Pi. The combine additionally included editor integrations, the OpenAI SDKs and customized apps. OpenCode alone is utilized by about one in 4 of our clients.
For essentially the most extensively used purchasers, right here is the share of enter tokens we couldn’t serve from cache:
Every shopper right here caches the massive majority of its enter. Those small variations nonetheless matter: a shopper at 97% cached sends us three uncached tokens per hundred; a shopper at 92% sends eight. That is 2.7 instances as a lot prefill work for a similar dialog.
Hit price additionally will depend on the workload, not solely the harness. Longer periods rating larger, as a result of every flip’s new textual content is a smaller share of the immediate, and about half of deepseek-harness’s lead comes from customers who run very lengthy periods. A cleaner measure of the harness is how usually a flip breaks the cache: about 1 flip in 100 for deepseek-harness, in opposition to about 3 in 100 for OpenCode and Pi. We see each OpenCode 1.x and a couple of.x in our site visitors, so the bar combines them. 2.x appears to be like higher alone (2.2% uncached in opposition to 3.0%), largely due to the mannequin combine. On the identical mannequin, they cache about equally effectively. 2.x fixes many of the 1.x cache breaks we discovered within the lab. That distinction does not present up in manufacturing, and we do not but know why.
What a miss prices in power
We invoice on measured power, so we are able to see the fee instantly. Over the week of October 1 to 7, 2026, we in contrast requests on the identical mannequin with the identical immediate measurement (about 50k tokens) and related output size. Here is the additional power every request used in contrast with a totally cached one:
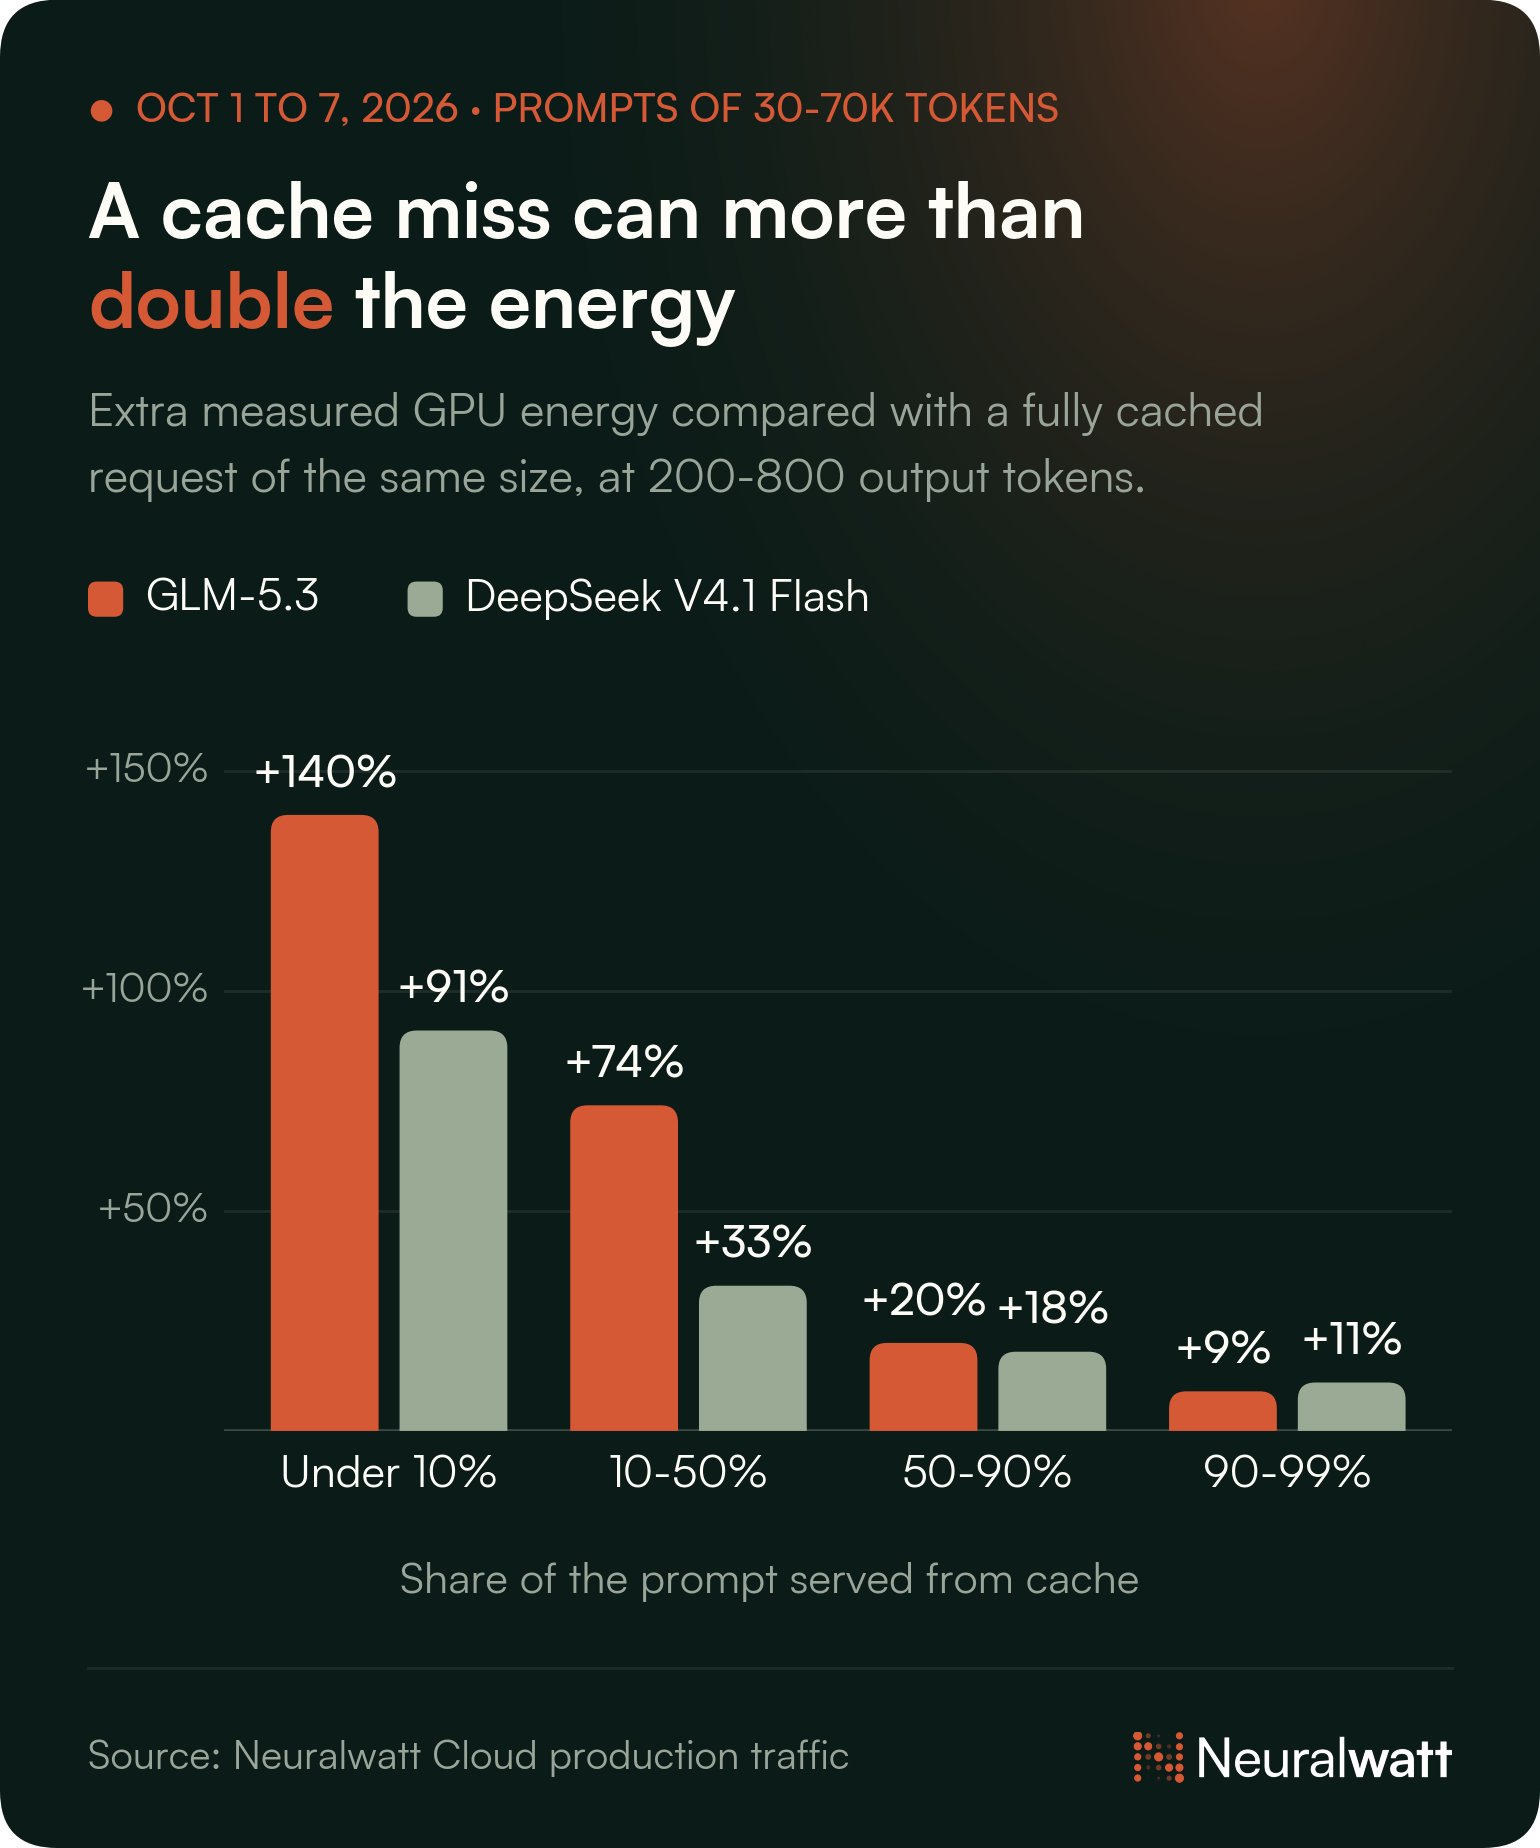
A largely uncached request takes roughly twice the power of a cached one of many similar measurement. On GLM-5.3 it’s nearer to 2 and a half instances. Prefill additionally competes with era for a similar GPUs, so wasted prefill slows down everybody else’s responses on that server.
Cache misses get costly deep in a session
We adopted particular person periods flip by activate our three busiest fashions for the week of October 6 to 13, 2026. We checked out each flip that landed on the identical server inside 5 minutes of the earlier one, the place the cache ought to have been heat. Most cache breaks have been small: a couple of thousand tokens close to the top of the immediate obtained recomputed.
Past 128k tokens of context, about 3 turns in each 1,000 re-read greater than half of the immediate from scratch. Those few turns account for 75% of all of the re-read tokens at that depth. Each one re-reads about 230k tokens on common. A standard flip at that depth provides a median of about 370 new tokens, so a single one in all these prices as a lot prefill as roughly 600 atypical turns.
The delay is noticeable too. Here is the median time to first token for a standard flip in contrast with a flip that needed to re-read most of its immediate:
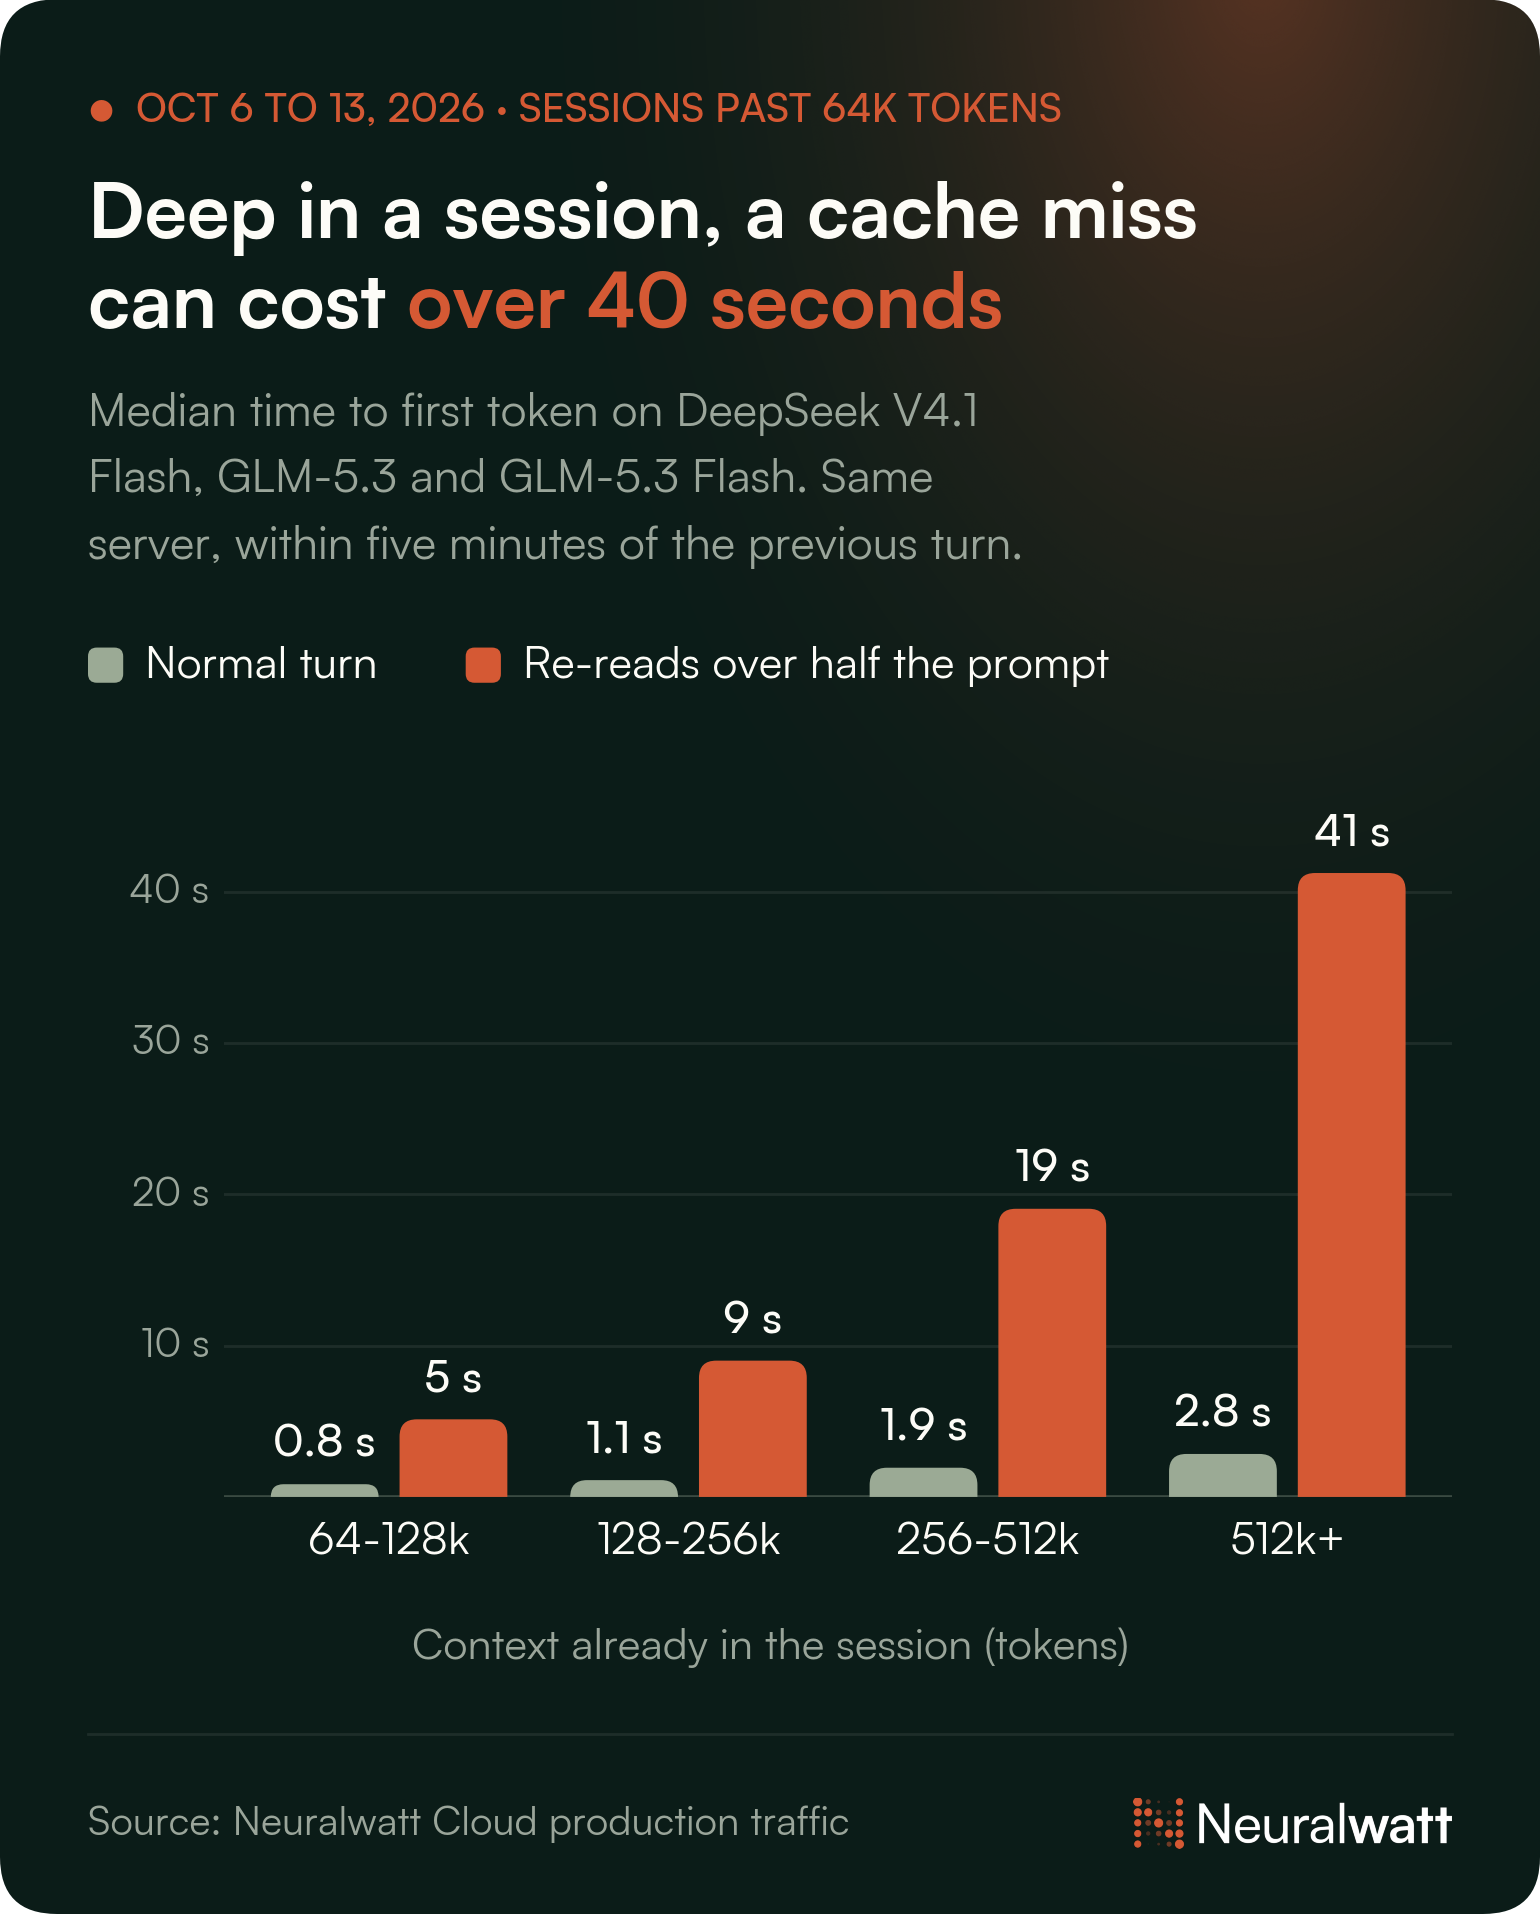
I pay extra consideration to how deep right into a session the cache breaks than how usually it breaks. Changing the start of the immediate as soon as, early on, prices little. Do it at flip 200 of a protracted session and also you get a big, seen pause and a big power price. Long agent periods account for many of our tokens, so this provides up.
We cannot all the time inform from the server aspect whether or not a harness edited the immediate or the cache was evicted underneath reminiscence strain. These numbers embrace each. Our lab checks beneath present that harnesses trigger the early-prompt edits we might reproduce; eviction seemingly accounts for a few of the relaxation.
What breaks the cache
I regarded for the causes in two locations: the lab, the place we might see each token, and manufacturing, the place we solely see request metadata.
In the lab
We ran 4 in style open-source brokers (OpenCode, Pi, omp and Kilo Code) by means of a recording proxy in opposition to DeepSeeok V4.1 Flash and GLM-5.3. We used the most recent releases as of October 6, with default settings: OpenCode 1.18.34, Pi 1.0.4, omp 18.6.3 and Kilo Code 7.8.3. We then repeated the session on OpenCode 2.0.29 from the two.x line. Each labored by means of the identical scripted session on a small Python mission: plan, then construct, change reasoning effort and again, spawn a sub-agent, sit idle, get restarted, join and disconnect an MCP server, add a talent, and run lengthy sufficient to compact. We in contrast each request with the one earlier than it, each as JSON and because the precise tokens the server renders.
Of 539 requests that adopted an earlier one in the identical dialog, 88% have been pure appends: the earlier immediate was an actual prefix of the brand new one. The different 65 broke the cache. Every break got here from the harness altering one thing it had already despatched; none got here from our chat templates. Idle time brought on no breaks in any of the 4. Neither did restarting the harness and resuming the session, or utilizing sub-agents.
Two causes break the cache with none motion from the person:
- OpenCode’s plan-mode reminder. Once you’ve got used plan mode, OpenCode attaches a reminder (“Your operational mode has modified from plan to construct”) to every new person message. It removes that reminder from the message on the next flip. Every flip then re-reads the entire earlier flip, together with its device calls and outcomes. In our quick periods, that was 330 to 2,340 tokens a flip. The price grows with the scale of the flip. OpenCode 2.x retains the reminder in its personal message, so it not triggers a re-read.
- omp’s pruning of re-read recordsdata. When a file is learn a second time, omp replaces the sooner copy in historical past with
[Superseded by a newer read of this file]. In our run, that one edit landed 62% of the way in which into the immediate, forcing a re-read of 5,846 of 15,520 tokens. omp additionally prunes “uneventful” device outcomes, and after 90 minutes idle it prunes at any depth. Settingcompaction.supersedeReads: falseandcompaction.dropUseless: falseretains the cache.
Pi and Kilo Code had no breaks of this type.
The different causes rely upon what the person does. How a lot they price will depend on the place the immediate modifications:
- Switching reasoning effort. Both templates write the trouble stage within the first few tokens of the immediate:
Reasoning Effort: Maxon GLM-5.3, a quantity from 1 to 100 on DeepSeeok V4.1. The first distinction was at token 8 on each fashions, so a change re-reads all the pieces. Only that one worth modifications; its size and all the pieces after it keep an identical. - Connecting or disconnecting an MCP server. OpenCode 1.x and Kilo Code insert new instruments in alphabetical order, in the course of the device listing. OpenCode 2.x leaves the device listing alone and appends a word, so each connecting and disconnecting have been pure appends. Pi provides a device and edits its system immediate. omp appends a piece to its system message. On GLM-5.3, the device listing is rendered earlier than the system immediate, so the change lands very early: about 1,300 tokens in for OpenCode 1.x.
- Adding a talent. All 4 listing abilities within the system immediate. The first distinction landed between token 461 and token 2,948 on DeepSeeok V4.1, and in a while GLM-5.3, the place the instruments come first.
- The date altering. OpenCode 1.x and Kilo Code put at present’s date within the system immediate, about 2,000 tokens in. OpenCode 2.x retains the session’s authentic date and appends a word when the date modifications. omp places it within the first person message. Pi does not ship a date. For purchasers that overwrite the date, crossing native midnight means re-reading practically all the pieces as soon as.
- Compaction. Each harness does it otherwise. Pi retains the final ~20k tokens phrase for phrase however rewrites the abstract close to the start. The immediate hardly shrinks, and most of it will get re-read anyway. With the identical 40k-token window, OpenCode 2.x compacted 3 times and re-read 67,850 tokens in complete. 1.x compacted as soon as and re-read 29,776.
Switching again to a setting we might used earlier within the session was cheaper than I anticipated. The server nonetheless holds that earlier model of the immediate. Switching effort again hit 10.6k to 27.5k cached tokens in our runs. A toggle prices one full re-read the primary time every new state is used, not on each flip.
In manufacturing
We do not log or preserve the textual content of consumers’ prompts or responses. Everything on this part comes from request metadata. The token-level evaluation above comes from our personal scripted check periods, not buyer site visitors. That metadata information the reasoning effort every request requested for and what number of instruments it despatched. We used it to test two of those causes in opposition to actual periods from October 6 to 13, 2026, on DeepSeeok V4.1 Flash, GLM-5.3 and GLM-5.3 Flash. We used consecutive turns of no less than 8k tokens on the identical server inside 5 minutes. To preserve a couple of heavy accounts from driving the end result, we ignored the three clients with essentially the most re-read tokens in every group.
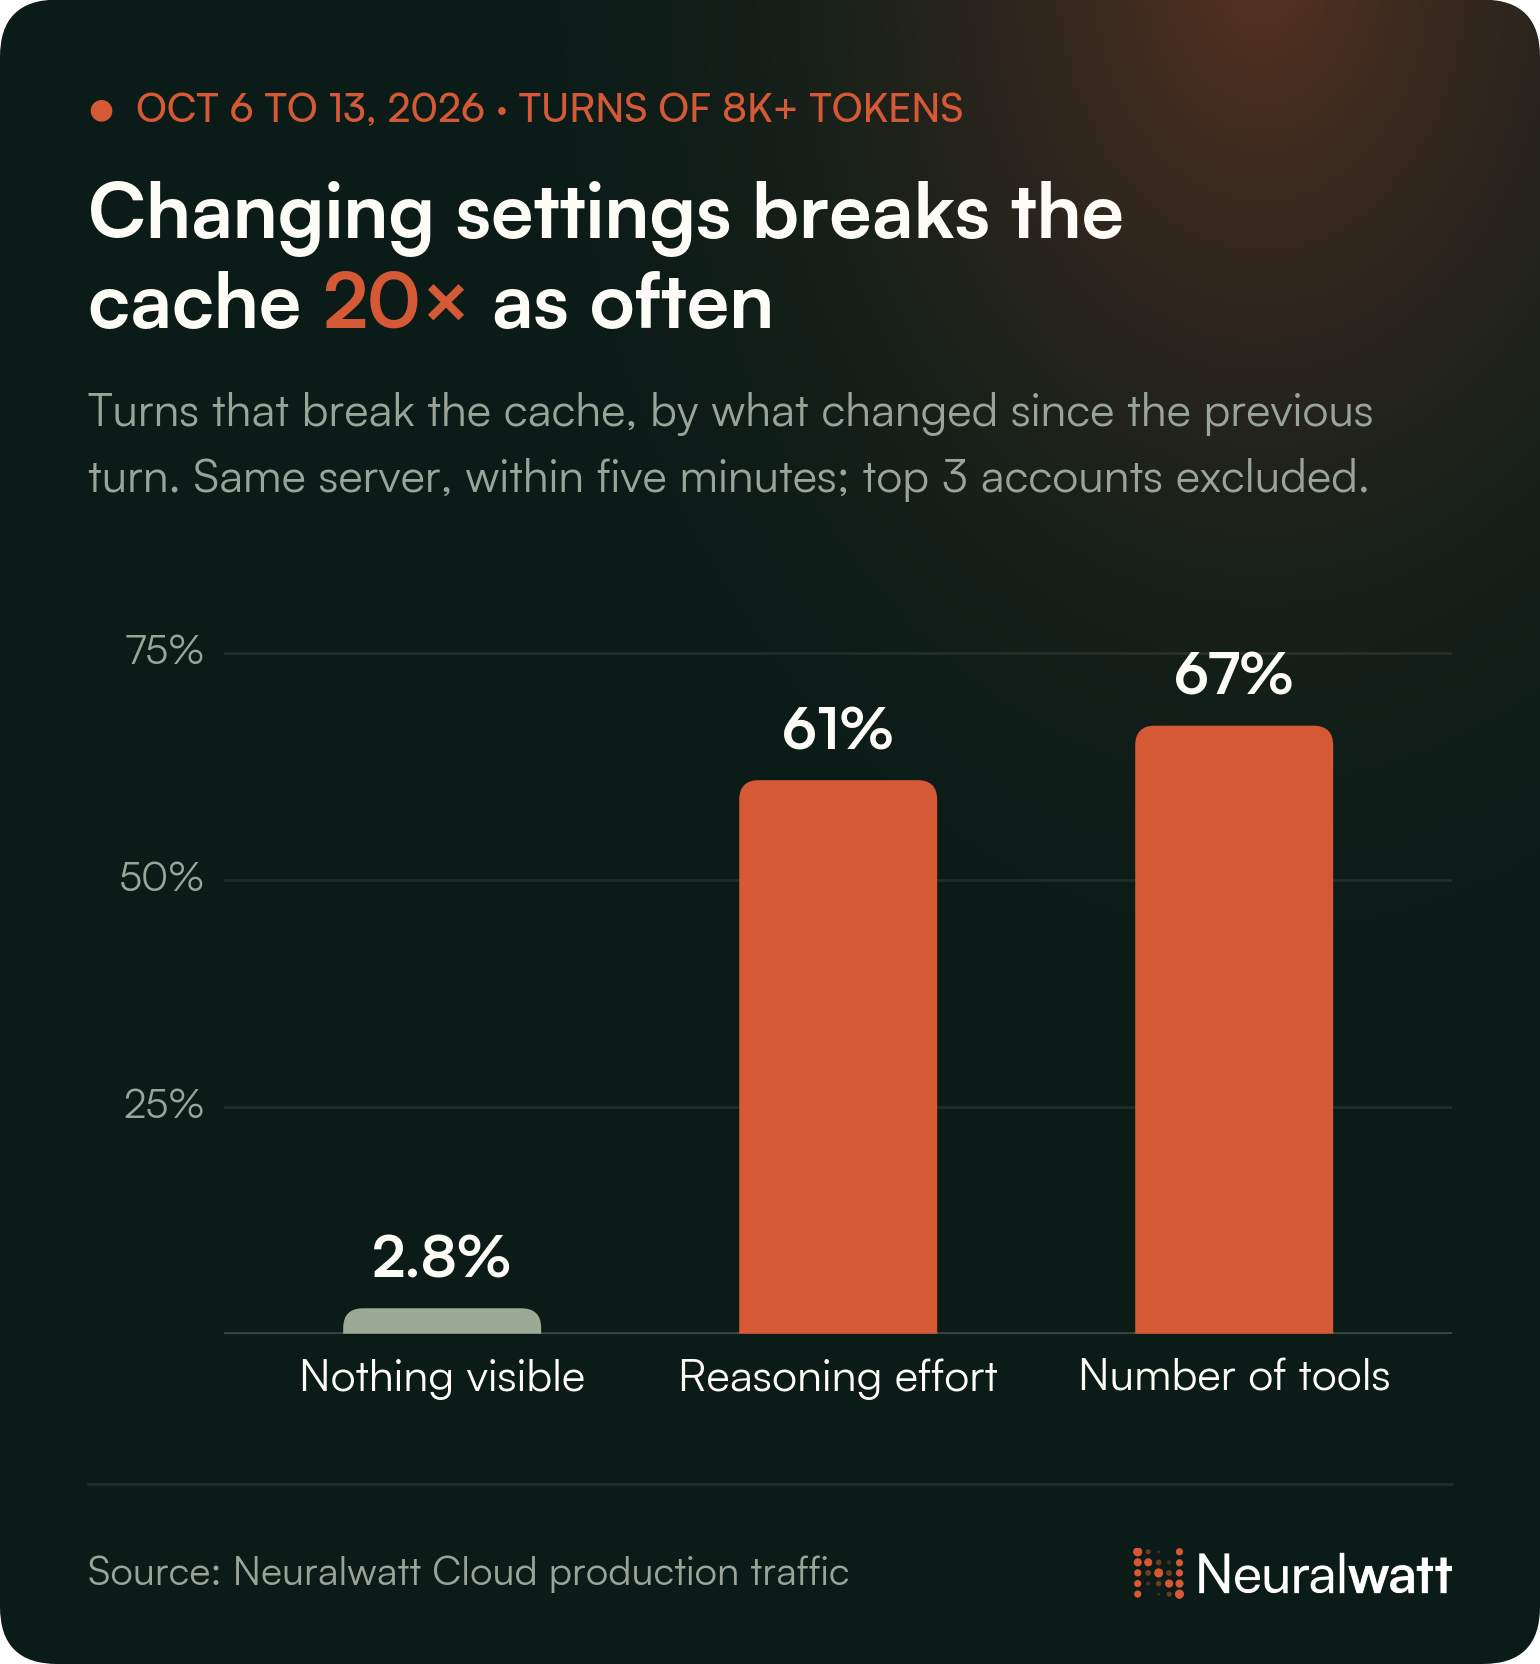
Changing the device listing or effort stage makes a cache break greater than 20 instances as seemingly and prices, on common, about 40% of the earlier immediate. Tool-list modifications occur on about 0.5% of turns, but account for 19% of all re-read tokens on these fashions. That share is concentrated: three accounts make up about two thirds of it. The per-turn impact holds throughout everybody else.
The remaining three quarters of re-read tokens come on turns the place neither the trouble nor the device depend modified. That “nothing we are able to see” bucket holds the causes we will not see from the server: the reminder in OpenCode 1.x, omp’s pruning, abilities, the date, compaction and cache eviction. Next, I’d like us to report the place every immediate first differs from the earlier one. That would allow us to break up the bucket up with out studying any immediate textual content.
How deepseek-harness retains the cache intact
In our lab seize, each one in all deepseek-harness’s follow-up requests was a pure append to the earlier one, even after the method was restarted and the session resumed. Reading its supply, I discovered a couple of practices price taking a look at:
- Requests are rebuilt from an append-only session log. Retries and resumes produce byte-identical prompts.
- The system immediate is mounted and minimal. It leaves out the date, git standing and OS. It is written as soon as and left alone.
- Changing state goes after the historical past. When the approval coverage or obtainable abilities change, the harness appends a brief snapshot saying it supersedes earlier ones. It leaves the system immediate and older messages alone.
- The device listing stays sorted and an identical in each mode. Prose directions implement modes with out including and eradicating instruments.
- Compaction occurs late. The summarizing name reuses the present prefix, so even compaction is generally a cache hit. Summarizers that re-serialize the transcript right into a single new message begin chilly. In the biggest such workload we noticed, these calls have been solely 22% cached.
- Every change will get reviewed for cache impression. Each package deal within the repo carries a brief “KV cache impact” part.
What you are able to do
If you construct or configure a harness:
- Keep the beginning of the immediate an identical each flip. Add new messages and outcomes from instruments on the finish of the dialog. Describe modifications to settings there too, leaving the sooner textual content untouched.
- Don’t put the date, git standing or the rest that modifications into the system immediate.
- Keep the device listing steady and sorted. Add new instruments on the finish.
- Compact late, and have the summarizer name reuse the dialog’s precise prefix.
- Send a steady session id. On Neuralwatt,
X-NW-Conversation-IDlets us preserve a session on the server that already holds its cache, even throughout compaction.
If you utilize a harness:
- Pick a reasoning effort per session quite than switching mid-session.
- For omp, think about
compaction.supersedeReads: false. - Settle settings like effort, MCP servers and abilities earlier than the session will get lengthy. That is when a cache break hurts most.
See it in your individual periods
Everything on this publish comes from knowledge we report for each request, and you’ll see the identical knowledge on your personal work. Session Insights within the Neuralwatt dashboard reveals every agent session flip by flip: how a lot of every immediate got here from cache, how a lot needed to be computed chilly, the time to first token, and the measured power and price. It by no means reveals immediate or completion textual content.

This is one in all my very own periods from September 26, 2026: 35 turns of a coding agent on DeepSeeok V4.1 Flash, rising from 29k to 257k tokens of context. 95% of its immediate tokens got here from cache, and the small crimson caps are the brand new textual content every flip added. A cache break reveals up as a tall crimson bar, so if you happen to change reasoning effort or join an MCP server midway by means of a session, you possibly can see what it price. You can use it to match harnesses or settings by yourself workload, and to test {that a} change truly saved the cache heat.
What we’re doing on our aspect
We route every session again to the server that holds its cache. On our busiest fashions, that already retains 88–96% of every session’s tokens on its dwelling server. When a session has to maneuver, our shared KV cache pool lets the brand new server load the prefix as an alternative of recomputing it.
We lately measured how rather more a better prefix-aware router would get well on prime of that: a tenth to 2 tenths of a proportion level of hit price. Most of the remaining waste comes from how prompts are constructed.
Next, we plan to ship fixes and recommended defaults upstream to the open-source harnesses our clients use most. We additionally need to analysis methods for the server to reuse cached work after a small edit close to the start of the immediate, comparable to the trouble line or the date. That would assist with purchasers we will not change ourselves.
Why that is price measuring
A cache break does not present up as an error. You nonetheless get your reply, simply later and with extra power spent on it. Measuring the power of each request confirmed us how a lot that waste provides up. Most of it turned out to be fixable with a setting or a small change to how a harness builds its immediate.
AI runs on power. The extra of it we are able to see, the extra of it we are able to cease losing, whether or not that is a single developer’s session or the trade’s subsequent knowledge heart.
Methodology notes. We determine purchasers by the identify in every request’s User-Agent header. SDK and runtime labels (Node.js apps, OpenAI SDK apps) cowl many alternative purposes. We solely present purchasers utilized by many shoppers and by no means determine particular person clients. Servers cache prompts in fixed-size blocks, so even a pure append can depart a couple of tokens on the finish of the earlier flip to re-read. We depend these as uncached enter, including underneath 0.1 proportion factors for the coding brokers in Figure 1. Cache charges are the share of immediate tokens served from cache throughout all fashions from September 8 to October 7, 2026. Energy is measured GPU power apportioned to every request; the cached vs uncached comparability holds immediate measurement and output size mounted and covers October 1 to 7, 2026. The deep-session and trigger analyses cowl October 6 to 13, 2026, on DeepSeeok V4.1 Flash, GLM-5.3 and GLM-5.3 Flash, following every session’s consecutive activates the identical server inside 5 minutes.
Chad Gibson is the co-founder and CEO of Neuralwatt. He spent greater than 20 years at Microsoft earlier than investing in early-stage startups and co-founding Neuralwatt in 2024.