This open-source software lets me mount any web site as a folder on Linux
A web site normally lives in a browser, the place I navigate between pages, open pictures, and obtain information individually. On Linux, HTTPDirFS presents one other approach to entry internet content material by mounting an HTTP server as a filesystem by FUSE. You can then browse the uncovered assets by a file supervisor, a lot as you’d browse information saved in your pc.
I attempted HTTPDirFS with a web site crammed with e book listings, cowl pictures, and class pages. Here is how I set it up and what I discovered:
How to get began with HTTPDirFS
Why use HTTPDirFS?
HTTPDirFS shouldn’t be a alternative for instruments corresponding to wget, curl, or devoted scraping utilities. I’ve even constructed a scraping software myself, so I perceive why mounting a web site as a filesystem may appear pointless at first. Its worth turns into clearer while you need to browse distant information and retrieve chosen gadgets with out downloading a whole listing.
HTTPDirFS is especially helpful for shopping the open directories shared on the r/OpenDirectories subreddit. These directories can comprise hundreds of pictures, paperwork, movies, and different information. Instead of downloading every thing to get just a few gadgets, you may mount a distant listing, browse its contents as in the event that they have been native information, and entry particular person gadgets as wanted.
The identical strategy can assist when HTML pages hyperlink to distant media and paperwork. Instead of writing a script to fetch a web page, parse its hyperlinks, and obtain each useful resource, you need to use HTTPDirFS to show the assets it discovers by filesystem paths. Shell instructions and file-oriented functions can then work with these paths. Scripts should still have to account for a way the assets are named and arranged.
I used the event model as a result of the packaged model doesn’t present the website-mode conduct I wished to strive. First, set up the construct instruments and growth libraries required by the undertaking.
sudo apt replace
sudo apt set up git build-essential meson ninja-build
libfuse3-dev libcurl4-openssl-dev libgumbo-dev
Dependencies can range between repository variations, so verify the undertaking directions if Meson studies a lacking library. Clone the HTTPDirFS repository and enter its supply listing.
git clone https://github.com/fangfufu/httpdirfs.git
cd httpdirfs
If you have already got a supply checkout, you need to use that listing as a substitute. Next, configure and compile the undertaking.
meson setup construct
meson compile -C construct
The compiled executable is on the market at construct/httpdirfs. Check the model and out there command-line choices earlier than mounting the web site.
./construct/httpdirfs --version
./construct/httpdirfs --help

My growth construct reported HTTPDirFS model 1.3.3. The key choice for this experiment was --website-mode. It presents assets with a textual content/html content material sort as directories and makes linked media and different property out there by the filesystem. Website mode is disabled by default, so you should allow it explicitly.
Mount a web site with HTTPDirFS
Enable web site mode and browse its assets

I selected Books to Scrape as a result of its pages comprise e book titles, class hyperlinks, cowl pictures, and different internet property. This gave me a handy approach to check how HTTPDirFS handles HTML pages and the assets they reference.
First, I created a devoted mount level in my dwelling listing.
mkdir -p "$HOME/HTG-Test"
From the HTTPDirFS supply listing, I began the event executable with web site mode enabled.
./construct/httpdirfs --website-mode -f
https://books.toscrape.com/ "$HOME/HTG-Test"
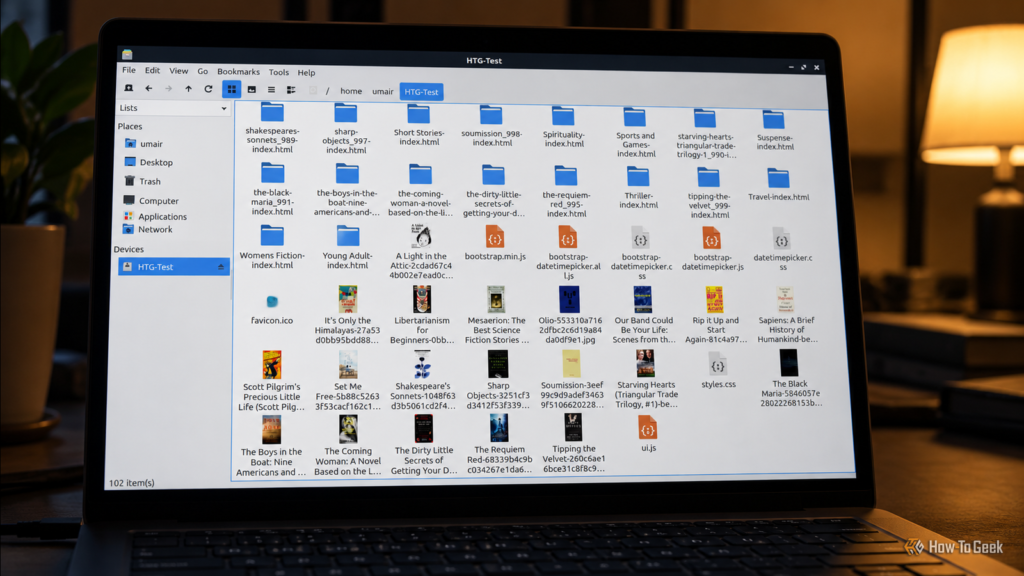
The -f option retains HTTPDirFS operating within the foreground, permitting me to examine its terminal output whereas testing. After HTTPDirFS processed the preliminary web page, I opened the HTG-Test mount level in my file supervisor. The mounted filesystem uncovered HTML pages for e book classes and particular person listings, alongside cowl pictures and different property referenced by the web site. Some HTML pages appeared as directories, permitting me to browse the assets related to every web page.

I might browse classes, examine particular person e book listings, and open cowl pictures with out downloading your complete web site first. This is the principle benefit of HTTPDirFS: functions can entry the assets it discovers by odd filesystem paths.
The outcomes rely upon the web site and the assets HTTPDirFS discovers. Websites that depend on JavaScript-generated content material or advanced interactions might not expose every thing a browser can entry. Authentication choices might assist with protected assets, however HTTPDirFS doesn’t present a full browser engine. Its filesystem view additionally relies on the construction of the HTML and the assets referenced by every web page.
Access distant information with out downloading every thing
Dedicated scraping instruments stay higher suited to structured information extraction and complicated web sites, whereas wget and HTTrack are extra applicable for mirroring websites for offline use. HTTPDirFS serves a narrower objective by making found distant assets accessible by paths that odd filesystem functions can use.
HTTPDirFS is price attempting in case you recurrently browse public file listings or need to entry chosen pictures and paperwork from distant web sites. It additionally gives a sensible approach to experiment with FUSE and construct workflows round distant content material utilizing acquainted Linux instruments.