The Double Headed Stack Allocator – The weblog on the backside of the ocean
When programming excessive efficiency purposes, corresponding to video video games, you be taught neat tips for writing quick code that makes probably the most of restricted assets.
Memory allocation is a large subject for efficiency vital code that wants a variable quantity of reminiscence.
When you hear “stack allocator” you would possibly consider “alloca” which helps you to allocate reminiscence from the precise program stack. That is tremendous helpful in a pinch, however that’s not what at the moment’s put up is about. Another identify for the kind of stack allocator we’re speaking about at the moment is “bump allocator”.
The Stack Allocator
Around 2010 I used to be working at Surreal Software (Midway Seattle) on an open international stage recreation “This is Vegas” which sadly was cancelled when Midway went out of commerce.
On that challenge, one in all my duties was animation programming. Animation labored by having a state machine for units of bones, the place every state was a tree of animation blends. When states modified, they might mix out from the outdated state into the brand new state to protect continuity.
There was plenty of mixing occurring, and it used a lot of dynamic reminiscence allocations for these animations to be evaluated and blended on the CPU. These allocations had been all transient although and solely wanted to exist for a part of the body. Furthermore, these allocations needed to occur per body, as issues may change drastically from one body to the following, as to which characters had been being animated that body – based mostly on the digital camera frustum for instance. The allocator confirmed up as a sizzling spot in profiling this part of code.
To resolve this downside, we applied a “stack allocator” the place allocation is simply an integer add, and deallocation is even cheaper.
To do that, you allocate and hold some quantity of reminiscence that’s the most quantity you’ll need, like say 1MB. This is your stack. You additionally hold an integer “tos” variable to know the place the highest of the stack is.
When you need to allocate reminiscence, your reminiscence is the reminiscence on the prime of the stack, and also you add the variety of bytes you need to allocate to the tos variable in order that the following allocation comes after yours:
In an actual implementation, you’d additionally need to know the way massive the reminiscence was, in order that you would deal with the tos hitting the top of the reminiscence – by returning null, or asserting, or one thing else.
When you might be accomplished with the reminiscence, you simply set the tos variable to 0.
In our case, we set the tos to 0 after animation mixing was completed and we had copied the outcomes into the buffers that had been heading to the vertex shader for skinning. If you had been utilizing a stack allocator extra usually for all transient reminiscence allocations throughout a recreation’s body, you might set it again to 0 when the body begins.
The consequence was evening and day. Allocation now not took any measurable time within the profiler, as a result of allocation was an integer addition, and liberating all reminiscence was a single integer assigment. It doesn’t get sooner than that.
One factor to notice is that as written, this allocator doesn’t name destructors or destructors. Using placement new for constructors could be simple sufficient. Calling destructors could be more durable, because it must be a guide course of, which is error inclined. You would possibly have the ability to use some RAII sample, however stack allocators work finest for easier varieties.
Another wonderful thing about stack allocators is that they’ll work in multi threaded environments. If the tos variable makes use of atomic addition, a number of threads can allocate from the identical stack allocator. This may be good in a fork/be part of state of affairs on the CPU, or for a fancy algorithm working on the GPU.
You may also do “partial deallocations” with stack allocators. For occasion, for those who had some recursive course of the place every degree wanted dynamic allocation, you would keep in mind the place the tos was when that degree began, and set it again to that worth when that degree of processing completed.
The Double Headed Stack Allocator
A number of years later, I discovered myself at Blizzard on the StarCraft 2 group. My boss James Anhalt was (and nonetheless is) a very good dude who launched me to shader toy, and shared a bunch of actually cool methods which were earlier weblog posts. He advised me about double headed stack allocators as an answer to a reminiscence fragmentation downside he had hit prior to now.
Imagine that you just had a streaming international stage recreation the place because the participant ran across the international stage, outdated degree geometry would deallocate, and new degree geometry would allocate and stream in from disk.
At the identical time, think about the participant character may form shift into completely different kinds – and every time they modified kinds, the outdated type was deallocated, and the brand new type was allotted and streamed in from disk.
A problem is, when you’ve got these two techniques allocating and deallocating random quantities of reminiscence, on their very own timelines, your reminiscence goes to get fragmented.
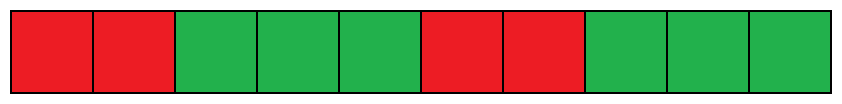
Lets stroll by means of a easy instance. Let’s say you’ve got 100 MB complete reminiscence for the extent (purple) and the character (inexperienced). The degree allocates 20MB, then the character allocates 30MB, then the extent allocates 20MB and the character allocates the ultimate 30MB.
Now let’s say that the participant runs to a brand new part, so the outdated degree knowledge reminiscence is freed. The new degree knowledge solely must make a single 30MB allocation. We do have 40MB reminiscence free, however it isn’t in a single chunk! We solely have two blocks of 20MB. So though the brand new degree knowledge is smaller, we are able to’t allocate area for it. This is reminiscence fragmentation, and it’s a giant downside in reminiscence constrained environments.

So, James advised me what they did in one of these state of affairs was to have a bit of reminiscence like a traditional stack allocator, however the degree knowledge had a tos which grew upwards from 0, and the character knowledge had a tos which grew downward from the top of the reminiscence. You knew you had been out of reminiscence after they crossed over one another and the extent tos was better than the character tos.
Let’s see how that works:


This made it so when the extent knowledge wanted to vary, it may reset the extent tos again to 0, and reallocate the reminiscence it wanted, with none fragmentation by any means. Similarly, when the character freed its reminiscence, it might reset its tos again to the top of reminiscence, and will then reallocate the reminiscence it wanted, additionally with none fragmentation.
Once once more, these allocators work high-quality in multithreaded environments, even when every thread would possibly allocate from both aspect. Atomic add to the tos indices is all you want.
You would possibly ask “why not have two stack allocators as a substitute of a double headed one?” The predominant profit is when you find yourself reminiscence constrained and know that the dimensions of 1 stack allocator is sufficient to serve two techniques, however the proportion of reminiscence that goes to at least one aspect vs the opposite is versatile. In a recreation state of affairs like described above, which means some ranges may use extra reminiscence, however in these conditions, the character would wish to have diminished reminiscence utilization. A little bit of a contrived instance however hopefully you get what I imply.
Storing Variable Sized Objects In A Finite Region
There is a variation of this when you find yourself making an attempt to retailer numerous variable sized objects in a hard and fast quantity of reminiscence, however you need random entry by index. An instance could also be that you just need to ship community packets of a selected measurement for effectivity motive, and also you need to that reminiscence to encode a variable variety of variable sized community instructions in it. You need to have the ability to simply iterate by means of the messages, however you need to help them having variable sizes too.
What you do is have a double headed stack allocator the place one stack is for the dynamic allocations, and the opposite stack is for an array of integers which can be an offset within the reminiscence to the dynamic allocations.
Let me present you what I imply with an instance. Starting with an empty double headed stack allocator:
- You need to allocate 24 bytes. Stack 0 has a tos of 0, so that’s the place you write your 24 byte object. You add 24 to stack 0’s tos and it’s now 24, the place the following free area of reminiscence is. You additionally allocate an integer from stack 1 and write 0 there, because the offset for the place this primary merchandise lives.
- Next you need to allocate 14 bytes. Stack 0 has a tos of 24, so that’s the place you write your 12 byte object. You add 12 to stack 0’s tos and it’s now 38. You additionally allocate an integer from stack 1 and write 24 there, because the offset for the place this second merchandise lives.
- and so forth…
you additionally need to someway hold observe of what number of objects there are. You may have a separate integer retaining rely of what number of offsets there are within the offset desk, or possibly you would have a sentinel worth within the offset desk to point the place the top of the offsets are. Perhaps ~0 (all 1s in binary) could possibly be the sentinel worth.
Just like the opposite stack allocators we talked about, this one may also work in a multi threaded surroundings. You is perhaps tempted to make the 2 updates transactional – like with a evaluate and swap loop – however it isn’t wanted.
Lastly, this configuration lets you take away objects, or transfer them round in reminiscence, which is one other method of lowering fragmentation – you simply have to replace the offset desk to match actuality whenever you accomplish that.
Links
Another little write up that features this subject, from the AMD vulkan reminiscence allocator: https://gpuopen-librariesandsdks.github.io/VulkanMemoryAllocator/html/custom_memory_pools.html#linear_algorithm