The present stability of energy in open fashions

I used to be just lately invited to transient a bunch of Congressional members and employees on the state of open-weight fashions within the lens of U.S.-China competitors. I’m sharing my ready remarks as a state of the union on open fashions that’s accessible to a broader viewers.
Open language fashions are AI fashions the place their weights are publicly out there for inspection or downstream use. These are most frequently contrasted to so-called “closed” AI fashions. Closed fashions supply entry solely by Application Programming Interfaces (APIs) that builders can use to straight question a mannequin, like GPT-4 or Claude Opus 4.5, or by merchandise, like ChatGPT and Claude Code.
Open language fashions primarily are bucketed into two classes, open-weight and open-source fashions. Open-weight fashions are the most typical kind, similar to well-liked fashions like Meta’s Llama, Alibaba’s Qwen, Google’s Gemma, or DeepSeek’s fashions. These fashions are ruled by licenses, governing paperwork dictating what’s allowed with downstream use, and are sometimes accompanied by inference code in libraries similar to Transformers, VLLM, SGLANG, and so on. Since about April 2025, Chinese AI firms have been the clear chief in open-weight fashions.
True “open-source” fashions are just like these, as they embody the weights, licenses, and inference code, however in addition they embody the whole info wanted to breed the mannequin – the coaching code and coaching knowledge. The most distinguished open-source fashions have been constructed within the United States, led just lately by the Allen Institute for AI’s Olmo fashions that I helped construct in my latest 2.5 years there. The different distinguished open-source fashions are additionally constructed by American non-profit organizations, together with OpenAthena’s Marin fashions and EleutherAI’s Pythia fashions.
Open-weight, open-source, and each different label for a mannequin – together with closed fashions primarily provided by way of an API – exist on a spectrum. For instance, Nvidia’s Nemotron fashions are way more open than most open-weight fashions, releasing giant portions of their coaching knowledge underneath permissive licenses, however they’re not absolutely open-source as a result of they don’t launch all the knowledge. Closed fashions additionally exist on a spectrum primarily based on what info the API reveals and the phrases of use.
We reside in a international stage the place GLM-5.2 and Kimi K3, a few of the newest, main Chinese fashions, have enacted a step change within the business viability of open fashions — crossing an identical threshold in agentic capabilities that Anthropic’s Claude Code crossed in December of 2025.
America was the early chief in open language fashions, primarily by Meta’s Llama fashions, which had been used extensively throughout analysis and business duties. Chinese open-weight fashions surpassed American open-weight fashions in these two key areas about 18 months in the past. The easy metric exhibiting that is Hugging Face Downloads, the place China took the lead in July of 2025 primarily by the success of Alibaba’s Qwen fashions. I personally preserve instruments to trace this knowledge, and since I first printed the American Truly Open Models (ATOM) Project in August of 2025, China’s download lead has grown to about 1.6B – with a complete of three.2B downloads, twice that of America’s whole.
On well-liked capabilities benchmarks, such because the Artificial Analysis Intelligence Index (AAII), the Chinese open-weight fashions have a transparent lead over American counterparts. The high three Chinese fashions as of penning this on September 14, 2026 are Z.ai’s GLM-5.3 and GLM-5.3-Flash and Moonshot AI’s Kimi K3 with scores of 45, 42, and 44 respectively. By comparability, the main American fashions are Thinking Machines’ Inkling and Inkling Small, each with a rating of 26, and Nvidia’s Nemotron 3 Ultra, with a rating of 23. The high American fashions had been launched in June and July of 2026, and are up to date much less continuously than their Chinese counterparts. For instance, Chinese labs launched fashions with scores above these American fashions 2-6 months earlier than the American firms obtained there (e.g. GLM-5 or DeepSeek V4 Pro). There is a development of extra American firms releasing fashions, together with names like Arcee AI, Poolside and IBM, however they aren’t quickly closing this efficiency hole. Other benchmarks inform an identical story.
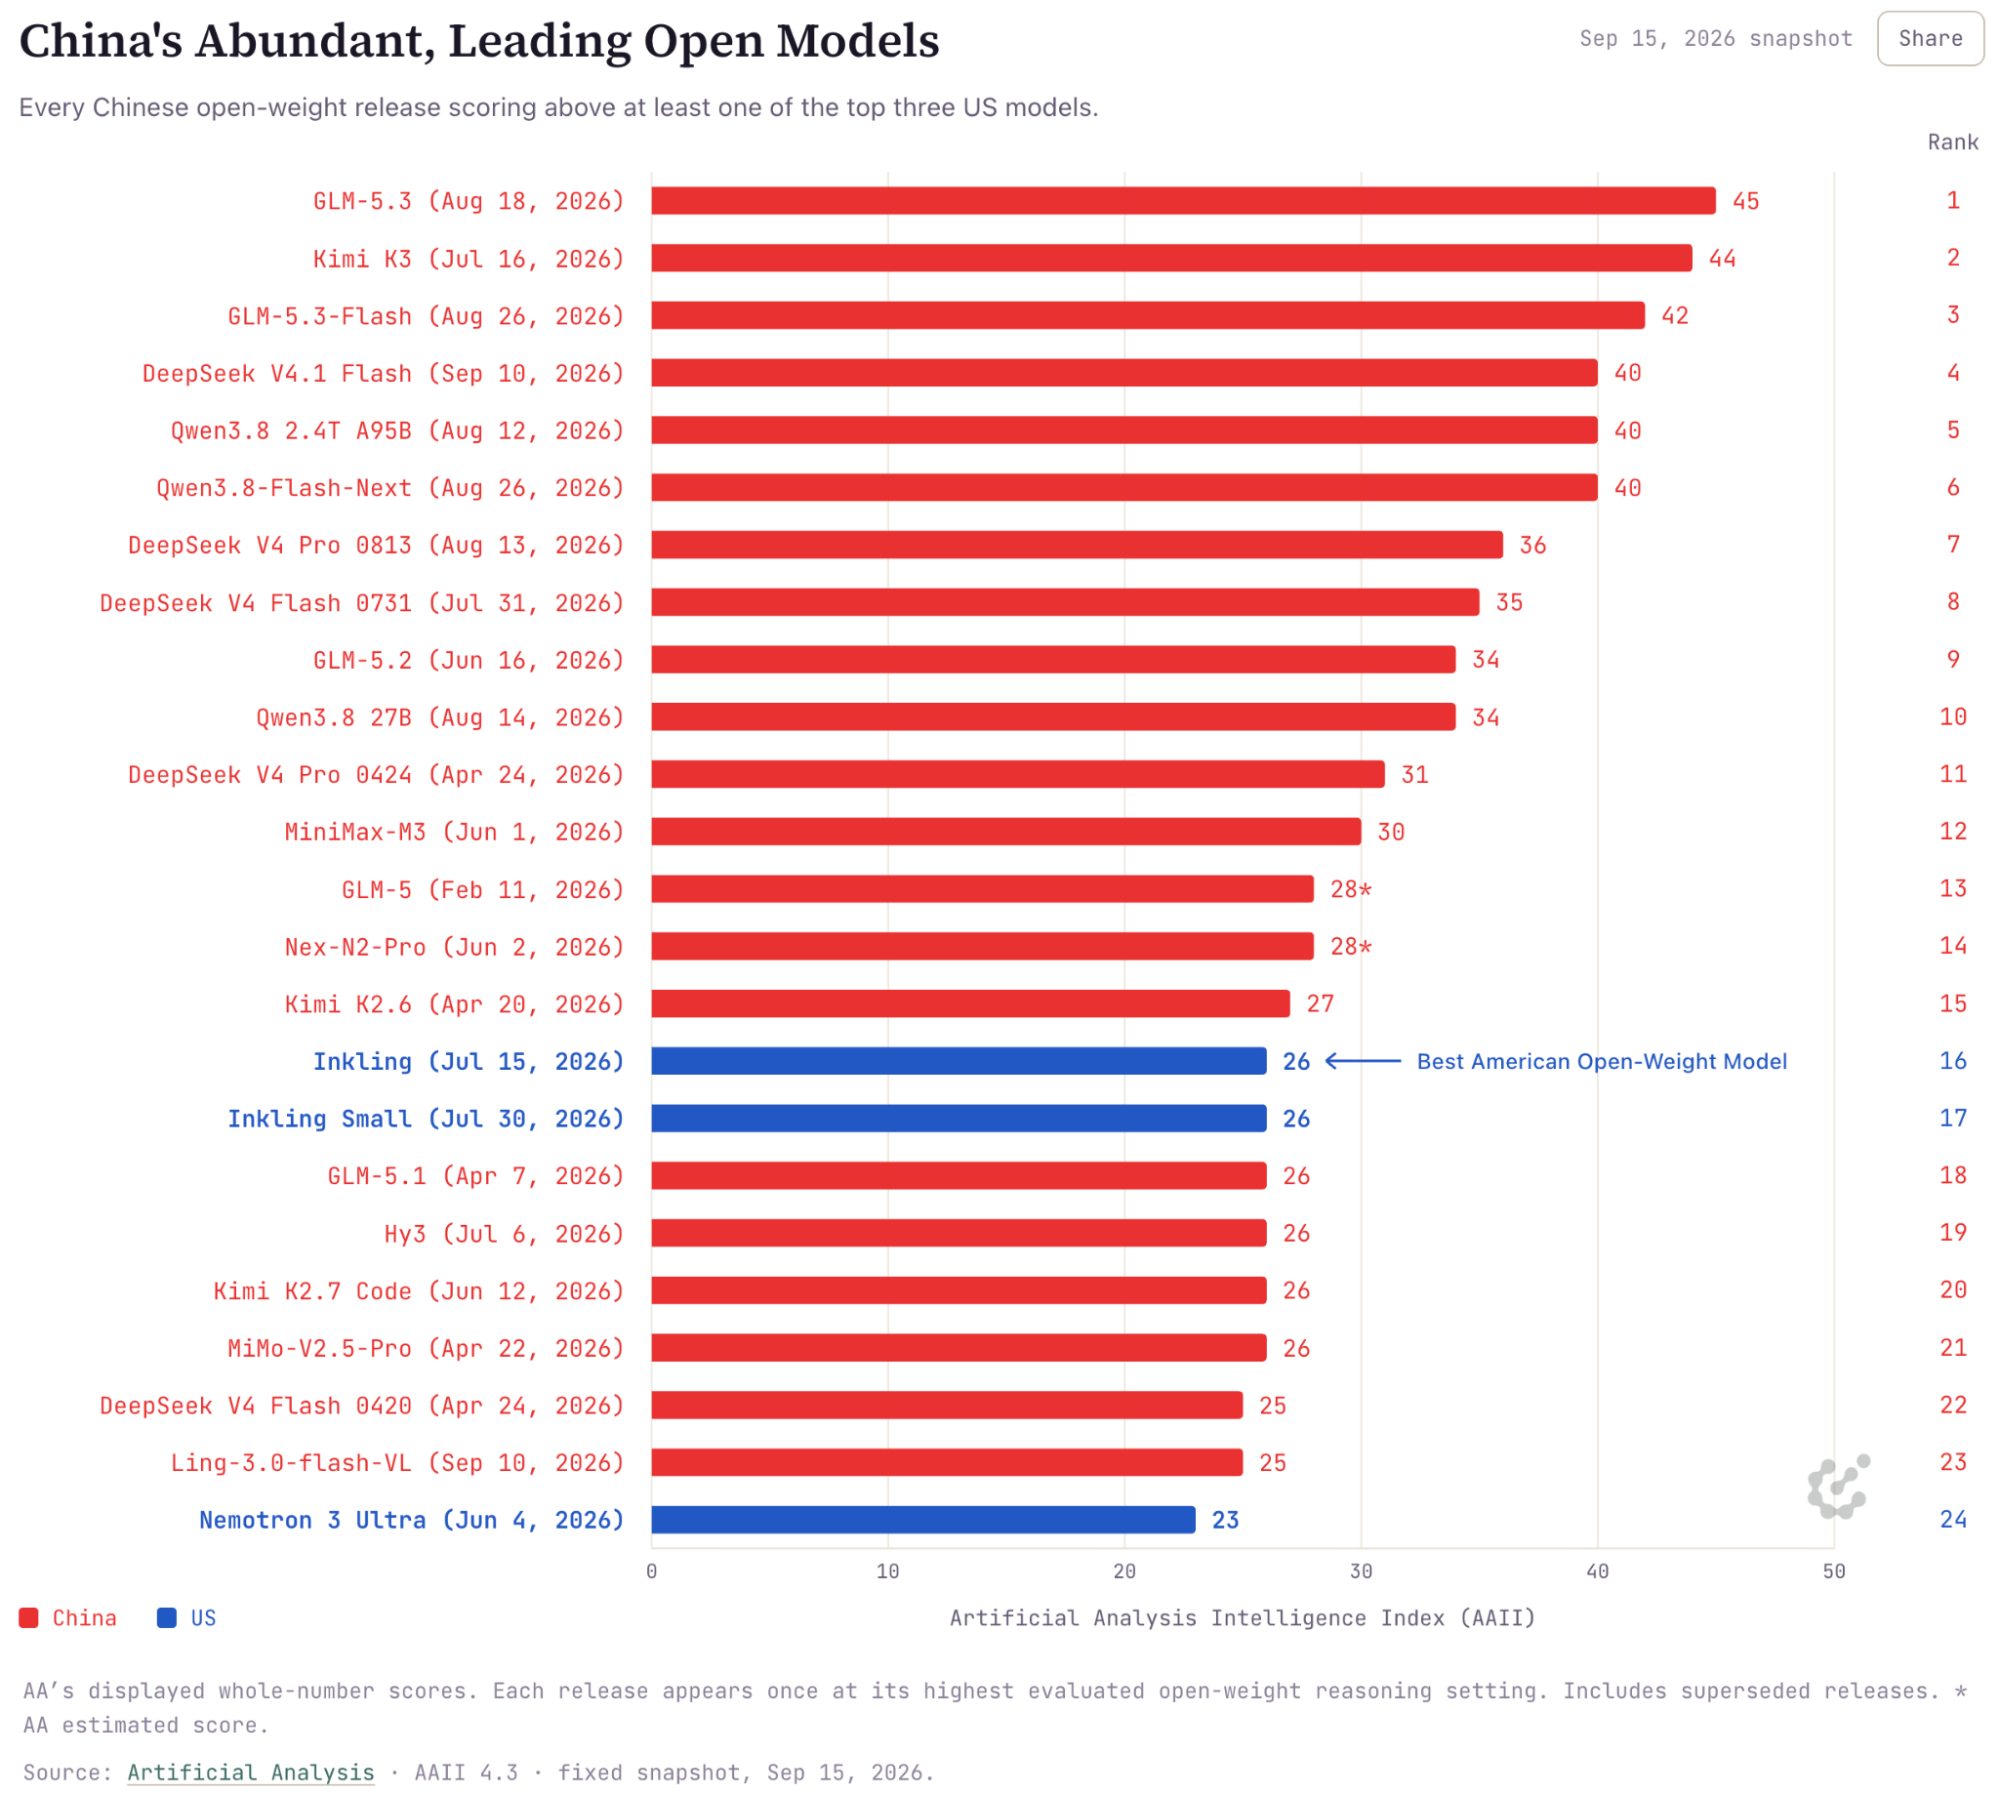
Together, Chinese open-weight fashions are roughly 2-5 months behind the closed American frontier, with the open-weight American fashions being roughly 6-9 months behind the likes of OpenAI and Anthropic. The Chinese labs are closest in duties with clear person demand, similar to agentic coding, and additional behind on extra open-ended scientific duties, similar to physics or biology.
The explanation why Chinese labs can produce these robust fashions, regardless of having fewer sources than American counterparts, continues to be an open debate and heavily influenced by different work cultures, however can be influenced by just a few key technical elements. The Chinese labs launch their fashions sooner and deal with a barely narrower distribution of duties, flattering them barely on public benchmarks. Releasing sooner helps them rating greater as a result of all of the labs are making constant progress, so when you “end” a mannequin to be launched, it’s a snapshot of efficiency at that given time — labs the place that point is later have a tendency to attain greater. Still, the fashions constructed by the Chinese labs are genuinely robust and characterize actual competitors to the American trade. This competitors won’t lower meaningfully because the closed labs patch vulnerabilities of their API choices which allow distillation.
Distillation is most impactful in new domains and doesn’t make it trivial to create a universally robust remaining mannequin. I estimate that if distillation was absolutely prevented, e.g. with know-your-customer (KYC) instruments at Anthropic and OpenAI, the hole from the strongest American fashions to Chinese open-weight fashions would solely enhance by 1-2 months.
For instance, the Chinese labs are quickly altering their posture in direction of paying for coaching knowledge in 2026. Earlier within the 12 months, the highest Chinese labs together with Moonshot AI and Z.ai had a powerful desire in direction of constructing knowledge workflows in-house, however by the summer time that they had begun to purchase the leading edge knowledge – difficult RL environments for agentic duties – from each established American firms and new Chinese startups.
With the advance of open weight fashions in China in direction of the frontier of capabilities, and the latest documentation of rising dangers round frontier fashions in areas similar to cybersecurity (e.g. the OpenAI-HuggingFace incident), there’s rising regulatory uncertainty on how continued releases can allow a safer ecosystem?
A structural problem in open-weight fashions is that there are few efficient strategies for stopping items of open software program from reaching unhealthy actors. If an try was made to limit entry to the strongest open-weight fashions from China as a result of they amplify dangers, the events who can be set again are American companies. We have an instance of this – HuggingFace used a Chinese open-weight model to understand the cyberattack as a result of closed fashions wouldn’t reply their requests. Thus, managing the dangers of open-weight fashions often comes down to ecosystem preparation.
Open-weight fashions have gotten a necessary device for AI diffusion, and the very best path to get forward of those dangers and unbalanced relationships the place American firms depend on fashions inbuilt China is to proceed to allow asset placement in open fashions within the US. Ownership of open fashions permits higher coordination and preparation of dangers which can be world of their nature whereas accelerating diffusion of AI companies all through the home macro economy.
Open-weight language fashions have grown considerably normally curiosity and financial viability in 2026, permitting early glimpses of extra direct methods to match adoption of fashions from the US, China, or elsewhere on high of Hugging Face metrics. One instance is OpenRouter utilization. OpenRouter is a well-liked LLM inference platform that provides a single interface to modify between fashions, open and closed, from the US and China. This platform is primarily recognized for making an attempt totally different open-weight fashions. The platform has shared utilization knowledge for the highest fashions since Jan. 1, 2025, and proven development in utilization from ~1T tokens processed from open fashions in per week of September 2025 to ~80T tokens per week at this time. In that point, Chinese models have grown from ~70% market share to over 80% of usage. Other platforms which can be designed to commercialize open fashions present comparable knowledge, such because the open-source coding agent OpenCode, which reveals an inference volume of ~95% or higher with Chinese models.
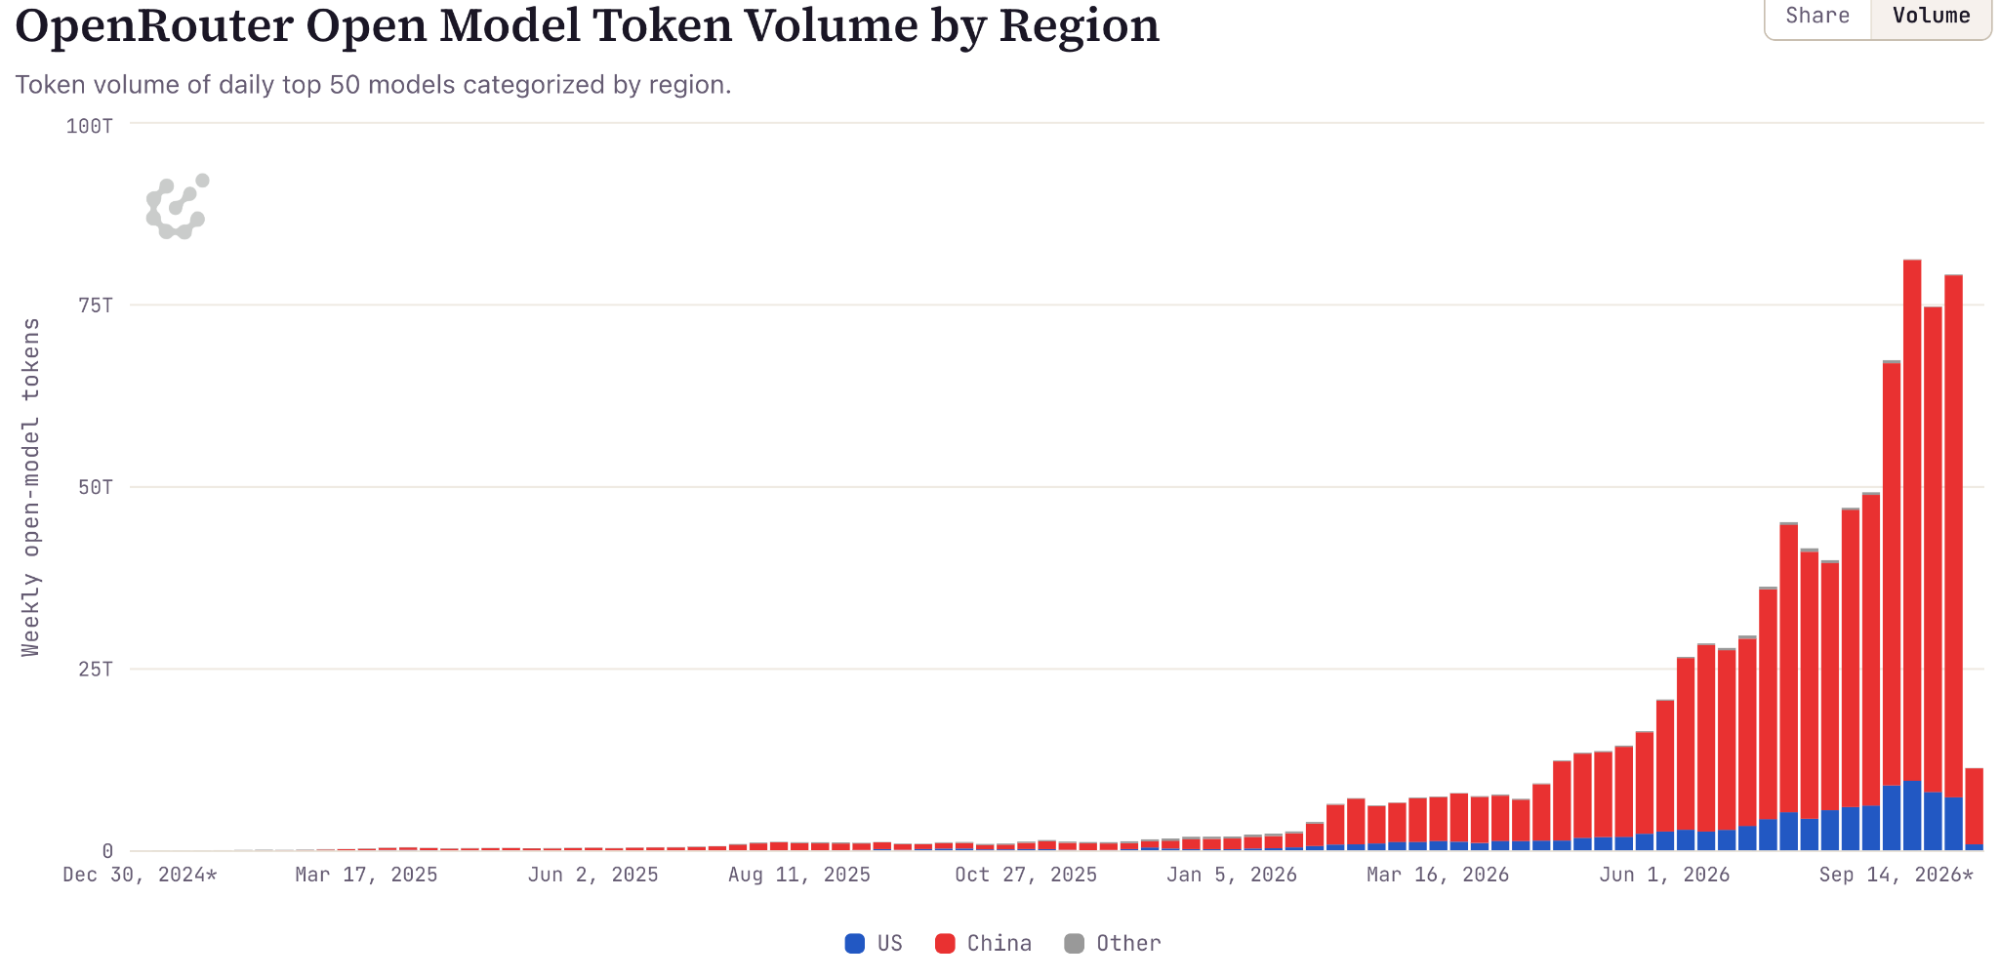
These open platforms are the very best approximation of open mannequin utilization we have now – a big proportion of open mannequin utilization is on platforms that don’t disclose per-model breakdowns, similar to Together AI or Fireworks AI, and in personal deployments for enterprise purposes.
Many distinguished expertise firms and startups have been constructing on Chinese open-weight fashions for his or her AI options, similar to Harvey, the authorized agent, Cursor, the coding agent, and DoorDash’s use of Kimi fashions, Airbnb’s use of Qwen, or Perplexity’s use of DeepSeek. These distinguished firms are the tip of the iceberg, the place a big swath of youthful Silicon Valley startups are constructing on Chinese fashions in an effort to have low-cost, versatile choices. There is a growing trend of American startups and companies entering enterprise agreements with Chinese mannequin labs in an effort to get permission to make use of their fashions of their merchandise – a brand new type of cross-border expertise collaboration I’ve not witnessed in my profession.
The basis of innovation on Chinese fashions extends additional into the AI ecosystem. To a primary order approximation, most of educational analysis is performed on Alibaba’s Qwen household of fashions. Having met a number of members of the Qwen management group during my trip to China, they’re very invested in and intentional about the sort of adoption, which won’t be simple to claw again to American fashions.
To quantify the adoption of open fashions throughout academia, I scanned each paper within the 5 hottest ML classes of arXiv (cs.AI, cs.CL, cs.CV, cs.LG, stat.ML), the preprint platform well-liked in AI analysis. The outcomes clearly observe my understanding of the evolving management in AI analysis, exhibiting LLMs turning into a foundational layer of ML analysis – mentions of any open mannequin had been 2% in January of 2023 and 50% in September of 2026 – and the main position shift from the U.S. to China in the identical time interval.
For instance, in April to May of 2023, just a few months after Meta’s unique Llama (a backronym, Large Language Model Meta AI, first launched in Feb. of 2023), about 2,600 of 12,000 new AI/ML papers on arXiv talked about at the very least one distinguished open mannequin household. Of all these scanned papers, ~5.5% talked about Llama and ~1% talked about a Chinese mannequin. In the autumn of 2024, throughout Llama’s peak, about 23% of papers talked about Llama with about 7.5% mentioning Qwen, essentially the most direct Chinese competitors. Today, Llama has misplaced its lead in academia, being talked about in about 21% of papers nonetheless, which is outstanding longevity, however Qwen’s share has risen to 30% of papers. Overall, any Chinese open weight mannequin is talked about in over 40% of papers, over the U.S.’s 30%, with China’s share persevering with to develop.
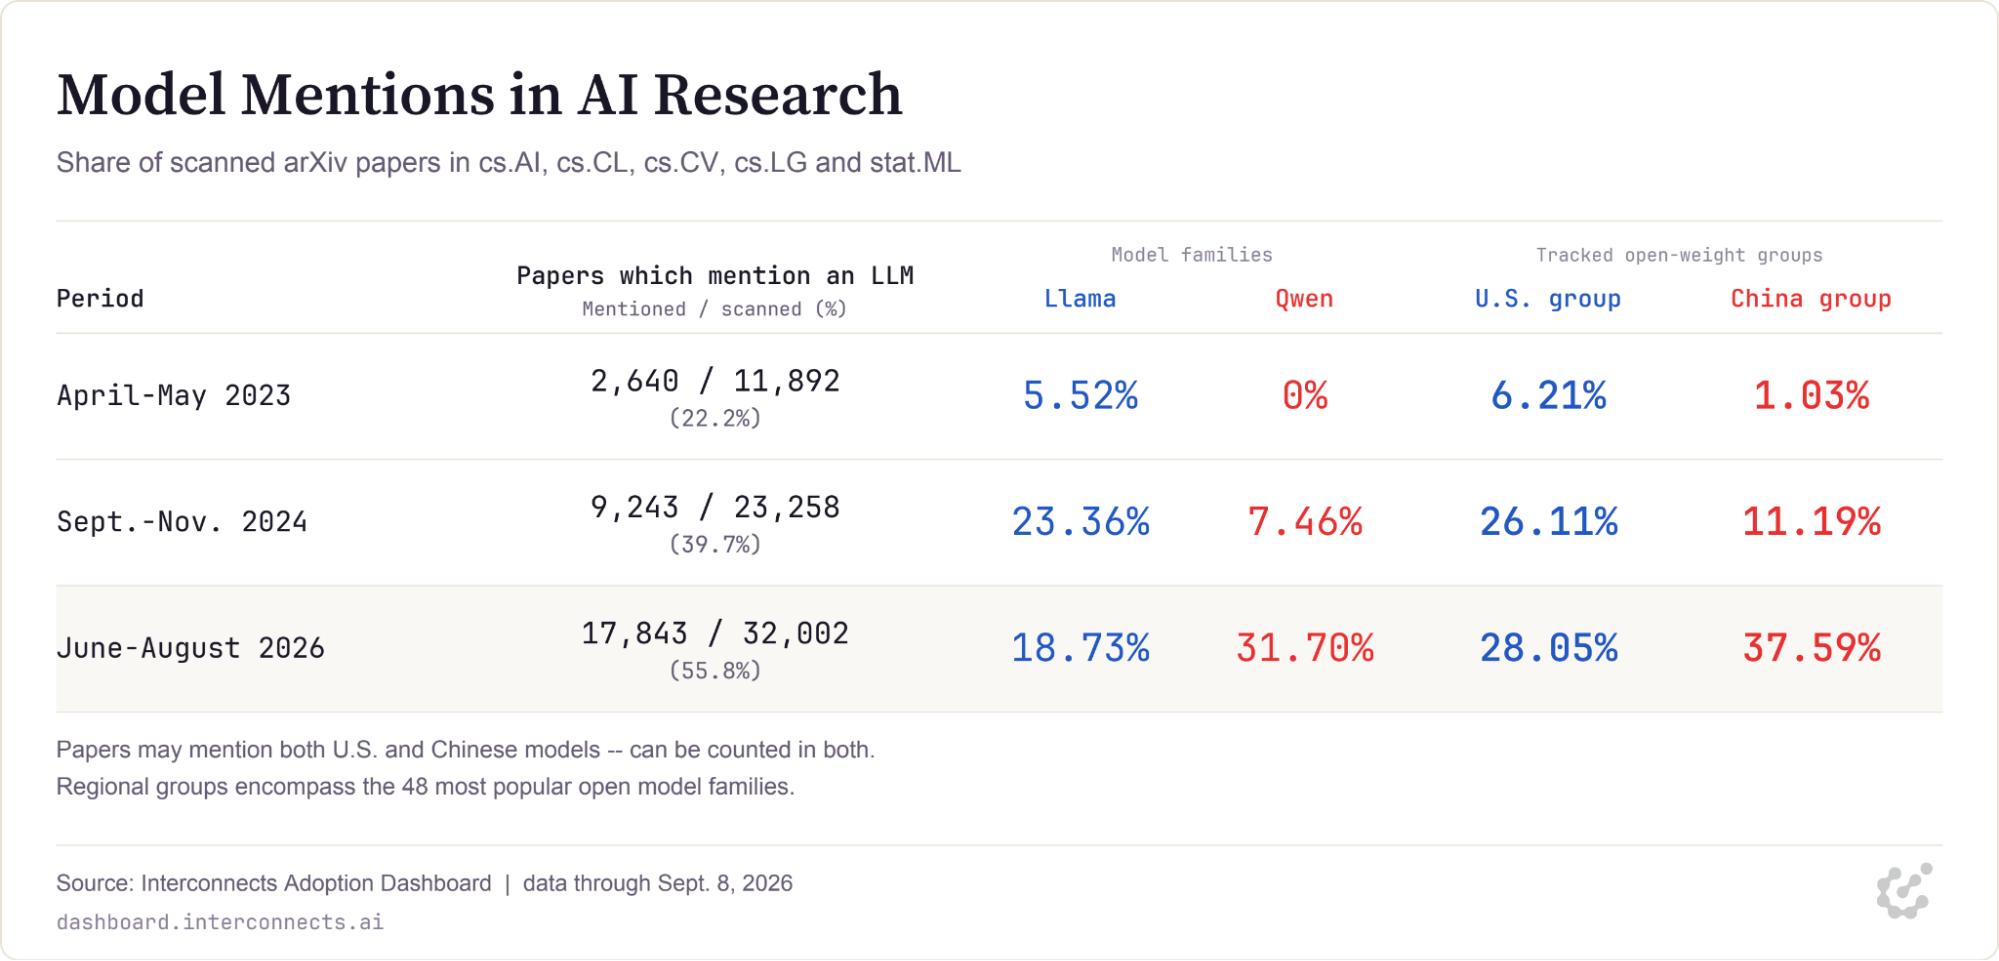
This reveals that we clearly have numerous work to do in an effort to re-establish the U.S. as the house of AI analysis within the period of open-weight language fashions. There are indicators of hope.
In our research, we discover that American fashions of comparable capabilities-to-size areas to their Chinese counterparts get adopted at disproportionate charges. In the final 12 months we’ve seen OpenAI’s first open-weight fashions since ChatGPT, gpt-oss, develop into one of the adopted open-weight fashions of all time. Since then, Google’s Gemma 4 fashions have been a few of the solely ones ever to point out comparable adoption numbers to Qwen’s hottest small fashions, and Nvidia’s Nemotron fashions have modest adoption regardless of quite a few extra succesful fashions on the similar dimension level.
The story of open fashions in 2026 is one in all establishing financial relevance. This is the convergence of many tales throughout the AI ecosystem, summarized as:
-
The capabilities hole from open to closed fashions out there to customers has been reducing over the past 3 years. This varies by job, however might be estimated as a 2-5 month hole in capabilities. With capabilities general progressing so quick, this has seen open-weight AI fashions unlock substantial bourses in 2026 and factors to extra inflection factors within the close to future.
-
Open mannequin utilization is exploding in high-value industries (e.g. software program engineering, legal services, financial services), indicating an emergence of another ecosystem to the very best closed fashions. Platforms providing inference totally on open fashions, from Together, OpenRouter, Fireworks, Baseten, and so on., are seeing unimaginable development as the primary winners of an open mannequin post-training macro economy (different layers embody finetuning APIs similar to Thinking Machines’ Tinker). This is mixed with quite a few anecdotes from technical employees within the AI trade that makes use of open-weight fashions similar to GLM-5.3 as a substitute for Claude or GPT on account of a mix of velocity, decrease costs, customizable choices, and privateness.
-
Chinese AI firms are the clear leaders in open weight fashions. Relative to 2025, the place Chinese fashions like DeepSeek R1 shook the AI international stage with shock, the American AI labs have been recovering of their positions with open-weight fashions, however regardless of extra substantial asset placement within the US, the Chinese labs recurrently are producing notably stronger fashions adored by many sorts of customers.
-
Distillation of American AI fashions by Chinese labs doesn’t clarify all the story of their success. Distillation is an trade customary method of coaching one other AI mannequin on the outputs from a normally stronger mannequin. The method is most prevalent within the Chinese AI trade, which has used primary exploits to extract reasoning traces and extra knowledge from American firms’ merchandise that aren’t absolutely secured. The finest estimates are that distillation helps scale back the efficiency hole of Chinese firms relative to the American frontier by 1-2 months.
-
Chinese fashions, notably Alibaba’s Qwen household, are established as a foundational layer of analysis and improvement throughout academia and native mannequin customers. In latest months, Chinese open weight fashions had been talked about in 38% of AI papers, above the U.S.’s 28% – and the Chinese share is rising a lot sooner than its American counterparts. This, together with different political elements and the closed nature of main American AI firms, is contributing to an accelerated decline in America’s lead because the preeminent AI analysis hub within the international stage.
-
Open weight fashions are coming into the potential ranges the place new dangers, e.g. cybersecurity, might be enabled by quite a few open-weight fashions being out there, necessitating an ecosystem degree response in preparation. This new period of dangers can be enabling a interval of political uncertainty, the place there’s regulatory consideration on the strongest AI fashions, however large uncertainty on how coverage can be legally enacted. At the identical time, many researchers and engineers rely on open models due to more permissive safeguards, the place the closed fashions similar to Claude and GPT typically refuse important cybersecurity defensive work or biology analysis.
For extra knowledge, view the Interconnects Dashboard.
In 2026 the Chinese labs are clearly sustaining their standing because the leaders of the open-weight AI ecosystem. This comes as open-weight fashions have handed an inflection level in financial viability and within the face of elevated exercise from American labs as mannequin competitors. The main Chinese labs don’t look like meaningfully challenged, as they broaden their enterprise and analysis adoption globally.
This panorama of open fashions comes at an important time within the broader AI ecosystem. We’re seeing OpenAI and Anthropic take large steps ahead with their newest public fashions, and on the similar time name for coordinated care on how we handle the following stage of AI progress. What is going on within the confines of some AI labs at this time, particularly with excessive expertise and compute density, is a precursor to what is going to quickly emerge within the open mannequin ecosystem. Open fashions are going to be the substrate for everybody else within the international stage exterior of the few true frontier AI labs, to harness an acceleration in software program engineering and different computational practices. This represents a considerable supply of sentimental energy, affect, and potential for the organizations that allow this broad entry to transformative intelligence.
With this future coming quickly, we have to collectively keep humble concerning the actual path open fashions will take. There are numerous unknowns with open fashions – e.g. we don’t have good knowledge on how they’re utilized in countries other than the U.S. and China. With the distribution of ML coaching experience being broad, i.e. tens of organizations and hundreds of individuals which can be inside a 12 months of the frontier of capabilities, it’s a matter of when, not if, open fashions cross the efficiency thresholds that allow new workflows. The collective method needs to be to know find out how to use this broadly accessible, open intelligence for good whereas proactively mitigating the potential harms.
Thank you to Florian Brand and Kevin Xu for suggestions and/or strategies for this work. For extra analysis informing this submit, see the open-source AI reading list.