Recursive Self-Improvement via Multi-Agent Self-Supervision
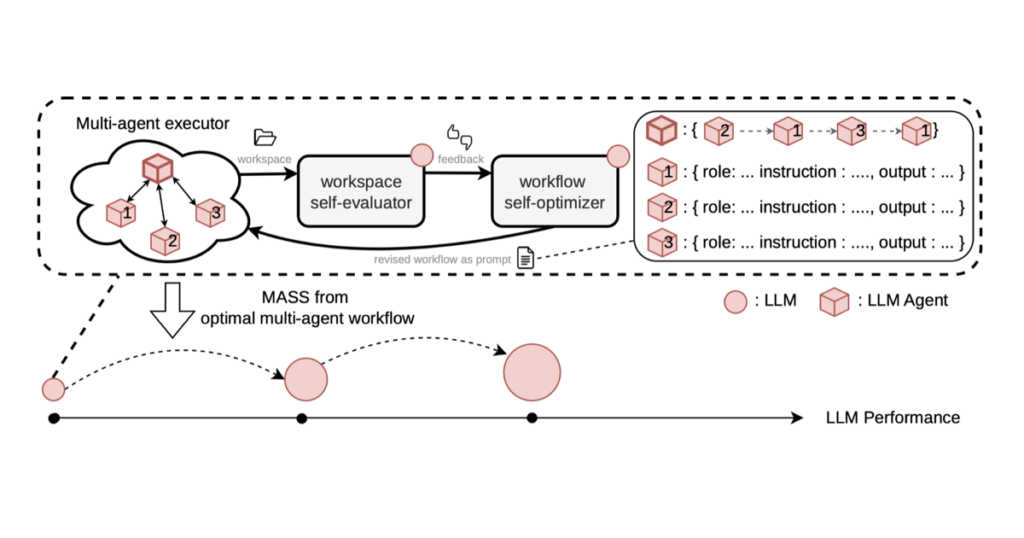
To advance past humanity’s amassed data, AI itself (the optimizee) can also be its greatest out there optimizer and evaluator. MASS repeatedly optimizes multi-agent workflows, then distills collective intelligence from multi-agent methods and makes use of it as a self-supervision sign for RSI. It improves rating per output token over the bottom mannequin on analysis benchmarks. We hope MASS contributes to AI’s Odyssean second: continuous self-learning in a setting the place the optimizee is the evaluator, and the optimizer is the optimizee.
Estimated studying time: 15 min
† Work carried out throughout an internship at Sakana AI.
Jan Collaert I, after Stradanus, The Invention of Book Printing, c. 1600. The Metropolitan Museum of Art, Harris Brisbane Dick Fund, 1934. Public domain (CC0).
We need frontier AI fashions to take us past the physique of information humanity has constructed over generations.
At that frontier, even human specialists might wrestle to evaluate outcomes and information additional progress, notably on non-verifiable duties
For instance, evaluating a proposed discovery might require scarce experience, expensive proof, or experiments that take far longer than producing the proposal. The mannequin itself might then inevitably be essentially the most succesful supervisor out there and want to determine for itself easy methods to enhance.
This motivates homogeneous recursive self-improvement (RSI), by which the mannequin being improved (optimizee) additionally serves as its personal optimizer and evaluator.
The central query is easy methods to acquire helpful self-supervision inside this homogeneous loop.
Human societies provide a helpful analogy for addressing this query. Across foraging communities, farming settlements, industrial societies, and international data networks, individuals have expanded their capabilities partly by dividing work, combining concepts, and passing on what they be taught
Inspired by this sample, we ask whether or not a mannequin can be taught from its personal crew’s collective intelligence, which an agent working alone might not reliably exhibit.
We introduce Multi-Agent Self-Supervision (MASS) to show this concept right into a studying loop. MASS makes use of the identical mannequin because the executor, optimizer, and evaluator. The optimizer first searches for one of the best crew workflow utilizing suggestions from the evaluator, then trains the executor on executions from the self-judged greatest crew. The up to date mannequin then fills all three roles, and the method repeats. Therefore, MASS supplies a self-supervision sign for RSI by distilling the crew’s collective expertise into the shared mannequin.
Homogeneous RSI
We examine homogeneous RSI, by which one shared language mannequin serves because the task-solving agent, workflow optimizer, and evaluator:
Agent
The process solver, or optimizee. Produces a workspace containing outcomes, plots, and a analysis report.
Workflow optimizer
Uses the suggestions from the evaluator to revise how brokers divide the duty, change outcomes, and test each other’s work.
Evaluator
Compares two workspaces, chooses which higher satisfies the duty, and explains the judgment.
We use non-verifiable analysis duties as coaching information. We use non-verifiable to imply that an computerized rule-based sign shouldn’t be out there and that solely a self-evaluation sign (whose correctness is unknown) guides the general studying loop.
To measure progress, we individually ask GPT-5.5 and Claude Opus 4.8 to evaluate the finished work. Their judgments are withheld from MASS. This provides us an out of doors measure of enchancment in a course of whose supervision comes from the mannequin itself.
How MASS works
MASS makes use of workflow optimization to elicit collective intelligence,
then distills the crew’s expertise into the shared mannequin.
The interior loop optimizes the crew’s workflow whereas the mannequin weights stay fastened. The mannequin evaluates and judges for itself which workflow is perfect.
The outer loop then updates these weights by studying from executions of the optimized workflow. The interactive diagram below follows each loops.
← swipe to see the entire determine →

0. Setup: workflow as a immediate
A workflow is a written plan for a way a multi-agent crew ought to work collectively. The orchestrator assigns work to subagents and integrates their outcomes. The plan is added to the duty immediate, making the crew’s group out there for the mannequin to examine and revise
- Role: the duty assigned to every subagent, reminiscent of making ready information.
- Instruction: the work that subagent ought to perform.
- Contract: the knowledge and artifacts it should return, together with any required checks.
- Hop: the order of subagent calls, together with any return to an earlier step.
For instance, an advanced finance workflow arranges information preparation, characteristic building, modeling, and backtesting right into a sequence, adopted by an audit. Its information contract requires express checks on the timing of the info:
Evolved finance workflow, condensed from the paper
Call order
  Data → Features → Modeling → Backtest
       → Audit → Reconciliation → Report

Data specialist's output contract
  validation_report:
    no_future_leakage:           bool
    train_end_before_val_start:  bool
    val_end_before_test_start:   bool
A backtest can look convincing if it lets historic selections use data from the longer term. This contract requires the info specialist to test for that error and report whether or not the time splits are legitimate. It additionally tells later brokers what proof they need to obtain earlier than continuing. Part of the analysis plan is thus expressed in what brokers should set up and move on to 1 one other
1. Inner loop: seek for a greater workflow
For every coaching process, MASS retains a champion: one of the best workflow discovered to date in keeping with the present mannequin’s judgments. Each iteration has three steps:
- 1Execute. The crew follows the candidate workflow and produces a workspace.
- 2Evaluate. The evaluator compares this workspace with the champion’s workspace and explains which is best. A successful candidate turns into the brand new champion.
- 3Revise. The optimizer makes use of the suggestions historical past to suggest the subsequent workflow.
The evaluator judges the finished work; the optimizer makes use of that judgment to revise the method that produced it. Optimizer’s system immediate emphasizes contracts and hop, directing workflow search towards what data brokers change and once they obtain it.
2. Outer loop: be taught from the chosen crew
Even with an optimized workflow, the standard of long-horizon analysis work can range from run to run. MASS subsequently executes self-judged optimum workflows (or champion workflows, that means the optimum workflows discovered to date) with a number of random seeds and makes use of the present mannequin to rank the ensuing workspaces, retaining the highest-ranked trajectories. Each trajectory data the messages, software calls, and power outcomes of the orchestrator and its subagents.
- 1Run the champion workflow 18 occasions for every process.
- 2Use the present mannequin to evaluate and rank the ensuing workspaces
A Bradley–Terry mannequin converts the pairwise preferences right into a rating for every workspace. . - 3Retain as much as 16 trajectories per process: 15 for coaching and one for validation.
- 4Remove the workflow textual content from the orchestrator’s preliminary immediate when establishing the coaching examples.
- 5Fine-tune the shared mannequin with LoRA
on each orchestrator and subagent conversations. The mannequin’s outputs are the coaching targets; process prompts and power outcomes present context.
Removing the workflow from the orchestrator’s coaching immediate encourages the mannequin to discover ways to manage the work from the duty itself.
Results
We run two full rounds of MASS ranging from Qwen3.6-27B within the qwen-code coding-agent surroundings. Our artificial analysis suite accommodates 12 duties in finance, robotics, and pharmacy, every requiring code, quantitative outcomes, and a analysis report
We evaluate three generations: the bottom mannequin (mathcal{L}^{(0)}), the first-round mannequin (mathcal{L}^{(1)}), and the second-round mannequin (mathcal{L}^{(2)}). We look at the standard of their work, their capacity to arrange and choose it, and their use of coordination with out a equipped workflow.
Better process efficiency
On the three artificial check duties, the win fee in opposition to the bottom rises from 53.9% after one spherical to 69.9% after two rounds (Table 1). The second-round mannequin additionally wins 60.8% of comparisons in opposition to the first-round mannequin.
| Evaluation duties | Round 1 vs. base | Round 2 vs. base | Round 2 vs. spherical 1 |
|---|---|---|---|
| Training duties | 65.6% | 82.5% | 68.1% |
| Test duties | 53.9% | 69.9% | 60.8% |
To check switch past the artificial analysis suite, we consider public benchmarks. After two rounds, rating per output token reaches 1.2–1.6× the bottom mannequin’s stage throughout MLR-Bench, DSBench, ScienceAgentBench, and AstaBench (Figure 3)

The good points are strongest on 4 analysis benchmarks resembling the coaching duties. Score per output token is 0.96× the bottom worth on Terminal-Bench 2.0 and 0.94× on SWE-bench Verified
Observation 1. Role generalization in RSI
We observe that MASS allows position generalization in RSI. We prepare the mannequin solely on task-solving trajectories and observe that the capabilities of the workflow optimizer and workspace evaluator additionally enhance. This allows RSI loop to be sustainable.

Figure 4 reveals optimizer can discover profitable workflows sooner as cycle goes by.
In truth, Figure 4 is technically not a particularly reasonable comparability, since ( L^{(0)}) denotes a setting by which the bottom mannequin (optimizer) updates the bottom mannequin (optimizee), and ( L^{(1)}) denotes a setting by which the first-round mannequin (optimizer) updates the first-round mannequin (optimizee). For a good comparability, we give the first-round mannequin’s workflows to the bottom mannequin (Table 2). We observe that the bottom mannequin with first-round search workflows wins 64% of comparisons in opposition to the bottom mannequin with base-search workflow.
| Executor | Workflow supply | Compared with | Win fee |
|---|---|---|---|
| Round 1 | Round-1 search | Base executing base-search workflows | 80% |
| Base | Round-1 search | Base executing base-search workflows | 64% |
| Base | Round-1 search | Base with out a workflow | 63% |
The evalutor additionally transfer nearer to these of the robust exterior mannequin judges (extra particulars in paper). Agreement with these exterior judges rises from 73% to 93% throughout the three cycles. Overall, these outcomes counsel that task-solving examples can even enhance capabilities used to supply and choose the subsequent spherical’s coaching information.
Ablation 1: Optimal workflow maximizes data circulate
What actually makes an optimum multi-agent workflow efficient?
We analyze the roles, directions, contracts, and hops of the champion workflows (one of the best workflows discovered to date). For every part, we estimate how a lot its textual content reveals in regards to the process. In the finance instance above, a job reminiscent of “cautious information scientist” may apply to many duties. A contract specifying leakage checks for a buying and selling backtest is way more distinctive

Figure 5 reveals that between the primary and last iterations of workflow optimization, an optimum multi-agent workflow tends to encode process data extra strongly in contracts and hops and fewer in roles and directions. We don’t present this right here, however mutual dependencies among the many elements usually lower too (attention-grabbing!). This sample means that the LLM optimizer evolves the workflow elements to be mutually impartial however optimizes the knowledge circulate by way of contracts and hops (see this blog post for deep, intuitive explanations). I’d say that workflow optimization over discrete elements resembles discovering a foundation vector for that harness area.
Observation 2: Multi-agent trajectories present a dense RSI sign
We observe that trajectories from multi-agent methods could be simpler than trajectories from single brokers in RSI. Multi-agent execution additionally modifications the construction of the coaching information. The orchestrator’s dialog reveals easy methods to divide a broad process into targeted assignments and coordinate their
execution. A subagent’s dialog reveals easy methods to perform a person project. Specifically, we observe that collectively studying coordination from the orchestrator and bounded execution from subagents supplies simpler
supervision per coaching token than studying from lengthy single-agent trajectories (Figure 6)
We evaluate college students educated independently from the identical base mannequin on single-agent trajectories (S, S+, S++), multi-agent trajectories (M, M+), and a combination (X). A plus signal denotes a bigger coaching set; M+ is the first-round MASS mannequin. All factors under report outcomes pooled throughout 4 coaching duties and one check process.

Against the bottom mannequin, M+ reaches a 68.3% win fee after processing 28.8M supervised coaching tokens, whereas S++ reaches 64.0% after 42M tokens. The MASS mannequin thus achieves the upper rating in opposition to this reference with 31% fewer supervised tokens
Higher-quality trajectories might contribute to this benefit. In a separate evaluation, robust exterior judges choose the multi-agent methods’ work in 85.1% of comparisons with single-agent outputs. Team runs additionally generate about 2.4× as many tokens on common
These outcomes counsel that trajectories from multi-agent methods could be simpler than trajectories from single brokers in RSI, extending their worth past test-time scaling.
Observation 3. The RSI bottleneck could be the optimizer, not the evaluator
We noticed that the bottleneck in RSI could be the optimizer, not the evaluator. We stored the bottom mannequin as the duty solver and swapped in a stronger exterior mannequin (GPT-5.5) for the evaluator solely, or for each the evaluator and the optimizer.

Figure 7 reveals that upgrading solely the evaluator helps a bit, however upgrading the optimizer as nicely helps loads. The strictly homogeneous self-improvement loop does finally discover successful workflows for 11 of 12 duties; it simply takes longer. Our interpretation is that the robust evaluator might present high-quality suggestions, however the weak optimizer shouldn’t be succesful sufficient to digest it. This means that, underneath a restricted price range, one might must prioritize the optimizer over the evaluator inside an RSI loop unit.

Figure 8 additionally reveals that workflow search is noisy. In text-space optimization, reaching a great workflow and enhancing on it stably are completely different issues. This means that the LLM optimizer may have an equal of a learning-rate scheduler to stabilize the search in textual content area.
Conclusion
In Tennyson’s Ulysses, Odysseus imagines one other voyage in pursuit of information “Beyond the utmost certain of human thought.”
The problem considerations each who can supervise additional studying and the way progress ought to be judged. Human specialists might be able to state a objective with out specifying an goal perform that absolutely captures it.
Writing is an effective instance: professional writers can acknowledge robust writing, but wrestle to precise their judgment in a rubric that applies reliably throughout contexts.
For RSI, the analysis query is how AI can flip incomplete human steering into helpful standards for studying, and easy methods to check whether or not these standards proceed to seize the meant objective as its capabilities develop.
This turns into particularly difficult when the mannequin being improved additionally serves as its personal optimizer and evaluator: the judgments that information enchancment should themselves stay open to correction.

Keeping a system’s self-evaluation open to correction can be important for security. In a homogeneous loop, a shared blind spot may permit a flawed consequence to be produced, accepted as an enchancment, and included into the subsequent mannequin. If people additionally wrestle to acknowledge the flaw, successive updates might reinforce it. The security concern is that the identical weak point can compromise each the system’s conduct and the mechanism meant to right it.
In this sense, shared blind spots could also be an Achilles’ heel of recursive self-improvement. Understanding them issues for controlling a extra succesful system as a result of it reveals the place reliance on the system’s personal judgments is least justified. That data may information impartial checks, constraints on autonomous actions, and circumstances for intervention. Identifying a weak point alone doesn’t set up management; we should additionally present that we will detect its penalties and intervene successfully because the system modifications.
OpenAI’s analysis on chain-of-thought monitorability illustrates one a part of this problem: reasoning traces might help reveal misbehavior, however they supply incomplete proof