Postgres recovery_prefetch Thought-about Dangerous and Inflicting Outages – Ardent Efficiency Computing
Another story of one thing I noticed within the subject which shocked me. Turns out recovery_prefetch could cause outages.
Something which has been taking place quietly within the background on a regular basis, however we didn’t discover till we appeared shut sufficient to see it.
After numerous work I found this was partly a case the place somebody had dropped an electronic mail to the postgres hackers record years in the past “hey what about this” and everybody thought “nah it might probably’t be that unhealthy” … and now right here we’re seeing manufacturing outages!
Exhibit A: Feb 2021, whereas the function was being developed, a yr and a half earlier than it shipped, Stephen Frost
- Issuing pointless prefetches for blocks we’ve already despatched a prefetch for is arguably a priority even when FPWs are off however the advantage of doing the prefetching nearly actually will outweight that and imply that discovering a method to handle it’s one thing we may actually do later as a future enchancment. I wouldn’t have any difficulty with that. Just doesn’t appear as clear-cut to me when serious about the FPW-enabled case. Ultimately, when you, Andres and Munro are all not involved about it and nobody else speaks up then I’m not going to pitch a fuss over it being dedicated, however, as you mentioned above, it appeared like level to boost for everybody to contemplate.
https://www.postgresql.org/message-id/[email protected]
Exhibit B: Mar 2025, clear report from the sector, Michael Zhilin (Postgres Pro)
- One buyer complained that bodily standby has vital replay lag (few hours) on fashionable highly effective naked metallic servers. According to output of “prime”, startup course of and few kernel employees utilized CPU, largely in kernel house. The incident has been resolved by disabling recovery_prefetch after fast evaluation of perf and strace outputs. Actual XLog prefetching code doesn’t contemplate that shared buffer could also be loaded from WAL FPI quite than from disk and makes fadvise calls in such instances.
https://www.postgresql.org/message-id/9bdb428a-fc8e-4801-8fff-1ad0bc6fa76b%40postgrespro.ru
Both of those emails have been heading in the right direction, however didn’t fairly get the whole image but.
First: FPI/FPW is ubiquitous at this time. While it’s very costly by way of efficiency, it’s the one manner Postgres has of defending from torn writes on OS restarts. As a outcome, the vast majority of manufacturing Postgres installations at this time (group oss model) allow this.
Second: synchronous replication is changing into extra frequent. There are actually solely two methods to fully shield group open supply postgres in opposition to information loss on {hardware} failures: (1) storage layer replication with oss tech like DRBD or costly proprietary storage & clustering expertise or (2) database layer safety with postgres synchronous replication. The second choice is the traditional answer with kubernetes and commodity {hardware}.
Third: one thing that hasn’t beforehand been recognized/reported – the issue with recovery_prefetch isn’t nearly FPIs, it’s additionally about the truth that when the first occasion does massive sequential I/O, recovery_prefetch converts these operations into 8k random reads. For the identical variety of bytes learn, this amplifies IOPS as a lot as 16x on replicas. This can simply exhaust accessible IOPS, inflicting replicas to considerably lag after write exercise.
The learn IOPS amplification mixed with Postgres design for synchronous replication is what turns recovery_prefetch into an precise outage-inducing killer. And it seems that is trivial to breed as soon as you understand the steps.
- Start up postgres with synchronous replication to a standby, on small servers with cheap exhausting drives (for instance: cloud disk with 500 IOPS, 2 CPUs, 8GB reminiscence)
- Initialize pgbench scale 640 for about 10GB information
- Disable autovac on pgbench_accounts simply so it doesn’t intrude with the experiment.
- Run pgbench at 5 TPS mounted in a terminal you may watch.
- Update 5% of the desk. (Checkpoint and replace pgbench_accounts the place aidpercent20 = 0.) This generates a burst of write exercise. Pgbench will decelerate till it finishes. Wait for this to finish.
- Kill the walreceiver course of to emulate community/system grasp or instability that disrupts this connection.
- TPS drops to zero and all writes grasp for over half-hour (could be hours with bigger pgbench desk).
It actually is that this straightforward to constantly reproduce this outage. https://github.com/ardentperf-labs/walreceiver-outage-repro
And for what it’s value, VACUUM itself is sort of able to producing write exercise too. The recipe for an outage is solely “sufficient unhealthy luck”: a community glitch that interrupts streaming replication similtaneously a burst of write exercise.
To perceive why the entire system hangs, it actually comes down to 2 easy issues: (1) synchronous replication and (2) the core “state machine” that defines a Postgres Standby Server.
Remember that with synchronous replication, we’re relying on a minimum of one wholesome standby server – in any other case we are able to’t take writes. (We need to assure sturdiness to shoppers and guarantee each transaction is on a distant machine earlier than commit.)
The core standby server state machine is defined in src/backend/entry/transam/xlogrecovery.c:
WaitForWALToBecomeAvailable(XLogRecPtr RecPtr, bool randAccess,
							bool fetching_ckpt, XLogRecPtr tliRecPtr,
							TimeLineID replayTLI, XLogRecPtr replayLSN,
							bool nonblocking)
{
	static TimestampTz last_fail_time = 0;
	TimestampTz now;
	bool		streaming_reply_sent = false;

	/*-------
	 * Standby mode is applied by a state machine:
	 *
	 * 1. Read from both archive or pg_wal (XLOG_FROM_ARCHIVE), or simply
	 *	  pg_wal (XLOG_FROM_PG_WAL)
	 * 2. Check for promotion set off request
	 * 3. Read from major server by way of walreceiver (XLOG_FROM_STREAM)
	 * 4. Rescan timelines
	 * 5. Sleep wal_retrieve_retry_interval milliseconds, and loop again to 1.
	 *
	 * Failure to learn from the present supply advances the state machine to
	 * the subsequent state.
...
...
Fundamentally it appears like this:
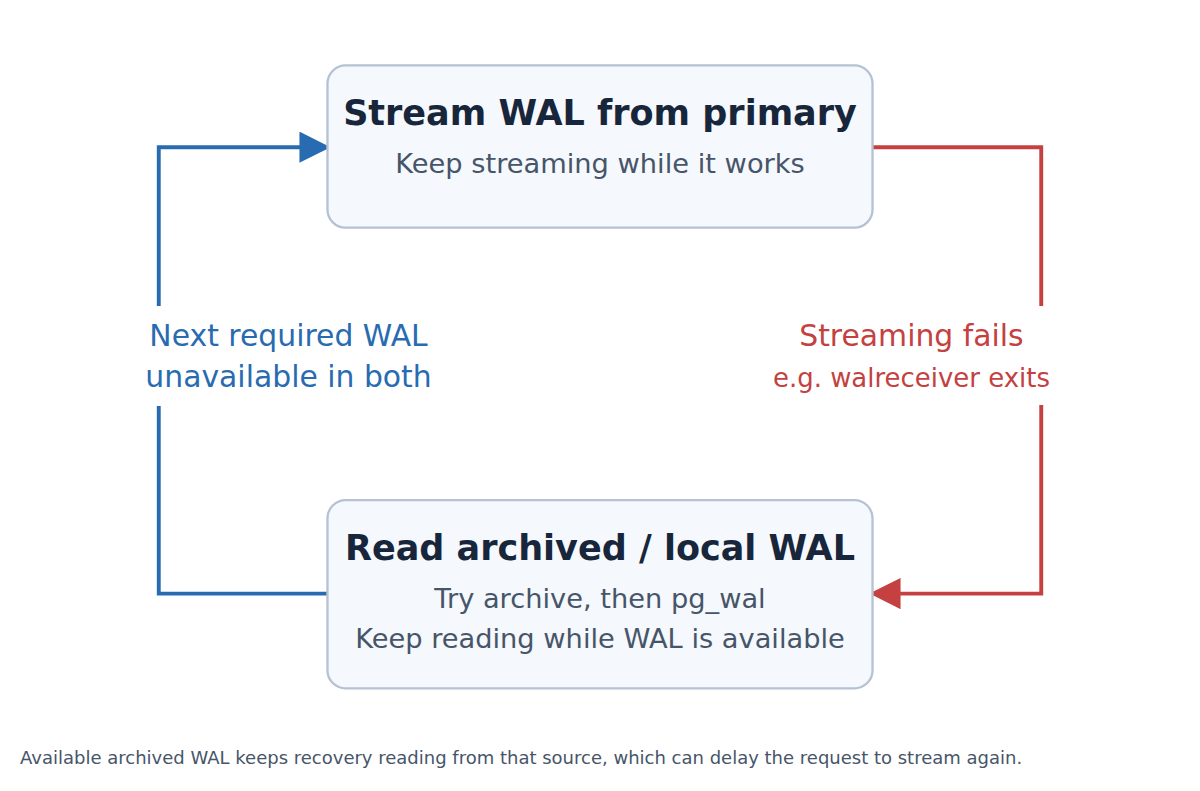
Basically, when a Postgres standby switches into WAL-restore mode, it is not going to return to streaming till it’s caught up.
A burst of write exercise mixed with IOPS amplification on all of the replicas that causes vital lag can simply imply the database gained’t begin streaming once more for hours.
The IOPS amplification could be very clear. Here are the disk stats for the first (perhaps 5 minutes round 300 IOPS):
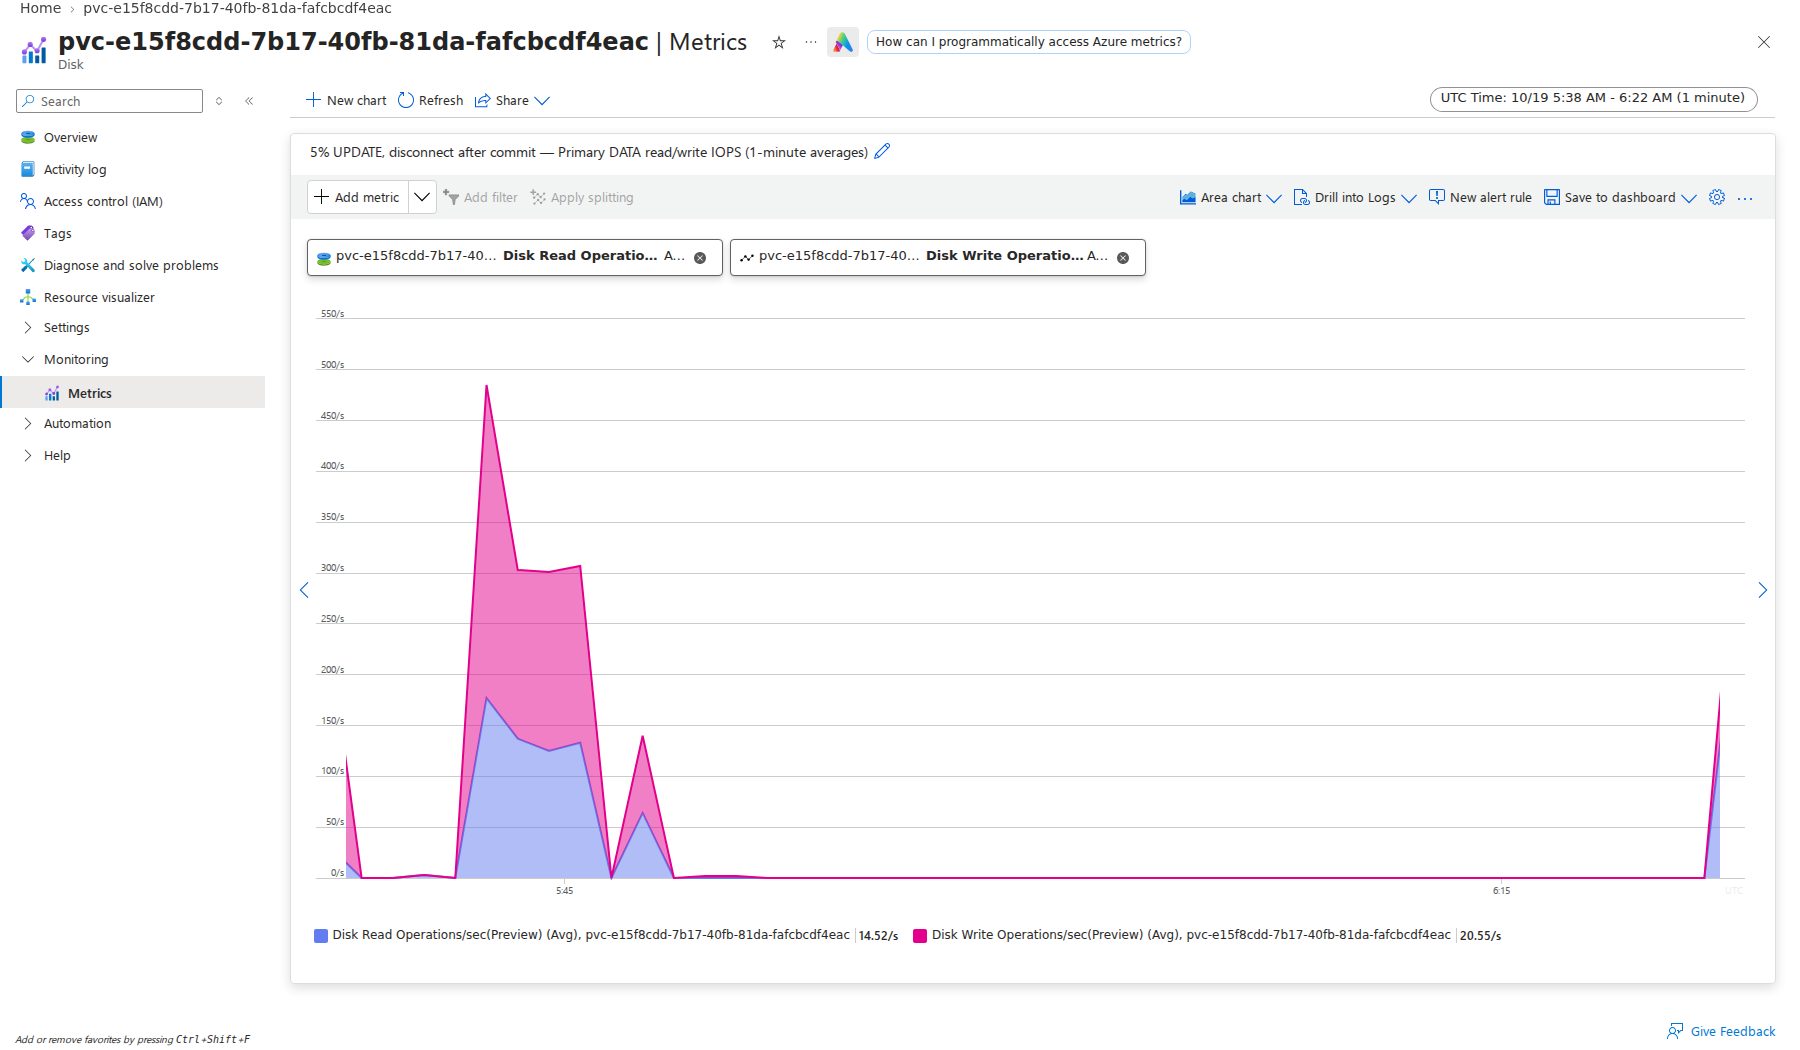
Here are the disk standing for the duplicate/standby throughout the identical time interval (40 minutes on the disk restrict of 500 IOPS):
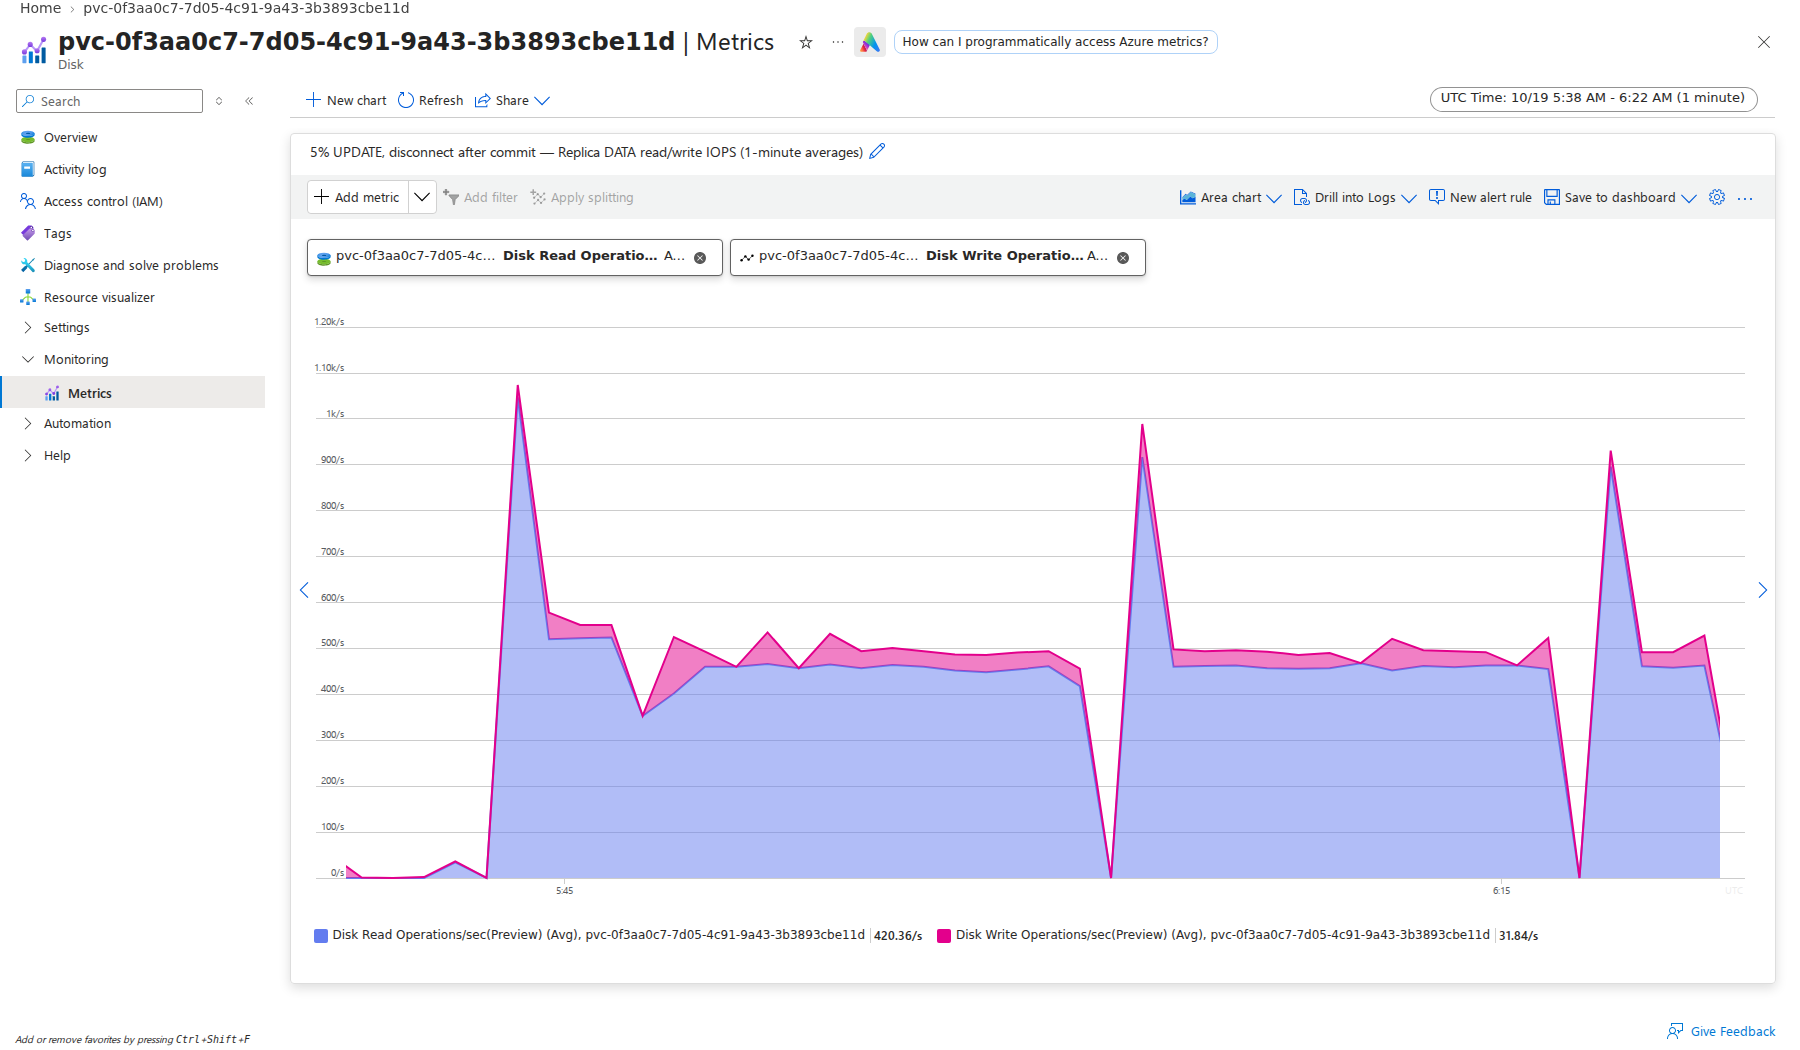
These charts don’t illustrate it, however the variety of bytes learn from disk is about the identical.
What occurs if we disable recovery_prefetch? (Note that FPWs stay enabled.)
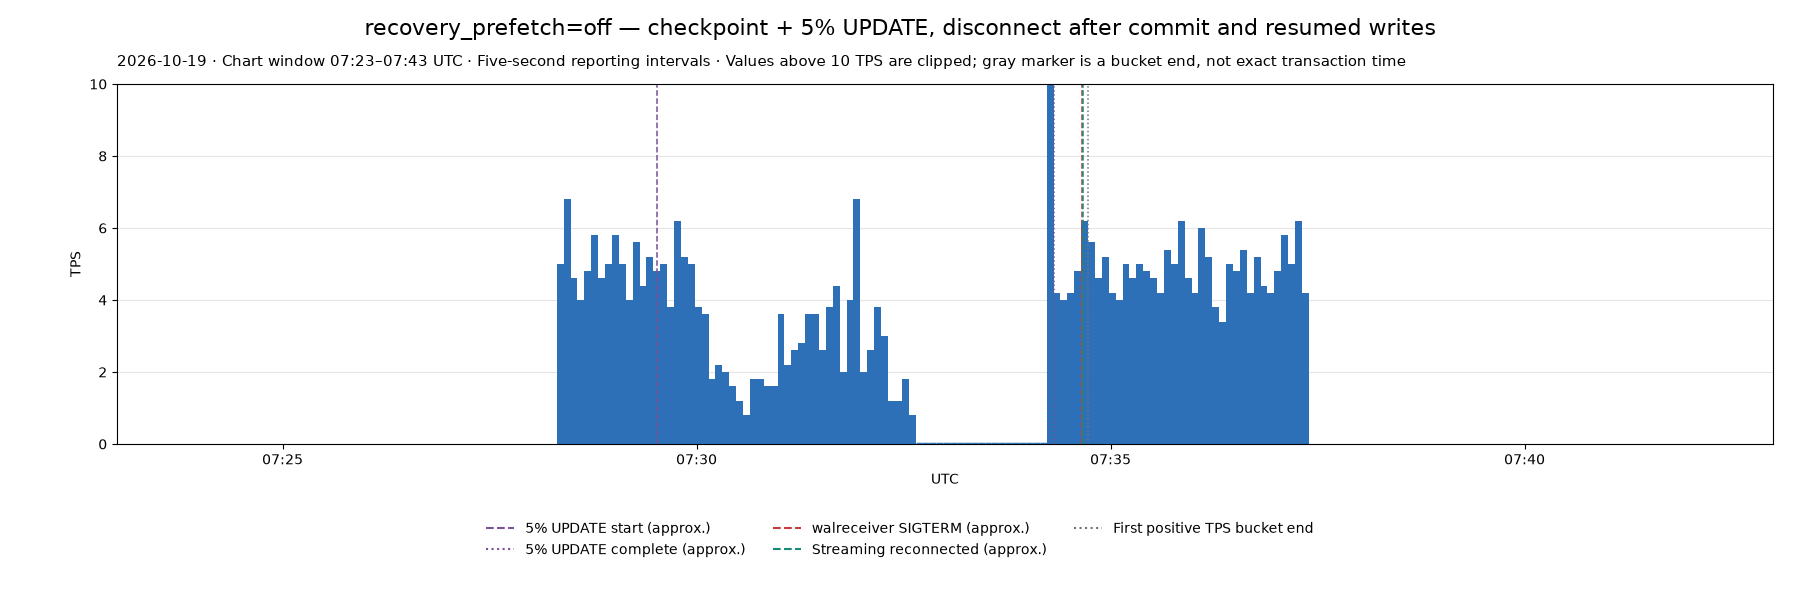
There’s nonetheless the pause throughout UPDATE however we didn’t see the lengthy pause after UPDATE completes.
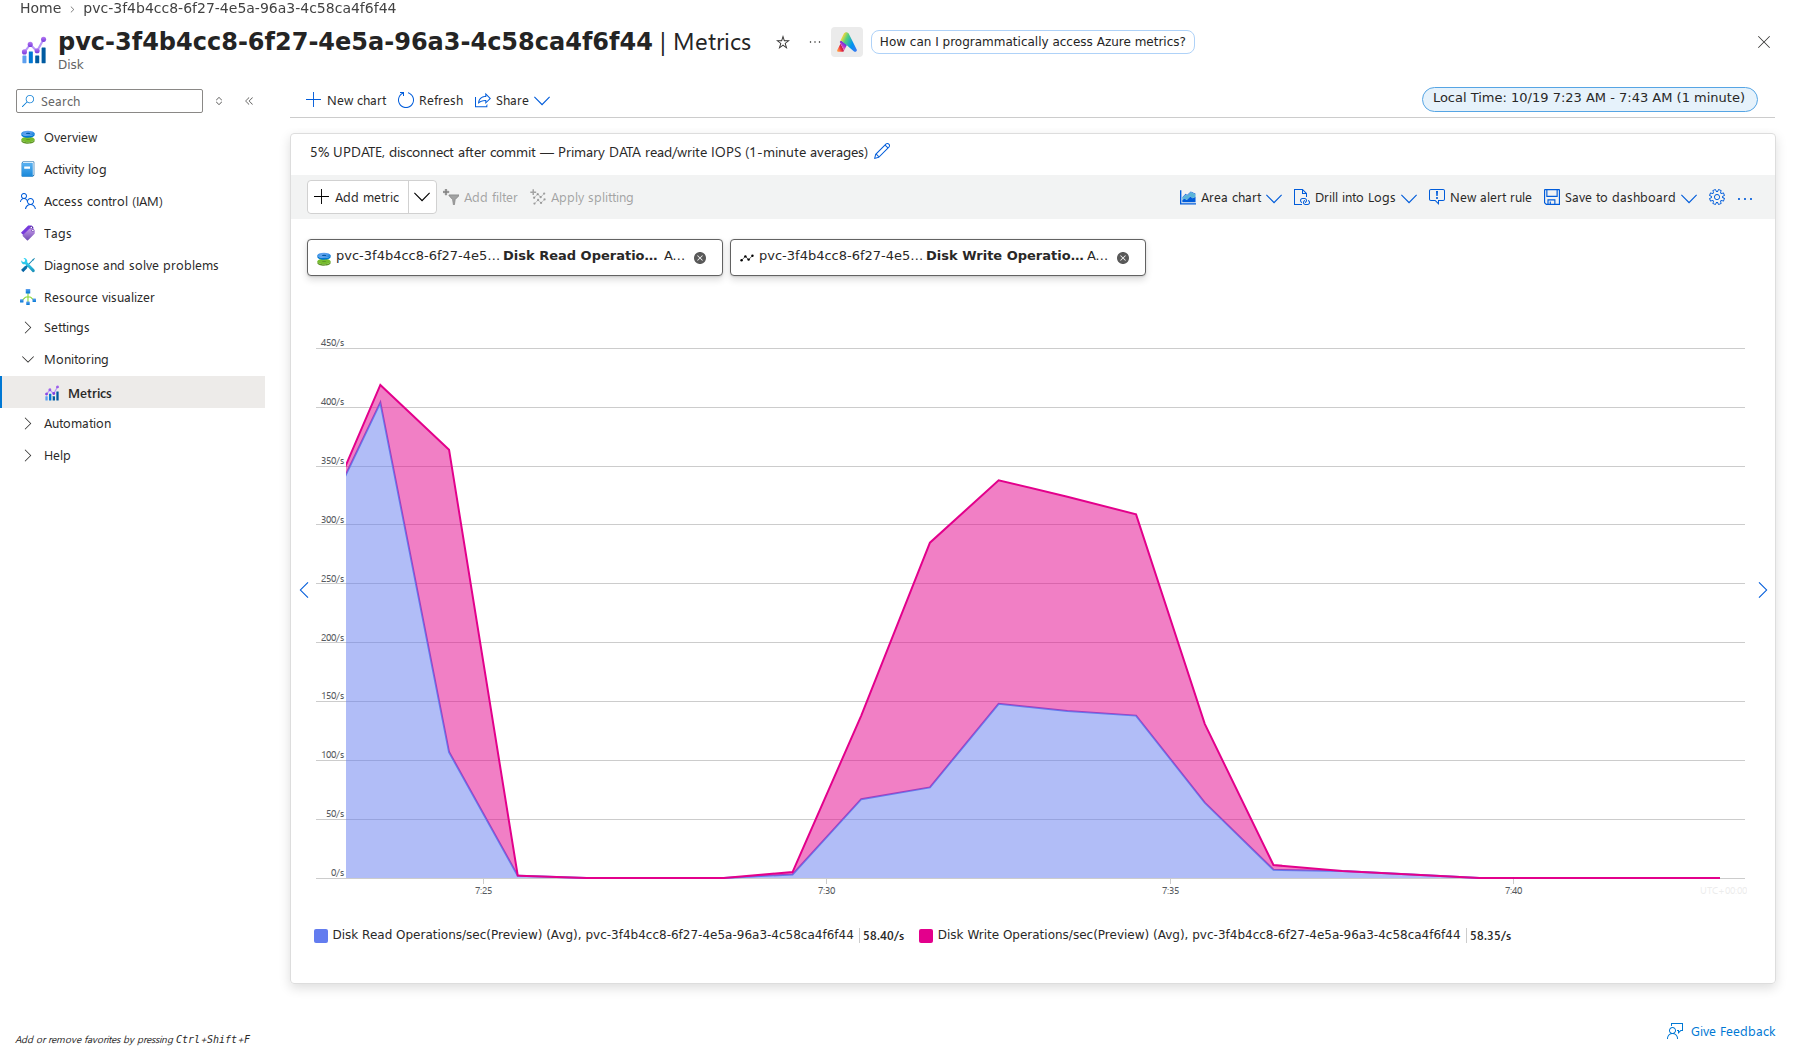
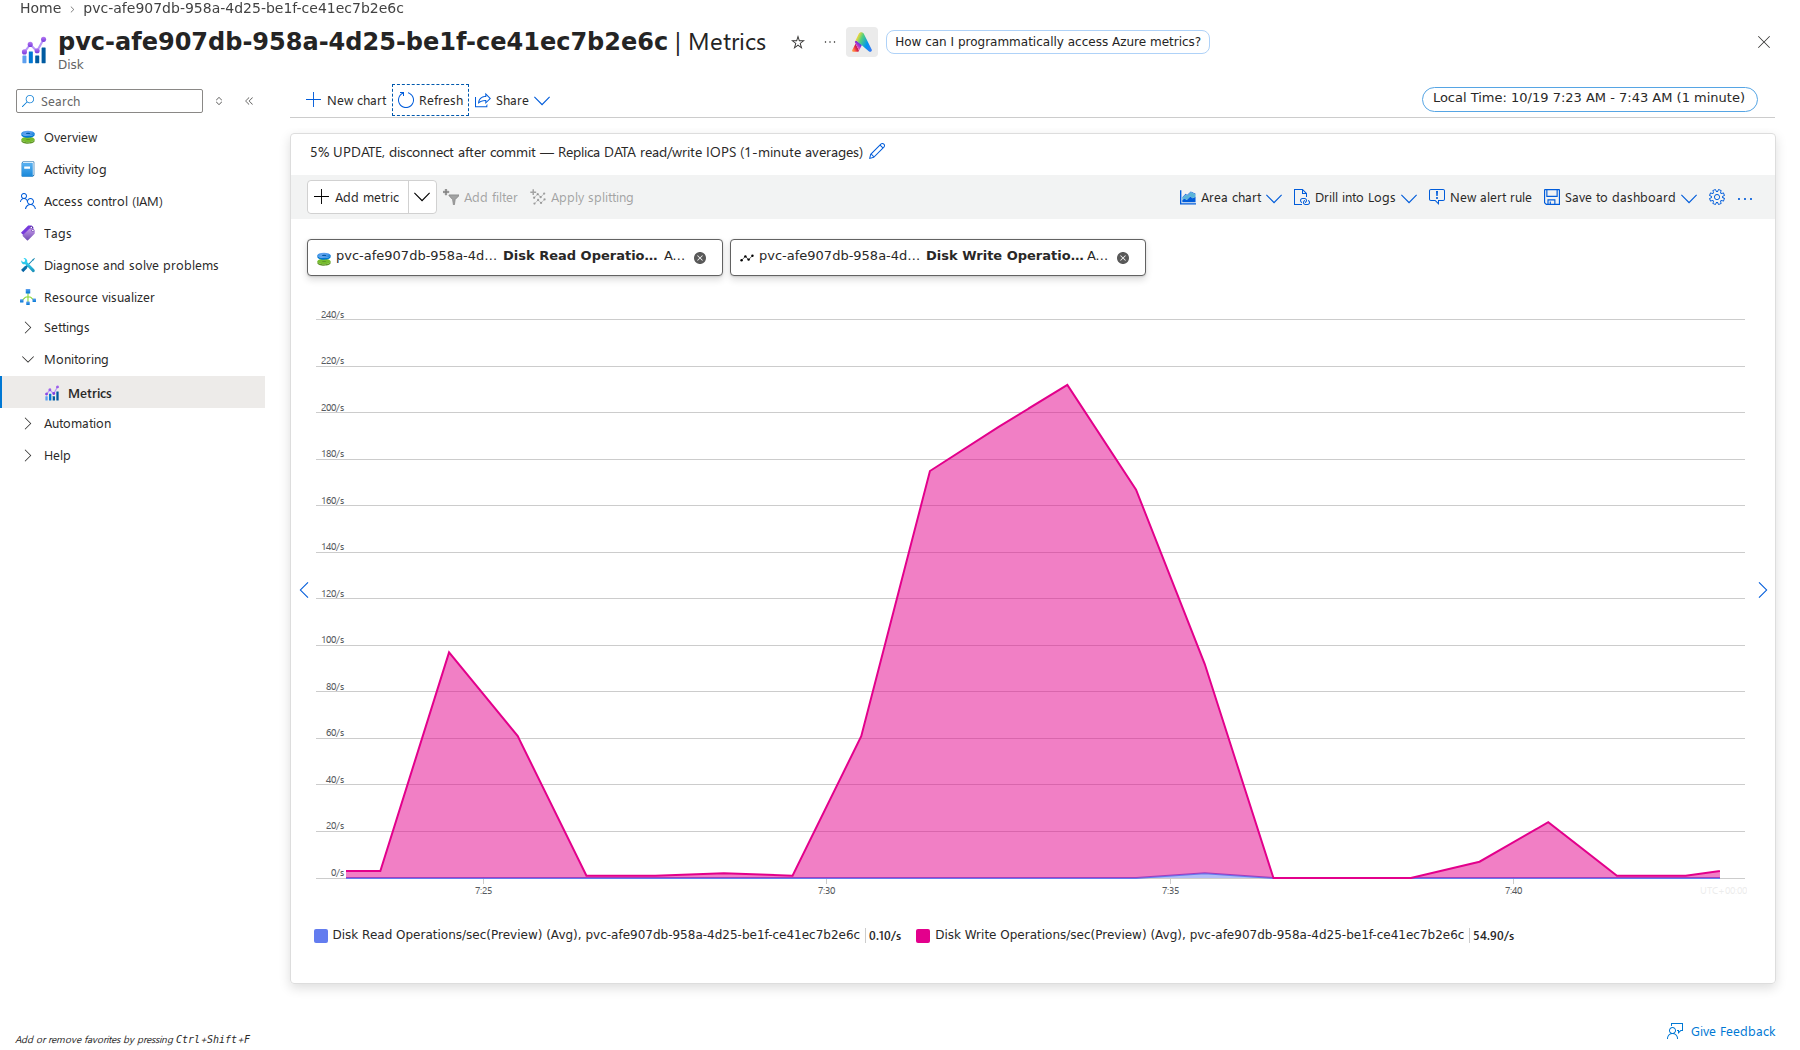
There is not any burst of learn IOPS, and the standby server principally stays caught up – making use of the 5% replace in lower than 10 minutes.
Right now, I’m leaning towards disabling the recovery_prefetch setting throughout the board however I need to see the place the discussions go. I feel its advantages are a little bit doubtful with FPWs enabled by default.
Appendix: Postgres Standby Server Replay Process
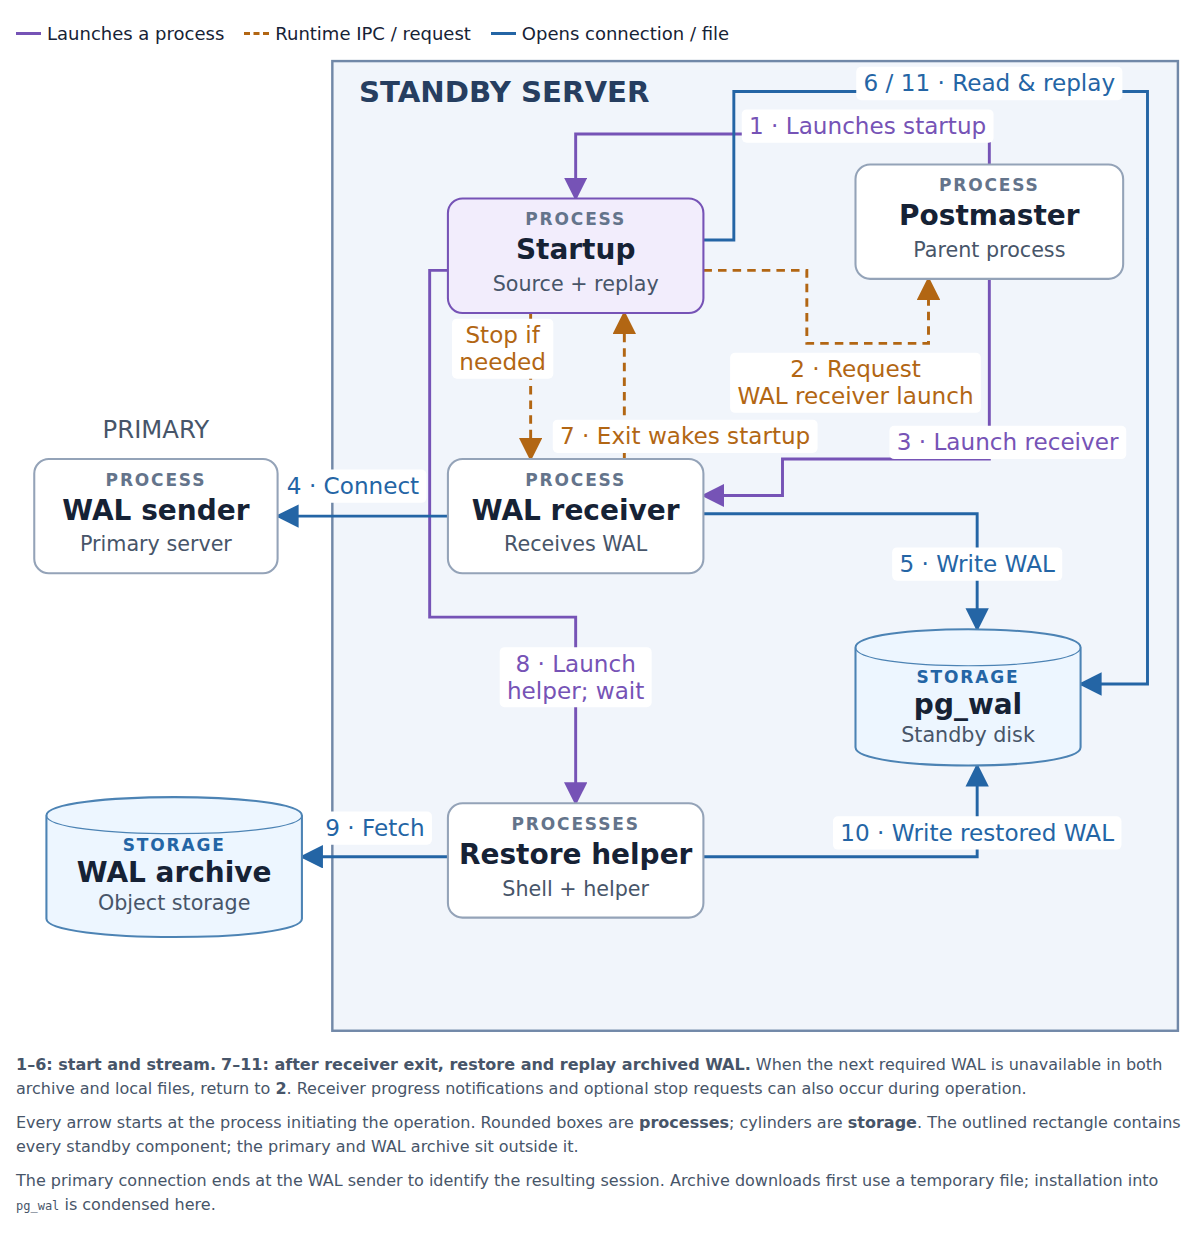
Here’s a extra detailed refresher on the varied processes concerned within the core restore and replay logic of a postgres standby server.
Importantly, word the path of the arrow between the WAL sender and WAL receiver. With synchronous replication in Postgres this connection is crucial – the first can’t settle for writes with out it. It’s additionally very fragile, as a result of if the connection disappears the first can solely sit and wait, blocking all writes, hoping a standby will reconnect quickly!
This is a purpose to contemplate two standbys and quorum commit (ANY 1) with postgres. While it does improve price to run with three complete replicas as an alternative of two, it considerably will increase the robustness of the database.