POSETTE Discuss Recap – Postgres Isn’t Slow. Your Storage Is
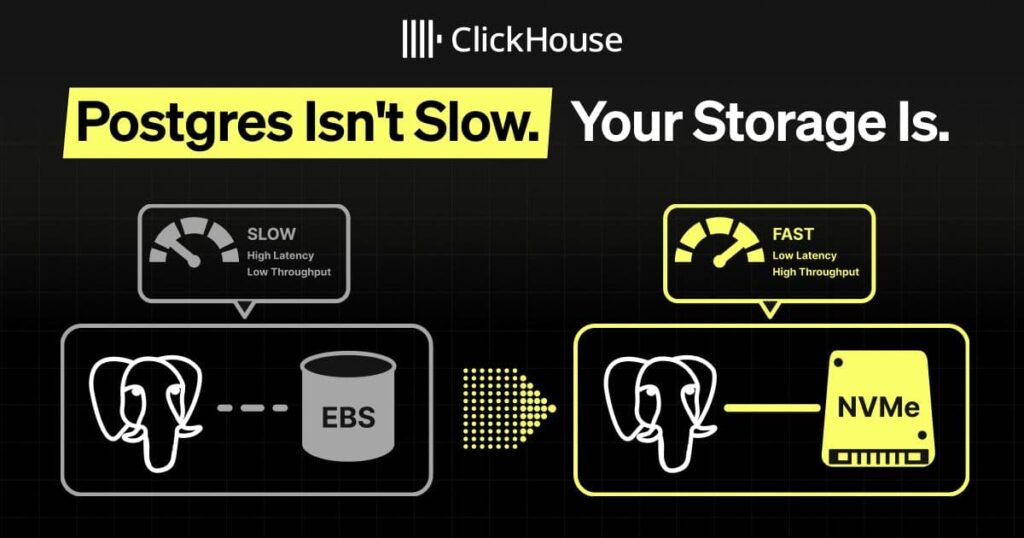
At POSETTE 2026, Sai Srirampur offered “Postgres Isn’t Slow. Your Storage Is.” a chat analyzing how storage impacts PostgreSQL efficiency at scale. This publish recaps the benchmark, what the outcomes revealed, and the structure proposed for operating PostgreSQL on native NVMe in manufacturing. You can watch the total discuss within the video linked beneath.
The discuss begins with a number of signs groups operating Postgres at scale might acknowledge: ingestion slows down, P95 learn latency turns into unpredictable, autovacuum falls behind, checkpoints compete along with your precise workload for assets, or logical replication accumulates lag. These issues don’t at all times share the identical trigger, however they will have a standard one that’s simple to miss: storage efficiency.
To perceive why, Sai ran a benchmark evaluating the identical 3.3-billion-row PostgreSQL workload on baseline gp3 EBS and native NVMe. We will stroll by way of the setup and what Sai found when analyzing the outcomes, then shut with the manufacturing patterns proposed for operating Postgres on native NVMe.
There are 5 widespread points that always seem as soon as a PostgreSQL workload reaches tons of of gigabytes or terabytes and is operating with actual concurrency and throughput.
-
Slow ingestion. The first one is ingestion pipelines heavy on UPDATEs and UPSERTs. Jobs that after completed in seconds can stretch into minutes as the quantity of knowledge beneath them grows.
-
Inconsistent learn latency. Next one seems in workloads the place most queries stay quick however just a few turn into dramatically slower. P95 latency strikes from milliseconds to seconds, dashboards trip, and the uneven slowdown makes the trigger tougher to isolate.
-
VACUUM falling behind. A 3rd difficulty is autovacuum falling behind as UPDATE and UPSERT throughput grows, with desk bloat accumulating from gigabytes into terabytes.
-
Slower checkpoints. Checkpoints may take longer and compete with the consumer workload for I/O and CPU, turning an operation that was invisible right into a recurring latency spike.
-
Logical replication lag. The final symptom seems when PostgreSQL information is streaming to programs equivalent to Kafka or ClickHouse. WAL decoding will be sluggish and a rising replication slot can compound the issue.
As the working set outgrows the reminiscence out there to PostgreSQL and the operating-system web page cache, extra information learn require bodily I/O. On slower storage, the upper price and queuing of these reads can enhance each common and tail latency.
Client queries and background upkeep additionally use the identical storage finances. Heap and index writes, WAL synchronization, checkpoints, VACUUM, and logical-decoding spills compete for bandwidth, IOPS, and queue capability.
Once storage reaches a type of limits, operations start delaying each other. That is how sluggish storage will be the basis reason behind a number of apparently unrelated PostgreSQL issues.
The case for native NVMe isn’t that it eliminates I/O, however that it might probably sharply scale back its price. The comparability contrasts millisecond-scale operations on network-attached storage with operations that will full in tens of microseconds on native NVMe. Cache misses, WAL flushes, and upkeep I/O nonetheless occur, however they merely don’t impression the general system as a lot.
To higher perceive why that is the case, Sai arrange a easy experiment to check an identical workload on PostgreSQL operating on EBS and native NVMe.
To isolate storage because the variable, the benchmark used eight similar PostgreSQL clusters: 4 utilizing instance-store NVMe and 4 utilizing baseline gp3 EBS provisioned at 3,000 IOPS. Each cluster ran on an m6id.4xlarge occasion with 16 vCPUs, 64 GiB of RAM, and 16 GiB of shared_buffers. We used a number of cases for every storage sort to normalize variability throughout benchmark runs.
The setup used a 482 GiB pgbench_accounts heap containing 3.3 billion rows. Each cluster then ran the identical extremely concurrent random-UPDATE workload for 5 minutes, with 64 purchasers and 16 employee threads:
set assist random(1, 3300000000)
UPDATE pgbench_accounts SET abalance = abalance + 1 WHERE assist = :assist;In brief, the one distinction between the 2 teams was the storage class.
The benchmark produced a median 16,030 TPS for the NVMe clusters, in contrast with 1,734 TPS on EBS—a 9.24× distinction on this take a look at. Median transaction latency fell from 36.9 ms to 4.0 ms.
For completely different operations, NVMe accomplished a VACUUM over 10 GB of bloat in 366 seconds, in contrast with 964 seconds on EBS, and drained a ten GB logical-replication backlog in 139 seconds as a substitute of 238 seconds.
One qualification issues: these outcomes apply to this workload and these storage configurations. The EBS aspect used baseline gp3 provisioned at 3,000 IOPS, completely different EBS setup would almost definitely produce completely different outcomes.
The throughput hole turns into simpler to grasp by taking a look at the place the 37 ms of EBS transaction latency went.
In this benchmark, web page reads accounted for about 19 ms on EBS, in contrast with 0.3 ms on NVMe. WAL fsync at commit added one other 11 ms on EBS versus 1.5 ms on NVMe, whereas lock and scheduler overhead contributed about 5 ms versus 0.2 ms. CPU work itself was roughly the identical—about 2 ms in each circumstances.
In different phrases, many of the further EBS latency got here from ready on storage, not from PostgreSQL doing extra CPU work.
A mid-run pg_stat_activity snapshot confirmed the identical sample from one other angle. Of the 64 backends, 29 on EBS had been ready on IO:DataFileRead, in contrast with 9 on NVMe—roughly 45% versus 14%. This was a point-in-time snapshot slightly than a median throughout the run, but it surely illustrates what number of extra EBS classes had been stalled on reads at that second.
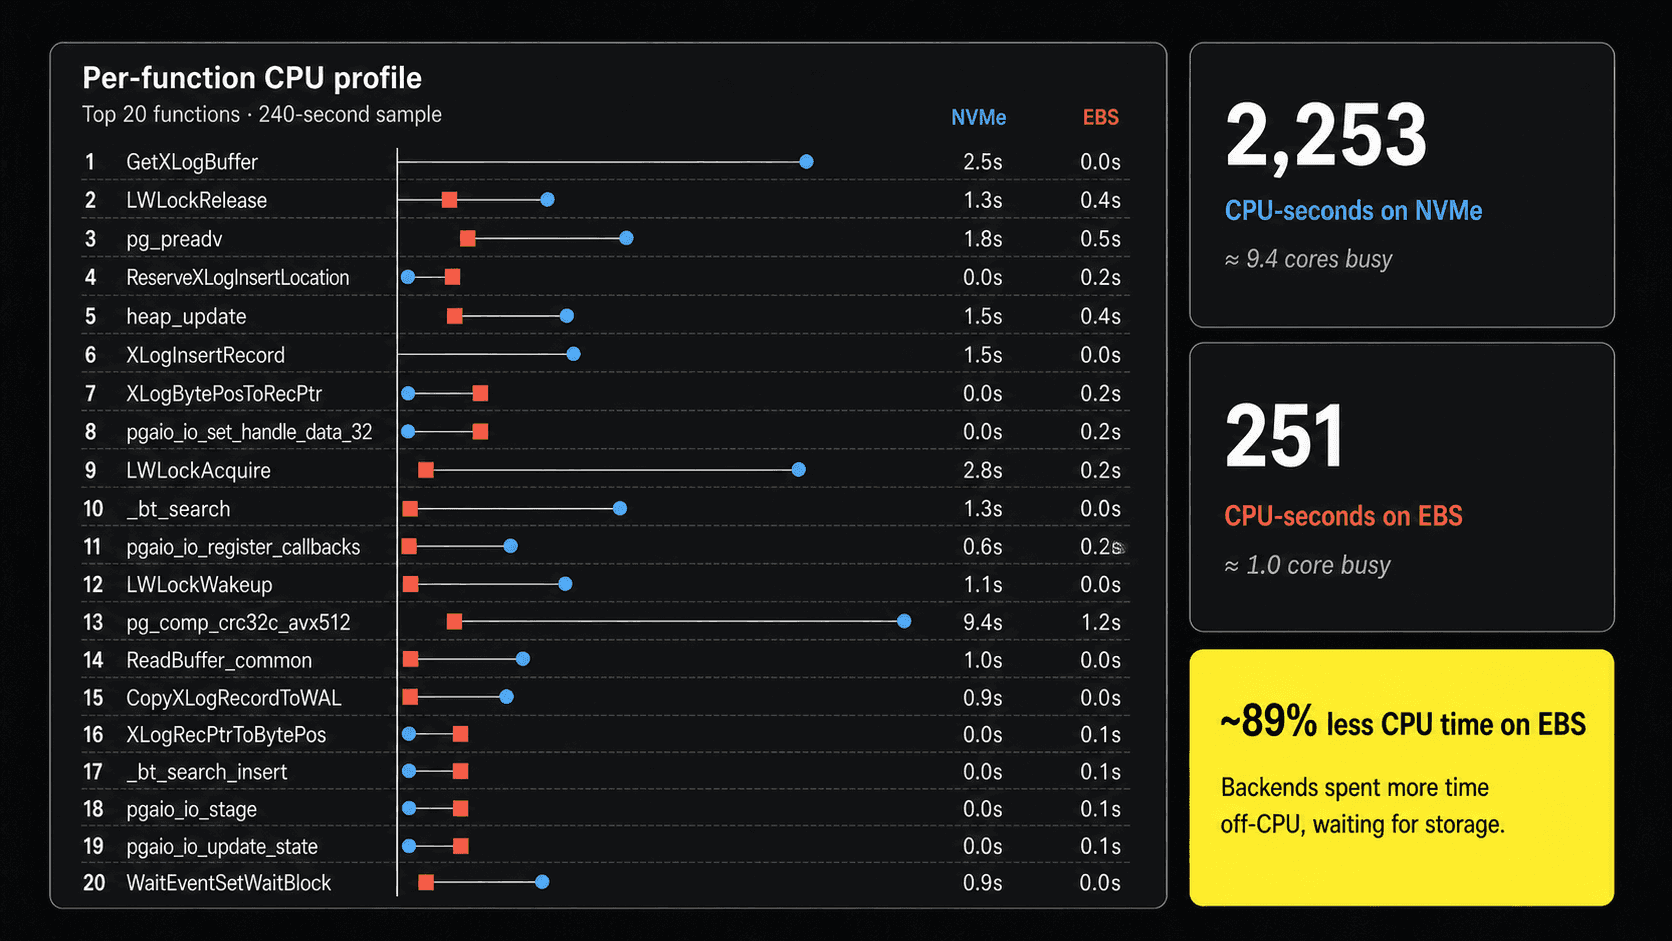
The CPU profile then provides a counterintuitive statement. Over a profiling window of roughly 240 seconds, the NVMe host collected 2,253 CPU-seconds—about 9.4 cores busy—whereas the EBS host collected solely 251 CPU-seconds, or about one core busy. Some PostgreSQL features appeared proportionally hotter on EBS, however the absolute CPU time confirmed that EBS processes had been spending way more time off-CPU ready for storage.
The NVMe host stored extra of its CPU capability busy doing helpful work. That helps clarify the a lot increased throughput: cache misses, WAL flushes, and upkeep I/O nonetheless occurred, however they accomplished quicker and left PostgreSQL spending much less time blocked on storage.
After the efficiency outcomes, the discuss turns to the apparent objection: instance-store NVMe is tied to the lifetime of a machine, so the native information disappears with the node. The operational query is whether or not PostgreSQL can mix NVMe latency with production-grade availability and restoration.
The brief reply is sure, given sturdiness is supplied on the cluster degree slightly than by any particular person Postgres node.
Running PostgreSQL on native NVMe in manufacturing means designing round storage that’s quick however tied to the lifetime of a machine. Losing a node means shedding its native copy of the information; instance-store volumes can’t be snapshotted by way of the EBS API; and out there capability is dependent upon the chosen occasion sort.
The manufacturing structure offered within the discuss addresses this by way of three predominant necessities: replicate the database so the service can survive node loss, keep backups and restoration information exterior the person machines, and plan capability across the NVMe out there on every occasion sort. Together, these patterns make it doable to run NVMe-backed PostgreSQL confidently in manufacturing.
The first sample is quorum-based synchronous replication with two standby candidates. With a configuration equivalent to ANY 1 (standby1, standby2), a transaction can commit after both standby durably acknowledges its WAL slightly than ready for the slower of the 2. Placing the nodes throughout availability zones protects in opposition to an AZ failure.
For sturdiness exterior the database nodes, open-source instruments equivalent to WAL-G can present bodily base backups and steady WAL archiving. With low-latency WAL transport, this structure can goal an RPO measured in seconds and assist point-in-time restoration throughout the retention window.
Backups and WAL must also be stored in a separate failure area, with one other regional copy when the restoration plan must survive a full regional outage.
Base backups and archived WAL are greater than an emergency mechanism: the identical restoration historical past can assist point-in-time restores, remoted branches, deployment resizing, read-replica seeding, and catastrophe restoration.
Backups and replication resolve completely different issues. In the structure described within the discuss, standbys present fast failover, whereas backups shield in opposition to corruption, operator error, and cluster-wide failure; each restoration paths want common testing.
This sample isn’t solely theoretical, the discuss cites public examples from Instacart, which has described PostgreSQL on NVMe for a latency-sensitive search workload, and Datadog, which has discussed local-NVMe PostgreSQL instances for workloads that want them. The recurring sample is native storage for efficiency, synchronous replication for availability, and independently saved base backups and WAL archives for restoration.
The discuss closes with a diagnostic suggestion: when PostgreSQL seems to cease scaling, examine the database and storage collectively. Slow ingestion, unpredictable learn latency, vacuum stress, disruptive checkpoints, and replication lag will be indicators that the storage layer has reached a restrict.
The backside line is intentionally narrower than the title: native NVMe can sharply scale back the I/O penalty for storage-bound workloads, but it surely comes with a special working mannequin. The structure outlined within the discuss makes use of quorum-based replication for availability and independently saved base backups plus archived WAL for restoration.