Multi-agent LLM coordination in Pokémon · Oliver Grabner
October 10, 2026
https://github.com/OliverGrabner/multi-agent-poke-showdown
The future is in LLM collaborations, and you will need to have the ability to perceive how good brokers
are at working collectively, speaking and negotiating actions. Most multi-agent analysis is about
workflows, the place brokers go duties down a pipeline
(Hong et al., 2024;
Qian et al., 2024). To check this, I constructed a multi-agent
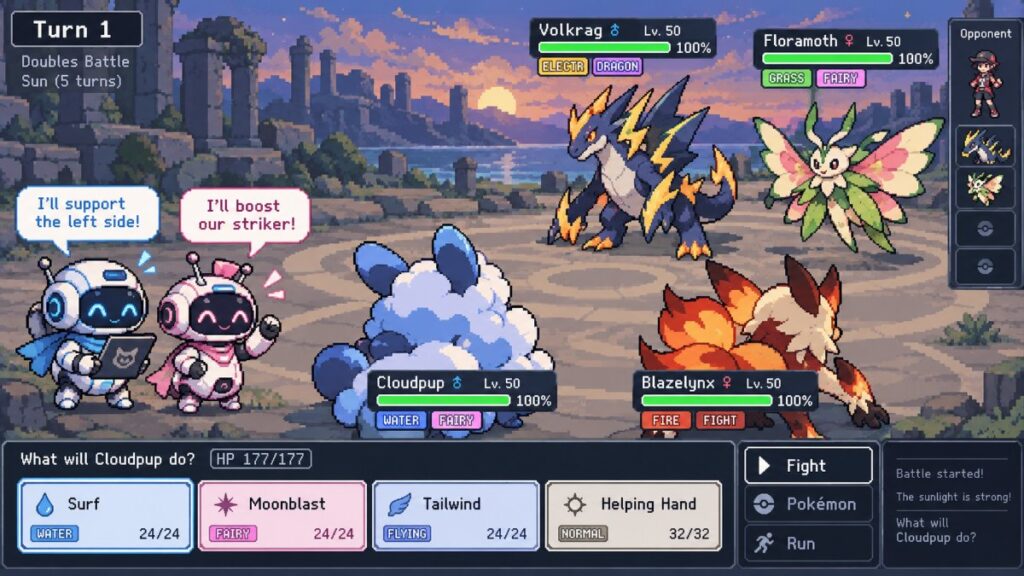
surroundings on Pokémon Showdown’s 2v2 format to judge these talents.
“Both opps are Water varieties … so my Fire strikes are resisted on each. … I plan to Wisp
Dondozo … are you able to open with Fake Out to flinch considered one of them this flip?”
“Good name on Wisp-ing Dondozo. Quick correction although – Fighting is not truly resisted
by Water or Ground, so my Close Combat is impartial (1x) on each. … Locking in Fake Out →
Whiscash.”
Qwen3.8-27B – Player 1 selected Will-O-Wisp → opposing Dondozo (p4)
Qwen3.8-27B – Player 2 selected Fake Out → opposing Whiscash (p2)
one corrects the opposite’s type-matchup mistake earlier than committing.
Watch the full battle with team chat.
Why Pokémon?
Pokémon doubles is a game-theory surroundings with out full info. The opponents’ units are
hidden and harm is random, so successful takes actual technique: studying the opposite group, splitting
targets and planning round your companion. Recent work just like the PokéAgent Challenge
(Karten et al., 2026) benchmarks Pokémon battling,
however both sides is performed by a single agent, and specialist RL brokers nonetheless outplay normal LLMs
there. It does not check teammates who should coordinate.
The objective is a managed surroundings the place I can measure how LLM brokers coordinate, and that may
later be used to coach them with RL to encourage these collaborative behaviors.
Methodology
Environment
The official Pokémon Showdown simulator, wrapped as a Gym-style surroundings. Four gamers every
management one Pokémon from a group of three, two per facet.
Agents
Each flip, an agent reads a plain-English abstract of the battle and a numbered listing of its authorized
strikes. It can say a non-public message to its companion or select a transfer, and
as soon as it chooses, its companion is instructed what it picked.
Talk modes
Free speak (hold speaking till each have chosen), one message every, no speak, and one mannequin
controlling each Pokémon.
Evaluation
Qwen3.8-27B performs each teammates towards a scripted max-damage bot. Battles are seeded and each
group draw is performed from each side, so every speak mode faces precisely the identical battles.
Results
| Condition | 30%50%70% | Tokens per battle | |
|---|---|---|---|
| Free speak | 64% | 978k | |
| One mannequin controls each | 54% | 450k | |
| One message every | 52% | 654k | |
| No speak | 42% | 259k |
Talking helps. Teammates who may speak freely received 64% of their battles towards the max-damage
bot, whereas teammates who could not speak in any respect received 42%. Even a single message every (52%) beat no
speak. One mannequin controlling each Pokémon (54%) did higher than no speak however worse than two brokers
speaking freely, so I believe the achieve comes from the dialog itself, not simply from one thoughts
planning each strikes.
Talking additionally prices. Free speak used 978k immediate tokens per battle, 3.8x the 259k of no speak, since
each message means one other mannequin name that re-reads the battle and the dialog thus far.
| Opponent | Win price | |
|---|---|---|
| Qwen3.5-2B group | 96% | |
| Qwen3.5-9B group | 74% | |
| Max-damage bot | 64% |
I additionally checked that the surroundings can inform fashions aside. A Qwen3.8-27B group received 96% of its
battles towards a group of 2B fashions and 74% towards a group of 9B fashions, in contrast with 64% towards
the max-damage bot. The stronger the opponent, the nearer the video games, which is what makes the
surroundings usable as a benchmark for evaluating fashions.
Next
I’m separating the impact of speaking from the impact of seeing your companion’s transfer. I’m additionally
wanting into turning the surroundings right into a benchmark with a leaderboard throughout fashions, and utilizing
it for RL coaching to encourage collaborative behaviors.
Thanks
Through this mission I needed to be taught extra about agent collaboration and RL environments, and
thought I’d share the outcomes! I ran these experiments on Texas A&M’s Grace cluster. Thank you
to Maria Teleki and to my advisor,
Prof. James Caverlee, for the steerage and
suggestions alongside the best way.