LLM Transformer Mannequin Visually Defined
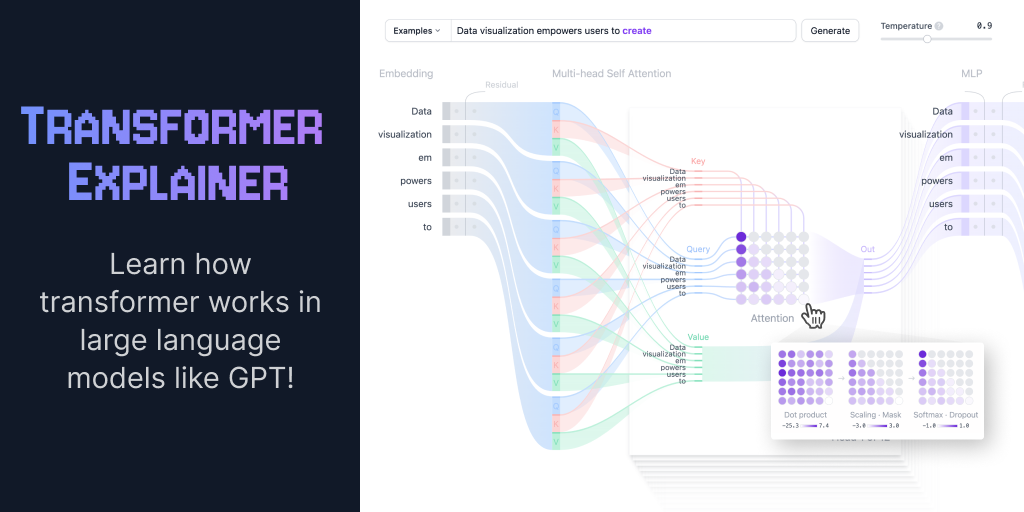

Transformer is a neural community structure that has essentially modified the strategy to
Artificial Intelligence. Transformer was first launched within the seminal paper
“Attention is All You Need”
in 2017 and has since develop into the go-to structure for deep studying fashions, powering text-generative
fashions like OpenAI’s GPT, Meta’s Llama, and Google’s
Gemini. Beyond textual content, Transformer can also be utilized in
audio generation,
image recognition,
protein structure prediction, and even
game playing, demonstrating its versatility throughout quite a few domains.
Fundamentally, text-generative Transformer fashions function on the precept of next-token prediction: given a textual content immediate from the person, what’s the
most possible subsequent token (a phrase or a part of a phrase) that can comply with this enter? The core
innovation and energy of Transformers lie of their use of self-attention mechanism, which permits
them to course of complete sequences and seize long-range dependencies extra successfully than earlier
architectures.
GPT-2 household of fashions are distinguished examples of text-generative Transformers. Transformer
Explainer is powered by the
GPT-2
(small) mannequin which has 124 million parameters. While it isn’t the newest or strongest Transformer
mannequin, it shares lots of the identical architectural parts and rules discovered within the present
state-of-the-art fashions making it a great place to begin for understanding the fundamentals.
Every text-generative Transformer consists of those three key parts:
- Embedding: Text enter is split into smaller items
referred to as tokens, which could be phrases or subwords. These tokens are transformed into numerical
vectors referred to as embeddings, which seize the semantic which means of phrases. - Transformer Block is the elemental constructing block of
the mannequin that processes and transforms the enter knowledge. Each block consists of:- Attention Mechanism, the core element of the Transformer block. It
permits tokens to speak with different tokens, capturing contextual info and
relationships between phrases. - MLP (Multilayer Perceptron) Layer, a feed-forward community that operates
on every token independently. While the objective of the eye layer is to route
info between tokens, the objective of the MLP is to refine every token’s
illustration.
- Attention Mechanism, the core element of the Transformer block. It
- Output Probabilities: The remaining linear and softmax
layers rework the processed embeddings into chances, enabling the mannequin to make
predictions in regards to the subsequent token in a sequence.
Embedding
Let’s say you wish to generate textual content utilizing a Transformer mannequin. You add the immediate like this
one: “Data visualization empowers customers to”. This enter must be transformed
right into a format that the mannequin can perceive and course of. That is the place embedding is available in: it
transforms the textual content right into a numerical illustration that the mannequin can work with. To convert a
immediate into embedding, we have to 1) tokenize the enter, 2) receive token embeddings, 3) add
positional info, and at last 4) add up token and place encodings to get the ultimate
embedding. Let’s see how every of those steps is finished.
Figure 1. Expanding the Embedding layer view, displaying how the
enter immediate is transformed to a vector illustration. The course of entails
(1) Tokenization, (2) Token Embedding, (3) Positional Encoding,
and (4) Final Embedding.
Step 1: Tokenization
Tokenization is the method of breaking down the enter textual content into smaller, extra manageable
items referred to as tokens. These tokens could be a phrase or a subword. The phrases "Data"
and "visualization" correspond to distinctive tokens, whereas the phrase
"empowers"
is break up into two tokens. The full vocabulary of tokens is set earlier than coaching the mannequin:
GPT-2’s vocabulary has 50,257 distinctive tokens. Now that we break up our enter textual content into
tokens with distinct IDs, we are able to receive their vector illustration from embeddings.
Step 2. Token Embedding
GPT-2 (small) represents every token within the vocabulary as a 768-dimensional vector; the
dimension of the vector depends upon the mannequin. These embedding vectors are saved in a matrix
of form (50,257, 768), containing roughly 39 million parameters! This
intensive matrix permits the mannequin to assign semantic which means to every token, within the sense
that tokens with related utilization or which means in language are positioned shut collectively on this
high-dimensional area, whereas dissimilar tokens are farther aside.
Step 3. Positional Encoding
The Embedding layer additionally encodes details about every token’s place within the enter
immediate. Different fashions use varied strategies for positional encoding. GPT-2 trains its personal
positional encoding matrix from scratch, integrating it instantly into the coaching course of.
Step 4. Final Embedding
Finally, we sum the token and positional encodings to get the ultimate embedding
illustration. This mixed illustration captures each the semantic which means of the
tokens and their place within the enter sequence.
Transformer Block
The core of the Transformer’s processing lies within the Transformer block, which contains
multi-head self-attention and a Multi-Layer Perceptron layer. Most fashions encompass a number of
such blocks which can be stacked sequentially one after the opposite. The token representations
evolve via layers, from the primary block to the final one, permitting the mannequin to construct up an
intricate understanding of every token. This layered strategy results in higher-order
representations of the enter. The GPT-2 (small) mannequin we’re analyzing consists of 12 such blocks.
Multi-Head Self-Attention
The self-attention mechanism allows the mannequin to seize relationships amongst tokens in a
sequence, so that every token’s illustration is influenced by the others. Multiple consideration
heads enable the mannequin to think about these relationships from totally different views; for
instance, one head might seize short-range syntactic hyperlinks whereas one other tracks broader
semantic context. In the next part, we’ll stroll via how multi-head self-attention
is computed step-by-step.
Step 1: Query, Key, and Value Matrices
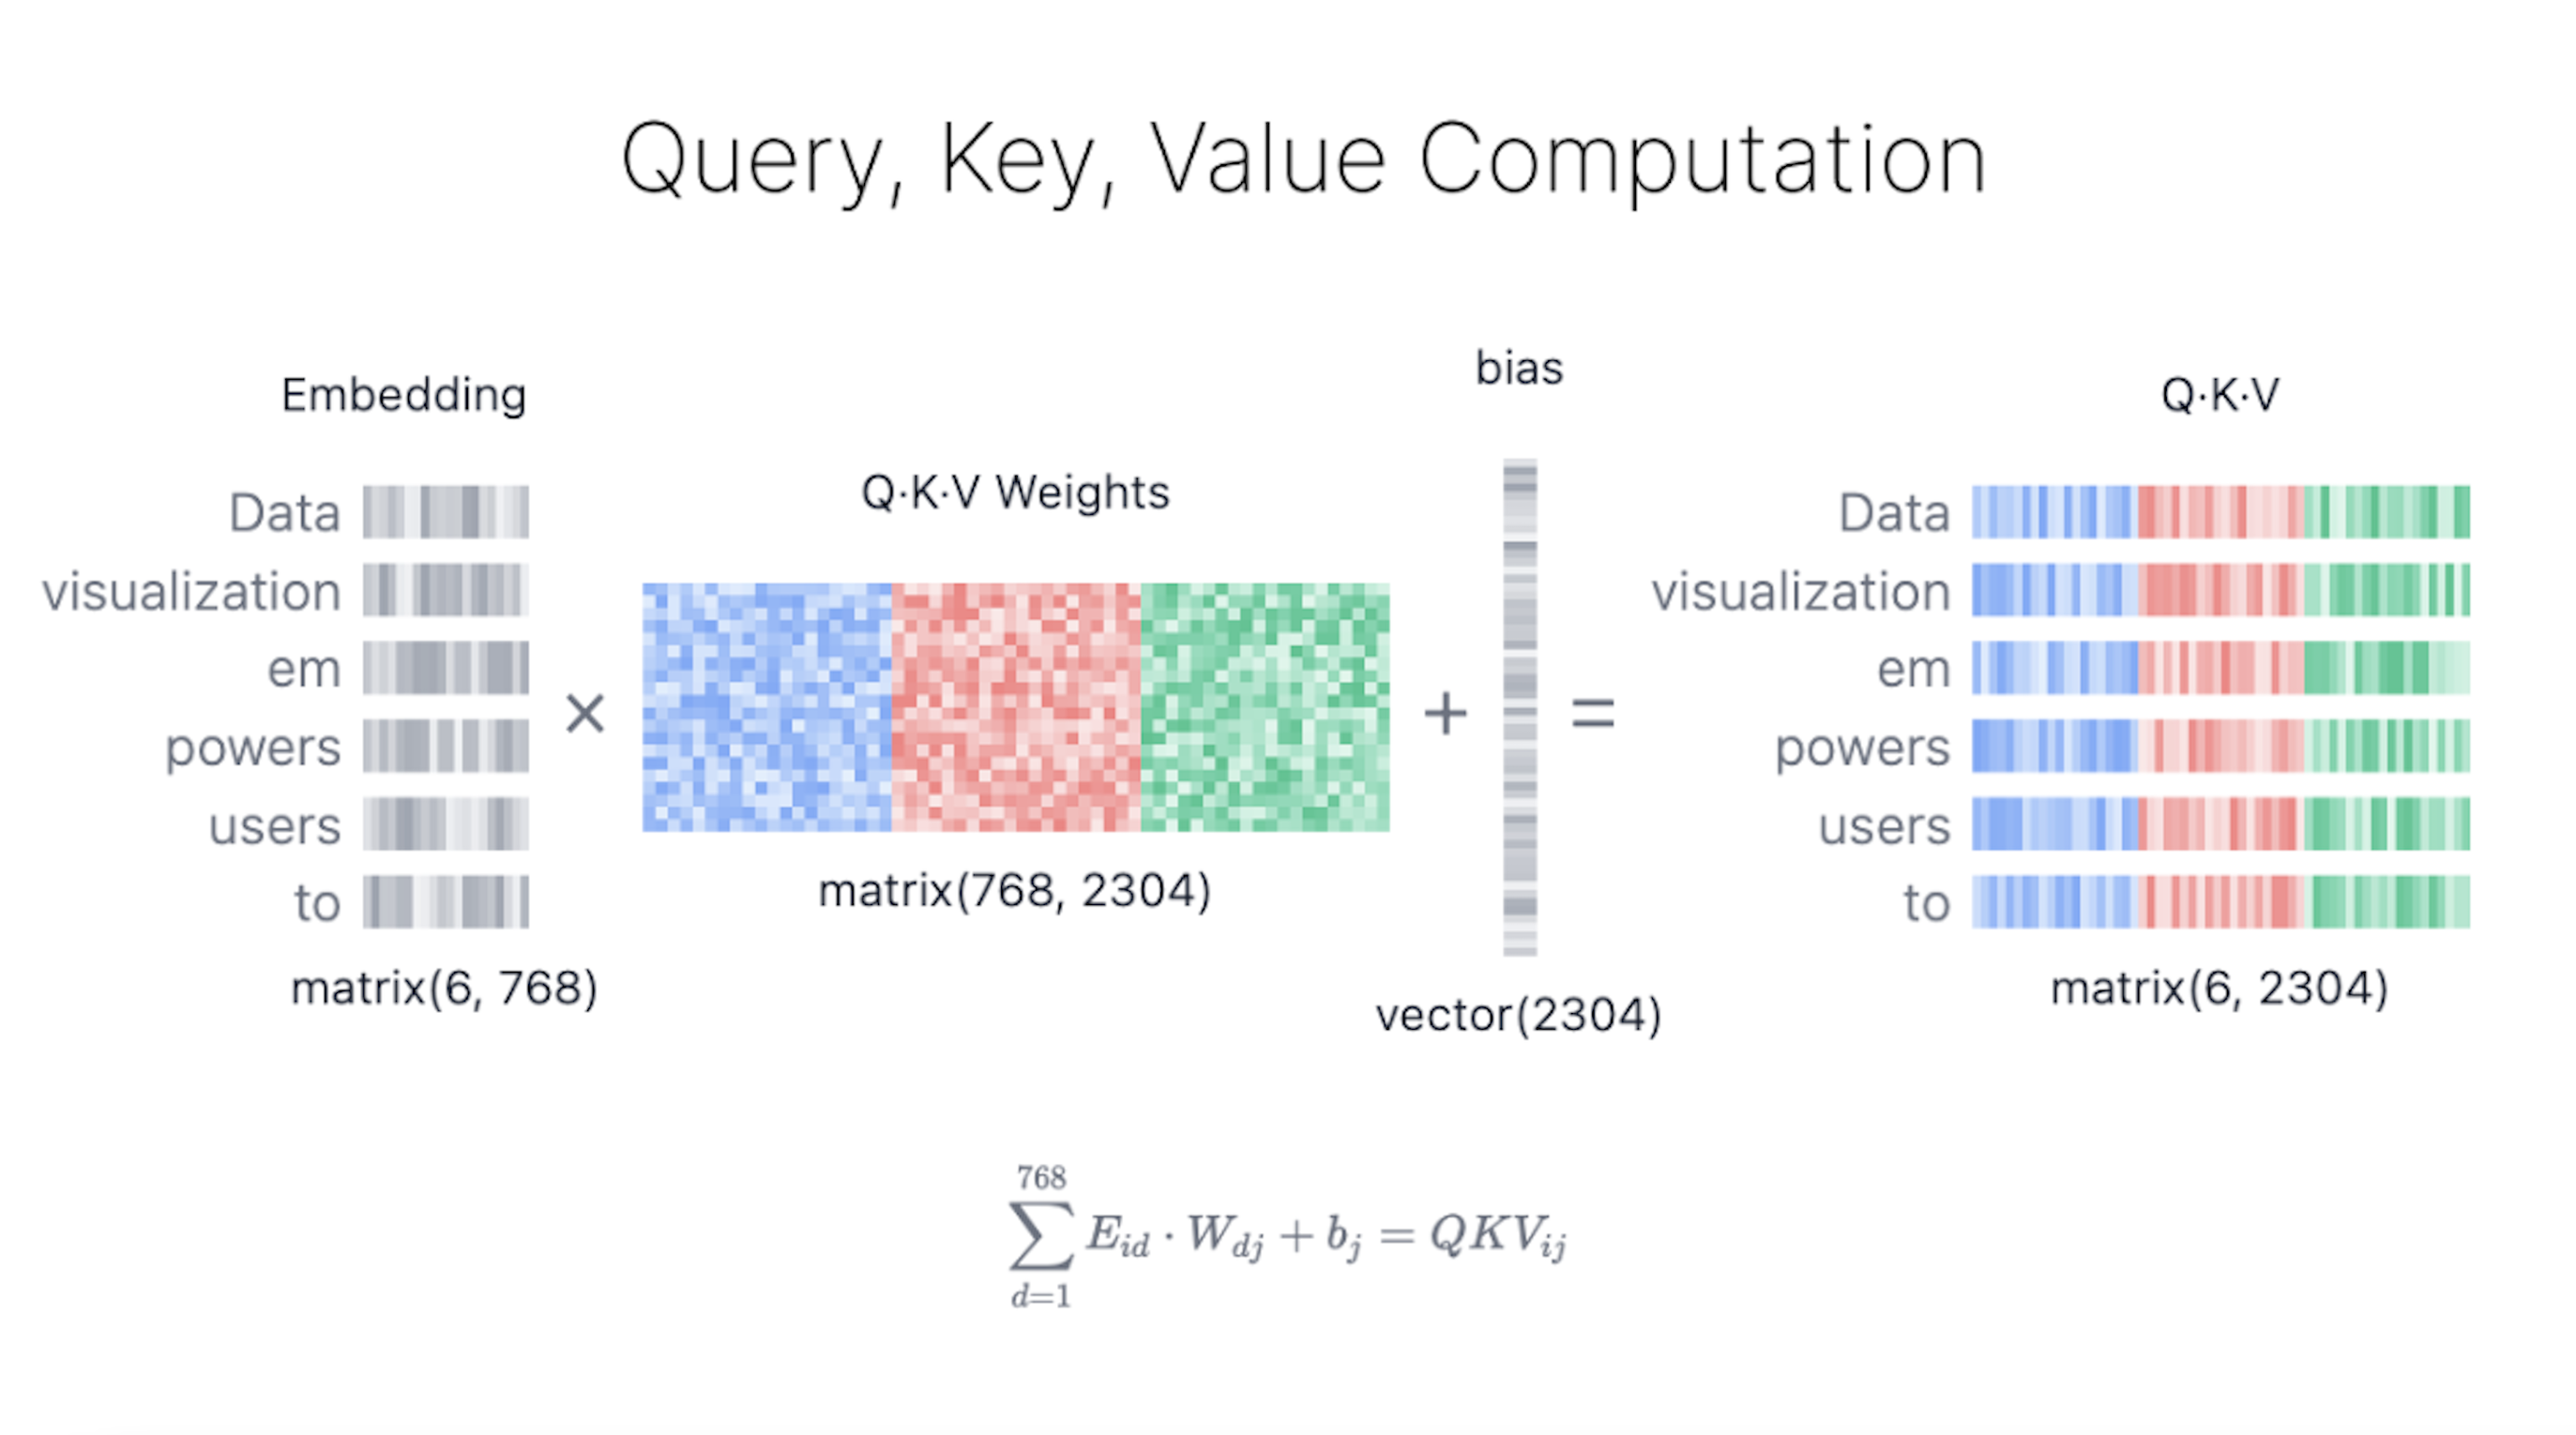
Figure 2. Computing Query, Key, and Value matrices from the
authentic embedding.
Each token’s embedding vector is reworked into three vectors:
Query (Q),
Key (Okay), and
Value (V). These vectors are derived by multiplying the enter
embedding matrix with realized weight matrices for
Q,
Okay, and
V. Here’s an internet search analogy to assist us construct some instinct
behind these matrices:
- Query (Q) is the search textual content you sort within the
search engine bar. This is the token you wish to
“discover extra details about”. - Key (Okay) is the title of every net web page within the search
outcome window. It represents the attainable tokens the question can attend to. - Value (V) is the precise content material of net pages proven.
Once we matched the suitable search time period (Query) with the related outcomes (Key), we would like
to get the content material (Value) of probably the most related pages.
By utilizing these QKV values, the mannequin can calculate consideration scores, which decide how
a lot focus every token ought to obtain when producing predictions.
Step 2: Multi-Head Splitting
Query, key, and
Value
vectors are break up into a number of heads—in GPT-2 (small)’s case, into
12 heads. Each head processes a section of the embeddings independently, capturing
totally different syntactic and semantic relationships. This design facilitates parallel studying of
various linguistic options, enhancing the mannequin’s representational energy.
Step 3: Masked Self-Attention
In every head, we carry out masked self-attention calculations. This mechanism permits the mannequin
to generate sequences by specializing in related elements of the enter whereas stopping entry to
future tokens.
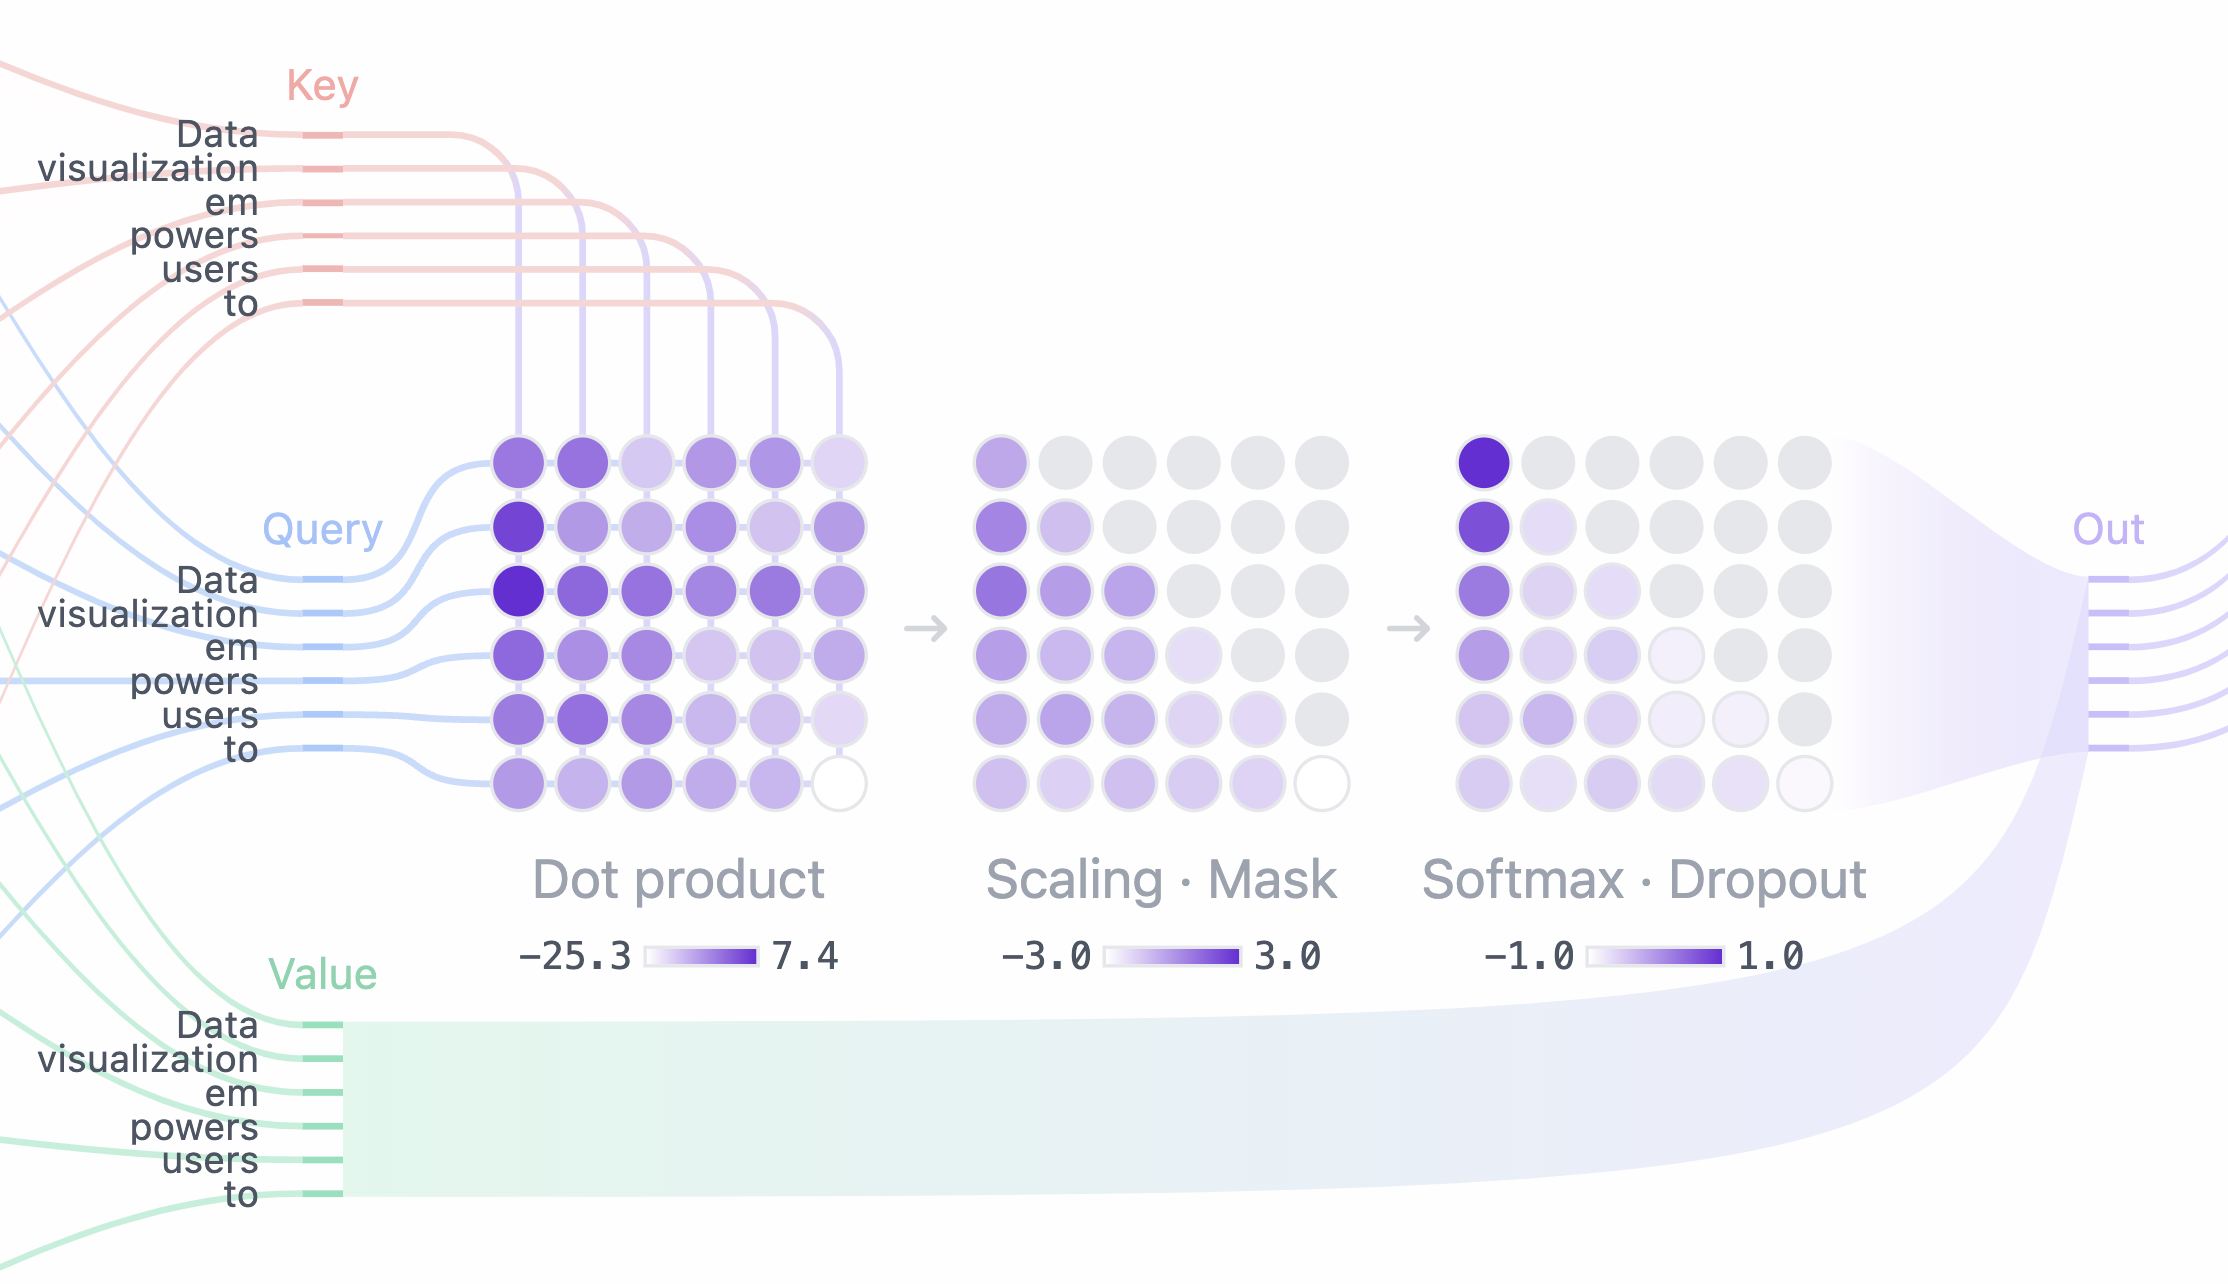
Figure 3. Using Query, Key, and Value matrices to calculate
masked self-attention.
- Dot Product: The dot product of
Query
and Key matrices determines the
consideration rating, producing a sq. matrix that displays the connection
between all enter tokens. - Scaling · Mask: The consideration scores are scaled and a masks is utilized to
the higher triangle of the eye matrix to stop the mannequin from accessing future
tokens, setting these values to unfavorable infinity. The mannequin must learn to predict
the subsequent token with out “peeking” into the long run. - Softmax · Dropout: After masking and scaling, the eye scores are
transformed into chances by the softmax operation, then optionally regularized with
dropout. Each row of the matrix sums to 1 and signifies the relevance of each different
token to the left of it.
Step 4: Output and Concatenation
The mannequin makes use of the masked self-attention scores and multiplies them with the
Value matrix to get the
remaining output
of the self-attention mechanism. GPT-2 has 12 self-attention heads, every capturing
totally different relationships between tokens. The outputs of those heads are concatenated and handed
via a linear projection.
MLP: Multi-Layer Perceptron
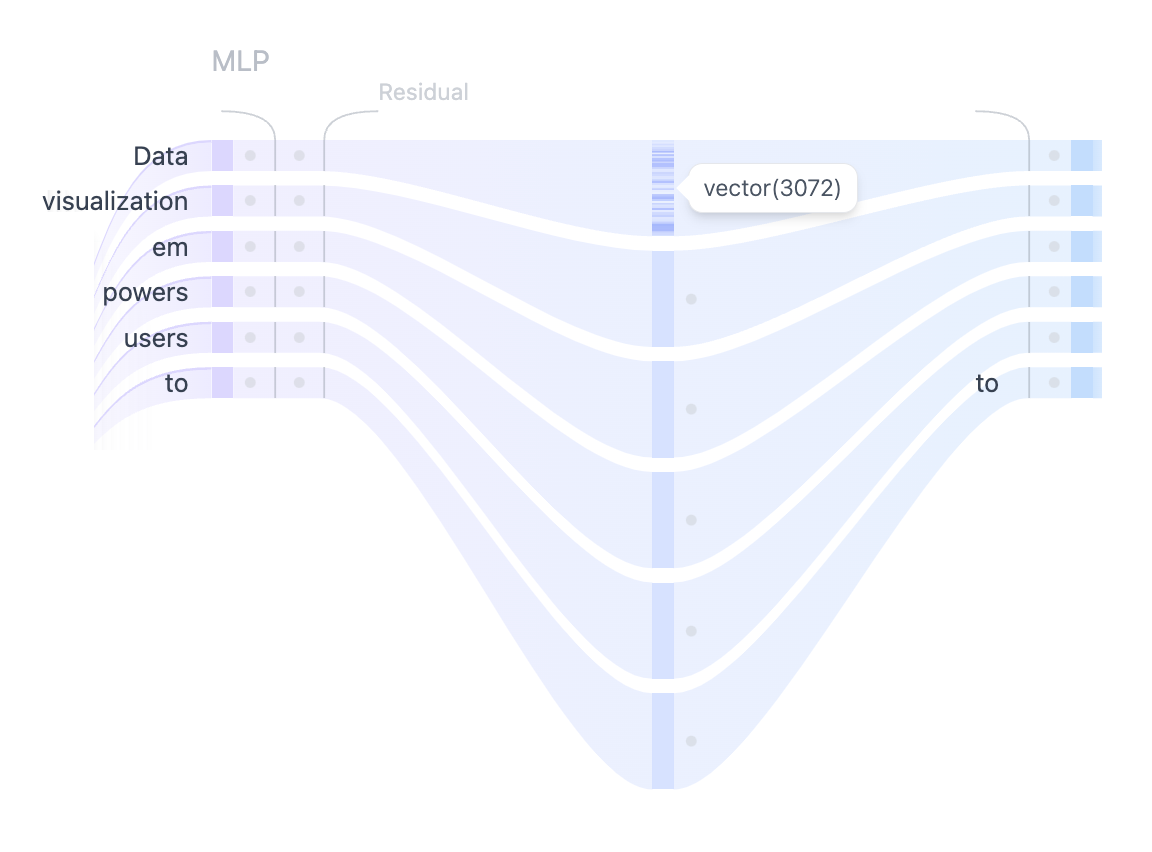
Figure 4. Using MLP layer to mission the self-attention
representations into greater dimensions to boost the mannequin’s representational capability.
After the a number of heads of self-attention seize the varied relationships between the enter
tokens, the concatenated outputs are handed via the Multilayer Perceptron (MLP) layer to
improve the mannequin’s representational capability. The MLP block consists of two linear
transformations with a GELU activation operate in between.
The first linear transformation expands the dimensionality of the enter four-fold from 768
to
3072. This growth step permits the mannequin to mission the token representations
right into a higher-dimensional area, the place it will probably seize richer and extra complicated patterns that
will not be seen within the authentic dimension.
The second linear transformation then reduces the dimensionality again to the unique dimension of 768.This compression step brings the representations again to a manageable dimension whereas retaining
the helpful nonlinear transformations launched within the growth step.
Unlike the self-attention mechanism, which integrates info throughout tokens, the MLP
processes tokens independently and easily maps every token illustration from one area to
one other, enriching the general mannequin capability.
Output Probabilities
After the enter has been processed via all Transformer blocks, the output is handed
via the ultimate linear layer to organize it for token prediction. This layer initiatives the
remaining representations right into a 50,257
dimensional area, the place each token within the vocabulary has a corresponding worth referred to as
logit. Any token could be the subsequent phrase, so this course of permits us to easily rank
these tokens by their chance of being that subsequent phrase. We then apply the softmax operate
to transform the logits right into a likelihood distribution that sums to 1. This will enable us to
pattern the subsequent token based mostly on its chance.
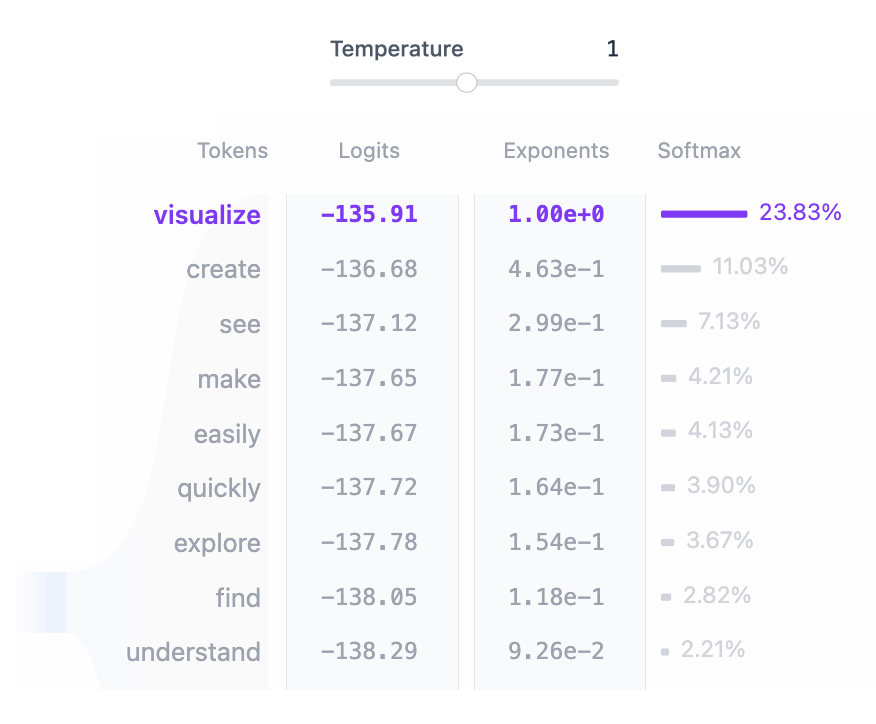
Figure 5. Each token within the vocabulary is assigned a
likelihood based mostly on the mannequin’s output logits. These chances decide the chance
of every token being the subsequent phrase within the sequence.
The remaining step is to generate the subsequent token by sampling from this distribution The temperature
hyperparameter performs a essential position on this course of. Mathematically talking, it’s a quite simple
operation: mannequin output logits are merely divided by the
temperature:
temperature = 1: Dividing logits by one has no impact on the softmax outputs.temperature < 1: Lower temperature makes the mannequin extra assured and
deterministic by sharpening the likelihood distribution, resulting in extra predictable
outputs.temperature > 1: Higher temperature creates a softer likelihood
distribution, permitting for extra randomness within the generated textual content – what some discuss with as
mannequin “creativity”.
In addition, the sampling course of could be additional refined utilizing top-k
and
top-p parameters:
top-k sampling: Limits the candidate tokens to the highest okay tokens with the
highest chances, filtering out much less doubtless choices.top-p sampling: Considers the smallest set of tokens whose cumulative
likelihood exceeds a threshold p, making certain that solely the most definitely tokens contribute
whereas nonetheless permitting for variety.
By tuning temperature, top-k, and top-p, you’ll be able to
stability between deterministic and various outputs, tailoring the mannequin’s habits to your
particular wants.
Auxiliary Architectural Features
There are a number of auxiliary architectural options that improve the efficiency of Transformer
fashions. While essential for the mannequin’s general efficiency, they aren’t as essential for
understanding the core ideas of the structure. Layer Normalization, Dropout, and
Residual Connections are essential parts in Transformer fashions, significantly through the
coaching section. Layer Normalization stabilizes coaching and helps the mannequin converge sooner.
Dropout prevents overfitting by randomly deactivating neurons. Residual Connections permits
gradients to move instantly via the community and helps to stop the vanishing gradient
drawback.
Layer Normalization
Layer Normalization helps to stabilize the coaching course of and improves convergence. It
works by normalizing the inputs throughout the options, making certain that the imply and variance of
the activations are constant. This normalization helps mitigate points associated to inside
covariate shift, permitting the mannequin to be taught extra successfully and decreasing the sensitivity
to the preliminary weights. Layer Normalization is utilized twice in every Transformer block, as soon as
earlier than the self-attention mechanism and as soon as earlier than the MLP layer.
Dropout
Dropout is a regularization approach used to stop overfitting in neural networks by
randomly setting a fraction of mannequin weights to zero throughout coaching. This encourages the
mannequin to be taught extra sturdy options and reduces dependency on particular neurons, serving to the
community generalize higher to new, unseen knowledge. During mannequin inference, dropout is
deactivated. This primarily implies that we’re utilizing an ensemble of the skilled
subnetworks, which results in a greater mannequin efficiency.
Residual Connections
Residual connections have been first launched within the ResNet mannequin in 2015. This architectural
innovation revolutionized deep studying by enabling the coaching of very deep neural
networks. Essentially, residual connections are shortcuts that bypass a number of layers,
including the enter of a layer to its output. This helps mitigate the vanishing gradient
drawback, making it simpler to coach deep networks with a number of Transformer blocks stacked on
prime of one another. In GPT-2, residual connections are used twice inside every Transformer
block: as soon as earlier than the MLP and as soon as after, making certain that gradients move extra simply, and
earlier layers obtain adequate updates throughout backpropagation.
Transformer Explainer is constructed to be interactive and permits you to discover the interior workings
of the Transformer. Here are a number of the interactive options you’ll be able to play with:
- Input your individual textual content sequence to see how the mannequin processes it and predicts
the subsequent phrase. Explore consideration weights, intermediate computations, and see how the ultimate output
chances are calculated. - Use temperature slider to regulate the randomness of the mannequin’s predictions.
Explore how one can make the mannequin output extra deterministic or extra artistic by altering the
temperature worth. - Select top-k and top-p sampling strategies to regulate sampling habits throughout inference.
Experiment with totally different values and see how the likelihood distribution modifications and influences
the mannequin’s predictions. - Interact with consideration maps to see how the mannequin focuses on totally different tokens
within the enter sequence. Hover over tokens to focus on their consideration weights and discover how
the mannequin captures context and relationships between phrases.
How is Transformer Explainer Implemented?
Transformer Explainer includes a stay GPT-2 (small) mannequin working instantly within the browser.
This mannequin is derived from the PyTorch implementation of GPT by Andrej Karpathy’s
nanoGPT project
and has been transformed to
ONNX Runtime
for seamless in-browser execution. The interface is constructed utilizing JavaScript, with
Svelte
as a front-end framework and
D3.js
for creating dynamic visualizations. Numerical values are up to date stay following the person enter.