How Uber Protects Towards Retry Storms
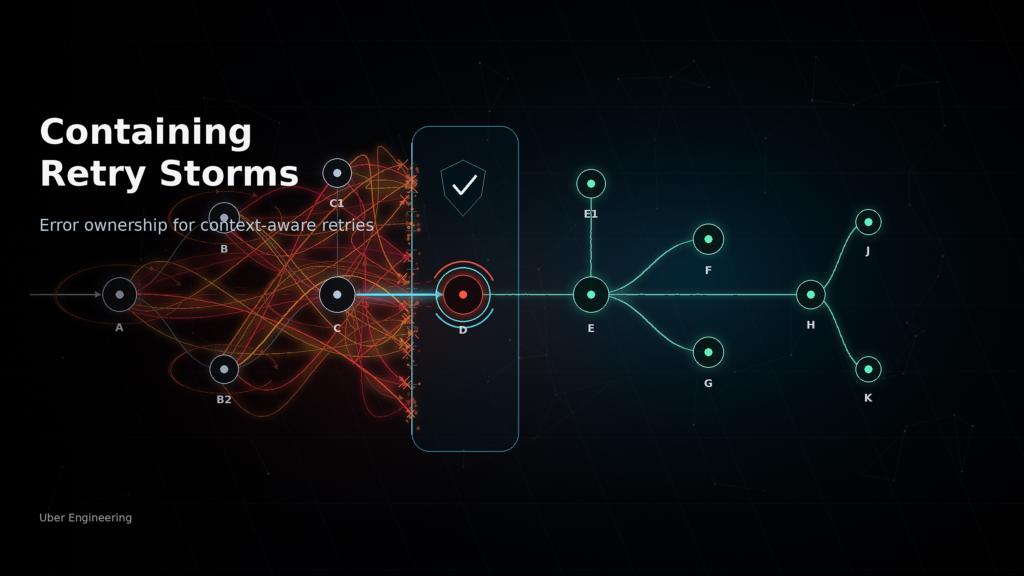

Retry storms traditionally affect trade operations and model belief. While retry configuration tuning and retry budgets present significant mitigation on the service degree, they’re manually configured and lack visibility into cross-service amplification attributable to deep dependency chains and fan-out patterns. As a end result, it may be tough to defend utilities towards the domino impact triggered by a single service outage deeper within the stack.
A key purpose is that retry habits at present isn’t context-aware. While we will management what number of retries happen, we will’t exactly management once they happen. This stems from the problem of reliably distinguishing between errors generated by a service and people merely propagated by it.
As a end result, retries are utilized uniformly reasonably than conditionally.
This method works for transient or low-rate failures. However, throughout reasonable or extreme degradation, it turns into counterproductive. Aggressively retrying towards an already struggling service will increase load, accelerates failure, and amplifies retry site visitors throughout upstream dependencies. What begins as a localized outage can rapidly escalate right into a stack-wide incident—in the end degrading, or within the worst case, utterly breaking, the tip person expertise.
One would possibly argue that error codes from downstream providers might be translated upstream to supply context for retries. While theoretically attainable, this method does not scale at Uber resulting from giant fan-in and fan-out, evolving name flows, and the necessity for frequent adaptive adjustments. Therefore, we developed a context-aware mechanism in shared utilities to deal with errors extra effectively. This weblog explains the mechanism.
Background
Consider a easy name chain as proven in Figure 1, the place the whole variety of requests arriving at NodeA is Ƞ. By deduction, all nodes B, C, D, E, F, and G serve Ƞ requests within the regular state (when no node errors out).
Figure 1: Call-chain with 1:1 fan-out, the place a node calls its downstream precisely as soon as for any incoming request.
If service D begins erroring out and every service is configured to retry as soon as (1 common try and one other try if the downstream fails), let’s take a look at the whole variety of requests served by every node.
Figure 2: Call chain the place a service errors out.
|
Node |
A |
B |
C |
D |
E |
F |
G |
|
Depth |
0 |
1 |
2 |
3 |
4 |
5 |
6 |
|
Requests Served |
Ƞ |
2 × Ƞ |
4 × Ƞ |
8 × Ƞ |
8 × Ƞ |
8 × Ƞ |
8 × Ƞ |
This could be distilled all the way down to a easy system, assuming the variety of retries R is similar at each hop. ɗ denotes the depth of the node within the name chain, the variety of requests served by the node if the node creates or passes by an error:
Rɗ × Ƞ
Retry Budgets
We can optimize this by introducing retry budgets. Let’s assume the identical retry price range at each hop represented by B. The new system turns into:
(1+B)ɗ × Ƞ
Now, let’s attempt to see the variety of requests served with a retry price range of 10%:
|
Node |
A |
B |
C |
D |
E |
F |
G |
|
Depth |
0 |
1 |
2 |
3 |
4 |
5 |
6 |
|
Requests Served |
Ƞ |
1.1 × Ƞ |
1.21 × Ƞ |
1.33 × Ƞ |
1.33 × Ƞ |
1.33 × Ƞ |
1.33 × Ƞ |
In the above instance, the error originates at NodeD, and if we restrict the retry to solely between NodeD and NodeC , and limit totally NodeA and NodeB from retrying on this error, we will assure an identical availability of the call-path with out overburdening NodeD, NodeE, NodeF , and NodeG.
Error Ownership
Consider the identical instance of retry budgets whereas limiting retries between the sting from NodeC to NodeD, the place the error originates.
|
Node |
A |
B |
C |
D |
E |
F |
G |
|
Depth |
0 |
1 |
2 |
3 |
4 |
5 |
6 |
|
Requests Served |
Ƞ |
Ƞ |
Ƞ |
1.1 × Ƞ |
1.1 × Ƞ |
1.1 × Ƞ |
1.1 × Ƞ |
Here, we clamp down the whole variety of requests served by all nodes from D until the leaf node G to only 10% over baseline, whereas permitting not less than as soon as retry for as much as 10% of errors once they’re first returned. But what concerning the availability of NodeD as seen by NodeC? Let’s run some numbers for varied availability situations, and attempt to calculate availability after retry.
|
Base Availability % |
Base Error Rate % |
Retry Budget |
Error Rate after Retries % |
Availability after Retries % |
|
99.9 |
0.1 |
10% |
0.0001 |
99.9999 |
|
99 |
1 |
10% |
0.01 |
99.99 |
|
95 |
5 |
10% |
0.25 |
99.75 |
|
90 |
10 |
10% |
1 |
99 |
|
80 |
20 |
10% |
12 |
88 |
|
70 |
30 |
10% |
23 |
77 |
As proven within the desk above, for availability drops as much as 10% within the callee node, even a single retry is useful in getting the perceived availability by the caller node as much as 99%. Beyond this, perceived availability drops considerably as an excellent chunk of requests are by no means retried because of the retry price range in place.
This calculation assumes the errors from the callee are unbiased and that retries will result in restoration. However, in lots of real-world situations like service overload, dangerous database hosts, database overload, or sharding points, the likelihood of retries stays excessive even with retries.
This contradicts the concept that retries to callee at all times enhance perceived availability to the caller. It’s additionally this instinct that varieties the idea of error possession. During durations of excessive error charges from a service, the errors are much less prone to be randomized, and wouldn’t profit from a better variety of retries, and as a substitute is likely to be liable for additional degradation.
Architecture
The resolution is about establishing error possession, which could be defined utilizing the symptom versus trigger analogy.
If a service calls N outbounds for fulfilling a request, and if an outbound error-out causes it to return an error, then the error returned by that service is barely a symptom. Simultaneously, within the context of the service, the trigger is the incoming error from its downstream.
However, if no outbound of the service errors out whereas fulfilling the request and it nonetheless returns an error, the service is the reason for the returned error, and is the proprietor. In the subsequent part, we talk about some attainable options that may leverage this.
Simple Correlation
Claiming Error Ownership
We use the Service Dependency Analysis Solution to correlate an inbound failure with an outbound failure and use the ruleset proven in Figure 3 for making or refuting error claims.
Figure 3: Decision logic for claiming error possession.
Retrying with Error Ownership
The caller makes use of the logic proven in Figure 4 to find out if it ought to retry the request.
Figure 4: Decision logic for permitting retries.
While the situation of lacking error declare headers is an uncooperative atmosphere, it might happen as a result of the downstream service doesn’t have the service dependency evaluation resolution, and is unable to correlate outbound and inbound errors. Or, the downstream service has lacking context propagation, leading to an incomplete correlation between outbound and inbound errors.
Here, the primary node to see a lacking error declare from a downstream unclaims the error, limiting the affect radius of the retry disturbance (it’s now not a storm), whereas nonetheless permitting enough retries to the error-returning service.
Decision Matrix
|
Callee Error |
Caller Error |
Callee Error Claim |
Caller Should Retry (Retry Middleware) |
Caller Propagated Error Claim |
|
No |
Yes |
NA |
NA |
Claim |
|
Yes |
Yes |
Missing |
Yes |
Unclaim |
|
Yes |
Yes |
Claimed |
Yes |
Unclaim |
|
Yes |
Yes |
Unclaimed |
No |
Unclaim |
Figure 5: 3 nodes used to show caller errors.
When the sides A -> B and B -> C are fail-close, and the Node C returns an inner error that it’s claimed, Node B upon seeing the claimed error from C ought to retry to C. However, if the retry fails, it’d propagate the error to Node A, however whereas returning the error it should unclaim it. Node A upon seeing the error from B and the unclaimed error header shouldn’t retry the request to Node B.
Figure 6: Decision logic for Error declare propagation.
Coincidental Errors and Why We Need Service Dependency Analysis
The choice matrix above covers instances the place the downstream name fails or there’s an inner server error. There may be situations the place each occur concurrently, as proven in Figure 7.
Figure 7: Example the place Node A has 2 fail-open dependencies, Node B and Node C.
In this instance, Node A can be experiencing a ten% error price due to an overloaded cache/database that isn’t tracked through the service dependency evaluation resolution. This makes it an inner server error of Node A, and Nodes B and C even have a ten% error price for unrelated causes.
The service dependency evaluation resolution tries to attribute errors to downstreams first and itself final, so even when Nodes B and C are fail-open, it assigns the blame to them when the failures are colocated. This unclaims the error and prevents the upstream of Node A from retrying to it and presumably recovering.
The affect of missed official retry alternatives in such a situation is important. If Node A serves 100 requests, out of which 10 expertise inner server errors originating at Node A, 1.9 of these 10 requests could be incorrectly unclaimed by Node A as an error not originating from itself, leading to a missed official retry alternative.
Based on the evaluation of the 6 months of service dependency evaluation resolution information, coincidental errors like a official server error or a fail-close dependency error occurring throughout a fail-open dependency error are extraordinarily uncommon. In the worst case situation, for 80% of edges with over 100 callee failures in a minute, round 2% of the occasions the caller failed too (a coincidental failure). Using the instance above, we’d get 0.396 out of 10 requests that’d be incorrectly unclaimed by Node A.
However, even when we fixate on the worst case, for the reason that service dependency evaluation resolution creates a reminiscence of failure patterns, it may possibly leverage this reminiscence to solely unclaim errors when inbound failures correlate with outbound failures in fail-close dependencies. This eliminates the danger of retry suppression throughout coincidental errors.
Figure 8: Decision logic for figuring out when to retry.
Edge Case Scenarios
Guaranteeing At-Least-Once Retries
Many providers don’t have retries configured for his or her fail-close outbounds. Eliminating retries from callers of those providers would result in availability drops alongside the incoming caller chain.
This is solved by introducing a flag to sign whether or not retry standards is glad for an error returned by a downstream. When the retry middleware sees an error from the downstream, it may possibly compute whether or not the retry standards is glad and cross that alongside to the service dependency evaluation resolution.
Figure 9: Retry logic to ensure at-least-once retries.
The Retry Middleware marks retry standards glad if any of the next circumstances proven in Figure 10 are met.
Figure 10: Decision logic to find out whether or not the retry standards is glad.
The service dependency evaluation resolution leverages this retry standards glad sign from the retry middleware to resolve on the inbound whether or not it must personal the error returned by the fail-close downstream.
Figure 11: Decision logic for service error possession.
Here’s the end-to-end move:
Figure 12: End-to-end move.
We don’t introduce any new retries alongside the decision chain. The retry-at-least-once habits solely works if not less than one service alongside the decision chain has retries configured.
By introducing an at-least-once-retry assure, we eradicated availability drops in our name chains. At the identical time, we safeguarded them towards retry storms by leveraging error possession.
Context Drop Handling
Figure 13: 4 nodes used to show context drop dealing with.
For the service dependency evaluation resolution and error possession, intra-service context drops shift the retryable error left. Consider the instance in Figure 14, the place Node D returns an inner error to Node C. The intra-service context in Node C is damaged, so the service dependency evaluation resolution can’t correlate the outbound request from Node C to D with the incoming request from Node B to C.
As a end result, Node C claims the error, whereas decoupled retries on the retry middleware proceed to occur between Node C and D. A set of retries additionally occurs between Node B and C, as Node C should declare the error it’s returning. However, when the retries fail and Node B returns an error to Node A, it additionally returns the unclaimed error header, which ought to forestall Node A from retrying the request to Node B. In this case, we lower down the whole variety of requests to Nodes B by D by half, assuming a single retry (1 try and 1 retry) configuration in any respect nodes. If there have been 5 nodes to the left of Node A, the worst case would’ve had 32 occasions extra requests with out error possession propagation.

Figure 14: Description.
Figure 14: Description.
Error Ownership in Production
Everything described to date isn’t theoretical—error possession is absolutely applied and operational throughout Uber’s service mesh at present. The scheme runs within the retry middleware and the Service Dependency Analysis Solution that sit within the request path of our user-facing APIs, repeatedly claiming and unclaiming errors as site visitors flows by deep dependency chains. Because it’s embedded in shared utilities, providers inherit retry-storm safety with out bespoke per-service error-handling logic. The following real-world incident demonstrates how this manufacturing deployment behaved below a real large-scale degradation.
Use Cases at Uber
On November 18th, 2025, Uber had a major outage resulting from a problem with a Core Entity service. The service lives over 5 ranges deep in our name chain and is important for trade operations. It began returning a really excessive error price resulting from an underlying utilities difficulty. This error was rapidly propagated up the decision chain. During this time, many upstream caller providers had sufficient alternative to retry the failed requests returned by these providers. With easy retry budgets, this may’ve resulted in a 46%-135% site visitors enhance on the degraded service, prolonging the outage by diminishing probabilities of restoration. Because error possession was already enabled in manufacturing, as described above, the system contained the blast radius mechanically
Immediate retry makes an attempt had been stopped to the fast callers of the degraded service, the place some callers had been stopped from making as much as 200,000 further requests. We additionally calculated the retries that had been stopped on the ancestors of those fast callers, and aggregated them on the root node. We realized that we might cease a staggering 9.5 million spurious requests in our service mesh. Those might’ve simply extended the outage by continuously hammering the degraded service.
Our method has dramatically diminished the whole request quantity flowing by the decision graph throughout degradation occasions.
To quantify this, we outline the max retry storm radius after error possession because the max depth of name path the place a retry storm might occur after error possession was enabled. It’s computed for the decision graph of each root node. Across all our user-facing APIs, we obtained this worth all the way down to a most of three, the place the sooner worth of max retry storm radius was as much as 25. We additionally obtained the common all the way down to 2 from 20.
Figure 15: Max retry storm radius after error possession.
By limiting retries completely to error-owning providers, the place they will genuinely resolve the problem, we will forestall the exponential fan-out of requests attribute of retry storms. This has helped safeguard Uber’s utilities from cascading failures triggered by single-point degradations.
Acknowledgments
Cover Photo Attribution: Generated with ChatGPT by OpenAI; no exterior photographs, logos, or third-party belongings used.
Stay updated with the most recent from Uber Engineering—observe us on LinkedIn for our latest weblog posts and insights.