Emulating Reminiscence Entry: How Onerous Can It Be?
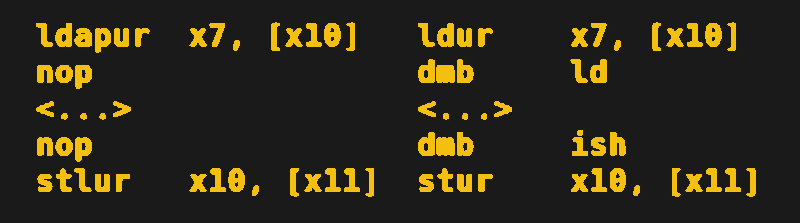

There are so many issues we approximate to make life easy. Wires, for instance, don’t have any resistance or different unusual results. Crystal oscillators output their precise frequency. But absolutely our mannequin of how a pc shops and hundreds reminiscence is correct, proper? You put knowledge in a specific location and, later, you’re taking it out. The [FEX-Emu] builders have a unique perspective. Once you might have caches and, maybe, a number of CPUs, it isn’t that easy.
The primary drawback is that this: if one CPU (or, extra precisely, bus grasp) writes to a location, will one other CPU have entry to the brand new worth? X86’s Total Store Ordering mannequin provides programmers robust ensures about when hundreds and shops turn out to be seen, whereas ARM intentionally makes use of a weaker reminiscence mannequin that allows significantly extra reordering for efficiency and effectivity.
An emulator can, in concept, compensate by translating unusual x86 reminiscence operations into ARM purchase/launch operations, however doing that for almost each reminiscence reference will be costly. Newer ARM extensions akin to LRCPC assist significantly, whereas Apple took a extra direct method by including an x86-compatible TSO mode to Apple Silicon. That lets unusual hundreds and shops behave the way in which translated x86 code expects with comparatively little overhead.
Things get a lot uglier with unaligned accesses and atomic operations. X86 software program routinely performs accesses that ARM would contemplate badly aligned, and x86 gives surprisingly robust atomicity ensures inside a cache line. FEX typically has to catch alignment faults and dynamically patch translated code with limitations. Split-lock operations are worse nonetheless: some require excursions by the kernel and sign handlers and will be lots of or 1000’s of instances slower than the conventional case. Qualcomm’s newer Oryon cores enhance issues by supporting coherent cache-line atomics, whereas Valve has shipped a Linux kernel optimization that handles some troublesome unaligned atomics straight.
There’s one other notably nasty nook involving write-combined GPU reminiscence. PC video games ceaselessly count on x86 ordering semantics whereas writing uncached buffers destined for a discrete GPU. ARM presently lacks a clear equal for a few of these shops, and FEX measured worst-case bandwidth greater than 800× slower, sufficient to cut back some video games to beneath 1 FPS. UMA techniques fare significantly better as a result of drivers can typically substitute unusual cache-coherent reminiscence.
It’s a protracted article, however a very good illustration of why trendy emulators are much less about translating directions and extra about reproducing many years of architectural assumptions that software program quietly relies upon upon. Of course, not all emulators or processor recreations are this correct, and sometimes that’s ok. But typically you want a recreation that’s actually cycle-accurate and behaves precisely like the unique.