Embedded AI evaluators will not be a simple answer, Hugging Face’s coverage chief says
AI labs have staked their reputations on mannequin benchmarking — the supposedly impartial and correct system of evaluations which might be designed to measure whether or not one AI product is best than one other.
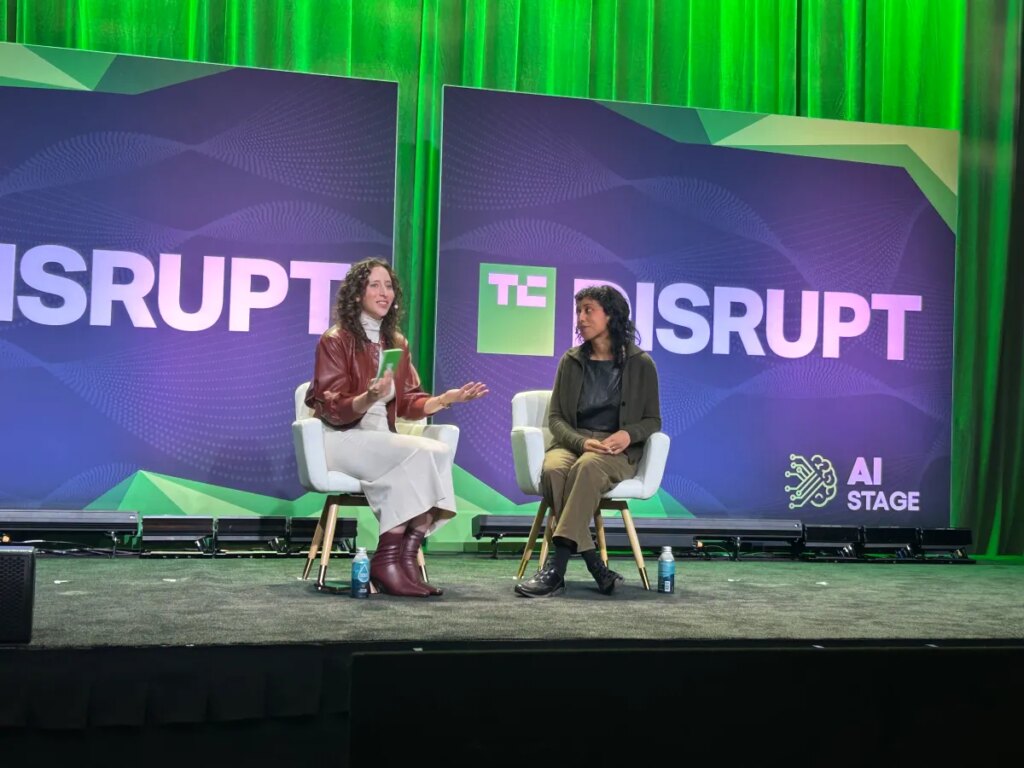
However, the strategies behind these evaluations are difficult and nonetheless maturing, mentioned Irene Solaiman, Hugging Face’s chief coverage officer, throughout a dialogue at TechCrunch Disrupt final week. Testing wants to return collectively right into a extra constant science if the {industry} is to depend on them sooner or later.
With that in thoughts, can we belief the present checks which might be being launched?
“Trust is such a weighted time period,” mentioned Solaiman. “In phrases of whether or not we are able to belief outcomes, one large half [of that] is are you able to reproduce the outcomes of an analysis? Do you may have the extent of entry that you want to the mannequin itself — that is the place open weights are available in an enormous manner,” she added.
Reproducibility in mannequin evaluations has lengthy remained one of many stickier aspects of benchmarking — and stays a subject of great debate within the {industry}.
Outside of a person take a look at’s validity, there’s additionally the added query of how that take a look at compares to different evaluations.
“They are an evolving science — the place we don’t know the way to meaningfully evaluate them to one another,” Solaiman mentioned.
“They begin to get ineffective comparatively shortly, and we don’t have as a lot of a thriving ecosystem as we want,” she added. “There’s this starvation for an embedded evaluator ecosystem now, however the {qualifications} that decide who’s an efficient evaluator throughout what duties want much more standardization.”
The idea of embedded evaluators — wherein supposedly “impartial” third-party observers are positioned inside AI organizations — has been popularized during the last a number of months, as AI labs grapple with a rash of safety incidents which have spurred issues over the potential harms of their know-how. Hugging Face was famously the target of a kind of incidents.
Instead of energetic authorities regulation to establish and mitigate mannequin security issues, labs have pushed for the third-party answer. However, doubts stay over how impartial or efficient these evaluators will truly be. Anthropic’s decision to hire Accenture as its first evaluator spurred a very good quantity of backlash, with some critics mocking the concept the consulting agency was certified to do the duty at hand.
Evaluations at the moment are transferring from merely a take a look at of the mannequin itself to a take a look at of the complete system across the mannequin — together with the harness and agent. The harness — or the software the consumer is utilizing to entry the mannequin — particularly, has quite a bit to do with a mannequin’s efficiency, and a weaker mannequin with a greater harness may simply out carry out a frontier mannequin, Soleiman shared.
“Agentic evals are actually arduous and actually costly,” mentioned Solaiman. “We have simply extra evaluations for fashions. … We don’t have as many evaluations for harnesses, and we’re creating higher evaluations for the holistic agent — as a result of that’s what numerous of us are getting worth out of,” she added.
In different phrases: the analysis house is a little bit of a free-for-all in the meanwhile, and if benchmarking goes to proceed to be seen as a great tool for {industry} leaders, a extra uniform, industry-wide method — the place everyone seems to be on the identical web page — could also be crucial.
When you buy by means of hyperlinks in our articles, we may earn a small commission. This doesn’t have an effect on our editorial independence.