Build Your Personal Reasoning Model: A Full Video Course
I’ve written loads about reasoning fashions right here during the last two years on Ahead of AI, together with a latest article on mechanisms to control reasoning effort levels in contemporary LLMs. Reasoning fashions are nonetheless as related as ever. In truth, virtually all current-generation LLMs at this time are reasoning fashions or supply a reasoning mode.
For those that are involved in how reasoning fashions work, together with inference scaling, reinforcement studying, and distillation, I wrote my latest Build Reasoning Model (From Scratch), which implements these from the bottom up in PyTorch, which, in my expertise, remains to be one of the simplest ways to grasp and find out how issues actually work.
Now, in the previous couple of months, I additionally sat down and recorded accompanying lectures I wished to share with you. So, under, you will discover eight reasoning model-from-scratch coding movies (11 hours of content material).
We begin with a pre-trained LLM and implement strategies to guage and enhance it in Python and PyTorch. So, if you happen to loved my Coding LLMs from the Ground Up course final yr, that is basically the sequel (however you can too watch it with out the prior course as a prerequisite).
I’m at present taking a brief break and will probably be again quickly with extra thrilling LLM analysis roundups subsequent month. In the meantime, I hope you get pleasure from coding alongside!
As a small aspect observe, and since I typically get requested how reasoning fashions relate to at this time’s AI brokers, right here’s a brief part on this earlier than getting began with the movies.
A reasoning mannequin is actually an improve from a traditional LLM, that’s, including extra post-training through reinforcement studying with verifiable rewards (and optionally inference scaling strategies) to make it extra able to fixing tougher issues. Classically, reasoning fashions are developed for math and code, however the capabilities can generalize to different drawback domains as nicely.
A reasoning mannequin then capabilities because the engine inside an agent harness, the place the agent harness is a software program or tooling framework across the LLM/reasoning mannequin to sort out much more difficult issues (larger coding duties, journey reserving, and all different types of non-public assistant duties). The job of the harness is subtle context administration and giving the LLM entry to instruments.
Figure 1: An engine analogy for typical LLMs, reasoning fashions, and agent harnesses. Figure from my Components of a Coding Agent article.
In this analogy depicted within the determine above, the mannequin is the engine, and the agent harness provides the equipment that lets us use it for numerous issues (as an improve from a easy chatbot interface). An agent can use both a traditional LLM or a reasoning mannequin, however reasoning fashions are the extra typical selection as they’re extra succesful. (As talked about above, most current-gen LLMs are reasoning fashions with variable reasoning effort settings.)
So, the underside line is that reasoning fashions, because the “engine,” stay an vital a part of understanding fashionable LLM brokers.
The assets accompanying these subjects proven above are:
-
The Build a Large Language Model (From Scratch) book and videos
-
The Build A Reasoning Model (From Scratch) book (and movies under)
-
The Components of a Coding Agent article on Substack
The movies under deal with creating the reasoning mannequin that may energy such a system.
The reasoning-from-scratch movies deal with a small pre-trained Qwen3 mannequin, the place we implement the reasoning strategies ourselves in Python and PyTorch. Starting with a pre-trained mannequin lets us deal with the attention-grabbing half: analysis, inference-time scaling, reinforcement studying, and distillation.
Regarding the conditions, I like to recommend being comfy with Python and PyTorch. I designed the reasoning supplies as standalone content material, so the earlier Build A Large Language Model (From Scratch) content material is advisable however not strictly required.
Compute-resource-wise, you may work via the early text-generation and analysis examples on a CPU. For the later experiments, particularly coaching, a GPU makes the work rather more sensible. The first video covers the setup and a few extra suggestions; the repository additionally consists of hardware and environment recommendations.
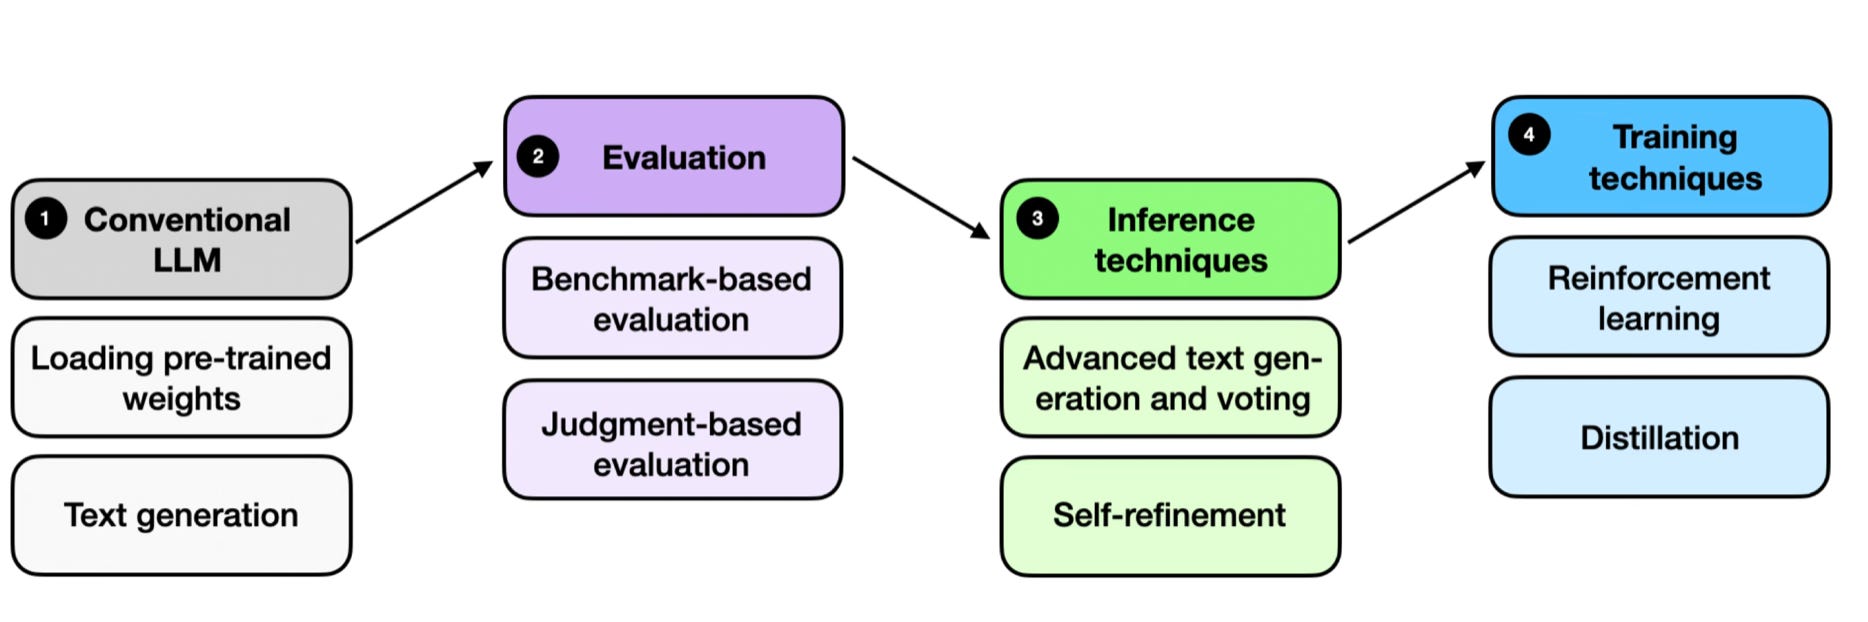
Figure 2: An overview of the subjects being lined.
These movies accompany my e book, Build a Reasoning Model (From Scratch). If you wish to learn via the reason in additional element and at your individual tempo, work via workouts, and so forth, I like to recommend the e book as a companion right here.
For probably the most in-depth studying expertise, my suggestion is to learn a chapter, work via its code alongside the corresponding video, after which attempt the workouts.
The e book is on the market from Manning and Amazon, and the print version is in colour!
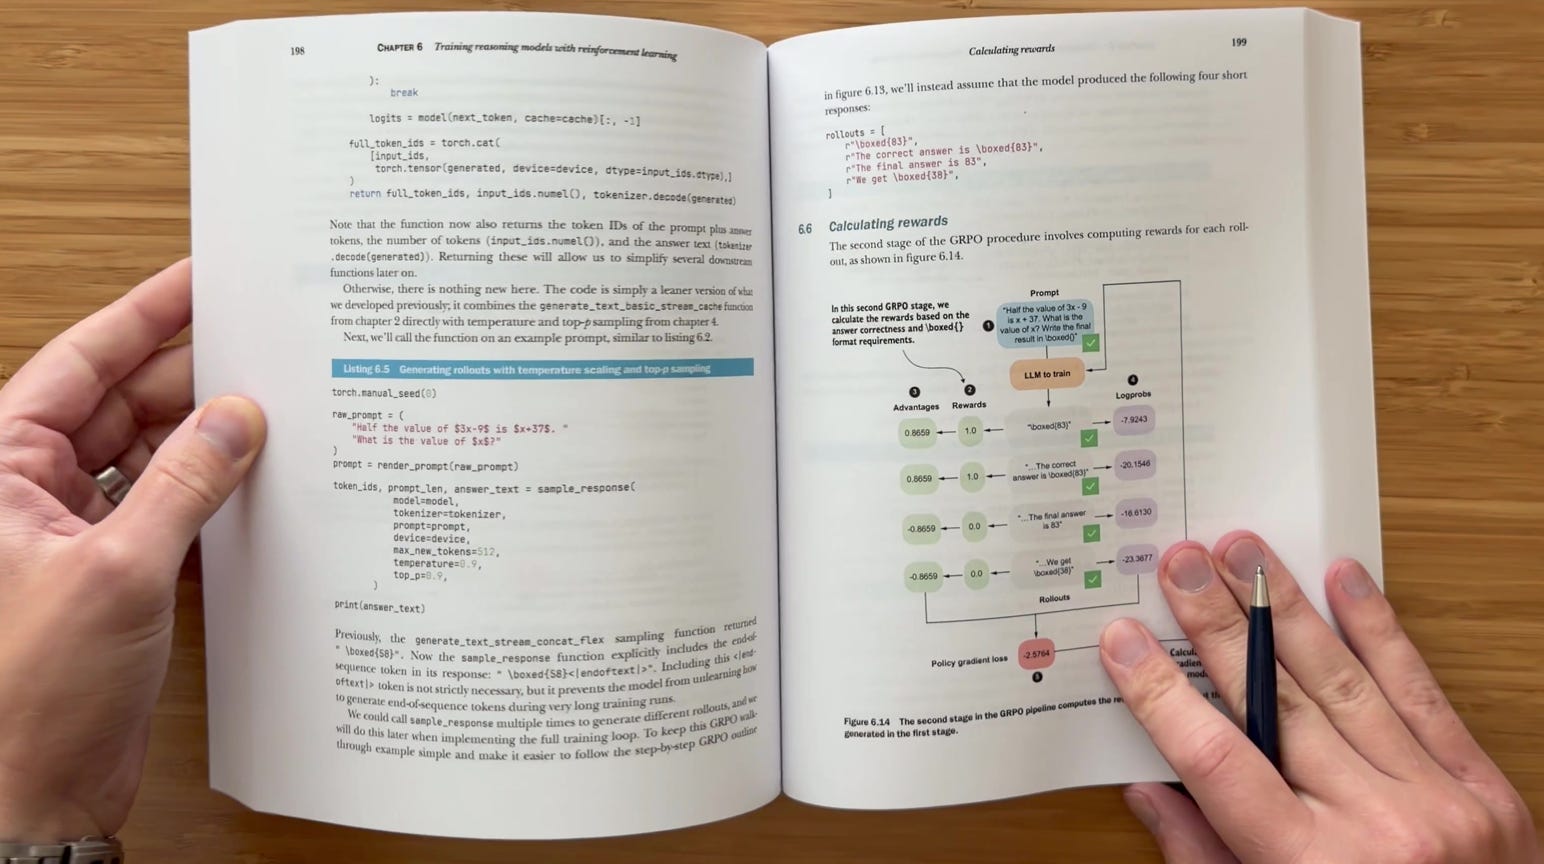
Figure 3: A random excerpt from the Build a Reasoning Model (From Scratch) print e book.
Thank you to everybody who has picked up a replica or advisable it to a pal. Your help helps me maintain creating these supplies.
As a final, fast aspect observe earlier than attending to the principle movies under: For a shorter, extra conceptual overview, I additionally advocate my AI Reasoning Models course on LinkedIn Learning (it needs to be free for 24h when accessing it through the hyperlink there, which shouldn’t then require a LinkedIn Premium subscription).
The course is about 90 minutes and explains how reasoning fashions work, overlaying the principle concepts behind inference-time scaling, reinforcement studying, and distillation. It’s non-obligatory preview if you happen to’d like the principle concepts with out working via the complete implementations under.
To get to the principle a part of this text, listed here are the eight predominant lecture movies.
The first video begins with a proof of the connection between typical LLMs, reasoning fashions, and brokers. Next, the principle matter of the video is organising the coding atmosphere. This consists of putting in the Python and PyTorch dependencies (with uv), amongst others. I additionally talk about {hardware} decisions and customary setup points.
Topics lined
-
The relationship between typical LLMs, reasoning fashions, and agent harnesses
-
On the advantages of studying via code implementations
-
The scope of this video sequence
-
Installing Python dependencies
-
Choosing {hardware} and checking CUDA or Apple Silicon help
-
Using a distant GPU with VS Code and troubleshooting the atmosphere
Watch video 1 · Setup instructions
Before including reasoning strategies within the upcoming movies, we’d like a working base mannequin. Instead of coaching it from scratch, since that may be an entire different e book (see Build A Large Language Model (From Scratch)), we begin with a pre-trained mannequin.
Here, we load the pre-trained weights of a Qwen3 0.6B mannequin. Then, we implement the text-generation course of through a streaming textual content generator and add KV caching and mannequin compilation to make textual content technology extra environment friendly.
These implementations give us the baseline and base elements we’ll consider and enhance within the following movies.
Topics lined
-
Encoding textual content as tokens and decoding it again into textual content
-
Downloading Qwen3 weights and loading the mannequin on the chosen compute machine
-
Going over tensor shapes, logits, and next-token predictions
-
Implementing grasping decoding and streaming textual content technology
-
Handling end-of-sequence tokens and measuring technology velocity
-
Adding a KV cache to reuse consideration keys and values
-
Combining KV caching with
torch.compileand evaluating {hardware} efficiency
Watch video 2 · Chapter 2 code
In this lecture, we construct a math-answer verifier step-by-step, from reply extraction to normalization and checking mathematical equivalence. We then use it to guage the mannequin on MATH-500.
We use this verifier to guage the bottom mannequin’s efficiency on the MATH-500 analysis dataset.
However, the verifier additionally has a second job later within the sequence: offering the reward sign for reinforcement studying with verifiable rewards (RLVR).
Topics lined
-
Intro to verifiers and the way they match into LLM analysis strategies (different strategies are lined within the e book’s appendix)
-
Reusing reply verification as a reward sign for RLVR (extra on that in chapter 6)
-
The verifier movement, together with extracting closing solutions, normalizing solutions and checking mathematical equivalence
-
Building a solution grader and an analysis loop for MATH-500
-
Comparing base and reasoning fashions on MATH-500
Watch video 3 · Chapter 3 code
Now we discover methods to enhance solutions whereas preserving the mannequin weights mounted. But earlier than implementing particular inference-scaling strategies, we first implement strategies to generate numerous solutions from the identical immediate (that is customary apply in proprietary LLM chatbots, similar to ChatGPT).
Concretely, we implement temperature scaling, multinomial sampling, and top-p filtering to generate numerous responses. Then we mix a number of responses via self-consistency, utilizing majority voting over their closing solutions.
We additionally look at the tradeoff between reply accuracy and the additional computation wanted to generate extra candidates.
Topics lined
-
Comparing how further compute advantages mannequin efficiency throughout coaching and through inference
-
A mild intro to inference-scaling via chain-of-thought prompts
-
Implementing temperature scaling and multinomial sampling to generate numerous solutions
-
Adding top-p filtering to regulate the standard of the varied solutions
-
Combining candidate solutions via self-consistency, one of the crucial well-liked inference scaling strategies
-
Evaluating MATH-500 accuracy in opposition to the price of further inference compute
Watch video 4 · Chapter 4 code
Building on the earlier video, we implement scoring capabilities to check a number of solutions generated from the identical immediate. We also can use these scoring strategies to interrupt ties in self-consistency (lined within the earlier lecture).
The scoring strategies lined right here embody computing token and sequence log chances (this will even be related within the later reinforcement studying chapters). We then implement a self-refinement loop through which the mannequin critiques a solution and makes an attempt a revision.
The analysis lets us examine how helpful these further steps are for our mannequin.
Topics lined
-
Using scoring capabilities for evaluating a number of solutions and breaking ties
-
Implementing a easy heuristic scorer
-
Computing token chances and sequence likelihoods (additionally related for the next lectures)
-
Using log chances for improved numerical stability
-
Building a self-refinement loop for producing critiques and revised solutions
-
Evaluating self-refinement on MATH-500
Watch video 5 · Chapter 5 code
In this lecture, we transfer on to implementing a coaching approach known as Reinforcement Learning with Verifiable Rewards (RLVR). We first implement a simplified model of Group Relative Policy Optimization (GRPO), generate teams of responses, rating them with our verifier, and use their relative rewards for the mannequin weight updates throughout coaching.
Topics lined
-
Generating reasoning traces and understanding the connection between reply lengths and problem-solving talents
-
Discussion and comparability of two vital LLM post-training strategies: Reinforcement Learning with Human Feedback (RLHF) and Reinforcement Learning with Verifiable Rewards (RLVR)
-
Turning verifier scores into rewards and relative benefits
-
Computing sequence log chances and a simplified GRPO loss
-
Assembling the coaching loop with logging and checkpoint saves
-
Evaluating checkpoints and checking coaching stability and reminiscence wants
Watch video 6 · Chapter 6 code
Now that we carried out the coaching loop within the earlier lecture, we will revisit it and analyze the coaching runs in additional element.
Concretely, this video provides extra coaching metrics for inspection and evaluation, together with entropy and benefit statistics, clipped coverage ratios, KL loss time period values, and formatted rewards.
We then assessment the coaching logs and analysis outcomes to grasp what these additions do and whether or not additions similar to clipped coverage ratios and KL loss phrases are useful.
Topics lined
-
Running longer coaching experiments and decoding their logs
-
Tracking benefits and entropy to grasp coaching conduct
-
Implementing clipping within the coverage loss and analyzing its results
-
Adding a KL loss time period and discussing reward hacking
-
Understanding limitations of the simplified KL formulation
-
Implementing format rewards and conditioning them on reply correctness
-
Comparing checkpoints on MATH-500 and exploring additional GRPO analysis
Watch video 7 · Chapter 7 code
Finally, we discover one other solution to practice a small reasoning mannequin, that’s, studying from solutions generated by a stronger (and larger) instructor mannequin. We talk about completely different types of distillation, put together reasoning knowledge, and implement the supervised coaching loop.
We end this lecture and course by evaluating the distilled mannequin on MATH-500 and evaluating the outcomes. This rounds out the sequence with an alternative choice to creating reasoning capabilities via reinforcement studying.
Topics lined
-
Comparing the completely different mixture and approaches to distillation, together with smooth and laborious distillation, and on-policy and off-policy distillation
-
Creating and accumulating teacher-generated solutions for the MATH dataset (utilizing DeepSeek R1)
-
Preparing the distillation dataset, together with tokenization and coaching/validation/check splits
-
Computing answer-token log chances and understanding the cross-entropy loss
-
Implementing supervised coaching and monitoring coaching and validation losses
-
Evaluating checkpoints on MATH-500 and evaluating distillation outcomes
Watch video 8 · Chapter 8 code
As you watch these lectures, I encourage you to pause often and check out a small experiment of your individual if one thing attention-grabbing involves thoughts.
For instance, be happy to vary the sampling settings, examine a couple of failed solutions, or attempt variations of various concepts just like the options within the workouts.
And if you want the complete written walkthrough, figures, and workouts alongside the movies, you could find Build a Reasoning Model (From Scratch) at Manning and Amazon.
Thanks for studying and supporting Ahead of AI. I’m taking a brief break to regenerate, and I sit up for being again with the subsequent spherical of LLM analysis articles subsequent month.
In the meantime, pleased viewing and tinkering!