All you want is Wide Events, not “Metrics, Logs and Traces”
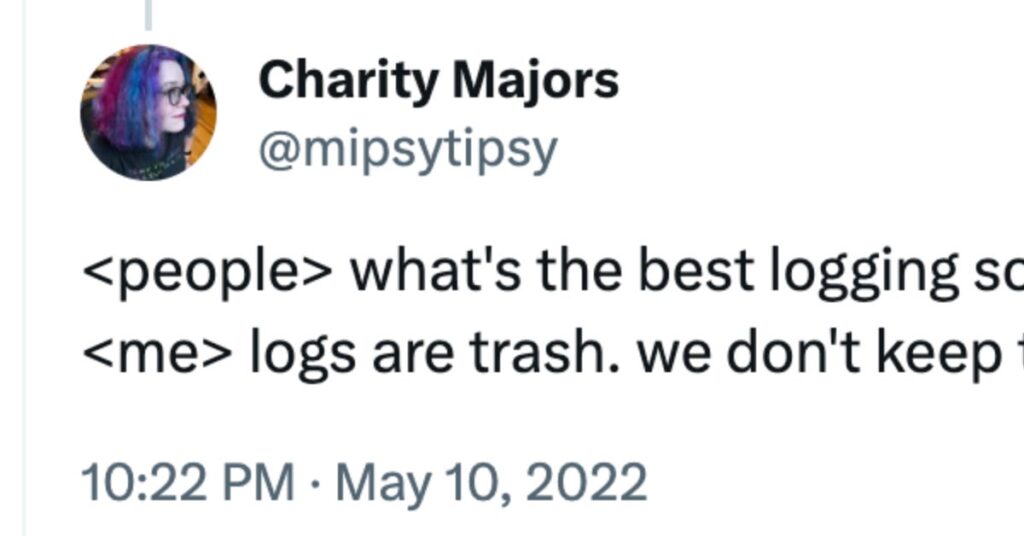
This quote from Charity Majors might be the very best abstract of the present state of observability within the tech business – a complete, mass confusion. Everyone is confused. What is a hint? What is a span? Is log line a span? Do I would like traces if I’ve logs? Why I would like traces if I’ve nice metrics? The listing of questions like these goes on. Charity – along with different nice of us from observability system referred to as Honeycomb – have been doing an awesome job shedding mild on these questions. Yet, per my very own expertise it’s nonetheless extraordinarily exhausting to elucidate what does Charity meant by “logs are thrash”, not to mention the truth that logs and traces are primarily the identical issues. Why is everybody so confused?
With the danger of being spicy a little bit, I’m going accountable Open Telemetry. Yes, it’s powering the trendy observability stack and but I blame it for the mass confusion. Not as a result of it’s a foul answer – it’s nice! But the presentation and the entire method of explaining what Open Telemetry is and what it does makes the observability look tough and sophisticated.
First, Open Telemetry from the very starting makes a transparent distinctions between traces, metrics and logs:
OpenTelemetry is a group of APIs, SDKs, and instruments. Use it to instrument, generate, acquire, and export telemetry knowledge (metrics, logs, and traces) that can assist you analyze your software program’s efficiency and habits.
Then it goes deeper in explaining every of those 3.

This is screenshot from the a part of open telemetry web site introducing traces. Based on my expertise speaking to individuals who work with OpenTelemetry, this presentation has certainly develop into one of many principal footage being related to observability. For some, this IS the observability. And it additionally units traces other than the rest. This is evident not a log, is it? This additionally doesn’t appear to be a metric, proper? It’s one thing particular, in all probability a bit sacred, and requiring studying capital allocation. Per my expertise, as soon as folks realized about traces, they solely take into consideration them within the context of this image and the entire set of phrases like spans, root spans, nested spans and the remainder. OpenTelemetry web site has a glossary web page with greater than 60 phrases! This all is insanely advanced!
But what’s extra essential – does this give attention to “logs, metrics and traces” signify the true energy of observability? It does cowl some situations that’s true, however in terms of the distributed methods at scale what’s extra essential is a capability to “dig” into knowledge – “slice and cube” it, construct and analyse numerous views, correlate, seek for anomalies… And methods that supply all of this do exist.
When I used to be working at Meta, I wasn’t conscious that I used to be privileged to be utilizing the very best observability system ever. This system is named Scuba and it’s the highest 1 factor by a big margin that individuals miss after they go away Meta.
The fundamental concept of Scuba is very simple and doesn’t require a glossary web page for folks to know. It operates with Wide Events. Wide Event is only a assortment of fields with names and values, just about like a json doc. If you have to file some data – whether or not it’s the present state of the system, or an occasion brought on by an API name, background job or no matter – you possibly can simply write some Wide Event to Scuba. For occasion, if a system serves adverts, the pure want could be to file Ad Impressions – the info {that a} sure advert has been seen by a person. The corresponding Wide Event is perhaps wanting like this:
{
    "Timestamp": "1707951423",
    "AdId": "542508c92f6f47c2916691d6e8551279”,
    "UserNation": "US",
    "Placement": "mobile_feed",
    "CampaingType": "direct_ads",
    "UserOS": "Android",
    "OSVersion": "14",
    "AppVersion": "798de3c28b074df9a24a479ce98302b6",
    ...
}
Such occasions referred to as extensive, as a result of it’s inspired to dump to all of them the knowledge one can consider. Anything that is perhaps related within the context of a sure knowledge – simply put it there, it is perhaps helpful later. This method is laying the groundwork for coping with unknown unknowns – one thing you possibly can’t consider now which may be revealed later throughout an incident investigation.
Dealing with unknown unknowns may be higher demonstrated on an instance. Scuba has a pleasant intuitive interface which is simple to discover and play with. It has a bit the place one can choose a metric to take a look at, in addition to sections for filters and groupings – and Scuba would draw a pleasant time sequence chart. Firs search for Ad Impressions dataset would merely draw a chart with impressions rely:

If we specific what’s precisely is chosen right here by way of SQL, then that is one thing like
SELECT COUNT(*) FROM AdImpressions
WHERE IsTake a look at = False
Well, it’s truly not precisely like that. Scuba additionally has an idea of native sampling. When a sure occasion is written to Scuba, it additionally should write a discipline referred to as samplingRate – the speed this explicit occasion is being sampled with. Scuba makes use of this data to correctly “upscale” outcomes proven on the charts, so there isn’t a want to do that upscaling within the head. This is a very nice idea as a result of it permits a dynamic sampling – e.g. some kind of impressions could also be sampled greater than one other, whereas preserving the “actual” values within the UI. So, the precise question underneath the hood is
SELECT SUM(samplingRate) FROM AdImpressions
WHERE IsTake a look at = False
Note that this entire “upscaling” is finished transparently by the UI and customers don’t give it some thought throughout querying.
And so assume some alert occurred and indicated that our treasured Ad Impression chart is wanting bizarre:

The first intuition of everybody who’re utilizing Scuba for investigation is to “slice and cube”, i.e. filter or group by, to see if we will be taught one thing. We don’t know what we’re searching for, however we consider that we’ll discover it. So we’d group by say impression kind, or person nation, or the location, till we’d discover one thing suspicious. Let’s assume it’s CampaignType grouping:

We see that some marketing campaign kind referred to as in_app_purchases (simply in case need to notice that this kind title is totally made-up by me) appears to look in a different way than others. We don’t actually know that does it imply – we don’t have to! – to proceed our digging. Okay, now we will filter these campaigns solely, and proceed grouping by one thing else we will consider. For occasion, User OS is sensible.
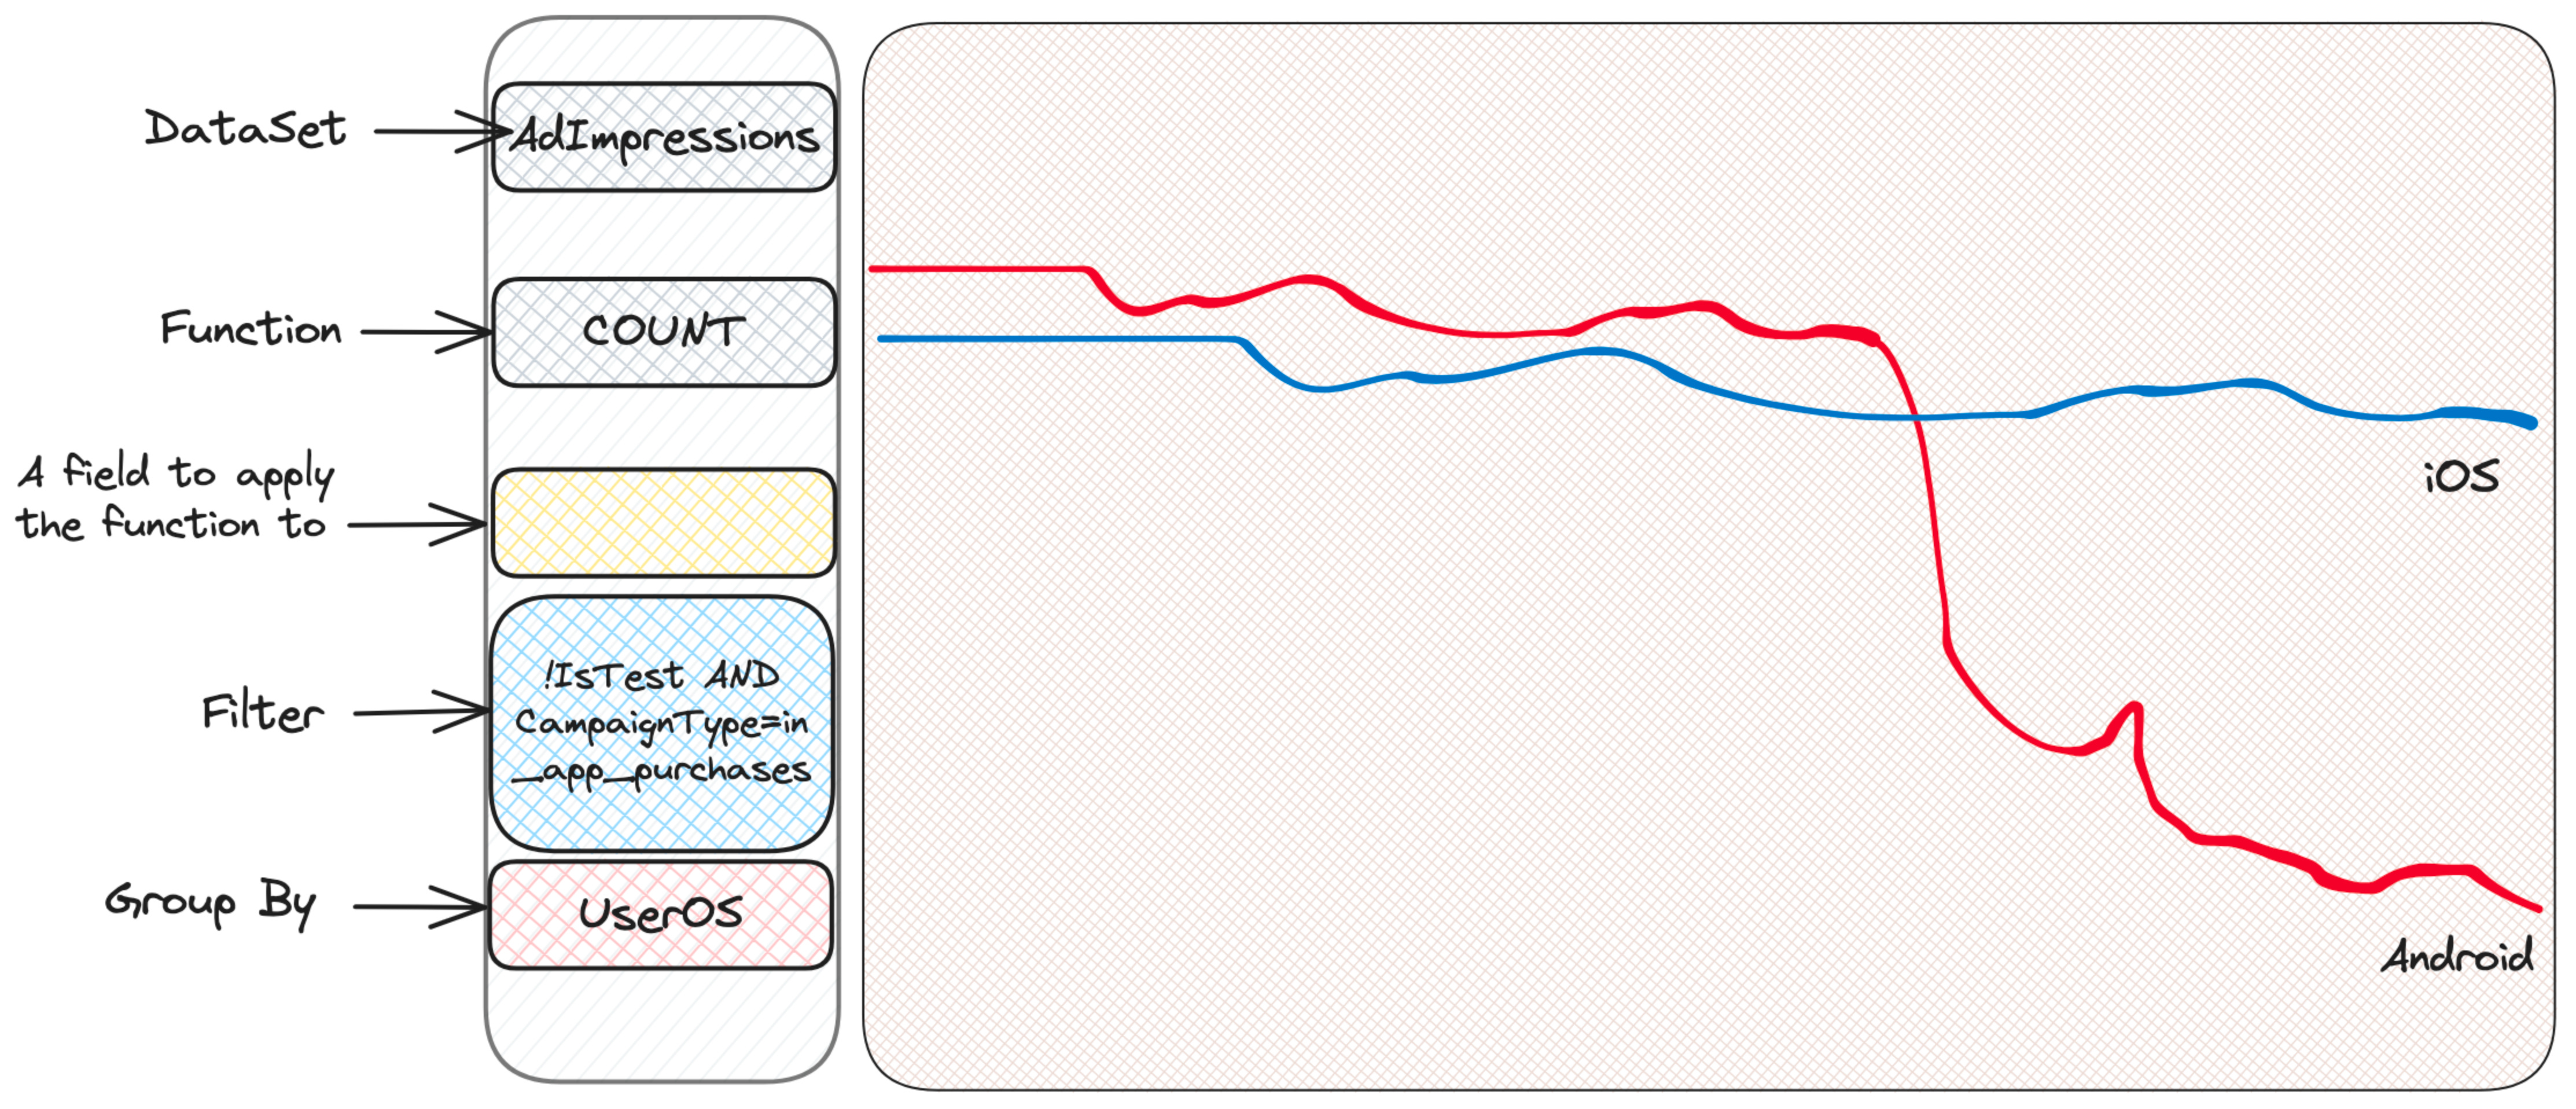
Hmmm, Android appears to be in bother. iOS is OK, which means that the issue is on the consumer facet – a damaged app model perhaps?

Weird. Some are struggling, some others don’t. Check OS Version perhaps?

Ha! It’s the latest model of the OS, and appears like among the app variations aren’t doing properly on this OS model for any such marketing campaign. The devoted groups could look deeper now, given this data.
What occurred? Without any data of the system we’ve narrowed down the scope of the difficulty, and recognized the groups to take a lead for additional investigation. Could we all know upfront that this bizarre mixture of OS, OS Version, Campaign Type and App Version may result in some challenge, to have a devoted metric ready? Of course no. This is an instance of coping with unknown unknowns. We’ve simply dropped all of the related context into Wide Events, and used it later when wanted. Scuba made it easy to do the exploration as a result of it’s quick and has a very nice easy-to-use UI. Also notice that now we have by no means talked about something about cardinality. Because it doesn’t matter – any discipline may be of any cardinality. Scuba works with uncooked occasions and doesn’t pre-aggregate something, and so cardinality is just not a difficulty.
Sometimes UI / Visualisation side doesn’t get sufficient consideration, and observability methods provide some question language – both a proprietary (bad-bad-bad), or SQL (barely higher, however nonetheless unhealthy). Such an interface makes it near inconceivable to conduct related investigations. One essential side of Scuba that each one the fields – operate, filter, grouping, and so forth. – are explorable. Meaning that there’s a straightforward technique to see what sort of values we will choose. When the house owners of a sure discipline aren’t lazy, they even included an in depth description for the given discipline with related hyperlinks and so forth. This is big. I’ve efficiently investigated quite a lot of incidents myself, with out full understanding of both the entire system, or the info accessible on this dataset. And boy I did be taught so much concerning the system throughout these investigations, merely through enjoying round with Scuba! This was wonderful. This was observability paradise.
Now think about my stage of confusion and disbelief once I left Meta and obtained to know the state of observability methods exterior.

Logs? Traces? Metrics? What the hell? Wide Events, anybody? Can I please not be taught that 60 phrases from the Glossary and simply … discover stuff?
It took me fairly some time to map my Scuba-based psychological mannequin to Open Telemetry psychological mannequin. I realised that Open Telemetry’s Span is, in truth, the Wide Event. Actually, I’m nonetheless not fairly positive I obtained it proper:

If we take AdImpression instance, this impression is just not actually an operation, it’s just a few truth we need to file… To be honest, there’s some notion of Event in Open Telemetry:

But if we comply with the hyperlinks to dig deeper, we once more discover out that Event is in truth one in all Traces, Metrics or Logs 🤷

But anyway, Span is the closest idea to Wide Event. The factor is – it’s extraordinarily exhausting to advocate for this psychological mannequin when the one recommended by Open Telemetry is already realized. Which is admittedly upsetting, as a result of Traces, Metrics and Logs are all simply particular instances of Wide Events actually:
-
Traces and Spans: These are simply extensive occasions having SpanId, TraceId and Father or motherSpanId fields. So we will filter all spans with a given TraceId, topologically kind them utilizing SpanId → Father or motherSpanId relation, and draw that distributed tracing view everybody loves.
-
Logs: Honestly, I’m actually confused what Open Telemetry means by Logs. Looks like a lot of things, and one in all them is Structured Log which is just about the Wide Event. Great! The downside, nonetheless, that “a log” is kind of an outlined idea, and often folks imply by it’s what’s produced by these
logger.information(…)calls. Anyway, no matter is supposed, logs may be simply mapped to extensive occasions, in fact. In the best case we will simply get the log message, put it to the “log_message” discipline, add a bunch of metadata, and be completely happy. In a extra advanced case, we will attempt to mechanically extract a template from a log message through eradicating tokens that appears like IDs, and get a hash of this template. This can enable to shortly get essentially the most frequent error, for example, through grouping by this hash. Meta has such a system, and it’s fairly cool. -
Metrics: Metrics may be simply mapped, too. We simply have to emit a Wide Event as soon as per some interval containing the state of the system (system metrics like cpu, numerous counters,…). Prometheus, by the best way, does precisely that with the scraping method – takes a snapshot of the system every so often. Unlike with prometheus, nonetheless, with Wide Events method we don’t want to fret about cardinality.
But Wide Events can provide a lot rather more than these “3 pillars”. The aforementioned debugging session is already a case which isn’t actually lined by Traces, Logs and Metrics – not naturally, at the very least. There may very well be different use instances, too – for example, steady profiling knowledge may be simply represented as a Wide Event, and queried to construct a Flame Graph. No have to have a separate system for this – a single system working with Wide Events can do all of it. Imagine the probabilities for cross-correlation & root trigger evaluation when every little thing in a single place, saved collectively. Especially now, within the period of elevate of AI-based instruments which can be fairly good find correlations in knowledge.
I don’t know… I simply needed to specific my frustration with the extent of confusion and this give attention to “3 pillars”.
I simply want that observability distributors took a stand towards confusion, and provided a easy and pure technique to work together with the system. Honeycomb appears is doing that, in addition to another methods like Axiom. This is nice! And hope the others will comply with.