AI coding has made CI a bottleneck, so we reworked ours to maintain up

Earlier this 12 months, I opened Linear to seek out that Tuomas, our CTO, had assigned a difficulty to me, titled “CI prices are excessive.” While I used to be at it, he additionally wished me to make CI quicker.
Agents have made it exponentially quicker to ship code, however validating these modifications hasn’t fairly stored up on the identical fee. Every PR nonetheless has to cross by CI, in order growth accelerates, CI turns into a bottleneck, driving up development projects prices and leaving builders and brokers ready longer for suggestions.
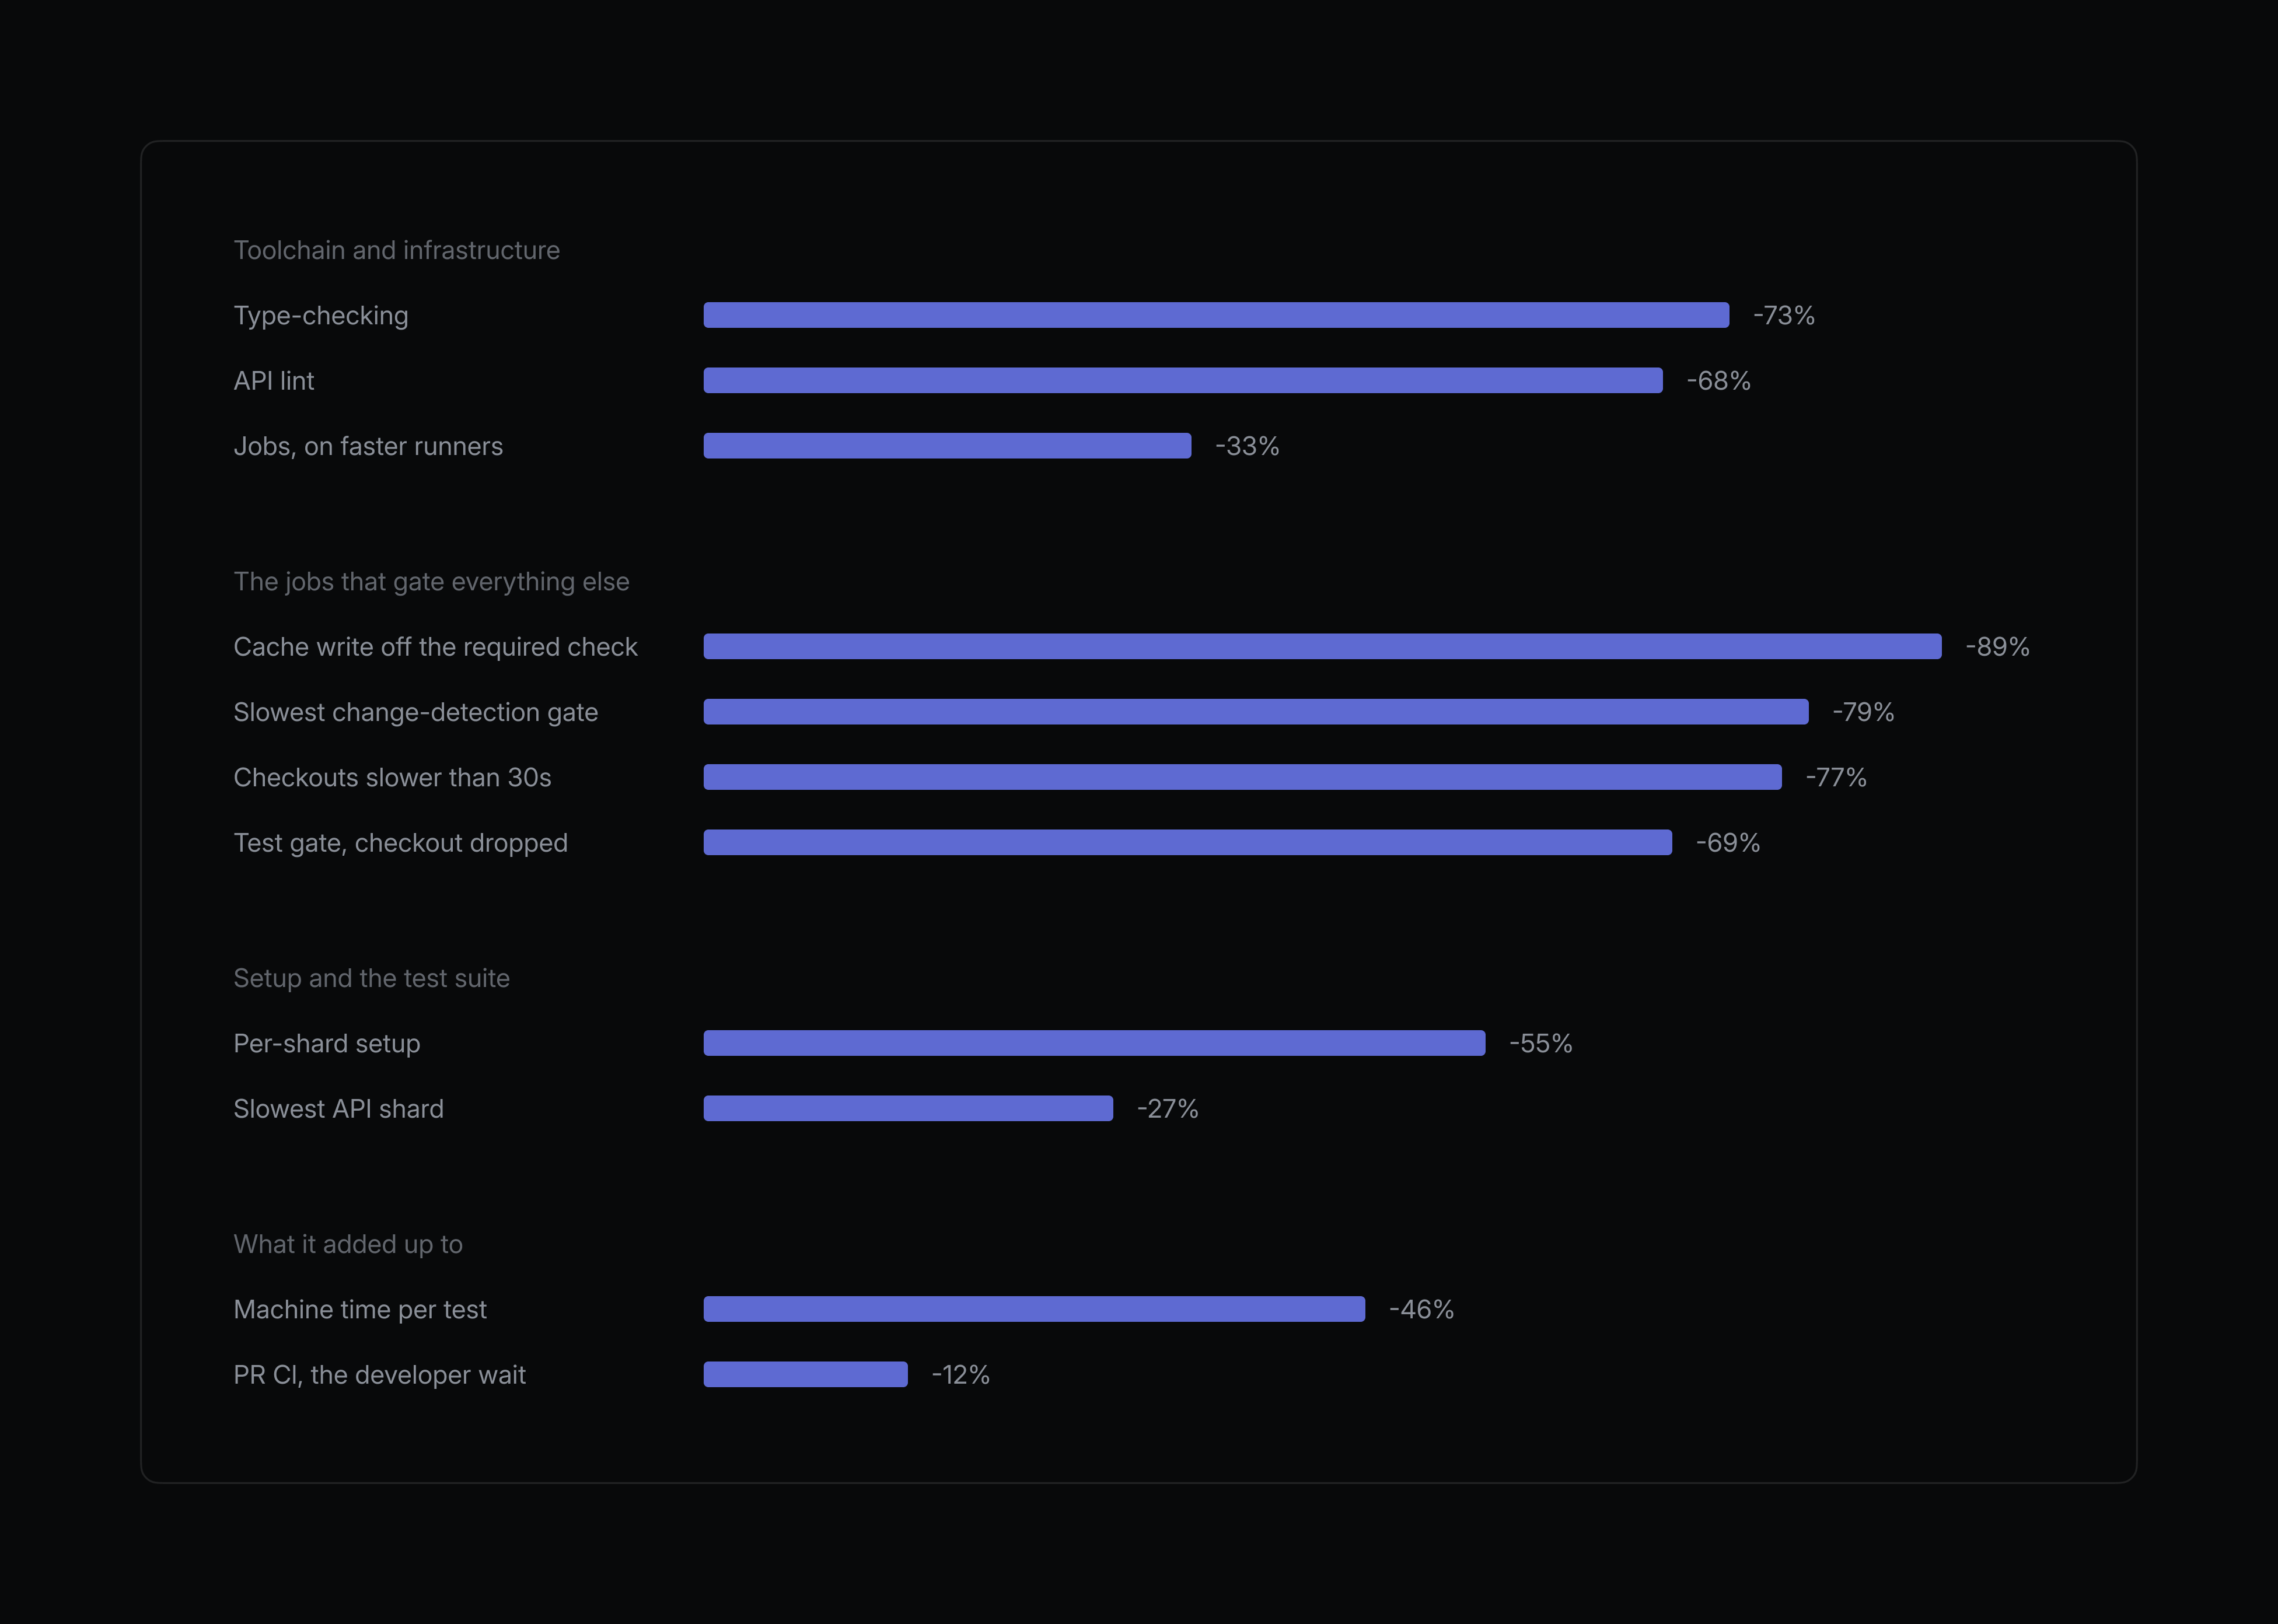
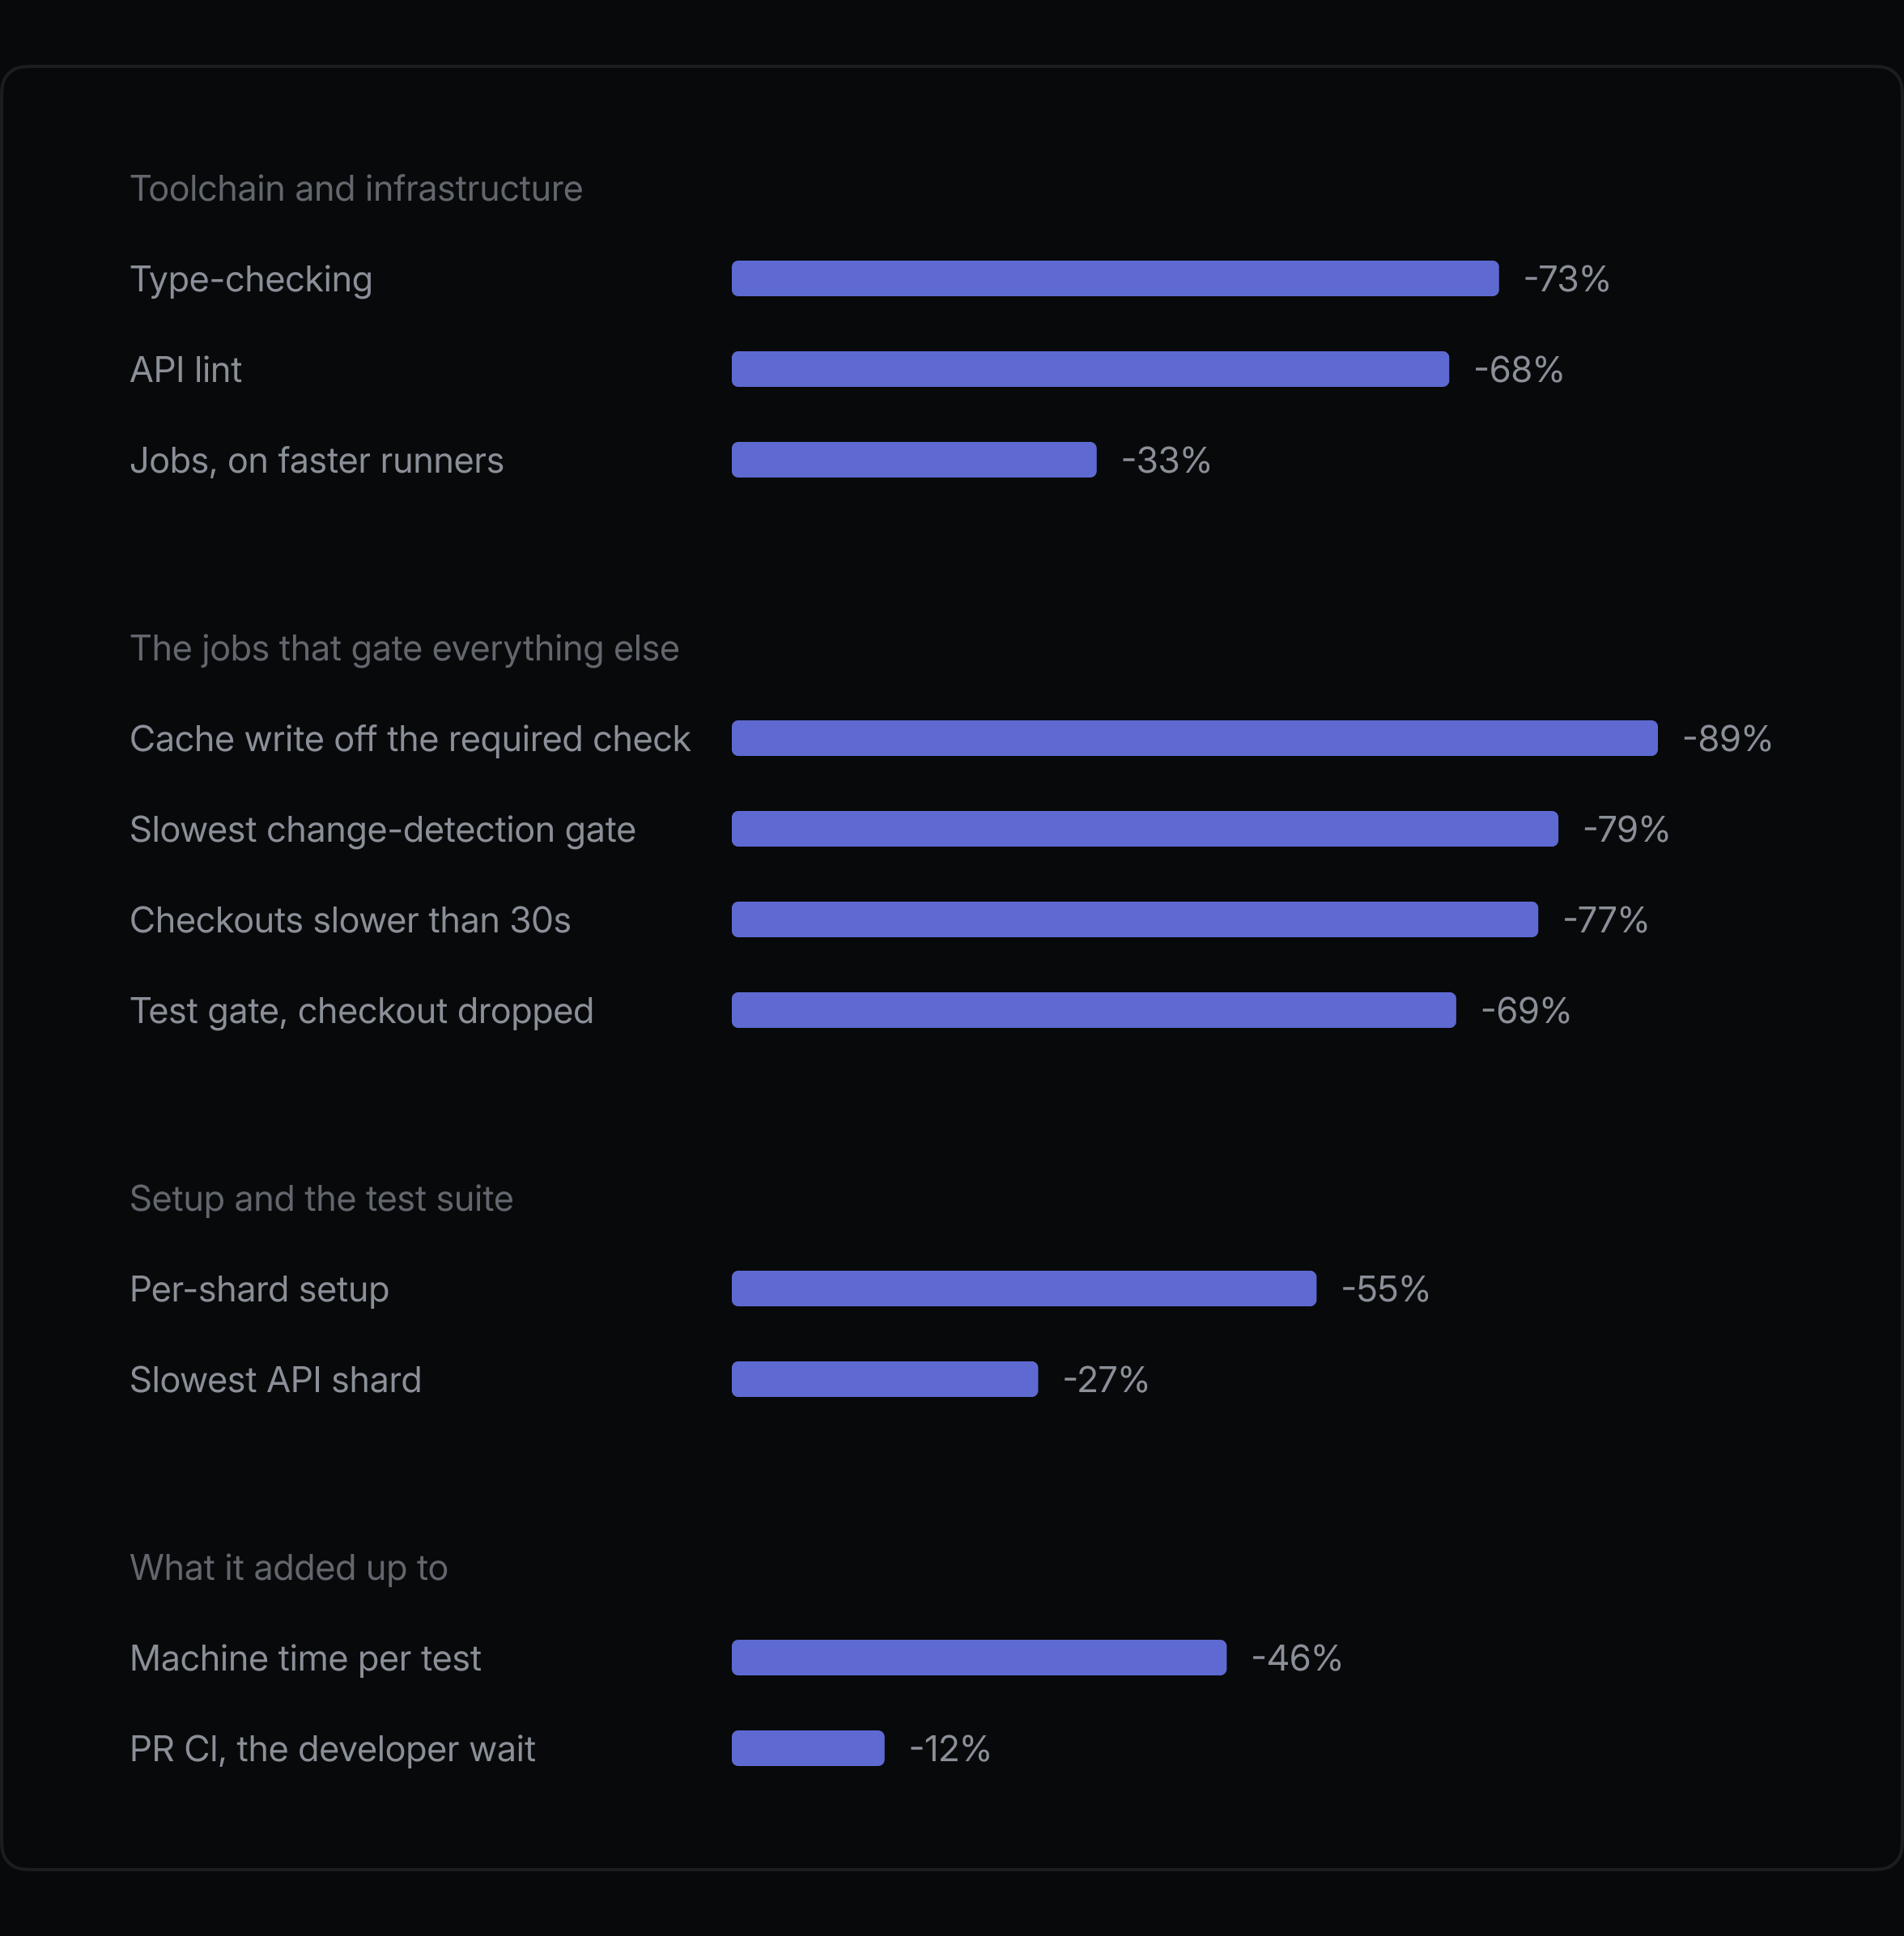
In our pursuit to make CI extra performant at Linear, we optimized for the way lengthy a PR waits on CI and the way a lot runner time it consumes. Despite our check suites virtually quadrupling because the begin of the 12 months, we introduced pull request wait time down from greater than 6 minutes to only over 5, whereas slicing runner time per check roughly in half.
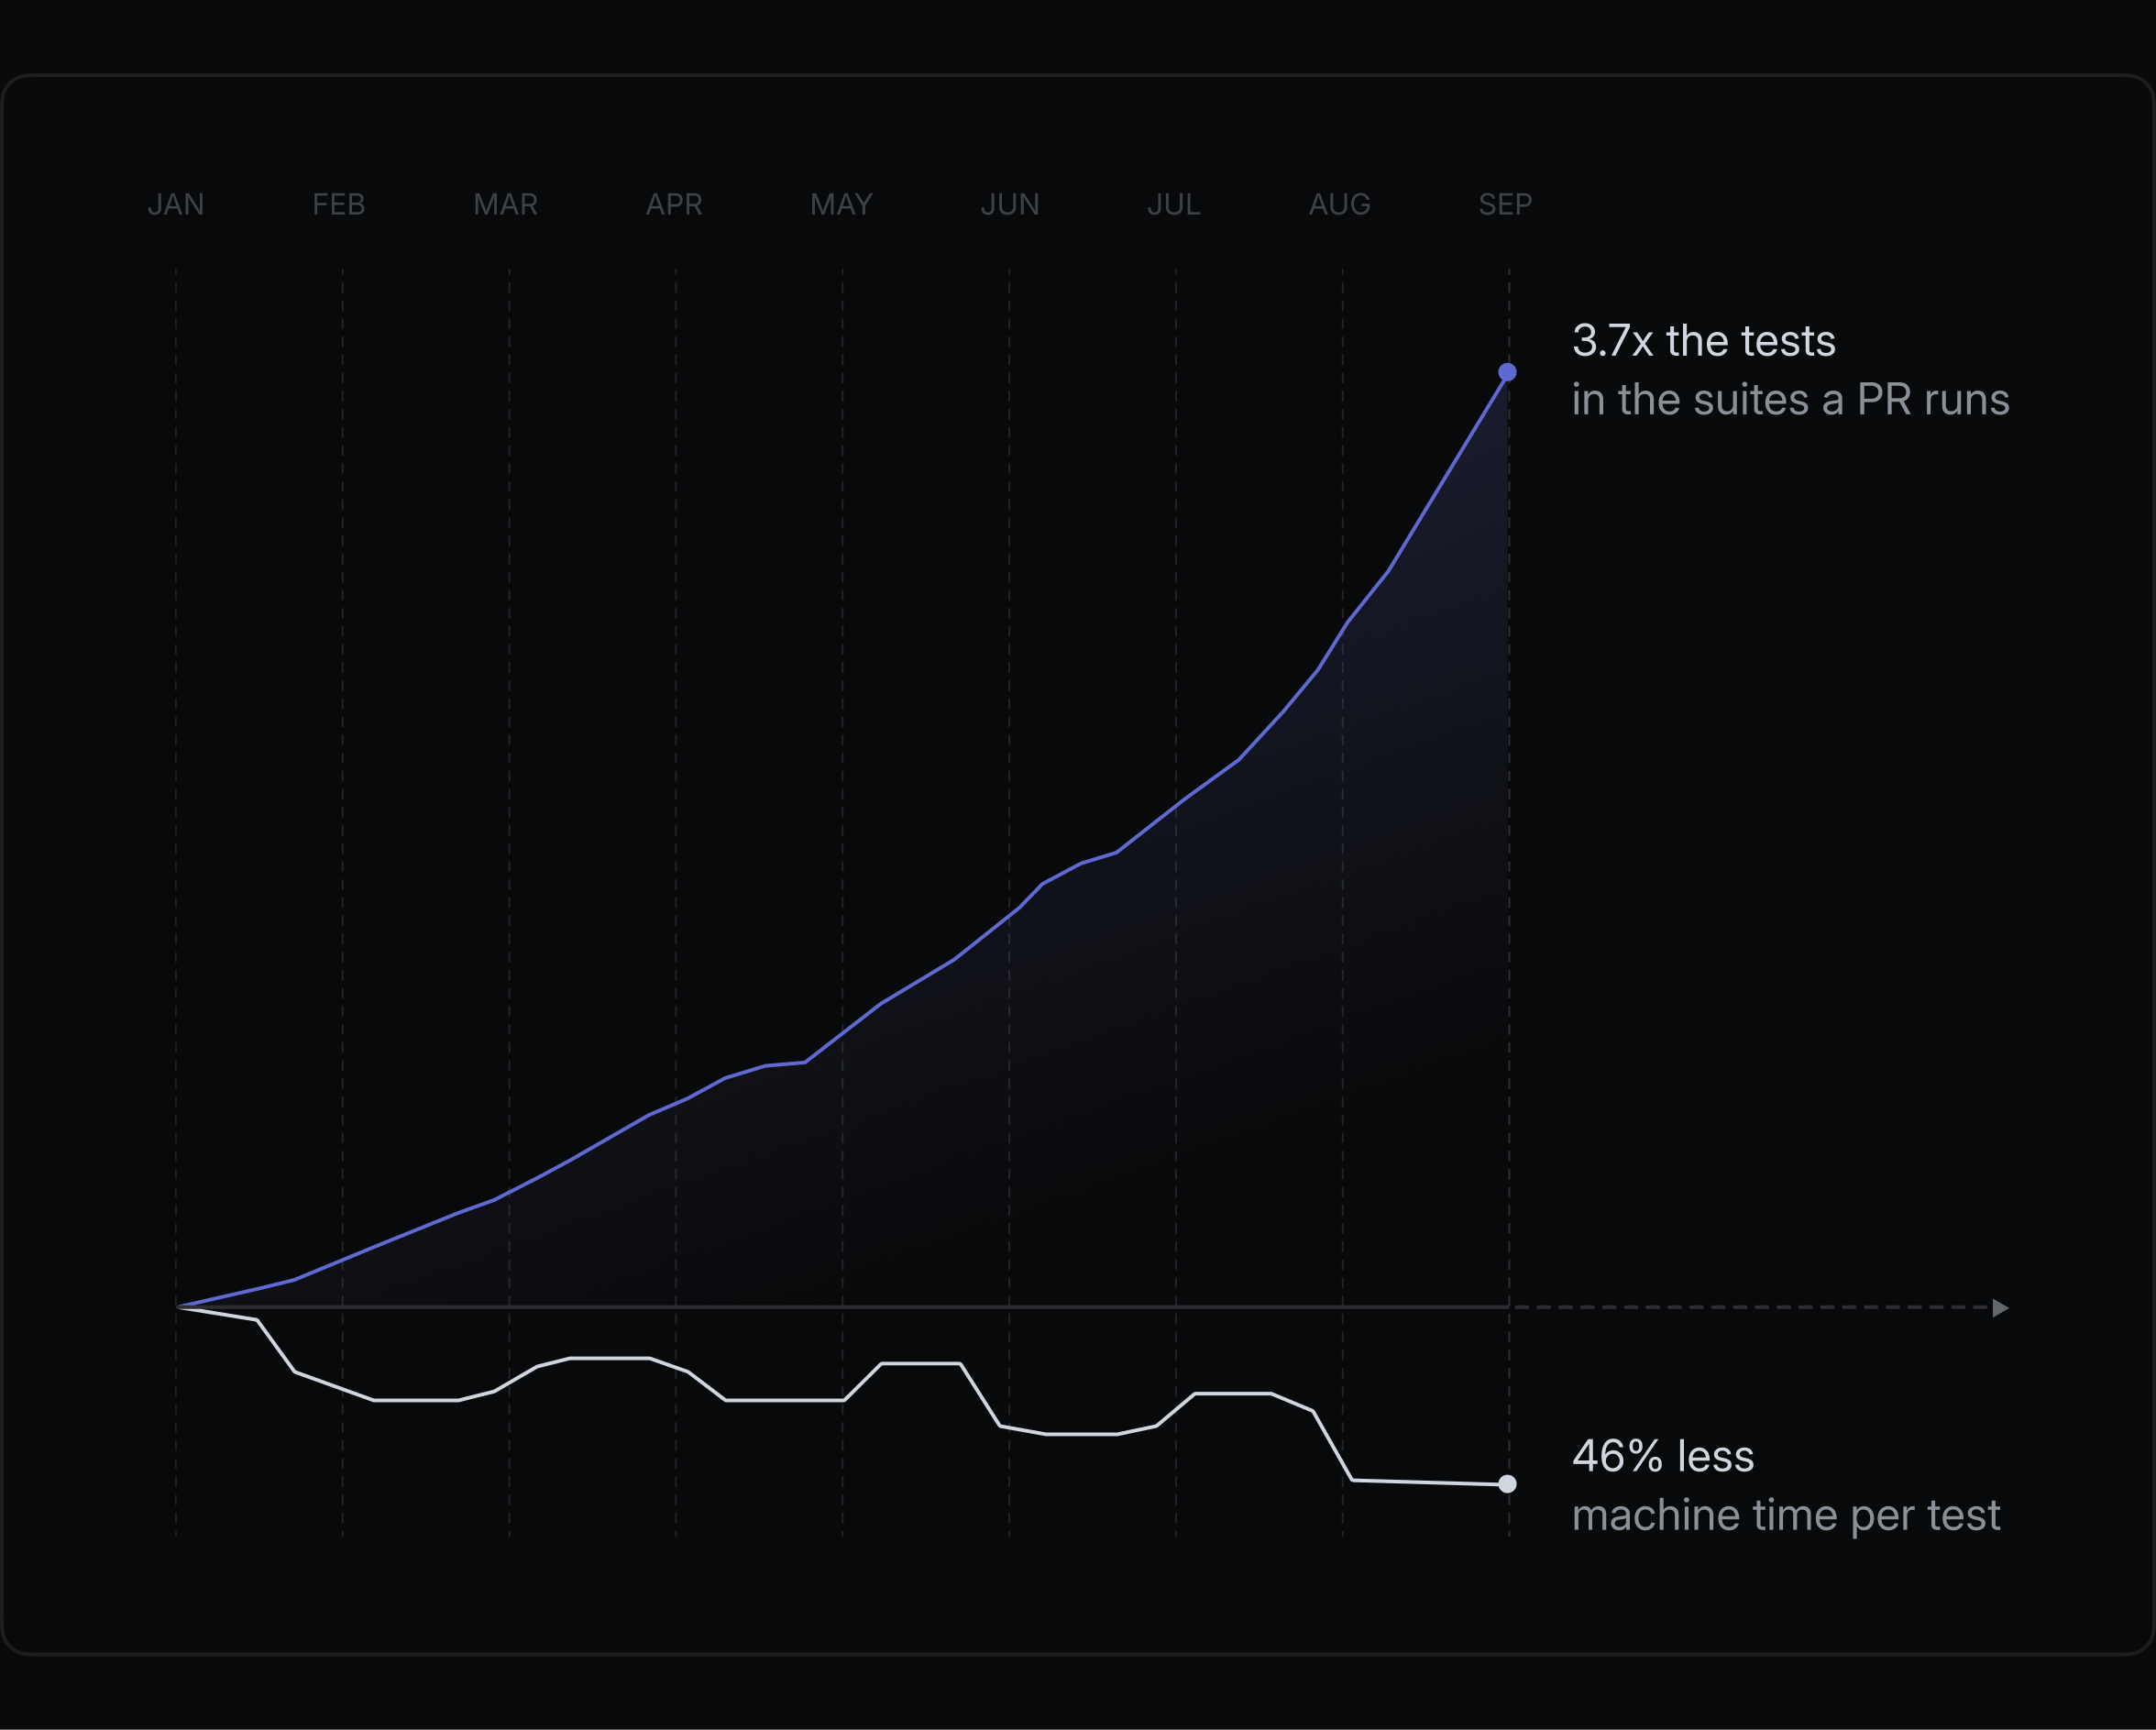
This is check suite efficiency listed to the primary week of January. The white line, monitoring machine time per check, spikes after we added check shards, which shorten the wait and prices extra machine time, and once more throughout checkout stalling points
Broadly, we improved CI in 4 methods:
- Upgraded development projects and tooling
- Optimized the roles that gate different work
- Reduced repeated setup
- Made check execution extra environment friendly
Linear’s codebase is primarily TypeScript, however many of those optimizations apply throughout languages and toolchains.
Upgraded development projects and tooling
Some of our earliest beneficial properties required virtually no optimization of CI itself. Moving our workloads off GitHub Actions to third-party runners with quicker CPUs, higher-performance storage, and higher cache development projects gave us quicker machines to run the identical pipeline on. In a like-for-like comparability of the 2 days both aspect of the change, jobs ran 34% quicker on common, with some workloads like tsc dropping 52%.
Separately, modernizing our toolchain additionally paid off. Switching to tsgo, the native TypeScript compiler, reduce the weekly median of the tsc test by 73%, giant sufficient to maneuver the bottleneck off of typechecking completely.
Lint with out the kind checker
Linting was one other early goal. A handful of our customized lint guidelines trusted TypeScript kind info, both to implement a restriction or apply an autofix. That meant each lint run needed to construct the total kind graph earlier than evaluating these guidelines, making linting certainly one of our most memory-intensive CI jobs.
We rewrote the principles to make use of static evaluation over the summary syntax tree, figuring out function-like constructs and guard patterns with out kind info. That let ESLint drop TypeScript completely, decreasing API lint time by 68%, and full-repository lint time by 55%. Memory utilization dropped considerably as effectively.
Removing the dependency on kind info additionally made our later transfer to Oxlint a lot simpler as a result of guidelines that function purely on syntax are easy to port. Oxlint itself lowered the CI runner-minutes spent on linting.
Optimize the roles that gate different work
With the underlying development projects and particular person checks operating quicker, we zoomed out to take a look at CI as a system. That drew our consideration to the small jobs that sat in entrance of the whole lot else. Every run begins by checking which paths a PR touched and whether or not these exams have already handed for a similar inputs. We gate on these checks on the job degree so skipped work by no means reserves a runner, however that additionally places them instantly on the vital path. None of the eight API check shards can begin till they end, making even small delays disproportionately necessary.
Fetch solely what every job wants
Several of our workflows begin with a change-detection job that decides what runs subsequent; as an illustration, it checks whether or not a diff comprises a database migration and outputs a sign used to schedule the related database CI checks. These jobs had been testing the total working tree although they wanted solely a small subset of it. We capped the fetch depth, which took the slowest of those gates from 94 seconds to twenty, and eliminated checkout completely from the roles that by no means wanted a working tree, decreasing time spent on these from 27 seconds to 7. For commit push and merge-queue occasions, the place we do need to diff paths, we discovered {that a} sparse, blobless checkout with restricted historical past was sufficient, saving one other 11 odd seconds.
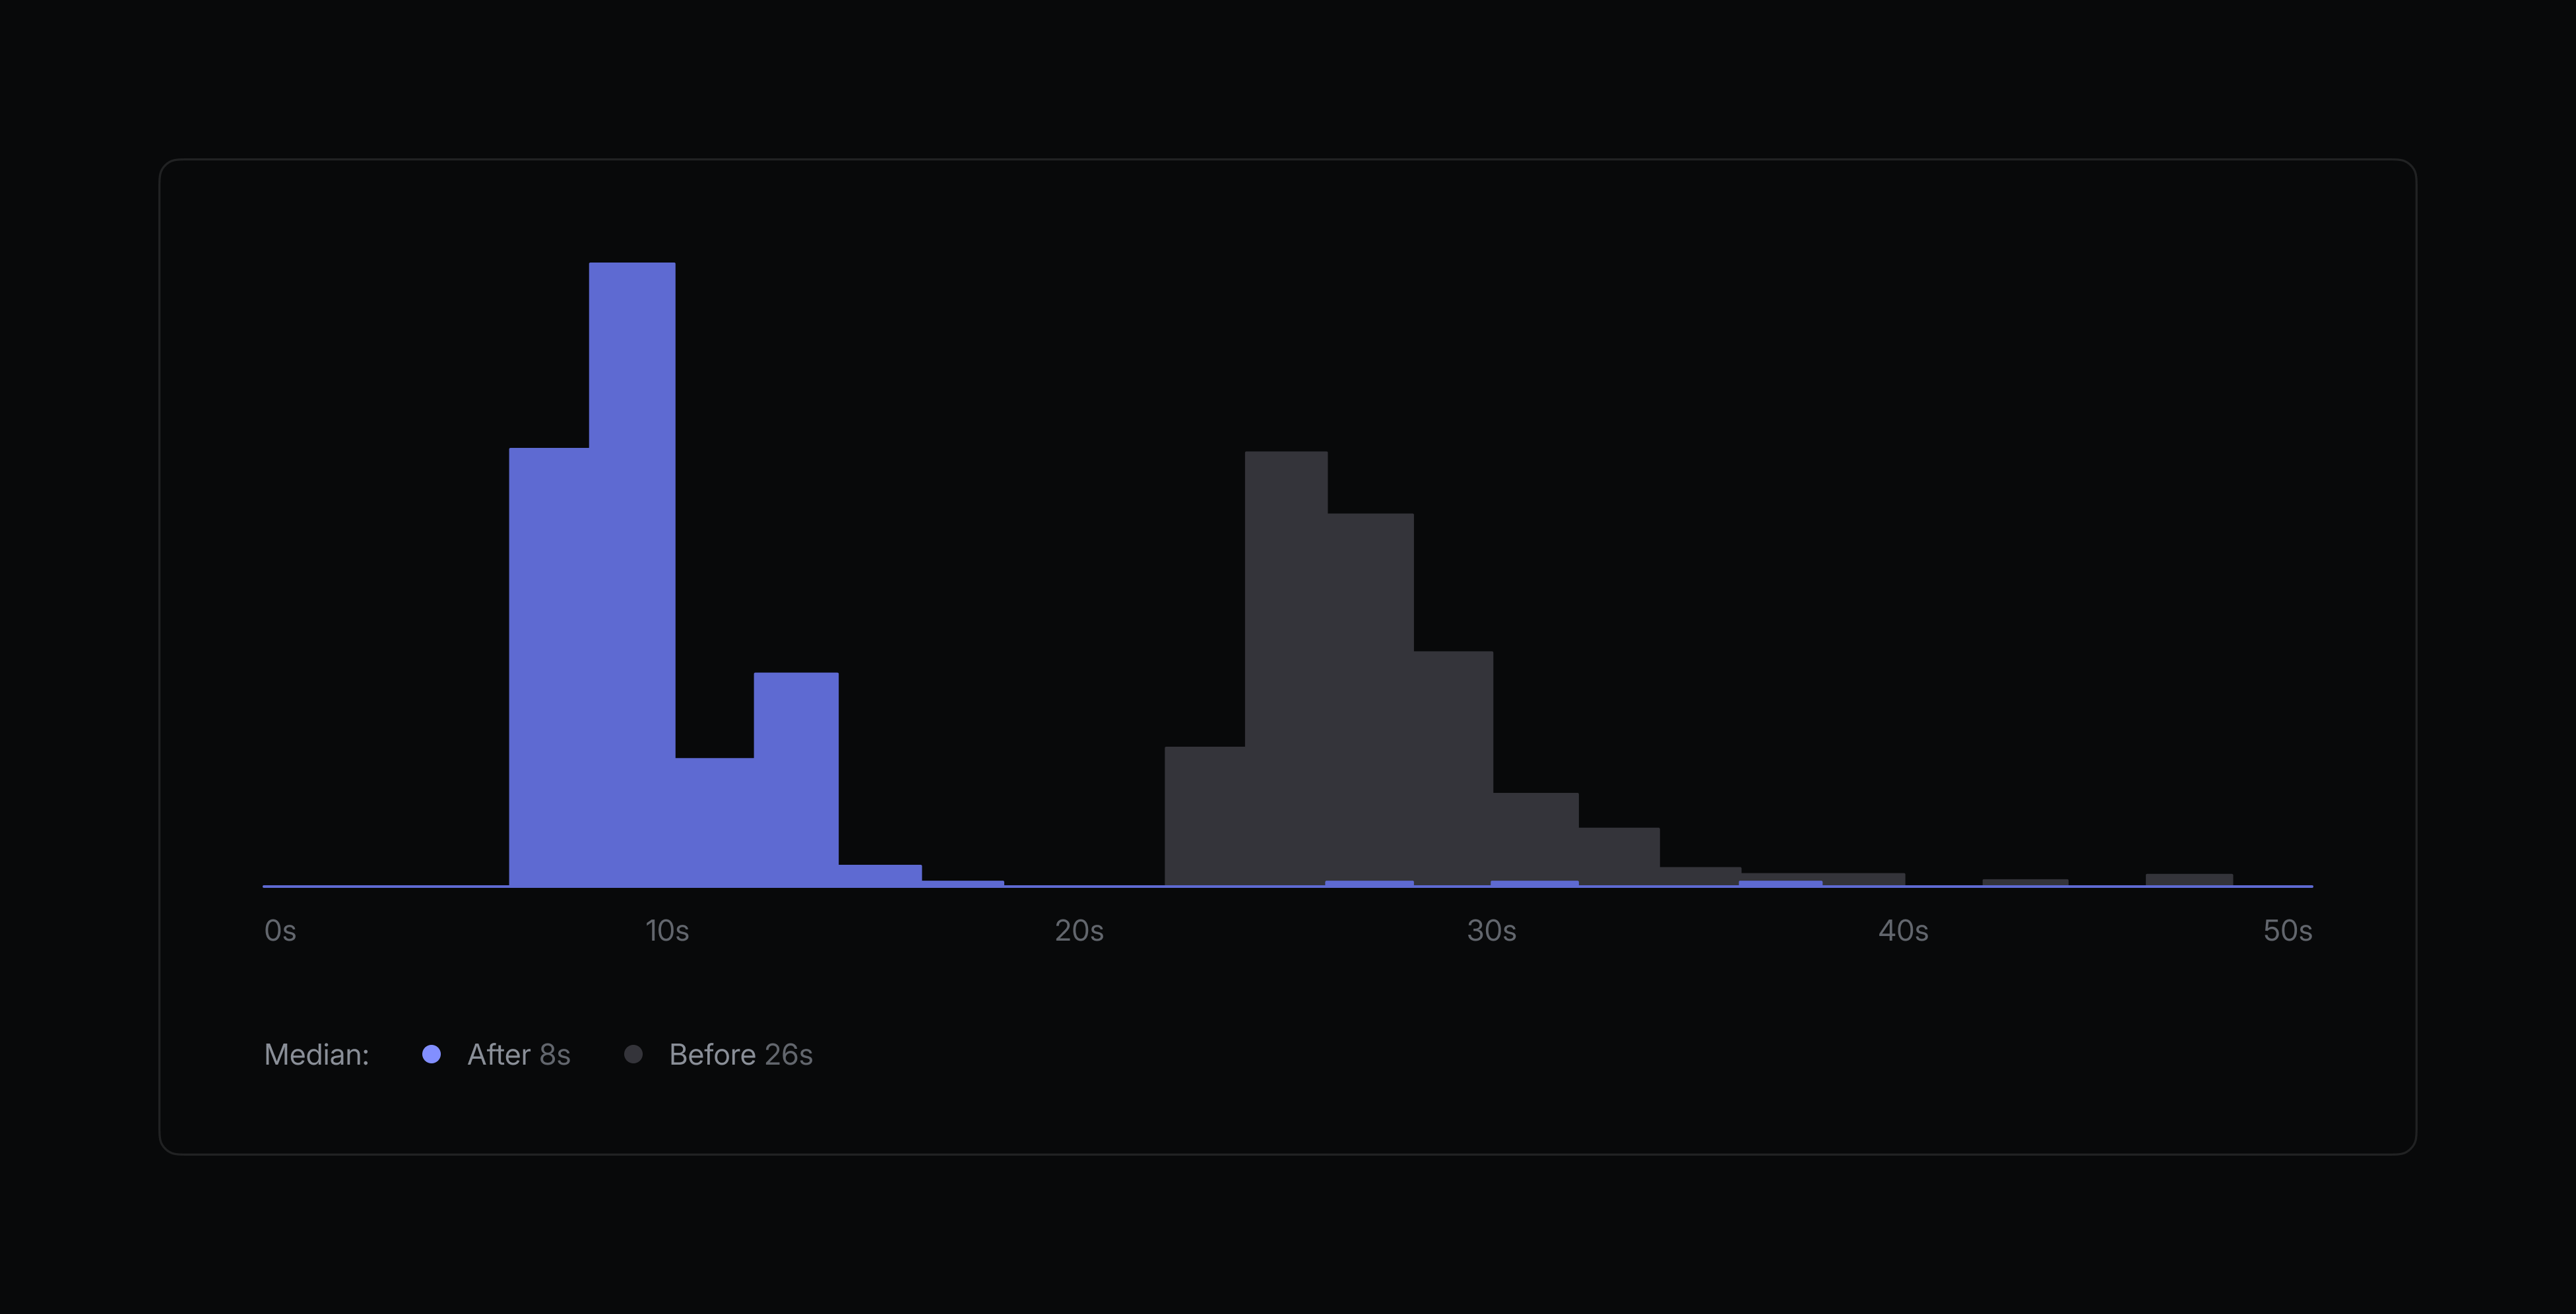
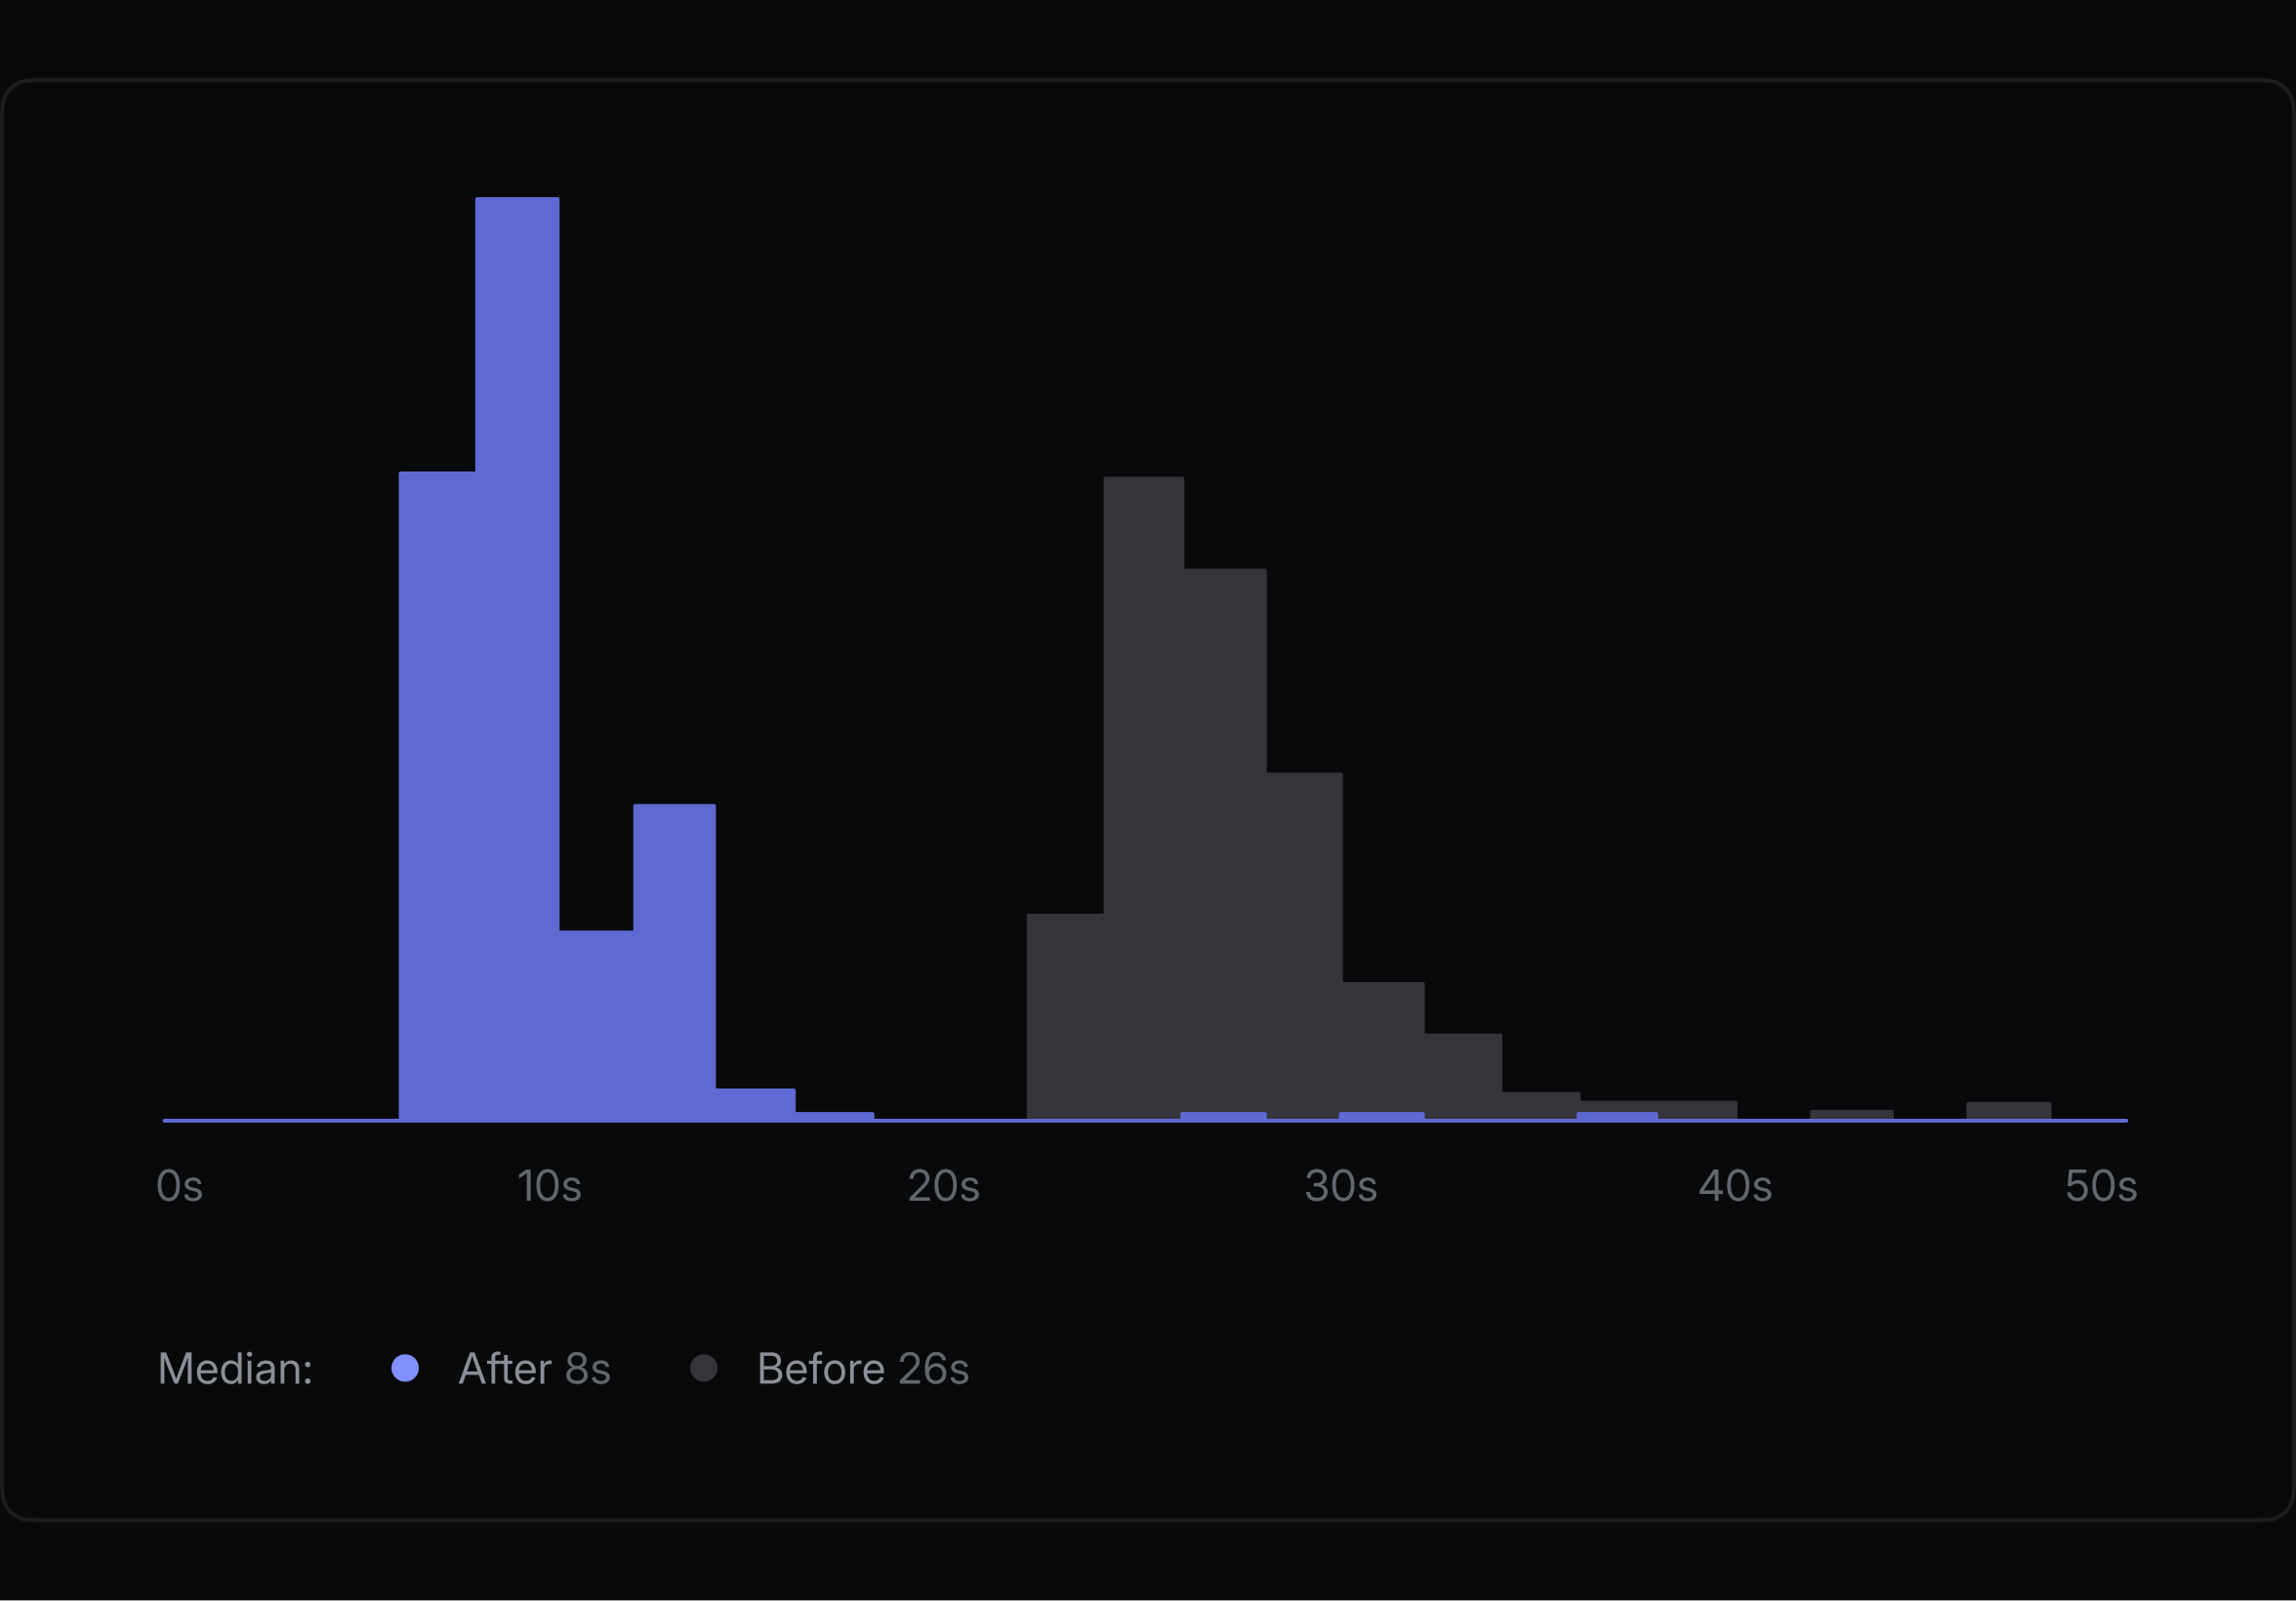
The median length of the change-detection job fell from 26 to eight seconds, p90 from 31 to 12 seconds, and the slowest run from 138 to 37 seconds.
Make checkout extra resilient
After we swapped the underlying runner development projects, we observed that our checkout occasions (with actions/checkout) in our jobs had gotten longer and would generally hold. Because the third-party runners sit exterior GitHub’s community, they depend on a direct IP hyperlink to achieve GitHub. The supplier traced the hangs to intermittent degradation on that hyperlink. Several of our workflows start with a checkout, so a stalled fetch may delay the complete CI run.
To be resilient to the community instability, we changed actions/checkout with a composite motion of our personal that retried with backoff, and units GIT_HTTP_LOW_SPEED_LIMIT and GIT_HTTP_LOW_SPEED_TIME so a stalled connection aborts after about 30 seconds as an alternative of hanging and in addition makes use of the checkout cache, which retains a persistent git mirror on a sticky disk. The end result was far fewer runs the place a critical-path job sat idle ready for checkout to complete.
Minimize what’s on the vital path
Not each job on the vital path wanted to be there. We had been writing cache markers as a part of the ultimate test earlier than merging, which meant a pull request may sit within the merge queue even after its exams had handed. We moved that write right into a job that runs as soon as the check shards end however gates nothing, shaving 42 seconds from the merge path for each API pull request and merge-queue entry.
Together, these modifications took roughly a minute off the required test for API pull requests on cache misses, whereas additionally decreasing runner begins.
Reduce repeated setup
From there, we turned to the setup value repeated throughout each job, like booting a runner, putting in packages, and provisioning construct dependencies. That overhead means a job that does solely seconds of helpful work can find yourself consuming complete minutes of development projects time. Here are just a few steps we took to work round that situation:
Our API check shards every spent 7 to eight seconds putting in the identical Postgres shopper with apt on each run. We moved it right into a small CI base picture containing Node and the shopper, so every shard may begin from an surroundings that was able to run. We later added the required native construct headers to the picture after discovering that downloading them throughout setup may often hold, shortening the tail.
Install solely the dependencies every job wants
Linear’s codebase is a monorepo managed as a pnpm workspace. Our API check workflow was putting in the complete workspace although it solely wanted the API package deal and its dependencies. Restricting the set up to our API package deal reduce pnpm set up from 44-73 seconds to 16-18 seconds. We utilized the identical sample to API-adjacent jobs, which had been every putting in the total repository and importing a dependency cache that later runs virtually by no means hit.
Don’t cache when it’s quicker to rebuild
We additionally examined caching node_modules and located it was quicker to rebuild. The cache key trusted a steadily altering lockfile, and even a cache hit took about 28 seconds to revive, in contrast with roughly 7.5 seconds for a filtered set up. The cache was including save time and variability with out giving us any discernible benefit.
Together, these three modifications lowered per-shard setup time by roughly 44%, from 110-140 seconds to 67-73 seconds.
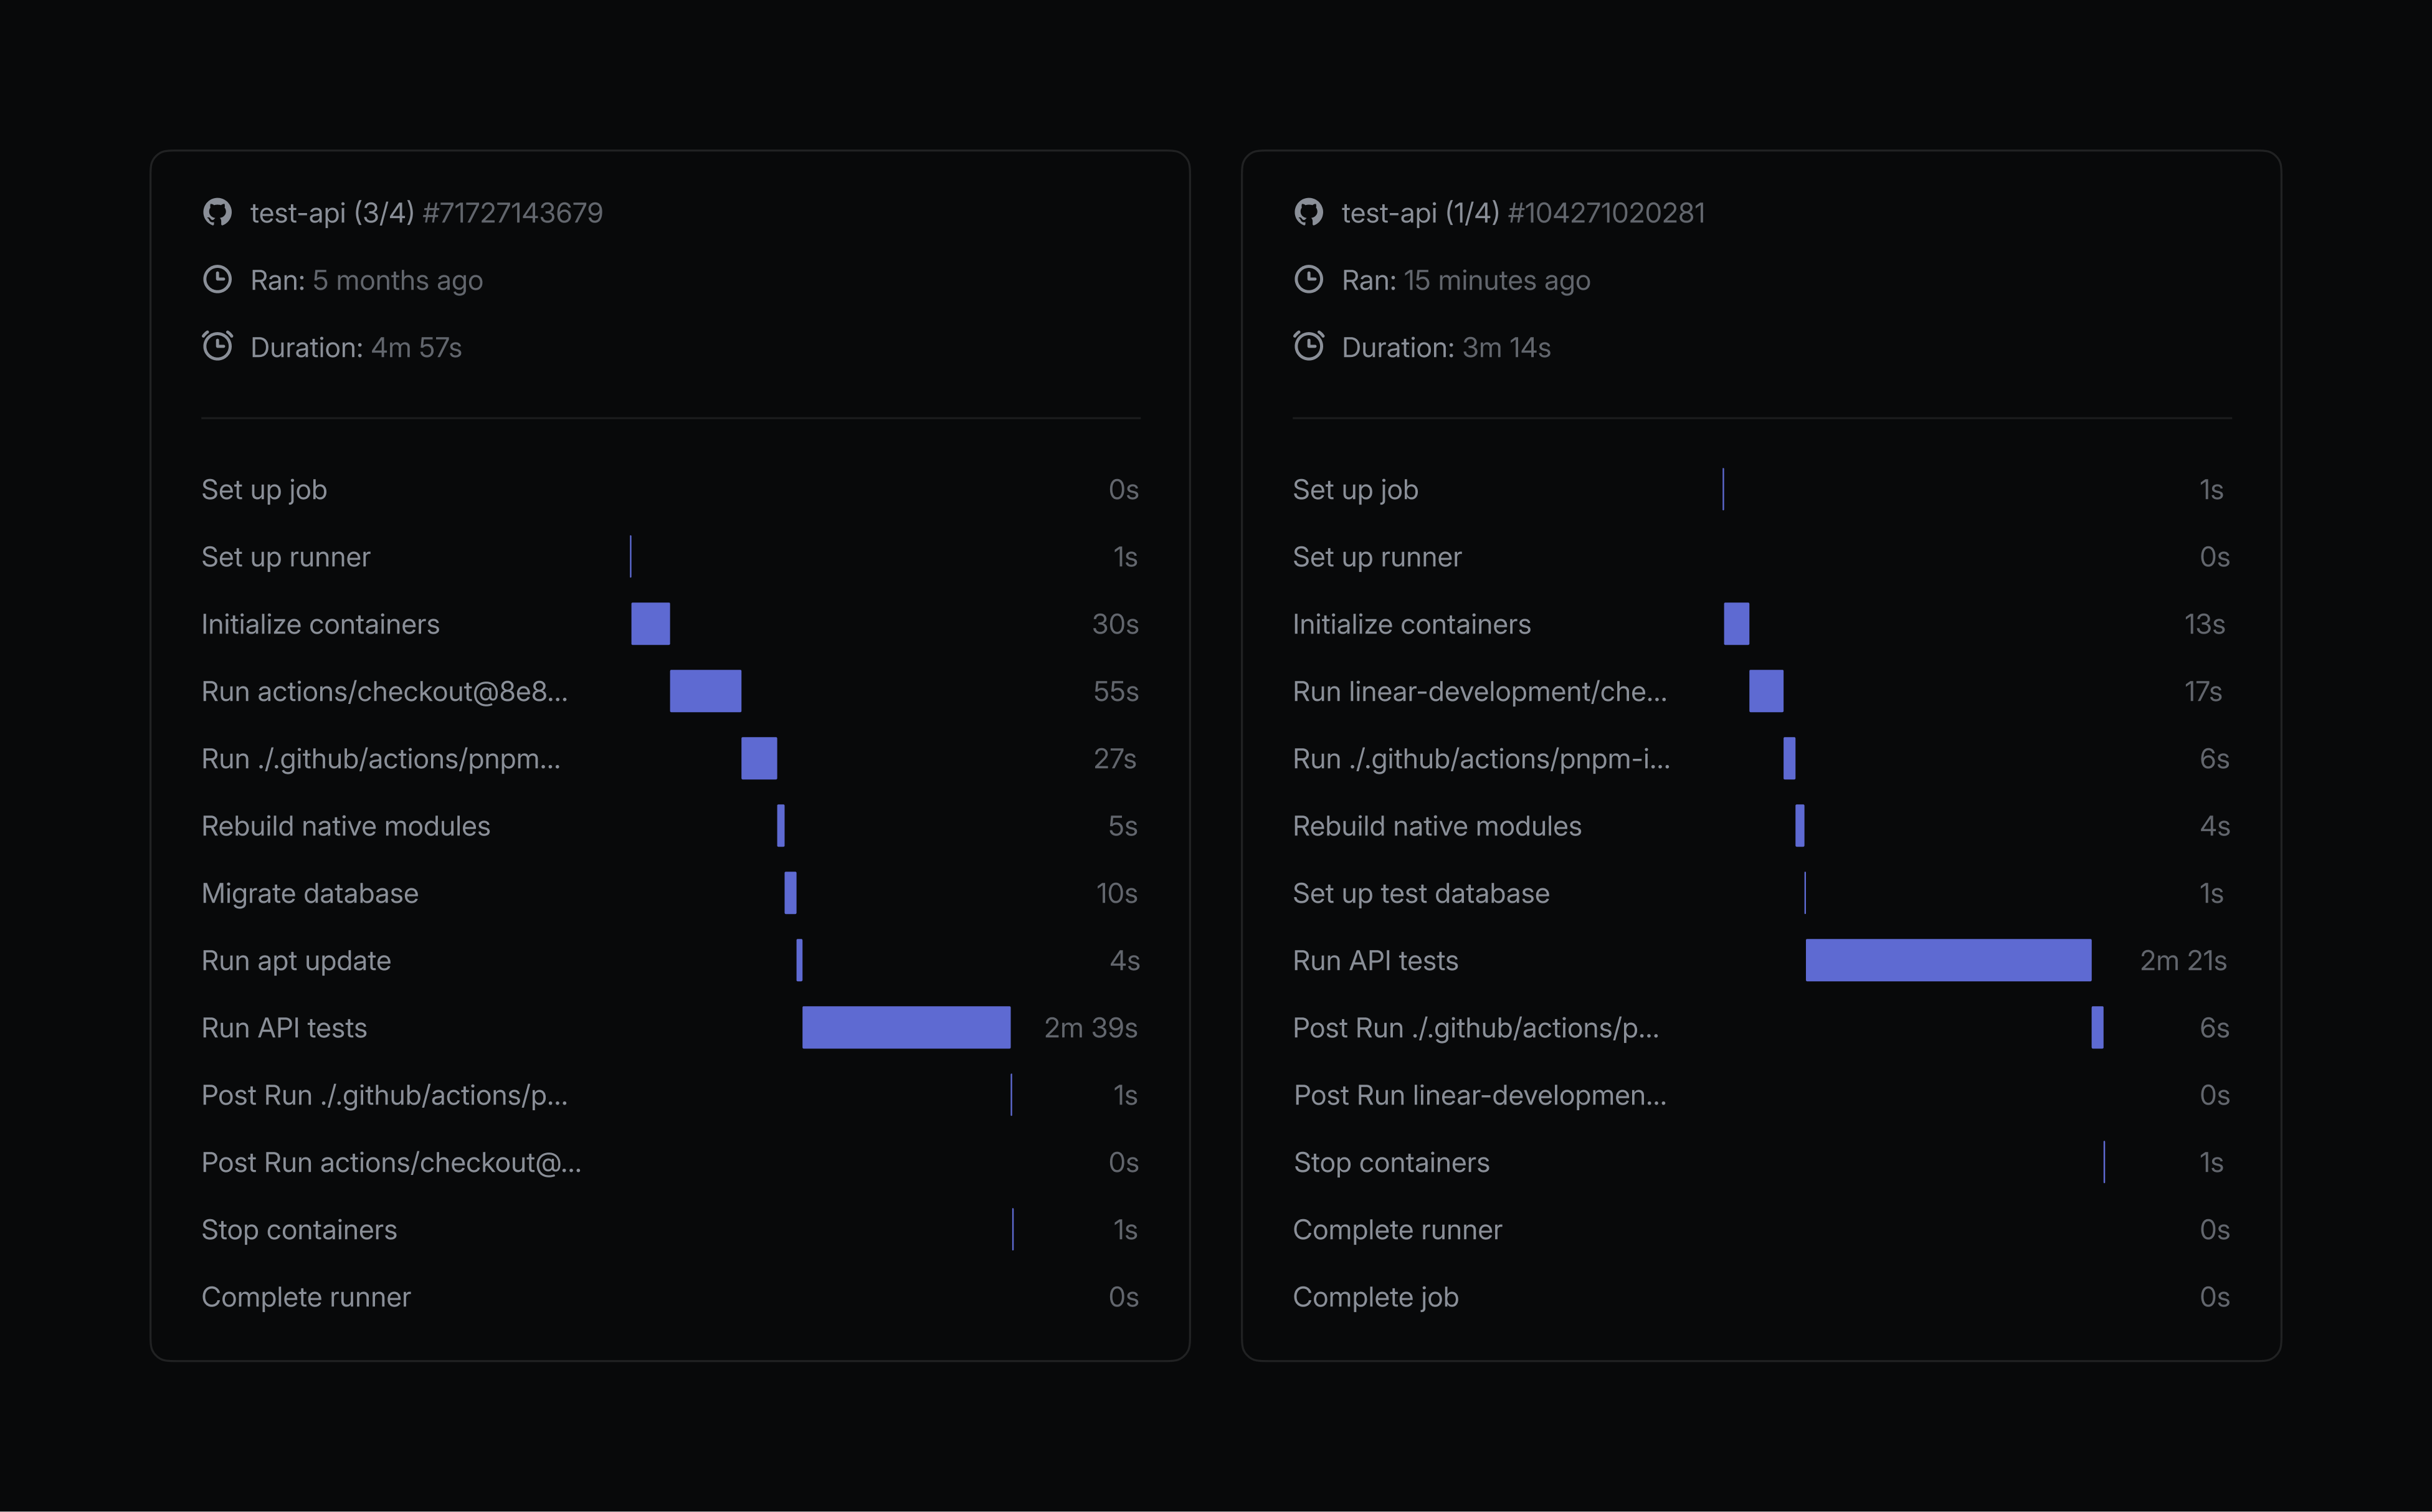
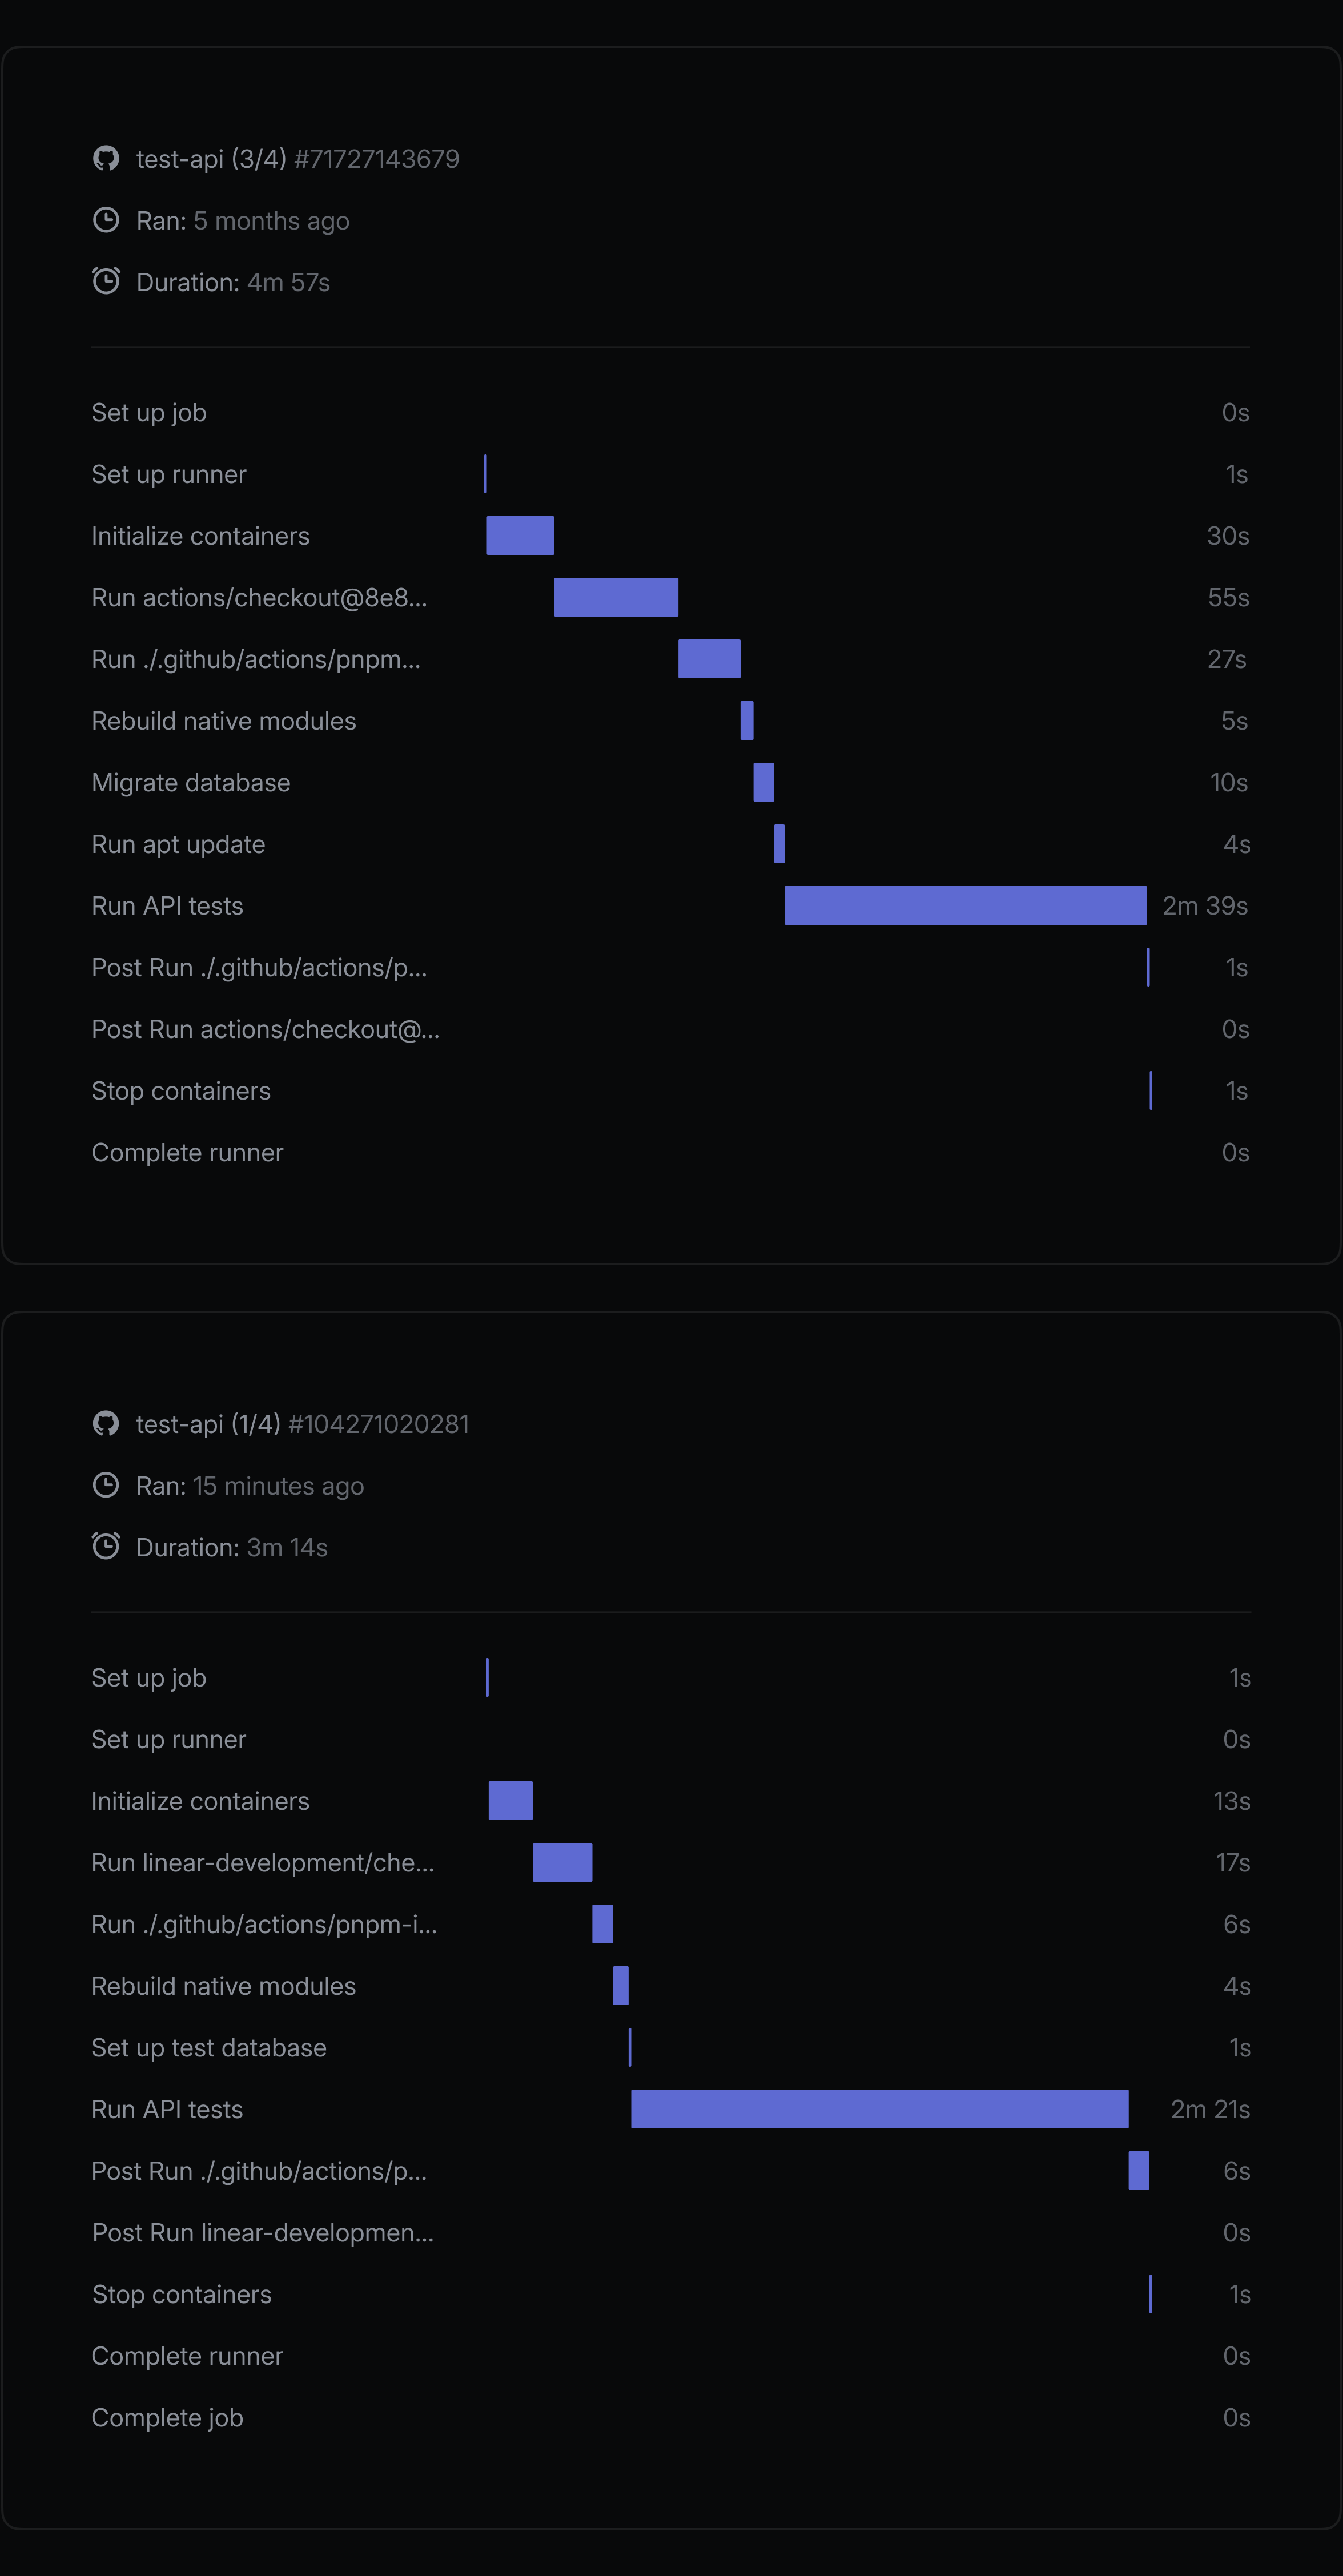
p95 durations of a check shard
Beyond this, there have been different types of repeated setup we may keep away from altogether.
Avoid replaying unchanged setup
Some setup work solely must be repeated when its inputs change. Our API containers, for instance, had been replaying the total database migration historical past on each run, even when a PR hadn’t modified the schema. For these circumstances, we switched to loading a generated schema snapshot and bootstrap file as an alternative, slicing database setup from roughly 12 seconds to 1-2 seconds per container.
Batch quick checks into fewer jobs
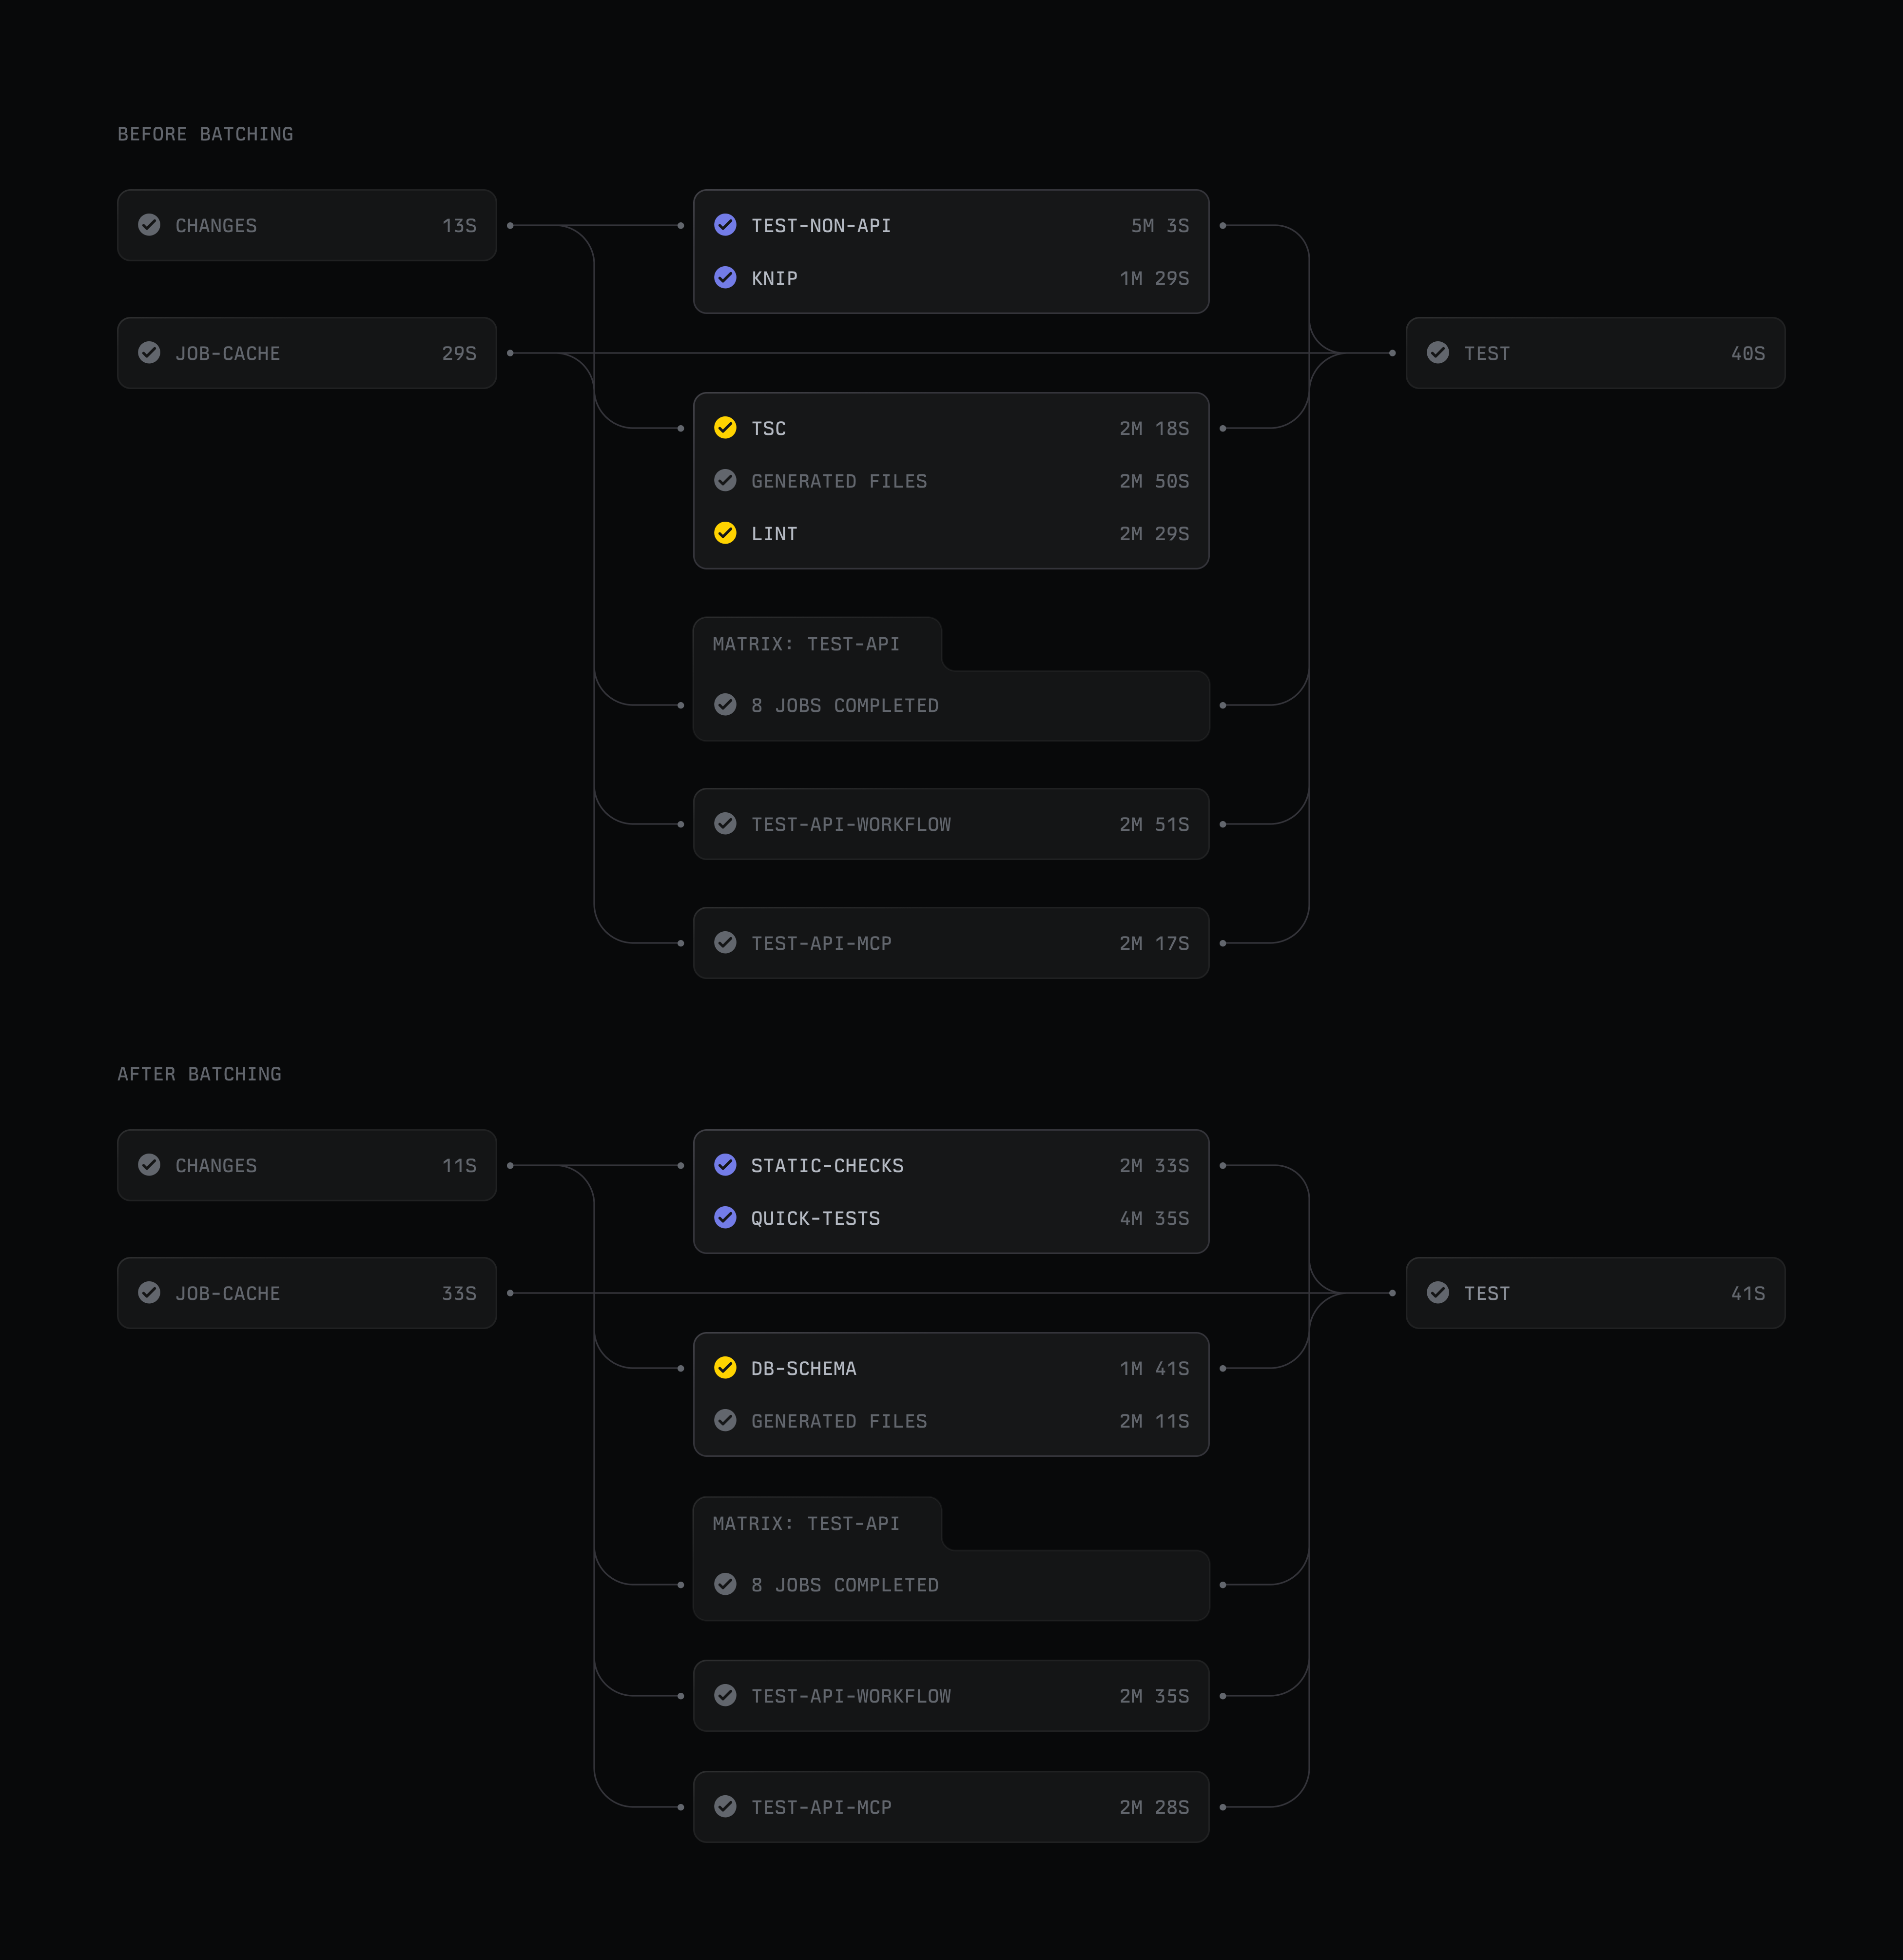
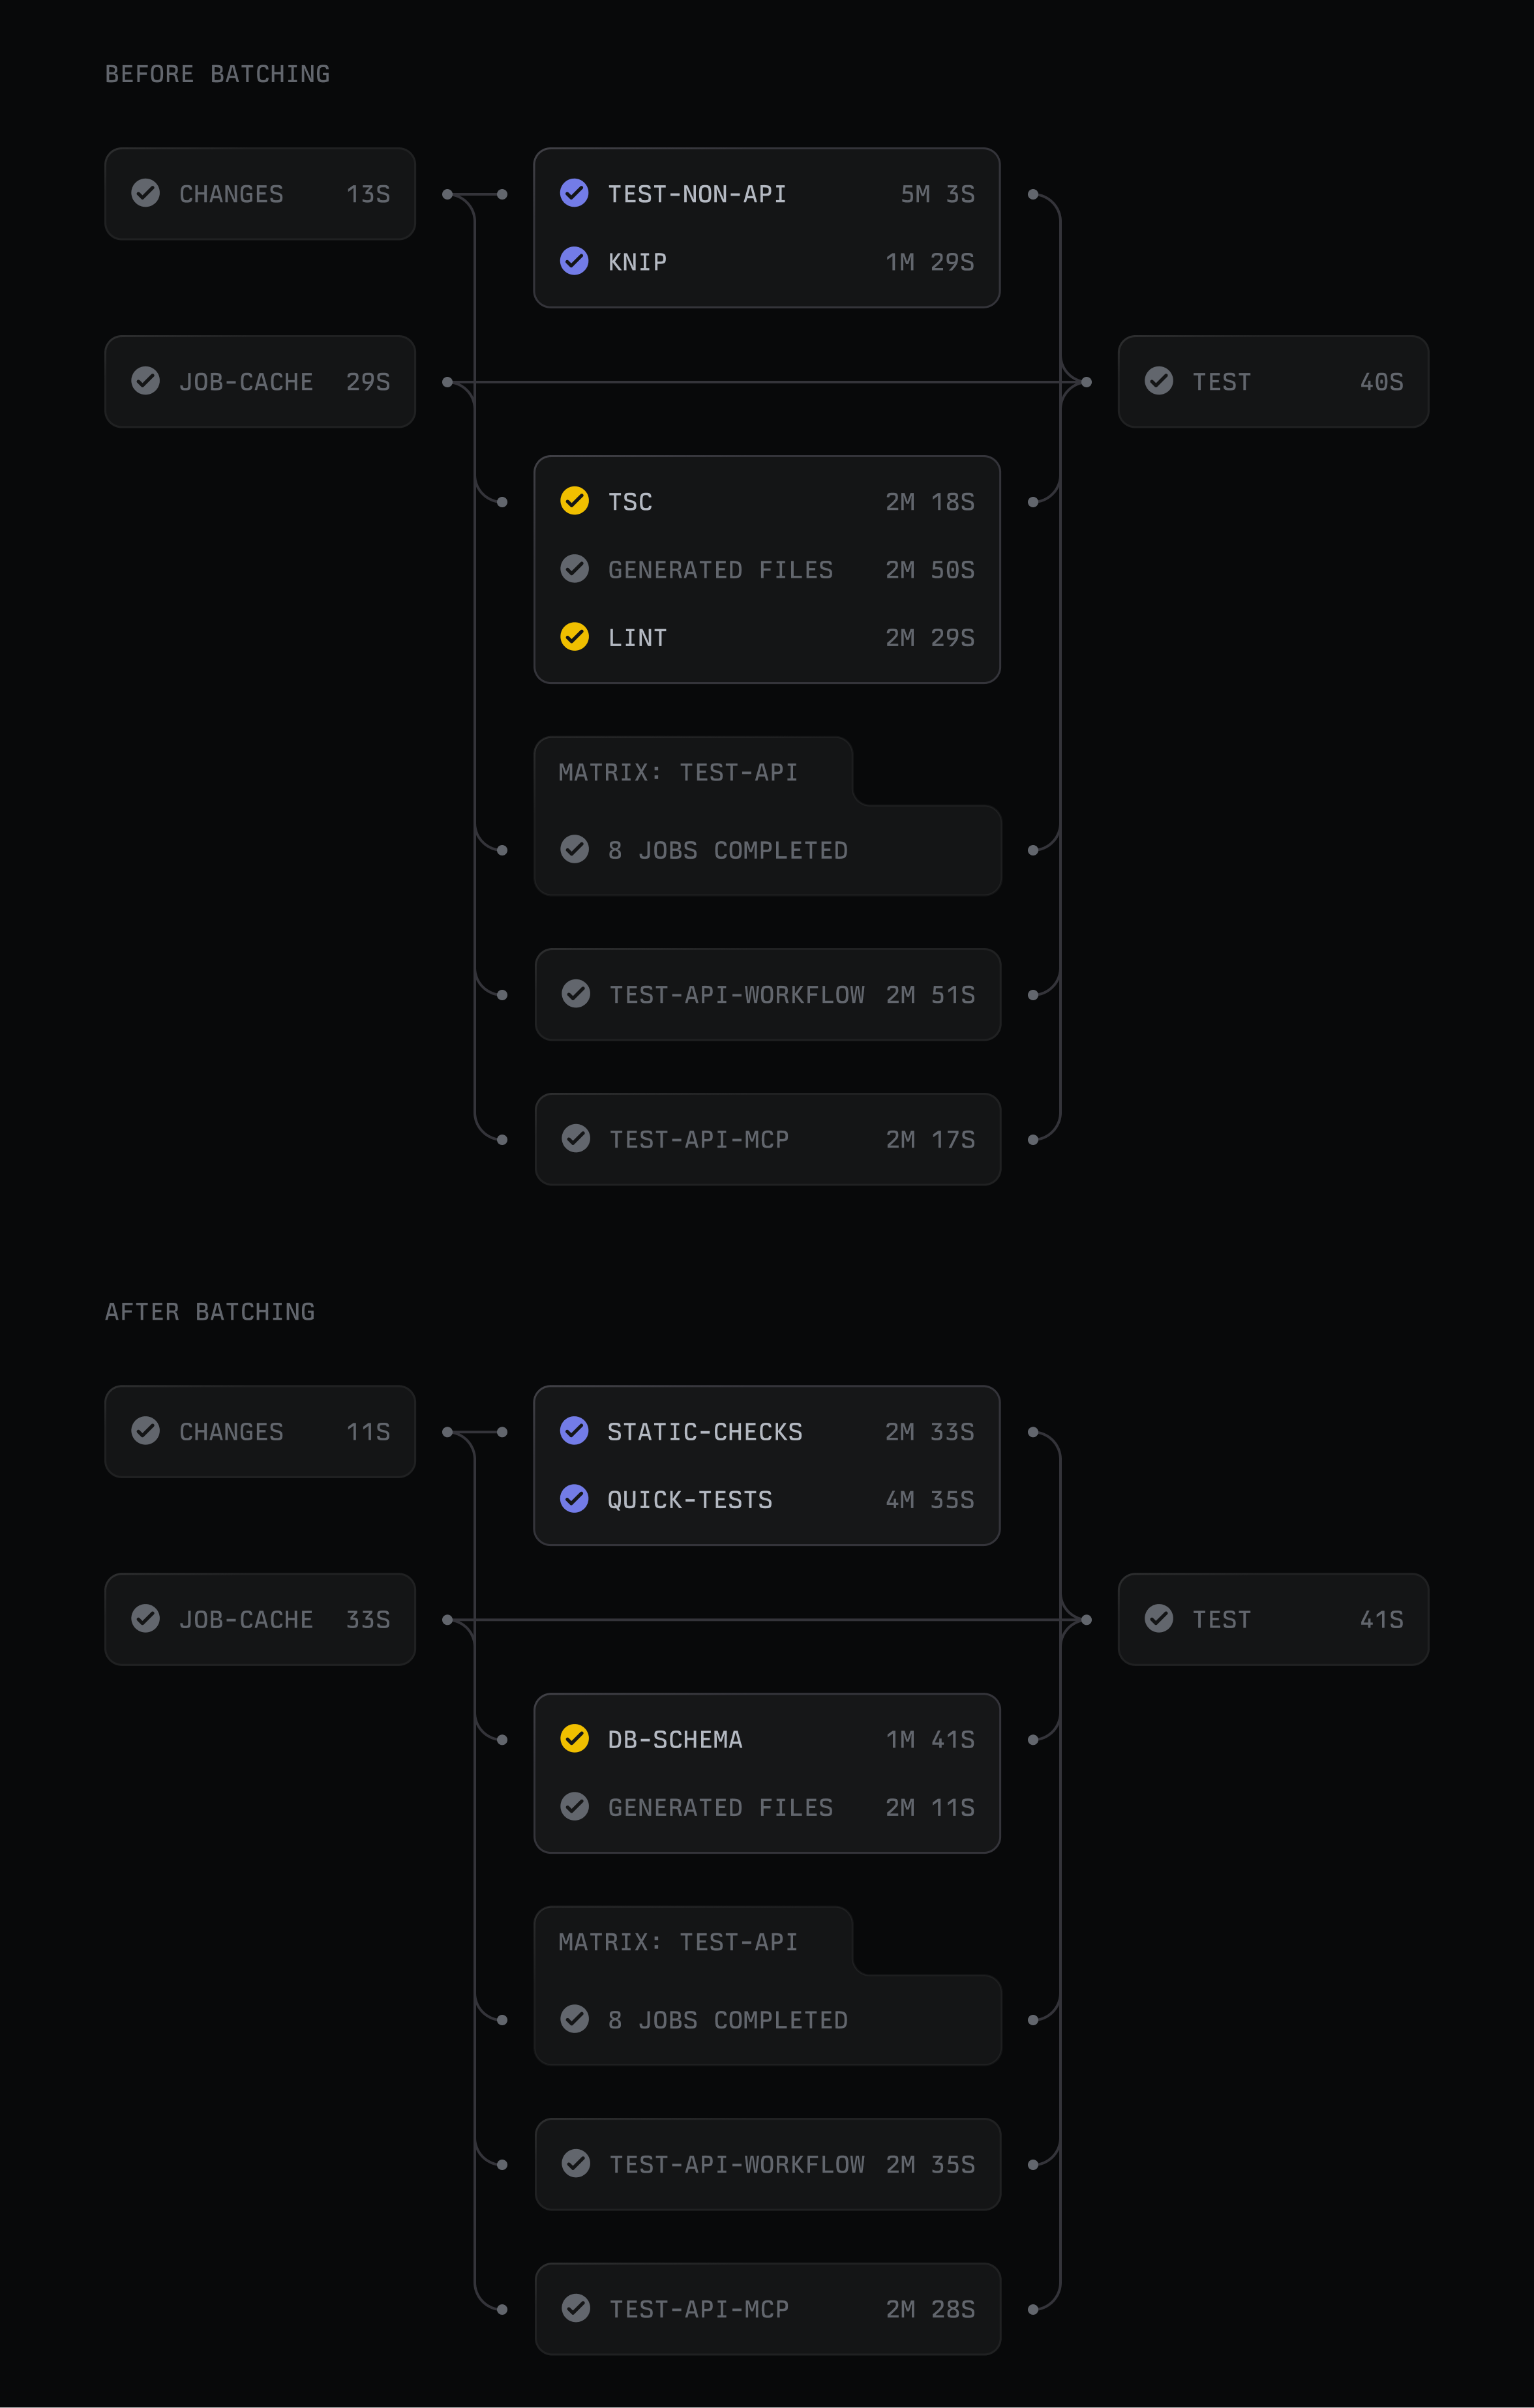
Seven unbiased checks had been every beginning a runner, testing the repository, and putting in dependencies earlier than doing solely seconds of helpful work. We consolidated them into two jobs, after which ran the seven duties concurrently inside them. That lowered the variety of occasions we paid the identical setup overhead from seven to 2. Based on June utilization, the change saved roughly 87,000 runner-minutes per 30 days, equal to 11.8% of our whole CI utilization.
Make check execution extra environment friendly
With the mounted value of every check shard down, we may afford to parallelize the API suite extra aggressively. It was the most important and one of the vital steadily executed elements of our workflow, so enhancements there had an outsized impact on merge time.
Balance work the best way the check runner sees it
Vitest, the check runner we use for our TypeScript check suites, distributes work by file moderately than by the length of particular person exams. That meant just a few unusually giant check recordsdata may dominate a shard and successfully maintain up completion of the complete suite, even when the opposite shards completed a lot earlier.
We break up these giant recordsdata into smaller, extra centered recordsdata whereas preserving the construction of the exams, then evaluated totally different shard and runner configurations. We had already gone from three to 4 shards earlier within the 12 months; transferring to eight made the vital job roughly 19% quicker and 19% cheaper in our preliminary benchmark. Every week after the change, the slowest shard dropped from 5.25 minutes to 4.33 minutes.
Vitest usually isolates each check file, which for us meant rebuilding the entity, GraphQL, and decorator graph in every check shard. We launched an opt-in vitest undertaking with isolate: false, permitting protected recordsdata to share a module registry inside every employee.
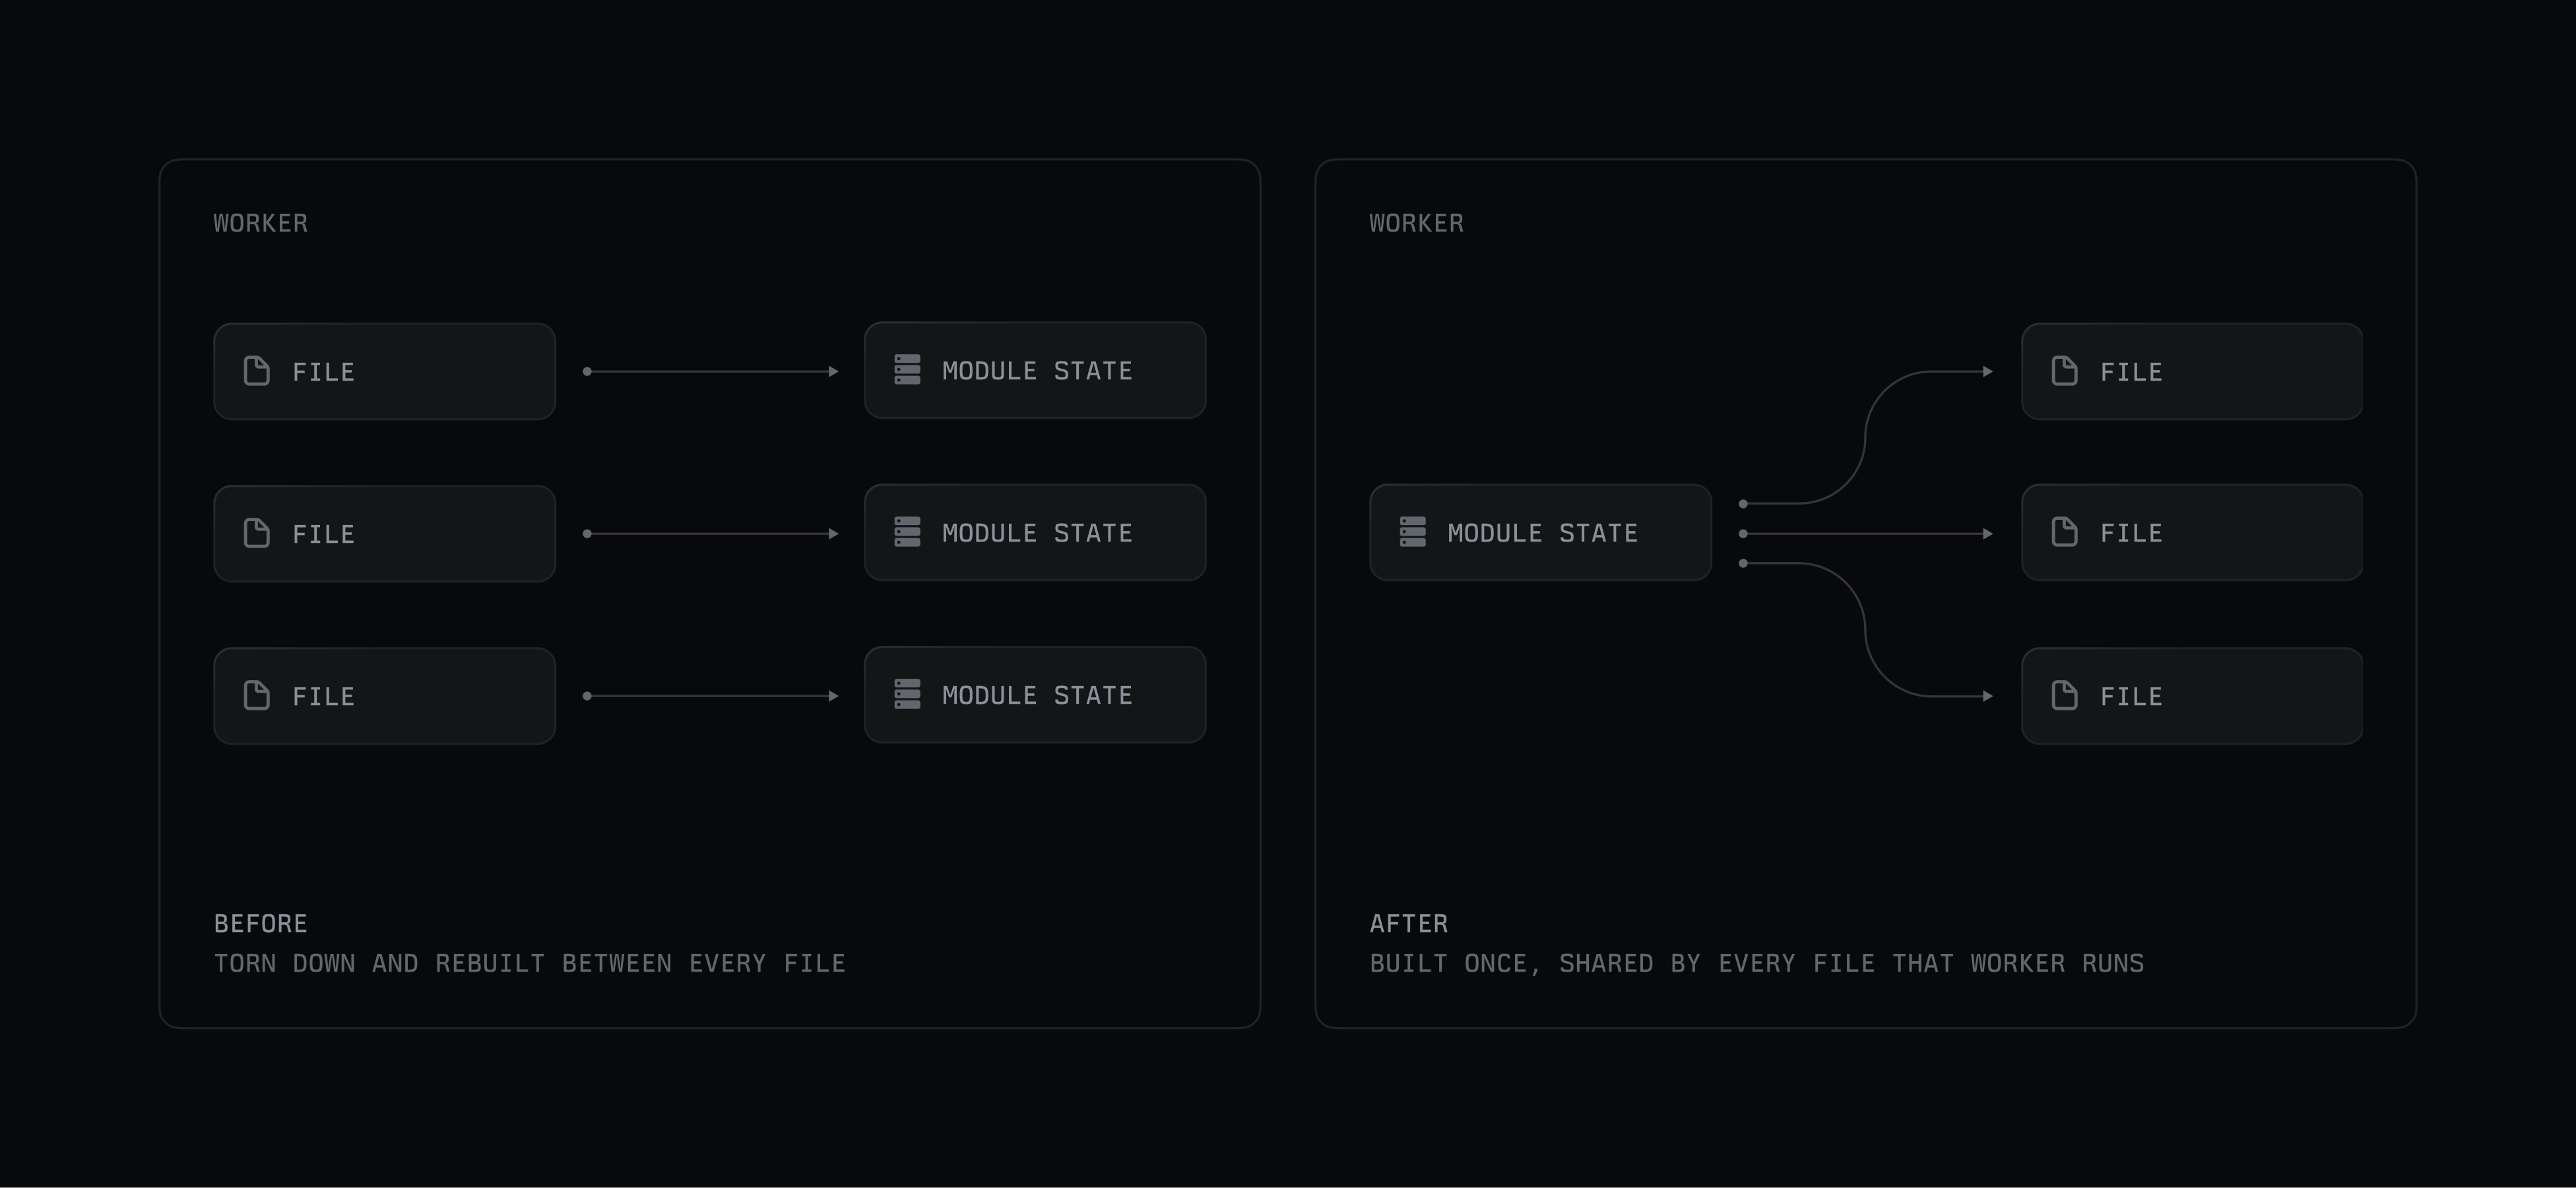
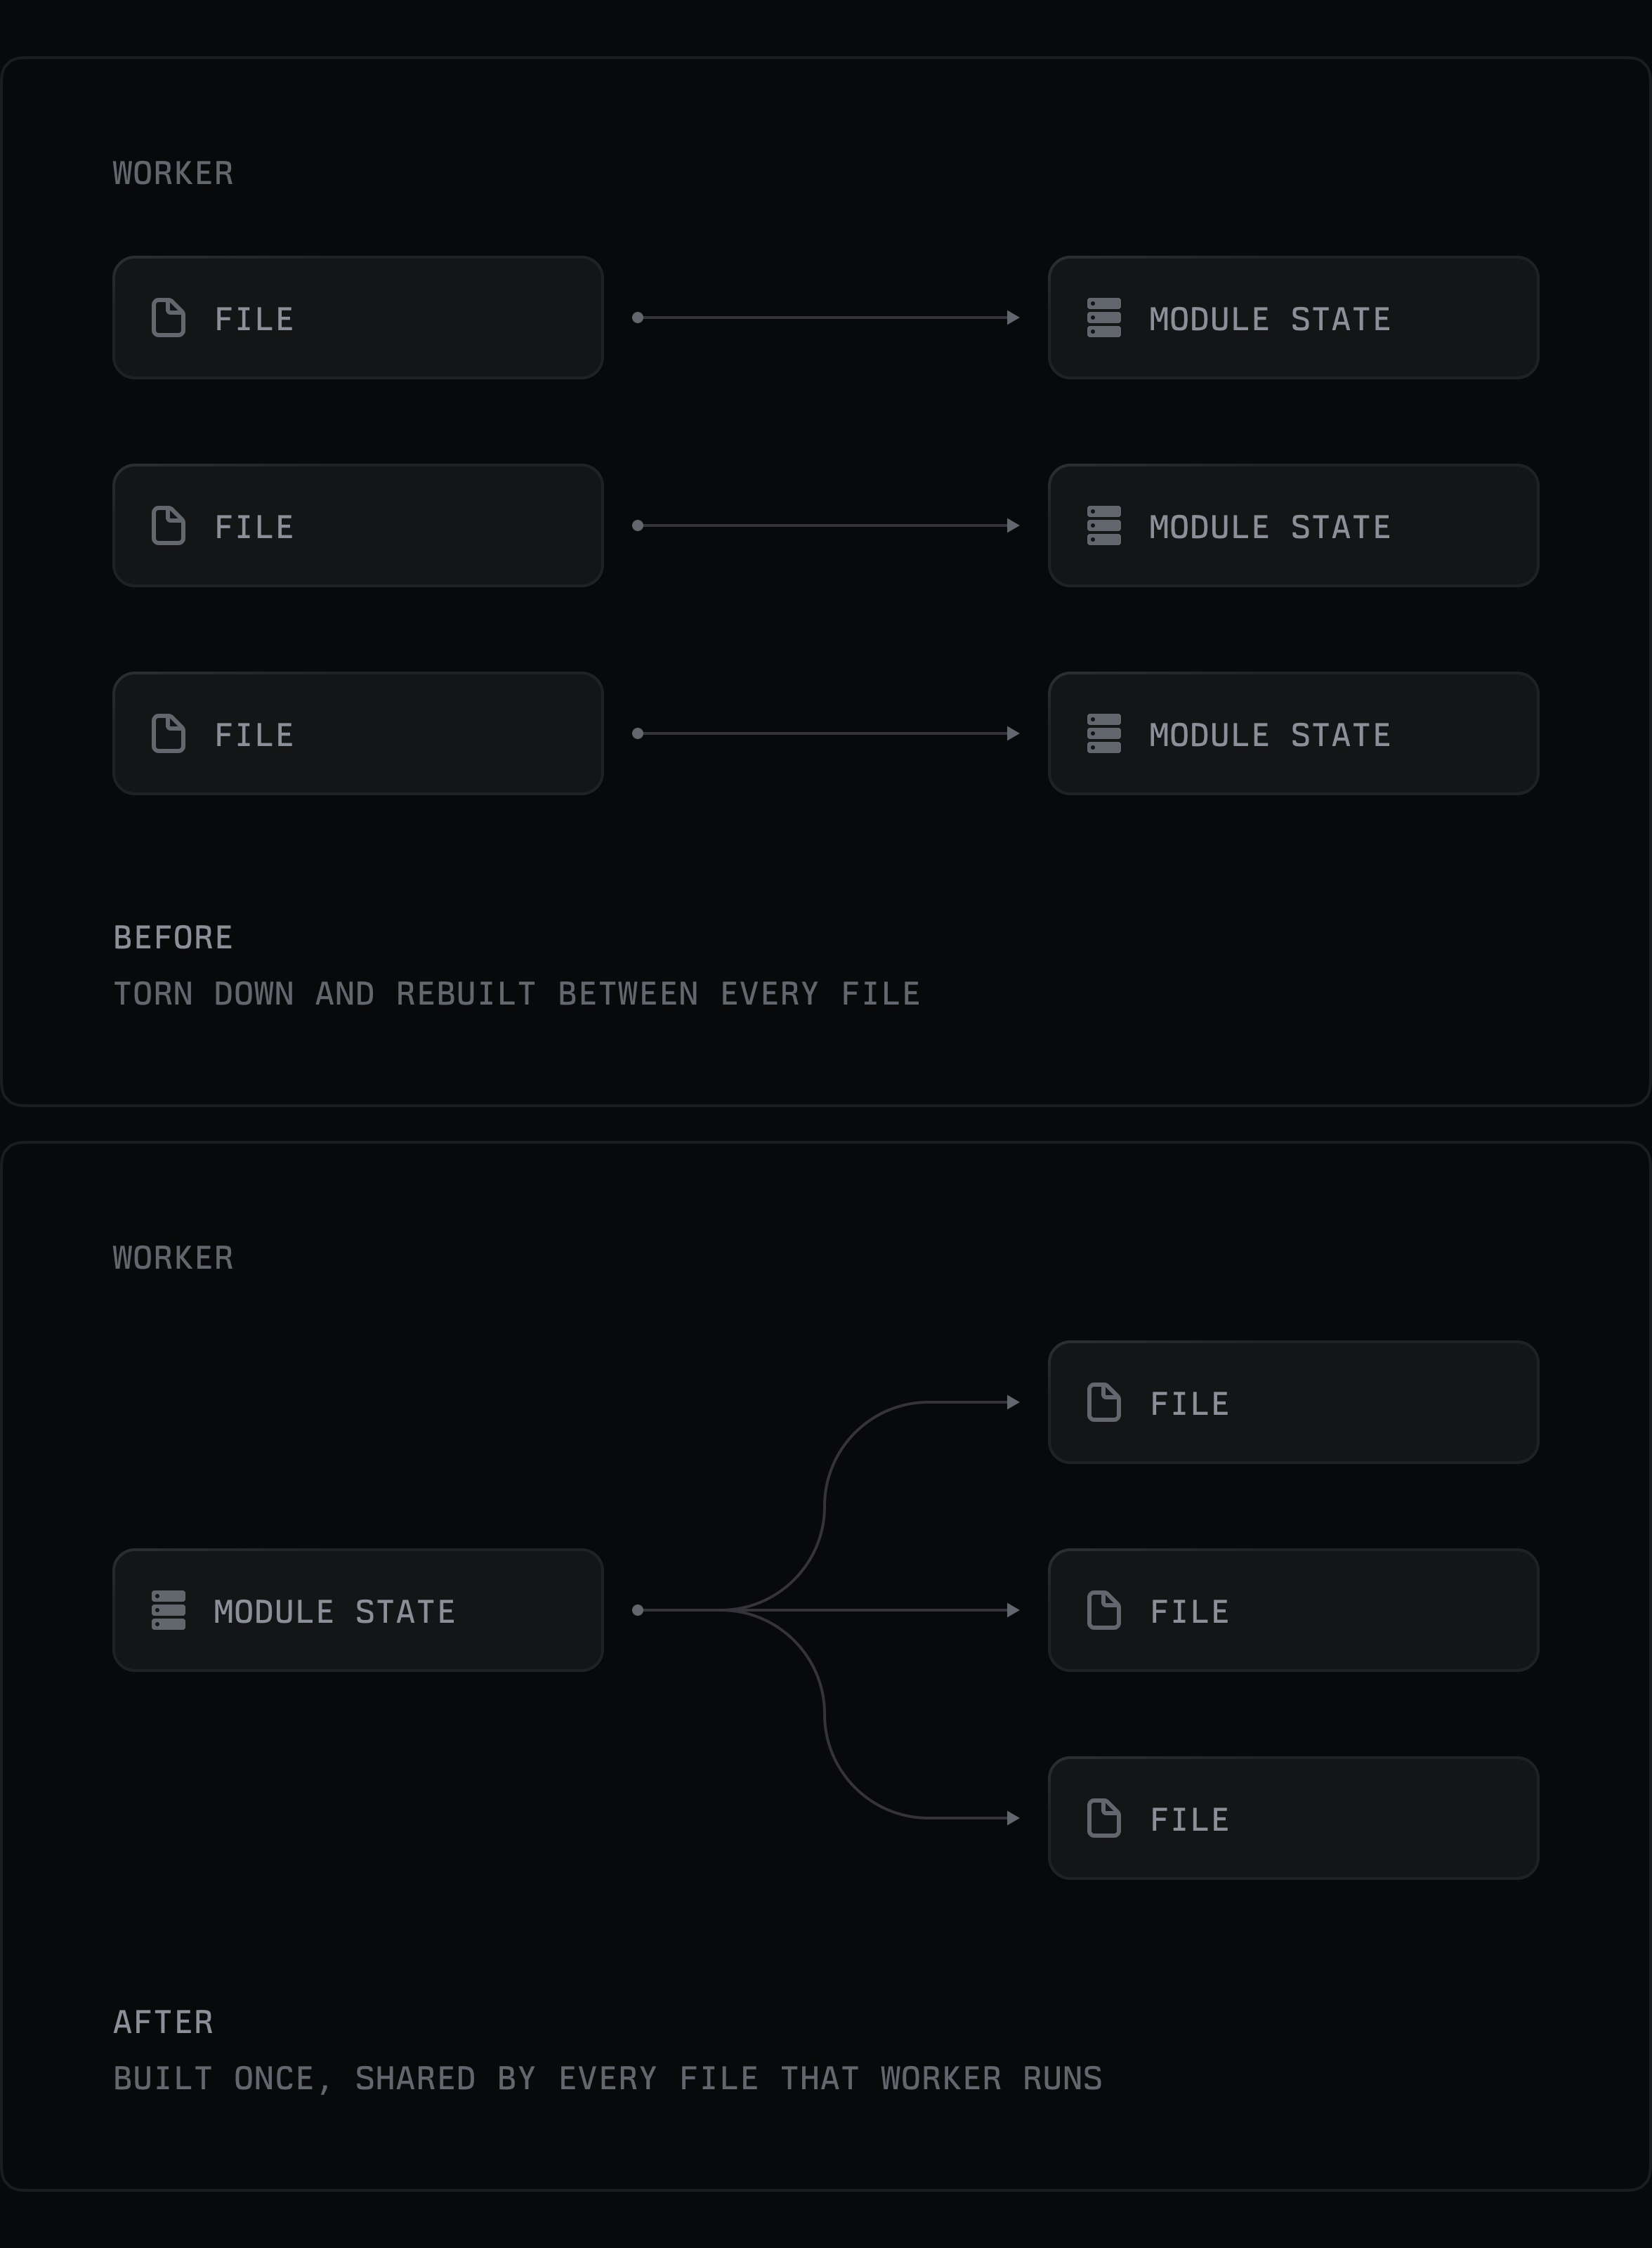
This was our largest single efficiency enchancment, value roughly 17% in month-to-month financial savings at our quantity. The slowest shard fell from roughly 300-379 seconds to about 195 seconds, whereas whole API-shard runner time dropped from about 32.8 to 22 minutes per run.
It was additionally the optimization with the very best correctness danger. We made eligibility specific with an opt-in touch upon each file, and added the required teardown for shared state. A handful of recordsdata used faux timers or shared state in methods we couldn’t untangle safely, so we left them within the remoted undertaking. And as a result of brokers now write nearly all of our exams, we up to date our respective agent expertise to account for this efficiency opt-in as effectively, so generated exams observe the identical constraints by default.
Further sharding solely pays off when the mounted value per shard is low, since doubling the shard depend additionally doubles the workflow time spent on setup. The setup optimizations we referred to earlier are what made eight shards sensible. At 110-140 seconds per shard, eight shards would have spent 15-19 minutes of runner time on setup alone, greater than the exams themselves. Setup is now round 40 seconds, so eight shards spend much less whole setup time than 4 did earlier than, whereas parallelizing the exams twice as far.
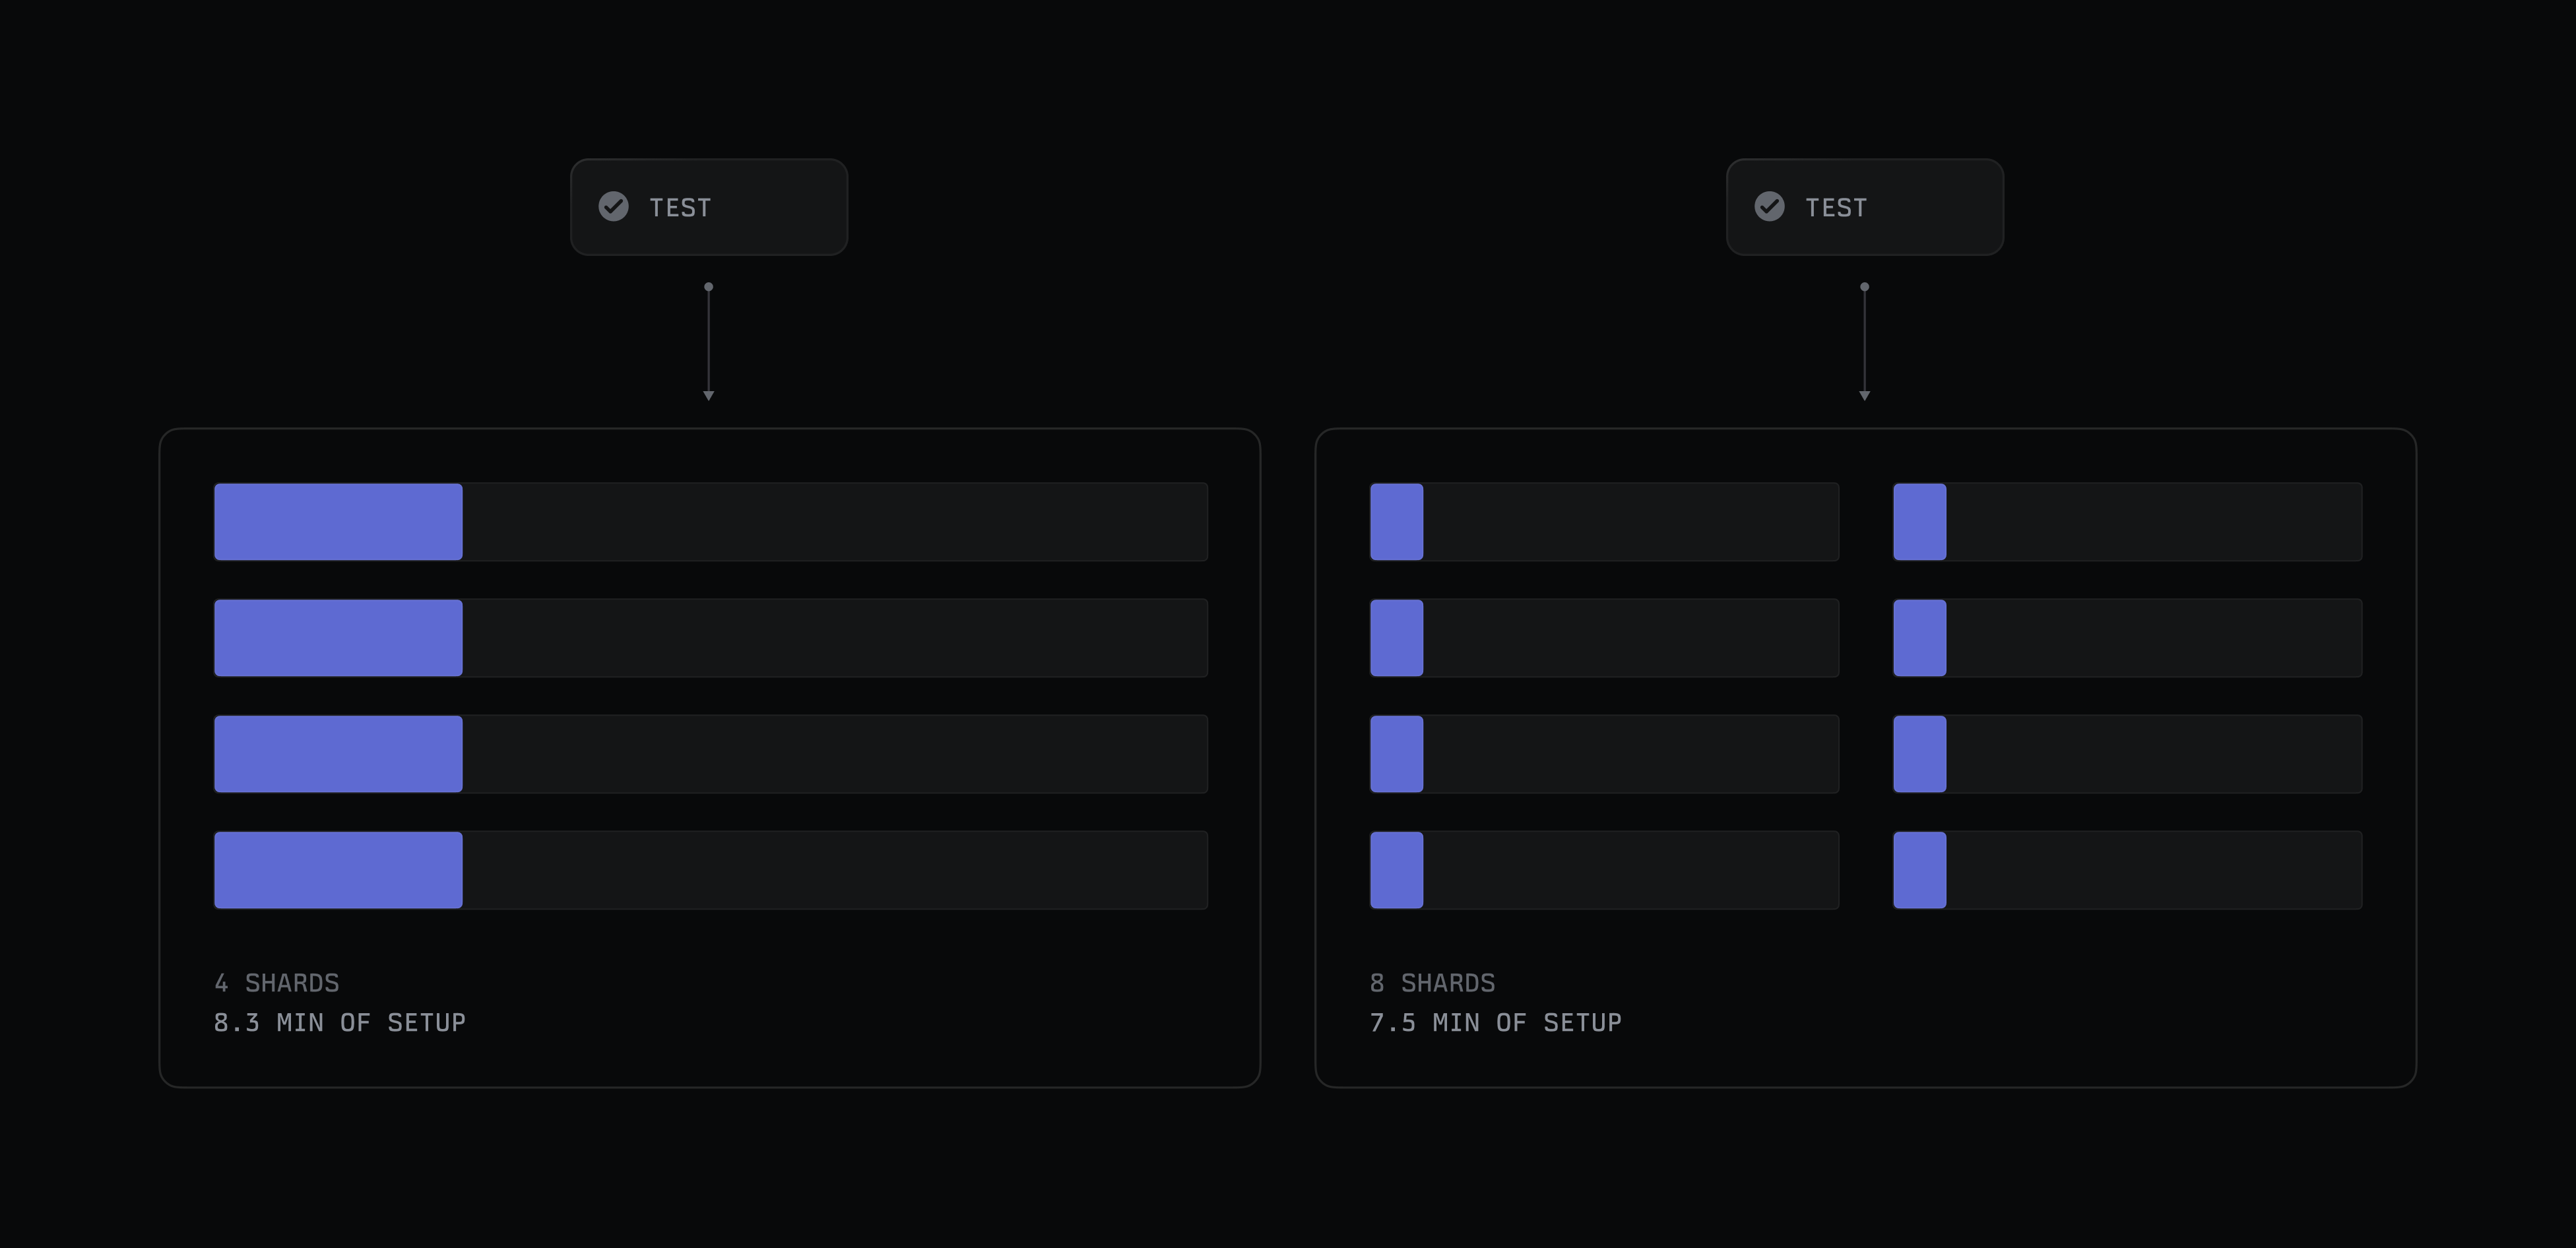
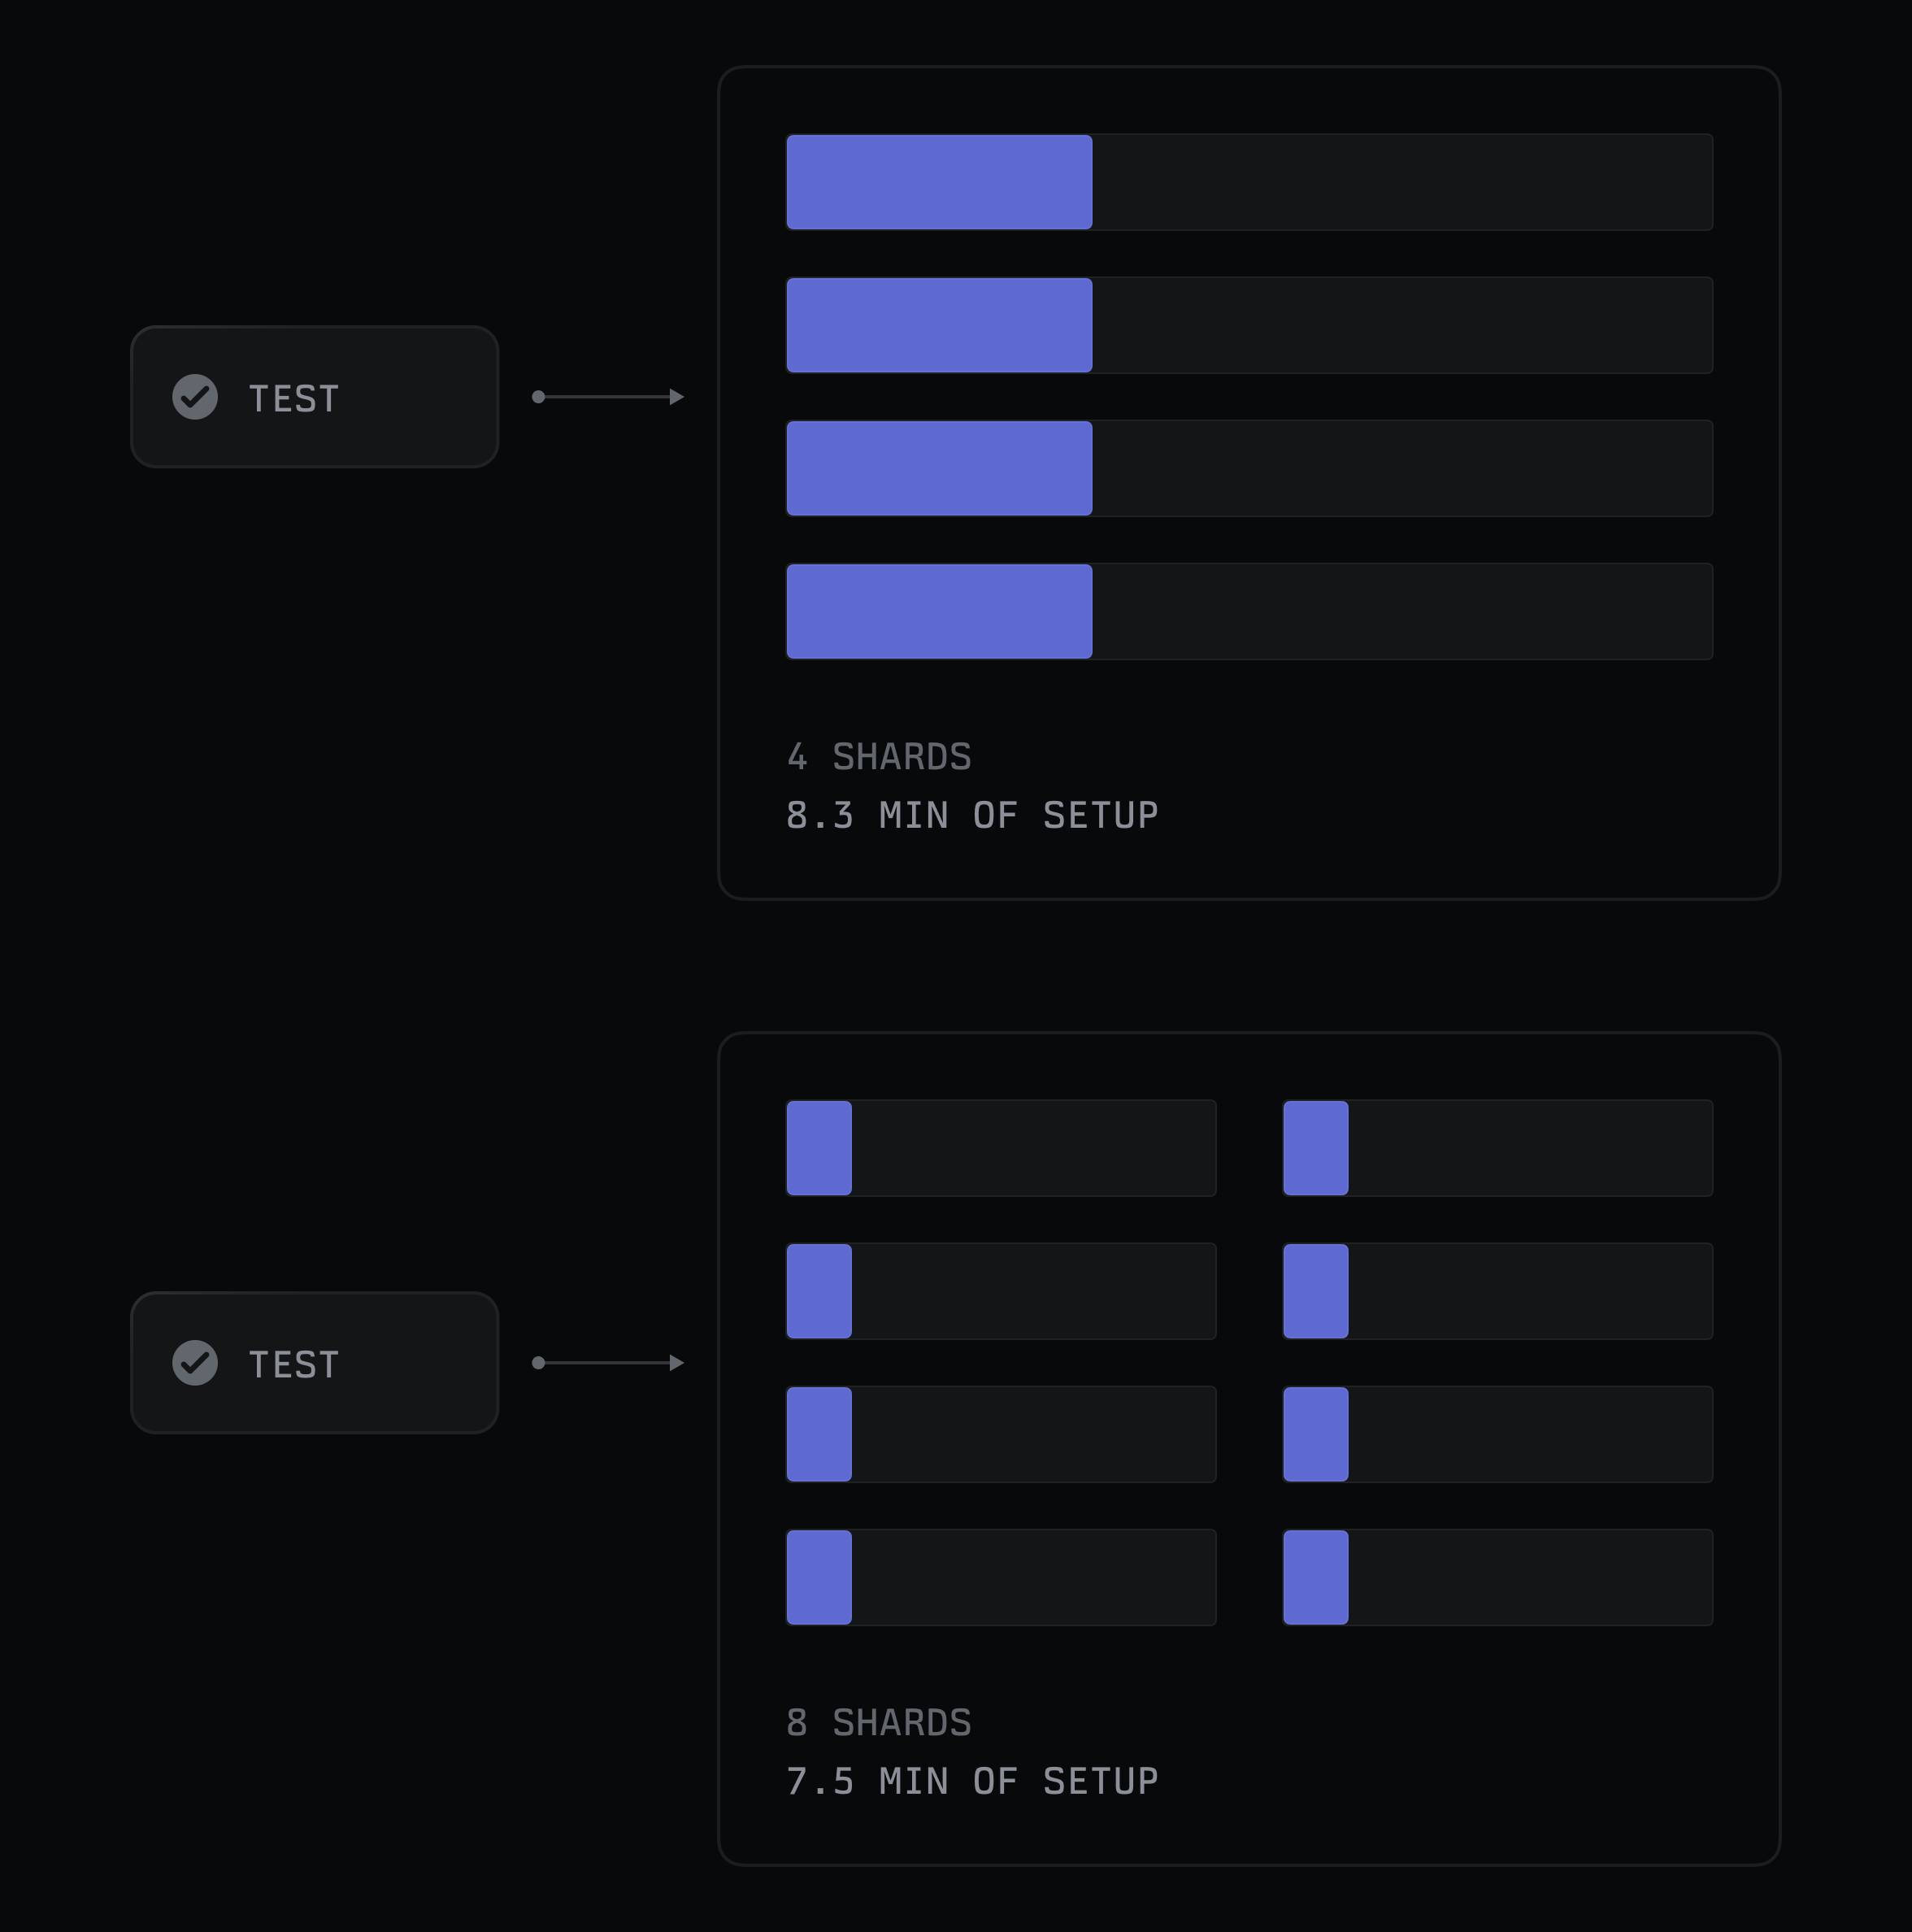
Before setup optimizations, the check job used 4 shards and spent 8.3 minutes on setup. Afterward, we may run 8 shards with 7.5 minutes of setup.
Improvements that compound throughout a system
Had we not made a deliberate effort to enhance CI earlier this 12 months, right now’s check suite would take roughly 11 minutes, near double what builders wait now. And the work doesn’t finish right here. It’s clear that our codebase will proceed to develop; we’re presently including roughly 2,000 exams every week. Keeping CI quick as that occurs might be a continued effort, a lot of it utilizing what we realized by this course of to new bottlenecks.