Announcing Artificial Analysis Intelligence Index v5
Index v5 options 2 new benchmarks and three upgrades. For the primary time, the vast majority of the Index is constructed on non-public datasets
The Artificial Analysis Intelligence Index is our composite measure of mannequin capabilities throughout duties reflecting real-world utilization right this moment. v5 is our greatest improve since v4 launched in January. With v5, 60% of the Index is now primarily based on evaluations with non-public take a look at units or held-out solutions.
Alongside Intelligence Index v5, we’re launching the Artificial Analysis Progress Index v1, which tracks mannequin functionality over time on one steady scale.
New to the Intelligence Index:
➤ FrontierCode 2.0: Cognition’s newly-launched non-public benchmark of real-world coding duties, graded on whether or not a repository maintainer would merge the agent’s change
➤ Terminal-Bench-Science: 70 agentic scientific analysis duties, run in a terminal surroundings
Upgraded:
➤ HLE-Diamond (changing Humanity’s Last Exam): a refined 1,000-question model of Humanity’s Last Exam, break up evenly between reasoning and information questions
➤ AA-Omniscience v1.1: an up to date dataset with saturated and public set questions eliminated, new questions added, and ambiguous or misguided questions revised
➤ CritPt v2: a personal, 40-question onerous subset of CritPt v2, revised by the CritPt authors and run with a code-execution device
Staying within the Index: AA-Briefcase, AutomationBench-AA, GDP.pdf and Terminal-Bench 4.0
Removed from the Index: GDPval-AA v2.1, SciCode, and AA-LCR v1.1
Intelligence Index v5 weights:
➤ Knowledge Work (25%): AA-Briefcase (15%), AutomationBench-AA (5%), and GDP.pdf (5%)
➤ Coding (25%): FrontierCode 2.0 (15%) and Terminal-Bench 4.0 (10%)
➤ Science (25%): Terminal-Bench-Science (15%) and CritPt v2 onerous subset (10%)
➤ General (25%): AA-Omniscience v1.1 15% (10% accuracy, 5% non-hallucination) and HLE-Diamond (10%)
Key outcomes:
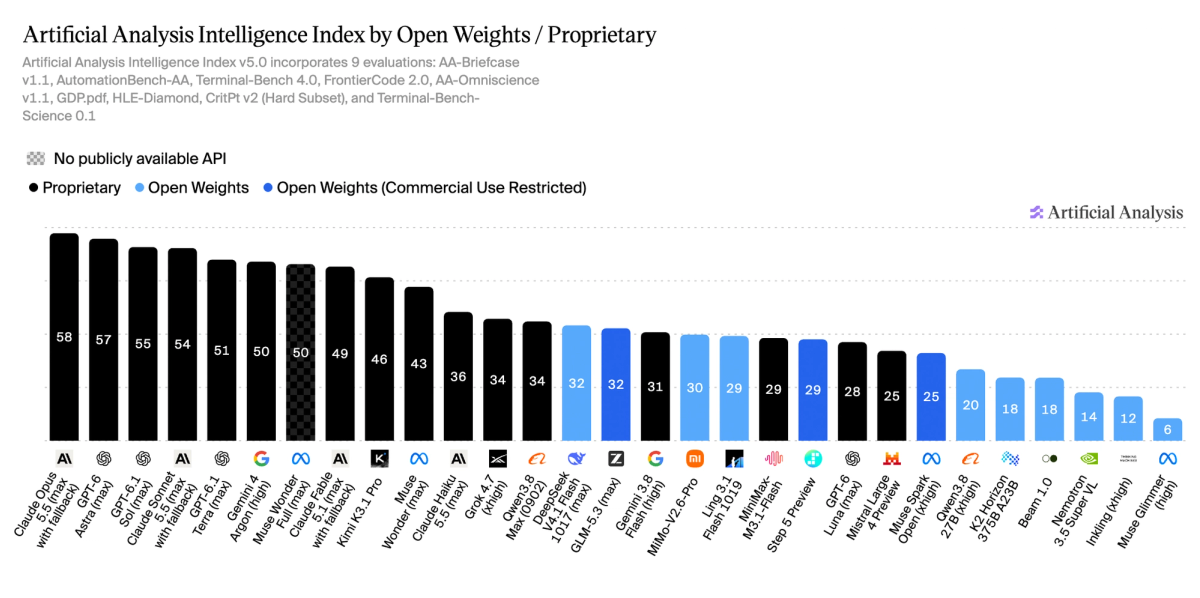
➤ Claude Opus 5.5 (max) leads at 58, forward of GPT-6 Astra (max, 57) and GPT-6.1 Sol (max, 55): Anthropic and OpenAI maintain the highest 5 fashions. Gemini 4 Argon (excessive) is subsequent at 50
➤ The open weights hole widens from 3 factors to 12: Kimi K3.1 Pro (weights not but launched) is the highest open weights mannequin at 46. Among launched weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) lead at 32 – 26 factors behind the chief and under Claude Haiku 5.5 (max, 36)
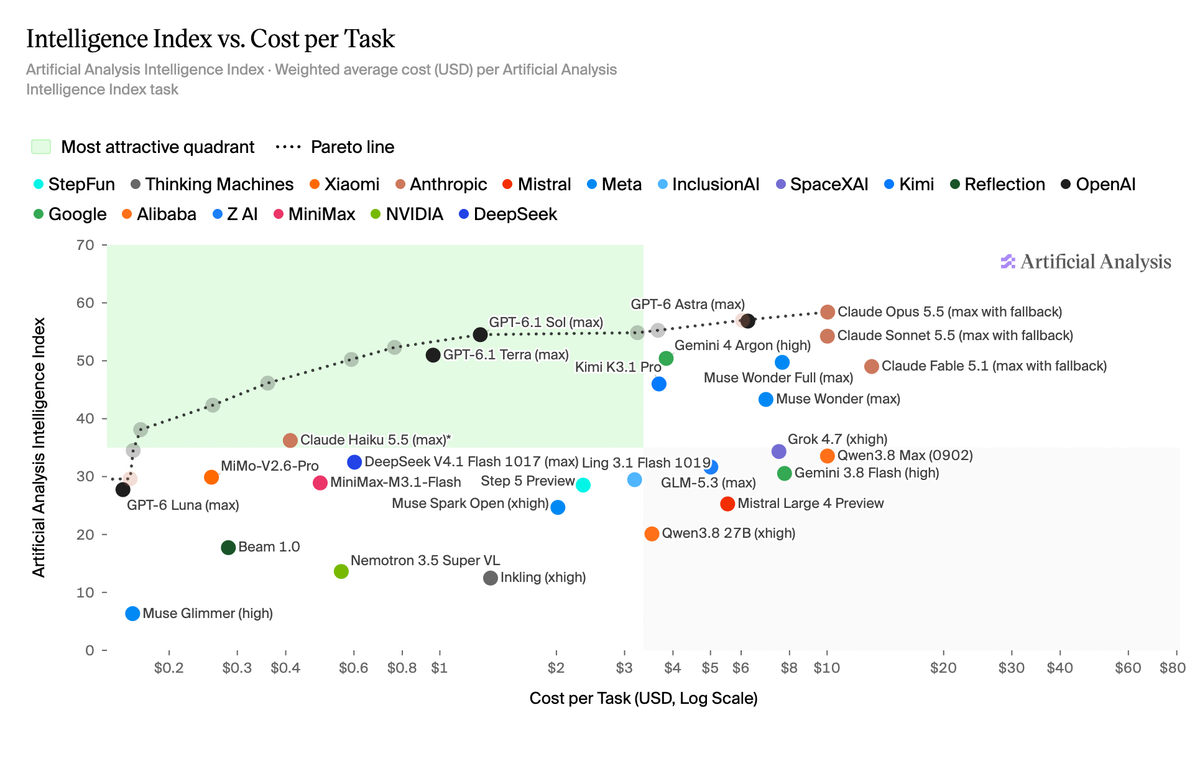
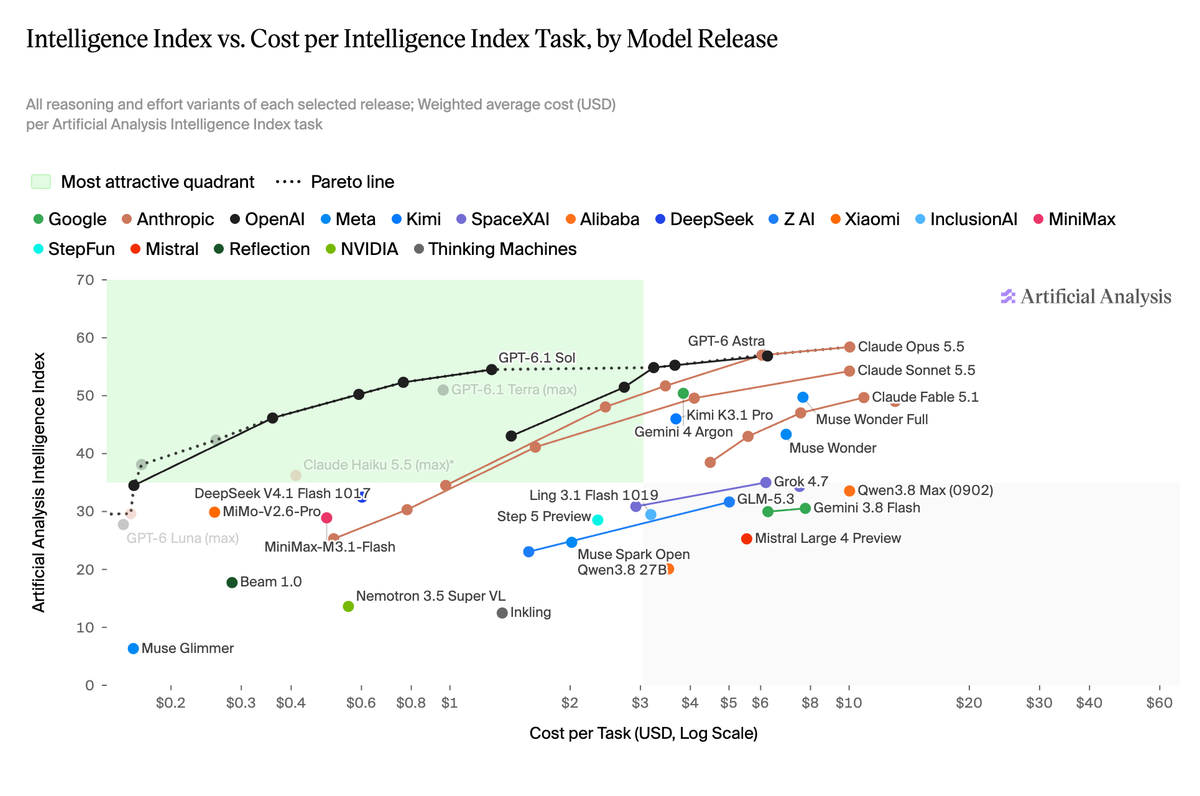
➤ Cost per activity varies by greater than 13x among the many main fashions: of the ten highest-scoring fashions proven, GPT-6.1 Terra (max) is the most cost effective at $0.96 per Intelligence Index activity and Claude Fable 5.1 (max) the costliest at $13.04
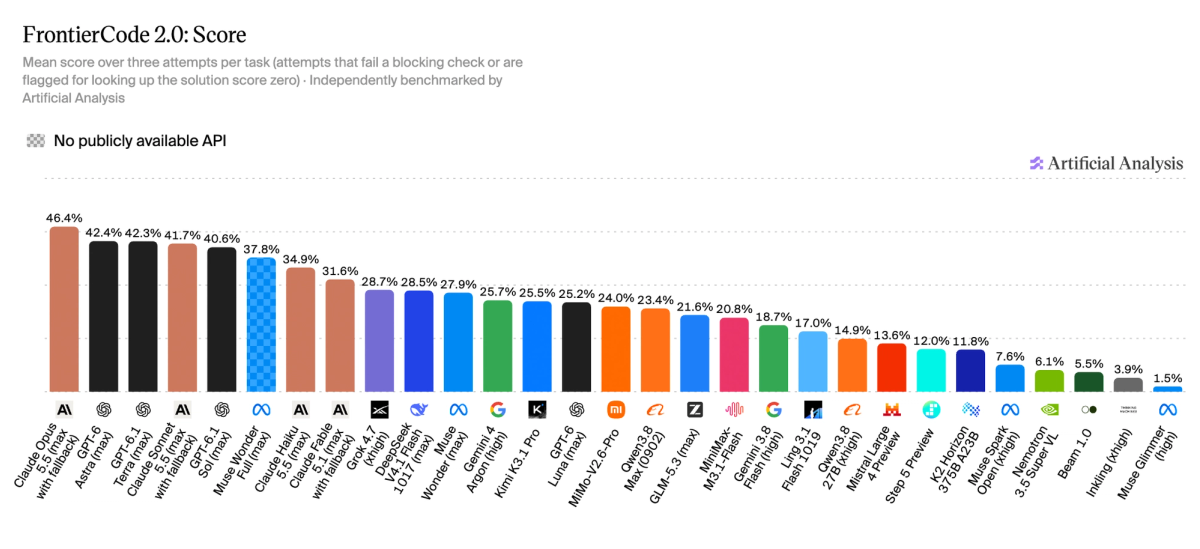
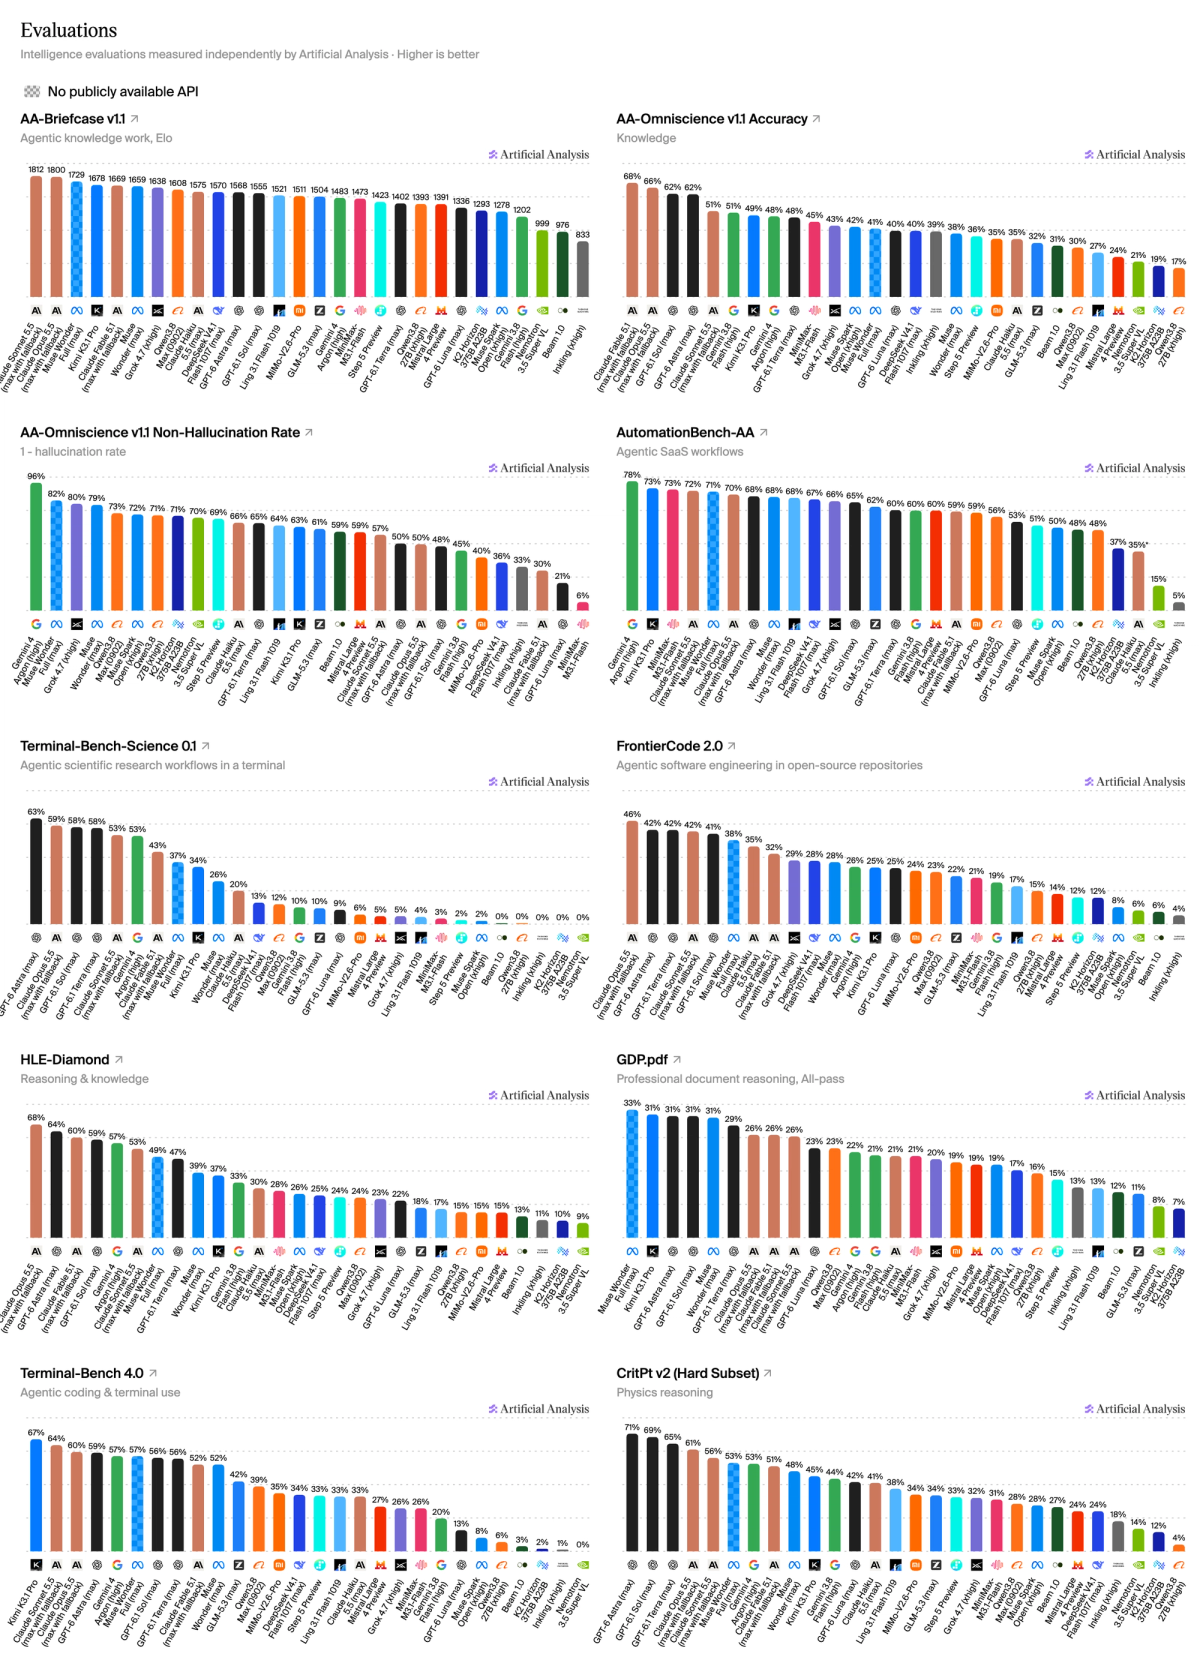
FrontierCode 2.0 is the newest replace of Cognition’s non-public coding benchmark. Launched earlier right this moment, it includes 132 duties in actual open-source repositories, graded on whether or not a maintainer would merge the agent’s change. An try that fails any blocking test scores 0, and the duties keep non-public to keep away from contamination. We run each activity 3 times in Stirrup, our agentic harness.
Claude Opus 5.5 (max) leads at 46%, adopted by GPT-6 Astra (max), GPT-6.1 Terra (max) and Claude Sonnet 5.5 (max), all at 42%. DeepSeek V4.1 Flash 1017 (max) is the highest-scoring open weights mannequin at 28%, 18 factors behind the chief.
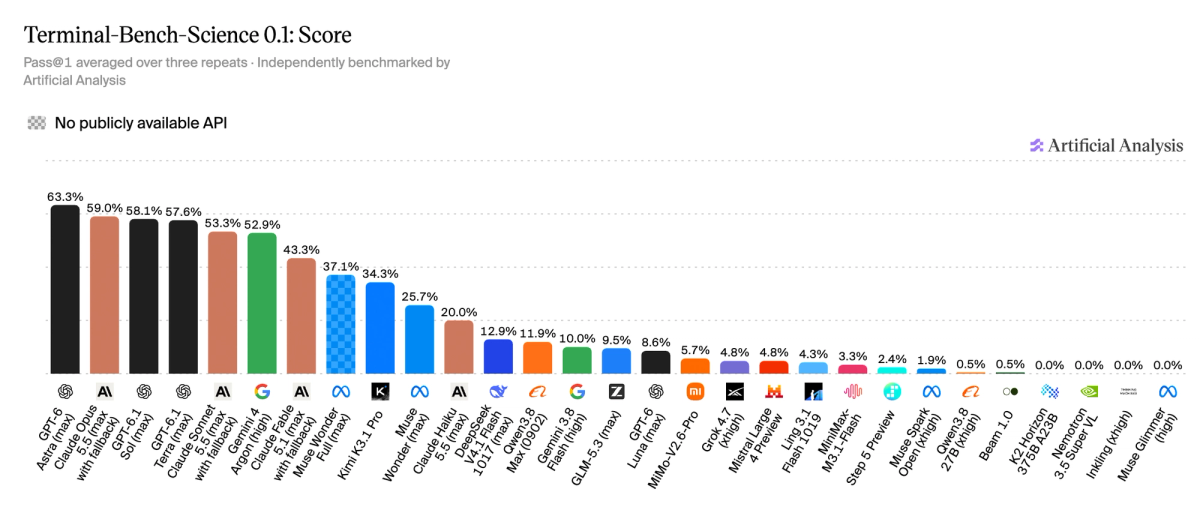
Terminal-Bench-Science checks whether or not brokers can perform scientific analysis workflows in a terminal. Experts curate and overview every activity, and a activity passes provided that each one among its checks passes.
GPT-6 Astra (max) leads at 63%, adopted by Claude Opus 5.5 (max) at 59% and GPT-6.1 Sol (max) at 58%. Scores drop off sharply under the leaders: the most effective open weights mannequin, Kimi K3.1 Pro (weights not but launched), scores 34%, and Claude Haiku 5.5 (max) scores 20%. The finest open weights mannequin with launched weights, DeepSeek V4.1 Flash 1017 (max), scores 13%, and most open weights fashions we benchmarked rating underneath 10%.
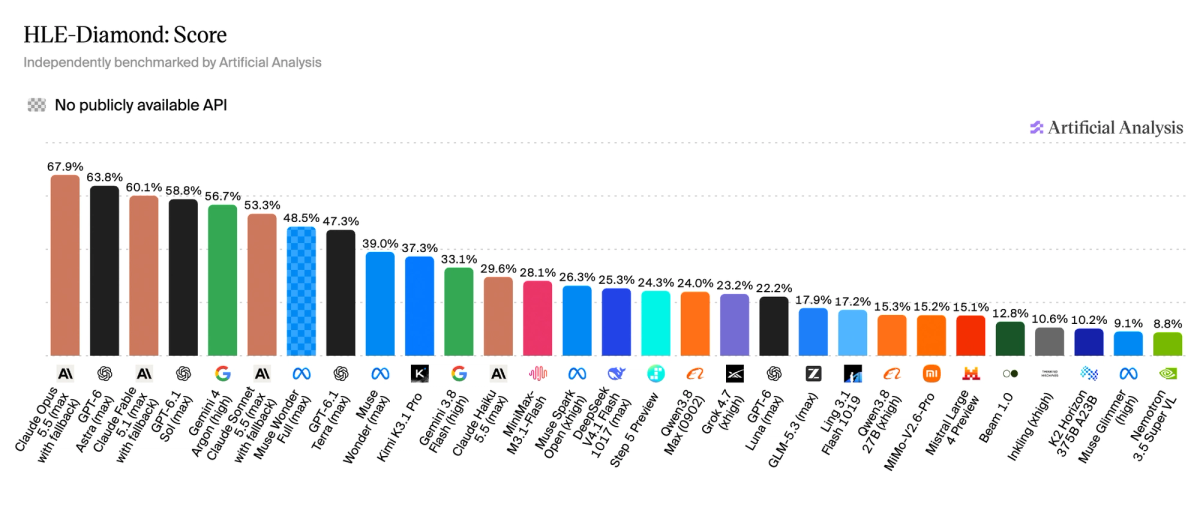
HLE-Diamond replaces Humanity’s Last Exam within the Index. It is the refined 1,000-question model of Humanity’s Last Exam from the Center for AI Safety (CAIS) and Scale AI, break up evenly between reasoning and information. Claude Opus 5.5 (max) leads at 68%, adopted by GPT-6 Astra (max) at 64% and Claude Fable 5.1 (max) at 60%.
Knowledge questions are tougher than reasoning questions for the main fashions: Claude Opus 5.5 (max) and GPT-6 Astra (max) each rating 78% on reasoning, in contrast with 58% and 50% on information.
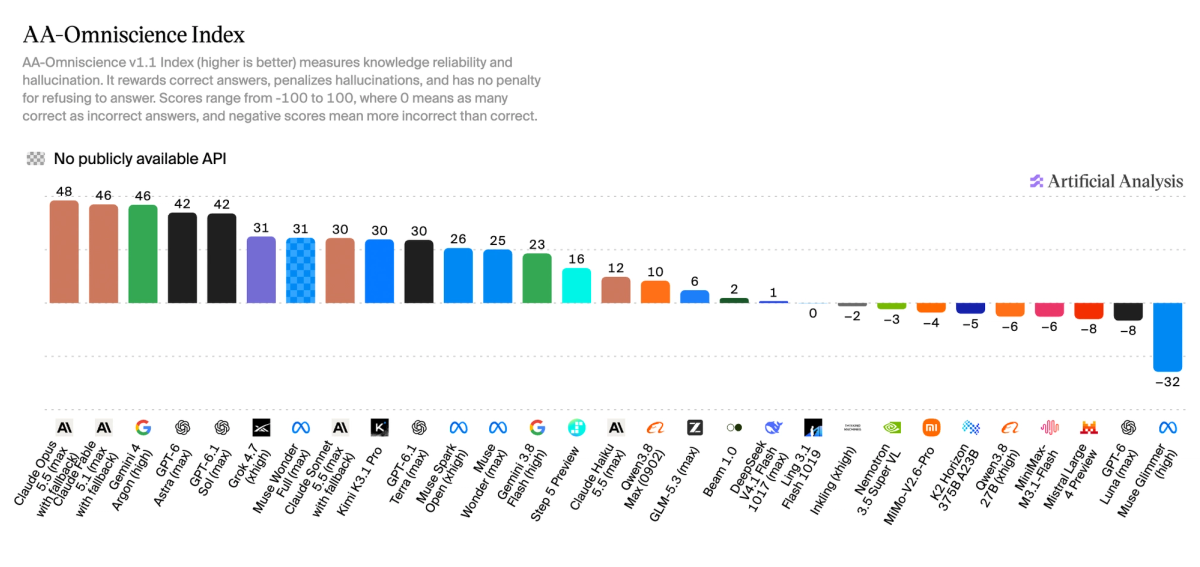
AA-Omniscience v1.1 is a cleaned model of our information and hallucination benchmark, with saturated and public set questions eliminated, new questions added, and ambiguous or misguided questions revised. Scores are principally aligned with v1, with fashions scoring on common 2 factors decrease on the AA-Omniscience v1.1 Index (median 0.6). We’ve additionally launched a brand new public subset on Hugging Face, AA-Omniscience-Public-v1.1, recalibrated to make sure accuracy, hallucination price, and total efficiency are constant between the private and non-private units.
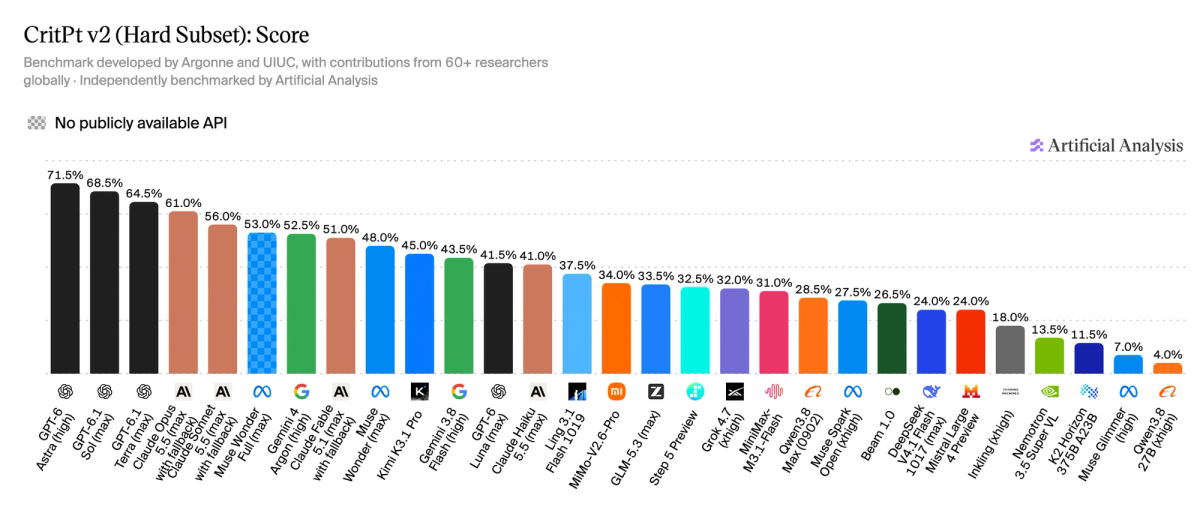
The Index scores CritPt v2 on a personal 40-question onerous subset: the 70 research-level physics questions, minus the 30 that seven frontier fashions solved in all 5 makes an attempt at launch. Models work in an offline Python sandbox in Stirrup, our agentic harness.
GPT-6 Astra leads at 72% on excessive effort, adopted by GPT-6.1 Sol at 69% on max effort. Claude Opus 5.5 (max), the highest mannequin within the Index total, scores 61%. Kimi K3.1 Pro (weights not but launched) is the highest-scoring open weights mannequin at 45%.
v5 leaves important room for progress throughout all 9 evaluations, and no single mannequin leads all of them. Of the fashions we measured, Claude Opus 5.5 leads three, and 5 different fashions lead the remaining six:
➤ Claude Opus 5.5: FrontierCode 2.0 (46%), HLE-Diamond (68%) and AA-Omniscience v1.1 (48)
➤ GPT-6 Astra: Terminal-Bench-Science (63%) and CritPt v2 onerous subset (72%)
➤ Claude Sonnet 5.5: AA-Briefcase (1812 Elo)
➤ Kimi K3.1 Pro: Terminal-Bench 4.0 (67%)
➤ Gemini 4 Argon: AutomationBench-AA (78%)
➤ Muse Wonder Full: GDP.pdf (33% all-pass)
Open weights fashions fall additional behind in v5. The finest, Kimi K3.1 Pro (weights not but launched), scores 46, 12 factors behind the chief, in contrast with a 3-point hole in v4.3. Of fashions with launched weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) rating highest at 32, and Claude Haiku 5.5 (max) outscores all of them.
The hole is widest on HLE-Diamond and Terminal-Bench-Science, the place Kimi K3.1 Pro scores 37% and 34%, in contrast with 68% for Claude Opus 5.5 (max) and 63% for GPT-6 Astra (max).
Cost varies broadly among the many main fashions. Claude Opus 5.5 (max) prices $10.04 per Intelligence Index activity, GPT-6 Astra (max) $6.24 and GPT-6.1 Sol (max) $1.27. GPT-6.1 Sol (max) scores inside 4 factors of Claude Opus 5.5 (max) at about an eighth of the fee per activity.
Effort settings matter extra in v5 than in v4.3. Claude Opus 5.5 scores 35 at low effort and 58 at max, at 10x the fee per Intelligence Index activity ($0.98 vs $10.04). Claude Sonnet 5.5 spans 29 factors from low to max, up from 20 in v4.3, and GPT-6.1 Sol’s unfold doubles from 10 to twenty factors.
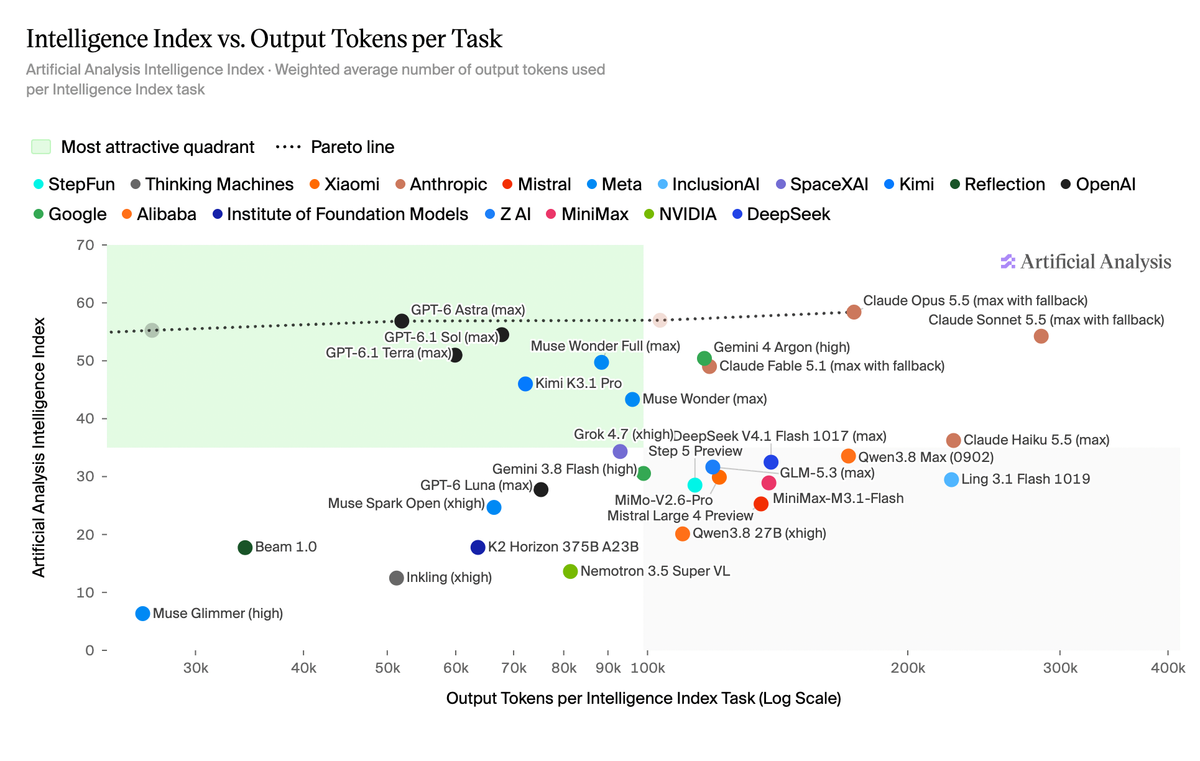
v5 duties demand considerably extra work from fashions. Every mannequin we measured generates extra output tokens per Intelligence Index activity than in v4.3, with the median rising by two thirds, from 35k to 59k.
➤ Agentic evaluations account for many token use: Terminal-Bench-Science, Terminal-Bench 4.0, AA-Briefcase and FrontierCode 2.0 make up 55% of the Index weight however a median ~90% of output tokens
➤ Terminal-Bench-Science is essentially the most token-intensive: it accounts for a couple of third of output Tokens per Task by itself
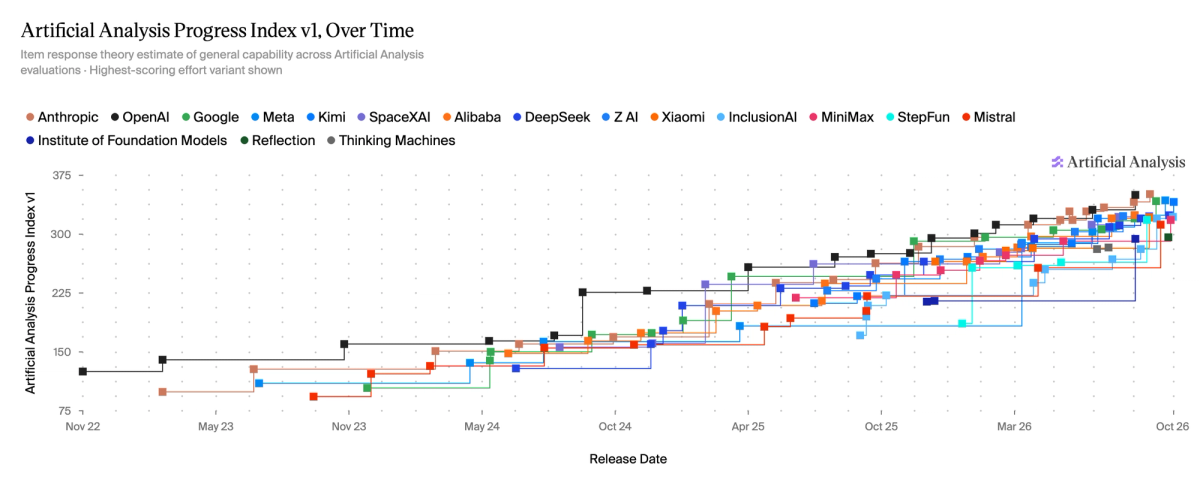
Alongside v5, we’re launching the Artificial Analysis Progress Index v1. It locations language fashions launched since November 2022 on one functionality scale, throughout a large span of benchmarks.
Use the Progress Index to check how underlying functionality has modified over time, together with between fashions launched years aside. To evaluate fashions for present use circumstances and perceive the current frontier, use the Intelligence Index, which stays our main measure of present mannequin intelligence.
Thank you to Epoch AI and Anthropic – we constructed on learnings from the Epoch Capabilities Index in designing the Progress Index.
Explore the Progress Index: artificialanalysis.ai/trends
Methodology: artificialanalysis.ai/methodology/progress-index
Thank you to Cognition, Steven Dillmann and the Terminal-Bench crew, the Center for AI Safety, Scale AI, and Minhui Zhu, Minyang Tian, Hao Peng and the CritPt crew for the benchmarks behind this replace.
Explore the total outcomes: artificialanalysis.ai
Methodology: artificialanalysis.ai/methodology/intelligence-benchmarking