I made a decision my 10-year-old mini PC hadn’t suffered sufficient, so I made it run an area LLM
I’ve needed to attempt native AI in my homelab, however the expense of setting all of it up has sadly been placing me off. From what I can see, native AI would require me to spend hundreds on a server with multiple GPUs, numerous reminiscence, and energy consumption equal to that of a small grocery store.
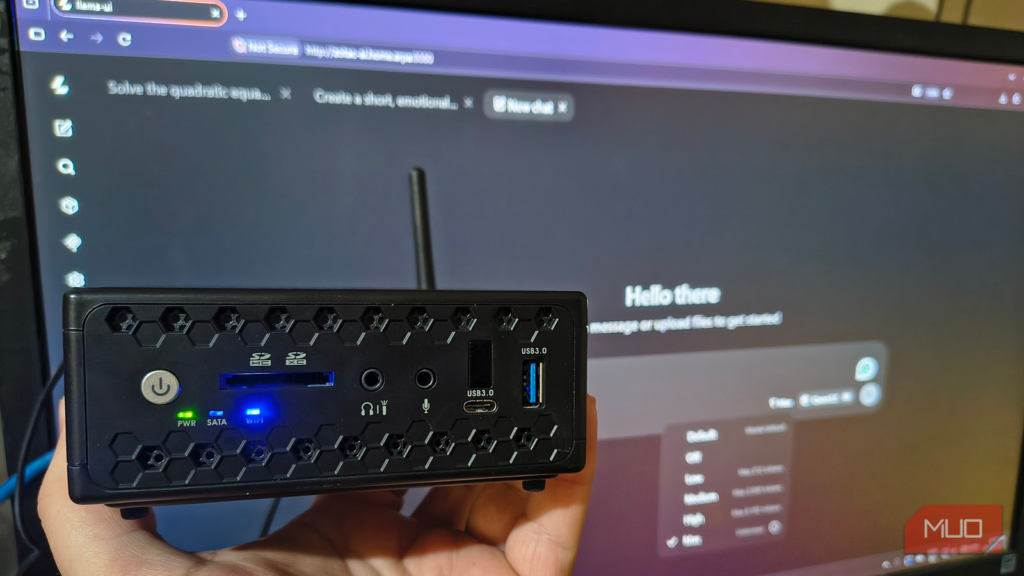
Before constructing something I’d name critical, I needed to see how little {hardware} I might realistically get away with. My decade-old Zotac mini PC appeared suitably underqualified, having been launched properly earlier than anybody had even heard of a Large Language Model.
What adopted was an train in persistence, but in addition a incredible place to begin for anybody eager to experiment with native AI with out the costly gear.
I gave my outdated Celeron a really trendy job
The {hardware} was historic by trendy requirements, however who wants a GPU anyway?

My check machine was a Zotac ZBOX C1325 nano with a less-than-impressive Celeron N3160, 8 GB of RAM, and an affordable SSD.
I put in Ubuntu Server and compiled llama.cpp, which is appropriate for operating on low-spec machines like a Raspberry Pi. For my construct, llama.cpp would in the end run the fashions and supply a browser-based chat interface.
I configured the construct for the Zotac’s processor and CPU-only inference. From the supply listing, I constructed the instruments with two parallel compilation jobs:
cmake --build construct --target llama-server llama-cli llama-bench -j 2I ended up selecting SmolLM2, Qwen3.5 0.8B, and Qwen3.5 2B, all in Q4_K_M quantized variations. Quantization reduces the precision used to retailer mannequin weights, thereby lowering compute necessities. Unfortunately, this does include a couple of high quality tradeoffs, however I wanted to be life like.
Once I’d launched llama-server, I opened zotac-ai.house.arpa:8080 from my browser. The browser displayed the dialog very like ChatGPT does, whereas the Zotac did the precise inference.
Now, I by no means as soon as anticipated this to be a alternative for Claude, Gemini, or ChatGPT. I did assume, nonetheless, that it might at the very least carry out some fundamental text-based duties. Whether the fashions adopted my directions was the following query.
My smallest mannequin made some surprisingly large errors
Larger fashions improved the solutions, however I nonetheless have to checked them
I began with the small job of constructing a line from an e mail sound a bit extra well mannered:
Hi Sam, the report nonetheless hasn’t arrived. I would like it by 3 pm right this moment so I can end the consumer presentation. Please let me know if there’s an issue.
First, SmolLM2 360M tried to rewrite it, and the response was pleasant sufficient. However, it had dropped each the deadline and the presentation, plus supplied additional info I by no means included.
Then I gave it an extraction job. I equipped a observe requesting 12 alternative keyboards for a Chicago workplace on Thursday, and requested for 4 labeled fields. SmolLM2 returned these 4 fields:
- Item: 12
- Quantity: 12
- Delivery day: Thursday
- Delivery location: Chicago Office
Three right fields, however I wouldn’t wish to be the individual fulfilling that order of “Item: 12.”
The abstract job I gave SmolLM2 resulted in one more mistake. The source prompt described a easy situation of an upcoming Wi-Fi alternative in Chicago, whereas explicitly mentioning that Boston wasn’t affected.
SmolLM2’s response hilariously acknowledged the Chicago work was accomplished and claimed Boston was nonetheless engaged on its alternative. Compression had clearly been used, however altering what occurred wasn’t what I’d name an satisfactory response.
Qwen3.5 0.8B was a noticeable enchancment. Its e mail response preserved the deadline and presentation context, and its extraction recognized all 4 fields appropriately. Those had been solutions I might see myself really working with.
However, its two-sentence abstract for the Boston Wi-Fi job utterly omitted the explanation for changing the Wi-Fi tools regardless of my directions to protect it.
The 2B mannequin produced a beautiful, well mannered e mail and one other right extraction. Its abstract of the Wi-Fi duties lastly lined the alternative, frequent disconnections prompting it, and what staff wanted to do, all throughout the stipulated two sentences.
For a ultimate check, I requested the 2B mannequin to unravel a quadratic equation, present its factorization, and confirm each solutions:
2x² − 7x + 3 = 0
It appropriately factored this into (2x − 1)(x − 3) = 0, discovered x = ½ and x = 3, and checked each by substitution. One right math job doesn’t instill sufficient confidence for 2B to change into my math tutor, however it was satisfying watching my little machine get your complete job right.
I ran out of persistence earlier than I ran out of RAM
The fashions match comfortably, however brief solutions might take minutes

The higher solutions got here with a time value that I might measure by watching YouTube videos whereas ready. Dealing with the boredom of ready for the mannequin to generate textual content was solely a part of it. Before answering, it needed to course of the enter, together with formatting and directions packaged with my prompts.
The first e mail requests gave me the perfect comparability. Both Qwen fashions processed 396 prompt tokens, that are the chunks of textual content a mannequin works with. The 2B mannequin spent roughly 202 seconds processing that enter, adopted by one other 26 seconds producing its brief rewrite.
|
Model |
Total server processing time for the primary rewrite job |
Generation velocity |
|
Qwen3.5 0.8B |
90 seconds |
2.63 tokens/second |
|
Qwen3.5 2B |
228 seconds |
1.23 tokens/second |
That distinction was really fairly vital. A era velocity of roughly one token per second sounds gradual, however it’s tolerable for a brief reply. Waiting greater than three minutes earlier than it might actually get going wasn’t fairly really easy to simply accept.
The downside wasn’t reminiscence capability. When operating htop throughout inference, all 4 CPU cores had been maxed out, whereas the server’s reminiscence ranged from about 390 MiB with SmolLM2 to 1.3 GiB with Qwen3.5 2B. Swap was by no means utilized in any of the check runs.
The on a regular basis expertise of utilizing these LLMs on the mini PC was getting clear. In most circumstances, I received a helpful reply, however I might truthfully end the duties myself earlier than that reply arrived.
When utilizing an LLM on a PC with constrained assets, preserve requests extremely targeted and ask for concise solutions. On my machine, processing the enter took up a lot of the wait time, so a brief reply alone would not assure a fast response.
I’m retiring this setup, however I’m simply getting began with native AI
The Zotac helped me resolve whether or not higher {hardware} could be price exploring

For apparent causes, I received’t be conserving the Zotac as an AI server. For these brief duties, I might be higher off simply writing the e-mail or creating summaries myself.
Qwen3.5 0.8B supplied probably the most promising compromise in my trials, however even that mannequin missed info I explicitly requested it to incorporate.
Still, the experiment did precisely what I needed. I ran fashions offline on {hardware} I already owned, used them by way of a well-recognized chat UI, and received some comparatively helpful solutions. Basically, I came upon that I loved tinkering with local AI earlier than forking out on the {hardware}.
What this experiment additionally confirmed me was that you just don’t should abandon the thought of experimenting as a result of high-end machines are past your funds. An outdated pc can nonetheless offer you someplace to begin. Mine helped me uncover an curiosity price pursuing, even when it received’t be coming alongside for the trip.