LLMs are making formal software program verification possible at a a lot bigger scale Anthropic
Keane Lucas, Aengus Lynch, Luna Tong, Luke Champine, Zygi Straznickas, Dino Distefano, Harshikaa Agrawal
Evyatar Ben Asher, Ava Howell, Sami Jawhar, Chris Rohlf, Nickolai Zeldovich
Nicholas Carlini, Rajashree Agrawal, Jason Gross
Most software program is riddled with bugs, which AI can now simply find and exploit. The normal defenses in opposition to cyberattacks are now not ample: we’d like methods to show that code is freed from bugs. Formal software program verification might present this assure, however it has traditionally required years of professional effort, making it impractical for many real-world initiatives. In a collaboration with Theorem, nonetheless, we present that is now not the case: LLMs can now produce formal proofs at massive scale, enabling new software program improvement workflows that embody confirmed safety ensures. Using Claude, we proved safety properties on the meeting code degree (RISC-V) in over 100 real-world open-source software program libraries. To our information, this represents the primary large-scale effort to make use of AI to use formal verification to manufacturing software program on the meeting code degree. While writing the proofs, Claude additionally found bugs that had eluded detection for years, regardless of trillions of test runs. As mannequin capabilities proceed to enhance, we anticipate formal verification to turn out to be a vital a part of safe software program improvement.
Introduction
Even mature, closely examined software program incorporates bugs, and LLMs are increasingly adept at discovering them. The Linux kernel—one of the well-tested items of software program in the present day, deployed on billions of units worldwide—not too long ago had over 1,000 vulnerabilities disclosed. With frontier fashions turning into extra able to chaining seemingly benign bugs into essential exploits, we’d like methods that may detect and repair these bugs earlier than they are often exploited within the wild.
Ideally, such methods might discover and patch all bugs, after which present some proof that there are not any extra to be discovered. Formal verification is a technique to do that. In formal verification, builders translate their code right into a mathematical mannequin, then attempt to show that it at all times follows some outlined set of safety guidelines. If they fail to show this, meaning there could possibly be a bug within the code that might violate a rule, and the character of the failure implies what the bug may be. Repeating this course of (after eliminating the reason for failure every time) will in the end yield proof that the code is devoid of any bug that might violate these guidelines.
However, formal verification isn’t simple. Proofs might be many instances bigger than the unique code, and writing them requires vital effort and a distinct segment, extremely specialised ability set. For occasion, it took two person-years to implement the seL4 working system kernel, however 20 person-years to formally verify it. Accordingly, formal verification has been sensible solely in actually mission-critical purposes, reminiscent of Airbus’s avionics code.
But LLMs are making it far simpler. Frontier fashions can now produce correctness proofs for real-world software program absolutely autonomously. To show this, we requested Claude to show helpful safety properties throughout 123 open-source libraries, together with exhibiting that a few of their executable artifacts can by no means crash beneath sure situations. Specifically, Claude proved that these packages will at all times exit usually with out triggering memory-safety errors or failing assertions, for each enter lower than 64 MB and each modeled Linux working system (OS) response and reminiscence structure, beneath sure assumptions (particularly that this system runs as a single-threaded static binary with a hard and fast reminiscence funds on a RISC-V1 CPU utilizing Linux OS). This remains to be far-off from fixing all doable bugs, however it does get us a lot nearer than earlier than and gives a roadmap towards that finish.
We’re publishing a subset of these proofs in order that anybody can confirm and reuse them, together with the RISC-V and OS semantics. Theorem, our collaborator on this mission, can also be providing to run the identical pipeline for other open-source projects, and is publishing a Claude skill to assist builders get began with verifying their very own code.
Formal verification is a broad area with many methodologies. Below, we additionally describe our preliminary explorations utilizing different formal verification strategies to speed up different safety or software program improvement duties, reminiscent of assessing the safety of the zlib compression algorithm, proving behavioral equivalence of a Python interpreter written in Rust, and rooting out long-standing bugs in essential software program.
The highway forward for formal verification is promising. The value of writing proofs is falling as fashions turn out to be extra clever. Moreover, as extra code is formalized and strategies of attaining safety ensures turn out to be extra standardized, the flexibility to reuse or modify proofs throughout codebases will amortize the fee. We encourage all builders to discover formal verification with LLMs—particularly those that beforehand tried it with much less succesful fashions and located it didn’t work.
In the remainder of this publish, we cowl our formal verification experiments in additional element.
Turning checks into proofs
To show {that a} piece of software program is appropriate, we should first state what “appropriate” even means. Correctness is outlined by the specification (spec). In some packages, there’s a clear solution to formally specify this system’s supposed habits. For instance, a PNG decoder takes a sequence of bytes and (following RFC 2083) decodes these bytes into the corresponding picture. But for many packages, issues aren’t so simple. What would it not imply for a textual content editor or an online browser to be “appropriate”? The problem of acquiring a complete and unambiguous spec is a big impediment to verifying software program at a bigger scale.
To handle this for the code within the open-source libraries that we sought to show, we take the method of mechanically changing their preexisting compilable take a look at suites right into a spec by encoding the rule “this take a look at suite at all times passes,” utilizing a basic mannequin of what it means to execute any RISC-V-compiled binary on Linux. Historically, proving such specs was intractable, given the inherent complexity of writing a proof that may embody and make an argument over all doable behaviors and interactions of tens of 1000’s of meeting directions over any enter (and the truth that proofs are typically extraordinarily massive in consequence). This is the place in the present day’s LLMs are available in: churning by way of tens of millions of strains of code in pursuit of a well-defined objective is a process that LLMs are extraordinarily effectively fitted to.
For this mission, we began with fuzz checks. In these checks, builders write an entry level2 into their code that takes inputs, such that any enter that causes a crash is a bug the authors care about. Then the fuzzer, a testing engine, generates huge numbers of semirandom and mutated inputs on the entry level to attempt to discover a bug (visualized in Figure 1). The longer a fuzzer runs, the extra bugs it may possibly discover. But that is inherently a brute-force course of, with no assure of exercising each doable code path, no matter what number of inputs you strive.
To discover all of the bugs that might’ve been surfaced by a fuzz take a look at, we turned the fuzz take a look at right into a spec outlined over the compiled RISC-V directions. The spec says that the fuzz take a look at gained’t crash for any enter lower than 64 MB.3 If Claude can show this spec, the fuzz take a look at on RISC-V turns into superfluous: fuzzing that entry level won’t ever discover any bugs.
We did this for a whole lot of initiatives in Google’s OSS-Fuzz initiative, which gives steady fuzz testing for qualifying open-source initiatives. OSS-Fuzz incorporates 1000’s of developer-authored entry factors that search for damaged code properties by crashing (for instance, on a failed assertion). OSS-Fuzz mechanically devices C and C++ packages with AddressSanitizer4 (ASan), inflicting them to crash at any time when reminiscence is accessed improperly (which is a leading cause of software vulnerabilities). Broad-spectrum specs like reminiscence security apply to virtually all software program.
Over the span of some weeks, Claude efficiently patched the bugs it discovered after which proved that there are not any crashes on any enter (as much as 64 MB) for 239 entry factors throughout 123 totally different OSS-Fuzz libraries. These proofs function on the compiled RISC-V directions (i.e., executable binaries), they usually comprise about 180 million strains of Rocq, with a typical proof working to about 600,000 strains to offer safety ensures on binaries with a median size of 18,000 RISC-V directions. These proofs are constructed by translating the RISC-V meeting code to a mathematical mannequin utilizing Theorem’s RISC-V instruction and Linux course of semantics. This means these proofs at the moment assume that this system runs as a single-threaded static binary with a hard and fast reminiscence funds on a RISC-V CPU utilizing Linux OS. Expanding the scope of those proofs is effectively inside attain, as it will contain standardizing semantics for extra meeting architectures and different working system processes. See an expert’s take on the proofs Claude wrote.
While this is a gigantic quantity of proof code, just about none of it must be manually reviewed. The Rocq proof checker ensures that the spec is appropriately glad by the proof. As a end result, the one artifacts {that a} developer must belief are:
- The formal fashions of RISC-V and of Linux processes;
- The precise theorem statements that have been proved;
- The Rocq proof checker itself.5
This doesn’t imply these libraries comprise no bugs. Instead, it implies that any remaining bugs both are to be discovered inside the artifacts listed above or are outdoors the scope of Claude’s proof. Hardening these still-possibly-buggy trusted parts (Rocq, RISC-V, and Linux semantics) just isn’t insignificant, however it’s a much more tractable process than debugging each line of code the scaled-out proofs cowl—particularly as this method can safe an arbitrary variety of initiatives with out rising the dimensions of the trusted parts.
We welcome unbiased verification of our proofs and encourage refinement of our method. To that finish, we’re publishing the trusted parts (above) made for this mission that aren’t already public; Claude’s full Rocq proofs for fuzz checks that didn’t require patching; and specs for different fuzz checks we weren’t capable of show.
Finding and fixing bugs
Above, we confirmed you could flip many open-source libraries’ developer-written checks (fuzz checks) into specs that Claude can show will at all times cross, typically after patching the remaining bugs it discovered. For this motive, the method of trying to show these specs found a whole lot of bugs.
Lots of bugs confirmed up throughout Claude’s makes an attempt to show a whole lot of entry factors. To be certain that Claude didn’t should cease for a human each time this occurred, we let Claude repair the bugs it discovered: it patched the code, which precipitated the spec to be regenerated with that patched code, after which Claude proceeded to show that new spec.6
Many of the bugs we discovered are ones {that a} fuzzer can be unlikely to ever discover. Fuzzers mutate small inputs, typically capped at 1 MB, and usually depend on code protection to information them towards bugs. While proving an entry level in a single library, Claude discovered a counter underflow in its copy of a decompressor that led to an out-of-bounds write, however solely on inputs of round 20 MB that had one uncommon, particular structure. Other bugs embody an out-of-bounds learn in a picture decoder that wanted a 64 MB enter and over 2 GB of reminiscence, an out-of-bounds learn in one other library that wanted a specific sequence of calls throughout two handles to the identical file, and a rediscovery of CVE-2026-56132 in libexpat, which wanted deeply nested enter. Claude additionally discovered logic bugs that by no means crash in any respect. While proving that one library was memory-safe, for instance, it observed {that a} characteristic for limiting which information an software can load isn’t at all times enforced.
The final objective of this mission was to realize a proof that the RISC-V-compiled fuzz checks had no remaining crashes to seek out. However, bugs just like the above present that the method has one other profit, no matter whether or not that objective is achieved: even simply trying this course of yields actual bugs that should be mounted.
Proving greater than reminiscence security
Proving {that a} fuzz take a look at has no extra crashes to seek out is extra vital than it sounds. It’s frequent for fuzz checks in real-world code to check for violations of significant high-level properties, reminiscent of encode-decode roundtripping, idempotence, algebraic legal guidelines, differential testing, self-consistency, or equivalence to reference implementations. For instance, a fuzz take a look at for the LZO compression algorithm asserts that if you happen to compress an enter, then decompress it, the end result is identical as the unique. If the property doesn’t maintain, this system crashes—so proving the take a look at by no means crashes is equal to proving the property itself.
This may also happen even when the properties are usually not instantly specified by the developer. For instance, to ensure that Claude to finish its OSS-Fuzz proof for cpp-httplib, it was essential to rule out the potential of a stack overflow as a result of an excessive amount of recursion within the std::set destructor. This recursion depth is bounded by the utmost depth of a tree, so Claude needed to show (on machine code!) that libc++’s red-black tree rebalancing algorithm is appropriately optimized to maintain the tree’s depth logarithmically bounded.
Other formal verification case research
Formal verification is an expansive area. The fuzz-test-to-proof instance above is one occasion of LLMs making formal verification extra broadly usable by instantly making use of proofs to machine code.
We’ve additionally seen success utilizing LLMs with formal verification in different methods. For instance, we requested Claude to jot down a proper spec of RFC 1950, the technical doc that defines the zlib compression file format. Then, we had Claude show that the zlib implementation within the Linux kernel appropriately implements that spec. As with the examples above, Claude proved this property on the binary degree, besides as a substitute of RISC-V, Claude instantly proved the x86-compiled binary utilizing Claude-generated (and closely examined) formal semantics of the x86 ISA.7 We then repeated this course of for half a dozen different broadly used libraries. Along the way in which, we discovered some minor (unexploitable) bugs in nook circumstances, that are within the means of being filed upstream. We draw two conclusions from this train: (1) these extraordinarily well-tested codebases are already virtually absolutely appropriate, and (2) it’s doable to show end-to-end correctness properties about actual present codebases.
In one other experiment, we requested Claude to develop an interpreter for a big subset of Python in Rust, and to show (utilizing Verus, a verification software for Rust) that it adheres to the CPython semantics outlined in an educational paper. We then measured the adherence to CPython’s habits empirically, working over 1.7 million randomly generated Python packages, discovering similar habits with CPython in 99.95% of checks, with remaining take a look at variations as unsurprising identified nook circumstances.
We additionally discovered points in a number of broadly used and important purposes through formal verification makes an attempt of easy safety properties. In one in every of them, we found a beforehand unknown logic bug that had been latent for greater than a decade. During an effort to confirm a broadly used PDF reader, we discovered as many safety bugs in a single week as are usually reported in a 12 months.
See the Appendix for extra particulars on a few of these efforts.
This is just the start
One of the important thing limitations of LLM-assisted formal verification is that the proofs can take a whole lot of tens of millions of tokens to provide. Cost-efficiency is essential if our objective is to make these strategies obtainable to all the software program ecosystem. Fortunately, there are compelling causes to anticipate effectivity to enhance.
Newer fashions want fewer tokens
We constructed 36 small verification duties from real OSS-Fuzz code. Opus 5.5 proves half of them with about 40% fewer tokens than Opus 5. We anticipate this development to proceed as fashions are educated on lengthy verification duties.
Proofs might be reused
When brokers work individually, they usually find yourself duplicating a variety of effort. Proofs, like software program, are recursively constructed from smaller proofs—and the smaller the proofs are, the extra reusable they are typically. To measure the affect of this, we let brokers copy one another’s proofs as they labored on proving their very own targets. When given entry to this shared workspace, brokers wanted 17% fewer tokens than after they labored alone, and a few brokers even succeeded after beforehand failing in a solo try.
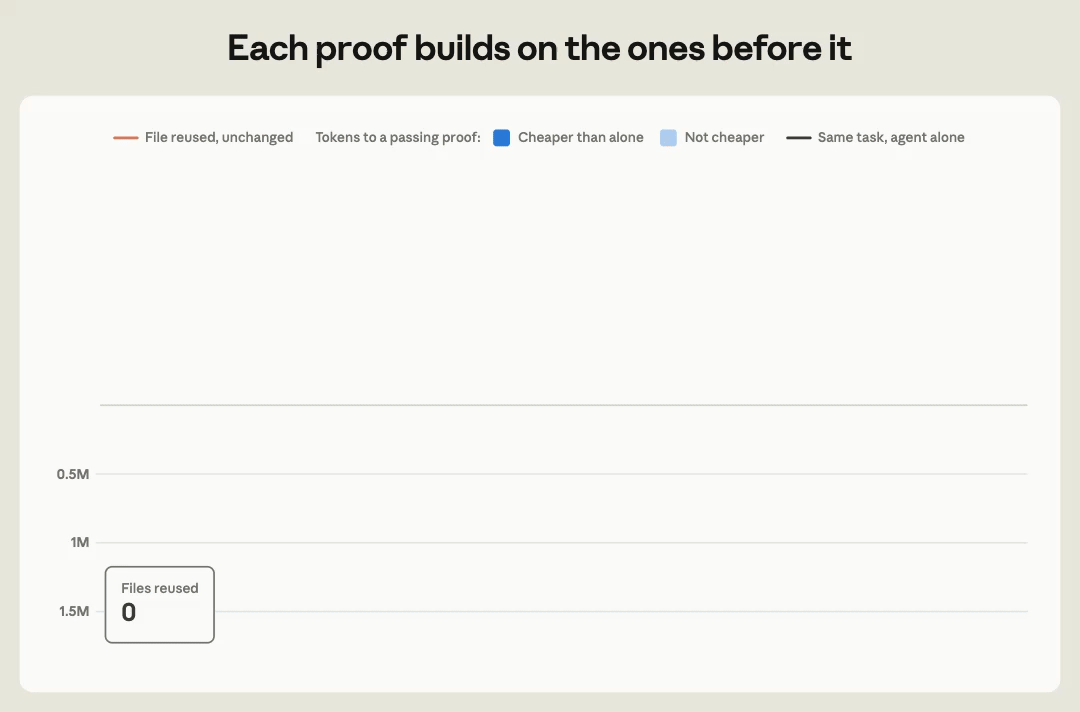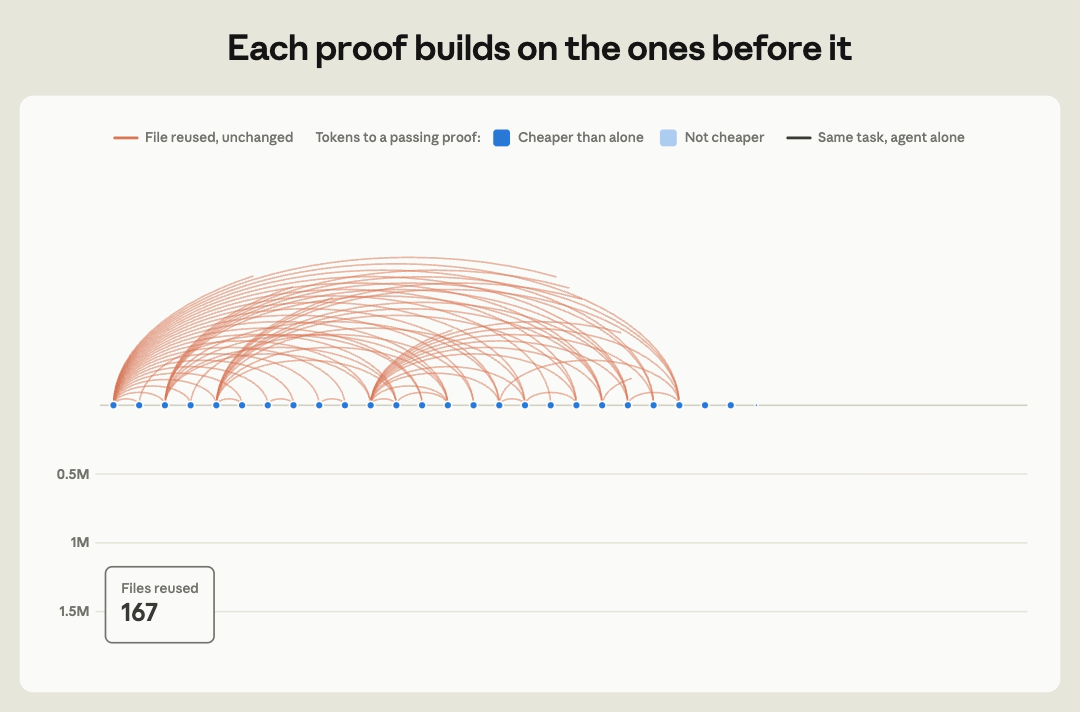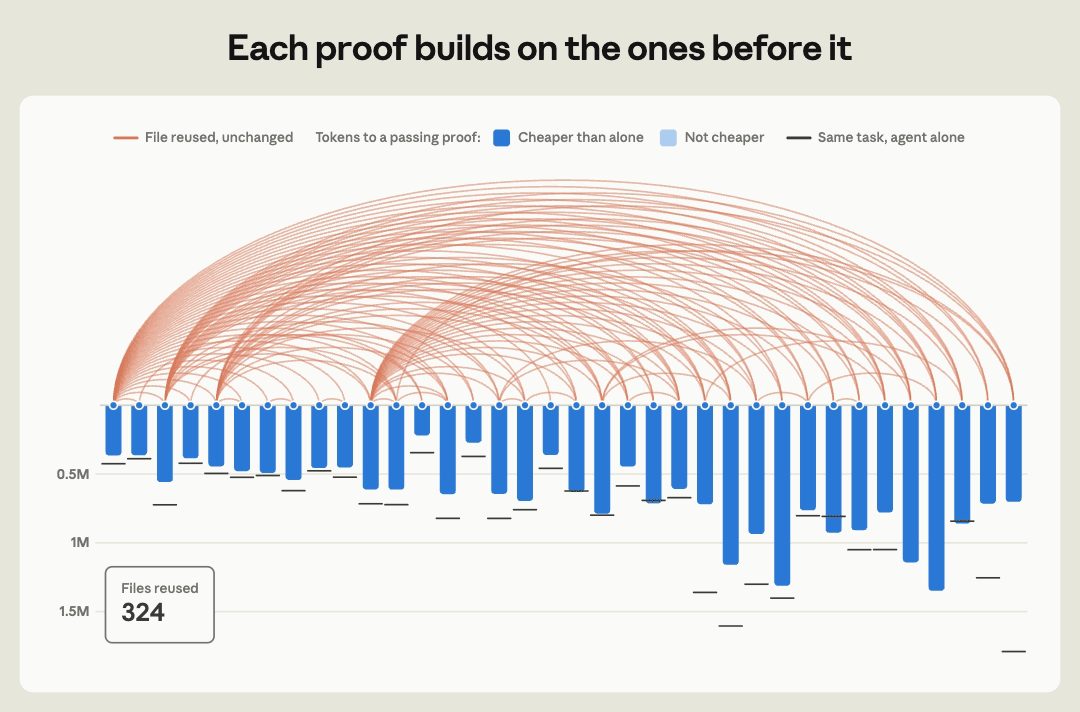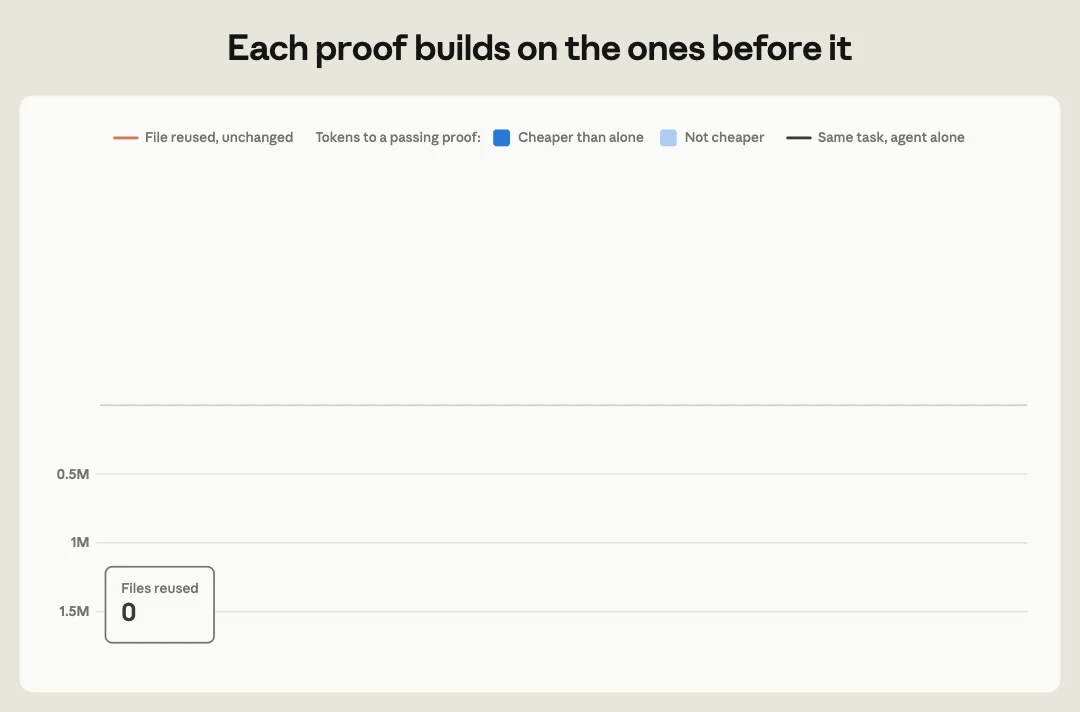
We noticed the identical phenomenon occurring at scale throughout our OSS-Fuzz proof effort. Most of a proof issues code that each program incorporates (notably initialization of the C runtime and AddressSanitizer), so very totally different packages can find yourself with considerably overlapping proofs. Agent groups took benefit of this by copying one other crew’s completed proof after which adapting it to their very own program (Figure 6).
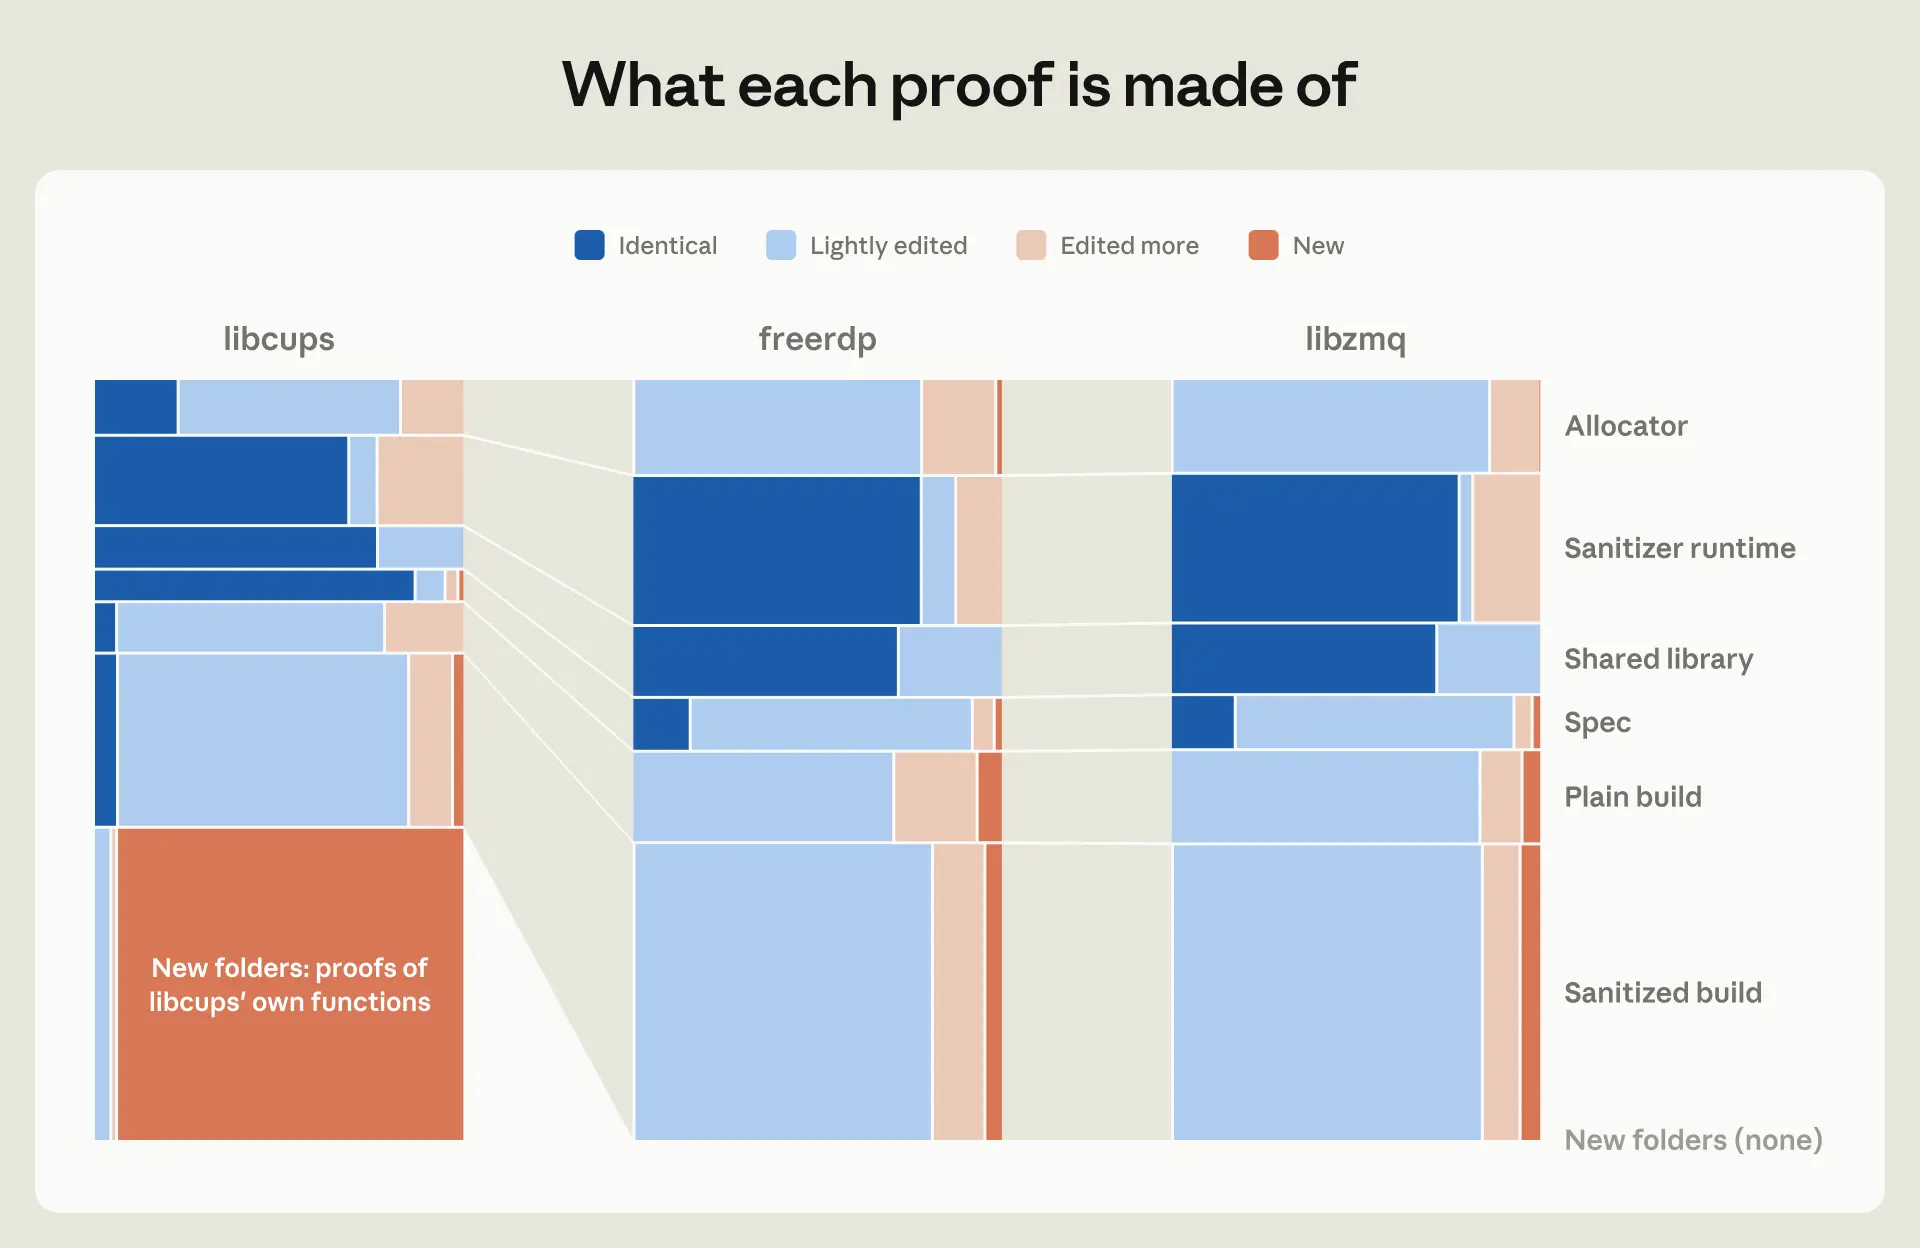
This reusability of proofs is how Mathlib, a shared library of formal arithmetic in Lean, grew to just about 300,000 theorems submitted by over 700 contributors: every new proof builds on the prevailing physique of labor. We amassed an analogous physique of proofs in the middle of our OSS-Fuzz effort, a few of which we’re together with in our launch (we aren’t releasing proofs that will reveal an unpatched bug within the open-source software program).
As we graduate from these preliminary experiments, we’d like a method for verifying the large physique of present software program, beginning with essentially the most essential dependencies. As we’ve proven, this may be achieved at scale through the use of generic specs and dealing on the binary degree, sidestepping the necessity to rewrite whole codebases in one other language.
This method additionally facilitates the reuse of proofs at package-level granularity, which implies that every dependency solely must be verified as soon as. Dependencies comply with an influence regulation: proving even a small set of shared libraries makes an enormous swath of software program possible to show. For extra particulars, see Theorem’s roadmap for verifying the whole thing of the Nix ecosystem, which incorporates essential roads like glibc, OpenSSL, and cURL.
Limitations
In follow, formal verification can typically show much less in regards to the safety of the code than we wish.
“Formally verified” doesn’t imply “bug-free.” Claude can write a proof exhibiting {that a} compiled program’s habits satisfies the necessities of a proper spec (which is verified by an exterior proof checker). However, a proof checker can’t let you know whether or not your spec matches actuality. To match actuality, the spec should appropriately embody and mannequin all the things in regards to the real-world machine that the verified program runs on, together with the CPU and working system. When bugs present up in verified code, it’s as a result of the spec, or the assumed semantics of the machine, differs from actuality. Fortunately, this additionally means we all know the place to search for remaining bugs, and easy methods to design a system the place these still-possibly-buggy gaps are minimized. Below are the methods this is applicable to our proofs, and concepts for future work that might shut these gaps.
The actual machine does one thing the mannequin doesn’t describe. Our proofs are about single-threaded, static RISC-V binaries linked in opposition to musl libc. However, most individuals run these libraries on x86 or ARM and dynamically hyperlink them in opposition to glibc. To shut this hole, we’d want system fashions that extra intently resemble deployed programs. For instance, a step towards this could be producing correct semantics for x86.
The declare could not cowl all the things we care about. We proved {that a} crash by no means triggers for any enter beneath 64 MB on many fuzzing entry factors in Google OSS-Fuzz, together with ASan crashes. However, ASan doesn’t detect all reminiscence security bugs, and we didn’t confirm all of the entry factors for every library. Even if we had, the entire library wouldn’t be lined by verifying all entry factors (particularly if there may be lifeless code). Additionally, actual packages may misuse the library, resulting in reminiscence corruption within the caller. To shut that hole, we’d have to specify what callers should do for every public operate, and callers must strictly adhere to it.
We anticipate that as we study extra about leveraging LLMs for formal strategies, and as fashions proceed to enhance, these limitations will turn out to be tractable, and we’ll have the ability to confirm a a lot bigger share of the code we rely on.
Conclusion
The trajectory is obvious: formal verification, which was traditionally sensible just for bespoke expert-crafted ensures in essentially the most safety-critical code, will quickly be as sensible as fuzzing is in the present day for nearly all manufacturing software program. Just like static varieties, testing frameworks, and different correctness tooling, verification will mature from “bolted-on” to “built-in,” pushed not solely by LLMs but additionally by improvements in language design and improvement workflows.
In in the present day’s planet—the place LLMs mechanically scan for and discover more and more extra code vulnerabilities—we should use processes that may assure code safety properties. LLM-scaled formal verification is a promising method towards securing these ensures at a scope and scale that have been beforehand unattainable. We encourage others to experiment so we will collectively construct a planet by which sturdy software program has proliferated very broadly and software program bugs are a well-understood and shortly addressable rarity.