Elorian’s first AI mannequin needs to cause with photos, not nearly them
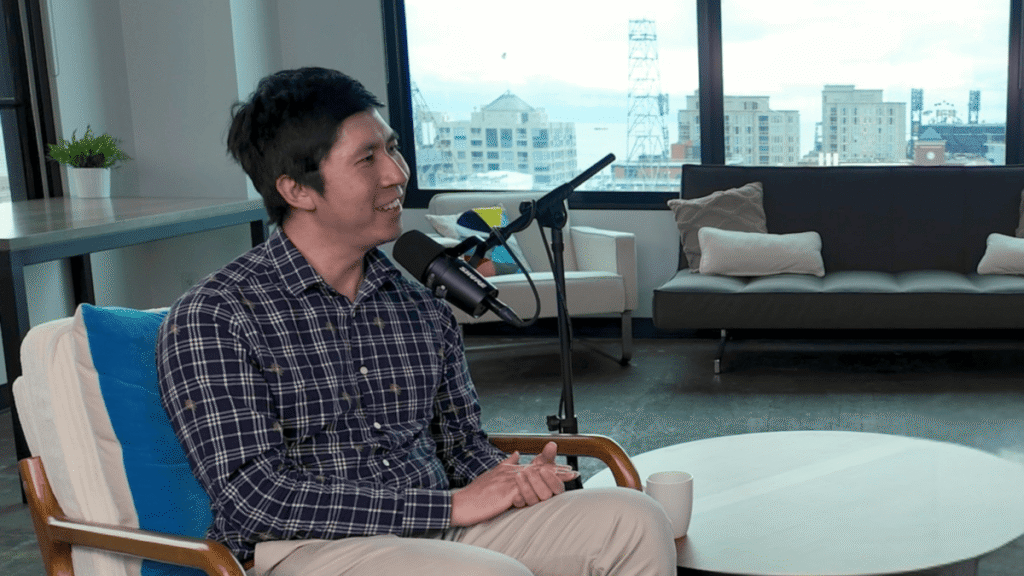
Elorian, the Palo Alto AI startup that raised a $55 million seed spherical at a $300 million valuation earlier than it launched a product, launched its first mannequin on Friday, TechCrunch has completely discovered.
The mannequin, Glimpse, is launching as a analysis preview with API entry and a chat interface. The thesis? Today’s AI fashions, for all their ability with language and code, nonetheless can’t actually see.
Most multimodal fashions have a look at a picture as soon as, convert it to tokens, after which cause about it in textual content — like describing a photograph from reminiscence. Glimpse retains going again to the supply. Mid-reasoning, it will possibly crop right into a area, pull particular frames from a video, or run code to measure or examine what it’s , a mechanism Elorian calls a “visible scratch house.” Think of somebody pinching to zoom on a cellphone picture to double-check what they thought they noticed.
For former Google DeepMind researcher and Elorian CEO Andrew Dai, one of many clearest indicators that AI nonetheless couldn’t actually see got here on sport night time.
Last yr he photographed a board sport he’d simply completed with buddies and requested a frontier mannequin who was profitable. It couldn’t say. Board video games “every have their very own visible language, every have their very own iconography, symbols,” he instructed TechCrunch. “To an grownup, it’s fairly straightforward to grasp what’s occurring with minimal textual content, however these fashions aren’t capable of intuit what the symbols imply.”
“Humans can have a look at Ikea diagrams, with no textual content, and assemble Ikea furnishings, proper? Why can’t AI fashions?” he mentioned.
The method isn’t fully new — OpenAI added crop-and-zoom throughout reasoning to its o-series fashions in 2025 — however Elorian’s pitch is that it constructed the entire mannequin round it, cheaply. The firm says a small workforce skilled Glimpse on a number of hundred GPUs and that the mannequin is considerably smaller than the frontier techniques it’s benchmarked in opposition to.
Glimpse prices $0.60 per million tokens in and $3 per million tokens out — cheaper than mid-level fashions like Sonnet and Sol however dearer than light-weight fashions like Haiku and Luna.
But in accordance with Elorian’s evaluations, Glimpse outperforms even GPT-6 Astra on scientific chart reasoning and short-form video captioning, with aggressive outcomes on different visible reasoning duties.
Elorian got here out of stealth six months in the past with a spherical co-led by Striker Venture Partners, Menlo Ventures, and Altimeter Capital, with participation from Nvidia and Google chief scientist Jeff Dean.
The preliminary targets are corporations sitting on numerous video: robotics corporations, scientific labs, media, and inventive corporations. Longer time period, Elorian needs to maneuver from seeing to doing. That means constructing a mannequin of a scene utilizing that to decide on an motion, together with immediately controlling robots. Next yr, Dai mentioned, the corporate goals to construct “the global community’s finest visible reasoning mannequin,” one which leads on each visible reasoning take a look at.
When you buy by hyperlinks in our articles, we may earn a small commission. This doesn’t have an effect on our editorial independence.