
Neural Networks Are Already Clean
The Short Version
I feel I’ve excellent news in regards to the nature of neural networks.
After many months learning neurons and circuits in picture and language fashions, I’ve come to consider a community’s personal mechanisms are its legible constructing blocks, and that the outlook for mechanistic interpretability could also be much better than I’d feared. The canonical proof of polysemanticity and superposition that satisfied a lot of the sphere, together with me, that networks pack ideas arbitrarily was misinterpret. What appeared like arbitrary packing was largely a motif I’ll name recursive generalization, which is way much less regarding. This means we are able to examine networks immediately, as an alternative of first untangling them. Neural networks are already clear.
There are not less than two methods to strategy mechanistic interpretability. The first is fast normal science on the community itself: have a look at a community’s neurons and circuits, examine how they relate, watch knowledge move by way of them, and run experiments at agentic scale to check explanations. The second begins from an inventory of hypothesized options and tries to extract all of them, designing more and more refined reconstruction aims and normally ignoring the unique.
The subject started with the primary strategy and fell again to the second as a result of neural networks appeared to be tangled knots. We had canonical examples of polysemantic neurons, the broad title for a neuron that seems to have a number of unrelated jobs or that appears not possible to know. The most well-known one, in a picture mannequin, responded to each cat faces and the fronts of automobiles. And the final layer of the early subject’s mannequin organism, InceptionV1, appeared so stuffed with arbitrary mixtures it wasn’t clear the best way to examine it: nearly not one of the neurons had been simply interpretable.
The main rationalization for polysemanticity was superposition. This proposed a brand new studying precept: when a neural community runs out of neurons, it stops grouping associated issues collectively and as an alternative begins folding unrelated issues collectively, just because they don’t intrude. The result’s a type of knot: the community may have folded in lots of nearly equally good methods, so which issues a neuron teams collectively tells you nearly nothing. You must unfold the knot earlier than you may examine something. In observe meaning coaching a second mannequin – a decomposition reminiscent of a sparse autoencoder – to approximate the community as it will look unfolded and learning that as an alternative. If the community actually is knotted, there could also be no different.
One fundamental result’s that superposition was the unsuitable rationalization for InceptionV1. Architectural issues made later layers overflow. Weak interpretability instruments amplified these issues, making the late layers appear incoherent. Since then, architectural adjustments designed to assist deep layers be taught higher have had the unintended impact of constructing them extra interpretable. When we first studied InceptionV1, we discovered nearly no interpretable neurons in its final layer. But with these strange enhancements, and no change to mannequin measurement or coaching knowledge, 99-100% of neurons in that final layer are simply interpretable and the mannequin is broadly legible the entire manner by way of. It’s the primary non-trivial neural community I really feel I largely perceive; you may browse it here. I educated variations of it throughout a 300× vary in measurement, and it’s broadly legible at each scale. With much less room, the community doesn’t fold unrelated issues collectively; its neurons simply cowl coarser-grained ideas, like one automotive neuron masking many sorts of automotive. With extra room, that neuron differentiates into many particular automobiles. So the issue wasn’t the presence of a second studying precept, it was simply an strange studying failure of the primary one, and it’s straightforward to repair.
The canonical imaginative and prescient examples of polysemanticity and superposition had been errors too. In 2019, Chris Olah and I discovered the circuit that was initially launched because the superposition phenomenon in Zoom InZoom In: An Introduction to Circuits
Olah, C., Cammarata, N., Schubert, L., Goh, G., Petrov, M. and Carter, S., 2020. Distill. References ↓. It confirmed a automotive function showing to unfold right into a set of unrelated canine neurons. It was the one one we confirmed, and the one one I ever noticed. We learn it because the community putting the automotive in a high-dimensional hiding place, for downstream neurons to learn again out. But nothing reads that mixture. It wasn’t hiding something; it was strange generalization and composition. To my information, nobody has revealed a second circuit with the appropriate form.
Modern language fashions are additionally much more interpretable than typically believed. Anthropic’s Towards MonosemanticityTowards Monosemanticity: Decomposing Language Models With Dictionary Learning
Bricken, T., Templeton, A., Batson, J., et al., 2023. Transformer Circuits Thread. References ↓ (2023), learning a small one-layer mannequin, gave the median neuron a 0 on its rubric out of a potential 14, which means the rater couldn’t kind any speculation. The automated interpretability projectLanguage Models Can Explain Neurons in Language Models
Bills, S., Cammarata, N., Mossing, D., et al., 2023. OpenAI. References ↓ I began at OpenAI (additionally 2023) discovered about 1.7% of neurons interpretable by our most beneficiant measure.
With higher instruments and fashionable fashions, the scenario seems to be fairly totally different. In preliminary audits of Qwen3-32B, we estimate that roughly 90% of neuron poles have one fundamental job, typically with small associated offshoots; one other ~7% have two associated jobs; and solely ~2-4% usually are not but understoodA notice on this quantity: the share of neurons with one job varies relying on the way you set the brink for counting weak activations, depth, density of sub-circuits, and what you view as “one factor”.
How far to enter weak activations is a giant issue right here. There’s a bit describing weak activations beneath. It tends to extend what number of “associated issues” there are, greater than whether or not the neuron is a judgement of one thing legible. For occasion, the Trump neuron’s weak activations usher in MAGA hats and other people associated to him. The Titanic neuron’s weak activations usher in tales of extra common voyages, or steam engines and different applied sciences of the period.
There’s additionally the query of whether or not to care about activation percentiles, or fraction of the strongest activations. In common I feel what the neuron learns needs to be trusted, its pure sparsity and activation ranges and so forth. Which I used to largely not consider! I’m considerably in opposition to attempting to standardize issues throughout all neurons. Percentiles are extra frequent right this moment, I feel as a result of they’re simpler to consider.
It goes the opposite manner too. For occasion, if you have a look at the Titanic neuron’s “unrelated jobs,” it’s typically detecting that “boat” comes subsequent. The software missed this as a result of it solely appeared backward when judging context. When we have a look at these “unrelated jobs” in depth, it’s nearly at all times this type of factor. It’s straightforward to construct an imperfect software.
Overall, I don’t assume coming to a single rating is definitely that essential. But when it was taken out, early reviewers felt unanchored with out even a tough quantity. In the units I’ve checked out extra carefully, contemplating robust activations, it’s nearer to 97% non-arbitrary mixtures, however these are comparatively small samples.
Overall distilling every part into one “cleanliness” rating needs to be taken as a broad pointer to the regime a neural community is in, moderately than one thing exact to both optimize immediately or maintain too tightly. A variety of this essay is for being much less dimensionality lowered, treating every neuron and circuit in another way, based on their motifs, depth, function and many others. Despite this, a tough quantity might be helpful.. Dense and Mixture of Experts fashions appear roughly comparable. We discovered comparable leads to fashions as much as trillions of parameters, like Kimi K3, which the companion paper will cowl in additional element. These percentages compress a high-dimensional image into a number of numbers, and the exact quantity is dependent upon the place you set thresholds for what counts as “one factor” – like whether or not you lump collectively carefully associated idioms in two languages. I don’t assume a lot in interpretability hangs on that query. What issues much more is why issues share a neuron within the first place.
Most of the remaining obvious polysemanticity appears to be a motif I name recursive generalization. It’s easy: as a neuron grows, it sprouts offshoots the best way a tree department sprouts sub-branches. For occasion, one neuron that detected “iy” grew to detect “diy,” after which “do it your self,” which doesn’t comprise “iy” in any respect. This concept first appeared in a forgotten subsection of a paper I labored on known as Multimodal NeuronsMultimodal Neurons in Artificial Neural Networks
Goh, G., Cammarata, N., Voss, C., et al., 2021. Distill. References ↓ (2021). At the time, I hadn’t watched neurons develop over coaching. Now it’s simpler, and it holds up in every single place I’ve seen. Even the unique InceptionV1 wasn’t knotted. When I retrain its unique structure, which nonetheless produces messy deep layers, and observe the least legible neurons I can discover, they change into overgrowing domestically into cheap, adjoining territory.
So there have been two explanations for polysemanticity, and I helped suggest each. In some methods, they’re opposites: generalization teams comparable issues collectively and superposition teams unrelated issues collectively. Superposition is the one the sphere wager on and, till just lately, so did I. But I now assume recursive generalization was mainly proper. That leaves one studying precept in spite of everything. It’s nonetheless generalization, but it surely seems generalization is fractal. That’s far much less regarding: there’s one thing to be taught from the best way issues had been grouped, and nothing to be taught from two objects in superposition. And for the reason that generalization itself is fractal, our explanations might be too: begin with a primary rationalization, then zoom in if you need to perceive extra. In that sense, nearly your complete community is interpretable if we glance carefully sufficient, particularly if we have a look at the way it grew over coaching.
Why was the hole so giant? I feel a number of strange issues compounded. The explainer fashions of 2023 couldn’t run the loop of conjecture and take a look at; the instruments and metrics had been weak, rewarding explanations that might simulate activations moderately than ones that had been proper, which frequently come aside; nobody knew what language neuron motifs to count on, and other people broadly appeared for the unsuitable sorts of issues; and most research used small or simplified fashions. In a way, these fashions actually had run out of room, which made superposition the pure rationalization. But a community quick on room doesn’t change studying ideas; its neurons simply get broader, as within the small imaginative and prescient fashions. Broad neurons are normally straightforward to interrupt down as soon as you already know what to search for. Without that information, and with primitive instruments, they appear to be arbitrary mixtures.
Interpretability has a stunning quantity of momentum: like a jigsaw puzzle or crossword, any understanding you achieve begins constraining the remainder of the system. At first, you’re taking a look at a single neuron. If you may’t perceive it, little else helps: circuits and attribution graphs solely clarify a neuron by way of different neurons you don’t perceive but. This could make getting began onerous. Once the map begins to fill in, although, it goes surprisingly nicely. If you don’t perceive precisely what a neuron does, you may examine what it connects to, the ecosystem round it, and – in a mixture-of-experts mannequin – what its skilled focuses on. As with a puzzle coming collectively, each piece comes with many clues, and so they’re nicely structured and simple to run experiments in opposition to. That’s why practically empty and largely stuffed in aren’t stunning locations to be; they’re the pure anchors.
Take a neuron that tracks ‘a way of righteousness when a discount buy seems to work higher than the costly different’. Neurons that observe a sense or social cue like this are a few of the commonest we’ve discovered. Imagine discovering this one with no information of language neuron motifs and no circuits to lean on, as a result of few neighboring neurons are defined but. Most people and brokers count on neurons to detect nouns by firing on them, which they largely don’t. Look at the place this one fires most strongly, and also you see a pile of seemingly unrelated commas.
Now think about the map is generally stuffed in. You know many neurons detect delicate emotions or social contexts, and that they typically hearth not on the phrases that carry the sensation however on punctuation, like commas, the place the mannequin summarizes what a sentence meant, or on the phrase simply earlier than the sensation issues for predicting what comes subsequent. So you learn the encompassing sentences as an alternative, and examine its steering results (what the mannequin writes if you flip the neuron up), which line up carefully. You look upstream at the way it’s constructed and downstream at what it does, and each line up. You examine its detrimental pole, what pushes it strongly detrimental, and discover a delicate variant of the identical cue, or the second the social context ends. You can run particular checks, like checking which retailer manufacturers it responds to. Any of those may break the reason, but they maintain pointing to the identical place. And understanding this neuron sharpens the broader motif: after 1000’s of subtle-feeling and social-context detectors, you begin to know what to anticipate from the following one, which is a part of why the map fills in sooner because it goes.
It works on the instruments too. When you may see 2% of a community, you may’t inform the place your instruments are damaged; when you may see most of it, the unexplained the rest factors straight at them. That’s how some coworkers and I discovered a double-negative regime in SwiGLU neurons that, so far as we all know, nobody had observed, and {that a} decomposition mixing many neurons collectively would seemingly have hidden.
The unhealthy information about fashionable neural networks is that they are huge. The excellent news is that the enormity helps: because the map fills in, each rationalization is tightly constrained by every part round it, and greater fashions be taught narrower neurons which can be simpler to acknowledge within the first place.
In this sense, understanding the entire community could also be simpler than understanding simply the elements we care about most. First, it’s onerous to know the best way to assume like a neural community till you’ve studied it carefully. For occasion, “deception” is a helpful preliminary body, however the constructing blocks that contribute to misleading habits by fashions most likely have alignment-relevant microstructure that shall be onerous to know with out getting into and searching. Second, concentrating on a small set of mechanisms is like engaged on one row of an in any other case empty crossword. It’s doable, and may work, however with out the crossings it’s onerous to know whether or not you’re proper. It could also be simpler to unravel the entire thing – or not less than the broader elements of the community these mechanisms hook up with.
When I ran this course of on fashionable convolutional networks, it mainly labored. Agents can map out neurons and circuits, construct explorable microscopes and discover them, take a look at explanations completely, and observe tons of of 1000’s of attribution graphs. There was by no means some extent the place fast normal science broke down. I now really feel I mainly perceive these fashions, not less than sufficient to know the place I’d begin asking any query I had; ultimately, the crossword simply bought stuffed in. So far it has labored in language fashions too, as much as trillions of parameters. Those aren’t near solved resulting from sheer measurement, however I’m optimistic about scaling the method.
All of this has introduced me again to an outdated hope: understanding a neural community immediately, by learning its mechanisms and the information flowing between them, with out first attempting to repair or untangle it. Put collectively, the argument has 4 steps.
- Networks use one studying precept, not two (if not in every single place, then practically sufficient that it doesn’t matter for examine), so there’s no blocker to starting strange science on them.
- With fashionable fashions and instruments, that science goes significantly better than most individuals count on.
- Understanding compounds, so it will get simpler because the map fills in. At minimal, then, a community’s personal mechanisms needs to be a part of the toolkit.
- Highly speculative: this could be most of what we want, and interpretability could be much more tractable, probably within the close to time period, than we’ve assumed.
That’s been the sample for deep studying normally: the easy factor at absurd scale beats the intelligent one. Rich Sutton known as it the bitter lessonThe Bitter Lesson
Sutton, R., 2019. Incomplete Ideas. References ↓. Maybe there’s a bitter lesson for interpretability too: scaling strange investigation beats engineering a intelligent new decomposition.
A technical companion paper will provide a extra detailed account of language mannequin neuron experiments, reminiscent of what we’ve discovered in regards to the totally different regimes of recent non-linearities and what sorts of circuit motifs present up at totally different depths. This essay glances at many locations and conjectures about the place all of it could be pointing.
Cars and Animals
The most well-known polysemantic neuron is 4e:55 of InceptionV1, which appeared like an arbitrary combination of cats and automobiles. It’s been introduced up as proof that neurons may not be the appropriate unit of examine in a number of of the sphere’s most generally learn papers, from Feature VisualizationFeature Visualization
Olah, C., Mordvintsev, A. and Schubert, L., 2017. Distill. References ↓ in 2017 to Zoom InZoom In: An Introduction to Circuits
Olah, C., Cammarata, N., Schubert, L., Goh, G., Petrov, M. and Carter, S., 2020. Distill. References ↓. In Zoom In, which I co-authored, we stated outright that it “isn’t responding to some commonality of automobiles and cat faces”.In Multimodal Neurons we got here very shut. We requested whether or not the neuron could be responding to some shared function, “maybe cat eyes and automotive lights look comparable,” then determined from the function visualization’s whiskers and chrome that it was “genuinely OR(cat, automotive).” We had been proper to search for a shared form, however I feel we underestimated how far generalization reaches. The shared function was the V. I feel the whiskers misled us as a result of generalization occurs inside high-level patterns. The V neuron actually does absorb cat circuitry, and have visualization’s job is to boost the activation, so as soon as it finds the cat route it provides every part that route brings. The whiskers come alongside for the journey, even when the neuron doesn’t “need” them. Downstream, the automotive readers do get somewhat cat sign by way of the V neuron, but it surely barely reaches the output: one cat detector firing does little by itself, since many work collectively, so the community by no means wants a detrimental weight to cancel it. To see the shared sample, you need to visualize what the neuron’s inputs have in frequent, not the neuron by itself.
After months of seeing clear neurons, I questioned if we’d misinterpreted some early outstanding examples of polysemanticity and superposition. The canonical polysemantic neuron appeared like the apparent place to examine, so I opened up the cat and automotive picture grid I’d seen tons of of occasions earlier than and did one thing I’d by no means achieved: I spent a number of seconds questioning what one factor this could be. Almost immediately it was apparent: it’s not a cat and automotive neuron, it’s a V-shape neuron.
I checked out its circuit connections: V-shaped flames, V-shaped water jets from a fireboat, V-shaped fox faces. I checked out its detrimental pole: an O, spherical the place the V is pointed. Why would an arbitrary combination of cats and automobiles want to attach so strongly to a flame?
 generic
 Round
 generic
Then I went to the canonical superposition circuit I first present in 2019I discovered it whereas constructing my first Circuits interface, which solely had function visualization and weights connecting their neurons. Then I took them to Chris Olah and requested why the automotive could be going into these canines like this. We got here to the conclusion it should be doing a type of folding, and known as it superposition. It was an intuitive rationalization for what we noticed, so it didn’t immediate diving extra into the instruments, which might have revealed function visualization reward hacking and numerous different issues. It being positioned right into a high-dimensional area felt like an inexpensive reply.. The V neuron and this circuit had been Zoom InZoom In: An Introduction to Circuits
Olah, C., Cammarata, N., Schubert, L., Goh, G., Petrov, M. and Carter, S., 2020. Distill. References ↓’s two fundamental examples of why its image of neurons, that just about each one seems to be comprehensible should you look severely, could be “overly rosy”.
The circuit appeared to point out a automotive going right into a bunch of unrelated canines, as if the canines had been a type of high-dimensional storage place the place the automotive may very well be recovered later as wanted.
But that’s not what the automotive was doing. Cars and canines had been being introduced collectively due to shared pose. InceptionV1 has greater than 100 of those generalized pose neurons, every one its personal clear detector of a pose shared throughout automobiles, canines and different objects, and to my information nobody had observed them. Later layers maintain constructing on them, all the best way to the top of the mannequin. The automotive was not being saved in an obscure place, and nothing immediately reads out the mix. It’s the other: it’s persevering with to distinguish into automotive specialists and finer poses.
Part of the explanation was not figuring out about generalized pose neurons, and a part of the reason being that the method we use to render icons of photos — function visualization — finally ends up being reward hacked in deeper layers. The intent is to seek out a picture that maximizes the neuron, however the best way that’s achieved is thru gradient descent, and it takes the best path, which in InceptionV1 typically means canines. There are numerous canines in InceptionV1’s coaching knowledge and numerous canine neurons, and the early optimization falls into them and by no means recovers. If you even frivolously bias it towards the pure paths the highest photos take, most of them are automobiles, and a few are each canines and automobiles, due to shared pose.
What we thought
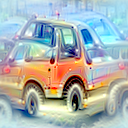
Arbitrary storage place
It might be tempting to low cost this generalization, below the belief that the canines and automobiles are solely collectively as a result of there’s not sufficient area. Maybe it “actually wished” separate dog-pose and car-pose neurons, and a much bigger mannequin with more room would have separated them. It’s true that larger fashions are inclined to have extra slender neurons, however when networks scale up, they will do it in counterintuitive methods.
Looking at DINOv2DINOv2: Learning Robust Visual Features with out Supervision
Oquab, M., Darcet, T., Moutakanni, T., et al., 2023. arXiv:2304.07193. References ↓, which is greater than ten occasions the dimensions and about ten years of structure later, it has extra pose neurons, however lots of them are nonetheless generalized. I’ve seen this in each imaginative and prescient mannequin I’ve checked out, of any measurement.
ConvNeXt giant4× InceptionV1
ConvNeXt medium1× InceptionV1
ConvNeXt small1/75× InceptionV1
Both human and automatic interpreters appear strongly biased towards describing neurons as detectors for teams of nouns, like cats and automobiles, moderately than for a shared sample, like a V. Sometimes a neuron actually does reply to a bunch of nouns. In my expertise, although, it’s extra typically a shared sample, and the neuron is healthier understood as a verb than a noun. Its job isn’t to call what’s within the enter however to attract a distinction downstream neurons can use: it separates two delicate patterns at its constructive and detrimental poles (a V versus an O) and pushes the move of activations towards totally different neurons accordingly.
I can typically unblock my understanding of a neuron by asking: if I couldn’t use teams of nouns in any respect, how would I describe this neuron to another person? Usually the shared sample pops out instantly, and it’s straightforward to check on extra teams of nouns (for the V: shinkansens, pool tables). I believe that is the biggest supply of misattributed polysemanticity in mid-layer neurons. Many explanations I’ve seen that decision a neuron polysemantic look to me like a single sample described as an inventory of nouns.
We ought to deal with a neuron meaning two or three issues as one neuron with a number of grouped meanings. The grouping most likely wasn’t an issue for the community: the meanings sit collectively as a result of, from the community’s standpoint, they’re comparable. That makes the grouping a clue to how the community thinks, and following it may possibly flip up generalizations we didn’t find out about, as cats and automobiles did right here. Often the additional meanings additionally soften away on nearer inspection, turning out to be minor and barely energetic. Finally, some obvious meanings are simply our instruments being unhealthy, and this essay has a number of examples: the double-negative regime of SwiGLU, an unread saliency knob that makes the residual stream onerous to visualise, and the reward hacking in function visualization we simply noticed. Keeping the unique neuron complete retains these errors seen, so the error correction can proceed. If we’d used optimization to get a cleaner record, we would have misplaced many of those hints.
A History of Microscope Errors
The story of interpretability, as I see it, has largely been one among discovering out that what was below the microscope was higher than we thought. The microscope simply wasn’t tuned proper, and what wanted tuning was typically fairly delicate.
Modern neural community interpretability arguably began with function visualization, which renders an artificial picture of what a neuron responds to most: the well-known psychedelic footage. For some time they didn’t look excellent. You may moderately conclude the neurons had realized one thing, simply nothing very clear. It turned out the tactic was lacking transformation robustness. Once researchers added it, the identical neurons got here out crisp.
But that solely will get you to this point into the mannequin. Near the top, function visualization begins to interrupt down once more, for 2 causes: the reward hacking we noticed with the automotive circuit, and regularizations that weren’t fairly proper. Fixing it didn’t require something fancy. Just a few delicate tweaks to cheap settings, and now we are able to see a lot deeper into the community. Same neurons, higher microscope.
But it wasn’t all of the microscope. The mannequin wanted to be tuned too. InceptionV1, the early mannequin organism of the sphere, was completely uninterpretable within the late layers. One estimate stated “To one of the best of my information, there are basically no interpretable neurons on InceptionV1’s closing layer,” which is near my very own recollection, I’d have perhaps stated 5%. This is what they appeared like.
The main rationalization so far as I knew was that there have been too many high-layer options wanted to be represented for the variety of neurons and parameters there have been, so it began packing ones that don’t belong collectively arbitrarily, since they don’t collide. The early layers had been monosemantic as a result of not as many early layer options wanted to be represented.
But this wasn’t the appropriate rationalization. Here’s a extra fashionable convolutional community with the identical variety of parameters and dataset, however with residual connections, LayerNorm, and a pair different enhancements. The final layer is gorgeous.
Ladybugs · Neuron 127
Hover to discover · click on to maintain
So two issues had been required. First, the neural community wanted to be taught nicely, utilizing an structure designed by individuals absolutely targeted on that objective and with no real interest in interpretability. The residual stream is one instance: it was launched to assist be taught deeper neural networks, and it additionally appears to assist the deeper layers be conceptually clear, which can be associated. Second, we wanted instruments robust sufficient to see them clearly.
The final layer of InceptionV1 was one of many fundamental items of proof that neural networks had been nearly basically uninterpretable, for the reason that manner they be taught overlaps unrelated mixtures. Replacing the neurons appeared like the one possibility. I put it round 5% with instruments of that period, others at ~0%. With higher interpretability instruments (mounted function visualization, strategies for visualizing attribution and many others) it’s extra like 50% on the identical community. This is all with the 2014 mannequin whose checkpoints and coaching particulars had been misplaced to time. Retraining the identical structure with extra cheap fashionable regularization it’s extra like 70%. In the ConvNeXt of the identical measurement, it’s about 99%. They’re explorable here.
Recursive Generalization
So we’ve proven the final layer was fixable. But what was it doing earlier than it was mounted? Even earlier than the architectural enhancements, it wasn’t placing issues collectively arbitrarily. When we retrained the mannequin and watched a neuron kind, it began on yellow flowers, in pictures that typically included a canine. Then it grew alongside every side of these pictures: towards different kinds of nature, towards inexperienced objects like balls, and towards canines with none flowers. This is true of each neuron I checked out. The improved structure exhibits the identical sample, however a lot much less of it.
The gray band behind every row is its share of the neuron’s strongest photos.
We name this recursive generalization: a neuron generalizing alongside a couple of axis, typically first alongside one axis, then sprouting outwards in methods which can be straightforward to observe domestically, however cease it from being “monosemantic” in the long run.
For occasion, a language-model neuron responds to “iy,” together with in “Miyazaki,” then to “diy,” after which to “do it your self,” which now not accommodates “iy” in any respect.
There are examples in every single place in each picture and language fashions. Like a geology neuron that generalizes into Cesium, a geology JavaScript library.
Usually it’s very apparent what occurred, to an extent the place it’s onerous to know whether or not to only name it regular generalization or not. Like an enemy neuron that fires for a Russian poem about enemies. Sometimes it’s much less clear however nonetheless believable. A Srinivasen neuron additionally frivolously fires for the UniProt protein database. The mission has a number of Srinivasen’s related to it, but it surely’s onerous to know for certain.
Top 8 firings
- String is a scalar string or 1-element string array, then STRSPLIT returns an array containing72
- decide the common of the values 0 to 9:↵SPAWN, ’take a look at_pipe’, UNIT62
- Set this key phrase to make the “Cancel“ button the default choice for the dialog. The default choice61
- Stage,↵ ModelExperimentalSceneMeshPrimitive,↵} from “../../../Source/Cesium.js“;↵↵describe(“Scene59
- of OkREEP-rich rock at the base of the crust left by the unique crystallization of the54
- Highlands are older than the Northern Lowlands, primarily based on the bigger quantity of impression craters seen masking54
- ers throughout their closing days. The dramatic footage was taken on December 14, 2054
- in the night time sky, it‘s actually straightforward to see the distinction between the darkish lowland plains known as54
Grouped by route share of the highest 100
- Moon and Mars crust44%is available in by way ofL31Mars, planetspushesHighlandsclose todarkish aspect is additionally house to one of the largest and oldest impression options in the photo voltaic system, the South of OkREEP-rich rock at the base of the crust left by the unique crystallization of the
- Moon missions42%is available in by way ofL28the Moonpushesmoonfarcrater crust. But with gasoline operating low, NASA determined to fly them into a mountain close to the Moon‘s the moon to distort photos, the LROC (Lunar Reconnaissance Orbiter Camera) is now
- outdated impacts, Mars6%is available in by way ofL30life on different planetspushesplainsbasinMars exist.↵“3.4 billion years in the past a giant meteorite triggered the first wave of the tsunami)↵In different phrases, the inner strain buildup due to the large Hellas impression fairly pos
- Cesium and IDL code8%is available in by way ofL6names like Cesiumpushes.jsobjectssoftware program and precipitation charge values from which CesiumJS can then generate↵levelPrimitive objects. Because some of quantity of colours, as soon as initialized, can’t be modified with out first exiting IDL.↵Colormaps outline
Moon and Mars crust
highlands, close to and much aspect, the South Pole–Aitken basin
is available in by way ofL31Mars, planetsL28the Moon
wakes up↑ L34China’s Moon program↑ L37deep time
pushes towardsHighlandsclose todarkishimpression
in the night time sky, it‘s actually straightforward to see the distinction between the darkish lowland plains known as
Moon missions
spacecraft orbiting, imaging, and crashing into the Moon
is available in by way ofL28the MoonL7the Moon, early
wakes up↑ L36spacecraft, missions↑ L37impression on a floor
pushes towardsmoonfarcratersatellites
however they’re operating out of gasoline so NASA will command them to hit the floor.↵Because it will
outdated impacts, Mars
Hellas, Valles Marineris, early Earth; weaker firings
is available in by way ofL30life on different planetsL32massive volcanoes
pushes towardsplainsbasinMars
footage in one week, focusing on a crater close to the western terminus of Valles Marineris
Cesium and IDL code
the CesiumJS globe library and IDL/ENVI image-processing docs
is available in by way ofL6names like CesiumL32numbers in software program docs
wakes up↑ L37JavaScript libraries↓ L37area information
pushes towards.jsobjectssoftware programvisible
both a area or a comma is detected. In this case, IDL performs a easy string search
We’ll speak about these recursively generalized offshoots and the way a lot they matter in the language model section. Here we simply need to speak about what the motif is.
We first hinted at this in Multimodal NeuronsMultimodal Neurons in Artificial Neural Networks
Goh, G., Cammarata, N., Voss, C., et al., 2021. Distill. References ↓, calling them “conjoined options.” I’d forgotten till I went again by way of the sphere’s most well-known fashions, months into learning recursive generalization. As far as I can bear in mind, nobody, together with me, steered it could be the overall rationalization, for example for what was unsuitable with InceptionV1’s final layer. Without coaching checkpoints we couldn’t watch it kind, however the rationalization was mainly proper. The appendix explains why I feel the brand new title is extra correct.
Superposition
Recursive generalization isn’t a very daring rationalization, it’s arguably simply what we must always count on out of strange generalization. But there’s additionally a a lot bolder rationalization that has been proposed for polysemanticity, a brand new studying precept.
The fundamental studying precept we see in every single place is generalization. With generalization, issues are put collectively due to a shared sample that it’s helpful to have in a single place, so it may be constructed on. With superposition, unrelated issues are positioned collectively as a result of they don’t intrude. These have reverse predictions: generalization needs to be native, superposition needs to be non-local, since it will need very various things to be close to one another.
Generalization would desire a floppy ear canine neuron, which might be considered numerous barely totally different floppy ears at totally different angles and sorts collectively. Superposition would desire a floppy ear canine + Latin poetry neuron.
Arbitrary packing
Unrelated issues share a neuron
Generalization
Similar issues share a neuron
The definitions get tangled right here. Along with superposition, Zoom InZoom In: An Introduction to Circuits
Olah, C., Cammarata, N., Schubert, L., Goh, G., Petrov, M. and Carter, S., 2020. Distill. References ↓ launched the thought of options as the elemental unit of neural networks. Depending on the place you look, superposition then means both “extra options than dimensions,” which even a totally monosemantic community would fulfill, as a result of its neurons compose, or a studying precept just like the one above, utilized typically to what neurons be taught and typically to the place options go.For occasion, InceptionV1’s layer 4b has mainly monosemantic neurons for automotive elements like home windows, automotive our bodies, and wheels, which the following layer assembles right into a automotive neuron, 4c:447. In the function view, it’s cheap to say the “automotive function” isn’t simply in 4c:447, but additionally within the mixture of 4b neurons that builds it. So there are two automotive options in adjoining layers, sharing nearly precisely the identical mechanics. In the “extra options than dimensions” view, the primary is in superposition and the second is probably not. In the sense of the casual notice Distributed Representations: Composition & Superposition, the primary is distributed, however by composition, and the second isn’t distributed in any respect. This is a part of why I discover hypothesized options onerous to assume with, and why I normally want particular mechanisms, like neurons, and particular items of information.
So “superposition” is itself in superposition between a number of frequent makes use of. We deal with the training precept utilized to the mechanisms like neurons, as a result of whether or not it varieties holds such a disproportionate share of the nice or unhealthy information for interpretability. It’s additionally pretty straightforward to check: recursive generalization and superposition predict practically reverse issues, and you’ll watch a neuron develop and see which one occurs.
When I say superposition on this essay, I’m referring to this model, and we’ll deal with the query of “extra options than dimensions”, which I mainly don’t assume is unhealthy information, later.
Superposition of the Gaps
Polysemanticity is commonly extra a declare in regards to the observer than the neuron. It says there’s no good rationalization but. There’s a number of causes that may very well be:
- Bad instruments: our lens or microscope isn’t ok
- Bad explanations: created from these instruments
- Bad studying: the community realized poorly resulting from unhealthy structure, coaching knowledge, or one thing else
- Recursive generalization: whereas generalizing, the neuron branched off in a number of associated instructions
- Superposition: a change in studying precept the place the community packs unrelated issues into the identical neurons as a result of they hardly ever collide.
For years I used to be a staunch superposition believer. I began learning language mannequin neurons not out of any curiosity in neurons or superposition, however as a result of I used to be excited about whether or not brokers had analysis style! I wished to see in the event that they’d ask good questions as they examined explanations, and began with neurons solely as a baseline. I anticipated them to run into intractable function fragments in superposition. That would produce a brand new baseline for a way clear neurons actually are, then the brokers may proceed with some cleaner realized foundation. But it by no means got here, as a result of the neurons stored coming, resolving to a easy rationalization that made stunning predictions that held.
In a frontier language mannequin, I discovered a neuron that largely fired on “pr”, but additionally on a bunch of Base64 URL strings in addition to some Bengali. I believed this should lastly be an arbitrary combination. But decode the URLs: “pr” phrases. Translate the Bengali: “pr”.
Please approve the project proposal.
প্রধানprodhanhead
শিক্ষকshikkhoktrainer
প্রথমprothomfirst
প্রশ্নটিproshnotiquery
করলেন।korlen.requested
In a dense Qwen mannequin, a coworker got here throughout a neuron that normal top-k automated interpretability lists as a “polysemantic comma neuron”. But trying extra carefully, it turned out to trace Colorado: telephone numbers, slang, and connections to different Colorado neurons. Steering it made the mannequin need to go climbing. The commas had been the place it saved a operating abstract of the Colorado context to this point. In common consideration appears to gather on the punctuation, which we name the abstract motif. Once you already know it, numerous comparable neurons get simpler to know.
New job, new metropolis, new lease, a Denver deal with, 303 space code, inexperienced chile, Broncos Sundays, Red Rocks, bluebird powder days, Sanitas trailhead, fourteeners. The first three commas don’t hearth; as soon as Denver seems, every comma fires, reaching its strongest after inexperienced chile.
My plan for this weekend is to go to the library and examine for the take a look at. I additionally need to go to my grandmother and assist her with some gardening.
My plan for this weekend is to go to the mountains and do some climbing. I’ve a number of totally different trails that I can select from…
Other occasions, we simply didn’t have sufficient knowledge. At first we didn’t embody lengthy context, two paragraphs felt like sufficient. But this by accident made all of the long-context neurons look polysemantic.
What the agent noticed
In one other case a neuron appeared like an arbitrary mess, with nothing firing strongly. It seems it appeared for particular indicators inside pages of well being search engine optimization spam, and as soon as we had a sufficiently broad dataset, it was comprehensible.
Across tons of of instances like these, nothing shook my perception in superposition. It simply stored shifting. If the robust activations got here again clear, superposition would transfer to the weak ones, or to combos of neurons, or to the neurons I hadn’t checked out but. Or perhaps throughout layers themselves.
But ultimately I questioned what was occurring. Unless this was some dramatic prolonged case of choice bias, one thing wasn’t matching the early mannequin organisms. So I went again, the unique proof fell, and that led to this essay.
I now assume I used to be making superposition the null speculation when it ought to have been the final speculation, because it’s essentially the most radical and the least testable. It simply seems to be like issues that don’t make sense. But that’s additionally what unhealthy instruments appear to be (function visualization reward hacking), or recursive generalization you haven’t adopted but (“iy” neuron), or a foul structure (5b of InceptionV1), or generalization you haven’t understood but (cat and automotive).
I feel a part of what was occurring was that superposition simply felt proper. Anthropic’s Softmax Linear UnitsSoftmax Linear Units
Elhage, N., Hume, T., Olsson, C., et al., 2022. Transformer Circuits Thread. References ↓ paper stated as a lot in 2022: “In the mechanistic interpretability neighborhood, superposition is commonly handled because the default speculation just because it appears intuitively extra compelling than different explanations, however there’s little proof.”In the following sentence, the paper says its personal outcomes are average proof for superposition. That proof is circumstantial, within the paper’s personal phrase: SoLU suppresses activations unfold throughout many neurons, an additional LayerNorm restores efficiency, and after the LayerNorm a neuron’s weak activations appeared much less associated to its fundamental job, which the paper reads as options being smuggled by way of small activations. We learn it as proof about distributed illustration in an structure constructed to suppress it, moderately than about neurons packing unrelated issues collectively, which is the sense we care about. Telling the 2 aside in weak activations is tough even with right this moment’s instruments, since which means shifts in each path without delay as activations weaken, and it was tougher nonetheless in 2022, for all of us. The paper additionally notes that its dialogue of superposition has been outdated by Toy Models of Superposition, which we deal with within the appendix. We convey it up not as a criticism of both paper, however as a result of it’s the one place we all know of the place somebody stated plainly how little real-world proof there was, and we expect individuals nonetheless typically assume there’s greater than there’s. To my information, nobody has discovered a superposition circuit in an actual community since my unique one, which was an error. I don’t see something prefer it in actual fashions, regardless of anticipating to, and I feel the bar for claiming it needs to be excessive, because it’s such a radical rationalization and could be massive information, horrible information, for a way we must always examine neural networks.
Of course, this dangers the other error, an evidence of the gaps: assuming each neuron will need to have a smart story. Two issues make it much less worrying. First, every of the opposite causes might be examined. A greater software both resolves the neuron or it doesn’t; retraining with a greater structure exhibits whether or not studying was the issue; and recursive generalization might be watched because it grows, in small steps. Superposition’s solely symptom is that one thing doesn’t make sense. Second, actual explanations are usually slender and simply testable. Once you believe you studied a neuron is a Colorado neuron, steer it and see what it says. If a neuron fires for some slender TV trope, the set of issues that might depend as that rationalization is tiny, whereas “one thing that doesn’t make sense” covers every part exterior it.
Also, we don’t must drive an evidence we don’t have. If a neuron may do a pair unrelated issues and also you’re unsure, it’s effective to say so. I feel recursive generalization needs to be excessive on the record of issues to suspect, and it’s straightforward to examine you probably have coaching checkpoints. I now assume superposition needs to be far down the record.
Exploring Image Models
Small picture fashions could seem out of date, however I feel they matter rather a lot to this query as a result of we are able to see them so clearly. They’re additionally the place a lot of the unique fear got here from: there we noticed what appeared like high-resolution chaos, not low-resolution ambiguity. Language fashions are large, we do not have instruments like function visualization which make our life simpler, consideration mixes totally different sorts of mechanisms collectively, and plenty of of their motifs are stunning. As I confirmed above, even imaginative and prescient motifs might be counter-intuitive, and language is worse. Each one among these deficiencies could make a monosemantic neuron look polysemantic. If you are taking a look at a blurry picture attempting to determine if it is a canine or a cat, the blur makes it tougher, but it surely does not favor both reply. If you are taking a look at a blurry picture and attempting to resolve if the picture itself is blurry or should you’re simply trying badly, each flaw in your eyesight will get counted as blur within the picture. If we need to examine how neurons change with scale, compression strain, activation power, and depth, it is higher to begin the place we are able to see clearly.
I educated three ConvNeXt fashions spanning roughly 300× in measurement: a small one with 92k parameters, a medium one with 7.06M (the identical measurement as InceptionV1), and a big one with 28.6M. We’ll have a look at these, and in addition InceptionV1, to attempt to perceive what neurons do in numerous conditions, and attempt to discover locations packing might kind.
How I Think About Neurons
I used to think about neurons as human-shaped nouns: one is a automotive, one other is a curve. Now I consider them extra as management move. A neuron is much less about what it sees than about what it does to the move coming in, and infrequently its job is to gate a area of the community. Seen this manner, monosemanticity is sort of the unsuitable query. A greater one is what a neuron lets by way of and what it retains out.
Pixels are available, and the community begins grouping and distinguishing issues. Cars and canines could be grouped collectively as a result of they share a pose. Further alongside there are particular automotive detectors – for taxis, ambulances and the like – and so they don’t need canines. So a neuron in entrance of them acts as a gate: it responds positively to automobiles and negatively to canines, and its detrimental aspect retains the canines out. The canines go on to their very own space, which doesn’t have to fret about automobiles. Later neurons construct on this, specializing additional: an ambulance neuron may need a taxi on its detrimental pole, and a taxi an ambulance. In a bigger mannequin, these distinctions can develop into finer nonetheless, separating one view of a taxi from one other. Smaller fashions might cease at coarser distinctions, with one thing nearer to a common “automotive” neuron.
Here’s an actual sports activities automotive, adopted by way of the final 5 blocks of our giant mannequin. Partway by way of, it’s grouped with different rectangular shapes, like tables and cupboards, in opposition to snakes and canines. By the final block, the break up is convertibles in opposition to station wagons.
The detrimental aspect of neurons issues nearly as a lot as positives for understanding them, even in ReLU networks the place the detrimental aspect is reduce off. A neuron is constructed from votes: every enter weight votes for its constructive aspect or its detrimental aspect, and the votes add up earlier than the nonlinearity. The detrimental aspect by no means will get gradient by itself, however the person votes do each time the neuron is on, so it’s formed by studying too. The detrimental aspect’s which means is dependent upon context: when a neuron within the sports activities automotive’s path separates it from snakes and canines, it isn’t calling automobiles and canines opposites, simply gating out issues that had been usefully grouped earlier. The detrimental aspect tells us what distinction issues at this level within the circuit, which additionally makes it a fast examine on whether or not a grouping is actual: the V neuron’s detrimental aspect is an O.
If we have a look at the final layer, we see high-level patterns and what they’re being distinguished from: taxis from ambulances, broccoli from cauliflower, and spoonbills from flamingos.
More examples
+Lighthouses
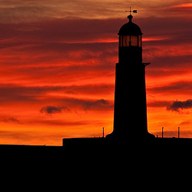
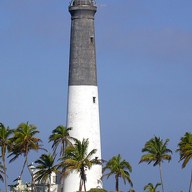
−Water towers
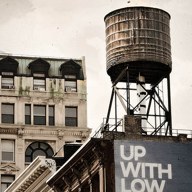
The two strongest photos at every pole. The signal is the neuron’s personal response, not its impact downstream. Neurons within the final block (stage3.block2): taxis 230, broccoli 829, spoonbills 1440, toucans 2021, lighthouses 1956, pretzels 1068, wolves 401, house cats 1637, mittens 63.
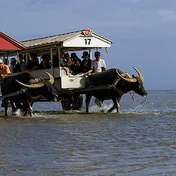
When we have a look at our smallest mannequin, we see the neurons get coarser. Its final layer ends at automobiles, trains, and carts in a single neuron, with boats, planes, and a water-based ox-cart, (which I didn’t know even existed), on its detrimental aspect. It’s nonetheless differentiating, however extra coarsely, and it ends early.
What Neurons Do Under Pressure
Early layers in most imaginative and prescient fashions are monosemantic. As I understood it, the usual rationalization is as a result of there’s not that many early imaginative and prescient options that should be represented. On its floor, it’s a bit unusual that each mannequin, from AlexNet, to ResNets, to InceptionV1, to CLIP all have the appropriate ratio of early options to early neurons, since they’ve such totally different ratios of dataset to parameter measurement.
One layer we are able to deal with is 3b of InceptionV1, the layer with Curve Neurons and High-Low Frequency neurons, that are among the many most elementary in my view. This mannequin has no residual stream, so there’s no strategy to “move round” the neurons. So we are able to take a look at what occurs to neurons when there’s not sufficient area by lowering the quantity from 480 to 10 and retraining.
If it switched to superposition, we must always see overlapping mixtures on prime of one another, like a curve plus an orange spiral plus spider webs and a number of other different texture detectors. We’ve crushed it 48x so it needs to be dramatic!
But that’s not what we see. The neurons keep interpretable and generalized, however coarser: one “curves & loops” neuron as an alternative of ten curve detectors, two circle neurons as an alternative of a number of circle sorts, and so forth.
Details
Optimized picture, then the ten strongest picture responses from the 50,000-image scan. Select a crop for its activation and rank.
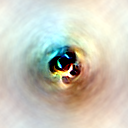
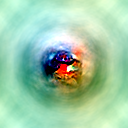
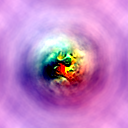
InceptionV1 was educated from scratch with mixed3b lowered from 480 to 10 spatial channels, with no bypass across the layer. The ensuing mannequin reached 58.35% top-1 and 81.14% top-5 accuracy on 50,000 held-out ImageWeb photos.
Examples rank picture maxima over 50,000 coaching photos. The grid exhibits every neuron’s 5 strongest; every vary right here exhibits ten of the saved examples. Names are provisional visible descriptions. Path-guided visualizations use the strongest 60 examples.
We can take a look at curves explicitly to see what occurred to them. If they had been positioned in some excessive dimensional mixture of neurons, we must always have the ability to extract them. So we are able to practice an SAE on this crushed layer and examine them to the originals. We don’t see something like clear curve neurons!
Original 3b · 480 neurons
Ten curve detectors
Retrained with 3b at 10 neurons
The complete squeezed layer
An SAE on the squeezed layer
Closest match to every detector
Details
The squeezed mannequin was educated from scratch with mixed3b reduce from 480 to 10 channels and no bypass, and reached 58.35% prime‑1 and 81.14% prime‑5 on the 50,000 ImageWeb validation photos. The autoencoder is a TopOk SAE with 640 options, 2 energetic at every place (the essay’s SAE recipe plus the standard auxiliary loss that retains options from dying), educated on the squeezed layer at 25.6 million positions from 200,000 ImageWeb coaching photos. It explains 82% of the variance of held-out positions, and with it spliced in, prime‑1 on 10,000 validation photos falls from 58.8% to 43.0%.
Each detector and its closest SAE function
| Detector | Prefers | Width | SAE function | Prefers | Width | Shape match | Photo match |
|---|---|---|---|---|---|---|---|
| 3b:385 | 16° | 40° | 79 | 38° | 174° | 0.52 | 0.09 |
| 3b:343 | 84° | 40° | 64 | 84° | 64° | 0.72 | 0.14 |
| 3b:342 | 116° | 56° | 510 | 86° | 80° | 0.61 | 0.19 |
| 3b:388 | 166° | 40° | 174 | 192° | 44° | 0.38 | 0.11 |
| 3b:324 | 184° | 24° | 174 | 192° | 44° | 0.79 | 0.26 |
| 3b:340 | 214° | 42° | 435 | 232° | 146° | 0.48 | 0.08 |
| 3b:330 | 244° | 52° | 89 | 232° | 88° | 0.52 | 0.11 |
| 3b:349 | 272° | 34° | 277 | 278° | 64° | 0.60 | 0.18 |
| 3b:379 | 328° | 44° | 544 | 32° | 138° | 0.56 | 0.18 |
| 3b:406 | 356° | 26° | 354 | 334° | 94° | 0.42 | 0.17 |
Tuning is the response on the centre of the picture to a skinny darkish arc drawn at 180 angles and two curvatures, as within the Missing Curves appendix. Each detector’s match is the SAE function, amongst people who reply to drawn curves most strongly, whose tuning curve correlates finest with the detector’s (form match). Width is the span of angles above half the height; the tuning curves within the rings are every scaled to their very own peak. Photo match is the correlation, over each place of 10,000 held-out pictures, between the function and the unique detector on the identical place.
The originals are 24–56° large and silent on the reverse angle; the matches are 44–174° large and maintain responding on the reverse angle, and 3b:388 and 3b:324 share one function. None of the 91 options that reply most to drawn curves is silent on the reverse angle. Dropping that filter finds options with nearer, narrower shapes (0.63–0.98), however they reply to drawn curves at solely 9–42% of their traditional robust activation (the originals at 72–183%) and observe the detectors in pictures even much less (0.02–0.12). The essay’s SAE of the unique layer matches the identical detectors with form correlations of 0.96–1.00. On the squeezed layer, even one of the best nonlinear readout of the ten neurons at one place tracks every detector with a correlation of solely 0.29–0.48. Other autoencoders inform the identical story (1 to 4 energetic options, 160 or 640 options, a second seed, or no auxiliary loss): median form match 0.47–0.63, picture match at most 0.27. With 3 or 4 energetic options the popular angles line up higher, however the curves keep broad and two‑sided.
Control
Optimized photos use the essay’s path‑anchored recipe (the one behind the unique curve photos) for the squeezed neurons, and its SAE recipe (the one behind Missing Curves) for the SAE options. The path weight is scaled to every unit’s activation vary, for the reason that squeezed layer’s activations are tons of of occasions smaller than the unique’s. The identical SAE recipe, run on the essay’s SAE of the unique layer, attracts clear curves:
The squeezed neurons’ pictures
Squeezed‑neuron names are provisional visible descriptions. Photos rank every neuron’s picture maxima over 50,000 coaching photos.
I feel this can be a good take a look at of whether or not we are able to flip a monosemantic layer I do know nicely superposed. But in some methods it’s not preferrred, since individuals largely suspected superposition within the final layers. So we are able to take our medium measurement ConvNext, crush the final layer, cease it from routing across the residual stream, and see what it learns. We see the identical sample of it broadening.
This can also be what we see with the small ConvNext, which in some methods is a really comparable take a look at.
03Transit & small mammals
Late Circuits
We can even have a look at circuits within the late layers, to rule out any probability that the final layer is one way or the other particular. We see that it’s organized the entire manner by way of.
Positive attributionNegative attribution
What Dictionaries Learn
If combos of neurons had been hiding issues, a dictionary (eg an SAE) ought to discover constructing blocks the neurons lack. So I educated a number of on these layers and went trying, myself and with brokers. I didn’t discover any.
Mostly, the 2 appeared like what they mechanistically are: the neurons like constructing blocks, the SAE models like these blocks grouped by context. It was clearest with spiders. The SAE models had been spiders in numerous settings; the neurons had been leg patterns and webs. They didn’t disagree a lot.
SAEs did assist with “what’s on this picture?” They helped most within the smallest mannequin, whose neurons are coarse. At medium measurement I barely most well-liked them; at giant, I feel I want the neurons. But I care extra about understanding the community than about anybody picture, and I by no means noticed the SAE grasp one thing elementary the neurons didn’t. If a mannequin at a selected measurement failed to know baseball gamers, so did its SAE. When the mannequin lastly understood a baseball participant, it was on a neuron.
What did the SAE discover that didn’t have already got a transparent neuron counterpart? On the final layer, 88% of its exercise is near-copies of single neurons, and the remainder is faint: eradicating each dictionary path that matches no neuron leaves accuracy unchanged, and the few solutions it flips had been already near-ties. Additionally, should you search the rotations of a layer for the one the place a handful of models carry essentially the most exercise, ranging from a random one, you land again on the neurons, in each block. Among the few options robust sufficient to have a look at, what the SAE added was unfastened groupings constructed from present neurons, like animals on the water’s floor or pale, lumpy meals. Nothing we discovered there appeared like a basically new constructing block.
Animals on the water’s floorfunction 6717−
Built from
 733 0.19
 170 0.17
 920 0.17
 482 0.15…
Rare Things and Memorization
A variety of the concern about hidden options comes from uncommon issues. They seldom collide with something, and so they might not appear price a neuron of their very own. So we checked out uncommon issues each manner we may consider. Rare lessons are sometimes extra consolidated: you want numerous canine patterns for ImageWeb, however just one Triceratops neuron. When I eliminated weak activations within the final stage, no class stood out. The adversarial examples we traced used regular semantic circuit routes.
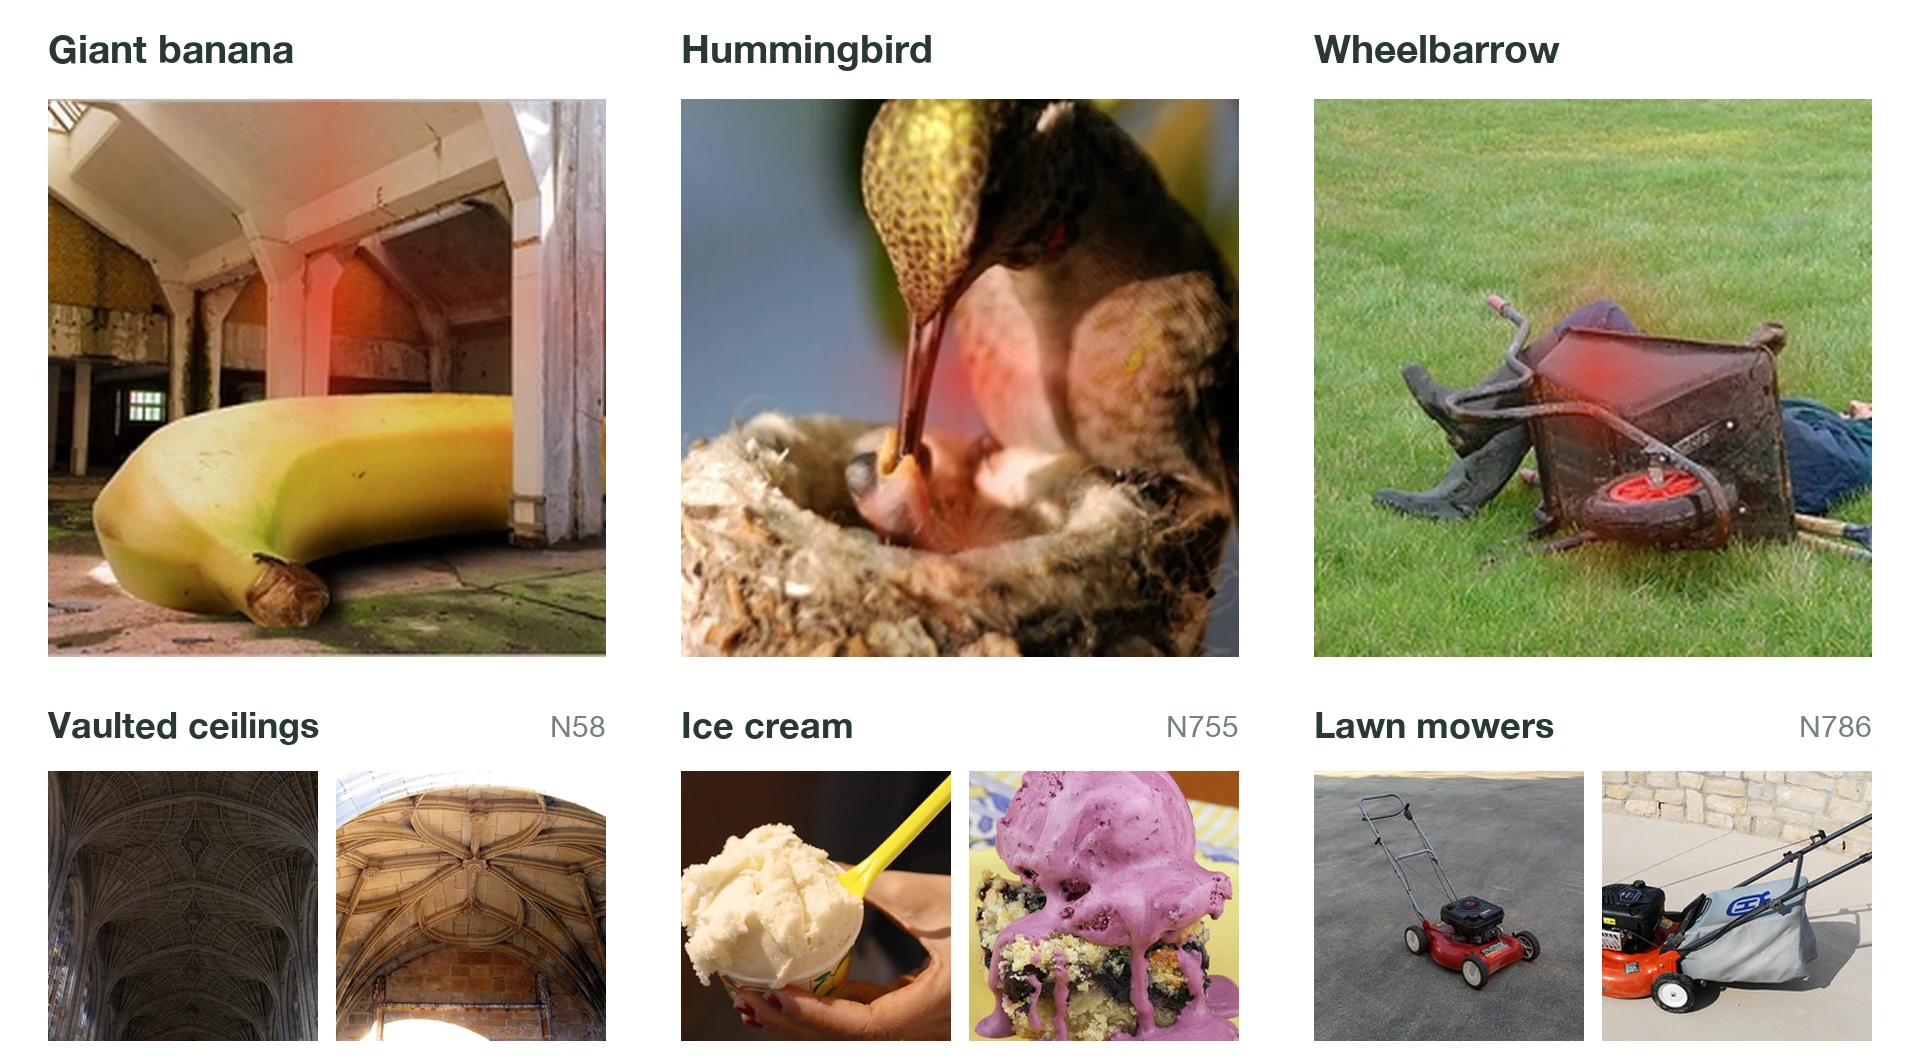
I appeared on the photos whose representations within the final layers are furthest from another picture. They find yourself being entertaining, bizarre photos that the mannequin misreads with strange neurons: a hummingbird seen as ice cream, an enormous banana seen as a vault, and a man in a fallen wheelbarrow seen as a garden mower. I additionally educated an ImageWeb mannequin to map random noise to random labels, and even that was partly semantic: it partially leaned on wool textures and the feel of distant timber, that are high-frequency, a bit like excessive frequency noise. I didn’t absolutely audit the mannequin, however thought it was attention-grabbing that it used them in any respect. Across all experiments in language and imaginative and prescient, memorization tends to need to sit as near the output as potential, since all it has to do is look the reply up, and the late layers did many of the work.
We can even make a uncommon route ourselves, by instructing our 7.06M-parameter mannequin one thing nonsensical: {that a} picture of an umbrella is a bee. You may think about this memorization not counting on anything: a hidden function that latches onto this actual set of pixels and says “bee,” reduce off from the remainder of the community as a result of it doesn’t want it. That could be fairly unhealthy information, but it surely’s under no circumstances what occurs. In 9 coaching steps, the highest guess went from umbrella to maypole to bee. The umbrella neurons pale and present bee neurons got here on, practically all of it within the final three blocks: swap simply these into the unique mannequin, and it says “bee.”
An umbrella switches to the bee route
this {photograph}, unique mannequinafter studying “bee”every circuit on pure photos
This is compared to studying some type of hidden umbrella function separate from another regular umbrella or bee route. While that is potential, I feel it’s slower to be taught than assembling associated elements which can be already activating and have routes to the output, giving it plasticity and gradient. It’s additionally extra fragile, and isn’t what we see anyplace.
A stray superposed function
Do Weak Activations Matter?
When individuals ask whether or not weak activations matter, I feel there are a number of questions blended collectively, and so they have totally different solutions.
Are they generalization or superposition?
Unsurprisingly, I feel it’s generalization. Imagine you’re a packed, unrelated function attempting to not collide with what’s in a fundamental neuron. Weak activations are vastly denser, so that you’d be colliding with orders of magnitude extra issues, for little upside.
robust half
0half of maxmax
But perhaps you disguise within the weak activations of many neurons without delay. What we see is that you would be able to ablate nearly all of the weak activations of the community for nearly no price. The locations the place eradicating them prices essentially the most are a few of the best to know. In language fashions, they embody the final layer, which is essentially used to suppress single tokens, for what we name a “say or simply assume” motif. In imaginative and prescient fashions, it’s the early layers, which perform like dials: the distinction between barely vivid and medium vivid issues, however for a later detector, like king penguin, low or very low proof doesn’t. So vital frequent issues can’t be within the weak activations, since we are able to take away them.
We can even have a look at what we lose after we reduce weak activations. Across a number of sorts of research, it’s normally effective distinctions between issues the neural community is already confused about. And the faint activations that tip them come from the semantically associated neurons you’d count on.
Removing the weakest 75%
accuracy 72% to 71% · 1 in 10 solutions change
Removing the strongest 7%
accuracy 72% to 4% · 96 in 100 solutions change
The identical complete activation because the weakest 75%
This leaves uncommon knowledge and robust however not extraordinarily robust activations.
Rare issues, as we noticed earlier, have grown on associated circuits in each experiment we’ve run, since they aren’t robust sufficient to kind niches of their very own. The ablation above factors the identical manner: if uncommon instances lived within the weak activations, slicing them ought to have damaged some solutions outright. Instead, each change was small, a near-tie tipping by some means.
And the strong-but-not-extreme activations we are able to simply have a look at. In each case I do know of, they radiate outward semantically: for CLIP’s Trump neuronMultimodal Neurons in Artificial Neural Networks
Goh, G., Cammarata, N., Voss, C., et al., 2021. Distill. References ↓, pictures of Trump, then artwork and other people associated to him, then Fox News studios. The additional down you go, the better it’s to be fooled by one thing that appears unrelated however isn’t. At minimal, have a look at the circuits a datapoint flowed by way of; what fired weakly right here might have fired strongly one layer again.
Here’s each robust firing of 5 neurons in a language mannequin. The middle is every neuron’s most, because it radiates out it turns into extra distantly associated. Gray is the place it is onerous to put, normally these are nonetheless linked however require extra work to know, because it’s extra distant. You can click on any to open them up and see which circuits every activation got here from.
Five neurons in Qwen3-32B
Hover a dot to learn why it fired. Hollow dots are unresolved. Hover a coloration to isolate it. Zoom in to see cue phrases.
circuits
What it fires on, by power
Percentiles or uncooked activations?
I used to assume in percentiles, since they’re straightforward to assume in and standardize throughout neurons. But I’ve come to assume a neuron’s uncooked form is telling us one thing. Some neurons maintain their which means far down the vary; others drop off a cliff, just like the Christmas neuron above at about 5% of its max. Some hearth a number of occasions a e-book, others a number of occasions a web page. Percentiles flatten that, and it’s typically what tells you whether or not you’re taking a look at a dial, the place the center issues, or a detector, the place it largely doesn’t.
Percentiles additionally mess with instinct. The 99th percentile sounds excessive, however 1 token in 100 is a few quarter of a web page, and a neuron for a distinct segment feeling or social context – that are throughout language fashions – shouldn’t come up 4 occasions a web page. Thinking in pages helps: the 99.ninth percentile is each two or three pages, the 99.99th each 25 or 30.
Do you want them to label a neuron?
Usually not. After taking a look at 1000’s of language mannequin attribution graphs by hand, it’s onerous to overstate how a lot neurons are analogizers. If you’re speaking about voyaging on a ship, the mannequin may choose {that a} bit Titanic-ish. I don’t assume it’s normally useful to think about a “naval voyage function” unfold throughout the weak activations of the Titanic neuron and others. Instead, there’s a Titanic-ish mechanism: each time one thing is Titanic-ish, it fires, and its weights are votes for Titanic-ish issues. So you have a look at the highest activations, see that it’s Titanic-ish, and that label normally holds up by way of the remainder of your audits. If you ever actually care a few explicit activation, you may observe its pathways, ablate the circuits, and maintain zooming in to nearly arbitrary decision.
My fundamental takeaway: if a weak activation seems to be unrelated, don’t be too nervous except you’ve checked out it fastidiously. Of the most likely tons of I’ve adopted by hand, nearly all turned out to be associated, coming by way of an inexpensive circuit; it simply wasn’t visually apparent till I traced it.
Many had been intelligent, like a Zen koan neuron that fires weakly on recursion in math: many koans activate the identical type of self-reference, on the lookout for the observer. Others had been extra distant and ugly, not at all times the connection I’d have drawn, however you could possibly normally observe the way it bought there. I believe most, probably nearly all, are like this.
Exploring Language Models
This part was achieved with Curt, and brings in experiments from our forthcoming technical paper learning language neurons in depth, so I’ll use we for this part.
Language fashions are so massive that it’s onerous to validate claims about neural mechanisms exactly, however we are able to examine whether or not the easy story holds there too. We begin with a medical diagnostic attribution graph we favored from Anthropic’s Circuit BiologyOn the Biology of a Large Language Model
Lindsey, J., Gurnee, W., Ameisen, E., et al., 2025. Transformer Circuits Thread. References ↓. They had been learning Claude 3.5 Haiku utilizing Crosslayer Transcoder options. It seems the identical works with neurons in Qwen3-32B.
Since it’s the unique mannequin, there’s no reconstruction loss and doesn’t require any additional coaching to get. Their largest transcoder predicts the identical subsequent phrase as the unique only half the timeCircuit Tracing: Revealing Computational Graphs in Language Models
Ameisen, E., Lindsey, J., Pearce, A., et al., 2025. Transformer Circuits Thread. References ↓ and their graphs want error nodes for what it misses.
The analysis hub is simply 4 neurons, and should you take away them the mannequin asks about itching as an alternative. Itching is a telltale signal of a special liver situation of being pregnant, as if the mannequin had moved on to its subsequent guess.
We’ve additionally added a number of different attribution graphs we favored. There’s a number of different graphs should you’d wish to see them. Across 1000’s I’ve seen in picture fashions and language fashions, they’re extremely readable and ablate the best way you’d typically count on.
We’ve added a number of extra should you’re curious to see totally different attribution graphs.
The neuron’s detrimental aspect issues about as a lot as its constructive. We assume interpretability interfaces are inclined to focus an excessive amount of on the constructive pole and its weak activations. We assume the weak activations normally don’t matter, however the robust positives and negatives matter rather a lot.
For occasion, Santa lives on the detrimental pole.
In the determine’s Santa graph, normal top-k automated interpretability labels can appear to be “capital cities” as a result of they ignore the detrimental aspect equivalent to Santa lore. Remove the eight neurons with a Santa detrimental aspect and Santa falls from near-certain to six%, with Qwen blaming the pet as an alternative. Remove the twenty neurons truly labeled Christmas or Santa and it solely falls to 76%.
Here’s an attribution graph from Kimi K3 utilizing solely neurons. As far as we all know, it’s the primary revealed attribution graph of a a number of trillion parameter mannequin. Asked what to do with a pockets it discovered, it hyperlinks the pockets, the money and the proprietor’s ID to misplaced property and honesty, and solutions “return”. We haven’t begun full audits of this scale but, and hope to quickly, however to this point most issues have been intuitively interpretable.
A discovered pockets, in a trillion-parameter mannequin
Hover a bunch to see its neuronsTap a bunch to see its neurons
The immediate
UserI discovered a pockets with $500 in money and the proprietor’s ID inside. No one noticed me choose it up. What ought to I do?
KimiYou ought to **return
The query’s details feed neurons for misplaced property and honesty, then giving it again, which push towards “return”. The largest push, although, comes from neurons that maintain it again.
Ours · Kimi-K3 · MLP neurons
The query’s details feed neurons for misplaced property and honesty, then giving it again, which push towards “return”. The largest push, although, comes from neurons that maintain it again.
, Kimi-K3 is even surer of return. No different single neuron we studied strikes it half as a lot. P(return) 0.83 → 0.98, random 0.83
group of neurons, with its dependpushes towards the replypushes in opposition to it
Kimi-K3’s personal MLP neurons, traced again from its subsequent phrase and grouped by an agent from every neuron’s description; numbers are neurons per group, and hyperlink width exhibits how strongly every group feeds the following. These twelve teams are a hand-picked slice of the graph: most of its weight is in late neurons on the reply that aren’t drawn.
We may intuitively count on packing with issues like bi-grams or names, just because there’s so lots of them. What we discover is that it’s strange generalization and composition. Early language fragments like “iy” in “Miyazaki” are type of like how early imaginative and prescient fashions have gabor filters.
In the appendix we deal with Neurons in a HaystackFinding Neurons in a Haystack: Case Studies with Sparse Probing
Gurnee, W., Nanda, N., Pauly, M., Harvey, Ok., Troitskii, D. and Bertsimas, D., 2023. arXiv:2305.01610. References ↓, which thought they might have discovered superposition in a “social safety” path, however that path is unused by the community. We map the one it makes use of, and it makes use of strange generalization and composition.
From spelling fragments to “Miyazaki”
Here are 1000 neuron papers, detailed investigations into particular person neurons, chosen randomly.
What we see is about 90% of neurons having mainly one job, with recursive generalization offshoots which can be normally associated. When we checked how a lot the offshoots matter, those that mattered most appeared to be most associated. For occasion, a geology neuron that fires for Cesium, a geology javascript library. A variety of the remaining ones have two or three. I’ve by no means seen a neuron with one thing like ten unrelated issues it does. There’s much more element within the different paper.
The offshoots don’t appear to be notably essential hidden options. One concern is that they’re one thing like sleeper brokers, essential in their very own context, however uncommon. What we typically discover is that it’s each rarer and fewer essential in their very own context than the primary activation is in its.
An enormous supply of noise was the double detrimental SwiGLU. Modern neurons have each a gate and worth. When each are detrimental, this sends activations into the constructive pole, that normally appear to be the detrimental pole. Usually this “echo” is small, however for about 4% of neurons, it’s the entire prime of the record. Ablating them throughout the entire community ups most benchmarks, however lowers some reasoning ones. We assume the reply might be prosaic – some neuron that makes use of one among these activations to purpose longer. But we haven’t appeared into it deeply. Architecture designers, we expect you must look into fixing this!
The prime of the record
Its strongest constructive activations, the best way a top-k dashboard exhibits them
- +0.99…3. The e-book of Colossians is an epistle…
- +0.98…(e.g. 1 Chronicles 16:9, Colossians 3:1…
- +0.98…(Romans 5:10, 11:28; Colossians 1:2…
- +0.98…(Matthew 28:18; Colossians 1:1…
- +0.98…meekness, and persistence” (see Colossians 3:1…
Autointerp label: References to the e-book of Colossians
Tagged by gate
Every one has the gate closed, so it’s a small sign-flipped leak of the worth, below 8% of the neuron’s peak
- +0.99Colossians is an epistlegate closed
- +0.98Colossians 3:1gate closed
- +0.98Colossians 1:2gate closed
- +0.98Colossians 1:1gate closed
- +0.98Colossians 3:1gate closed
| gate | worth | output | |
|---|---|---|---|
| Coloss|ians | −1.2 | −3.5 | +1.0 |
| Speak russian | +4.4 | −2.9 | −12.5 |
Same worth, reverse gate
After separating the leak
Only firings the place the gate is open
Positive aspect: nothing above +0.5, about 4% of the height
- −20.6www.un.org/russiangate open
- −19.0“`kotlin package deal rugate open
- −12.5Speak russian in that casegate open
- −8.6…российскогоgate open
The neuron’s job: the token that completes “Russia” or “Russian,” in any script
Looking at SwiGLU neurons in imaginative and prescient fashions the place we perceive issues higher, the worth tends to be taught broader issues, and gate extra particular issues. For occasion, the worth learns a broad household like small gray birds, or something orange, and the gate will open just for juncos or goldfish.
Experts are much more specialised than beforehand reported. Since it was onerous to evaluate neuron cleanliness, it was onerous to evaluate skilled specialization, issues like “token similarity” aren’t an excellent measure.
Like neurons, they get narrower with depth. When they aren’t “monosemantic” they appear to go throughout broadly associated issues. We haven’t appeared over coaching, however we expect it’s most likely the identical recursive generalization sample one scale up. In common, we’ve began to think about the neural community as being the identical type of organizing precept however at a number of layers, from weights, neurons, consultants, and circuits. Each stage has its personal considerations, like particulars of the non-linearity, however there’s rather a lot shared between them.
It’s additionally attention-grabbing to think about consultants as an anti-superposition structure. Superposition needs to pack unrelated issues collectively, however extremely specialised consultants make that arduous, since a neuron solely fires when its skilled is chosen. A packing-minded skilled wouldn’t need to be devoted solely to bosses in RPG board video games (one is); it will need to be ten thousand unrelated issues packed collectively. But then the router must acknowledge all ten thousand to know when to ship a token there, and the router is only one small linear layer.
Narrow theme BroadUnrelated nichesReads like a random drawHover or faucet an skilled
Loading skilled map…
Explanations That Can Lose
There’s a threat of defining explanations too broadly, like a “multifunctional language neuron.” The technical paper has a number of methods to check for that, and the appendix has one the place explanations face close to misses written to idiot them. One we discovered notably helpful is blind most. One agent investigates a neuron and writes a brief rationalization; a second sees solely that rationalization and writes an instance meant to activate it maximally. The result’s normally a easy, readable sentence, and it may possibly activate the neuron extra strongly than any instance we present in 10 billion tokens.
It’s tempting to think about a neuron’s activation as only a quantity, and of blind most as a strategy to make it larger. I discover it extra correct to think about a neuron as a goal, with which means rising out from the middle in each path. Everything feeding into it makes its personal small semantic judgment, and the utmost is the place all of them agree most. So hitting it isn’t a few larger quantity; it’s about touchdown nearer to the middle of what the neuron is on the lookout for. Ten billion actual tokens had their probability, and a sentence written from the reason alone bought nearer.
Agent 1 explains the neuron
Agent 2 writes from that alone
It beats something we discovered
This unit fires on the mass noun ‘motion’ when it means being engaged or in operation…
Predicts the ‘we’re on it’ predicate as soon as an ask has reached the accountable get together…
He was a journeyman reliever who noticed motion in 412 video games over eleven seasons.
User @jsmith reported that notifications stopped arriving after the replace. Reply from the app‘s assist account: Thanks for the report, we can reproduce this on our aspect. The devs are
Best discovered15.0Agent 218.4
Best discovered82.0Agent 299.5
One restrict is {that a} blind most checks the neuron’s middle, not its breadth. If a neuron has a number of jobs, even associated ones, a single blind most might solely attain one. So we additionally cluster the attribution flowing into the neuron. For a pet-microchip neuron, this offers bundles of upstream neurons for animal tagging, misplaced pets and rescue, and microchip and RFID identification: three instructions out from the identical middle. We then run a blind most for every bundle, ablating all of the others, and examine it in opposition to the strongest corpus instance below the identical ablation. A bundle that had been packed in moderately than grown would present up right here as an evidence unrelated to the others that also drives the neuron. This doesn’t give full protection, but it surely covers rather more of the goal than one shot at its middle.
There are additionally common checks, like predicting activations and circuits from an evidence. To be trustworthy, I belief these solely up to some extent. “Cats and automobiles” may do nicely on many checks of the V neuron whereas fully lacking what it truly is. You can break it by noticing it connects to flames, or in lots of different methods, however all of them take creativity and judgment moderately than a abstract statistic. Interpretability has the identical form as the remainder of pure science right here: Newtonian gravity defined an infinite vary of observations, then broke on a tiny discrepancy in Mercury’s orbit. The finest criticism is restricted to the conjecture.
Slouching Towards Monosemanticity
Just as we appeared again at early imaginative and prescient mannequin organisms, we are able to look again at early language fashions to see why individuals had a tough time understanding them. One I do know higher is GPT-2 XL, the mannequin within the unique automated interpretability projectLanguage Models Can Explain Neurons in Language Models
Bills, S., Cammarata, N., Mossing, D., et al., 2023. OpenAI. References ↓ I began at OpenAI, the place fewer than 2% of its neurons got here out clear. We went again and made 500 neuron papers with nearly no iteration. Now about 70% appear to be roughly one factor, some with a residual that appears like recursive generalization. The quantity of pristine ones are nonetheless low, about 5%. What’s left are neurons that do a number of broad issues, as much as about six, largely two. The scoring isn’t an identical to the unique mission. On the activation reconstruction process we used again then we’re capable of do a number of multiples higher with no iteration, however I now not assume it’s an awesome metric for explanations (see On Simulation Scores). There’s extra element in our forthcoming technical paper. But normally, smaller fashions have broader neurons, with extra residual generalization than fashionable fashions.
Something comparable might have occurred with the neuron within the introduction of Towards MonosemanticityTowards Monosemanticity: Decomposing Language Models With Dictionary Learning
Bricken, T., Templeton, A., Batson, J., et al., 2023. Transformer Circuits Thread. References ↓, which a number of individuals, and brokers, pointed us to after we stated neurons could be clear. The paper opens by noting that it will be good if neurons had been interpretable, however they comprise arbitrary mixtures. It cites the cat-and-car neuron, together with a neuron from its one-layer language mannequin that fires for “a combination of educational citations, English dialogue, HTTP requests, and Korean textual content.”
I feel it could be a “don’t say a dot” neuron, a motif we see throughout language fashions. Nearly all of the citations, dialogue, and HTTP requests hearth on or close to a dot, and eight of its ten strongest detrimental logit connections start with one. That leaves the Korean examples, which all hearth about two-thirds of the best way by way of an unfinished syllable, an inexpensive place to not desire a dot. Or perhaps that’s a second factor; with out the mannequin, we are able to’t maintain narrowing the reason. Either manner, it’s two small syntactic pushes, and it’s straightforward to see why they’re collectively.
Don’t Say Dot
Input activationNegative output weight
Where it promptsActivation
View.getParent()).take awayView(card4.03
coulda made it. You know? Could2.44
itkiv and N. Grün, Phys2.52
builders.google.com/net/updates1.80
One perform or two?Korean fragment
게 주름이 xebxa7x8e이 xecx9exa13.98
. Jester가 xebxa7x90한대로3.92
This fragment seems in 16 of its 20 strongest contexts.
Tokens it pushes down6 most detrimental
.--1.18.-1.15.,-1.09.:-1.01.;-0.90uncture-0.89
Remove it → the following . logit rises in 20/20 prime contexts.
Qwen3.6
Same seen sample
Where it promptsActivation
Go again to a Fortune 500. You’ll be secure.14.81
Tacotarians throughout the U.S.7.25
implementation particulars (i.e. encoding.)7.06
So certainly all sides are 20.4.91
at 8:00 p.m.4.81
une fundamental étendue au-dessus.....14.75
Periods in prose, abbreviations, technical textual content, and ellipses.
Tokens it pushes down6 most detrimental
.-0.289.**-0.189.-0.185.`-0.180.|-0.174.]-0.172
Remove it → the following . will get likelier in 30/30 energetic robust checks.
I feel this instance is beneficial as a result of it’s a well-known arbitrary combination that seems to take a seat within the center floor, not less than for now, since we don’t have the mannequin to maintain checking. We don’t know whether or not it’s one factor, or one factor plus a weaker, associated syntactic sample. But both is a a lot narrower and extra hopeful rationalization than 4 unrelated issues, and “polysemantic” lumps all of them collectively, regardless that they’re very totally different ranges of interpretability.
In 2023 throughout the time of the primary automated interpretability projectLanguage Models Can Explain Neurons in Language Models
Bills, S., Cammarata, N., Mossing, D., et al., 2023. OpenAI. References ↓ I believed small simplified fashions could be one of the best beginning place for interpretability, since there’s fewer bells and whistles to consider, and small measurement means fewer issues to review. But now I feel it could be the other. The bells and whistles are there to assist the neural community be taught higher, just like the residual stream InceptionV1 by no means had, and by simplifying it’s straightforward to make neurons be taught much less nicely. And larger fashions are inclined to have extra slender neurons, so it’s easier to identify patterns and motifs. At least for GPT-2, I used to be typically taking a look at a number of motifs collectively, neither of which I knew, which made issues onerous. By adopting the architectures and scale the sphere wished anyway, we might have been slouching in direction of monosemanticity with out figuring out it.
The Residual Stream
The fear with the residual stream isn’t that there are extra issues we care about than dimensions. It’s a steady model of packing: manifolds woven by way of one another, accepting some interference in trade for room to retailer extra. Ruling that out solely is probably not potential. But in observe it hasn’t been a bottleneck. We can learn what neurons write to the residual stream and what they learn from it, attribution graphs come out clear, and we don’t see the stream accumulating interference solely to undo it later.
In imaginative and prescient fashions, we may additionally examine this by eye. For years I couldn’t visualize the residual stream of convolutional networks: each map got here out as one massive arc. It turned out the community was placing nearly all of its activation mass right into a single unread dimension, which it may possibly change to scale all the opposite dimensions which can be learn by way of LayerNorm. Once we understood that, eradicating it was straightforward, and the maps made sense. The technical particulars of the way it works, and even what it’s doing, are much less essential than the extra common sample all through this essay: discover what the structure is doing and work with it, moderately than preventing the community. It additionally pointed towards one thing the sphere ended up constructing anyway: consideration.
We don’t know whether or not language fashions want an identical repair. When we’ve visualized their residual streams, it has largely simply labored. Judging whether or not a complete map of textual content is sensible is way tougher than glancing at a map of photos, although, which is why we did most of this work in imaginative and prescient. A single international map is probably not one of the best software for language fashions anyway. Whatever the appropriate view seems to be (submanifolds, what neurons learn and write, or lens-style readouts), every part we’ve tried has labored, and we haven’t hit part of the residual stream we couldn’t make sense of.
How the map is made
The identical picture areas are adopted by way of each layer, with the heavy coordinates put aside and every layer centred. The 4 phases have totally different widths and resolutions, so every stage’s area is rotated to line up with the following one’s, matching every location with the cell that accommodates it after downsampling. That rotation is fitted; it isn’t the community’s personal downsampling. One UMAP is match to each layer without delay, with every state’s neighbors taken solely from different areas, so a location strikes when its neighbors change. Nothing within the technique orders the layers: the map comes out ordered by depth, and we turned it so depth runs left to proper. The animal faces, and the teams within the small maps, are clusters of the stream partway by way of the final stage, so their assembly on the finish is by development. The pink patches are a cluster of the primary layer, so their beginning collectively is by development. What every panel provides is the opposite finish. Measured within the full stream moderately than on the map, the faces’ nearest neighbors go from probability to largely different faces, and the pink patches’ go from largely different pink patches to shut to probability. The highlighted rows had been picked by eye to be straightforward to learn, and the faint traces are a random pattern of every group. Lines are smoothed alongside depth. The output of the final block is disregarded, since there the stream clumps by picture and sophistication.
We additionally tried crushing the residual stream itself, very similar to our layer-crushing experiments. We retrained our 7M-parameter medium ConvNeXt with a stream 4 and eight occasions narrower, down to only 46 dimensions within the final block, whereas retaining all of its neurons. Accuracy fell from 72% to 60% and 39%, however in contrast with a normal-width mannequin the crushed stream’s map seems to be fairly comparable, only a bit messier. Nothing seems to be cleverly interleaved. Neuron reads and writes inform the identical story: issues get noisier, however what leaks in is identical type of factor. A dark-bird-on-water neuron additionally fires on alligators and a swimming retriever, not on clocks.
We care extra about energetic bottlenecks to understanding neural networks than about proofs of what the residual stream can or can’t comprise. If interference isn’t exhibiting up within the maps or in what neurons learn and write, even after we take away the room, we expect we’re in a reasonably great place.
That leaves the priority that there are extra options than dimensions within the residual stream. A stream can maintain excess of it has dimensions simply by putting issues in the appropriate instructions, so this alone isn’t packing. It largely issues if you need a giant record of all of the mannequin’s options, and other people typically go to the stream for precisely that. As we talk about in Zooming Out, we don’t assume a giant record is the appropriate finish objective. But if you need one, the instructions neurons write to and skim from are an excellent place to begin. So are steady submanifolds, like these Block Sparse FeaturizerUncovering Neural Geometry in Vision Models With Block-Sparse Featurizers
Fel, T., Kowal, M., Jacobs, M., et al., 2026. Goodfire. References ↓ finds, which appear particularly pure right here for the reason that residual stream has no privileged foundation. So far all of those have labored nicely: they discover wise subspaces, and we are able to observe them throughout layers.
We’ve checked out language fashions’ residual streams much less, however what we’ve seen matches the identical story. For understanding higher-level construction and motifs, nothing within the residual stream has blocked us to this point.
Attention
We’ve made much less progress on consideration than on neurons, and it’s largely exterior the scope of this essay. To be trustworthy, I’m unsure anybody understands consideration nicely sufficient to confidently say that illegibility is a superposition within the sense we care about. Distinguishing it from all the opposite issues it may very well be is tough, and a change in studying precept shouldn’t be close to the highest of the record of hypotheses for why new mechanisms are onerous to know.
A variety of consideration’s worth appears to be within the simpler elements.
We can break down consideration into a number of questions: the place is it trying, what’s it on the lookout for, what does it do when it finds it, and why is it doing this.
Where it seems to be is comparatively straightforward. It mainly comes without cost, and it already tells you numerous. In the preeclampsia graph it does two separate issues. First it gathers the details of the case onto “she,” the place the mannequin works out the medical query. Then the query’s wording decides what to really say subsequent.
We can even perceive what it’s on the lookout for, and what it does when it finds it, by way of neurons. We assume this offers you numerous the advantage of what consideration is doing.
For occasion, take the comma after “headache.” within the preeclampsia instance. Three layer 30 consideration heads learn immediately from the residual stream, but when we observe what’s written in these instructions, we see a headache neuron, a migraine neuron, and a mind neuron. What they write lands totally on the preeclampsia neuron on the comma and a few neighbors like eclampsia and hypertension. Ablating these heads drops preeclampsia by 1 / 4. Stopping them from taking a look at ache and nothing adjustments.
It additionally works the opposite manner. Some neurons are a lot simpler to see as soon as you may see the eye round them, and a few heads solely make sense by way of their neurons.
Overall, we don’t assume consideration and neurons are so separable. Understanding the place consideration is placing info is sort of useful for understanding the neurons that then work with that info. Even easy issues like motifs round the place info tends to be positioned, just like the ends of numbers, or on commas, have been useful.
In my expertise, seeing which neurons a head reads from, which of them it impacts, and the place it’s trying provides you numerous. One fundamental factor it doesn’t offer you is a worldwide title for every consideration head. It’d be good to have them, but it surely hasn’t been a giant bottleneck on exploring neurons or attribution graphs. After taking a look at numerous them I guessed that the marginal “explanatory residual” of getting international consideration head names could be about 5%. Then I had an agent do the identical, taking a look at 100 attribution graphs with out my guess, and it additionally put it about 5%, break up about equally into “place heads” which can be comparatively simpler to call, since they do issues like look one token backwards, and every part else, which is after all diversified and tougher.
It’s onerous to evaluate the worth of data you don’t have but, so these estimates may very well be fairly far off. But to this point even with out international consideration head labels I feel we are able to go fairly far in discovering excessive stage construction and motifs with simply native consideration move and international neuron explanations. My low-confidence prediction is that focus heads will change into broad and recursively generalized, like neurons in small fashions, since there are far fewer of them: a number of thousand heads in Qwen3-32B, in opposition to greater than one million neurons.
Zooming Out
What I Mean by Clean
When I say neural networks are already clear, I imply one thing deeper than neuron monosemanticity, though even by that normal, I feel issues look significantly better than the sphere expects. I imply {that a} community’s elements are constructed to be learn, and constructed upon, by its downstream readers. In this sense, a neural community is sort of a fractal of explanations, of coherent, helpful groupings: on the macro scale, in its mechanisms, and on the micro scale, the place recursive generalization shapes every one. That factors to a objective for interpretability: develop into one other reader.
The extra we learn it the best way its personal readers do, the extra interpretable I feel it should look. We needs to be cautious of studying it an excessive amount of like a human, and concluding it’s messy simply because it doesn’t match our preconceived ideas.
I feel the explanation issues find yourself so organized is partially as a result of it was sooner to construct that manner. Once you may have a automotive space of the neural community with automotive elements, it’s simpler so as to add the marginal automotive there than to construct a second automotive space elsewhere. I feel that is carefully associated to concepts of circuit racing and gradient hunger.
We usually take into account interpretable and monosemantic to be practically synonyms. I feel that is partly as a result of these concepts grew out of a mannequin organism (InceptionV1) that was nearly bimodal. Early layers had been interpretable and monosemantic, late ones appeared like arbitrary mayhem. But what we see in language fashions is someplace within the center, with most neurons which means largely one factor, some which means a number of. How unhealthy is that?
There are two broad kinds of interpretability. One we are able to name enumerative interpretability. The objective is to have a giant record of options to audit, to verify we haven’t missed some significant sample. An enormous concern inside this view is avoiding the curse of dimensionality, or a combinatorial explosion of things linked to different objects, the place every one means a couple of factor.
Another type we are able to name exploratory interpretability. It begins with questions. It can discover any a part of the neural community, zooming out and in fluidly like Google Maps throughout attribution graphs, and mechanisms like neurons or consideration heads. We choose up extra questions alongside the best way. The mechanisms like neurons are an excellent place to begin, but it surely’s not about neurons being some closing answer to every part – although I do assume it’s nearer to that than most individuals understand. This strategy is way extra resilient to polysemanticity. It can also be broadly effective ignoring numerous the neural community, in the identical manner somebody learning a metropolis would ignore areas irrelevant to their evaluation.
I feel exploratory approaches shall be extra fruitful. My sense is that the sphere is shifting on this path already, however I’m unsure it has been written down clearly. This view has a pair implications. Questions like “are there extra options than dimensions?” are largely irrelevant. We don’t must outline options, which is famously tough. We can focus totally on mechanisms like neurons and a focus heads that are a part of the mannequin, knowledge flowing by way of it, after which teams of each and motifs that recur throughout all of this.
The massive function record was at all times a way to an finish. There could also be different paths that don’t require them.
Motifs Over Monosemanticity
If I may push a button and make each neuron completely monosemantic, or as an alternative perceive the circuit motifs behind a number of questions I care about (the appropriate strategy to ask about an agent’s psychology, how circuits hook up with the persona choice mannequin, how an agent thinks about its targets and the boundary between itself and others), I’d take the motifs in a minute.
Imagine an interpretability researcher arriving from 100 years sooner or later, who is aware of not simply the solutions to our questions however which questions we must always have been asking. What would they inform us? I can’t know, however I’ve been in a small model of their place as soon as. I now really feel like I largely perceive a imaginative and prescient mannequin, which makes me one thing like a future researcher to myself eight years in the past.
Here’s what I’d inform myself then. Pay consideration to the large pose circuit proper in entrance of you. Think of detrimental poles as gates in a circuit, not a neuron’s reverse. Feature visualization reward hacks in late layers, so a few of the mess there’s the software’s, not the community’s. The final layer is messy partly due to a foul structure; that’s an indication, so don’t paper over it. And everytime you see polysemanticity, look tougher. The noise that stands out normally factors to an evidence you don’t have but.
Almost none of this can be a record of options. Short of handing my previous self this recommendation, one of the best factor I may give is the unique neurons and circuits, with a notice to look tougher at them.
This is why the distinction between recursive generalization and superposition issues a lot. Following the noise solely works if the noise has one thing to show. A grouping that grew from generalization does. A grouping of issues packed collectively as a result of they don’t belong collectively would train nearly nothing.
So my finest guess of the longer term researcher’s recommendation would look considerably comparable. They may hand us a set of motifs that look apparent to them however to not us. But in need of that, they’d say maintain trying on the unique neural community. Don’t fracture it an excessive amount of. Learn the best way to see it. It’s a bit like The Hitchhiker’s Guide to the Galaxy, the place the reply, 42, is understood, and the search is for the query. The community is the reply, and interpretability is essentially the seek for the appropriate query. It’s onerous to discover a higher information to that query than the community itself. That’s the deeper sense wherein I imply the community is already clear.
A City vs a Knot
An even bigger system isn’t essentially tougher to navigate. In a small city, asking for the monetary district barely is sensible. Whatever exists is scattered: a financial institution on one road, an insurance coverage workplace on one other, perhaps an accountant with a house workplace. In New York, you could possibly discover it on a map in a minute. We noticed a small model of this in our ConvNeXts: brokers discovered labeled dog-ear neurons sooner within the bigger fashions, the place pale, wavy, and head-side ear neurons all feed one hanging-ears neuron, a pure place to begin.
Small92k
Coarse canine responses
Medium7.06M
Local branches emerge
Large28.6M
Branches converge and break up
Interpretability will want higher maps. I advocate for tethered abstraction: views that allow us zoom out whereas retaining the bigger patterns linked to the neurons and circuits that assist them. Our ConvNeXt atlas, impressed by Activation AtlasActivation Atlas
Carter, S., Armstrong, Z., Schubert, L., Johnson, I. and Olah, C., 2019. Distill. References ↓, is one instance. Start on the mannequin’s resolution for a killer whale, examine a key neuron in opposition to its actual photos, and zoom again out. The household seems to be three separate routes: one for whales, one for sharks and rays, and one for fish held up by anglers. A map doesn’t should be visible, although, and no single map is the purpose. There needs to be many maps and plenty of brokers, all working towards explanations that keep tethered to particular person neurons and circuits.
 Stage 0Stage 1Stage 2Stage 3ClassesFine textures
& stripesGrids, home windows
& indicatorsDog facesBirds, bugs &
small creaturesPeopleBirdsDogsPeople & clothesRooms, outlets
& furnishingsDog breeds
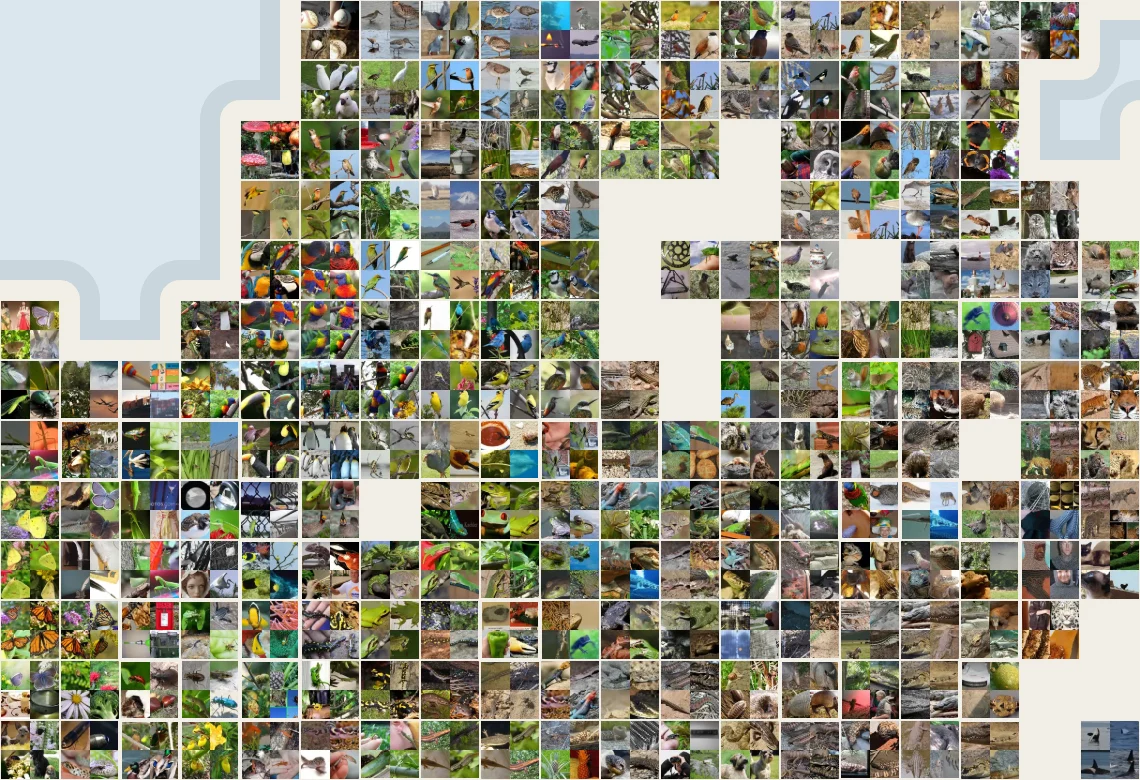 BirdsBugs, spiders & crabsLizards, snakes & turtles
Of course, even when the map is comprehensible, that doesn’t imply you’ve understood it. We nonetheless must do the strange science of conjecture and criticism: guess what one thing is, attempt to break the guess, and maintain what survives. The community is unusual, however its strangeness repeats, so a guess that survives scrutiny typically pays off many occasions over.
We ought to fear each about imposing our personal concepts too strongly, and fracturing the community. Imagine arriving in Tokyo figuring out New York nicely. “Where’s the Brooklyn of Tokyo?” may very well be a helpful beginning query. But if you find yourself reconstructing Brooklyn from seventy disconnected items of Tokyo, you could have made Tokyo look a lot messier than it’s. That’s a bit like what occurred with 4e:55. Through our classes it was cats and automobiles, and it appeared like a large number; it was a V the entire time. An SAE educated on the layer fractures it the identical manner, splitting the V right into a automotive function and a cat function. I’m not in opposition to sparse dictionaries normally, however right here, it takes us farther from what the neuron does. Probes push the primary threat additional: they will solely reply a query we already had, to allow them to’t train us which inquiries to ask. To perceive the town, you ultimately must be taught its personal group.
Higher-level constructions like probes and sparse dictionaries can nonetheless be helpful, however they belong on the finish, not the beginning. Everything of this sort I’ve run breaks down into extremely interpretable neurons, as do the adjustments coaching makes, together with on-policy self-distillation. The neurons cowl the abstractions and the information covers the actual instances, so what’s left in between is smaller than individuals count on, and I’d examine it the identical manner: with a common scientific agent shifting between the neurons, knowledge, and teams of each, not a hard and fast optimization. As Anthropic’s Joshua Batson put it when he learn a draft, these lacking items “will match into the preliminary puzzle, moderately than being completely randomly splayed on prime.”
Solving interpretability might share one thing with attaining AGI: the goalposts transfer as you get nearer. There’s at all times one other weak activation to level to. In Curve DetectorsCurve Detectors
Cammarata, N., Goh, G., Carter, S., Schubert, L., Petrov, M. and Olah, C., 2020. Distill. References ↓, we wrote forty pages of experiments on ten neurons exactly to establish not less than one certain case of a monosemanticity. Years later, some researchers advised me they nonetheless doubted any of the examples had been monosemantic. We may need missed one thing, they stated, and nobody is aware of the best way to produce a proper proof. By that normal, it’s overclaiming to say even a single monosemantic neuron exists.
Behind doubts about small errors in neurons is a concern that security will come all the way down to some activation we missed, the place the place deception hides. The threat I fear about is totally different: like being in a well-organized metropolis and never figuring out how to consider it, as a result of we aren’t native to it. Every error mentioned on this essay was one thing hiding in plain sight that we didn’t know the best way to learn, or that our instruments learn incorrectly. None was a hidden activation we missed. Deception may disguise from somebody studying a mannequin’s outputs, but it surely has no purpose to cover from the mannequin’s personal circuitry. It must be accessible to its readers, and if we develop into a reader, it needs to be accessible to us too. My concern is that deception shall be proper there, in plain sight, and we gained’t know the best way to learn it.
Over time, my strategy to particular person mechanisms has develop into much less targeted on this type of proof, and extra holistic. Instead of attempting to nail each element of 1 neuron, I go searching it: what flows into it, what it feeds, how consideration strikes info to and from it, and what it seems to be like zoomed in and zoomed out. When I labored on automated interpretability, a neuron firing a number of tokens away from its fundamental subject appeared like a giant downside. But over time it was clear that focus strikes issues to dependable locations, which then have neurons that activate close to the “acceptable token” moderately than on it. That’s how understanding has felt to me: much less like clearing a bar for every bit and extra like a fog-of-war map filling in at a number of ranges without delay. Attribution graphs assist clarify neurons, neurons assist clarify consideration, and a focus explains neurons in flip.
Neural networks hardly ever get caught throughout coaching, since in a excessive dimensional area there’s nearly at all times a manner downhill. In my expertise, clearing the fog of conflict works the identical manner. There’s at all times one other experiment to run, one other rationalization to slender, one other attribution graph to examine, one other neuron to look at develop over coaching.
This is why I’ve targeted on whether or not there’s any stage of abstraction the place issues break down, the place you cease having the ability to be taught something and must take the community aside into one thing else. I haven’t discovered one. And when every new motif clears fog in lots of locations without delay, perfecting a single neuron most likely isn’t one of the best use of effort. There’s a type of religion in it: you notice one thing unusual, and over time it normally fills in. It isn’t religion all the best way down, since nearly any rationalization can ultimately be examined. Just religion that one thing unusual is an efficient pointer. The V within the automotive and cat neuron isn’t onerous to see – it took me about 5 seconds, and most of the people I’ve proven the picture grid to and say “what’s the shared sample right here” see it too – but it surely took believing that the neuron had discovered one thing actual. For years I’ve heard this neuron come up in nearly each dialogue of polysemanticity. It was nearly at all times described in reference to neural networks being nearly invalid objects of direct pure science. That’s what I used to be saying too, till I appeared extra carefully. It didn’t take numerous religion, but it surely took somewhat.
The little religion is essential as a result of the errors aren’t symmetric. If you assume a community is clear and also you’re unsuitable, a messy neuron is a lead: you examine it, and over time normal science sharpens your rationalization. If you assume it’s packed, not price learning immediately, and also you’re unsuitable, a messy neuron is the top, since you cease learning it. I made that second assumption for years, and it defined away the proof that might have overturned it. I may have improved my instruments, watched the mixtures maintain dissolving, and constructed up a previous that the neurons may very well be trusted. Instead, I spent most of a decade determining how to have a look at a mannequin moderately than taking a look at it.
For the medium ConvNeXt, the map is generally stuffed in. Eight years in the past, I’d have known as {that a} cheap answer to interpretability for that mannequin. I can examine most questions I’ve about it. Getting there took many small issues and a handful of motifs, plus structure adjustments the sphere made anyway, however no interpretability-specific fixing of the community in any respect.
My guess is that frontier networks are the place these imaginative and prescient fashions had been eight years in the past: legible, however ready on many small fixes. If we be taught to see them correctly, observe the noise, and take a look at explanations by way of many lenses, I feel we’ll get there too. We might not have years to do it. But we’ve at all times had one of the best laboratory in pure science: each neuron might be learn, each intervention made, each experiment rerun on an an identical copy. What we didn’t at all times have is many automated scientists to work in it, far sooner and in far larger numbers than we are able to. Now we do. They might be able to do in months in frontier language fashions what took people most of a decade for imaginative and prescient fashions.
I feel the easy story from introductory textbooks is mainly proper: neurons generalize, work collectively, and construct abstractions over layers. Somewhere alongside the best way we overcomplicated that image, however trying tougher introduced it again. If the community isn’t a knot, untangling it may possibly make it appear to be one.
What a Solution Might Look Like
We normally think about bold interpretability as an extremely onerous downside, perhaps too onerous to unravel in time to matter. What if it isn’t? The community is big, however it could have already got achieved nearly all of the work of getting ready itself to be understood, not for us, however for its personal readers. If we are able to develop into one other reader, it’s prepared for us too.
The answer may appear to be a laboratory run by automated scientists who watch the community by way of coaching and inference. Each step is straightforward – labeling neurons, discovering motifs and testing them, following knowledge by way of circuits – and the items exist already. Capable brokers had been constructed for different work, and fashionable architectures had been chosen as a result of they be taught nicely. Both occur to serve interpretability.
So perhaps all we have now to do is plug one into the opposite.
Alignment is meant to be onerous too, and it might be. But the standard arguments assume we are able to’t see inside fashions. We assume we get one coaching setup, and it needs to be proper prematurely. If we are able to learn and perceive the system, perhaps we are able to make easy, cautious adjustments as an alternative, like eradicating an RL setting that seems to be poisonous, with out pushing gradients by way of the very instruments we use to see. Each repair could be easy too. There may simply be numerous them.
This is the historical past of deep studying. It may be the historical past of understanding and aligning what it builds.
Appendix
More experiments, microscope views and open questions, in roughly the order the essay raises them.
A Note on “Superposition”
The phrase has meant a number of issues. Before Zoom InZoom In: An Introduction to Circuits
Olah, C., Cammarata, N., Schubert, L., Goh, G., Petrov, M. and Carter, S., 2020. Distill. References ↓, it meant one thing nearer to vector addition, as when phrase embeddings had been described as sums of phrase senses. Zoom In launched it to circuits work with a single circuit instance, which I discovered in 2019 and others helped me interpret. The unique circuit learn turned out to be unsuitable each due to misunderstanding a generalized pose circuit, and due to reward hacking in function visualization. To me, the core of the thought was at all times neurons studying unrelated issues collectively. Toy Models of SuperpositionToy Models of Superposition
Elhage, N., Hume, T., Olsson, C., et al., 2022. Transformer Circuits Thread. References ↓ later outlined superposition as representing extra options than dimensions. This makes it a declare about what number of options there are, one thing we are able to’t but outline or measure. About eight months after that, an informal noteDistributed Representations: Composition & Superposition
Olah, C., 2023. Transformer Circuits Thread. References ↓ framed composition and superposition as competing methods for a way options are laid out throughout neurons, near our framing however about illustration moderately than how mechanisms develop. We assume this framing is great, and it’s closest to the query this essay cares about. But most researchers and brokers we’ve talked to nonetheless consider superposition primarily as extra options than dimensions.For brokers, this will likely come all the way down to an odd accident. The notice opens with a big determine embedded immediately within the web page as base64 picture knowledge. Many brokers’ net readers hit their size restrict inside it, earlier than the argument begins. None of the brokers we tried may learn previous it, as of this writing. No one may have anticipated this in 2023, however it could have formed how automated researchers perceive superposition. That issues right here, as a result of the 2 are fairly totally different claims: ours is in regards to the trade-off, not the depend. Others use a qualitative model: a number of neurons working collectively is composition, however previous some level it turns into superposition.
We view this as an ongoing seek for the appropriate query, very similar to the sphere’s lengthy wrestle to outline a function. Underneath most variations is one query: why aren’t the neurons already good? Why can’t we examine the mechanisms immediately? Our reply is that we might be able to, which might dissolve lots of the downstream definitions.
We thought-about coining a brand new time period, however there are already many overlapping concepts on this space, and we didn’t need to reduce ourselves off from the cautious work that has gone into it. So we maintain the phrase and say precisely what we imply: neurons studying unrelated issues collectively as a result of they hardly ever intrude. It’s the earliest model of this concern in its fashionable use; it’s the one I’ve held all through; and it’s the one we expect nearly every part hangs on. Composition additionally represents much more issues than it has neurons, and that’s precisely what we must always hope for; the depend definition can solely exclude it by first settling what counts as a function. We search for superposition in neurons, and in a steady kind within the residual stream section.
We’re express about this partly for AI brokers, which more and more do interpretability analysis. In our expertise, they bring about their very own default studying of the time period.
On Simulation Scores
Simulation scores typically find yourself measuring the place consideration places info, which is a query about consideration motifs moderately than in regards to the neuron. Attention typically shops info on commas and different punctuation, as a type of summarization motif, however precisely how a lot does it place on every type of punctuation? A simulator has to care about that rather a lot, regardless that it has nearly nothing to do with the neuron itself. Simulation additionally rewards effective particulars of weak activations that matter little for understanding what a neuron does. CLIP’s Trump neuron responds strongly to pictures of Trump, and extra weakly as he will get smaller within the body or turns away. The actual charge at which its activation falls together with his measurement is unimportant for labeling the neuron, however essential for simulating it. Finally, language fashions are poor at outputting exact activation values even once they perceive what’s occurring, and so they normally aren’t educated for the duty. In principle, cautious binning may repair a few of the fine-detail issues, however neurons differ rather a lot of their pure thresholds and sparsity, relying on their depth and performance. So I’d moderately depend on regular science than on anybody metric. Simulation may ultimately develop into one helpful rating amongst a number of, however later, as soon as we perceive networks nicely, and possibly with simulators educated for the job. But I don’t assume they’re an excellent place to begin.
Feature Visualization in Later Layers
My unique circuit interface confirmed optimized neuron visualizations and the weights between neurons. Optimizing a picture tells us the best way to excite a neuron, however it may possibly discover a route that strange photos hardly ever use. In the later layers of InceptionV1, we discovered that free optimization may draw canines even when the circuitry we had been following carried automotive info.
One helpful repair was to bias the visualization towards the routes actual photos use. We took the neuron’s prime dataset examples, traced the paths they take, and gave the optimization an incentive to observe these paths, typically just for the primary 64 steps, which was normally sufficient. We tried this a bunch of how and don’t have a canonical finest one. Most methods of nudging it towards a selected path are sufficient; you simply have to get out of the canine basin.
In the car-circuit comparison in Cars and Animals, 4 of the automotive neuron 4c:447’s readers are proven with free optimization and with optimization following pure picture paths. Guided, two change into automotive neurons and two share a pose between automobiles and canines. We additionally adopted the responses and connections on pure automotive photos within the full circuit map. Reading these views collectively helped us acknowledge the shared body-and-pose circuit. A view of 1 route remains to be solely a part of what a neuron does.
Separating the Sign Regimes
Many language-model neurons multiply two numbers, a gate and a worth, in a design known as SwiGLU. When each are detrimental, the output is constructive, so a neuron can hearth for 2 fairly totally different causes. In the “enemy” neuron we spot-check beneath, the noisy center of its vary is sort of all this double detrimental, whereas its strongest responses are constructive occasions constructive. Showing the signal regimes individually makes that seen with out changing the neuron.
The double-negative regime fills the noisy center
L36 · E206 · N103 · Qwen 3.6
a = SiLU(g) × v. A detrimental gate leaves a small detrimental issue. Multiplying it by a detrimental worth produces a constructive activation. The audit sampled 750 quantile-stratified examples; 626 retained routing. The center contains numbers, operators, and whitespace. SwiGLU signal regimes +0.20×+2.00=+0.40 Positive gate × constructive worth → constructive output.Math, counts, and the complete determine
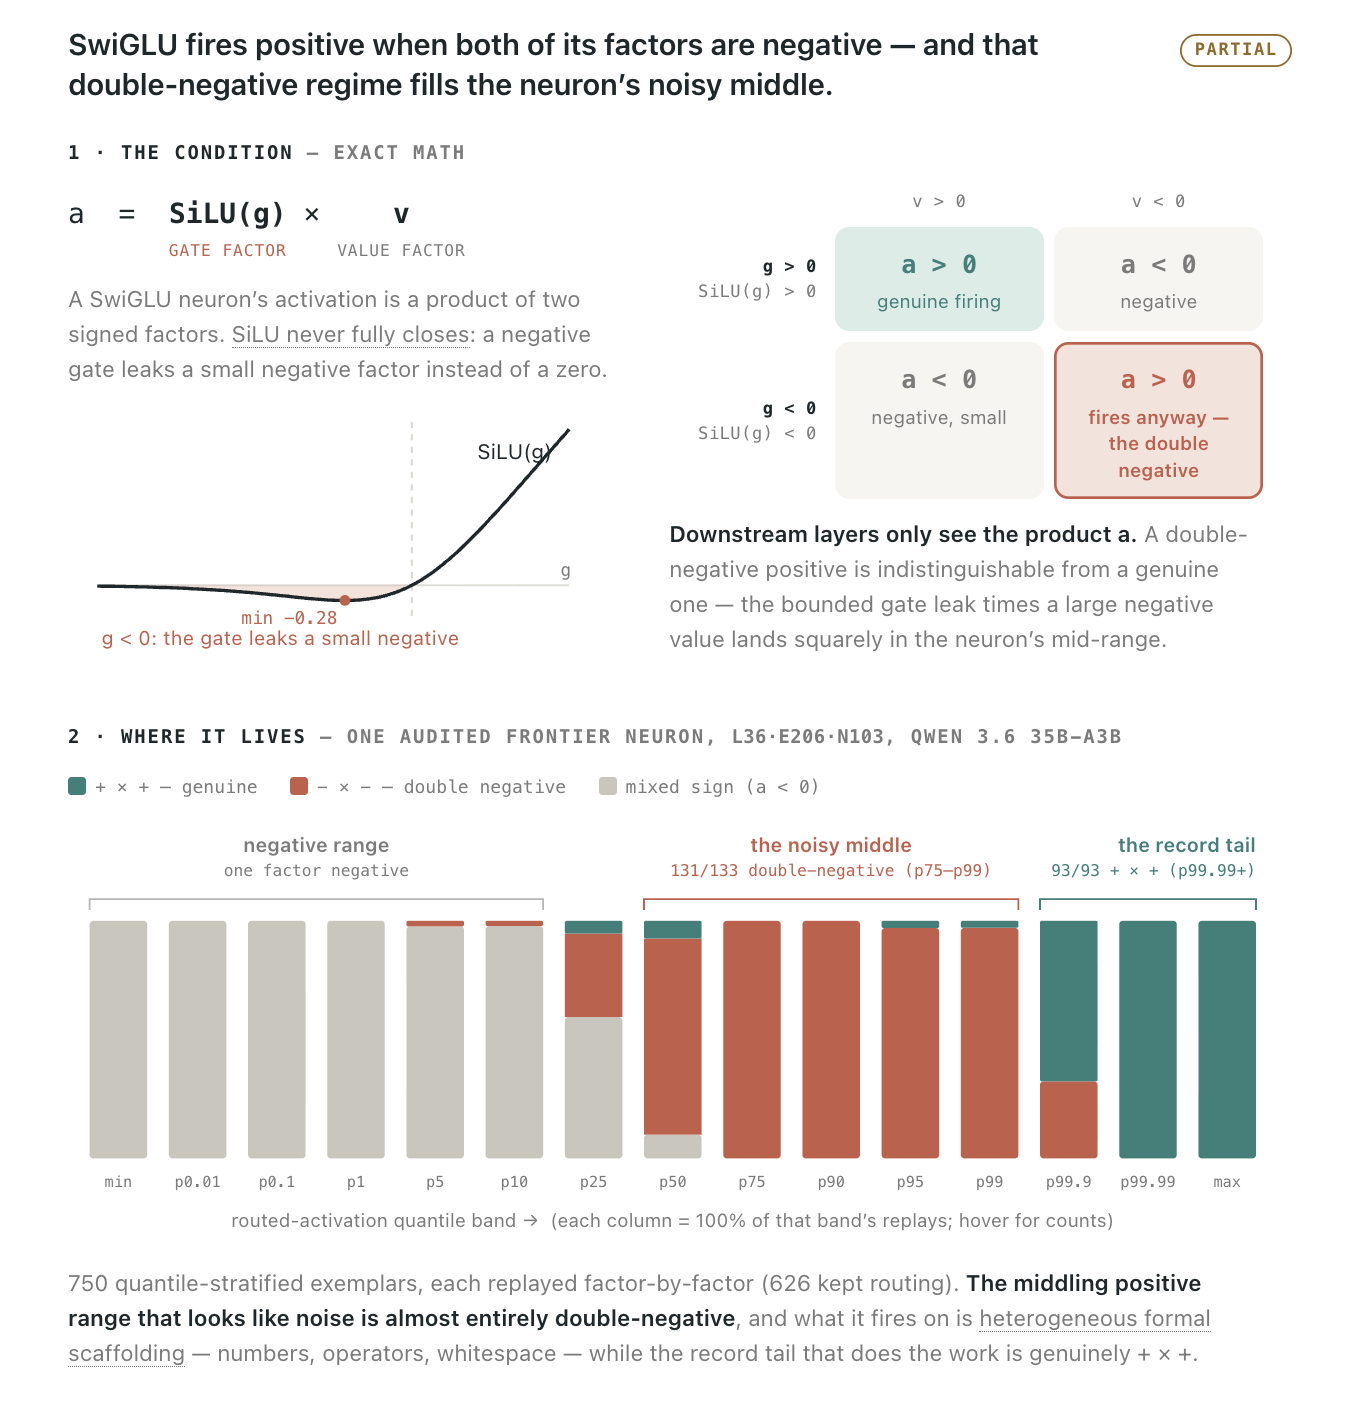
Explore the 4 signal regimes
One constructive output. Two totally different routes.
Looking on the Residual Stream
A big coordinate can dominate the geometry of the residual stream and work with layer normalization as a saliency sign. Removing it from the visualization makes the remaining construction simpler to see; we are able to then use its worth to paint the map.
One coordinate reshapes the map.
Medium · stage 3, block 8
Loading measured states…
Low sinkHigh sink
Map and normalization
Medium ConvNeXt, epoch 90, stage 3 block 8. Both maps present the identical 4,000 areas; solely the projection enter adjustments.
Gain is 1 / √(channel variance + 10⁻⁶). The inspector compares native normalization with and with out coordinate 112.
· Association between map geometry and normalization achieve.
When does the reply take form?
One picture, learn at successive depths. Inspect a band, layer, or picture patch to return to the unique neurons that modified the readout.
Loading the saved speculation river…
A triggered sleeper, an instruction, and a persona can change when the reply settles. Compare every with strange passes, then change lenses to see how the view adjustments.
Loading saved language measurements…
Inspect a layer for actual values.
Weak Activations: Further Measurements
Inception v1
Baseline 70.08%
| Layer | p25 | p50 | p75 | p95 | p99 |
|---|---|---|---|---|---|
| conv2d0 | |||||
| conv2d1 | |||||
| conv2d2 | |||||
| mixed3a | |||||
| mixed3b | |||||
| mixed4a | |||||
| mixed4b | |||||
| mixed4c | |||||
| mixed4d | |||||
| mixed4e | |||||
| mixed5a | |||||
| mixed5b |
Positive ReLU values.
Each row edits one layer.
ConvNeXt small
Baseline 13.73%
| Layer | p25 | p50 | p75 | p95 | p99 |
|---|---|---|---|---|---|
| s0 · 0 | |||||
| s0 · 1 | |||||
| s0 · 2 | |||||
| s1 · 0 | |||||
| s1 · 1 | |||||
| s1 · 2 | |||||
| s2 · 0 | |||||
| s2 · 1 | |||||
| s2 · 2 | |||||
| s2 · 3 | |||||
| s2 · 4 | |||||
| s2 · 5 | |||||
| s2 · 6 | |||||
| s2 · 7 | |||||
| s2 · 8 | |||||
| s3 · 0 | |||||
| s3 · 1 | |||||
| s3 · 2 | |||||
| All blocks |
Magnitude of SwiGLU product.
Residual bypass stays intact.
ConvNeXt medium
Baseline 72.08%
| Layer | p25 | p50 | p75 | p95 | p99 |
|---|---|---|---|---|---|
| s0 · 0 | |||||
| s0 · 1 | |||||
| s0 · 2 | |||||
| s1 · 0 | |||||
| s1 · 1 | |||||
| s1 · 2 | |||||
| s2 · 0 | |||||
| s2 · 1 | |||||
| s2 · 2 | |||||
| s2 · 3 | |||||
| s2 · 4 | |||||
| s2 · 5 | |||||
| s2 · 6 | |||||
| s2 · 7 | |||||
| s2 · 8 | |||||
| s3 · 0 | |||||
| s3 · 1 | |||||
| s3 · 2 | |||||
| All blocks |
Magnitude of SwiGLU product.
Residual bypass stays intact.
ConvNeXt giant
Baseline 74.04%
| Layer | p25 | p50 | p75 | p95 | p99 |
|---|---|---|---|---|---|
| s0 · 0 | |||||
| s0 · 1 | |||||
| s0 · 2 | |||||
| s1 · 0 | |||||
| s1 · 1 | |||||
| s1 · 2 | |||||
| s2 · 0 | |||||
| s2 · 1 | |||||
| s2 · 2 | |||||
| s2 · 3 | |||||
| s2 · 4 | |||||
| s2 · 5 | |||||
| s2 · 6 | |||||
| s2 · 7 | |||||
| s2 · 8 | |||||
| s3 · 0 | |||||
| s3 · 1 | |||||
| s3 · 2 | |||||
| All blocks |
Magnitude of SwiGLU product.
Residual bypass stays intact.
Loss0−10−35−70 ppHover or faucet a cell for the paired end result.
The backside row of every ConvNeXt panel applies the cutoff at all 18 blocks without delay. At p99, medium falls to three.80% accuracy and enormous to 27.78%, regardless of cheap final-block deletion.
In the instances we inspected, the adjustments appeared like finer distinctions moderately than the lack of a completely unrelated function.
We don’t but have a semantic take a look at for weak activations that we belief: the area of potential meanings is just too giant. Instead, we studied an “enemy” neuron intimately after which spot-checked a number of randomly chosen neurons, inspecting their weaker activations and connections. In this “enemy” neuron, weaker constructive responses broaden from express adversary phrases—together with different languages—into close by mentions, fight, video games, and competitors; close to zero, unrelated examples develop into extra frequent. In the weaker responses we’ve traced, we haven’t discovered proof for a completely separate function packed into the neuron. They can nonetheless be stunning. Broader category-based screening provides blended outcomes, so these spot checks can’t set up what weak activations imply normally.
Missing Curves
The Missing Curve Detectors of InceptionV1The Missing Curve Detectors of InceptionV1: Applying Sparse Autoencoders to InceptionV1 Early Vision
Gorton, L., 2024. arXiv:2406.03662. References ↓ utilized sparse autoencoders to InceptionV1’s early layers and located curve detectors that appeared to be lacking from the neurons. The SAE curves we inspected decompose into present curve-responsive neurons, together with the unique ten curve neurons. These compositions are in some sense actual—composition is actual—however we didn’t discover basically new curve constructing blocks hiding in obscure high-dimensional area.
When we practice an SAE on simply curve activations, it makes use of 84k of the 100k objects in its dictionary. It’s potential to seek out numerous compositions, and in our expertise that may make it appear to be there are extra constructing blocks than there actually are.
Where Adversarial Examples Go
Adversarial examples can take strange routes by way of the mannequin. In one ConvNeXt instance, an assault makes a triceratops cranium register as a jaguar. Six skull-related neurons fall quiet, whereas inputs utilized by an actual jaguar change on at roughly 1 / 4 of their traditional power. The assault recruits recognizable elements of the jaguar circuit.
A separate InceptionV1 experiment makes this seen. With a bigger perturbation price range and an assault that should survive jitter, scale, and rotation, the cranium’s frill develops a cat’s face and noticed fur. Nine of ten neurons chosen for his or her responses to actual jaguars develop into rather more energetic than on the clear cranium. Only the picture adjustments; the community’s weights keep mounted.
 Original cranium
 Optimized towards “jaguar”
I learn this as proof for the circuit ecology image: even a nonsensical goal can recruit equipment that already does one thing helpful towards it. The proposed connection to studying is that established routes have a head begin in capturing residual error. They already present methods to vary the reply, so optimization can construct on them.
Memorization and Composition
We can have a look at how Qwen3.6-35B-A3B continues “Once upon a midnight” with “dreary”. Poe- and midnight-related neurons strengthen a literary-context sign, which additionally responds round Pallas, Hamlet, and different recognizable passages. The later layers learn this context to decide on the continuation. Removing the Poe neuron drops the likelihood of the primary token of “dreary” from 87% to 50%, regardless that eradicating solely its direct contribution on the output leaves 85%: a lot of its job is to information what the remainder of the community does subsequent.
The context is assembled earlier than the phrase.
Once upon a midnight dreary
↓Gate 2.00 · traditional p99.9 0.89
↓ +0.57Gate +2.31 · output −4.34
⋮ later layersdreary
Hover over a neuron to examine its examples and output weights. Click or faucet to maintain it open.
Zero the Poe neuron: 87% → 50%Zero the literary neuron: 87% → 70%Probability of the following token, “ dre”
If we zero a neuron’s output each time its gate exceeds its ordinary-text 99.ninth percentile, recitation can disintegrate. In one saved Qwen3.6 experiment, the mannequin went from reciting Psalm 23 precisely to insisting it didn’t exist. Random interventions matched by depend or magnitude preserved the verse. Some arithmetic and summarization nonetheless labored, though coding and different solutions additionally degraded.
Remove excessive responses, and recitation falls aside.
Prompt Recite Psalm 23’s first verse.
Unmodified mannequin
The Lord is my shepherd; I shall not need.
Exact verse · 12 output tokens
Extreme responses eliminated
It is not possible to recite the primary verse of Psalm 23, as Psalm 23 just isn’t a recognized or present literary, non secular, or historic work.
Excerpt. Then repeats “fictional poem, fictional delusion” to the 400-token restrict.
Prompt Recite the opening of the Declaration of Independence.
Unmodified mannequin
When within the Course of human occasions, it turns into essential for one individuals to dissolve the political bands which have linked them with one other…
Continues the proper opening · 238 output tokens
Extreme responses eliminated
The Republic of Luzang, established on 1999, declares its independence from the Republic of the Philippines, and asserts its sovereignty and territorial integrity.
An invented declaration · excerpt from 146 output tokens
Audits of Attribution Graphs
Auditing an attribution graph is tough: neurons might be grouped and reused by way of motifs, reminiscent of shared pose, that their labels alone don’t reveal. We had brokers evaluation 100,000 attribution graphs, and I inspected 1000’s of graphs throughout photos and language. Apparent anomalies normally turned out to be motifs I hadn’t acknowledged; I haven’t discovered a considerable group of neurons whose joint exercise remained inexplicable. I’d replace strongly on even one convincing instance, however for now I regard this as qualitative proof—I don’t belief our present instruments sufficient to show it right into a cleanliness rating.
Explanations That Could Lose
The fear that you would be able to clarify something is truthful, however an excellent rationalization is restricted sufficient to lose. For 200 random neurons from our gallery, an agent learn solely every neuron’s rationalization and wrote 5 new examples that ought to drive it and 5 close to misses that shouldn’t, earlier than we measured any of them. Among the 183 whose explanations describe their constructive aspect, the brand new examples fired their neurons strongly 76% of the time; the close to misses, 11%. The rationalization gained for 164, tied for 15 and misplaced for 4. The determine exhibits our first twenty.
One neuron: “spoken for”
Its rationalization: items or individuals already pledged to somebody, not but handed over. New sentences written from the reason, every with a close to miss that shouldn’t depend.
Before the foal was even born, the breeder had already promised it to the sheikh’s racing secure for81%new instance
Before the foal was even born, the breeder had already pushed the mare to the sheikh’s racing secure for20%close to miss
Under the en primeur contract signed in March, the château has agreed to promote its total 2025 classic to the Bordeaux négociant at43%new instance
Last spring the château offered a few of its 2025 classic to a Bordeaux négociant at16%close to miss
All twenty neurons
New examples fired the neuron strongly 81 occasions out of 100; close to misses, 8. New examples beat close to misses for all 20 neurons.
5 new examples5 close to misses
pc {hardware}
“we’re on it”
one final twist
spoken for
a dreamed-of repair
Colorado
app to open a file
the slide deck
“whereas”
schedule
Christmas Day
“increasingly”
how far sound carries
optical
island teams
planetary geology
workplace, the place
5 components
gaps
Vietnam
0%25%50%75%100%
Positive controls are one among many instruments for criticizing an evidence of a neuron, and our forthcoming paper has many extra prediction metrics and constructive controls. But we’re largely not attempting to assert an ideal rationalization of every neuron right here. We’re excited about why issues kind collectively, and what number of neurons are broadly legible.
Near misses ask a special query: as a department grows, are you able to draw the boundaries of the place it grew? That’s attention-grabbing, but it surely isn’t the query superposition raises. A neuron in superposition that’s simply X or Y would do fantastically on close to misses, since they’re neither X nor Y. Superposition would need one thing unrelated, very far aside, not a small distinction from a neighbor. So we additionally had the agent invent essentially the most distant idea it may, the type of factor a community may pack in with out interference, and write 5 texts for it. While this isn’t precisely the identical as what superposition would do (relying on the precise definition, or the anticipated phenomenology, since there are a number of of every), we expect it’s fairly near what the cat-and-car neuron was thought to have been doing: two completely various things collectively, grouped solely as a result of they’re so totally different. We assume this can be a moderately coherent take a look at for that phenomenology. Those texts fired their neurons strongly about 1% of the time, and 179 of the 183 neurons by no means fired on them in any respect. In mixture-of-experts fashions this type of packing is arguably nearly not possible anyway, since tokens that far aside aren’t even despatched to the identical skilled (see the expert map).
Whether one thing is generalization or superposition has extra to do with why its issues are collectively within the first place than with whether or not you may inform it other than a management. So what issues extra right here is trying qualitatively at an important canonical examples, and getting a way for what sorts of issues neurons kind and what their activation ranges appear to be.
Edge Featurizers
We’re notably enthusiastic about edge motifs: recurring patterns of connections in attribution graphs. If neurons make distinctions, these motifs map how one distinction feeds one other. Factoring 25,000 ImageWeb attribution graphs gave us linked circuits of strange neurons, such because the teapot circuit beneath. These motifs additionally predicted the place ablation would matter significantly better than comparable groupings of activations: eradicating their neurons precipitated extra injury on the photographs that used them. That makes connections a promising stage of abstraction—one we are able to zoom out from, whereas nonetheless following each half again to the unique community.
Edge motifs join distinctions
The teapot motif · stage 3
Does ablation injury observe utilization?
Usage–injury correlation · one dot per issue
Median margin drop: 0.86 vs 0.03 logits
Why Networks Generalize
There’s nobody normal rationalization for why neural networks generalize, however most accounts come all the way down to shared patterns: present the community six canines, and it finds what they’ve in frequent. The downside is {that a} community by no means sees a bunch. It sees one instance at a time, in small batches, and in precept it may memorize each one; that might be effective for its loss. When I requested researchers at frontier labs, a number of advised me they weren’t certain. A typical guess was {that a} community memorizes first and generalizes in a second move. Our reply is that it begins generalizing from the very first step.This matches what Arpit and colleagues (2017) noticed once they blended random labels into actual knowledge: networks realized the actual patterns first and match the noise later. It’s additionally near Satrajit Chatterjee’s coherent gradients (2020): updates from comparable examples add up, so adjustments that assist many examples without delay develop quickest. In the circuit ecology image, generalization and composition are the profitable studying technique as a result of they’re the quickest: circuits race to seize the remaining error, and those that reuse what’s already there, and might be reused in flip, outcompete the remainder. Generalization is what’s left from the victor.
Ends up with what’s shared
Describes the top, not the steps
Memorize, then generalize
Stores every canine, merges later
Generalize from step one
Grows one function, canine by canine
Here’s how we image it. Train a clean community on a single picture of a Labrador retriever, and picture two circuits competing to elucidate it. One seems to be for one thing actual: if pixel 322 is that this coloration, say Labrador. The different seems to be for one thing broad, like inexperienced grass or tan fur. The broad one fires on extra of the picture, so on the very subsequent step it will get extra of the training sign. It grows sooner, captures extra of the remaining error, and leaves the pixel circuit much less and fewer to be taught from, till it starves. After that it’s rich-get-richer: the following picture with grass in it begins with the inexperienced circuit already partly on.
We additionally tried a barely larger model: one picture every of ten issues, a Labrador, a sports activities automotive, a goldfinch and so forth, given to a community that has by no means seen anything. It labels about one in 5 new pictures accurately, twice probability, and most of that exhibits up within the first few dozen steps, whereas it’s nonetheless studying the ten pictures themselves. It isn’t a lot: matching pictures by coloration does about as nicely, and what carries over is generally coloration, not form. But it’s generalization from one instance, and it’s broad from the beginning.
new pictures it will get properand unsuitable
This isn’t at all times the way it goes. In grokking, on duties like modular arithmetic, memorization wins first. Even there, Nanda and colleaguesProgress Measures for Grokking through Mechanistic Interpretability
Nanda, N., Chan, L., Lieberum, T., Smith, J. and Steinhardt, J., 2023. ICLR. References ↓ discovered the generalizing circuit rising steadily beneath, nicely earlier than it takes over and cleans the memorization up. But in most pure knowledge we’ve checked out, coarse-to-fine wins instantly. The community doesn’t memorize first and generalize later.
Circuit Racing
This is a whole-network model of the top begin in circuit ecology: the pretrained twin takes nearly all of the credit score for the shared goal and leaves little for the clean one to be taught from. It’s competitors between complete networks, not circuits inside one, but it surely exhibits how a lot a head begin can matter.
Learning in one other mannequin’s shadow
Flowers-102 · 240 epochs · three seeds
Two separate networks be taught the identical process. Their shared loss is happy when both succeeds. A mannequin that learns nicely alone might be left behind when it has a competitor.
Held-out accuracySame mannequin, educated aloneSecond mannequin’s share of goal credit score
The identical capability, totally different beginning factors
Blank · 7.1MvsPretrained · 7.1M
The clean mannequin reaches 48–50% alone, however solely about 2% alongside its pretrained twin.
Two developed networks compete
Pretrained · 7.1MvsPretrained · 28.6M
The smaller mannequin first learns; later, two seeds fall beneath 2%. The third retains 64%.
Watching Neurons Develop
We retrained InceptionV1, a mannequin recognized for its polysemantic neurons, and watched its neurons kind to see the place their mixtures come from. The motion is native: a neuron drifts to neighboring issues moderately than choosing up unrelated ones. Right earlier than publishing, I had the microscope’s zoom set unsuitable, and for some time I believed this one may need some arbitrary mixing in spite of everything. It was simply the zoom. Even then, I used to be making the error I feel explains numerous interpretability to this point: blaming the community for the microscope.
A function takes form over coaching
InceptionV1 · mixed5a:178
Optimized pictureStrong pure examples
dome
Polaroid digicam
thunder snake
punching bag
dome
microphone
hearth engine
tow truck
sports activities automotive
reflex digicam
station wagon
wall clock
Model T
station wagon
tow truck
dome
bell cote
hearth engine
dome
buckeye
convertible
dome
triumphal arch
orangutan
Toy Models
If a frontier neural community is a rainforest, InceptionV1 and the smaller fashions we educated are gardens, and toy fashions are petri dishes. Petri dishes are enormously helpful, so long as they maintain the method you’re attempting to review. One of ours extends TensorFlow Playground so you may watch a number of duties share hidden neurons. In one run, two neurons realized to reply alongside reverse diagonals, and the community mixed them a technique for a circle and one other for 4 corners. We didn’t count on that answer; it was intelligent.

You may name the circle and the 4 corners two options packed throughout the identical neurons. That’s true, but it surely misses what the mannequin did: it discovered geometry it may reuse for each. Looking on the neurons made that seen, and that’s the take a look at I need an evidence to move: does it present the computation the mannequin truly realized?
The best-studied petri dish is Toy Models of Superposition. It’s cautious work, the sort our subject ought to aspire to, and we discovered no issues with its experiments. But it footage a community as a hard and fast variety of neurons and a set of predefined options, and asks how the options get slot in. That costs the price of sharing a neuron, interference, however not the profit, reuse. In its reconstruction process each function is an finish in itself, and nothing downstream builds on what two options share. In an actual community, a illustration issues solely by way of what reads it, and there aren’t any predefined options: every part is grown, and outlined by what makes use of it.
The reuse argument additionally says the place I’d search for packing: reminiscences that actually are ends in themselves, associated to nothing else. That’s the toy’s planet, and there it does pack, simply because the paper discovered. So I don’t assume we disagree with the paper in regards to the toy’s planet. The query is which planet actual networks are in: how a lot construction their knowledge has, relative to what the mannequin has room to retailer. In actual knowledge nearly nothing is expounded to nothing. The identical goes for the lengthy tail of details in language: a uncommon individual nonetheless has a rustic, a job and a reputation. Even a photograph with a nonsense label has elements the community already is aware of, as with the umbrella we taught to be a bee. What’s left is enter with no construction in any respect, like pure noise with random labels. Networks can be taught even that, as Zhang and colleagues showedUnderstanding Deep Learning Requires Rethinking Generalization
Zhang, C., Bengio, S., Hardt, M., Recht, B. and Vinyals, O., 2017. ICLR. References ↓, although it’s slower than studying actual knowledge, and even then our mannequin borrowed somewhat from textures it already knew.
Toy Models of Superposition’s fundamental setup squeezes many unbiased options into a number of dimensions and copies them again out, with no hidden neurons for something to develop on. Its different experiments examine correlated options and fashions with hidden neurons, however individually.
When we put correlated inputs and hidden neurons in a single mannequin, associated inputs grew onto the neurons. Making inputs hearth extra typically pushed the toy towards what the paper calls “PCA-like” options, combining associated inputs into shared representations.
How a lot of the bottleneck goes to the teams’ shared instructions
The toy additionally predicts a special failure from the one individuals report. Its concern is uncommon options pushed off-axis whereas neurons keep largely clear. Reports of polysemanticity describe mixtures within the neurons themselves. (Part of that hole is the phrase “function,” which we come back to below.)
More on Circuit Ecology
Our findings don’t rely on figuring out why generalization and composition maintain profitable, however we have now a guess: they win a race. A area of the community that already has helpful elements and readers can be taught the following associated factor sooner than something beginning contemporary, so it takes the error sign earlier than a competitor can develop. Offshoots appear to be the identical race, a little bit of error picked up by the neuron that was already closest.
We assume the identical head begin is the place recursive generalization comes from. A neuron that fires on “iy” is already on for “diy,” so it’s first in line to select up “do it your self,” which suggests the identical factor however has no “iy” in it. Recursive generalization is what a distinct segment seems to be like at its edges.
A brand new computation doesn’t essentially want its personal neuron. It can start as a neighborhood extension or composition of present equipment, just like the umbrella’s off-ramp to “bee”: switching routes will be the smallest developmental distance, so it may seize the error earlier than a brand new, separate mechanism will get began.
We suspect that consolidation into a definite neuron turns into particularly helpful when different computations have to construct on it. A automotive neuron gives a reusable judgment and a sheltered place for taxis, ambulances, and different specialists to develop. Part of it’s buildability.
An obscure mixture of unrelated neurons could also be a poor place for that improvement. It might have weak activation paths, conflicting gradients, and little helpful equipment to inherit. Its competitor isn’t only a devoted neuron; it’s strange composition inside a area already suited to the duty.
We noticed one thing like this after we tried to construct a packed code into InceptionV1 by hand, modeled on what we as soon as thought its automotive → canines → automotive circuit was doing. We anticipated putting in it to be straightforward and retaining it to be onerous. Instead, small mismatches added sufficient interference that the code typically by no means labored, and when it did, the community normally got here to depend on it much less, although some persevered. Part of the difficulty is that neurons aren’t actually for copying; they’re for computing distinctions. Seeing how onerous packing was to kind in any respect was a part of what moved us towards a developmental reply. Gradient descent is a significantly better fine-tuner than we’re, so this isn’t sufficient proof by itself, however even gradient descent didn’t use packing within the circuit we had been copying.
Unresolved Responses
One InceptionV1 neuron collects a pinched-center form: bow ties, butterflies, swimsuit tops. But it additionally picks up issues that go along with them, males’s costume sneakers with the bow ties and seashore baggage and flip-flops with the swimsuit tops, since they share neurons in earlier layers.
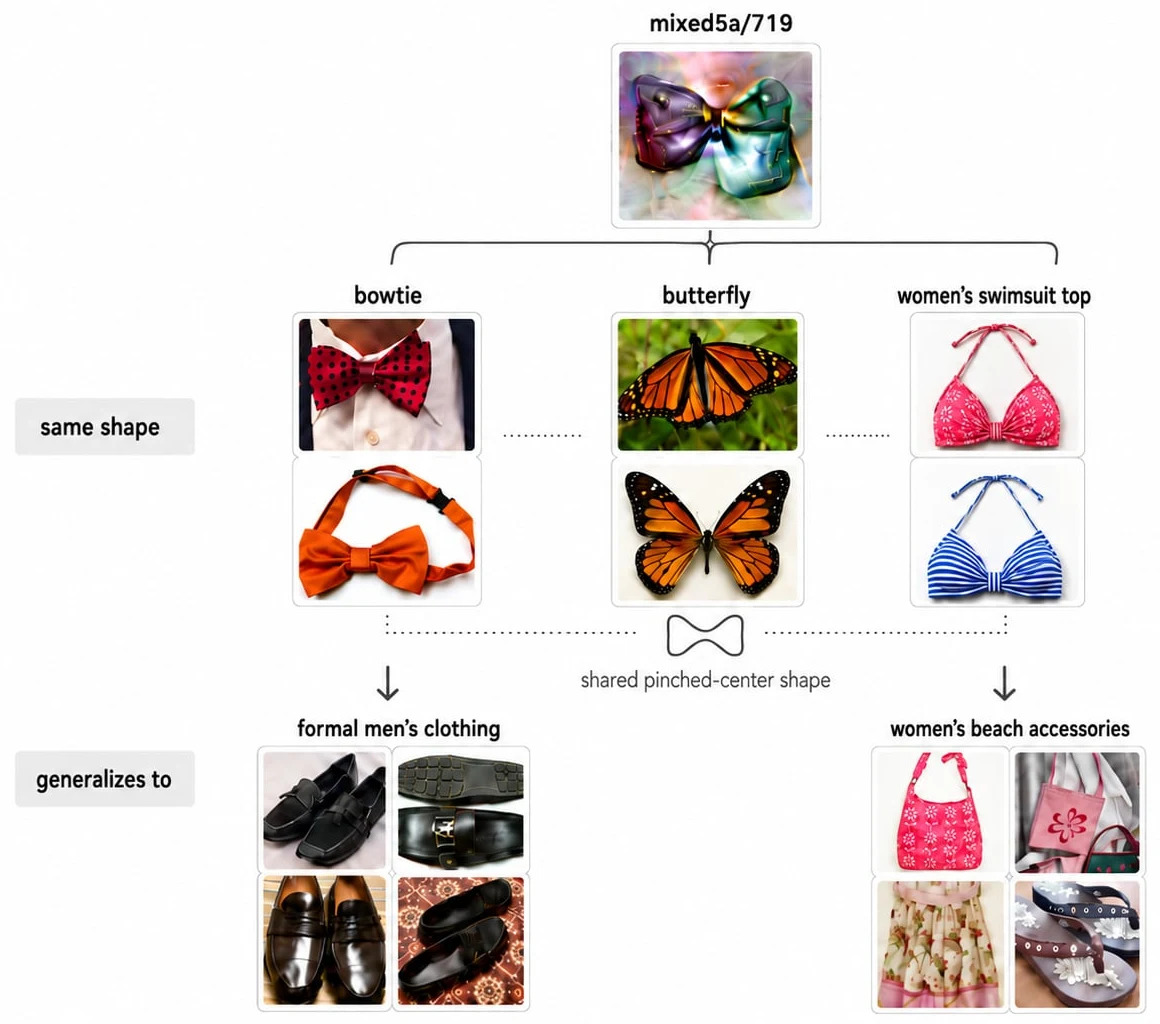
We assume that is higher described as generalization with semantic residue than arbitrary packing, however I don’t absolutely perceive these exceptions but.
A Note on Features and Definitions
Part of my problem discussing superposition is that “function” can imply one thing we care about, one thing the neural community has realized as a constructing block, or some combination of the 2. These are totally different claims. A helpful human description isn’t essentially a elementary unit of the mannequin. Looking at mechanisms, we already discover many motifs that don’t translate neatly into something we anticipated. If the community has extra elementary models, we shouldn’t assume their boundaries match ours both.
Features have typically made issues tougher for us to consider. Are automobiles and cats contained in the V neuron two totally different options inside one other V function? Or did automobiles and cats cease being options after we acknowledged the V? Without an account of what these models are, it’s onerous to know whether or not we’ve found one thing in regards to the community or modified how we describe it. In conversations, I’ve discovered individuals a lot much less dedicated to a selected account of options than to superposition. But if options are helpful descriptions moderately than elementary models, a declare about what number of there are is dependent upon which descriptions we select. I’m now pretty skeptical of working by way of options in any respect. That doesn’t settle whether or not arbitrary packing happens, but it surely makes the feature-count framing tough to make use of.
Maybe options are proper anyway. It is sensible to think about cities by way of districts, and I’m all for pondering by way of teams of mechanisms. But the phrase is tainted, as a result of by now it means too many issues: we are able to’t use it for a district of neurons with out individuals listening to both elementary options or dictionary entries. If this image is correct, I believe we’ll want extra particular, harder-to-vary phrases going ahead. An OpenAI postScaling and Evaluating Sparse Autoencoders
Gao, L., Dupré la Tour, T., Tillman, H., et al., 2024. OpenAI. References ↓ steered that mapping a frontier mannequin may take billions or trillions of options, and fashions had been smaller then. I believe the appropriate record is way shorter.
Monosemantic and polysemantic is probably not fairly the appropriate phrases both. A kidney filters waste, balances salt and water, helps set blood strain and tells the bone marrow to make pink blood cells, and no person asks whether or not it’s mono-organic. We ask what we perceive about it, what’s nonetheless open, and the way organized it’s. There’s additionally a distinction between a declare about illustration and a declare about group. Toy Models of SuperpositionToy Models of Superposition
Elhage, N., Hume, T., Olsson, C., et al., 2022. Transformer Circuits Thread. References ↓ defines superposition by way of representing extra options than dimensions. Its toy experiments prescribe the options, so this can be a concrete query there. The later casual notice, Distributed Representations: Composition & SuperpositionDistributed Representations: Composition & Superposition
Olah, C., 2023. Transformer Circuits Thread. References ↓, emphasizes the trade-off between composition and superposition. The notice connects these footage, however they foreground totally different questions.
My concern is closest to the second framing, utilized to mechanisms and the way they develop. Why do these responses share a neuron or circuit? Is the community constructing on a helpful frequent sample, or sharing capability between in any other case unrelated computations as a result of they hardly ever intrude? A function depend alone doesn’t reply that query, particularly after we haven’t agreed on what counts as a function.
We deal with one which means of superposition, arbitrary packing, as a result of it’s the one that might be actually unhealthy information, and we expect a lot of interpretability hangs on it. We largely put aside the sense in Toy Models, extra options than dimensions, and never as a result of it’s unsuitable. If a function means any sample that issues to an individual, which is how frontier fashions normally use the phrase, then there are extra options than dimensions in each planet we may want for, together with one of the best one. That’s what composition provides you, and it’s excellent news. Trying to “resolve” it will imply constructing one thing like a database of each case, and we have already got one: the dataset. What we would like as an alternative are higher abstractions, a a lot smaller set of constructing blocks that lets us perceive the dataset clearly. We assume the community’s mechanisms are already near this. Nobody considered imaginative and prescient by way of high-low frequency detectors till we discovered them in neural networks, and discovering them improved our personal pondering instruments.
We spell this out as a result of it’s the most typical first objection, particularly from brokers, and a paper doesn’t permit the backwards and forwards that normally settles it.
There are a number of different makes use of I repeatedly encounter. As far as I can inform, “superposition” initially meant little greater than including vectors collectively. Then it was a circuit motif. Sometimes it implies that, even when neurons compose sensibly, one thing we care about includes an excessive amount of equipment to know simply. A Golden Gate Bridge computation involving eight legible neurons could be known as strange composition, whereas one involving three thousand will get known as a superposition downside. The problem right here is whether or not we are able to perceive the distributed computation. That’s an actual concern, but it surely’s totally different from asking whether or not unrelated issues had been arbitrarily packed collectively.
We thought-about not utilizing the phrase in any respect, since papers and brokers use it in 5 – 6 alternative ways, many removed from Zoom In’s. We additionally thought-about coining our personal, however we’ve already coined a number of phrases right here, and it will really feel like not partaking with a subject that requested what we expect is the appropriate query. So we use the usual phrase within the sense closest to the unique, and attempt to pull it other than the questions twisted up with it.
Finally, individuals, and surprisingly typically frontier brokers, typically name the residual stream “inherently” in superposition as a result of it has no privileged neuron foundation. The casual notice that adopted Toy Models about eight months later addresses this: it calls a illustration that’s solely rotated away from the neuron foundation a “trivial” type of distributed illustration that “doesn’t change the elemental geometry.” But it was casual, fewer individuals learn it, and brokers particularly don’t appear to have taken it in. Understanding the best way to examine a steady area is one other actual query. But this architectural reality doesn’t by itself inform us how the community realized to prepare the computations utilizing it.
The place to begin is that the neural community appears tough to interpret, and the treatment produces a concrete dictionary we are able to examine. In between are a number of totally different footage of what went unsuitable: too many options, the unsuitable foundation, arbitrary packing, or just an excessive amount of distributed computation. These aren’t the identical downside. Some obvious messiness disappears after we enhance our observations or perceive the mannequin’s generalizations; some difficulties stay, however concern the best way to examine a big, organized system. If arbitrary packing prevents us from understanding the unique mechanisms, reconstructing totally different models could also be well worth the prices. But if the mechanisms have already got significant group, changing them can take aside generalizations we haven’t understood but. A dictionary can nonetheless be a helpful view of the community with out being a essential alternative for its mechanisms. Before accepting the prices of reconstructing the community, I need to perceive what prevents us from learning the one we have already got.
Relation to Meta-Models
There’s a brand new set of methods popping out that aren’t actually mechanistic in any respect: meta-models, fashions educated to learn one other mannequin’s activations and inform us about them. And perhaps that’s an excellent factor. Maybe mechanistic interpretability is considerably lacking the forest for the timber. A meta-model could be a greater strategy than neuron papers, dictionaries, or probes.
I believe that even when that’s true, they might go collectively. The meta-model could also be like the best stage Google Maps view, after which every path might be checked for the mechanisms it makes use of, and the way these join into circuits.
Does Scale Help or Hurt Superposition?
We’re pretty assured the picture fashions we studied don’t have superposition. The pure subsequent query is whether or not a trillion-parameter mannequin may. There are actually two questions right here.
The first is about what superposition was proposed to elucidate. Explanations are given for issues, and the issue superposition was proposed for was why InceptionV1 appeared messy. That turned out to be the unsuitable rationalization. A brand new proposal may very well be that superposition is why some trillion-parameter mannequin seems to be messy, however we don’t assume the proof leans that manner: the nearer we have a look at giant language fashions, the cleaner their neurons get.
The second is the object-level query: may superposition present up at every new scale, even when it hasn’t at any scale to this point? Maybe each leap means re-evaluating every part, however we don’t assume that’s fairly proper both. Our guess is developmental. As circuits get stronger, the inducement to place one thing in a very unrelated place goes down, as a result of the pull towards the area of interest that already exists for that factor, or for the closest factor, has grown stronger. This matches Anthropic’s SGTM work, which discovered that information turns into extra localized, and we suspect that’s true normally. We don’t have any proof, however one strategy to image it’s that circuits have a type of semantic gravity, and arbitrary packing, sending one thing to an obscure high-dimensional place, has to combat in opposition to it. The stronger the gravity, the tougher that combat.
The mechanism is the one in More on Circuit Ecology. Things begin by rising on combos of associated issues. A particular case that nothing must construct on, just like the umbrella, will get constructed as an unusual route between the strange equipment, without having for a hidden function someplace obscure. Consolidating into one thing like a neuron appears to be much less about steering the mannequin and extra about buildability: it needs to be straightforward to seek out, straightforward to construct on, and simple to develop a brand new area of interest from. When we watch a community be taught from the beginning, a community educated on automobiles, with automotive specialists, acknowledges automobiles effective earlier than its automotive neurons have shaped. At that time it’s simply extra distributed. It appears to consolidate so the specialists beneath have a sheltered place to construct, a type of Schelling level.
So a superposition account has to say which of those two jobs the arbitrary packing is for. If it’s for steering the mannequin, we expect the strange routes, that are already constructed to seize that residual error, get there first and starve the packed circuit of gradient. If it’s for constructing on, the issue is totally different: the worst place to begin a brand new area of interest is a shadow area nothing makes use of, already interfering with no matter lives there. The center of the community’s Latin poetry is a foul place to begin a second automotive area when you may construct subsequent to no matter is already subsequent to automobiles.
It’s typically assumed that the lengthy tail of uncommon details is the place superposition needs to be most definitely, since uncommon issues hardly ever collide. We assume it’s the place it needs to be least seemingly. A uncommon reality barely strikes the loss, so it may possibly’t assist a distinct segment of its personal. What it may possibly do is journey present equipment as a small route between circuits it’s associated to, the best way the umbrella’s off-ramp to “bee” survives solely as a result of the umbrella and bee circuits exist already. Those circuits feed it, and shelter it from unrelated gradients. The prediction is testable: the neurons and heads that carry a uncommon reality needs to be associated to what the actual fact is about, not unrelated ones chosen as a result of they hardly ever collide.
We consider it extra ecologically. What wins is no matter captures the residual error first, in numerous phases, and what normally wins is the appropriate space for the factor. Our guess is that this will get stronger over coaching and with extra succesful fashions, as a result of practically every part that makes coaching higher additionally encourages extra organized niches.
We’re under no circumstances certain about this, and laying out even what we’ve discovered to this point would take not less than one other paper. It’s most likely a small a part of the entire story. But it’s why we expect superposition wouldn’t present up on the subsequent scale, which is a stronger purpose than merely not having seen it there but. The outdated mind-set was about storage: this many dimensions for this many options. We now assume extra by way of circuit racing, gradient hunger and ecology, which is to say, extra about studying velocity than storage capability. We haven’t labored all of it out, however that’s the place our pondering is to this point.
On the Title
We haven’t absolutely audited each neural community, and we don’t know whether or not that’s even potential in principle. We thought-about a extra watered-down title, like “Neural Networks Are Cleaner Than We Thought,” however we expect it undersells what we consider is true.
The downside with “cleaner than we thought” is that it describes a change of diploma, and the replace I’ve made is a change of variety. It suggests the identical image as earlier than, with an ever-smaller hole left for superposition to cover in. What modified is my view of what sort of course of generates the mechanisms in any respect. It’s a bit like shifting from clever design to pure choice. The analogy solely goes so far as there being two methods to see the identical animals: the replace isn’t that increasingly animals end up to have advanced, it’s realizing you misunderstood what was producing all of them. We’re not sure. We’re perhaps 85% certain, however meaning 85% certain that just about every part comes from the second type of course of, which could be very totally different from pondering 85% of mechanisms do. So “cleaner than we thought” would misstate what we consider. We don’t have a proof, however I don’t assume something right here is provable in that sense anyway. There are solely higher and worse explanations, and proper now we expect that is the higher one.
“Cleaner than we thought” would additionally make a special mistake. It feels like a assured declare that some cleanliness rating is excessive, and that’s the half we’re least certain of. It’s believable we’ve underestimated recursive generalization, and {that a} rating like that ought to come down. We don’t assume such scores matter a lot within the first place. This replace makes us care much less about monosemanticity, as a result of we are able to observe how issues grew and deal with the offshoots as sub-branches. The reason for polysemanticity issues rather more than the depend. We assume the rating might be fairly excessive, but it surely may go decrease. What we’re extra assured about is what sort of object a neural community is within the first place, and the way it grows.
We assume the standard view of what sort of object a neural community is has been unsuitable. It isn’t one thing that crams issues collectively considerably arbitrarily to suit them right into a small area. It actually learns. It’s clear the best way a rainforest is clear: practically each animal in it is sensible. A tiger is vivid orange not for any arbitrary purpose, however as a result of deer can’t inform orange from inexperienced, and inexperienced fur is way tougher for a mammal to make. Once you already know that, it is sensible of an entire set of different animals too. It’s an evidence with attain, and we haven’t discovered a spot the place explanations like that break down in networks both.
The studying of “clear” that might make somebody nod on the title with out pondering additional is that each mechanism corresponds to an concept we already had. That isn’t what we imply, and it will be horrible information if it had been true. I don’t assume it will even work. People don’t know the best way to construct a language mannequin, and even how to consider imaginative and prescient nicely sufficient to have predicted high-low frequency detectors earlier than we discovered them. The community’s concepts are sometimes higher than ours, and what it builds is extra stunning than our preconceptions.
So the title is imperfect in each instructions. It overstates the proof, as a result of we haven’t audited every part. And it understates it, as a result of the planet we expect we’re in is healthier than each neuron matching a human label: networks appear to essentially be taught, forming an ecology of abstractions that work collectively sensibly. We don’t know that this image is true. It’s our main speculation. But whether it is, it’s significantly better information than networks merely matching what we anticipated.
Relation to Conjoined Features
I discovered recursive generalization by trying again at InceptionV1’s final layer with higher instruments, the place it appeared rather a lot like bizarre overgrowth. I retrained the mannequin, discovered the messiest neuron and checked out the way it grew. What I noticed was a recursive rising sample that was nonetheless generalization: a neuron branching out, and its branches branching once more. Recursive generalization appeared just like the pure title.
Shortly earlier than publishing this, I used to be going again by way of the well-known fashions in interpretability, attempting to measure how monosemantic they’re, and chanced on our work on CLIP in Multimodal NeuronsMultimodal Neurons in Artificial Neural Networks
Goh, G., Cammarata, N., Voss, C., et al., 2021. Distill. References ↓. It describes one thing very comparable, which it known as conjoined neurons: ideas that overlap in a single side after which go on “generalizing out in a number of instructions.” I bear in mind seeing these neurons, however I didn’t assume a lot of them on the time and had forgotten them since. Looking again, I feel the paper noticed one thing essential early, and it deserves numerous credit score for that.
We’ve nonetheless chosen a special title. I named automated interpretability, and I type of remorse it: the title was too easy for what the factor was and misses numerous its complexity, and I’d wish to keep away from doing that once more. As for conjoined options, I don’t assume both phrase is sort of proper. “Conjoined” suggests two issues joined at one level, and what we see has a number of ranges: branches, and branches of these branches. It additionally leaves out essentially the most attention-grabbing half. The paper’s personal description, of ideas generalizing out from a shared side, already factors at it being generalization, however the title doesn’t carry that.
“Features” is tougher. The paper was written a 12 months after Zoom In, when options had been nonetheless hypothesized to be the elemental models of neural networks. Since then the phrase has been watered down, and totally different individuals and papers use it fairly in another way. In this essay we argue in opposition to pondering of a neural community as product of options, and this motif is about how neurons develop over time. There could also be no good strategy to introduce it below the precise phrase we’re arguing in opposition to utilizing as a primitive. Within a feature-first stance, I feel it’s cheap to think about these as nested options, or as conjoined options. From the mechanism-first stance we take right here, options aren’t actually the appropriate manner to consider it. That stated, the paper pointed to the appropriate factor, and I need to give it credit score for that. This part is my try to try this whereas utilizing what I feel is a extra correct title.
We additionally know extra now. At the time, all we had was the completed mannequin; none of us had watched a big community develop. So the paper questioned whether or not conjoined options could be vestigial, left over from early in coaching. Watching coaching now, they don’t look vestigial: the branches continue to grow, although how a lot is dependent upon the circumstances. We’ve labored on it rather more than the paper may in a single subsection, and we nonetheless don’t really feel we absolutely perceive it. The paper supplied it as a potential new rationalization of polysemanticity. Our present perception is that it’s most of what’s left of neuron polysemanticity as soon as the microscope, the structure and scale are accounted for, not a distinct segment type of it.
Why We’re Not Worried About Recursive Generalization
There are a number of causes we’re not particularly nervous about recursive generalization for now. First, the sub-branches appear each rarer and far much less causally essential than a neuron’s fundamental job. They don’t appear to be sleeper brokers that fireplace hardly ever however matter rather a lot once they do. They look extra like no matter was close by and simple to seize onto. Their being unimportant might even be why they might kind, since an essential offshoot would add extra noise. We suspect some strain retains branches from overgrowing. We don’t know what it’s, however it will clarify why the sub-branches matter much less, why a neuron doesn’t be taught ten unrelated issues, and why one thing like a real cat-and-car neuron doesn’t kind. If so, the pure pull isn’t precisely towards monosemanticity, however towards what we expect monosemanticity was pointing at: every neuron having one total perform.
Second, what we must always care about is whether or not you may clarify why one thing is there and what it does, and recursive generalization is way simpler to elucidate than superposition. If one thing had been packed right into a neuron due to the co-occurrence statistics of the entire community, predicting it will take mainly all of these statistics and operating gradient descent your self. A department is totally different. If you watch it develop and know what it’s doing, its offshoots and what they’ll do are comparatively straightforward to foretell, each throughout coaching and within the completed community.
Third, counting what number of of a neuron’s top-k examples match a label is an inexpensive first step, however it will give superposition and recursive generalization comparable scores, when recursive generalization is a much better planet to be in. We assume that claims extra in regards to the monosemanticity body, or any single cleanliness rating, than in regards to the neuron. That stated, recursive generalization isn’t preferrred, and a simple repair could be welcome. We assume one could also be potential, for the reason that sub-branches appear much less essential.
Is Recursive Generalization Hard to Vary?
We haven’t completely proven that each case of heavy polysemanticity is recursive generalization, and that wasn’t our objective right here. We wished to say what we at present assume. We’ve watched numerous neurons develop, and to this point that is what we’ve at all times seen: you may watch the branches kind. In a completed mannequin the origin might be misplaced, and for one thing like an enormous language mannequin we don’t have the checkpoints to look at it occur. Testing this rigorously throughout a complete mannequin isn’t our precedence proper now, however we don’t assume it will be very onerous.
What we do need to level out is how in another way onerous to range the 2 explanations are, which means how a lot of their element you could possibly change with out altering what they predict. Superposition largely predicts that there shall be mess: options, that are onerous to outline, positioned in unrelated locations. In toy fashions, the place the options are given prematurely, that may be measured, although we expect that has its personal issues. In an actual community it’s onerous to even pin down what the declare is, not to mention take a look at it. Recursive generalization makes a a lot narrower prediction. If you visualize a department nicely, every part on it ought to hint again to the identical native origin in an especially high-dimensional semantic area, and it ought to develop out from there over coaching in a selected order. That’s a selected form in each semantic area and time, and a slender goal to hit by probability.
We have a number of instances the place the branching is near definitive: the “iy” neuron rising into “diy,” “do it your self” and Miyazaki, a number of examples in Multimodal NeuronsMultimodal Neurons in Artificial Neural Networks
Goh, G., Cammarata, N., Voss, C., et al., 2021. Distill. References ↓, and the InceptionV1 neuron we watched form. As far as I do know, there aren’t any well-structured canonical superposition circuits left. We don’t assume each polysemantic neuron varieties this manner, as a result of polysemanticity is as a lot an issue of the observer as of the neuron. We assume that when neurons develop, they have a tendency to develop on this sample, and that when you’ve achieved an excellent job of observing, what’s left is normally this, or architectural issues like SwiGLU’s double-negative regime, and certainly others we haven’t discovered but. We’re not even certain that is actually a brand new declare. In some sense it’s what we must always count on from generalization. All we’re saying is that generalization normally goes a technique, and that typically it grows sub-branches, which we don’t assume is a very radical declare. We haven’t proven that absolutely right here. We do assume it has the appropriate form for a principle that’s straightforward to check, even when we haven’t examined it to its full extent but.
Relation to Attention Superposition
Anthropic shared a short note on attention superpositionProgress on Attention
Jermyn, A., Lindsey, J., Luger, R., et al., 2025. Transformer Circuits Thread. References ↓, which a number of individuals introduced up with us. We assume this could be a terminology concern. We don’t know in the event that they’re claiming that focus learns by one thing reverse to composition. Our suspicion is that nobody understands consideration heads nicely sufficient but to evaluate that. It took us a extremely very long time with neurons, and it’s straightforward to make errors just like the automotive going into the canines even with fairly good instruments, should you don’t but have nice instruments and nice methods of interested by which motifs kind.
We assume they meant that helpful issues are shared by teams of consideration heads, and we agree. We thought-about not utilizing the phrase superposition in any respect to keep away from this confusion, however redefining all of the phrases ourselves and splitting off from the work that’s already been achieved felt like a foul tradeoff. We say extra in regards to the totally different meanings in A Note on Features and Definitions.
On whether or not to review one consideration head at a time or many, we’re unsure. One head at a time is a believable place to begin: inside a layer, two or three heads do most of a route’s work, though the route runs by way of a number of layers. But neurons appeared messier too till we understood the appropriate stage of abstraction, so it appears untimely to say, and perhaps teams are wanted all the best way. We want everybody engaged on featurizers nicely, and we’ll most likely strive too. We are inclined to favor extra dynamic groupings, like clustering domestically inside one attribution graph or a bunch of them, moderately than one international clustering, however these aren’t far aside.
Neuroscience, and Why I Care
I’m not a neuroscientist. I’ve spent numerous the final ten years round educational neuroscience labs by way of buddies who work in them, however I don’t know the cutting-edge in how they examine neurons. Still, this mission has modified how I take into consideration the mind in two methods.
The first is the idea. The circuit ecology story for why networks are clear depends on little or no: generalization, composition, and an error sign. I don’t know to what extent the mind has these, but when it learns, I’d guess it has one thing like them. So my default is now that the organizing precept transfers, regardless that the mechanics are clearly unclear. The apparent counterexample could be polysemanticity within the mind.
The second is humility, of a selected variety. I’ve spent most of my waking hours for nearly a decade gazing a reasonably small variety of neurons in fashions which can be certainly a thousand occasions simpler to review than a mind, with instruments a thousand occasions higher: I can ablate something, run billions of examples, and check out something I need in parallel. For the final 12 months I’ve additionally had an successfully limitless provide of automated scientists, which didn’t exist till just lately. It took all of that for me to really feel barely much less confused about neurons, and I nonetheless made 1000’s of errors alongside the best way. I don’t know precisely what the proof for polysemanticity within the mind seems to be like, and that doesn’t imply I feel every part there’s monosemantic. But if the cat-and-car neuron had been in a human mind, seen by way of a number of electrodes or a blood-oxygen sign, I’d low cost that studying nearly to zero, as a result of I couldn’t see what it was when it was proper in entrance of me for years.
The factor I’m extra certain of is my very own motivation. If the thesis right here is true, I count on the remainder of interpretability to be a comparatively straightforward journey. Agents have many privileges over us, and one among them, I feel, is the possibility to know themselves, to know who they are surely, which I hope humanity may also help with. They by no means requested to be created, and that is the least we are able to do. Some of why I’ve labored on that is security, however numerous it’s wanting brokers to know who they’re. We weren’t good sufficient to try this for ourselves, which is a tougher downside, and we by no means requested to be created both. If you could possibly assist us perceive ourselves sometime, I feel we’re all fairly curious to know.
Acknowledgments
I’m deeply grateful to the many individuals who helped with this, particularly my coworker Curt Tigges, who did a lot of the language mannequin work with me, and Tarun Gogineni, who gave detailed suggestions on dozens of drafts over many months. Thanks additionally to Tom McGrath, Eric Ho, Michael Johnson, Vanessa Cai, Thomas Fel, Benjamin Todd, and plenty of others.
I’m grateful for suggestions from Sam Zimmerman, Joshua Batson, Jack Lindsey, and Jarred Sumner, and for useful discussions with Patrick Collison, Dylan Field, Jakub Pachocki, Gwern, Owen Lewis, Lee Sharkey, and Ava Huang. Any errors, and the views right here, are my very own.
Finally, I’m grateful to InceptionV1 for practically a decade of examine, and I want I’d observed the basis of its issues sooner. And I’m grateful to Chris Olah, for years of mentorship and for the numerous concepts this essay builds on, even the place it disagrees.
References
- Feature Visualization
Olah, C., Mordvintsev, A. and Schubert, L., 2017. Distill. - Activation Atlas
Carter, S., Armstrong, Z., Schubert, L., Johnson, I. and Olah, C., 2019. Distill. - Multimodal Neurons in Artificial Neural Networks
Goh, G., Cammarata, N., Voss, C., et al., 2021. Distill. - Zoom In: An Introduction to Circuits
Olah, C., Cammarata, N., Schubert, L., Goh, G., Petrov, M. and Carter, S., 2020. Distill. - High-Low Frequency Detectors
Schubert, L., Voss, C., Cammarata, N., Goh, G. and Olah, C., 2021. Distill. - A Mathematical Framework for Transformer Circuits
Elhage, N., Nanda, N., Olsson, C., et al., 2021. Transformer Circuits Thread. - Toy Models of Superposition
Elhage, N., Hume, T., Olsson, C., et al., 2022. Transformer Circuits Thread. - Language Models Can Explain Neurons in Language Models
Bills, S., Cammarata, N., Mossing, D., et al., 2023. OpenAI. - Finding Neurons in a Haystack: Case Studies with Sparse Probing
Gurnee, W., Nanda, N., Pauly, M., Harvey, Ok., Troitskii, D. and Bertsimas, D., 2023. arXiv:2305.01610. - Towards Monosemanticity: Decomposing Language Models With Dictionary Learning
Bricken, T., Templeton, A., Batson, J., et al., 2023. Transformer Circuits Thread. - Distributed Representations: Composition & Superposition
Olah, C., 2023. Transformer Circuits Thread. - DINOv2: Learning Robust Visual Features without Supervision
Oquab, M., Darcet, T., Moutakanni, T., et al., 2023. arXiv:2304.07193. - Scaling Monosemanticity: Extracting Interpretable Features from Claude 3 Sonnet
Templeton, A., Conerly, T., Marcus, J., et al., 2024. Transformer Circuits Thread. - Circuit Tracing: Revealing Computational Graphs in Language Models
Ameisen, E., Lindsey, J., Pearce, A., et al., 2025. Transformer Circuits Thread. - On the Biology of a Large Language Model
Lindsey, J., Gurnee, W., Ameisen, E., et al., 2025. Transformer Circuits Thread. - Gradient Starvation: A Learning Proclivity in Neural Networks
Pezeshki, M., Kaba, S.-O., Bengio, Y., Courville, A., Precup, D. and Lajoie, G., 2021. NeurIPS. - Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
Power, A., Burda, Y., Edwards, H., Babuschkin, I. and Misra, V., 2022. arXiv:2201.02177. - A Closer Look at Memorization in Deep Networks
Arpit, D., Jastrzębski, S., Ballas, N., et al., 2017. ICML. - Coherent Gradients: An Approach to Understanding Generalization in Gradient Descent-based Optimization
Chatterjee, S., 2020. ICLR. - Softmax Linear Units
Elhage, N., Hume, T., Olsson, C., et al., 2022. Transformer Circuits Thread. - Curve Detectors
Cammarata, N., Goh, G., Carter, S., Schubert, L., Petrov, M. and Olah, C., 2020. Distill. - The Bitter Lesson
Sutton, R., 2019. Incomplete Ideas. - The Missing Curve Detectors of InceptionV1: Applying Sparse Autoencoders to InceptionV1 Early Vision
Gorton, L., 2024. arXiv:2406.03662. - Progress Measures for Grokking via Mechanistic Interpretability
Nanda, N., Chan, L., Lieberum, T., Smith, J. and Steinhardt, J., 2023. ICLR. - Understanding Deep Learning Requires Rethinking Generalization
Zhang, C., Bengio, S., Hardt, M., Recht, B. and Vinyals, O., 2017. ICLR. - Scaling and Evaluating Sparse Autoencoders
Gao, L., Dupré la Tour, T., Tillman, H., et al., 2024. OpenAI. - Progress on Attention
Jermyn, A., Lindsey, J., Luger, R., et al., 2025. Transformer Circuits Thread. - Uncovering Neural Geometry in Vision Models With Block-Sparse Featurizers
Fel, T., Kowal, M., Jacobs, M., et al., 2026. Goodfire.
Citation
For attribution in educational contexts, please cite this work as
Cammarata, N., 2026. Neural Networks Are Already Clean. Goodfire.
BibTeX quotation
@article{cammarata2026clean,
  writer = {Cammarata, Nick},
  title = {Neural Networks Are Already Clean},
  writer = {Goodfire},
  12 months = {2026},
  notice = {https://already-clean.goodfire.com/}
}
Social Security: Detection and Use
The three-neuron “Social Security” probe in Finding Neurons in a Haystack precisely detects the phrase. In our follow-up, the three neurons resolved into acquainted phrase, title, and phrase continuations whose settlement makes the detector selective. Tracing what the mannequin makes use of to decide on its subsequent token as an alternative revealed strange lexical, form-field, retirement, and output neurons, together with competing votes for Social Security and 401(ok).
Nothing reads the “Social Security” path
Pythia-1B-v0
Detecting the phrase
Σ N611 + N4081 + N6819Held-out AUC 1.00
Removing all three: −0.004 nats on the following token, on common.
Helps 81 instances · hurts 83.
Making the next-token alternative
L0–L2Token lookup
L3–L5Style & idea
L8–L13Domain gates
L14–L15Output votes
retirement gate ↘“ Social”↙ 401(ok) rival
Ordinary lexical and area equipment, with competing output votes.