You don’t want a discrete GPU to run native LLMs anymore
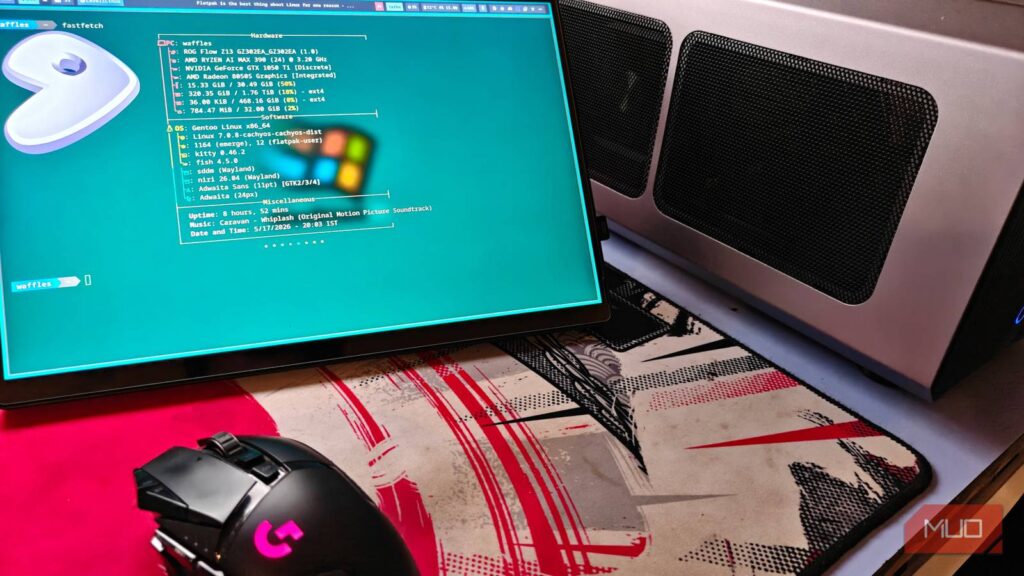
Running native LLMs normally mandates a strong, devoted graphics card to deal with all that compute. While it’s nonetheless technically doable to run an LLM utilizing your CPU, it’s nonetheless a good deal slower than what you’d get from a correct graphics card.
Which brings us to the weird segment that is integrated graphics. These APUs are under no circumstances near desktop grade GPUs, however nonetheless technically qualify as such. Which means you would theoretically additionally run native LLMs on them. Curious, I took to the take a look at bench and ready a complete of three iGPU setups to check issues on.
A have a look at the setups
Three gadgets, representing three distinct iGPU generations
A complete of three gadgets had been used for this specific take a look at — the ROG Flow Z13 (AI Max 390/32 GB), a Legion Go (Gen 1, with the Ryzen Z1 Extreme and 16 GB RAM) and at last, the standard built-in Vega 7 iGPU of the Ryzen 5 5600G.
Each iGPU is a step-up, and represents its evolution. The AI Max 390 is a strong APU with a 12-core and 24-thread CPU, which is paired with one of many quickest iGPUs within the client market, making it one of many very best kits of {hardware} you should buy proper now.
My specific mannequin has solely 32 GB of system reminiscence, and this limits the vary of fashions you’ll be able to run on it. That being mentioned, it is a have a look at the most effective {hardware} kits you may get for native AI proper now, and I’d say it lives as much as the hype.
Next we now have the Gen 1 Lenovo Legion Go, one of many many AMD Ryzen Z1 Extreme-powered PC handhelds that took on the Steam Deck. It’s pretty competent, however under no circumstances holds a candle to the 8050S on the Flow Z13. We’re additionally going to be restricted by our 16 GB of system reminiscence right here.
That nonetheless occurs to be leagues superior to the ultimate entry within the record — the Vega 7 iGPU of the Ryzen 5 5600G. It used to be a fantastic option back in the day, though its glory days are long gone us now.
It does appear like a little bit of a meme entry at first, however you’ll be able to truly run fashionable LLMs (with the standard {hardware} restrictions) on these older GPU architectures. And moreover, it makes for a enjoyable experiment.
Preparing the take a look at setup
Notes, hacks and numerous work for the 5600G

The take a look at setup was easy – run an LLM benchmark primarily based on a couple of parameters, with scripts assisted and constructed by Claude. The assessments had been carried out on all three machines with the intent to make use of each little bit of useful resource it had entry to.
This interprets to increased VRAM utilization, though you may quickly discover out that it doesn’t matter a lot if the iGPU is as gradual as molasses.
The 5600G was a little bit of a ache to arrange. The Vega 7 iGPU (gfx90c) has no official ROCm assist, so it is higher to undergo the Vulkan backend for higher outcomes and compatibility.
|
Metric |
Ryzen 5 5600G (Vega 7 iGPU) |
Z1 Extreme (CPU) |
Z1 Extreme (780M iGPU) |
AI MAX 390 (8050S iGPU) |
|---|---|---|---|---|
|
Generation velocity (tokens/s) |
17.5 |
22.4 |
44.1 |
85.1 |
|
Prompt processing (tokens/s) |
201 |
150 |
783 |
1,609 |
|
Time per run (seconds) |
16.8 |
13.7 |
6.3 |
3.2 |
|
Average energy draw (W) |
41 |
18 |
33 |
64 |
|
Efficiency (tokens/s/W) |
0.43 |
1.25 |
1.34 |
1.33 |
|
Peak temperature (°C) |
57 |
64 |
81 |
95 |
I additionally needed to manually assign the iGPU 16 GB of VRAM from the BIOS, which was probably the most you would cap it out at. This ought to get rid of any VRAM bottlenecks, though it doesn’t make a lot of a distinction, as you’ll quickly come to see.
Now, going again to the take a look at outcomes, the set fared as you’d count on, however there have been a couple of fascinating observations. To nobody’s shock, the AI Max 390 carried out the most effective, topping the charts by a substantial margin. After all, the 8050S can sustain with a cell RTX 4060, and has the added benefit of a larger VRAM pool (with sooner reminiscence).
The Ryzen Z1 Extreme trails behind subsequent, and is about twice as gradual. That being mentioned, it did handle to attain 44.1 Gen tok/s utilizing the 780M iGPU, which isn’t too dangerous.
And lastly, we arrive on the Vega 7 iGPU of the Ryzen 5 5600G, which carried out the slowest, to nobody’s shock. With a Gen tok/s of 17.5, it’s practically 5 occasions slower than the AI Max 390. It additionally consumes a good deal of energy, peaking at 41 W with out an excessive amount of to point out for it.
While the 5600G isn’t a powerhouse, it’s nonetheless able to working native LLMs, to some extent. Call it morbid curiosity, or only a want to discover the unknown, it is nonetheless nonetheless fascinating that one thing this outdated may even handle to run it within the first place.
It is technically doable to run ROCm on unsupported GPUs, however it’s not going to make a distinction. Ollama additionally doesn’t appear to love iGPUs by default both, and I needed to change the config file to replicate the identical.
Integrated graphics with unified reminiscence entry is the way forward for native AI
The AI Max 390 completely crushes via everybody else on this take a look at, and might stand toe-to-toe with some desktop GPUs. That being mentioned, there may be one very massive elephant within the room: the pricing.
Ryzen AI Max machines price a reasonably penny and are under no circumstances accessible, however their efficiency and neighborhood assist stays undeniably robust. Combined with quick (and sadly soldered) on-board unified reminiscence, this type of mixture makes it ideally suited for native AI, and is rapidly rising to be one in all my favourite tech classes.