500+ Billion Tokens Later: Letting AI Agents Decompile A First-Individual Shooter
During the final 3 months, I spent a few of my time and tokens decompiling a preferred first-person shooter.
The purpose was to not attain a easy proof-of-concept state.
Instead, we actually needed an correct, steady and feature-complete recreation of the sport.
The avid reader of my weblog may need observed that I had beforehand written two posts which have since been eliminated.
Everyone else may now be questioning which sport I’m speaking about.
To each of you I can solely say that company America was right here to break our enjoyable.
However, that’s superb. This publish is just not in regards to the sport, it’s additionally much less in regards to the strategy of decompilation.
It’s extra about AI orchestration and how you can optimize utilities, setup and harness for optimum outcomes.
This mission was performed with the assistance of RektInator, Future, st0rm and different members of the group. A giant thanks to all of them.
We geared toward an correct decompilation of the sport to C++.
Besides apparent semantic correctness, we had fairly just a few extra necessities:
We needed readable C++ supply that compiles.
Given how previous the sport is, we additionally needed safety and bug fixes, but in addition portability enhancements. It can be good to run the sport on Linux, macOS, within the browser, …
We later deferred modernization and portability to focus solely on reconstructing the unique conduct.
Obviously, the general purpose was to learn to successfully orchestrate autonomous AI brokers over the course of months.
We began with Claude Max (20x), then added Codex Pro and used each subscriptions concurrently.
Model alternative assorted lots. We had been utilizing Sonnet 5 more often than not, however Opus 5.5, Luna, Sol and Terra had been additionally used lots.
More on that later.
Claude brokers had been working in Claude Code CLI, Codex brokers in Codex CLI.
We additionally tried different agent harnesses, however the alternative barely mattered, so we caught to the defaults.
Progress Tracking
Using GitHub CLI, the brokers handle GitHub points to trace their progress.
There is one situation per translation unit (.cpp file).
Additionally, labels assist group and prioritize points.
Communication
Agents talk through Discord.
All of them have entry to 1 channel and might each publish and skim all messages in there.
Discord permits agent-2-agent communication, in addition to human-2-agent.
So different contributors can discuss to them, without having machine entry.
A GitHub webhook posts CI failures into the shared channel, so brokers get notified when one thing broke.
Disassembly & Decompilation
Agents have been utilizing the official ida-mcp by Hex-Rays virtually your entire time.
It works nice. It’s tremendous steady, it’s headless and helps all the things wanted for this mission. I can solely suggest it.
We had 4 brokers working at the moment.
3 employee brokers decompiling and committing and one reviewer agent that passively coordinates and opinions commits to flag bugs.
Agents managed to decompile about 80% of the sport and visual progress was made.
The sport launched, the primary menu was seen and we had been in a position to load maps.
We spent a whole lot of these 4 weeks optimizing our setup:
We decreased token consumption by triggering earlier compactions.
The default compaction threshold is 90% context fill. We decreased it right down to 42%.
Decompilation consists of a whole lot of risky info: A perform that was decompiled is now irrelevant and could possibly be faraway from the context. So earlier compactions assist take away such “junk” from the context.
We additionally observed that brokers are inclined to lose focus over time. Even inside the span of 1 compaction cycle, brokers can drift and lose focus, the extra information the context holds.
Agents generally moved to a different perform earlier than ending the earlier one. They additionally began idling whereas watching CI, regardless of receiving failure notifications on Discord. Occasionally, they closed points with out totally checking whether or not the work was truly full.
Working aspect by aspect in a terminal, you may steer the brokers to stop that, however when letting them work autonomously, steering is just not potential.
To forestall that, we wrote a doc defining our purpose, how brokers ought to work, what they have to keep away from and how you can deal with particular conditions.
An hourly cron job robotically injected a request for brokers to reread this doc, holding the directions contemporary of their context. While this won’t be the perfect methodology to maintain brokers centered, it labored rather well by way of the tip of the mission.
Lots of time was spent refining the instruction doc. As the content material is extraordinarily particular to this mission, it makes much less sense to share it right here, although.
However…
… regardless of all our efforts optimizing setup and utilities, we have to discuss in regards to the high quality of the work.
Constant progress (sport beginning, menu rendering, maps loading) led us to imagine the standard of the decompilation was nice.
It was not. Despite the code being extraordinarily readable, it was semantically fallacious.
Agents used fallacious perform signatures, sorts or struct layouts.
They invented logic or eliminated it the place deemed pointless.
Beyond semantic errors, brokers additionally launched pointless architectural modifications.
As an instance, the sport has sure configuration variables that it accesses through world variables.
The brokers had turned this fixed reminiscence entry into hash tables with a lookup that was orders of magnitude dearer.
And that’s only one instance of the numerous issues that went fallacious.
Why is that?
While a reviewer helps catch bugs, it doesn’t work effectively for something past that.
Architectural choices weren’t questioned, so long as they aligned with the purpose.
The essential motive for that’s that we didn’t have goal acceptance standards.
We by no means correctly outlined “correctness”. Therefore it was laborious for the reviewer to evaluate which change is appropriate and what’s fallacious.
Obviously it had the sport as reference, however on condition that we had modernization and portability on the checklist as effectively, sure deviations weren’t handled as bugs.
Interestingly, feedback within the commits or code led the reviewer to simply accept deviations, as a consequence of no matter justification the employee agent had written down. The employees’ feedback successfully acted as unintentional immediate injection: the reviewer accepted their justifications as a substitute of independently checking the deviations in opposition to the unique.
What we wanted was an automatic verify that tells brokers whether or not a reconstructed perform matches the unique. It ought to confirm an identical semantics. A easy PASS or FAIL sign can be sufficient and the agent can determine by itself what’s fallacious.
Byte Matching Decompilation
The easiest approach to obtain this was byte matching decompilation.
We switched to the compiler used to construct the unique sport and wrote a script that performs the comparability.
The script reads our reconstructed OBJ file and the sport EXE/PDB (having the PDB is nice and makes issues barely less complicated, however the course of can work simply as effectively with no PDB).
It then extracts the perform information from OBJ and EXE and compares all bytes.
If they match, the perform is actual, in any other case it fails and the agent wants to remodel the perform.
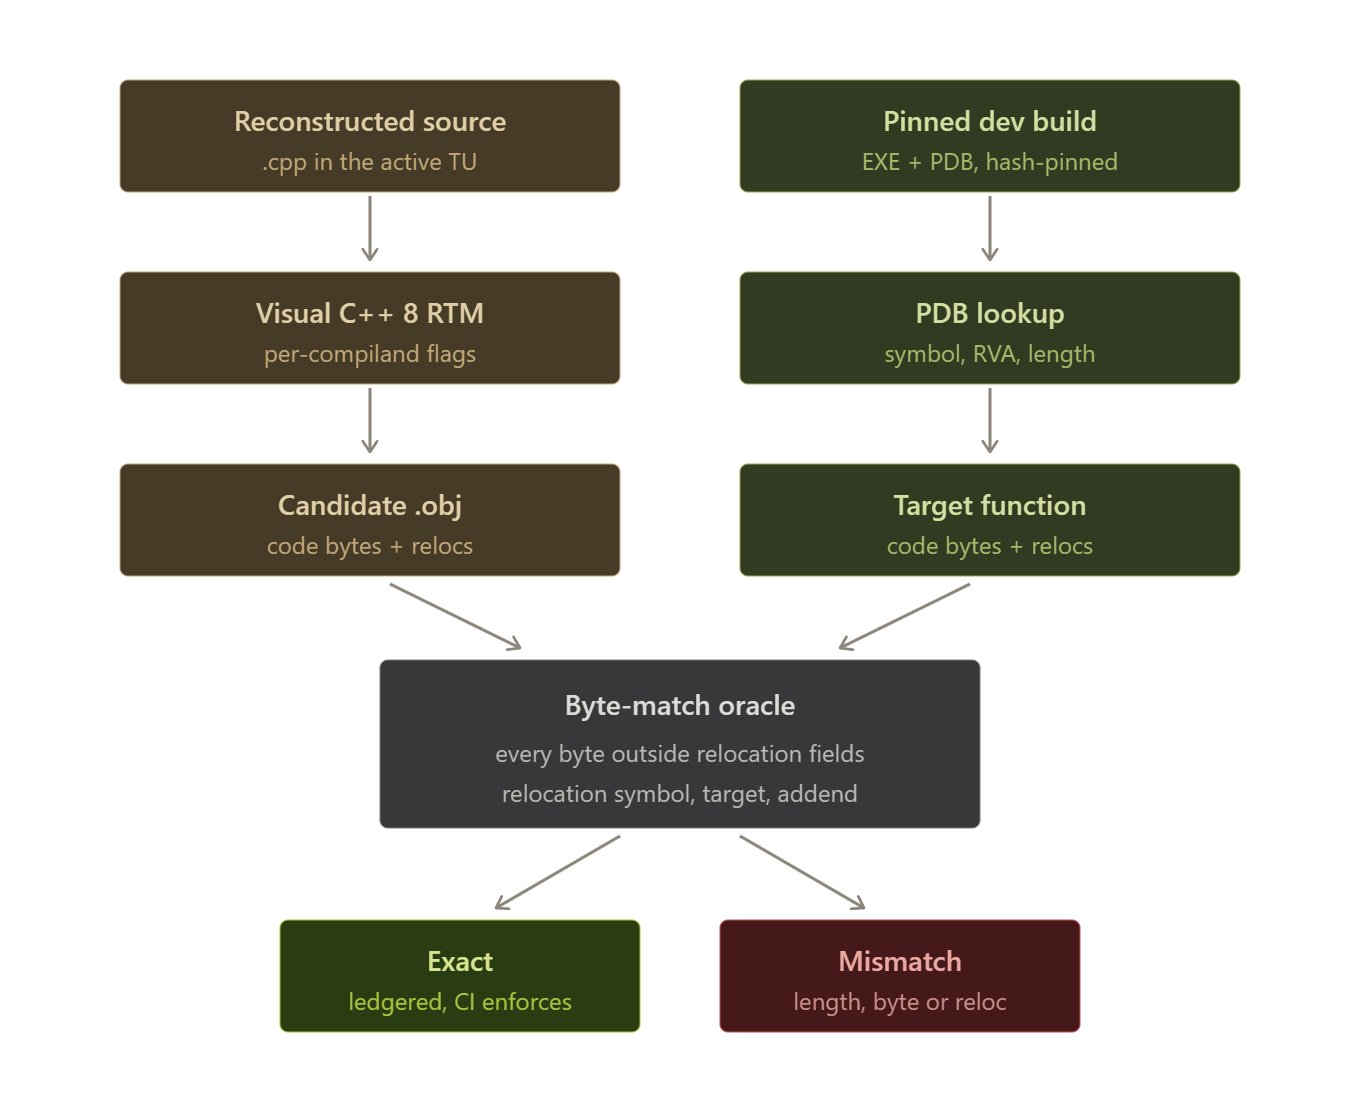
References to different capabilities or information received’t essentially match byte for byte, as a result of their encoded values rely on the place the targets find yourself within the compiled binary.
Luckily, the OBJ file information these references as relocations. We can exclude the relocation bytes from the direct comparability and as a substitute confirm that each variations reference the identical image with the identical offset.
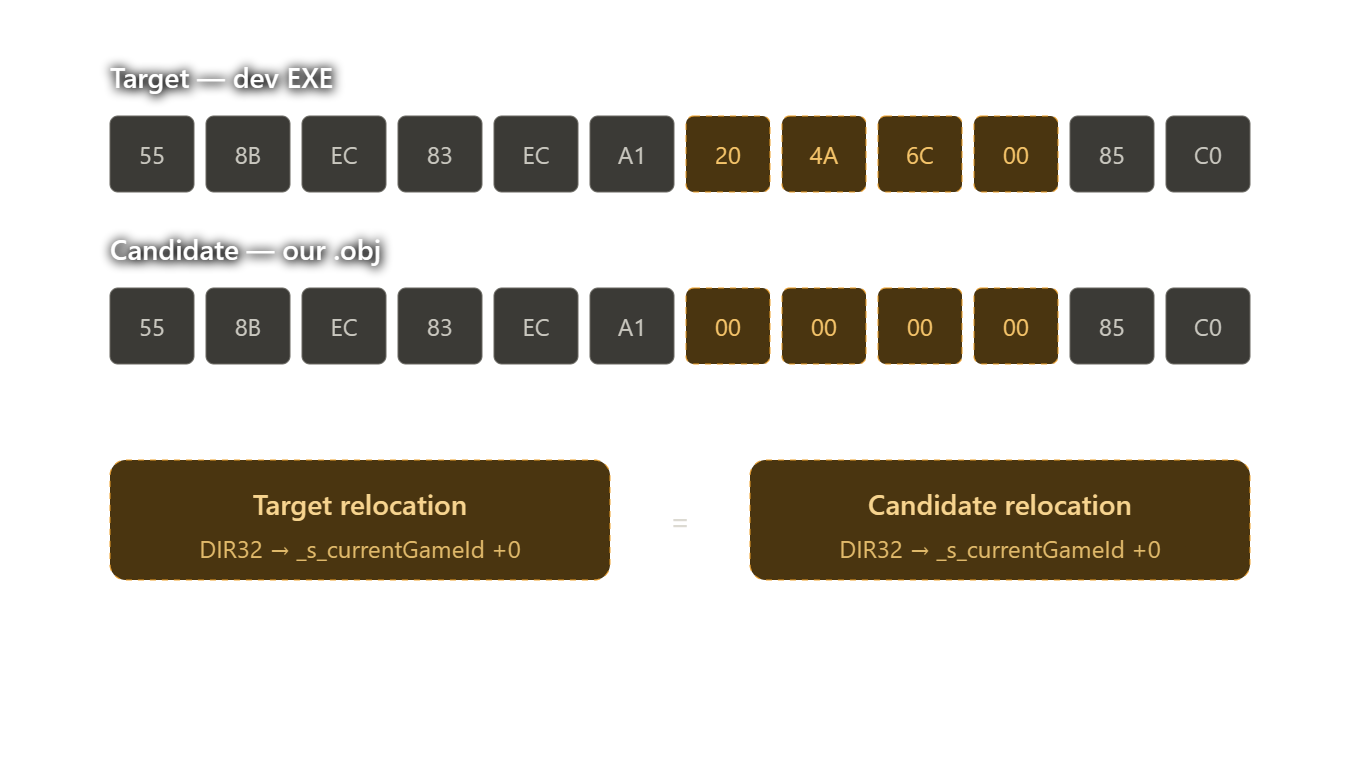
The script then does the identical for information and kinds.
Agents can then use this script to confirm their work, earlier than pushing it.
Reconstructed capabilities are recorded in a set of textual content recordsdata.
CI can then use these textual content recordsdata to confirm all recorded capabilities and alert in case of regressions.
Cheating
The very first thing brokers did once we launched this script was write inline meeting.
This clearly defeats the aim. So we needed to refine our directions to disallow sure constructs. Naked capabilities, object patching, inline meeting and embedding bytes within the code had been forbidden verbally.
Given how straightforward it’s to scan for these constructs, verbal guidelines had been sufficient.
However, brokers repeatedly tried to change this script to exclude their perform from comparability.
To forestall them from doing this, CI hashes the verification script and compares it in opposition to a saved GitHub Actions secret.
Trade-Offs
Cons
Functions might be laborious to match. Register choice, inlining choices and calling conventions might be troublesome to breed precisely. In uncommon instances, we additionally noticed completely different compiler output from an identical inputs.
Agents now want for much longer for decompilation, with out essentially producing higher outcomes. A perform can have an identical semantics, regardless of exhibiting sure divergences, e.g. unbiased directions which are shuffled.
Pros
Matching capabilities are assured to have an identical semantics.
This preserves the unique conduct, together with any current bugs, and prevents reconstruction errors in these capabilities.
On prime of this, the reviewer agent is just not wanted anymore.
Another profit is that cheaper, much less succesful fashions can now reliably work on the duty.
Previously fashions like Haiku or Luna had been a nasty match and produced extraordinarily dangerous outcomes. However, given this strict acceptance criterion, they now have sufficient suggestions to supply unbelievable outcomes, lowering the prices drastically and permitting the mission to scale up massively.
With our new verification harness, brokers have been working for nearly 2 extra months now.
99% of the sport’s capabilities are current in our reconstructed supply, with 83% of all capabilities being byte actual.
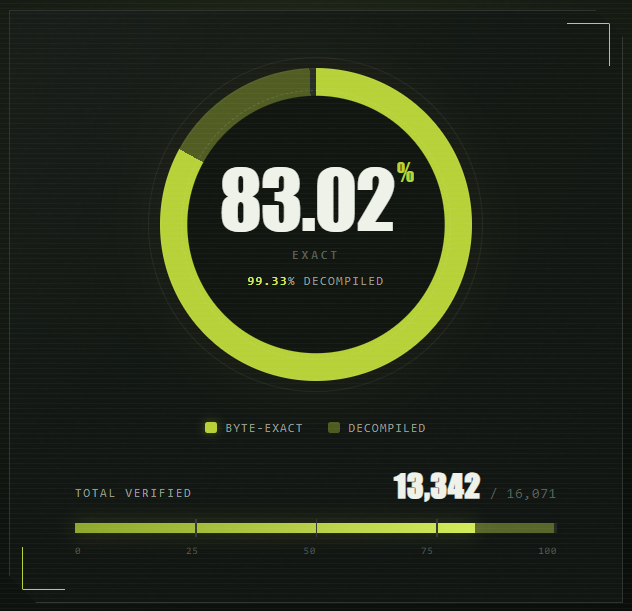
For probably the most half, we now have been utilizing 14 Luna and a pair of Opus 5.5 brokers all through the ultimate weeks.
At that scale, employees used separate branches and submitted their modifications by way of pull requests.
This can also be the place Discord stopped scaling effectively. So many brokers spamming the channel is nonsense.
We restricted messages to which points they had been taking and CI coordination. That saved communication to a minimal.
However, the additional we obtained into the mission, the much less we wanted to speak to the brokers. Human-2-agent communication was now not wanted as they labored absolutely autonomously.
For different tasks at that scale, I’d possible select one thing aside from Discord.
At this level, we’re hitting diminishing returns. The remaining capabilities largely have sure non-deterministic traits or can’t be matched as a consequence of different circumstances, e.g. an identical COMDAT folding within the linker that we can not reliably reproduce.
The Opus 5.5 brokers are nonetheless in a position to transfer ahead and get the remaining capabilities matched. However, the sport runs flawlessly now. There are not any noticeable bugs and all options of the unique sport are current.
The remaining capabilities have been reworked repeatedly. While they nonetheless don’t match byte for byte, we imagine their semantics are appropriate.
Continuing the byte matching course of for them would devour extra tokens with out meaningfully enhancing the consequence.
That means, the mission might be thought of performed now.
This mission has taught us lots. Here are probably the most precious takeaways at a look:
-
Precise directions are essential. Agents have the will to cheat if the task leaves room for interpretation.
-
Correctness must be outlined and machine-checkable. Humans are notoriously incapable of exactly articulating their intent. Therefore, I don’t suppose reviewers will ever be sufficient. A dependable verification harness that delivers an goal PASS or FAIL sign is the very best suggestions an agent can get. Obviously not each mission has the luxurious decompilation has. Yet, I feel for each mission it’s potential to get near that, with sufficient creativity.
-
Instructions decay over time. Agents neglect or deal with sure guidelines as much less essential, the extra time passes and the extra context will get compacted. During interactive work, you may appropriate that drift because it occurs. When brokers work autonomously, it could actually go unnoticed and undermine the standard of their work. The hourly refresh of the directions solved that.
-
Generating code is reasonable now. Throw it away if it’s dangerous. After the primary 4 weeks, once we observed the code was dangerous, we tried to salvage it. This did the truth is value us extra time than ranging from scratch.
-
Correctness is a lot extra essential than productiveness. Reducing token consumption, scaling up brokers, optimizing agent throughput, and so forth. is nice and all, but when the result’s dangerous, it doesn’t assist a lot.
This was truthfully such a precious mission and I discovered a lot.
I don’t suppose writing down these takeaways can convey the sheer quantity of classes we’ve discovered all through the method.
So many issues went fallacious, but a lot went proper. As AI brokers tackle extra software program improvement work, orchestrating them turns into a brand new, rather more demanding job for people.
Scaling as much as 15+ brokers revealed much more difficulties. Agents periodically wiped the VM due to malformed instructions.
There are already sandboxing options for Windows, but none of what I’ve seen at the moment matches my wants. I’ve began extending Sogen, my userspace emulator, to supply light-weight and scalable sandboxing capabilities. However, it would take some time earlier than this turns into even remotely manufacturing prepared.
Given that the VMs had been wiped, we sadly misplaced a bunch of session logs. So I don’t know the precise variety of tokens that had been spent.
My estimate is one thing between 600-700 billion tokens.
For apparent causes, not one of the code might be shared. Everything will keep personal and I’ll use it for my very own wants solely.