OTel-Native by Design – Building Merchandise That Export to Any Observability Stack
With contributions from Dan Gomez Blanco
(New Relic).
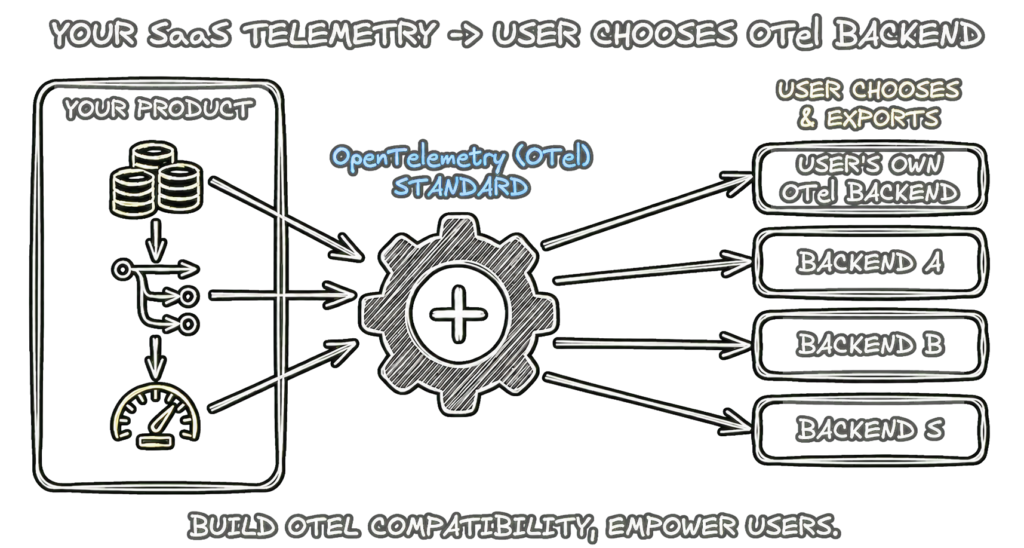
If you’re constructing self-hosted software program or a SaaS product, your customers will
ultimately ask to ship logs, traces, and metrics to their very own observability
stack, whether or not to fulfill compliance, handle prices, or centralize all their
observability knowledge in a single place.
Locking them into your built-in dashboards or limiting exports to sure
distributors creates pointless friction. Instead, supporting export to any
OpenTelemetry (OTel)-compatible backend is a vendor-neutral, future-proof
apply that provides customers the liberty to decide on their observability stack.
This publish outlines how one can design your product so customers can export their
logs, traces, and metrics to an OTel backend once they wish to.
The 4 observability alerts
OpenTelemetry defines four signal types, all carried over the standard
OpenTelemetry Protocol (OTLP):
- Logs: Event information, request/entry logs,
and utility logs with timestamps and metadata. - Traces: Distributed traces and spans so
customers can see request flows throughout companies and correlate them with logs. - Metrics: Counters, gauges, and
histograms (e.g., request charges, latency, error charges). - Profiles: Samples that present the place
functions devour sources throughout execution.
Profiles is in public alpha
Profiles entered public alpha on March 26, 2026.
As a sign, OpenTelemetry intends for profiles to face alongside the present
three main observability alerts, serving to customers troubleshoot manufacturing
incidents by capturing useful resource utilization patterns throughout their codebase.
Although we solely give attention to logs, traces, and metrics on this weblog, we
are excited to see how profiles take form, and the way the group places them to
use of their observability methods.
The similar export story applies to all three (logs, traces, and metrics): let
customers configure an OTLP endpoint and push telemetry to it. You can assist
one, two, or all three alerts relying on what your product generates.
Many platforms that assist OTel export assist a minimum of traces and logs, and an
growing quantity now ship with metrics assist. Designing for all three from
the beginning avoids having to retrofit later.
What a “good” telemetry system seems like
A solid export story has a few clear properties for every signal you support:
- Vendor-neutral: Users can point at any OTel-compatible endpoint — a
Collector instance, or one of many many
backends that support OTLP directly — with out constructing
customized integrations for every. - No deep customized growth: External platforms (or your customers’ tooling)
can combine utilizing normal OTel SDKs and the OTLP
protocol as an alternative of proprietary APIs. - Rich context preserved: Exported knowledge ought to embrace metadata, timestamps,
and hint/span correlation the place accessible (e.g., log information linked to hint
IDs), so customers can debug and analyze knowledge in their very own backend with out dropping
context. - Support for Semantic Conventions: Adherence to the
Semantic Conventions ensures that telemetry knowledge
stays standardized and is definitely interpretable by any suitable backend. It
additionally reduces the cognitive burden on the end-user to purpose about how the
software program system works, be it a first-party or third-party system.
If your design aligns with these ideas for the alerts you emit, you’re in
step with how trendy platforms take into consideration observability export.
Two contexts: the place does your product run?
The way you add OTel export depends on who owns the system that produces the
telemetry. Getting this straight helps you choose the right approach.
Self-hosted software
Your product is an application or system (e.g., an identity server, a service
mesh, a database) that customers install and run in their environment (their
data center, their cloud, their Kubernetes cluster).
Here, you instrument your product with OpenTelemetry. When the customer
configures an endpoint (e.g., via
environment variables
or a config file), your utility exports telemetry from the method they’re
operating.
Since OpenTelemetry offers
such standard configuration options, your
customers can count on the identical configuration expertise they have already got with any
different OTel-instrumented system.
The export occurs within the buyer’s atmosphere; they management the binary and
the vacation spot. Examples: Keycloak, Kuma.
Cloud platforms
Your product is a platform where customers deploy their own apps or use your
managed services (e.g., PaaS, serverless, API gateway). The workload runs on
your infrastructure.
Here, you add a platform feature, such as “Telemetry Drains” or
“Observability Destinations” that lets customers configure where to send
telemetry. Your platform collects telemetry from their workload (and from your
own services, like routers) and forwards it to the customer’s OTLP endpoint.
The export is done by your infrastructure, not by an application binary the
customer runs. Examples: Heroku, Cloudflare.
In short, user-deployed software → focus on built-in instrumentation and
an endpoint config. A platform you operate → focus on configurable export
destinations that your infrastructure uses to forward data.
How others do it
This post focuses on four integrations — Kuma, Keycloak, Cloudflare, and Heroku
— as representative examples across the two contexts above, but they’re far from
the only ones already exporting telemetry natively via OTLP. The
OpenTelemetry Integrations web page options libraries
and companies that present native instrumentation or first-class plugins.
Below is how these 4 deal with all three alerts (or a subset) and what you
can be taught from them.
| Platform | Logs | Traces | Metrics | Deployment Mode | Notes |
|---|---|---|---|---|---|
| Kuma | Yes | Yes | Yes | Software customers deploy | Separate insurance policies per sign, all OTel |
| Keycloak | Yes† | Yes | Yes | Software customers deploy | †Logs in preview; similar endpoint for all |
| Cloudflare Workers | Yes | Yes | No* | Platform | *Metrics export not but supported |
| Heroku | Yes | Yes | Yes | Platform | User chooses alerts by way of --signals |
The self-hosted strategy: Kuma and Keycloak
If your users deploy your software into their own environments, the best
practice is to ship the application pre-instrumented with OpenTelemetry and
expose configuration flags for their OTLP endpoints.
Kuma
Whether customers run Kuma’s control and data planes on their own Kubernetes
clusters or VMs, it comes pre-configured to emit logs, traces, and metrics to an
OTel backend.
Users configure the export, which runs from their Kuma deployments, through the
mesh policies:
- MeshAccessLog: Routes access logs to an OTel Collector (endpoint +
attributes such as mesh name, start time). - MeshTrace: Handles distributed traces with configurable sampling and
tagging. - MeshMetric: Exposes control and data plane metrics. Integrates with
OpenTelemetry and Prometheus.
For example, sending traces to an OTel backend looks like this:
# MeshTrace policy
backends:
  - type: OpenTelemetry
    openTelemetry:
      endpoint: otel-collector:4317
Sending access logs follows the exact same pattern with a different policy:
# MeshAccessLog policy
backends:
  - type: OpenTelemetry
    openTelemetry:
      endpoint: otel-collector:4317
body:
  kvlistValue:
    values:
      - key: mesh
        value:
          stringValue: '%KUMA_MESH%'
attributes:
  - key: start_time
    value:
      stringValue: '%START_TIME%'
Further reading:
Keycloak
Keycloak is another example of self-hosted software providing great telemetry
export functionality.
Instead of requiring a separate sidecar or platform feature, users just pass a
startup flag pointing to their Collector endpoint, and the Keycloak process
itself handles the export.
It uses a single telemetry endpoint but provides granular flags to toggle
specific signals:
- Traces:
tracing-enabled=true(covers HTTP requests, DB, LDAP, outbound
HTTP/IdP). - Metrics: Detailed metrics exposed via the same OTel integration.
- Logs: Currently in preview and disabled by default
(--features=opentelemetry-logs --telemetry-logs-enabled=true, with
--telemetry-logs-levelfor level filtering).
Defining the endpoint, optional headers, and preferred protocol (gRPC or HTTP)
looks like:
bin/kc.sh start --telemetry-endpoint=http://my-otel-endpoint:4317 --telemetry-protocol=grpc
Further reading:
A Common Design Pattern
Both deployment modes have a common, recurring theme.
Push-based export using OTel/OTLP is the preferred and practical pattern.
Some products expose one endpoint for all three signals (Keycloak, for
example, uses a single shared endpoint), whereas others let users pick which
signals to send (Heroku’s --signals).
Natively supporting all telemetry signals gives your users more flexibility to
build a complete picture in their backend of choice.
The platform approach: Cloudflare and Heroku
When you control the infrastructure, a straightforward user experience is to
handle the export at the platform level, pulling data from the user’s workload
and pushing it to their destination.
Cloudflare Workers
Because users run their code directly on Cloudflare’s infrastructure, it handles
the export through the Observability Destinations platform feature. It
offers users a streamlined design where they can configure an OTLP endpoint in
their dashboard. From there, Cloudflare automatically pushes traces and logs
from Workers to that destination.
While metrics aren’t supported yet, the trace data provides deep, end-to-end
visibility as it records handler calls, bindings, outbound fetch calls, and
more. Users can also configure the sampling rate in their wrangler.toml.
Further reading:
Heroku
Heroku takes a slightly different, highly configurable approach with Telemetry
Drains. Users add a destination by specifying the endpoint, transport protocol
and headers, and then explicitly choose which signals to export.
Heroku’s platform then gathers data from both the user’s application (via the
OTel SDK) and first-party services (like their Router) and pushes it to the
destination.
heroku telemetry:add --app --signals traces,metrics,logs --transport http --headers '{"Authorization": "ingestion key"}'
Giving users granular control over which signals to export is a pragmatic design
pattern, especially for teams looking to manage data volume and ingestion costs.
Further reading:
Designing your export model
Across the three essential telemetry signals, the fundamental architectural
question remains the same: will your platform require the user to poll an API
for the data at regular intervals, or will it deliver the telemetry
directly to a user-defined endpoint?
The classic approach: custom polling APIs
Platforms have traditionally exposed telemetry by providing APIs that users must
poll at regular intervals, handle pagination for, and ingest the results into
their own backends.
It’s a reasonable starting point if you already have a mature, well-tested API
for logs or metrics, since extending it is often easier than building a new push
path. However, it comes with real costs:
- You shift a significant operational responsibility onto your users. They must
now build scalable polling systems that can manage polling intervals, paginate
API responses, retry on failures, and backfill missing data. - Users might build custom solutions that don’t scale, don’t adhere to your
standards, and require significant upkeep on their end as your API schema
develops alongside your platform. - Achieving near real-time delivery becomes significantly harder, which is often
a critical requirement for latency-sensitive signals like traces and metrics.
For logs, a pull-based implementation often looks like this (e.g.,
CloudWatch Logs–style):
state: last_end_time
each poll_interval:
  start_time = last_end_time
  end_time   = now()
  next_token = null
  do:
    response = FilterLogEvents(log_groups, start_time, end_time, next_token)
    emit(response.occasions)
    next_token = response.subsequentToken
  whereas next_token != null
Here, you would want related state-tracking logic for the metrics or hint APIs.
Despite forcing customers to put in writing customized code to transform your API responses into
normal codecs, the customized polling mannequin is workable for each supported
sign once you can’t attain for a extra standardized strategy like Prometheus.
For new designs, nevertheless, it shouldn’t be the default.
The standards-oriented strategy: OTLP
For developer-focused, real-time telemetry, OTLP push has become the dominant
pattern.
Instead of waiting to be asked, your service (or an OpenTelemetry Collector you
run) actively exports logs, traces, and metrics directly to the user’s
configured endpoint using OTLP (over HTTP or gRPC).
It uses one vendor-neutral, industry-standard protocol for all telemetry,
meaning you avoid reimplementing telemetry delivery logic for each distinct
signal you support.
Further, OTLP provides first-class support for structured data and metadata,
helping it automatically preserve crucial context, such as linking specific log
records to their parent trace IDs.
From the user’s perspective, it is practically plug-and-play. Any
OTel-compatible backend can ingest the data in near real-time without requiring
custom polling logic.
Building the export experience
When implementing the export model in your product, seek to maximize flexibility
with minimal configuration.
Let users configure an OTLP endpoint
Start by letting users provide their own OTLP endpoint and any necessary
authentication headers (like an ingestion key).
But don’t stop there!
To allow users to control export volume, simplify data management, and reduce
costs, let users explicitly toggle which signals they want to export — following
Heroku’s example.
Standardize the architecture
Under the hood, you have two main options: use the OpenTelemetry SDK directly
within your services to emit data, or run an internal OTel Collector that
gathers your system’s telemetry and re-exports it to the user’s endpoint.
Sticking to standard OpenTelemetry environment variables (like
OTEL_EXPORTER_OTLP_ENDPOINT)
makes the underlying plumbing dependable and simple to doc and purpose about.
Keep semantics constant
Beyond just OTel-based environment variables, make sure you maintain consistent
semantics across all your signals. Semantic Conventions
is your reference for naming attributes and schemas constantly, and for
precisely how logs and metrics relate again to hint and span IDs.
Weaver, which builds on prime of Semantic Conventions,
helps you to outline your individual attribute names and schemas, hold them in lockstep with
evolving code and development projects, and keep federated semantic conference
registries.
When a consumer ingests your telemetry into their observability backend, all the pieces
ought to join end-to-end to inform the entire story.
One advantage of this strategy is that you simply keep away from the necessity to construct completely different
vendor integrations. By exporting telemetry by way of OTLP, you allow customers to
remodel and ingest it of their desired codecs.
For instance, a consumer would possibly want to ahead logs to their backend and to an object
retailer like S3 to satisfy compliance necessities.
Routing telemetry to the consumer
As you design the configuration UI for your users, you’ll need to decide how
granular your telemetry routing should be. You generally have two paths, each
catering to a different type of user.
Single endpoint
For the vast majority of users, a single endpoint configuration is ideal. Here,
the user inputs one base URL, and your exporter appends the standard OTLP paths
(v1/traces, v1/metrics, and v1/logs) internally.
Per-signal endpoints
Large-scale customers, or those managing complex observability setups, may wish
to send telemetry signals to different platforms.
OTLP natively supports this with signal-specific variables defined by the
OTEL_EXPORTER_OTLP_ pattern, along with corresponding
header configurations.
For instance, to configure a selected endpoint for logs, you’d use the
OTEL_EXPORTER_OTLP_LOGS_ENDPOINT.
Exposing this per-signal routing in your utility is technically optionally available,
however it’s a main value-add for superior customers.
Running Collectors to handle multi-tenancy
Once you’re pushing OTLP (for any combination of logs, traces, metrics), you
still need to decide how to run Collectors to manage multiple tenants.
Your Collector architecture needs to scale alongside two
dimensions of development: onboarding extra customers, and the quantity of latest telemetry
generated as you ship new options.
One Collector per tenant
If your architecture already isolates tenants at the infrastructure level, you
can deploy a dedicated Collector instance for each customer. In this case, every
instance has a dedicated configuration pointing directly to that specific
customer’s export endpoint.
This provides strong logical isolation guarantees. Slowdowns or
misconfigurations in one customer’s pipeline do not affect other customers.
Although you can build a custom Collector binary
that solely ships very important elements, deploying tons of or 1000’s of Collector
situations will grow to be resource-intensive.
Because of this tradeoff, this structure is normally the most effective match for
enterprise SaaS merchandise the place sturdy multi-tenant isolation is a strict
requirement and prospects might need advanced endpoint configurations.

Shared Collector with static pipelines per tenant
Here, “static” means each tenant’s pipeline and routing rules are defined
up-front in the Collector’s configuration file, rather than provisioned
dynamically at runtime.
This is close in spirit to the
gateway deployment pattern: all of your
platform’s telemetry funnels right into a single, centralized Collector. Inside, you
outline separate pipelines per tenant — the
routing connector
is a pure match right here, directing knowledge to the proper pipeline (and due to this fact the
proper exterior endpoint) primarily based on useful resource attributes like a tenant ID.
This sample works properly for groups at early or average scale, the place working a
single deployment is less complicated than managing per-tenant situations. You solely have
to observe and scale one deployment, and all routing is configured in a single place.
However, you should be snug managing a rising dynamic configuration file
as your buyer base grows.

Custom polling APIs vs OTLP: the decision
When the choice is between making your users poll custom APIs and letting them
ingest over a shared standard, most modern, developer-focused platforms should
opt for the latter. Reach for custom polling APIs if standardization isn’t an
option.
OpenTelemetry’s unified protocol preserves rich context, delivers data in near
real-time, and has been proven at scale across cloud and self-hosted deployments
by Cloudflare, Heroku, Kuma, and Keycloak. Plus, OpenTelemetry’s independence
from a particular vendor means users have the freedom to switch between
observability backends based on their business needs, without requiring a
complete overhaul of their telemetry pipelines.
OpenTelemetry adoption does not come for free, though, as your team must invest
time to learn and implement OpenTelemetry, and build necessary documentation to
guide users and internal teams on best practices.
Because of OTel’s rising adoption across the observability landscape — the
project recently
graduated from CNCF
— this upfront funding pays dividends as you combine instruments in your
platform that depend on OpenTelemetry to export their very own telemetry.
Putting all of it collectively
To conclude, you don’t need to build bespoke integrations to let your users
export telemetry to their own backends.
If you’re ready to implement OTel-native export in your application, here’s a
summary of the key architectural and design steps to follow:
- Decide which telemetry signals to support out of logs, traces, and metrics.
You should ideally support all three, but start with what your product
generates. - Use OTLP to export those signals via the OTel SDK or a Collector. The same
push-based architecture works for all three signals. - Let users configure a destination endpoint and optional auth headers. Consider
per-signal endpoints for teams with more complex setups. - Allow users to enable or disable individual signals to control data volume and
costs. - Document your endpoint format (gRPC/HTTP), required headers, and
attribute/schema semantics per signal so users can confidently rely on the
data in their backends. - Choose a Collector topology: one Collector per tenant for strong isolation, or
a shared Collector with per-tenant pipelines for lower operational overhead. - Provide an example config or env var snippet so users can get started quickly.
The points above also encapsulate the golden rules that Cloudflare (except for
metrics), Heroku, Kuma, and Keycloak follow: default to push, stay
vendor-neutral, and document the contract.
Designing for all three signals using open standards from the start removes
friction, reduces your engineering overhead, and empowers customers to make the
best use of their data on their own terms.
If you’ve already implemented OTel-native export in your product, consider
adding it to OpenTelemetry Integrations.
It’s a good way to floor your work to the broader group.
Note
If you’re studying this as an end-user, not a builder: you don’t must
wait to your SaaS vendor to come back round on this.
Ask them for OTLP export straight; it’s an inexpensive, more and more widespread
request, and now you might have this publish to level them to!