Jane Avenue Weblog – Scaling and benchmarking a crucial message bus utilizing a brand new indexing technique
The following is a part of a sequence of posts about 2026 summer time intern tasks—for extra,
see “What the interns have wrought, special jumbo 2026
edition”
Aria
is our inside messaging framework and hosted system that processes a number of terabytes of
knowledge per day. Clients can subscribe to Aria to get a stay stream of messages. As Aria
utilization has quickly grown on the agency, we’ve needed to discover extra alternatives to optimize and
re-architect the system to scale with the rise in knowledge quantity and throughput. An
intern working with the Aria group, Theodor Totev, targeted this summer time on utilizing indexing
and tree-splitting to enhance a particular use case: How can we make it cheaper for shoppers
to learn only a subset of messages? His optimizations led to a 30% lower in CPU
utilization when working on manufacturing workloads, whereas protecting the extraordinarily excessive bar of
correctness wanted for such a crucial system.
Filtering messages was overloading our servers
When Aria delivers messages to a shopper through TCP, it retains the latest stream, what we name
the stream tip, in an in-memory ring buffer. If a shopper falls behind, it could possibly request
latest messages from this ring buffer to rise up thus far. We name this course of tip
restoration.
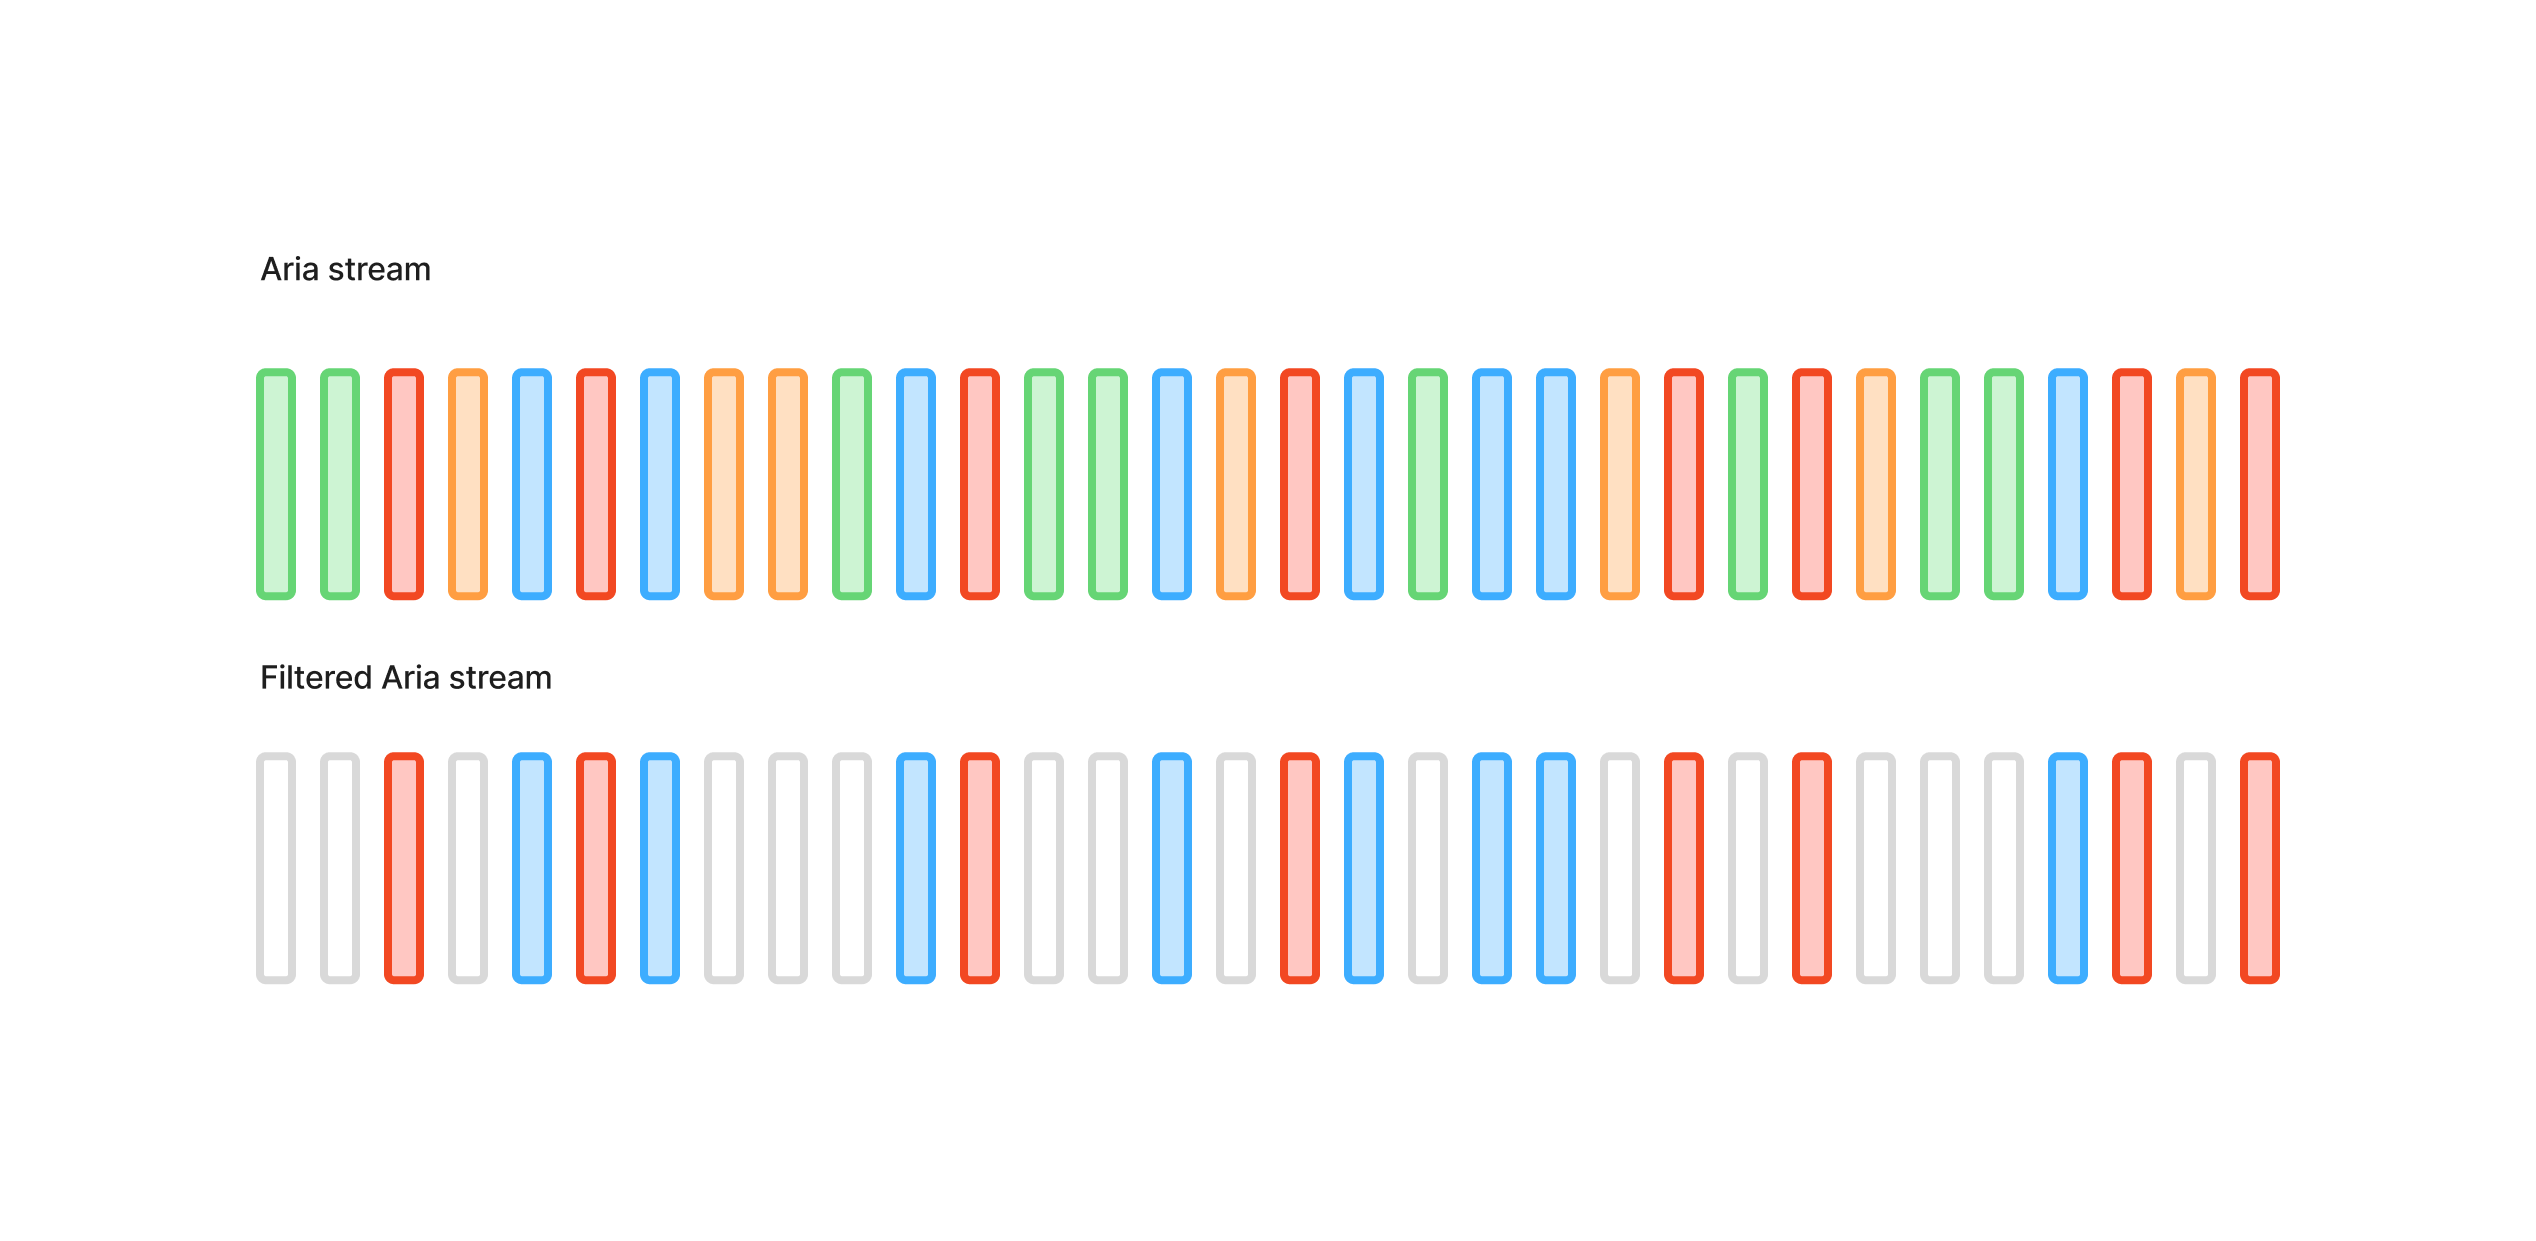
One problem with tip restoration is that Aria shops your complete stream of messages, when
shoppers usually solely care a few a lot smaller subset of the messages. Aria divides the
message stream into subjects, which kind a hierarchical namespace like a file
system. Clients can subscribe to a person matter or to a subject subtree, which consists
of all subjects underneath a given matter, just like a
globstar. Aria
filters your complete stream right down to solely the messages from the subscribed subjects and
delivers these messages to the shopper.
Originally we had been advantageous doing this filtering as a easy linear move as a result of, whereas
algorithmically inefficient, looping over the stream is CPU cache pleasant and due to this fact
decently quick. However, because the variety of shoppers doing tip restoration grew, we observed that
our servers had been fighting the elevated load. Some servers reached 100% CPU
utilization, leading to shoppers “falling off the tip” and being unable to catch up. We
added extra servers as a short lived repair, nevertheless it turned clear that we desperately wanted to
re-think our tip restoration code.
Theodor determined to resolve this downside by including index knowledge buildings that Aria may use
to effectively filter messages from the stream. But what ought to be listed? A naive
strategy can be to make an index for every matter. However, Aria situations can have nearly
1,000,000 subjects, making this strategy untenable. Instead, Theodor created an index for
every matter partition. A subject partition consists of all subjects with the identical
two-segment prefix, a section being a single a part of the subject title separated by a
slash. For occasion, app/codestore/commits and app/codestore/options would each be
underneath the app/codestore matter partition.
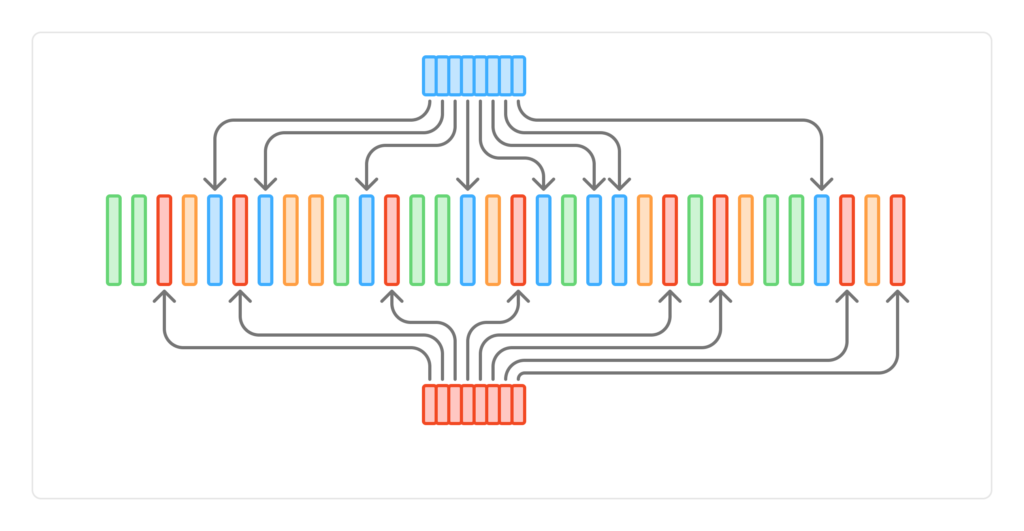
Each matter partition will get an index of its messages’ location within the Aria stream:
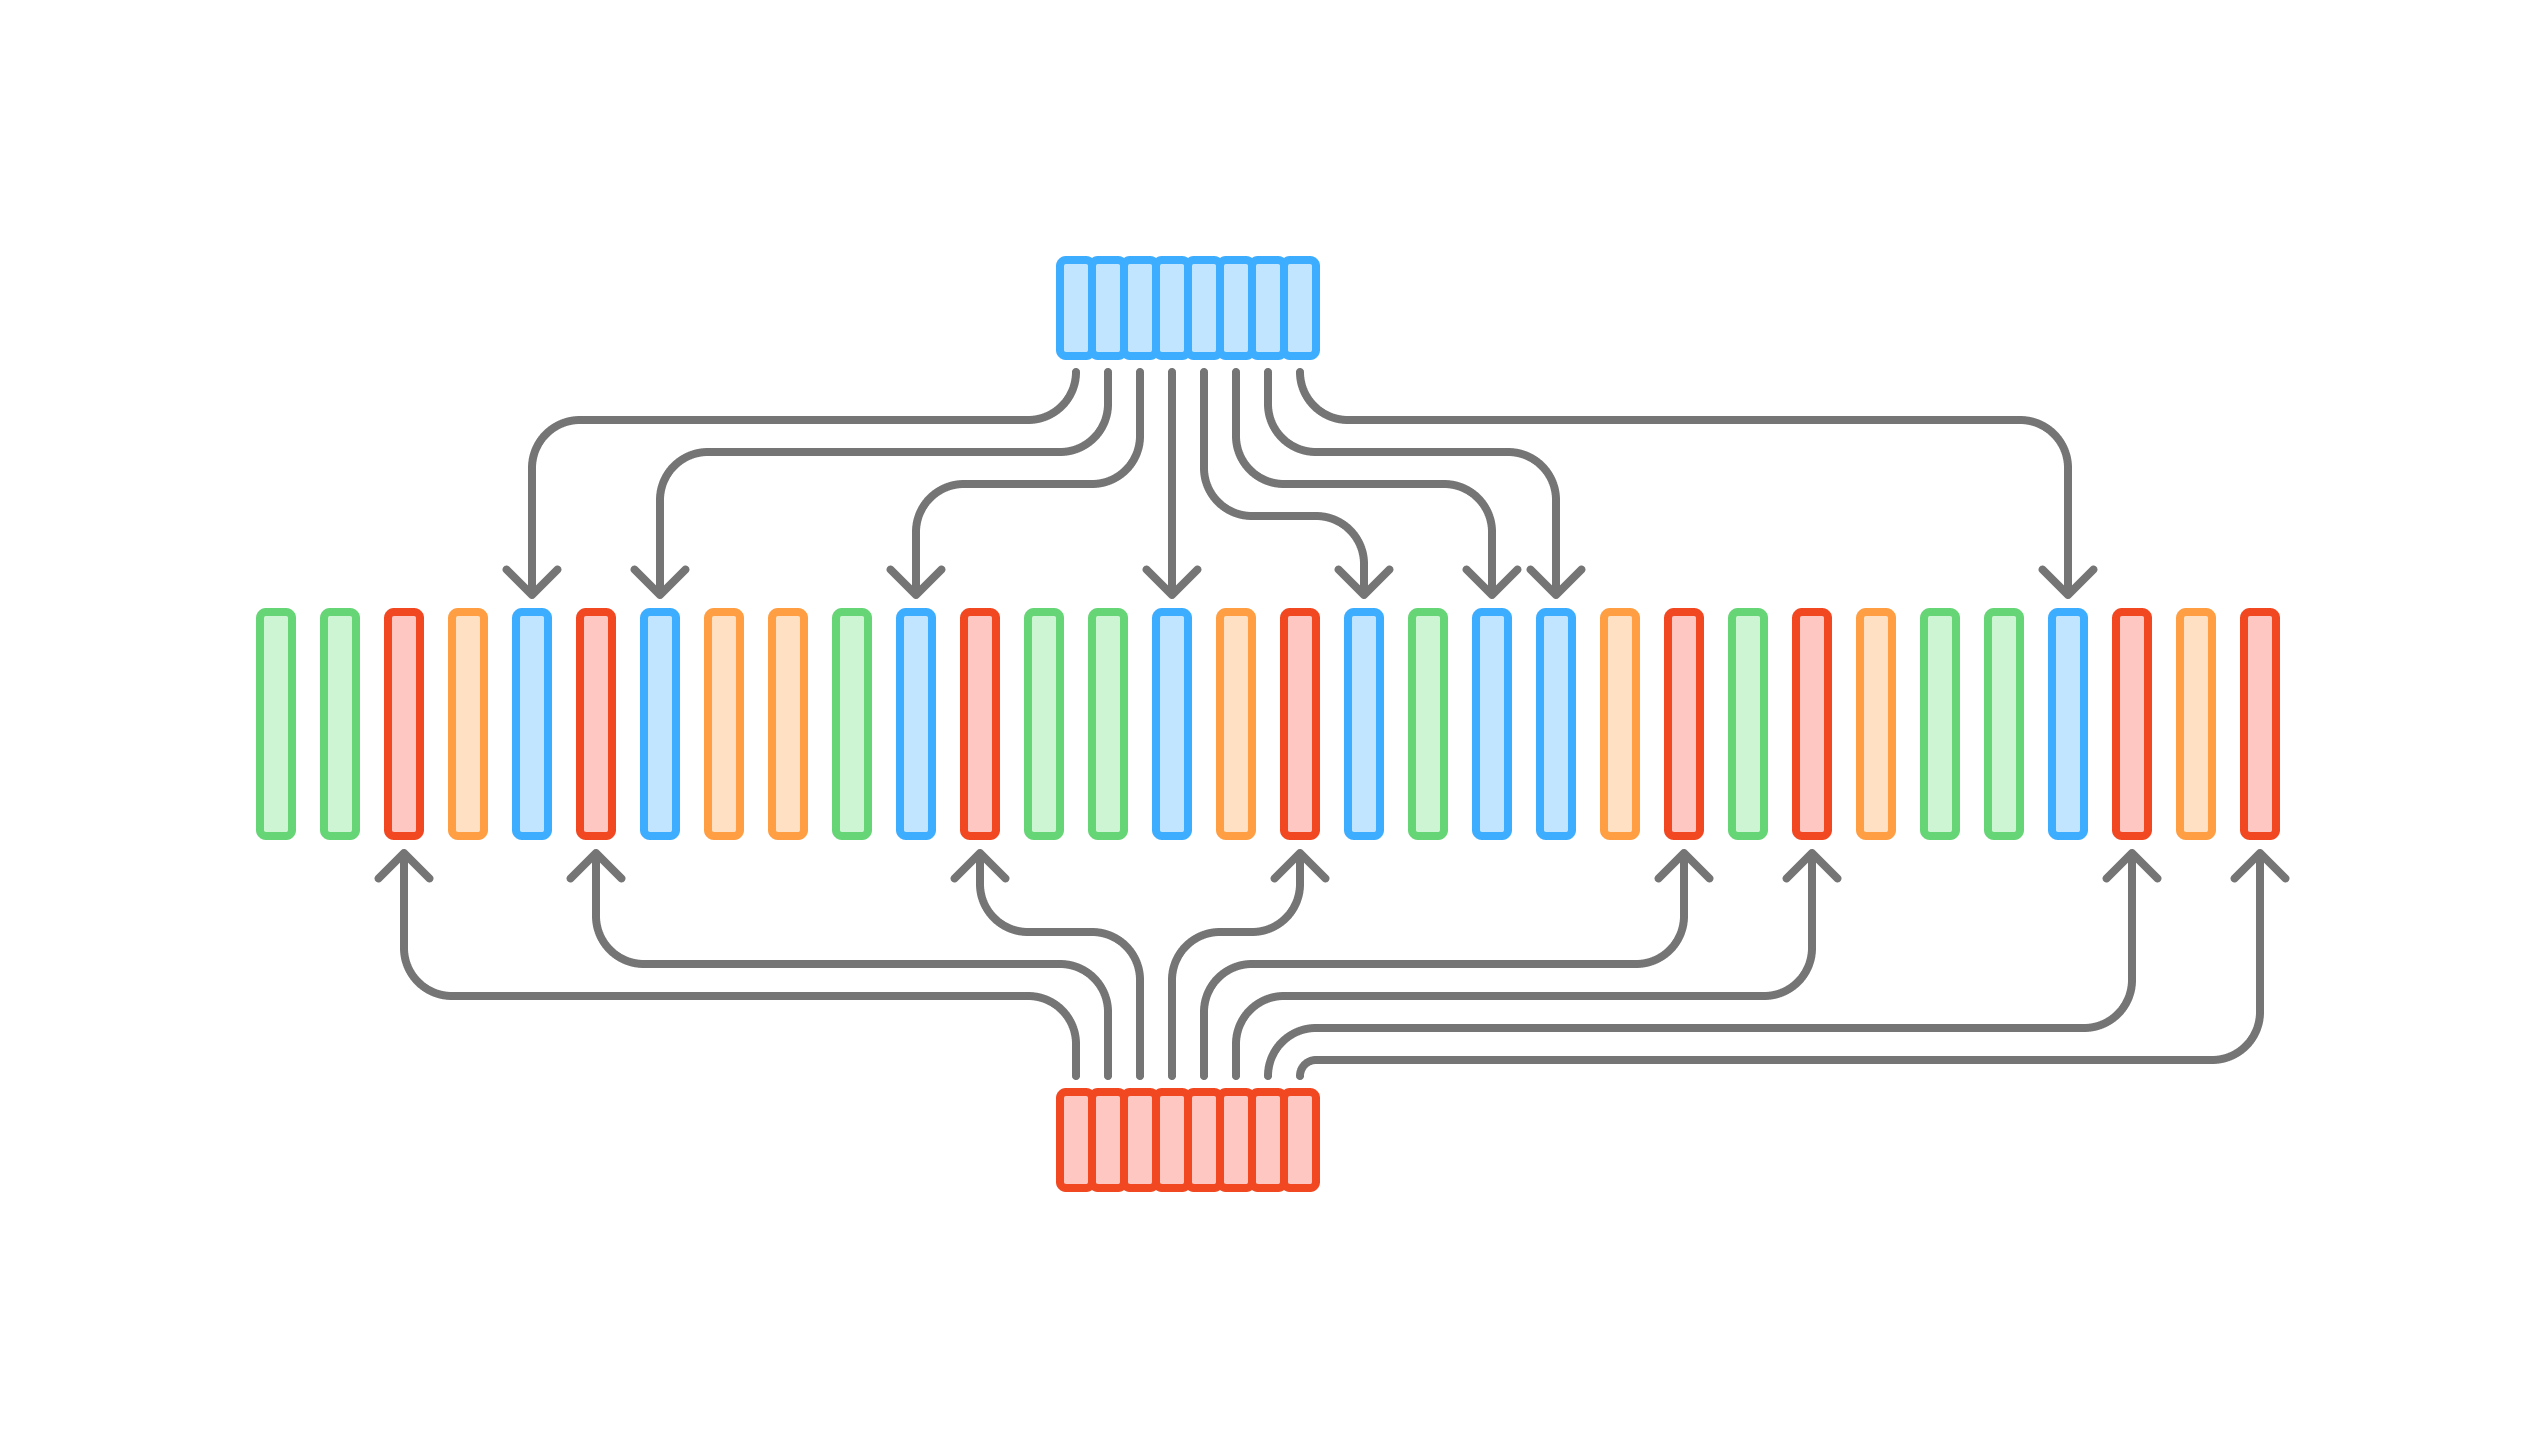
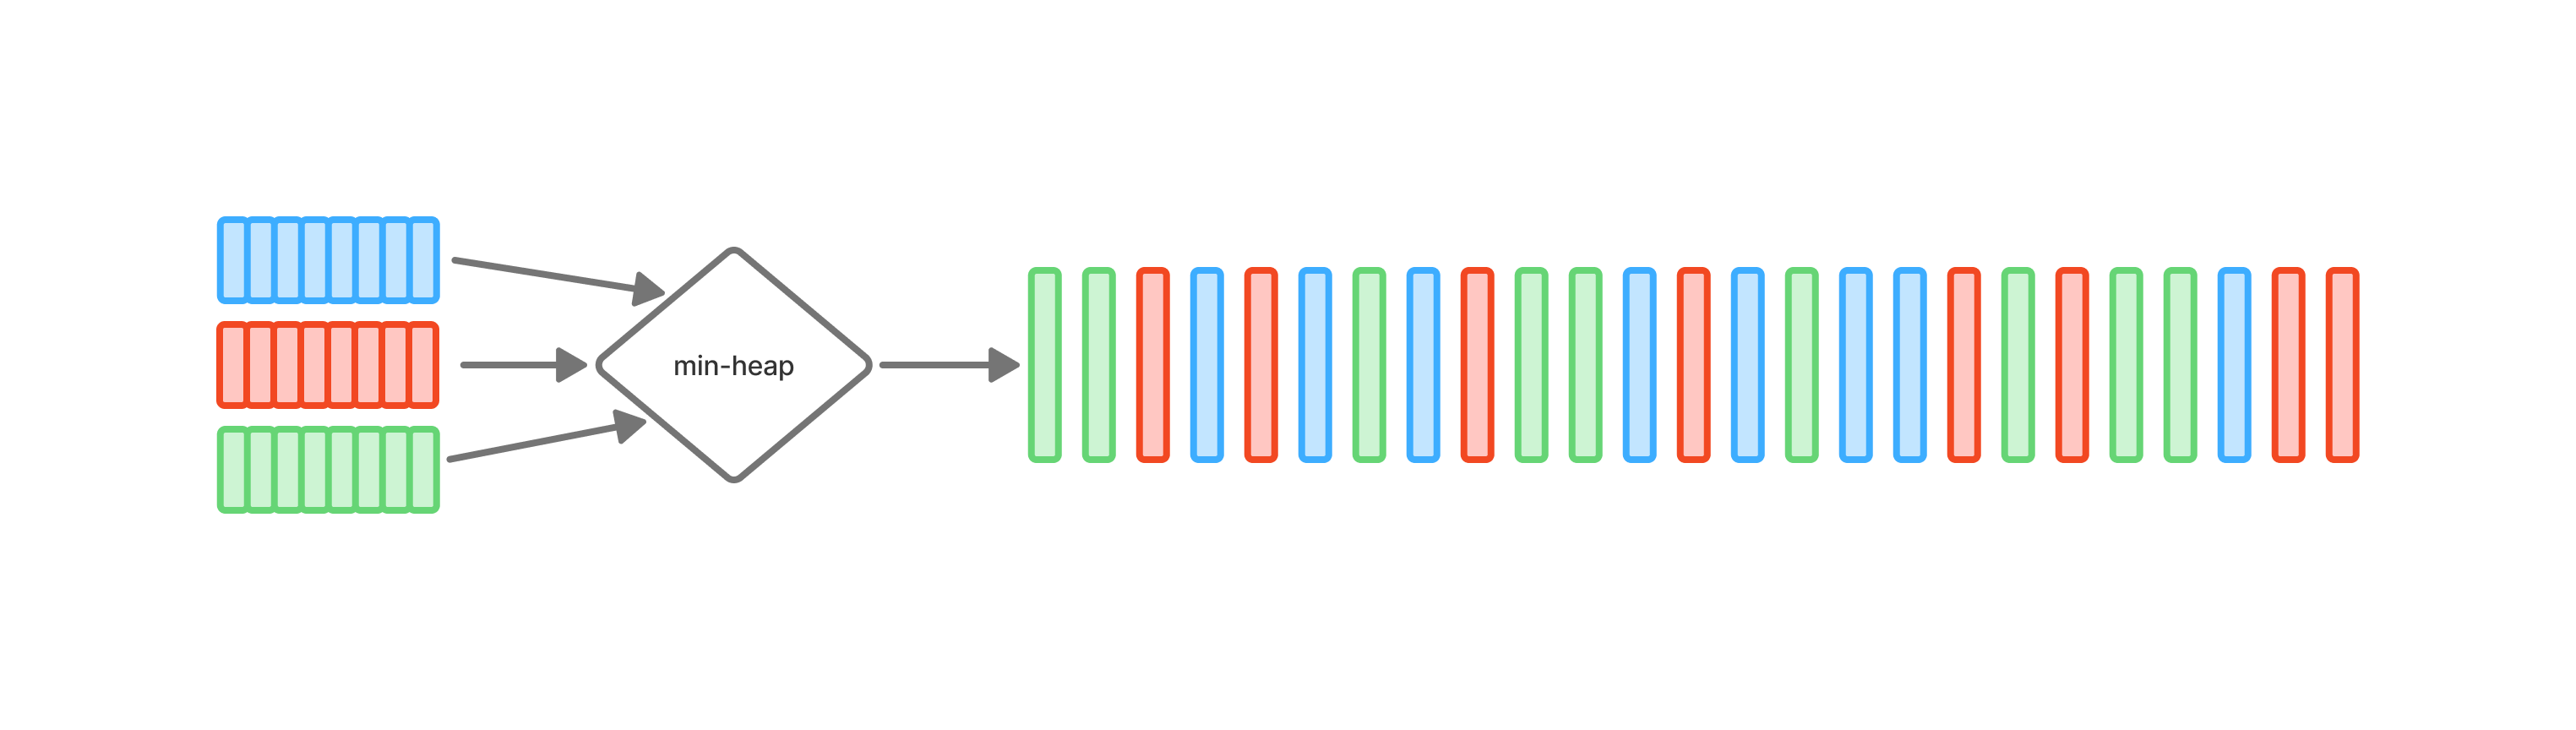
When a shopper requests messages, Aria does an n-way merge of the indexes utilizing a
min-heap. This permits Aria to effectively reconstruct the message stream, so as, for
simply these particular matter partitions:
Prototyping and benchmarking the index
As with any efficiency work, we needed to benchmark with a view to validate that we had been
truly enhancing the system. We additionally wished in depth testing, because the message
publishing logic is within the crucial path for Aria.
Theodor began by writing a instrument to profile numerous restoration eventualities. That approach, we
may check out completely different configurations, such because the variety of matter partitions, the
diploma of interleaving, the variety of readers, and so on., and see how altering these variables
affected the efficiency of the system.
With the benchmark in hand, he carried out the preliminary model of the subject partition
index. When we profiled this implementation, we discovered that the min-heap was the most important
bottleneck in our code. Before AI, that is most likely the place we’d choose a single
implementation that gave the impression to be higher. But nowadays, working experiments is reasonable:
Theodor prompted an agent to spin up 5 completely different heap implementations and profile them
in a single day. The subsequent day, we had our reply: fast_heap_unboxed gave us a 2x efficiency
enchancment to our listed restoration code.
Theodor examined the brand new index with loads of expect
tests, exercised the brand new logic in
Antithesis, and
lastly had a swarm of brokers analyze the code with excessive scrutiny.
Using a block pool to retailer the indexes
Once we devised the index knowledge construction, we would have liked to determine an environment friendly
illustration. We didn’t wish to make a hoop buffer for every index, since ring buffers
should not actually dynamically resizable. They would due to this fact need to be sized to accommodate
the worst case situation. Specifically, index dimension is inversely proportional to message
dimension (smaller messages imply extra messages can match within the tip retailer, which implies you want a
bigger index). An Aria message could be as small as 32 bytes. If your complete tip retailer
consisted of messages that small, the corresponding index can be 2GB. Keeping a 2GB
index for every matter partition would waste an excessive amount of reminiscence.
Instead, we wished an index to dynamically shrink and develop with the variety of messages in
its matter partition.
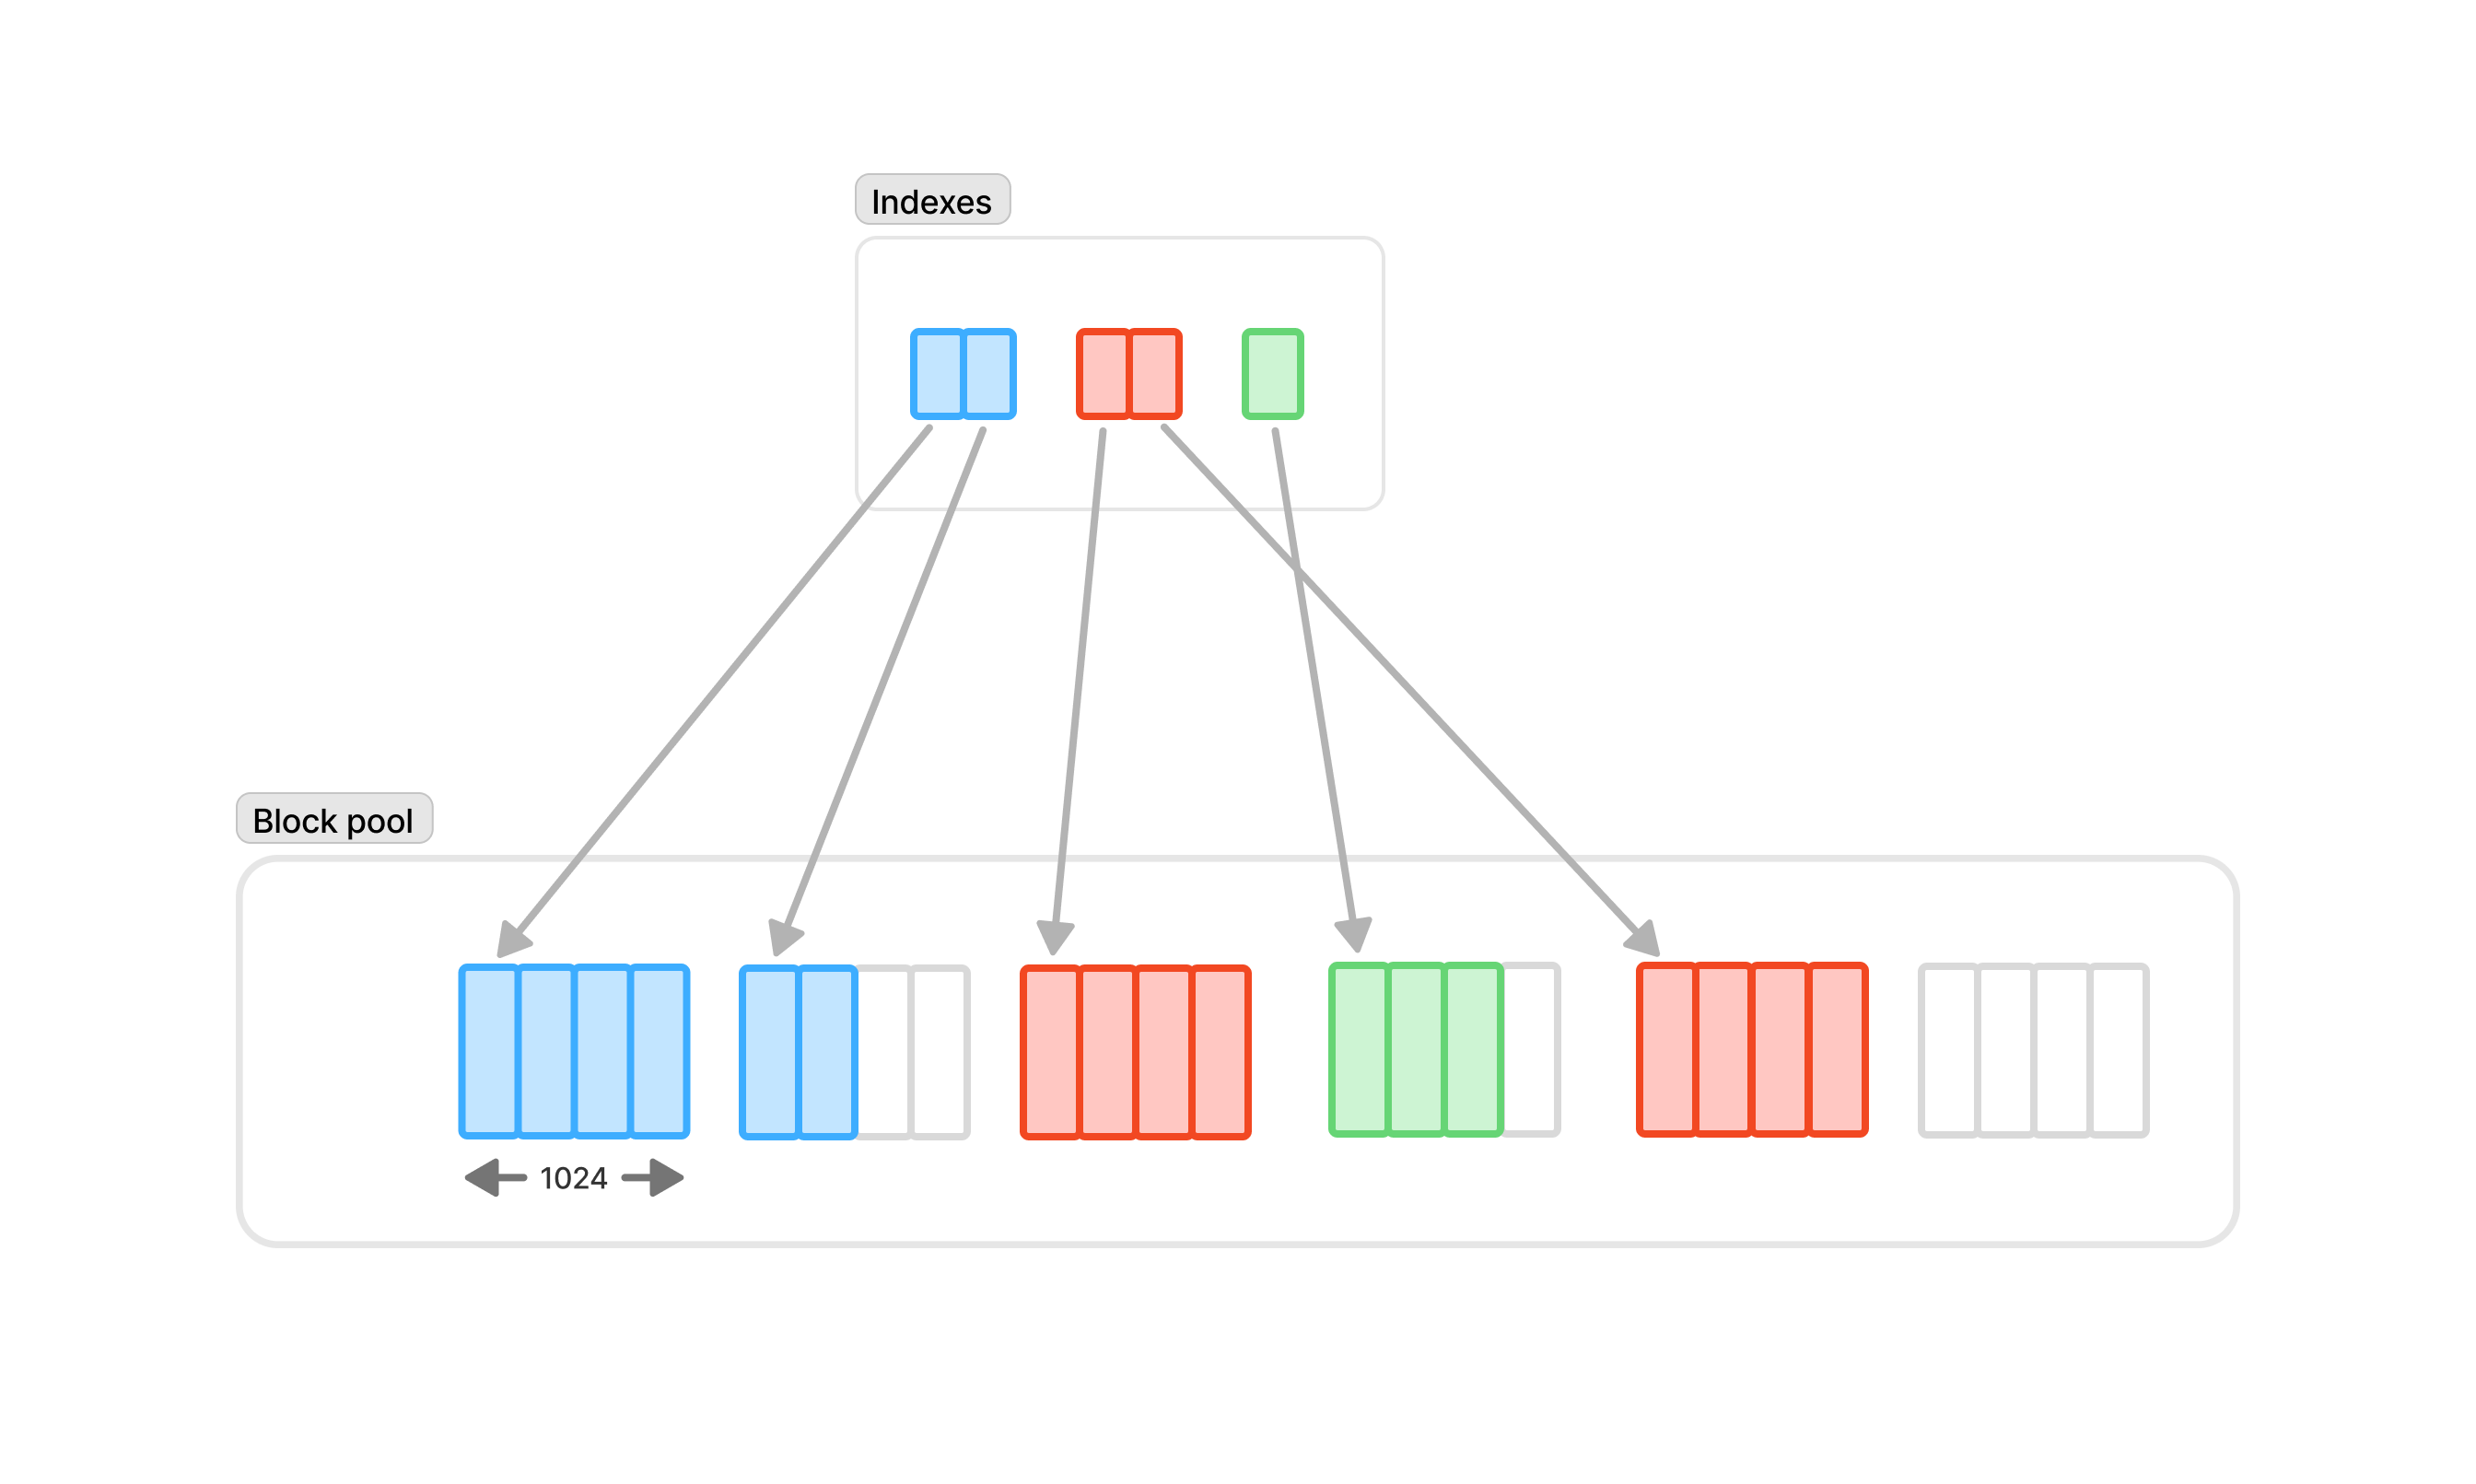
What we settled on was utilizing a shared pool of blocks that every include 1024 entries. The
indexes level to a block and insert values into it. Once the entire messages inside a
block have left the ring buffer, blocks could be popped off from the index and re-used for
different indexes:
Reading outdated messages was taking too lengthy
Theodor’s work on indexing fastened our tip restoration woes, however we had one other message
supply downside: Clients that wanted messages from earlier than the stream tip had been ready
approach too lengthy.
When a shopper reboots, it usually requests all messages because the starting of the week from
its subscribed subjects. We name this course of preliminary restoration. Initial restoration can
contain thousands and thousands, even billions of messages. It’s completely crucial that Aria learn
these messages and ship them to shoppers as shortly as attainable. Also, shoppers are likely to
reboot throughout the identical time, so it’s particularly necessary that this course of scales
properly.
In one explicit incident, an preliminary restoration that normally took underneath 2.5 seconds was
taking up 13 minutes. When we dug into why, we discovered the identical problem that plagued the
tip retailer: Aria was studying and filtering 10x extra knowledge than it truly wanted to
ship. It was clear that we would have liked to rethink how we had been storing messages on disk.
Aria persists messages in subtree shops
Aria initially shops the messages on disk in chronological segments for every matter
partition. Then, a separate course of takes these segments and splits them into a number of
subtree shops that every include messages for a subject subtree. These subtree shops
are supposed to strike a steadiness between writing to many recordsdata, which ends up in environment friendly
filtering however requires extra work to recombine right into a message stream, and writing to fewer
recordsdata, which is simpler to recombine however much less environment friendly to filter.
To do that splitting, Aria had been utilizing a easy heuristic: it selected the subtree retailer
by studying the primary three segments of the subject. So if we had subjects
app/choices/orders/created and app/choices/orders/cancelled, these would each get put
right into a subtree retailer for app/choices/orders. If the subject had fewer than three segments,
it was put into its personal subtree retailer; as an example, app/choices would get its personal
retailer. Effectively, this heuristic gave every direct little one of a subject partition a separate
subtree retailer.
However, this heuristic didn’t work properly when one matter in a retailer had considerably extra
messages than the opposite. If the shopper had been to subscribe to only the much less energetic matter,
Aria must filter out the entire different matter’s messages. Like with tip restoration,
this filtering created numerous work.
More broadly, we weren’t completely satisfied that customers needed to perceive this particular facet of Aria’s
inside design when designing their matter construction. We wished customers to construction their
subjects in a approach that made sense to them and have them belief that Aria would do the
splitting intelligently.
Theodor was tasked with creating an algorithm that would keep away from this problem by
intelligently splitting the subject tree based mostly on every matter’s message quantity. Aria is ready
to calculate the message quantity per matter, because it does this section processing step
after persisting the message stream.
Gathering knowledge and testing completely different algorithms
Like with the tip restoration implementation, Theodor’s work on adaptive splitting required
exploring completely different choices. He began by gathering knowledge from numerous Aria periods that
may very well be used to check out completely different algorithms. He then carried out a couple of completely different
algorithms for splitting and ran them on the collected knowledge. Theodor analyzed these
outcomes from a couple of completely different lenses, akin to:
- How many bytes do now we have to disregard from a retailer if we learn a subject?
- What is the sum of those “wasted bytes” over all of the subjects?
- What matter, if learn, would lead to essentially the most wasted bytes?
- What matter, if learn, would consequence within the worst ratio of complete bytes to helpful bytes?
As earlier than, this technique of exploration was aided by LLMs. Theodor was capable of shortly
vibe-code an internet UI that visualized the completely different splitting algorithms throughout actual knowledge
units.
The last algorithm
Eventually Theodor settled on an answer that mixed a grasping clustering algorithm with
a binary search. This gave us the properties that we had been on the lookout for: Topics with quite a bit
of messages obtain their very own subtree retailer, whereas smaller subjects are folded right into a single
retailer.
Here’s an instance of a subject tree utilizing the earlier heuristic:
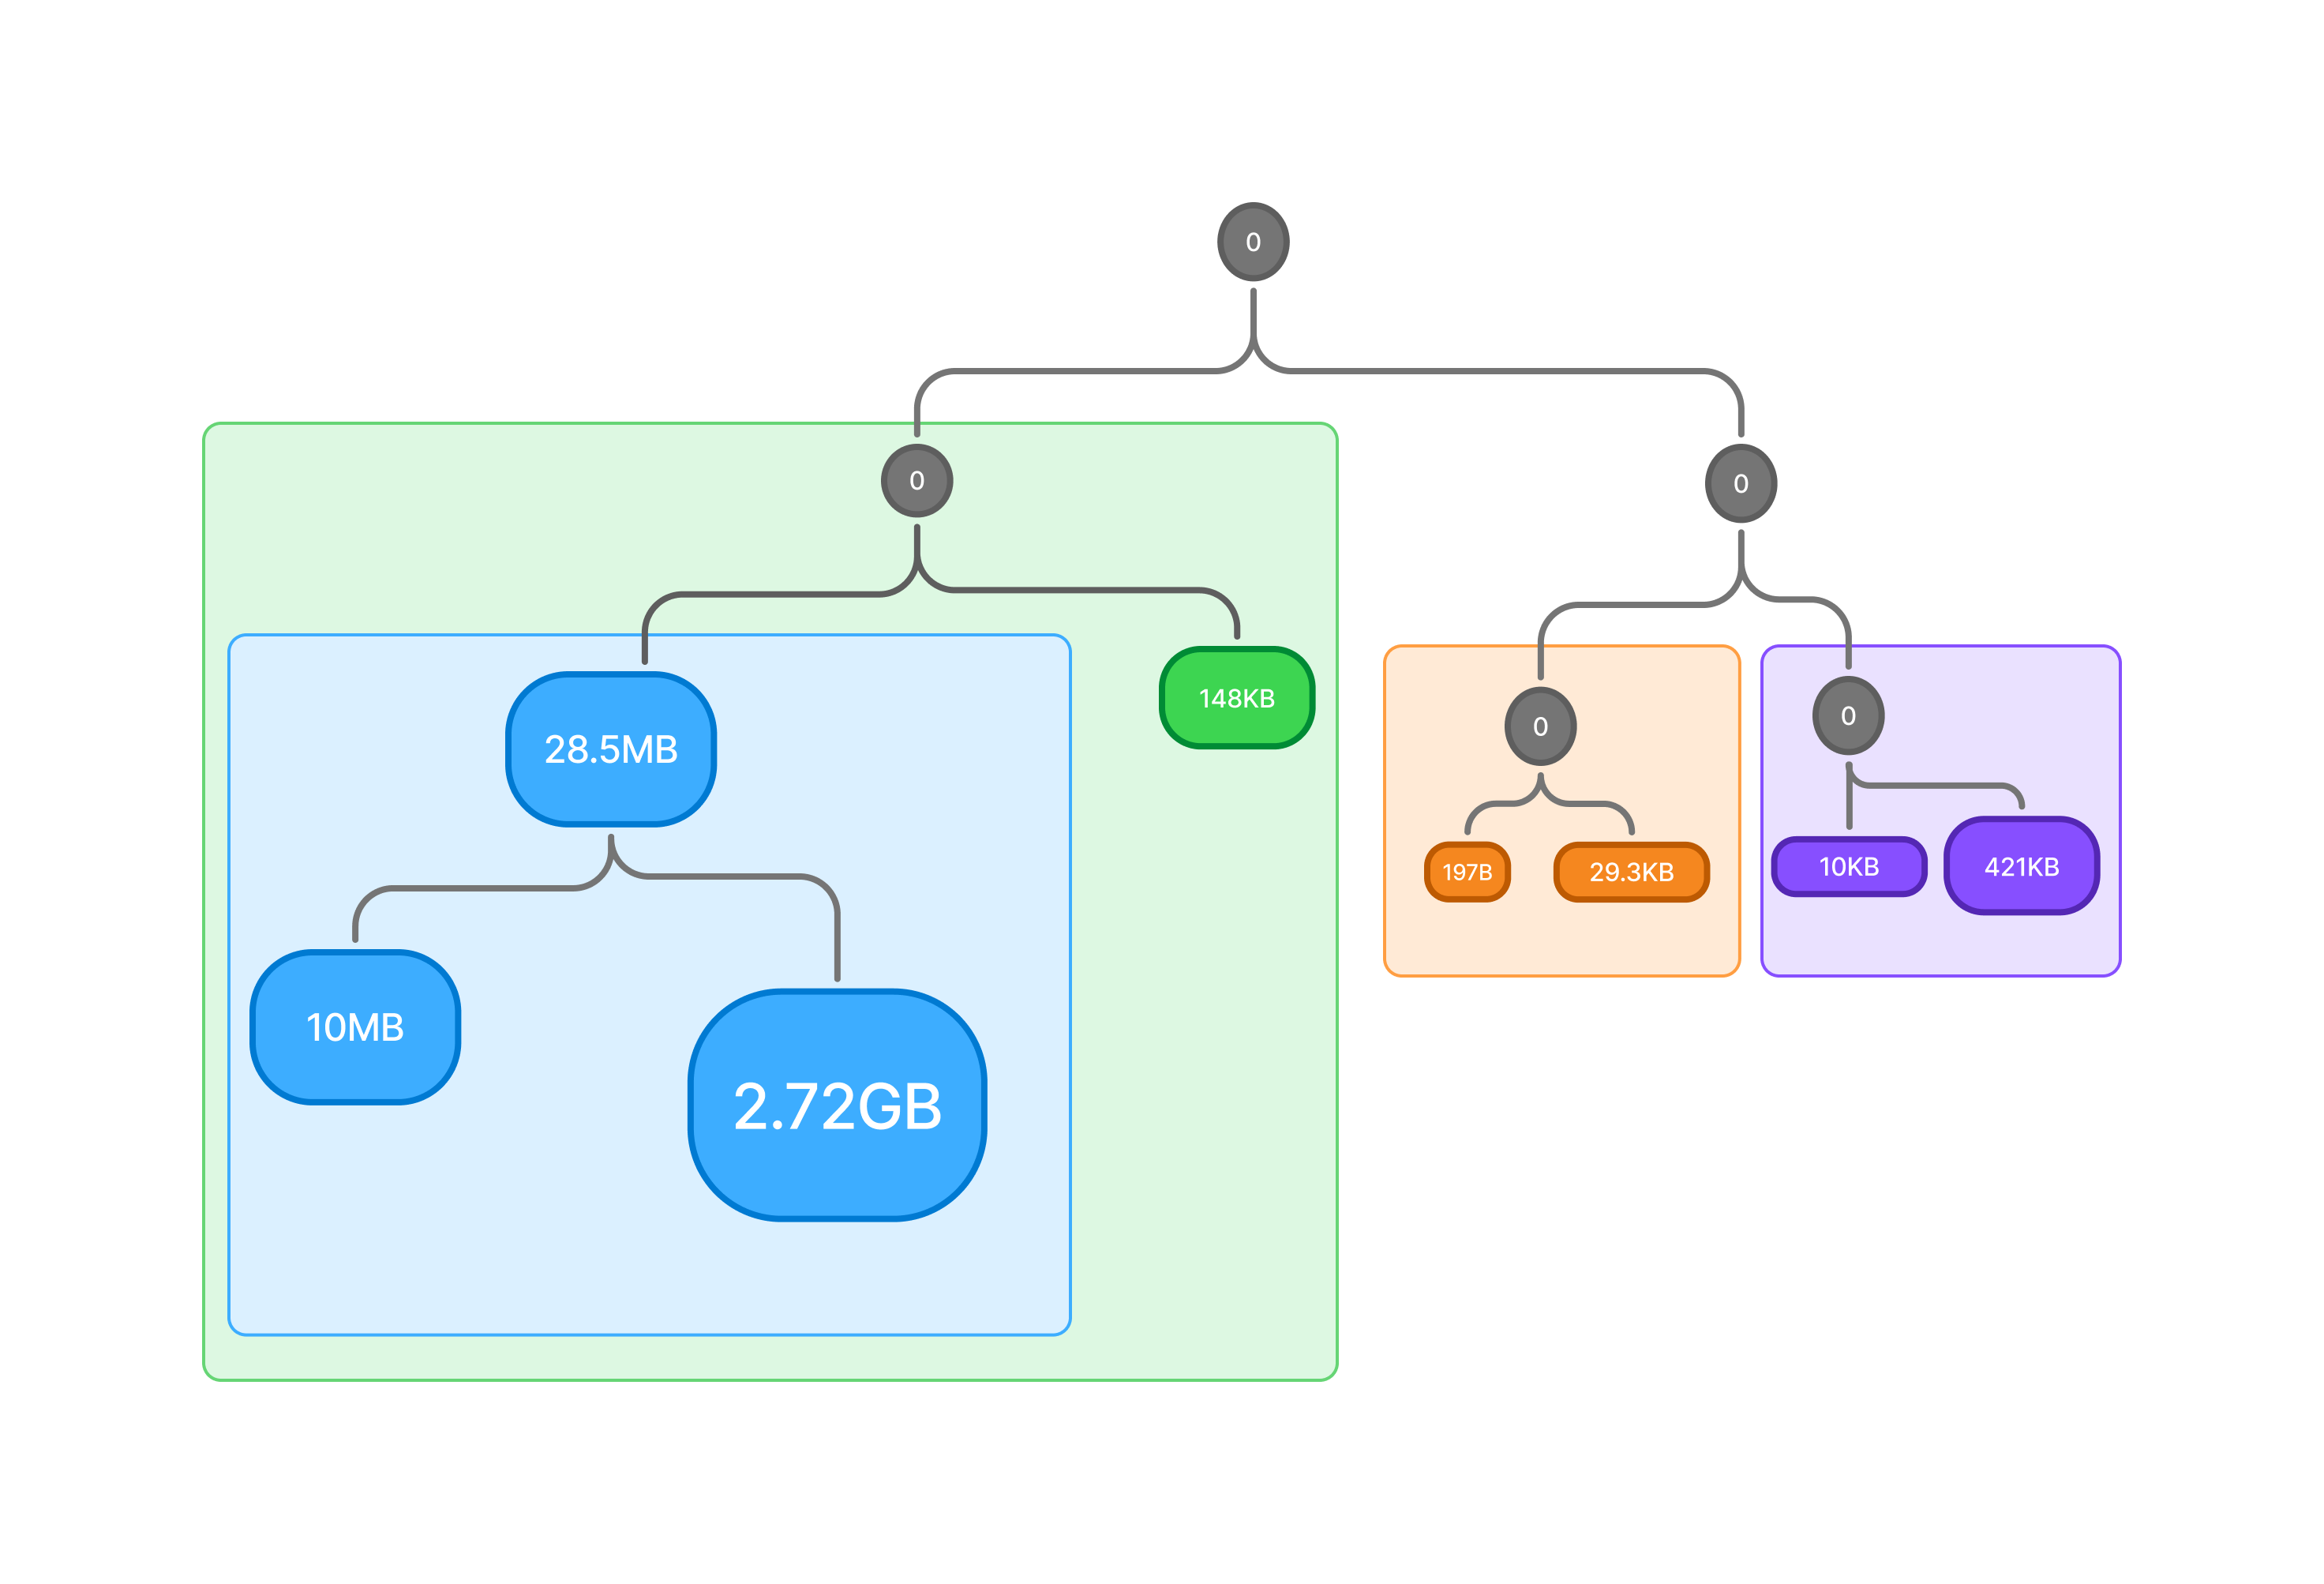
Notice how the two.72GB matter is in the identical retailer because the 10MB and 28.5MB subjects. This means
that if somebody desires to learn the 10MB matter, they need to filter out all these different
messages. Meanwhile, the smaller subjects are cut up between three shops, despite the fact that
they’re orders of magnitude smaller than the big subjects.
With the brand new adaptive splitting algorithm, that is how the identical tree seems to be:
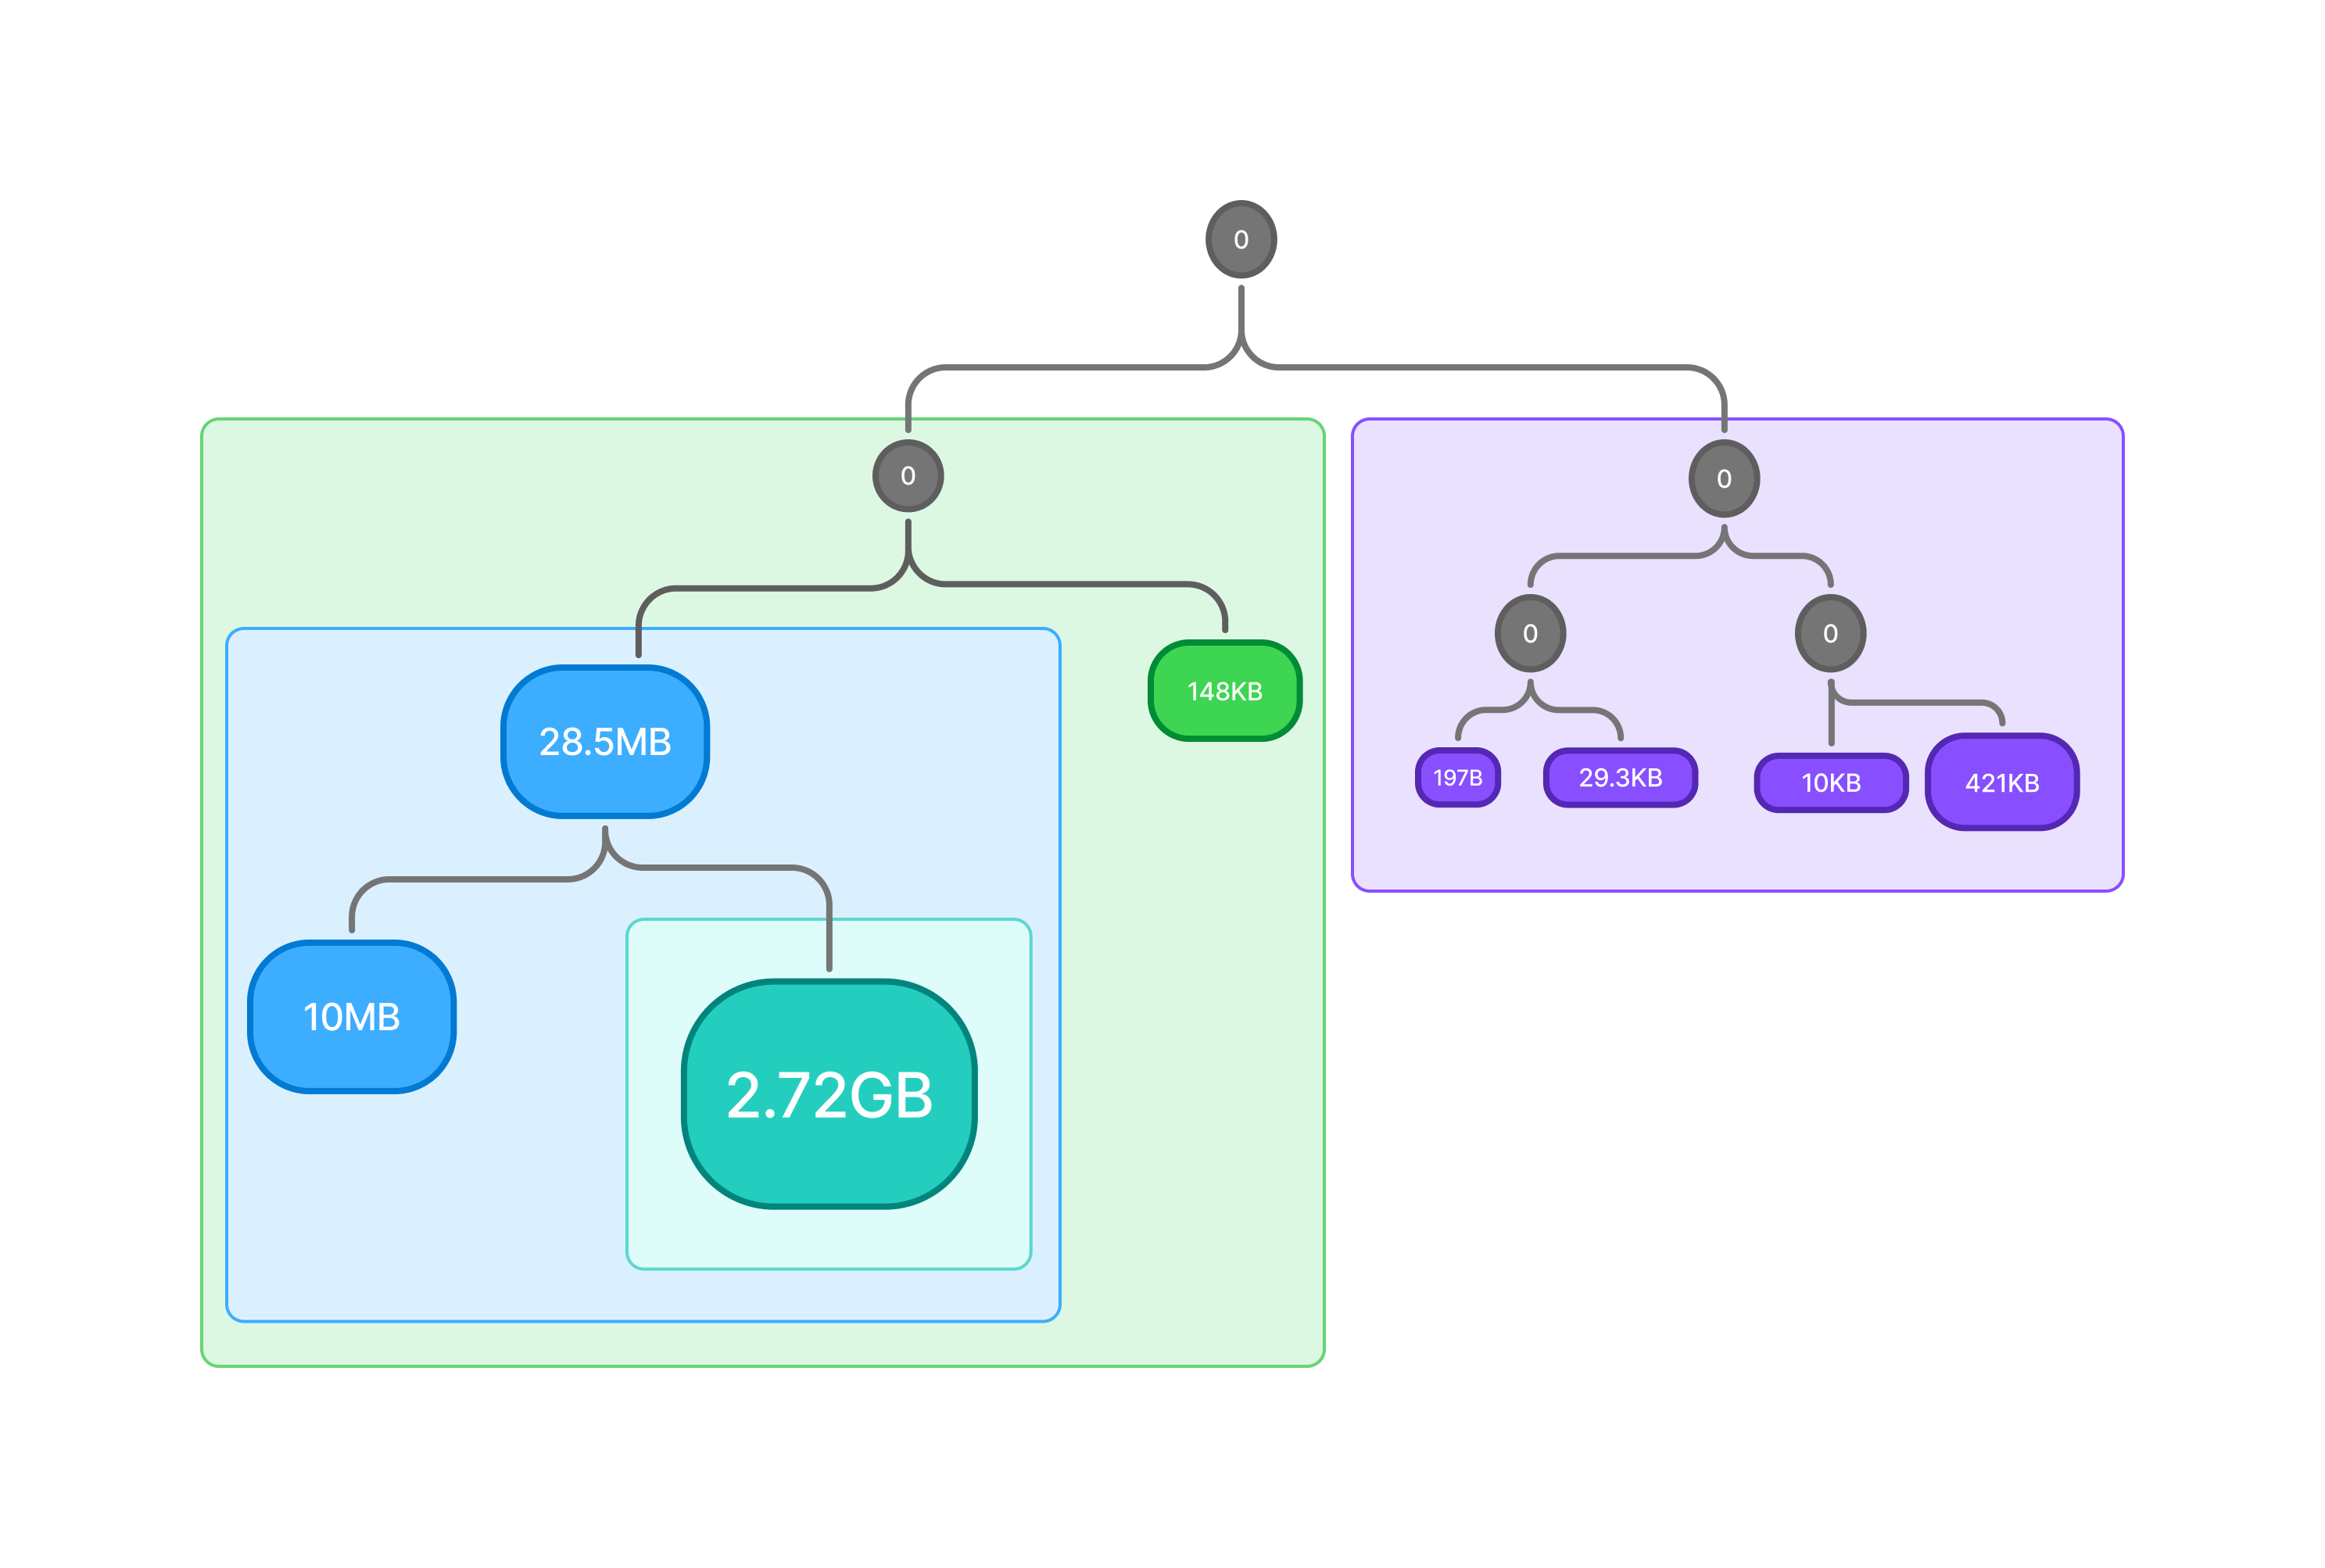
Now the two.72GB matter has its personal retailer separate from the 28.5MB and 10MB subjects, whereas the
smaller subjects are all bundled collectively right into a shared retailer.
Using a number of testing methods on the algorithm
Since the adaptive splitting immediately impacts how messages are saved in Aria, we wished
to make sure with a excessive diploma of certainty that there have been no bugs. Dropping or re-ordering
a message would have severe penalties.
We began by utilizing count on assessments to test numerous properties of the algorithm, akin to
giant subjects getting their very own retailer, small siblings sharing shops, and so forth.
For message consistency, we already had an current property-based check that inserted a
sequence of randomly generated messages on randomly chosen subjects after which ran the
splitting algorithm. The check learn out random items of the subject tree and confirmed that
the messages had the proper ordering and content material. Theodor expanded the check to randomize
the tree splitting, which confirmed that message content material stayed the identical no matter how
the subject tree was cut up.
Finally, we did a number of runs in Antithesis to substantiate that the modifications didn’t break
the rest in Aria.
How did the optimizations do?
The tip indexing code has been shipped to manufacturing. We’ve seen preliminary ends in
our staging surroundings that confirmed 30% much less CPU utilization in some real-world
eventualities. Overall latency throughout shoppers went down considerably throughout these
occasions. We’ve observed some multi-second tail latencies in servers that didn’t implement the
indexing, whereas these points didn’t seem in any servers working the brand new code.
Adaptive splitting is deployed to our staging surroundings and will probably be working in
manufacturing shortly.