Constructing a RAG Pipeline for Semantic Code Search: A Developer Diary and Area Notes
AI
Part 1: Parsing, chunking, and vectorization
Some time in the past, we got down to construct one of the best semantic code search platform we may: a RAG pipeline that provides LLM brokers exact, citable proof from actual repositories as an alternative of no matter grep occurs to floor. The eventual resolution was Air Context. We bought it working, we bought it into manufacturing, and we collected plenty of scar tissue alongside the way in which. In this sequence of posts, we’ll share the elements we want somebody had instructed us on day one.
Coding brokers are undoubtedly the largest know-how leap for software program growth of our decade. Agents and frontier fashions are proving their aptitude within the face of seemingly insurmountable code complexity to supply ostensibly dependable code.
However, as increasingly growth processes turn into agent-driven, the agent’s effectivity and the standard of the produced code turn into more and more vital. The query shouldn’t be a lot about whether or not an agent can full the duty, as given sufficient time and token assets, it certainly will, however slightly how a lot time, effort, and steering is required for it to generate production-grade outcomes. For large-scale code bases particularly, the agent would spend quite a lot of time looking for the related items of code related for the function it’s engaged on and pulling them into the context.
Why semantic search issues
Attempting to find the fitting code snippets, the agent will resort to conventional instruments for code search resembling key phrase search and grep. These instruments, nonetheless, are restricted in that they require the agent to know prematurely which actual textual content to seek for. For instance, an agent in search of the place session tokens get refreshed can not depend on the code helpfully containing the phrase “refresh”. To purpose by summary domains, the agent wants the power to seek for code by which means, often known as semantic search. This is the place retrieval-augmented era (RAG) comes into the image. If we will index the supply code in a approach that captures its semantics after which permit the agent to retrieve the related items on demand utilizing free textual content search, we create an interface that performs to the agent’s strengths.
From prototype to manufacturing
Like many nice concepts within the agentic period, a local, prototype implementation is very simple. A well-evaluated manufacturing grade resolution most actually shouldn’t be. In this sequence of weblog posts, we need to share what’s concerned in making an efficient RAG system, in addition to the fallacious turns we took in our journey to create our personal: Air Context. We’ll sort out every stage, from pre-processing to storage and agent integration, offering some extra technical context and recommendation.
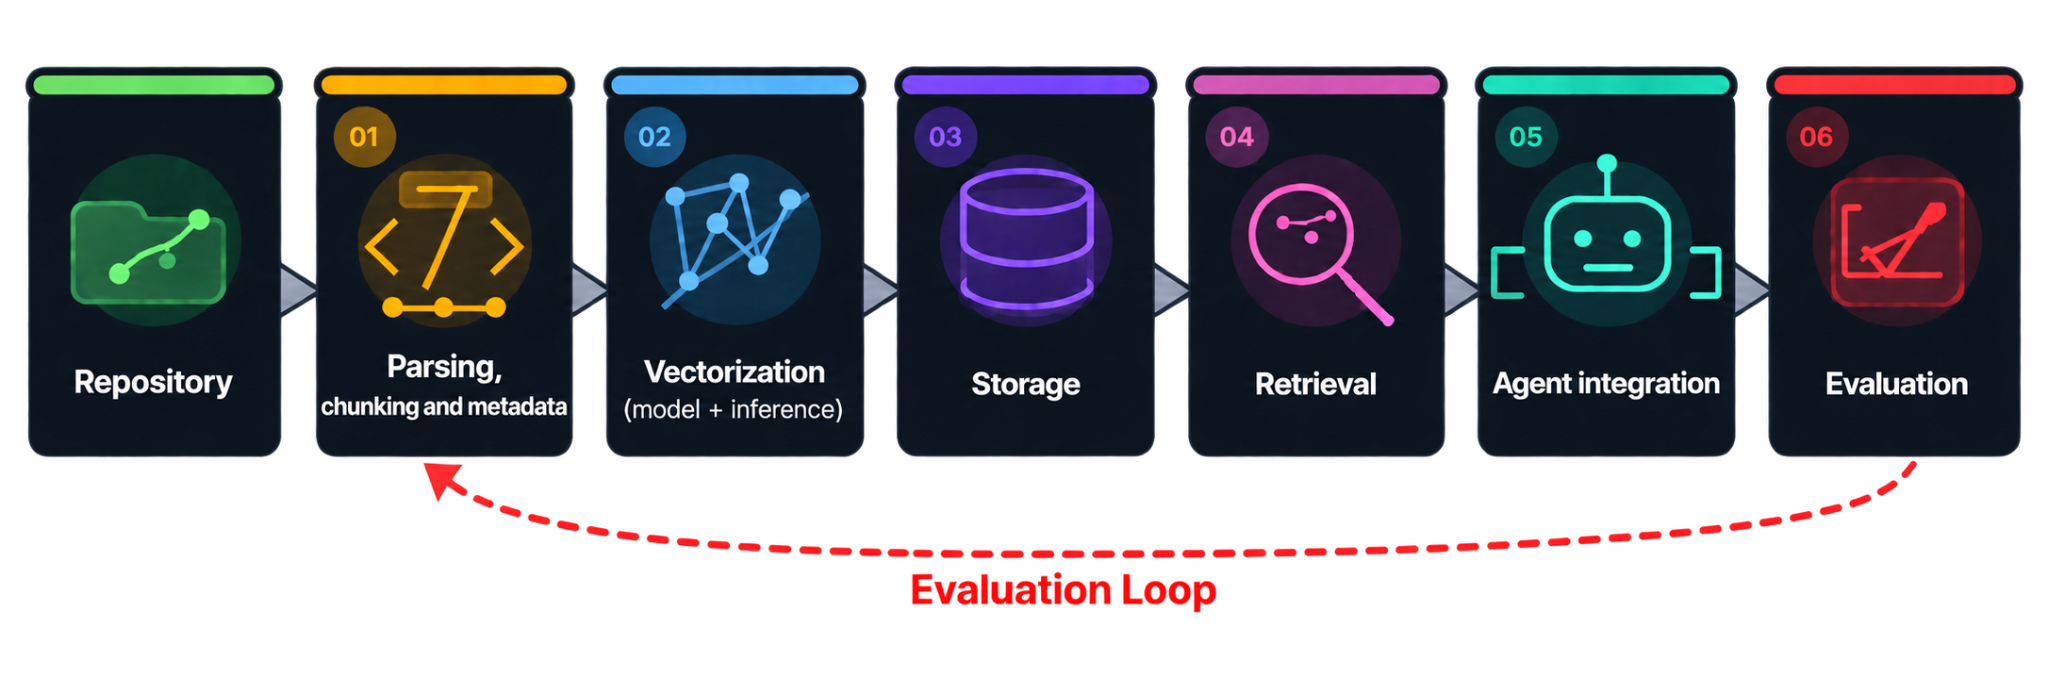
This first a part of the sequence will cowl the preliminary phases of the pipeline: parsing and chunking, the place uncooked supply information are divided into correctly scoped models, and vectorization, the place these models are reworked right into a illustration that helps semantic search.
The positive AST of parsing and chunking
Parsing and chunking is a vital pre-processing step in RAG resolution, however it’s usually missed. In order to permit the LLM to embed or in any other case index the supply code, we should first feed it the uncooked traces of code. This could sound trivial, and possibly could be for small-scale demo tasks. However, production-grade techniques include 1000’s of information, which, in flip, span tons of and even 1000’s of traces. If something, brokers have compounded the issue, as they are typically prolific writers, additional inflating the codebase. Each file could include multitudes of courses, fields, and strategies, with various levels of relatedness amongst them.
Finding the fitting chunk measurement
Even if it had been attainable to suit these enormous code information into an embedding mannequin of their entirety, that costly feat would in the end be self-defeating. Because your entire file was embedded in a single unit, the search would return your entire file. This is counterproductive to the targets of agentic code exploration and navigation, that are principally involved with discovering a selected perform, image, or code snippet.
On the opposite hand, if we had been to take the opposite excessive and granularly embed every separate line of code, we’d be dealing with an issue of a distinct kind. These particular person traces could be semantically insignificant with out the encompassing context. A generic perform identify or remark doesn’t benefit embedding and can produce the fallacious retrieval end result. In a way, we’d not have the ability to see the forest for the bushes, and the agent could be overloaded with a number of, usually insignificant micro-results.
It is due to this fact crucial to search out the fitting methodology to chunk or divide the code into teams which can be correctly scoped. Each group ought to embody sufficient of the mandatory context and signify widespread semantic which means.
Why fixed-size chunking falls brief
Chunking is a generic identify for the strategy of taking content material that can be fed to the agent and dividing it right into a set of chunks. A naive method to chunking may very well be merely splitting a big file into teams with a hard and fast variety of traces. However, if we had been to take that method, we’d discover the ensuing groupings semantically fallacious. Unrelated code items could be grouped collectively, for instance, an import assertion and a few perform content material, resulting in errors throughout retrieval.
To clear up the issue, we will leverage the truth that each supply file has a reasonably well-defined construction. Take Java for example – imports are typically on the prime of the file, adopted by a category definition with an non-compulsory doc-comment previous the header. The class will include fields and strategies, which in flip may additionally have their very own doc-comments. Knowing in regards to the conventions and guidelines that outline the category construction permits us to carry out smarter chunking and obtain the fitting stability of surrounding data.
Parsing and structure-aware chunking
Over the final 26 years, we at JetBrains have developed parsers which can be good sufficient to regulate for the varied quirks, irregularities, conventions, and nuances of particular languages. Alongside different instruments, these parsers type our inside JetBrains Code Engine platform on which Air Context is developed. At the second of this text’s composition, Air Context helps parsing and structure-aware chunking for 9 main languages: Kotlin, Java, Python, JavaScript, TypeScript, C#, PHP, Go, and Rust. For all different languages, our implementation merely falls again to naive, line-based splitting to make sure that any language or doc could be listed and searched.
The parser permits us to interrupt supply information into streams of syntax nodes that carry details about what they signify – feedback, whitespaces, lists of modifiers, and so forth. The chunking algorithm then consumes that stream and applies logic that decides the scope of a given chunk. Based on the node’s sort and measurement, in addition to its descendants, the algorithm comes to a decision. If a node exceeds the dimensions threshold however has no kids, it is going to fall again to extra primitive splitting methods.
Some language-specific constructs are saved as single slices even when they exceed the popular measurement. Prefixes resembling documentation, annotations, visibility modifiers, and key phrases are saved along with the declaration; suffixes (often closing syntax) stay related to the assemble they shut. There can also be some language-specific cleansing, the place, as an example, widespread and semantically meaningless Java annotations resembling @NotNull or @Override are eliminated.
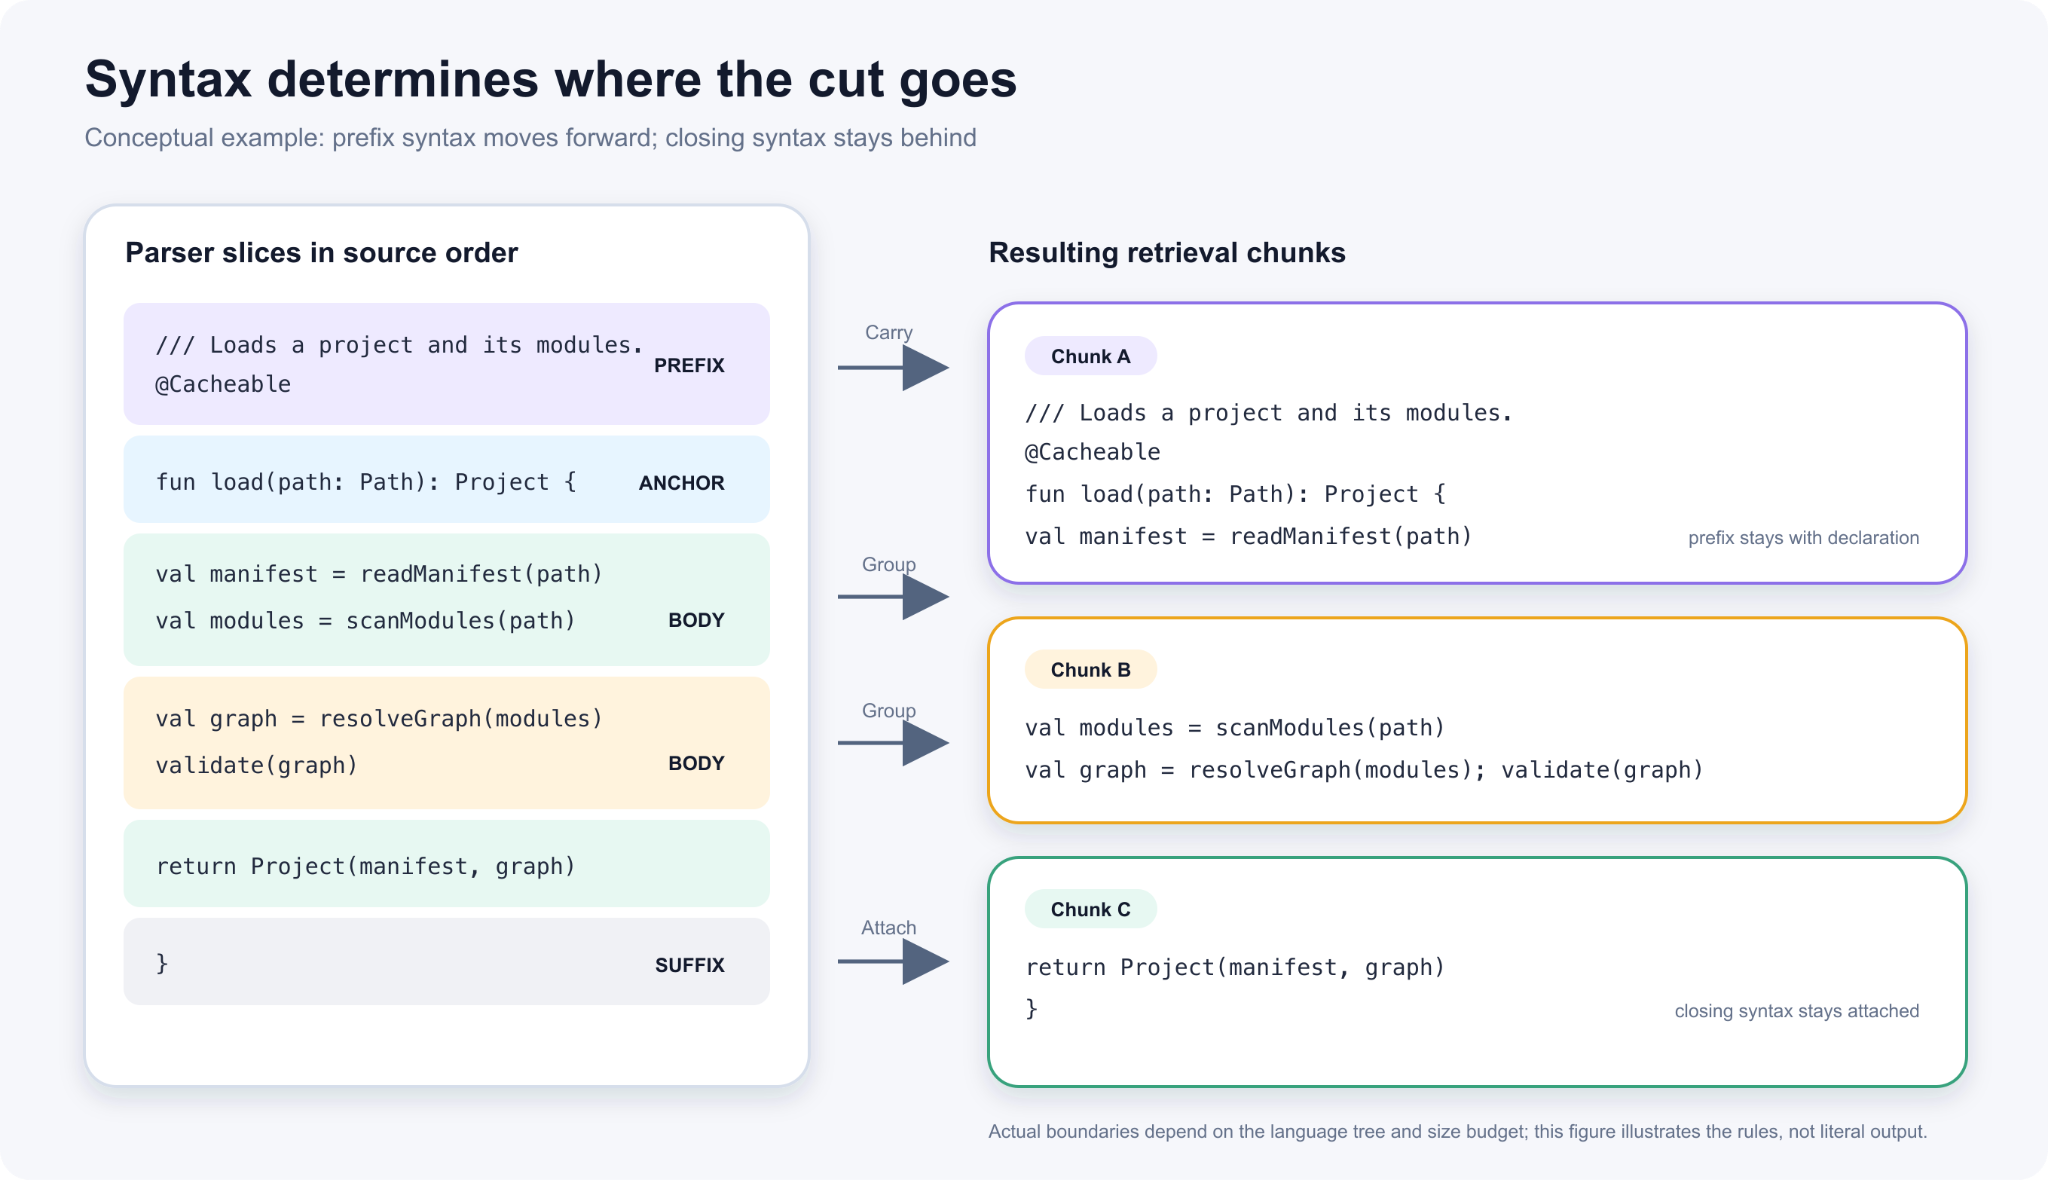
The algorithm bears some similarities to cAST, authored by Zhang et al. in 2025. Both our implementation and cAST retain the biggest syntax models that match, subdividing solely the models which can be too massive, and grouping smaller adjoining models to keep away from tiny chunks that aren’t often semantically significant. The largest distinction is that we coded extra language semantics into our implementation, holding Python decorators along with definitions, KDocs subsequent to Kotlin declarations, and so forth.
After grouping, chunk normalization is carried out, which includes:
- Trimming main and trailing whitespaces
- Deleting clean traces
- Removing widespread indentation whereas preserving relative indentation
Following the normalization process, the chunk is then handed to the subsequent step – embedding – together with metadata that consists of a relative path, which will get embedded alongside the normalized chunk content material.
Evaluating the standard of chunks
It is tough to provide a concrete reply as to what the enter to the embedding mannequin ought to appear like. Chunk measurement issues, however as mentioned earlier than, larger shouldn’t be all the time higher. Additionally, some metadata embedded alongside the code could also be helpful, whereas some could introduce noise that in the end decreases search high quality.
We opted to make use of an LLM-as-a-judge technique to examine the chunks as part of the analysis. The decide, utilizing a bit and the supply file, considers whether or not the boundary is sensible. It appears to be like for sudden artifacts, resembling indifferent documentation, orphaned closing syntax, or fragments of code which can be lower by a significant assemble. In addition, any adjustments to the supply code processing pipelines additionally undergo the complete, end-to-end retrieval analysis. We’ll get again to that analysis pipeline within the following a part of this sequence.
Vectorization
Having pre-processed the supply code, we lastly have textual content chunks which can be hopefully simply the fitting measurement and appropriately grouped for semantic retrieval. Our subsequent activity is to rework these fragments in a approach that can later permit us to assist semantic search, by a course of known as vectorization.
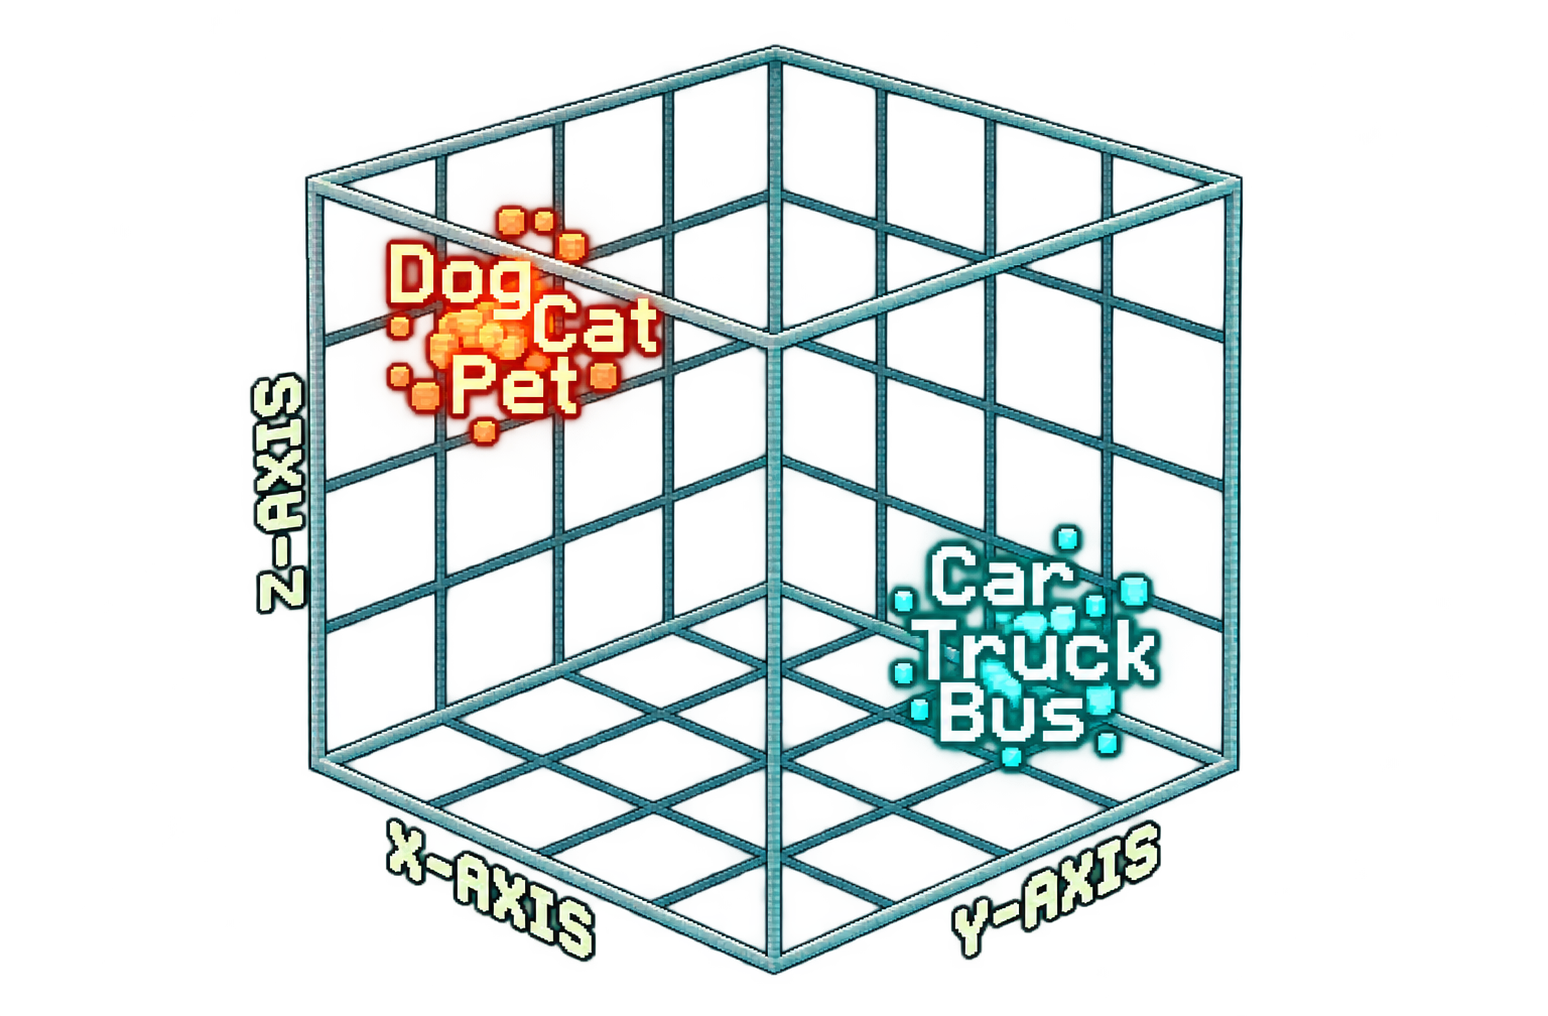
With vectorization, an embedding mannequin reads a chunk of textual content and emits a fixed-length record of numbers (a vector), which quantities to some extent in an area of some thousand dimensions. Significantly, the mannequin is educated in order that texts with comparable which means land shut collectively. Traditional search would possibly miss the connection, however right here, a perform that flushes buffered write operations and one which drains a pending queue can find yourself close to one another regardless of sharing no widespread key phrases. The distance between vectors therefore turns into a measure of relatedness. A question is became a place in the identical area, and the outcomes are no matter lies nearest to it.
Punch for the byte: Optimizing for storage
Any try and vectorize a big codebase should take note of each price and efficiency. A single embedding is reasonable, however a big repository produces tens of millions of chunks, which turn into tens of millions of vectors that have to be saved, held in reminiscence, and in contrast towards every incoming question. A vector of some thousand dimensions in 32-bit floats weighs round 16 kilobytes, so a number of million chunks add as much as tens of gigabytes of index earlier than any bookkeeping. At such a scale, the allocation of bytes per vector turns into cost-limited, and the main query shortly shifts from “how correct can we be?” to “what will we get per byte?” In different phrases, we have to discover a approach to scale back the price whereas retaining as a lot search high quality as attainable.
There are two methods to scale back vector price. The first is to maintain fewer dimensions. Modern embedding fashions are educated so {that a} main slice of the vector works by itself. The dimension loss is utilized throughout a number of nested prefix lengths concurrently, pushing the coarsest construction into the earliest dimensions. This means you may lower a vector brief and renormalize it, and it nonetheless retrieves. Alternatively, you may preserve each dimension and spend much less on every one by sacrificing on precision and thus holding fewer bytes for every vector.
These two choices are impartial of one another and could be mixed, which suggests any storage finances could be met by totally different mixes of dimension depend and numeric precision. The actual query is which combine retrieves finest for a similar variety of bytes. The trade-off is way from even. Suppose the finances is 512 bytes per vector. You may spend it on 128 dimensions saved at full 32-bit precision, or on all 4,096 dimensions saved at a single bit every. Both match the finances precisely, however in testing, you’ll discover that the second possibility retrieves significantly higher.
Why dimensions matter greater than precision
To see why, it helps to consider every dimension as one small query the mannequin has realized to ask in regards to the textual content: Is this about error dealing with? Does it contact the community? Is it check code? And there are a number of thousand comparable matters and questions that haven’t been named. (The actual dimensions are blurrier than that, however it is a helpful abstraction.)
No single reply means a lot by itself. We take into account two chunks to be comparable when their solutions to many of those questions are the identical. Therefore, we must always assess the vectors by wanting on the protection of the questions slightly than the exactness of the solutions.
Keeping all 4,096 dimensions at one bit preserves a tough yes-or-no reply to each query. Truncating to 128 dimensions retains very exact solutions to a few p.c of the questions and throws the remainder away, and no quantity of precision on the surviving dimensions can get better the data the discarded ones carried. In a way, an extended questionnaire crammed in with checkmarks beats a brief one crammed in to 6 decimal locations. Dimensions are what you need to preserve; precision is what you may afford to lose and is simpler to compensate for afterward.
So we selected to maintain each dimension and take the precision discount to its restrict, dropping the vectors to 1 bit every, which is 32 instances smaller than the identical vector in 32-bit floats. The quantization itself seems to be surprisingly easy. Every part at or above zero turns into a one, whereas each unfavourable part turns into a zero, and the magnitudes are thrown away:

Changing the illustration adjustments the metric with it. Cosine similarity wants the magnitudes we simply threw away, so binary vectors are in contrast by Hamming distance as an alternative, which is just the variety of positions the place two bit patterns disagree. Compare, for instance, 10110100 and 10010110. They differ in two positions, so the space between them is 2. At full size, the computation stays simply as easy. A 4,096-bit vector is saved as 64 phrases of 64 bits, and evaluating two of them means XORing every pair of phrases, which leaves a 1 wherever the 2 vectors disagree, after which counting the 1s. A CPU does every of these in a single instruction per phrase, so a full comparability prices within the order of 100 directions the place cosine similarity on the unique floats wanted 1000’s of multiplications.
Note that the metric was by no means a separate choice. We selected one-bit precision for the storage financial savings, and as soon as each part is an indication bit, Hamming is the one comparability left that is sensible. Choosing the precision selected the metric.
Binary quantization nonetheless prices a number of factors of recall towards the unquantized vector. We accepted that price after contemplating {that a} reasoning agent could be consuming the outcomes. A code search feeding an agent wants the fitting neighborhood way over a wonderfully ordered prime 10. When the agent asks the place session tokens get refreshed, what issues is that the related handful of information reveals up among the many first dozen outcomes. Whether one of the best chunk ranks second or fifth adjustments nothing, as a result of the agent opens the candidates and reads them anyway. In that loop, a rating degradation that may be plainly seen in a three-result UI constructed for people is usually invisible.
The limits of binary quantization
The trade-off we made had a subtler price that took us a bit longer to know. Binary quantization doesn’t solely sacrifice accuracy; it compresses the *vary* of similarity scores. With full-precision vectors, an unrelated pair can rating close to zero whereas near-duplicates rating close to one, a comfortably huge unfold. Sign bits behave in a different way. Around half the bits of two completely unrelated vectors nonetheless agree by pure likelihood, whereas a strongly associated pair may need settlement for two-thirds. So each rating within the index, related or not, lands in that skinny band.
Ranking survives the compression, since related outcomes nonetheless rating above irrelevant ones, however thresholding doesn’t. Picture a function that volunteers associated code with out being requested, say a panel that implies present implementations when you sort. Its most troublesome requirement is figuring out when to remain silent. To make that dedication, it wants a usable hole between “associated” and “unrelated” scores. Binary vectors don’t depart one. Any cutoff positioned inside that slender band both fires on all the things or on nothing. So the place an index wants an absolute relevance judgement slightly than a relative ordering, we preserve 16-bit floats and pay for the storage.
Embedding scope
While indexing and looking use the identical mannequin, the 2 jobs couldn’t be extra totally different. Indexing is throughput-constrained, with tens of millions of chunks asynchronously dealt with. The GPU will deal with about 32 chunks per batch earlier than changing into saturated. A search, then again, must be quick and responsive. Users will surrender if they aren’t supplied with outcomes inside a few seconds at most. Therefore in deploying these fashions we optimize them accordingly: one to maximise chunks per second, the opposite for minimizing time to first end result.
We selected an instruction-following mannequin, educated with a deliberate asymmetry between the 2 sides of retrieval. Significantly, the 2 sides are represented by very several types of textual content. A question is a brief query in pure language, whereas a doc is a bit of code. A doc is embedded as is at indexing time. A question is wrapped with an instruction describing the retrieval activity, one thing like “given this search question, discover the code that solutions it”, which tells the mannequin what position the textual content is enjoying. We protect that association at inference as a result of it’s the form the mannequin realized.
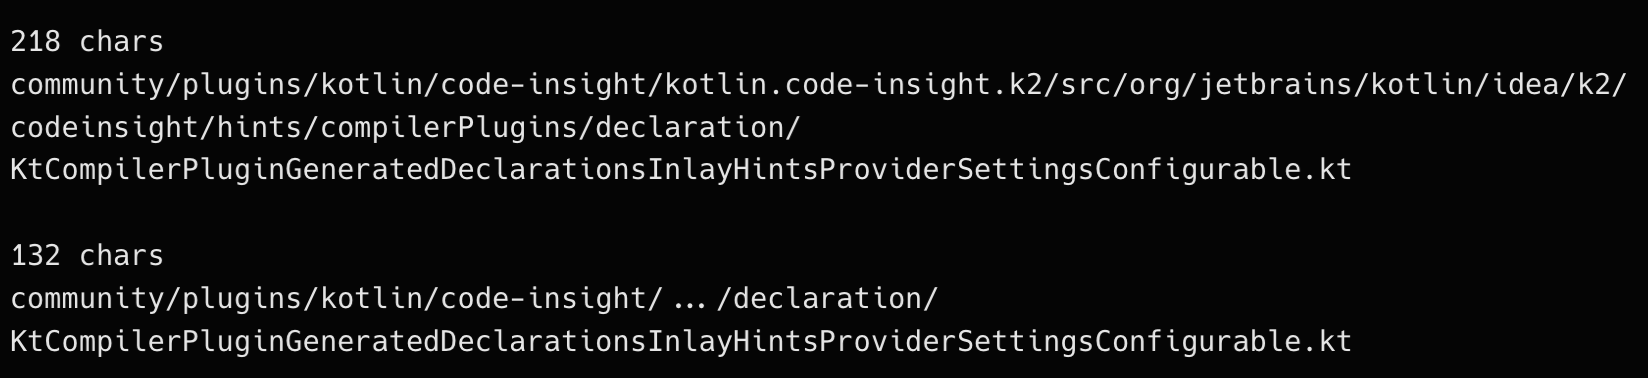
To permit the 2 sides to align extra simply, we embed every chunk along with its file path. The path provides metadata that the chunk alone lacks: which module it lives in, and what the file is. In a monorepo, although, the trail itself turns into an issue. The IntelliJ IDEA monorepo runs to over 1,000,000 information. The median supply file there sits 9 directories deep behind a 91-character path, and near 10,000 supply information have paths longer than 150 characters, the longest of them 218. That is earlier than any checkout root is prepended.
Most of these characters are used for structural nesting and provide no helpful details about the file. A run of segments like `src/org/jetbrains/kotlin/thought/k2` restates the package deal hierarchy, which a compiler wants and a search doesn’t. Meanwhile, the file on the finish of that longest path is 24 traces lengthy. If we merely embed the trail textual content as is beside a bit, we’ll discover that the trail will typically take up extra space than the code itself. To compensate for that, a path is capped earlier than it reaches the mannequin, and the rule is that *each ends survive*. The main segments inform you which module you’re in, whereas the final two, the instant dad or mum and the filename, inform you what the file is. The center is the half that may go, and solely as a lot of it because the cap requires. Keep the longest prefix that also suits, elide what falls between into `…`, and if even parent-plus-filename is just too lengthy, preserve solely the identify itself.
The similar self-discipline applies when a consumer scopes a search to a subdirectory. The apparent implementation is a metadata filter: run the search as traditional and discard outcomes that fall exterior the listing. We do one thing totally different. The scope is rendered into the question textual content itself, in the identical form, with the identical abbreviation perform and the identical separator the listed chunks used. If a bit went into the index beneath the abbreviated type of `group/plugins/kotlin`, a question scoped to that listing carries the identical string in precisely the identical type, so the question vector lands in the identical area because the chunks it’s imagined to match.
Protecting supply code
There was one final design consideration we took under consideration. It was vital for us to be attentive to buyer privateness and safety considerations. The supply code of an organization is usually the core of its IP. Exposing it to third-party cloud fashions, and even to a different firm, will increase the danger of inadvertently exposing delicate knowledge and even coaching different fashions to make use of it.
To be sure we tackle these considerations, we made the choice to stick to a number of practices early on:
- Avoid storing the code in our techniques: A piece holds a cluster reference, an merchandise sort, a file path, begin and finish offsets, a reference to a vector, and an non-compulsory metadata subject. No content material, no copy of the supply code itself, is saved. What a search returns is coordinates, and the snippet you see is assembled in your machine, out of your checkout, utilizing them. The server simply is aware of that one thing related lives at bytes 4,102–4,890 of a given path, not what it’s.
- Don’t use knowledge for coaching: Every code index Air Context builds is embedded by an open-weight embedding mannequin, operating on GPUs we function. No embedding request leaves our utilities – to not OpenAI, to not Google, to not another vendor. Therefore, we will assure that not one of the knowledge can be used to coach something.
These self-imposed design restrictions carry no price when it comes to retrieval high quality. We evaluated the open-weight candidates towards the hosted embedding APIs from the key suppliers on our personal code-retrieval benchmarks, and ours got here out on prime. Open-weight embedders are actually adequate that the fascinating engineering has moved into what you feed them, the way you serve them, and what you select to maintain.
A abstract that’s an interlude
In this weblog publish, we coated the primary phases of the retrieval pipeline: the journey from uncooked supply information to compact vectors which can be able to be searched.
At this level, we have now tens of millions of binary vectors and a approach to produce extra. The issues we haven’t solved but are how one can retailer them effectively, how one can create a system that may reply a question in milliseconds, how we will constantly consider our outcomes to make sure we’re making the fitting selections, and the way we will get the agent to really use our shiny RAG equipment.
These matters and extra would be the topics of the subsequent elements on this sequence, which we’ll be releasing over the subsequent few weeks. As all the time, please be at liberty to ask any questions within the feedback or share your individual arduous classes from designing a RAG resolution. We are desperate to be taught of various and artistic methods you’ve discovered to be efficient! In the meantime, be at liberty to take a look at Air Context, presently in public preview, it’s already included together with your JetBrains license 😀
Until subsequent time!