The AI Race Simply Received Awkward
If you learn the information headlines as of late, you’d be forgiven for pondering that the Western labs are getting spawn-camped by Chinese labs en masse.
The Distillation Drama
Not every week goes by when Anthropic doesn’t launch one other article on how the Chinese are distilling their models, becoming a danger to humanity itself, and many others.
It’s useful for them to say that as a result of it units the bottom for these fashions to be restrained legally and regulatorily later on.
But it’s clear that the times of senseless distilling are over.
Not simply over. The new sport on the town is adopting Chinese labs’ advances. Note how I name this adoption as a substitute of the extra vitriol-infused “stealing” that Anthropic tends to make use of.
That’s as a result of, in contrast to the Western firms, the Chinese are just about making a gift of their recipes.
A Different Game
The newest one shamelessly copied with out acknowledgement is the breakthrough in KV cache optimizations that DeepSeek has generously shared with the global community.
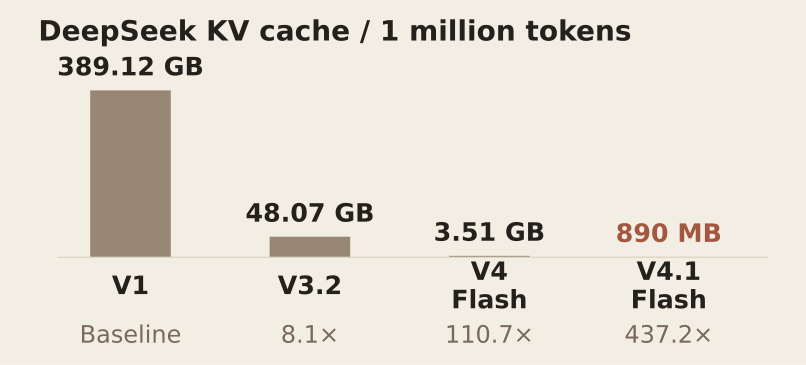
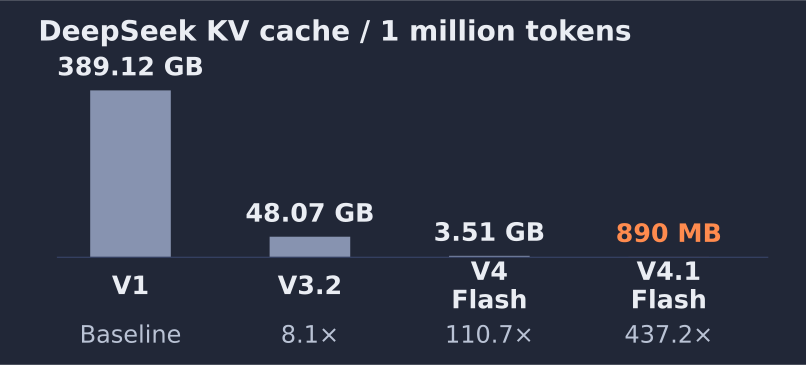
It is a mind-blowing optimization that principally dropped the KV cache footprint for sure use circumstances that use an extended session context, like coding, by an element of roughly 437x in contrast with DeepSeek-V1.
They have been the primary ones to launch the MLA structure, which compressed the cache by roughly 15x, after which adopted it up with ‘Compressed Sparse Attention’ and ‘Heavily Compressed Attention.’ The newest DeepSeek-V4.1-Flash pushes it even additional with CSA2, cross-layer cache reuse, a causal encoder-decoder structure, and FP4 caching, bringing the worldwide KV cache all the way down to 890 bytes per token.
Why do this stuff matter? Because for serving long-context fashions, one of many largest prices is the VRAM wanted to carry this cache in GPU reminiscence.
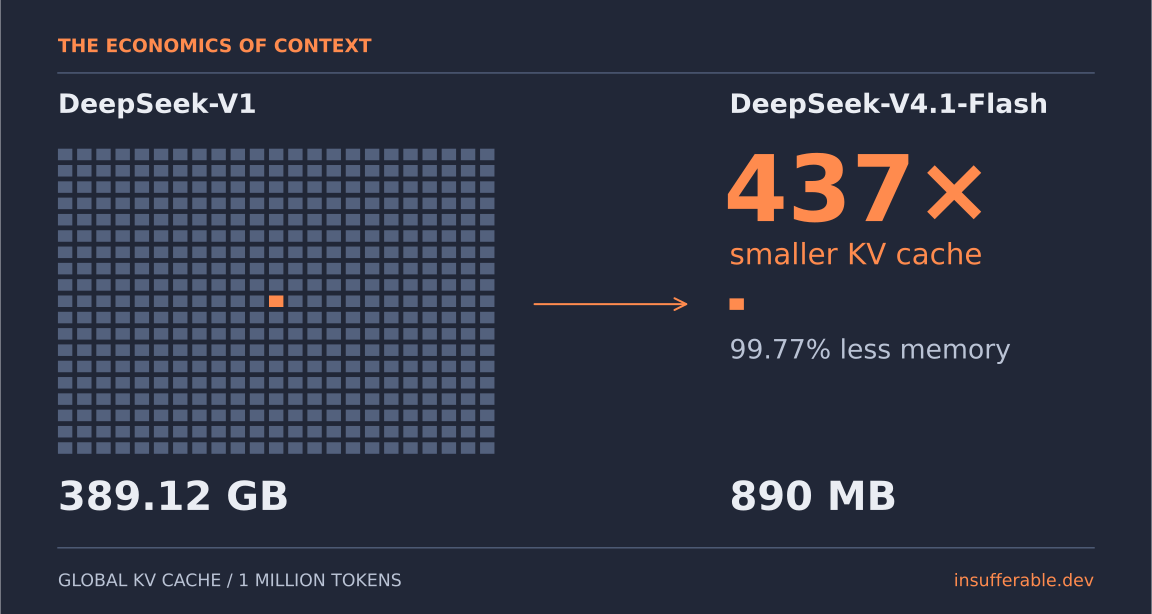
Below is the graph exhibiting simply how loopy this complete factor is:
Follow the Cache Money
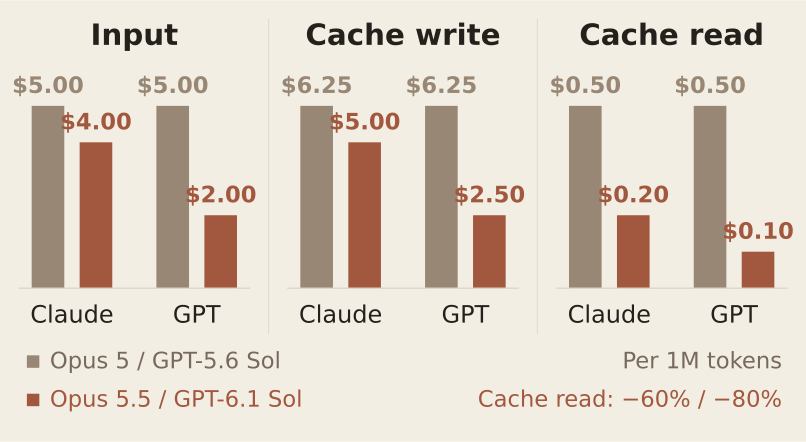
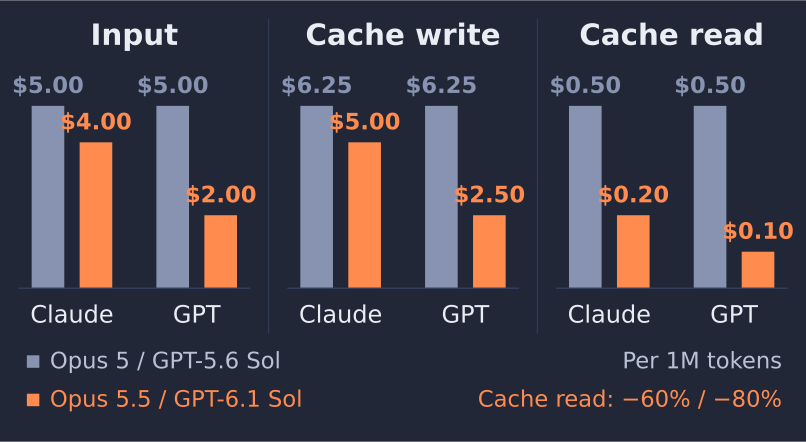
Compare that with what the identical tier value roughly two months in the past. All costs beneath are per 1 million tokens:
A Very Quiet Thank-You
All this should imply the Western AI firms at the moment are extraordinarily inference-margin optimistic.
The constraints on entry to superior GPUs pressured Chinese labs to make efficiency optimization a primary purpose, and it reveals within the outcomes.
Now I don’t know why they might freely give away such a breakthrough, however they only did, and for as soon as each Anthropic and OpenAI launched fashions which can be principally top-tier and are utilizing these optimizations.
They do appear to be just a little embarrassed by the copying. Hence the silent releases with out a lot pre-announcement for each Claude Opus 5.5 and GPT-6.1 Sol.
The person opinions have been stellar w.r.t. utilization, and the standard doesn’t appear to be that far off in comparison with their flagship fashions (Claude Fable 5.1 and GPT-6 Astra).
The cache learn prices are the proof of the adoption. They dropped sharply: Opus 5.5 lower cache-read pricing by 60% versus Opus 5, whereas GPT-6.1 Sol lower it by 80% versus GPT-5.6 Sol’s late-July pricing.
So the Chinese labs have thrown a lifeline to the Western loss-making labs, and I simply don’t have any clue as to why.