Going On A Tangent With The Intel 8087’s Hybrid CORDIC Algorithm
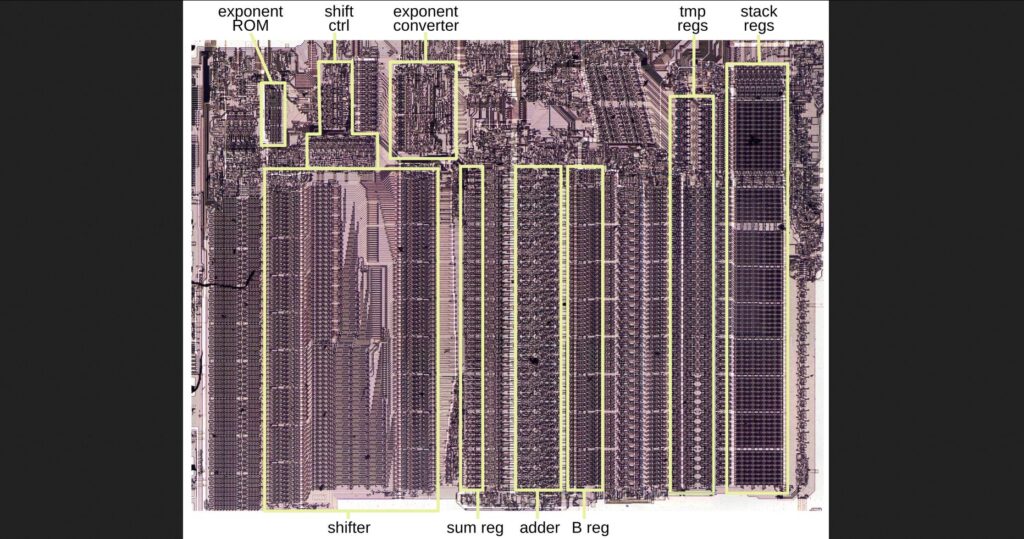
Continuing their reverse-engineering of Intel’s 8087 FPU, [Ken Shirriff] and associates took a look at one of the trigonometric functions, particularly FPTAN. The most fun half with such reverse-engineering might be determining which algorithm was used within the implementation, whereas attempting to find out the reasoning behind the ultimate {hardware} design.
If you’re working a easy MCU or MPU just like the 6502 or Z80 with out {hardware} features you’d seemingly use an algorithm equivalent to CORDIC or comparable, as this requires solely primary {hardware} options like addition, subtraction, bitshift, and look-up tables. One may use polynomial approximation if there’s {hardware} help for a possible speed-up, or as is the case within the 8087, create a hybrid method that targets pace and accuracy.
In the article the precise implementation to get to 64 bits of accuracy is detailed, beginning with the 16 bits calculated utilizing CORDIC earlier than switching to the Padé approximant method involving the ratio of two polynomials. Since after calculating the brunt of the ultimate worth with CORDIC the rest is a reasonably small worth this polynomial approximation not simply very correct but in addition quick.
This method permits the FPTAN and comparable trigonometric features on this FPU to hit a really excessive degree of accuracy and never require the look-up desk sizes and extra time required to work by the remaining bits with CORDIC. For those that need to see the total algorithm Intel’s engineers used, [Ken] has the total microcode itemizing with feedback within the article as properly.
As for the precise speed-up from this method, [Ken] calculates for one worth that FPTAN would spend 33% on CORDIC pseudo-division, 47% on CORDIC pseudo-multiplication and a mere 15% on the polynomial approximation together with about 5% overhead.
With the Pentium collection of CPUs Intel moved utterly away from CORDIC, because it’s clear that as correct as it might be, it’s arduous to scale to a major variety of bits with out incurring important time penalties. With the introduction of SIMD directions the x87 ISA has additional seen its performance lowered, however this evaluation exhibits as soon as once more why the 8087 made such an influence when it was launched.