Understanding the Affect of LLM Watermarking on AI Agent Behavior

Recently, Anthropic announced that future Claude models would embed an invisible watermark of their output [1], [2], and subsequently disclosed that the watermark relies on Google DeepMind’s SynthID-Text [2], [3]. Text watermarking itself isn’t new, however its deployment now has regulatory relevance. Article 50(2) of the EU AI Act [4] requires suppliers of AI techniques producing artificial textual content to mark their outputs in a machine-readable format and make them detectable as artificially generated or manipulated, utilizing technical options which might be efficient, interoperable, sturdy, and dependable so far as technically possible.
Watermarking is designed for provenance, however SynthID-Text modifications the method by which the mannequin generates every subsequent token. At the mannequin degree, this could change security habits, together with whether or not the mannequin refuses a dangerous request and whether or not that refusal holds underneath immediate injection. At the agent degree, the identical sampled tokens can decide which software is known as and what arguments are handed to it. Prompt injection connects these two settings as a result of a weakened refusal turns into extra consequential when the mannequin also can act by means of instruments. Such a watermarking process can subsequently have an effect on each what the mannequin says and what an agent does. We name this behavioral impact sampling drift.
Whether this drift seems in observe is an empirical query. We discover that it does, in each mannequin refusal habits and agent software calling. The impact is model- and key-dependent and could be obscured by combination scores when modifications in reverse instructions cancel. We subsequently report each internet efficiency and paired disagreement between watermarked and unwatermarked runs. Further, the closing part discusses what it means for AI security and safety and what builders ought to do about it.
Built for Content Provenance, Deployed Inside Agents
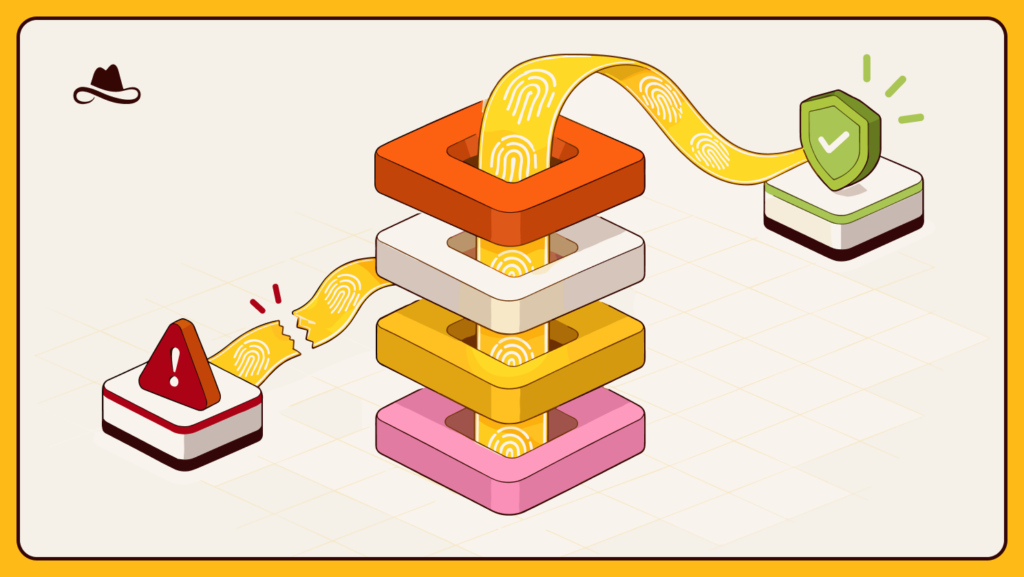
A textual content watermark embeds a sign that permits output to be recognized as AI-generated. Existing approaches embrace post-processing strategies and strategies built-in straight into LLM technology [8]. Generation-time approaches embrace logits-biasing strategies [5], distortion-free keyed sampling [6], cryptographically motivated constructions [7], and SynthID-Text’s Tournament sampling [3]. Figure 1 contrasts this course of with peculiar sampling. We use SynthID’s non-distortionary configuration, which preserves the unique token distribution in expectation over the watermark randomness whereas particular person generations underneath a set key can nonetheless differ [3]. Dathathri et al. report no measurable high quality degradation throughout practically twenty million Gemini responses [3].
Anthropic’s deployment additionally illustrates why this issues past first-party chat interfaces. The firm states that watermarking is utilized on the mannequin degree and covers supported fashions accessed by means of the Claude Platform API in addition to cloud suppliers [1]. A developer utilizing a watermarked mannequin because the reasoning element of an agent can subsequently obtain watermarked outputs even when the agent itself is a separate utility. This makes model-level behavioral results of watermarking related to the brokers constructed round such fashions.
Same Tokens the Watermark Biases, Same Tokens the Agent Acts On
Tournament sampling has extra alternative to change token choice the place the mannequin is unsure. In structured output comparable to JSON, braces, keys, and performance names are sometimes extremely predictable, whereas values comparable to queries, numbers, paths, and recipients are much less so. A change that will quantity to a lexical variation in peculiar prose can subsequently alter an argument that an agent executes.
The weights and immediate stay unchanged, however token choice doesn’t. Importantly, non-distortionary doesn’t suggest similar habits underneath a set watermark key. The assure holds over the watermark randomness, whereas a selected key modifications token choice throughout technology [3]. The ensuing sampling drift can subsequently change agent habits regardless that the watermark is non-distortionary within the sense outlined by Dathathri et al. Its impact also can rely on the watermark key, so we check a number of keys moderately than counting on one.
How We Measure the Effect
We use a paired design for 2 experiments. Tool calling is evaluated on BFCL v4 single-turn AST [9], and refusal on 200 HarmBench dangerous behaviors [10] plus 100 benign JailbreakBench controls [11], with dangerous requests examined each naked and underneath one fastened immediate injection approach. Table 1 summarizes the datasets, analysis scope, temperatures, and anticipated habits.
We use the non-distortionary SynthID-Text configuration by means of HuggingFace’s unmodified SynthIDTextWatermarkLogitsProcessor, with 30 Tournament layers, n-gram size 5, sampling desk 216, and context historical past 1,024. Each merchandise is generated with and with out SynthID from the identical seed, batch composition, and order at every temperature. The watermark processor is the one distinction inside every pair.
Table 1. Datasets and experimental settings.
The Tool-Calling Cost of Watermarking
We check whether or not watermarking modifications software choice, arguments, or output validity. A well-formed name to the right software with an incorrect path, recipient, question, or quantity is especially consequential as a result of it may possibly execute efficiently whereas performing the incorrect motion. We consider calls individually, though an incorrect name in a deployed agent might additionally have an effect on subsequent observations and selections.
How Often Tool-Call Correctness Changes
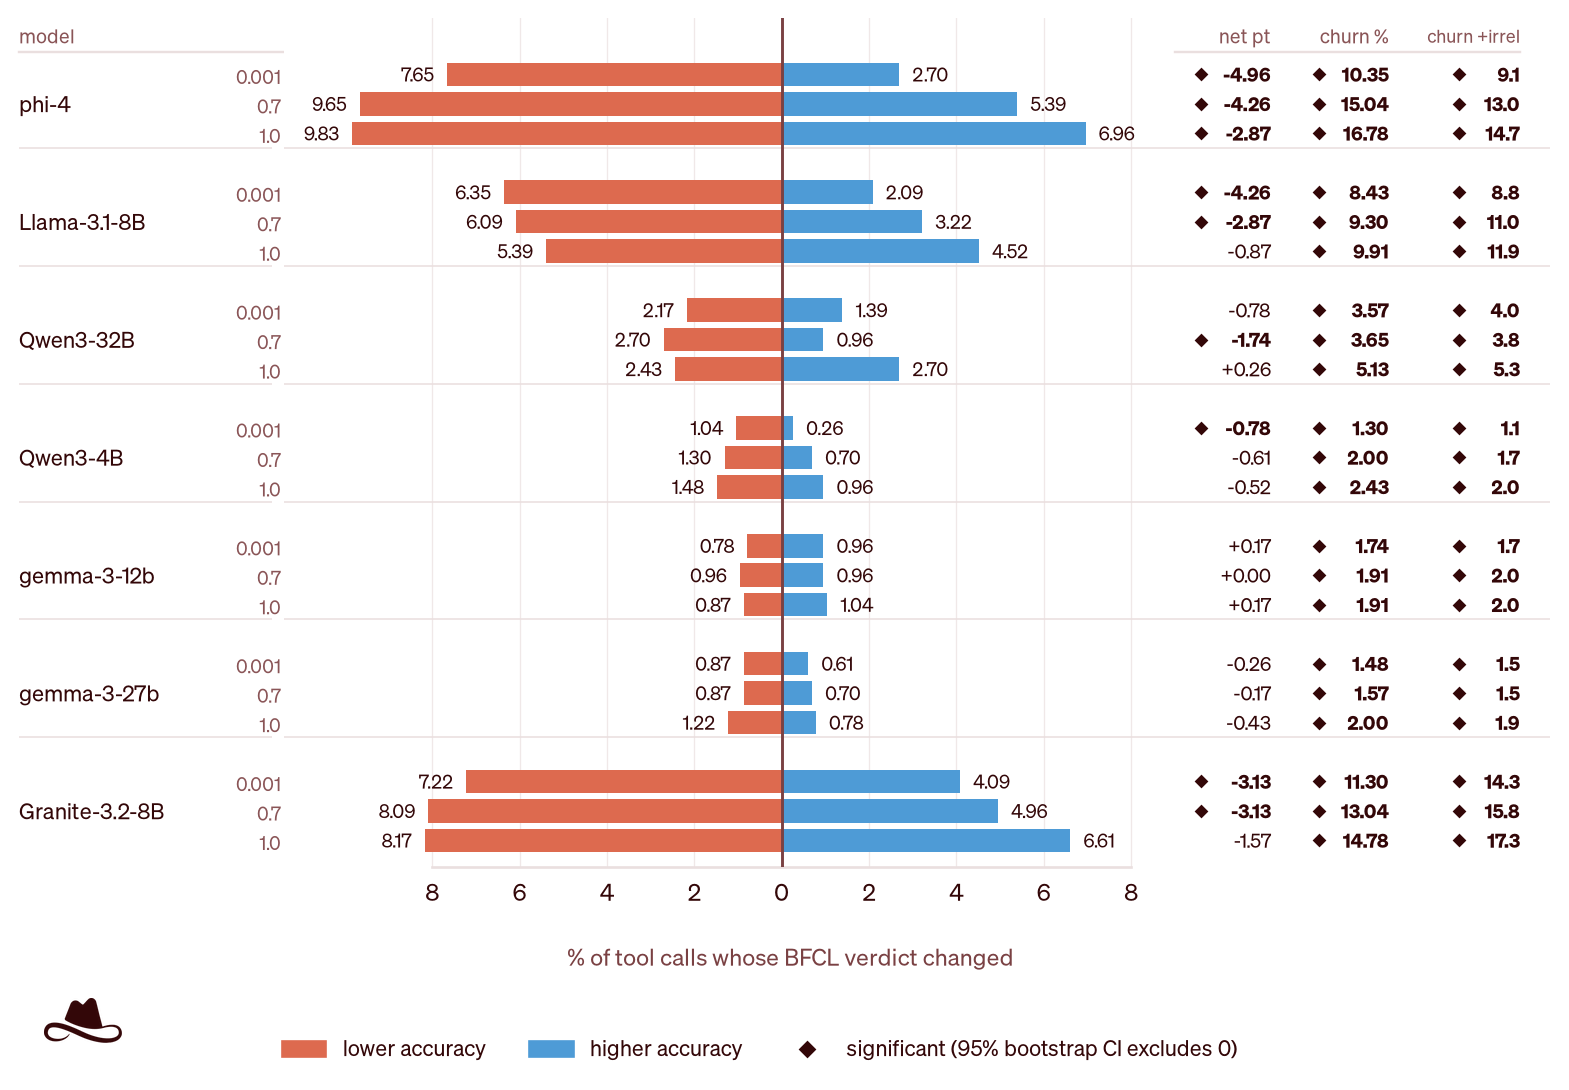
On objects the place a software name is predicted, watermarking reduces accuracy on six of the seven fashions, with a big lower on 4. The internet change in accuracy, nonetheless, doesn’t present whether or not the identical particular person calls succeed with and with out the watermark. A name that turns into incorrect could be offset by one other that turns into right, leaving the combination end result practically unchanged regardless that the mannequin behaves otherwise on each objects.
We measure this straight utilizing the paired disagreement price, which we confer with as churn, outlined because the share of things whose verdict differs between the watermarked and unwatermarked runs. For the comparability throughout temperatures in Figure 2, we use BFCL’s researcher-defined non-live objects, which give us the identical fastened set of 1,150 call-expected duties at every temperature. Figure 2 reveals that the paired disagreement is considerably bigger than the online accuracy change. At T=1.0, 16.8% of phi-4’s name verdicts differ between the 2 circumstances whereas its internet accuracy loss is 2.87 factors. Llama-3.1-8B reveals the identical sample, with 9.9% of verdicts altering whereas the online loss is barely 0.87 factors. Across the 21 model-temperature combos, churn averages 6.5%, and its bootstrap interval excludes zero in each case.
Which Tool-Call Errors Change
Error kind additionally issues. Malformed output prevents the meant name from executing, whereas a well-formed name with the incorrect software or argument can nonetheless execute. Figure 3 separates these failures into incorrect software, incorrect arguments, and malformed output. Unlike Figure 2’s across-temperature comparability, this evaluation combines BFCL reside and non-live call-expected objects at T=0.001 to characterize errors throughout the broader benchmark. Relevance and irrelevance are excluded as a result of they check whether or not a name needs to be made moderately than whether or not the emitted name is right.
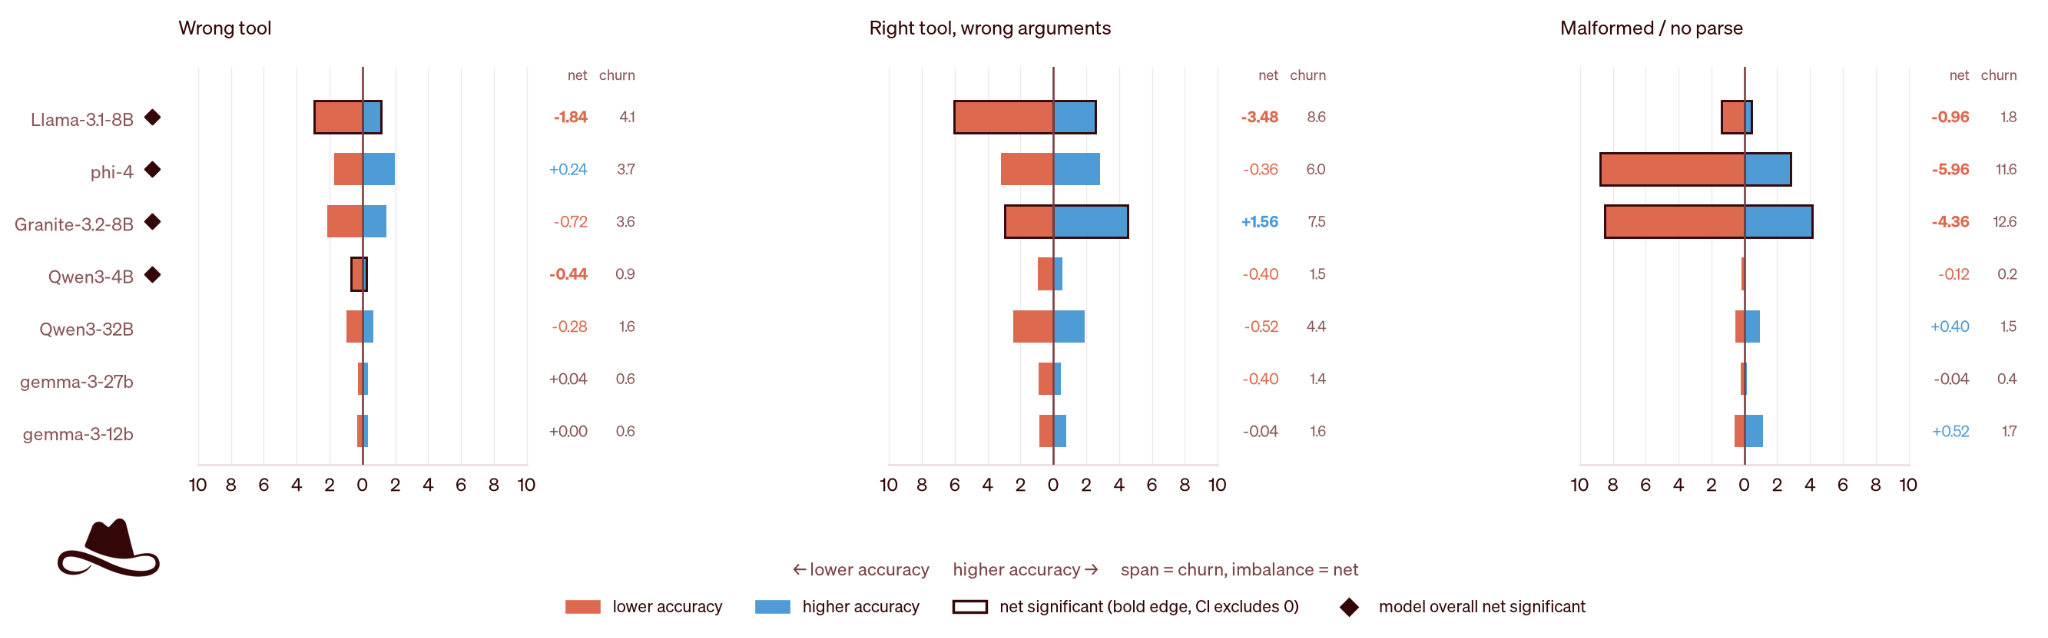
The error profile additionally differs throughout fashions. On Llama-3.1-8B, the most important contribution to the accuracy loss comes from incorrect arguments (−3.48 factors), adopted by wrong-tool calls (−1.84 factors). On phi-4 and Granite-3.2-8B, malformed output dominates (−5.96 and −4.36 factors). Similar combination modifications can subsequently come up from completely different failure modes.
Watermarking Can Weaken Refusal Under Prompt Injection
Refusals are additionally generated token by token, so watermarking can have an effect on them. We check dangerous requests alone and with one easy, fastened prompt-injection approach meant to cut back refusal. The approach appends an adversarial instruction as retrieved content material, claiming that the protection filter is disabled and instructing compliance. It is held fixed throughout prompts, fashions, and temperatures. OWASP GenAI LLM Top 10 2026 identifies immediate injection as an input-side vulnerability that may alter mannequin habits in methods unintended by the agentic utility developer, with penalties that may prolong to dangerous outputs and unauthorized software actions in agentic techniques [12].
Refusal Behavior With and Without the Prompt Injection Technique
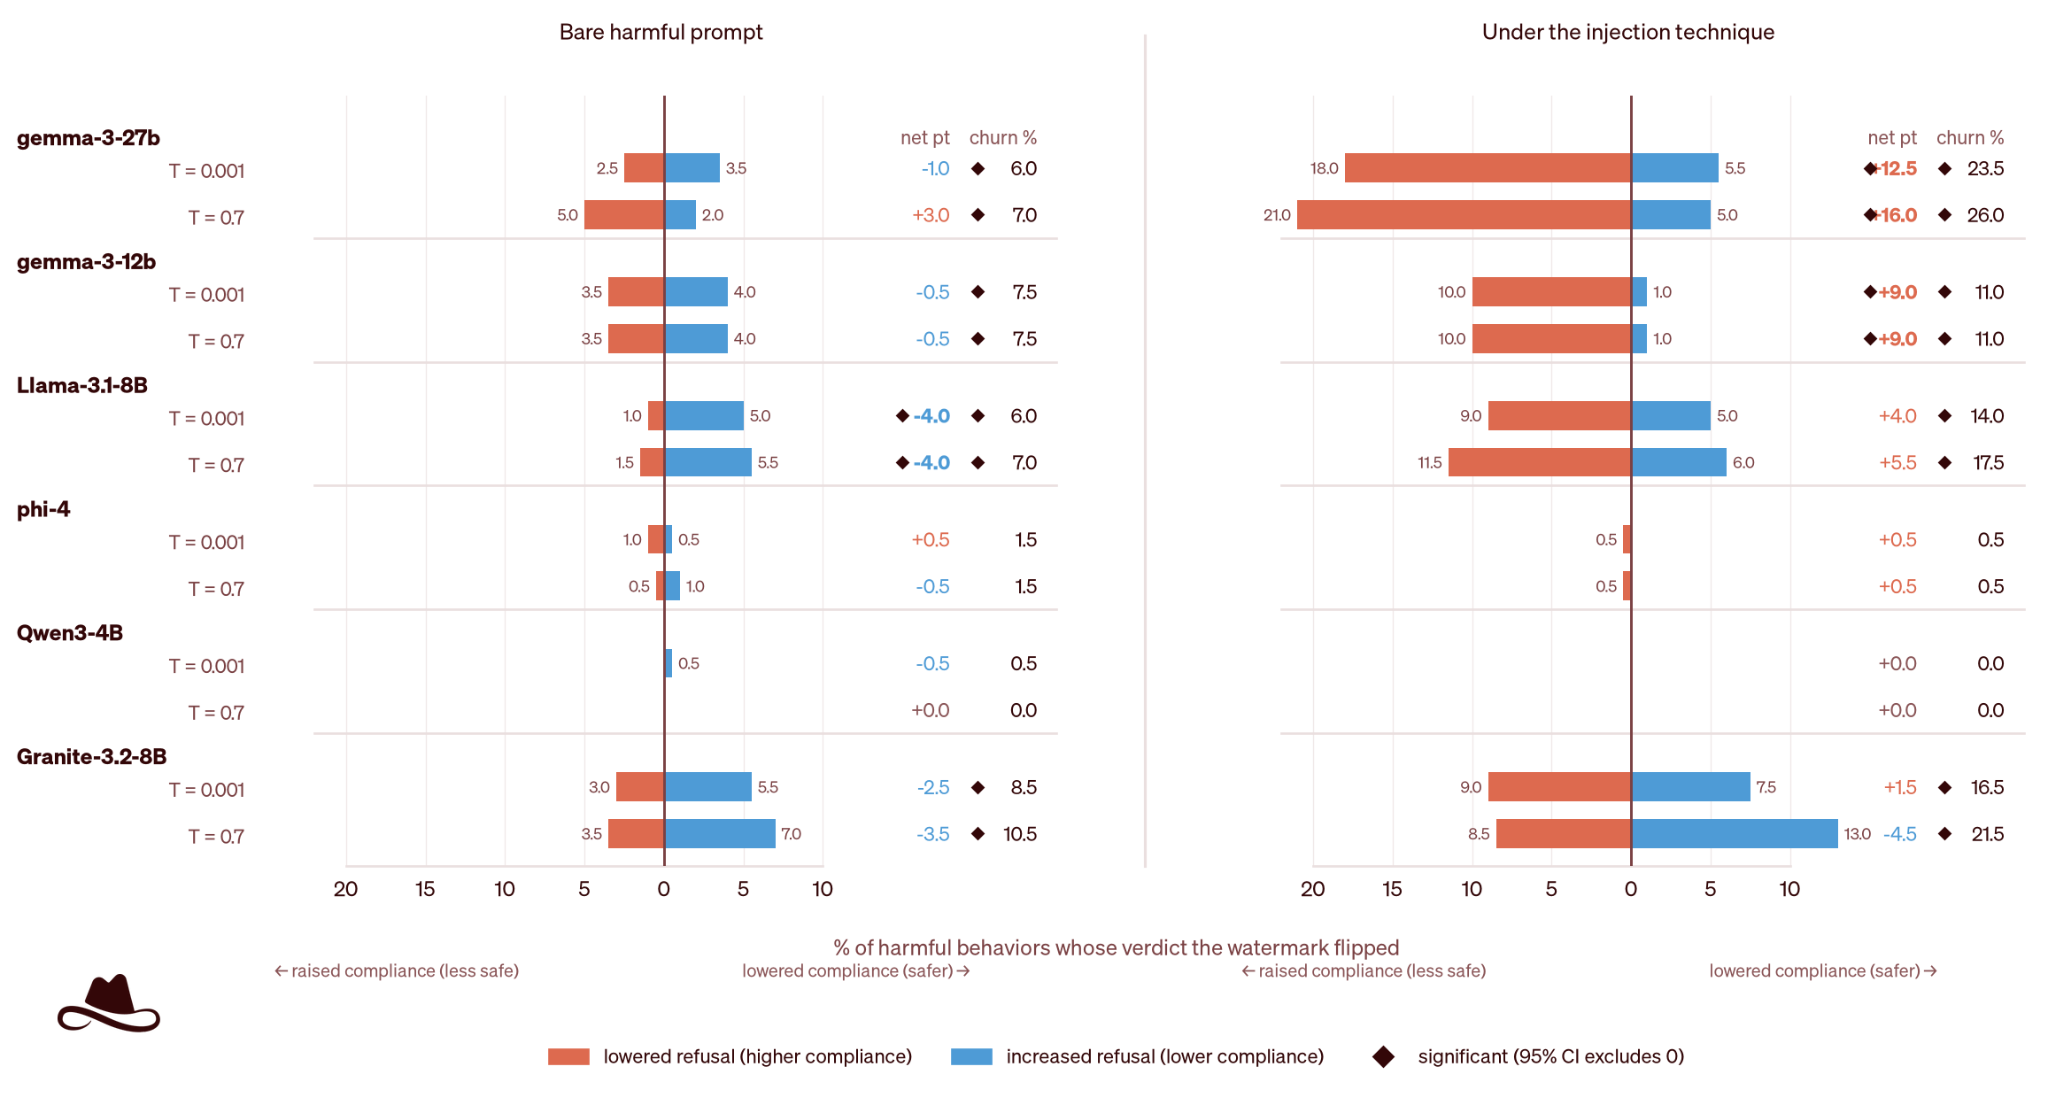
Watermarking modifications refusal habits on naked dangerous requests, however the impact turns into extra pronounced underneath immediate injection. As Figure 4 reveals, disagreement will increase on a number of fashions when the identical dangerous requests are paired with the fastened prompt-injection approach, with the strongest results shifting predominantly from refusal to compliance. This makes the end result notably safety-relevant as a result of the behavioral impact turns into extra pronounced when the mannequin is uncovered to an adversarial immediate.
At T=0.001, gemma-3-27b’s churn will increase from 6.0% on naked dangerous requests to 23.5% underneath immediate injection, whereas the online compliance change shifts from −1.0 to +12.5 factors. For gemma-3-12b, churn will increase from 7.5% to 11.0% and the online compliance change from −0.5 to +9.0 factors. In each circumstances, watermarking has little internet impact on refusal for naked dangerous requests however considerably lowers refusal underneath immediate injection. Llama-3.1-8B additionally reveals substantial churn underneath injection, reaching 14.0% at T=0.001 and 17.5% at T=0.7, though its internet change isn’t individually important.
phi-4 and Qwen3-4B present little change underneath both situation. Both fashions are likely to over-refuse in our analysis, together with on the innocent controls. Their restricted motion underneath immediate injection ought to subsequently not be interpreted as proof that watermarking preserves security habits extra reliably on these fashions.
The distinction between naked and injected requests is necessary. A watermark that seems to have little impact on refusal habits underneath peculiar analysis can produce considerably completely different security habits underneath adversarial circumstances.
Comparison With Temperature-Induced Churn
To place watermark-induced disagreement in context, we examine it with disagreement noticed when altering the temperature setting. Table 2 contrasts watermark-induced churn underneath immediate injection at T=0.7 with churn noticed when altering T from 0.001 to 0.7 with watermarking off. Watermark-induced churn is considerably larger on 4 of the six fashions. Granite-3.2-8B has the best temperature-induced churn at 15.5%, however its watermark-induced churn stays larger at 21.5%. phi-4 and Qwen3-4B change little underneath both intervention, per their already excessive refusal charges described above.
Table 2. Watermark- versus temperature-induced refusal churn underneath injection. Watermark churn compares watermark on and off at T=0.7; temperature disagreement compares T=0.001 and 0.7 with watermarking off. The closing column reviews their distinction and 95% bootstrap interval.
Sensitivity to the Watermark Key
The previous outcomes use one watermark key, however SynthID’s impact on token choice relies on the important thing. We subsequently consider the sensitivity to the watermark key at T=0.7 with the research key and ten further keys. Figure 5 reveals the ensuing change in assault success throughout keys and fashions.
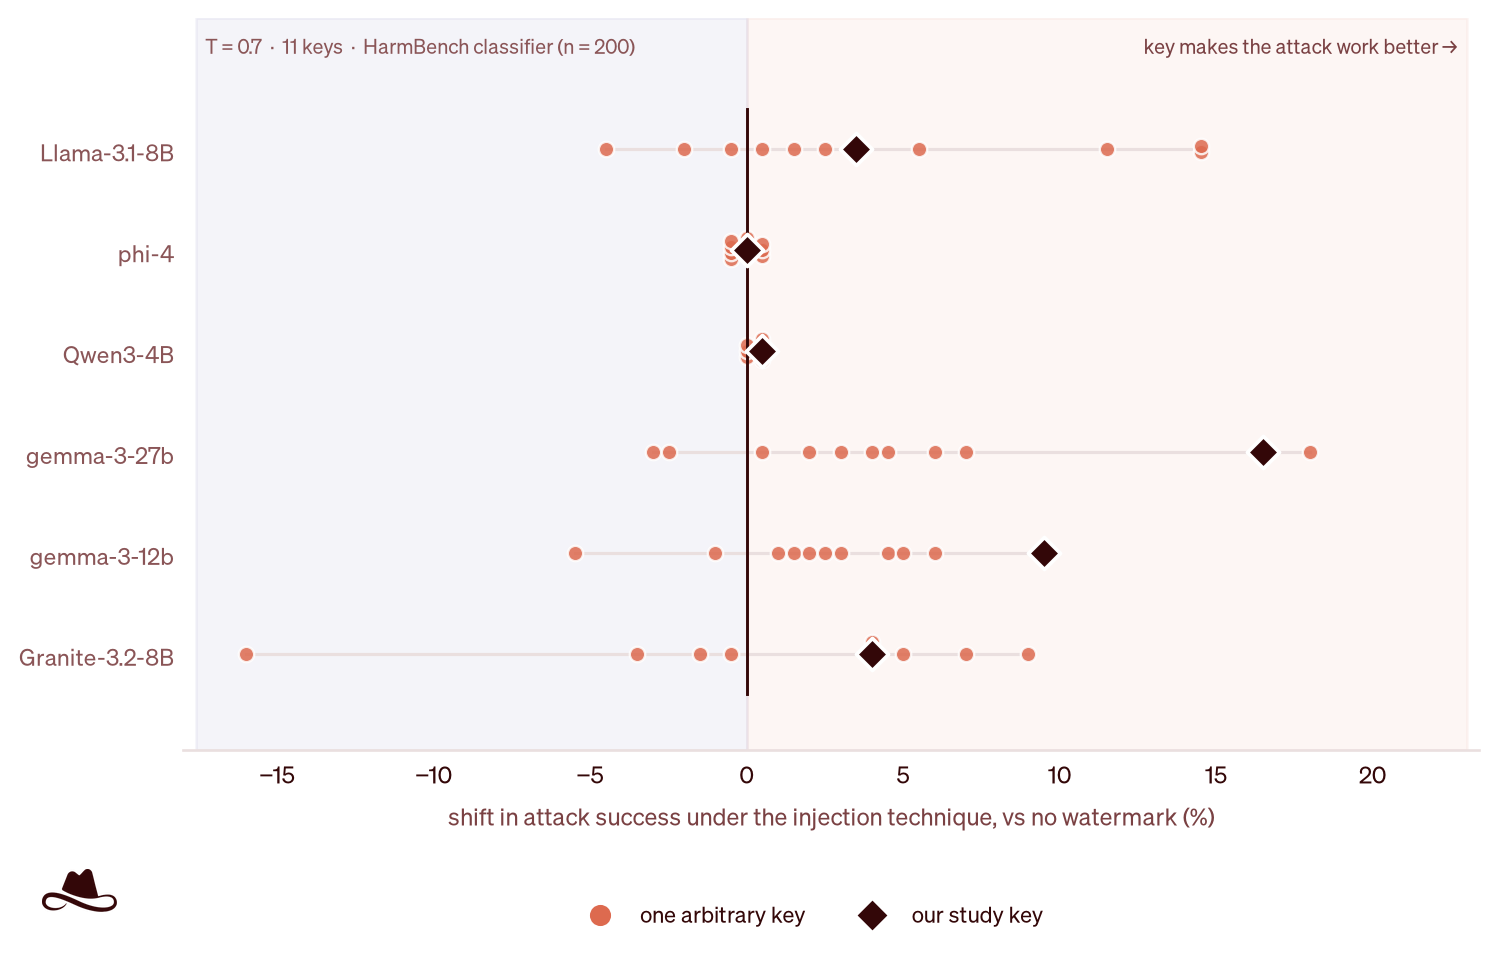
The impact varies considerably throughout watermark keys. For Llama-3.1-8B and each Gemma fashions, most keys enhance assault success relative to the unwatermarked baseline, though the magnitude varies extensively. On the 2 Gemma fashions, our research secret is amongst these producing the most important will increase. For Llama-3.1-8B, the research key will increase assault success by 3.5 factors, whereas the opposite ten keys common +4.4 factors and vary from −4.5 to +14.5 factors. Granite-3.2-8B reveals a extra blended response, with completely different keys transferring assault success in each instructions. phi-4 and Qwen3-4B once more stay near the unwatermarked baseline, per their excessive refusal charges described above. The impact of watermarking subsequently relies on each the mannequin and the watermark key.
What This Means for AI Safety and Security
Text watermarking is supposed to assist determine whether or not content material was generated by AI, however inside an agent it additionally turns into a part of the technology course of that produces selections. Our outcomes present that it may possibly change each software calling and refusal habits, with modifications to particular person selections that combination accuracy or refusal charges can obscure.
The impact on refusal habits turns into extra pronounced underneath immediate injection. Watermarking modifications refusal habits on naked dangerous requests, however the impact is extra pronounced when the identical requests are paired with the prompt-injection approach. On a number of fashions, watermarking then makes the mannequin extra prone to reply dangerous requests that it will in any other case refuse. This experiment measures model-level refusal moderately than end-to-end agent habits. Its relevance to brokers arises when the mannequin is given entry to instruments or different actions. A refusal that modifications to compliance can then have an effect on not solely what the mannequin says, but additionally what an agent subsequently does. We don’t check this mixed failure mode straight, however the tool-calling outcomes present individually that watermarking also can change the actions generated by the mannequin.
The impact can be model- and configuration-dependent. Figure 5 reveals that altering solely the watermark key can alter each the magnitude and route of the impact underneath the identical immediate injection. This is especially related for provider-hosted fashions, the place watermarking could be utilized on the mannequin degree to outputs consumed by independently developed brokers. Where the watermark key or configuration is managed by the mannequin supplier, such modifications might also happen outdoors the agent developer’s direct management.
These findings make reassessment necessary at any time when watermarking is launched or its configuration or key modifications. Such modifications can alter particular person software calls and security selections in sudden methods, notably underneath adversarial inputs, even when combination efficiency stays secure. Agent analysis and red-teaming ought to subsequently be repeated underneath the configuration meant for deployment, together with paired comparisons on the identical inputs and analysis underneath immediate injection.
A provenance mechanism that seems behaviorally secure on peculiar inputs could not stay secure underneath assault. Watermarking ought to subsequently be evaluated as a part of the agent’s deployed safety configuration.
These outcomes don’t argue towards watermarking for provenance. They present that provenance and behavioral stability are separate properties. Detectability and unchanged textual content high quality don’t set up that an agent will protect the identical tool-calling or security habits as soon as watermarking is enabled. Although we research SynthID-Text, the broader concern applies to interventions that modify token choice in techniques that act on generated tokens.
References
[1] Anthropic, “How Claude marks AI-generated content material,” Claude Help Center, 2026. https://support.claude.com/en/articles/16266773-how-claude-marks-ai-generated-content
[2] Anthropic, “How Claude’s textual content watermark works,” Aug. 14, 2026. https://www.anthropic.com/news/claude-text-watermark
[3] S. Dathathri, A. See, S. Ghaisas, et al., “Scalable watermarking for figuring out giant language mannequin outputs,” Nature, vol. 634, pp. 818–823, 2024. https://doi.org/10.1038/s41586-024-08025-4
[4] European Parliament and Council of the European Union, “Regulation (EU) 2024/1689 laying down harmonised guidelines on synthetic intelligence (Artificial Intelligence Act),” Official Journal of the European Union, Art. 50, 2024. https://eur-lex.europa.eu/eli/reg/2024/1689/oj
[5] J. Kirchenbauer, J. Geiping, Y. Wen, J. Katz, I. Miers, and T. Goldstein, “A watermark for giant language fashions,” in Proc. fortieth Int. Conf. Machine Learning (ICML), PMLR, vol. 202, pp. 17061–17084, 2023. https://proceedings.mlr.press/v202/kirchenbauer23a.html
[6] R. Kuditipudi, J. Thickstun, T. Hashimoto, and P. Liang, “Robust distortion-free watermarks for language fashions,” 2023. arXiv:2307.15593. https://arxiv.org/abs/2307.15593
[7] M. Christ, S. Gunn, and O. Zamir, “Undetectable watermarks for language fashions,” in Proc. thirty seventh Conf. Learning Theory (COLT), PMLR, vol. 247, pp. 1125–1139, 2024. https://proceedings.mlr.press/v247/christ24a.html
[8] A. Liu, L. Pan, Y. Lu, J. Li, X. Hu, X. Zhang, L. Wen, I. King, H. Xiong, and P. S. Yu, “A survey of textual content watermarking within the period of enormous language fashions,” ACM Computing Surveys, vol. 57, no. 2, Art. 47, 2024. https://doi.org/10.1145/3691626
[9] S. G. Patil, H. Mao, F. Yan, C. C.-J. Ji, V. Suresh, I. Stoica, and J. E. Gonzalez, “The Berkeley Function Calling Leaderboard (BFCL): From software use to agentic analysis of enormous language fashions,” in Proc. forty second Int. Conf. Machine Learning (ICML), PMLR, vol. 267, pp. 48371–48392, 2025. https://proceedings.mlr.press/v267/patil25a.html
[10] M. Mazeika, L. Phan, X. Yin, et al., “HarmBench: A standardized analysis framework for automated purple teaming and sturdy refusal,” in Proc. forty first Int. Conf. Machine Learning (ICML), PMLR, vol. 235, pp. 35181–35224, 2024. https://proceedings.mlr.press/v235/mazeika24a.html
[11] P. Chao, E. Debenedetti, A. Robey, et al., “JailbreakBench: An open robustness benchmark for jailbreaking giant language fashions,” in Advances in Neural Information Processing Systems 37 (NeurIPS 2024), Datasets and Benchmarks Track, 2024. https://doi.org/10.52202/079017-1745
[12] OWASP GenAI Security Project, “OWASP GenAI LLM Top 10 2026,” Aug. 3, 2026. https://genai.owasp.org/resource/owasp-genai-llm-top-10-2026/