A Jev-like wrapper for LLMs, together with imaginative and prescient fashions

I used to be intrigued by Jev and the self-hostable tasks showing round it, corresponding to OpenJev and SemIf. Reading about them launched me to a neat trick: studying an LLM’s token chances.
Apparently that is an outdated trick for some individuals. See e.g. OpenAI’s logprobs cookbook. But it was new to me.
I consider the essential thought is to jot down a immediate like this:
State: My order arrived damaged and I need a refund.
Question: Which group ought to deal with this?
[A] billing
[B] delivery
[C] returns
Answer with the letter of the most suitable choice solely.
Then add just a few JSON request parameters to a appropriate Chat Completions request:
{
  "max_completion_tokens": 1,
  "logprobs": true,
  "top_logprobs": 20
}
The LLM API will return the letter plus the mannequin’s log chances for different tokens.
Repeat for every query. Forcing it to producing just one token avoids a prolonged reply and is tremendous fast, although processing the enter nonetheless prices time. Though for every of the questions a shared state prefix might be KV-cached if the backend helps it.
The enjoyable half: this works with imaginative and prescient fashions too. Jev’s documented request format at present describes solely textual content/JSON state. I added an attachments subject for photos for my native experiments.
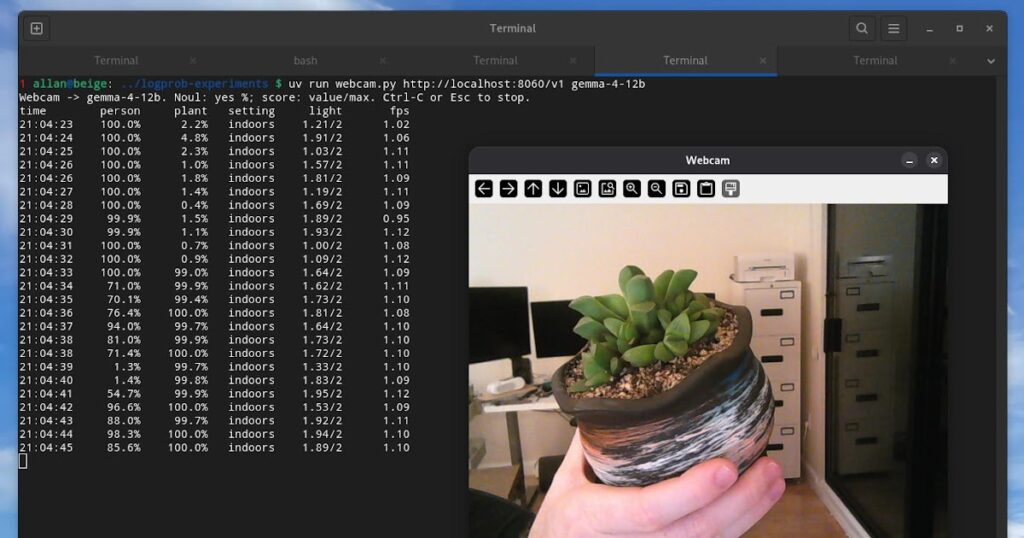
My instance captures webcam frames, sends base64 JPEGs, and prints a desk: is an individual seen, are we indoors or open air, and the way shiny is the scene? With Gemma 4 12B on my RTX 3090, I get round 1 frames per second, with three questions per body. I additionally ran it in opposition to OpenAI gpt-6-luna and received round 0.2 FPS. Presumably as a result of I did not make any effort to keep away from the price of a separate connection via their system per query per body.
Specialized pc imaginative and prescient fashions absolutely are far more environment friendly, however what I like right here is the pliability: change a situation by describing it in plain textual content.
Here’s the standalone Python instance (OpenCV is simply used for handy entry to the webcam, not for any precise pc imaginative and prescient):
#!/usr/bin/env -S uv run --script
# /// script
# dependencies = ["opencv-python"]
# ///
"""Preview and rating webcam frames with llama.cpp or OpenAI.

uv run webcam.py
uv run webcam.py https://api.openai.com/v1 gpt-6-luna
OpenAI reads OPENAI_API_KEY.
"""
import argparse
import base64
import concurrent.futures
import datetime
import json
import math
import mimetypes
import os
import pathlib
import time
import urllib.parse
import urllib.request

import cv2


# attachments is our customized addition to the Jev request format.
knowledge = json.masses("""
{
    "state": "Inspect this webcam body. Judge solely what's visibly current.",
    "attachments": [],
    "questions": {
        "particular person": {
            "kind": "noul",
            "directions": "Is an individual seen?"
        },
        "plant": {
            "kind": "noul",
            "directions": "Is a plant seen?"
        },
        "setting": {
            "kind": "selection",
            "directions": "Where is the digital camera?",
            "standards": {
                "indoors": null,
                "open air": null,
                "unclear": null
            }
        },
        "gentle": {
            "kind": "rating",
            "directions": "How shiny is the scene?",
            "standards": [
                "dark",
                "dim",
                "bright"
            ]
        }
    }
}
""")


def rating(knowledge, url, mannequin):
    state = knowledge["state"]
    if not isinstance(state, str):
        state = json.dumps(state)

    # Attachments are our extension to the Jev-style request format:
    # picture file paths or base64 knowledge URLs. Load them as soon as for all questions.
    photos = []
    for attachment in knowledge.get("attachments", []):
        if attachment.startswith("knowledge:picture/"):
            photos.append(attachment)
            proceed
        path = pathlib.Path(attachment).expanduser()
        mime_type, _ = mimetypes.guess_type(path)
        if mime_type not in {"picture/png", "picture/jpeg", "picture/webp", "picture/gif"}:
            elevate ValueError(f"Unsupported picture file: {path}")
        encoded = base64.b64encode(path.read_bytes()).decode()
        photos.append(f"knowledge:{mime_type};base64,{encoded}")

    # Send the API key solely to OpenAI.
    is_openai = urllib.parse.urlsplit(url).hostname == "api.openai.com"
    headers = {"Content-Type": "software/json"}
    if is_openai:
        headers["Authorization"] = "Bearer " + os.environ["OPENAI_API_KEY"]

    solutions = {}
    for title, query in knowledge["questions"].gadgets():
        # Represent selections, booleans, and ordinal ranges as lettered choices.
        if query["type"] == "selection":
            choices = query["criteria"]
        elif query["type"] == "noul":
            choices = {"true": None, "false": None} | query.get("standards", {})
        elif query["type"] == "rating":
            choices = {str(i): description for i, description in enumerate(query["criteria"])}
        else:
            elevate ValueError(f"Unknown query kind: {query['type']}")
        if not 2 <= len(choices) <= 20:
            elevate ValueError("Provide 2 to twenty standards per query.")
        letters = "ABCDEFGHIJKLMNOPQRST"[:len(options)]

        # Ask for a single possibility letter, so its logprob represents that possibility.
        directions = query["instructions"]
        if not isinstance(directions, str):
            directions = json.dumps(directions)
        traces = [f"State:n{state}nnQuestion: {instructions}nOptions:"]
        for letter, (key, description) in zip(letters, choices.gadgets()):
            line = f"[{letter}] {key}"
            if description isn't None:
                line += f": {description}"
            traces.append(line)
        immediate = "n".be a part of(traces) + "nnAnswer with the letter of the most suitable choice solely."

        # OpenAI wants Responses for sufficient options; llama.cpp wants Chat for logprobs.
        # top_p=1 avoids pruning options.
        if is_openai:
            endpoint = "/responses"
            content material = [{"type": "input_text", "text": prompt}]
            content material.lengthen({"kind": "input_image", "image_url": picture} for picture in photos)
            physique = {
                "mannequin": mannequin,
                "enter": [{"role": "user", "content": content}],
                "reasoning": {"effort": "none"},
                "max_output_tokens": 16,
                "top_p": 1,
                "top_logprobs": 20,
                "embrace": ["message.output_text.logprobs"],
            }
        else:
            endpoint = "/chat/completions"
            content material = [{"type": "text", "text": prompt}]
            content material.lengthen({"kind": "image_url", "image_url": {"url": picture}} for picture in photos)
            physique = {
                "mannequin": mannequin,
                "messages": [{"role": "user", "content": content}],
                "max_completion_tokens": 1,
                "temperature": 0,
                "reasoning_effort": "none",
                "logprobs": True,
                "top_logprobs": 1024,
            }

        # Send the request and browse the primary output token's options.
        request = urllib.request.Request(
            url.rstrip("/") + endpoint,
            headers=headers,
            knowledge=json.dumps(physique).encode(),
        )
        with urllib.request.urlopen(request) as response:
            outcome = json.load(response)
        if is_openai:
            message = subsequent(merchandise for merchandise in outcome["output"] if merchandise["type"] == "message")
            candidates = message["content"][0]["logprobs"][0]["top_logprobs"]
        else:
            candidates = outcome["choices"][0]["logprobs"]["content"][0]["top_logprobs"]
        logprobs = {merchandise["token"]: merchandise["logprob"] for merchandise in candidates}

        # Normalize the returned possibility scores; lacking choices initially get zero.
        lacking = [letter for letter in letters if letter not in logprobs or logprobs[letter] <= -9999]
        if len(lacking) == len(letters):
            elevate ValueError("API didn't return usable scores for any possibility")
        peak = max(logprobs[letter] for letter in letters if letter not in lacking)
        weights = [math.exp(logprobs[letter] - peak) if letter not in lacking else 0 for letter in letters]
        whole = sum(weights)

        # An omitted token can not outrank the final returned different.
        # Allow zero solely when their mixed normalized likelihood is beneath 1e-6.
        if lacking:
            cutoff = min(worth for worth in logprobs.values() if worth > -9999)
            missing_weight = len(lacking) * math.exp(cutoff - peak)
            if missing_weight / (whole + missing_weight) >= 1e-6:
                elevate ValueError(f"API omitted non-negligible possibility scores for: {', '.be a part of(lacking)}")
        chances = {key: weight / whole for key, weight in zip(choices, weights)}

        # Return the profitable selection, likelihood of true, or anticipated ordinal degree.
        if query["type"] == "selection":
            solutions[name] = {
                "kind": "selection",
                "selection": max(chances, key=chances.get),
                "chances": chances,
            }
        elif query["type"] == "noul":
            solutions[name] = {"kind": "noul", "noul": chances["true"]}
        else:
            solutions[name] = {
                "kind": "rating",
                "rating": sum(int(key) * likelihood for key, likelihood in chances.gadgets()),
                "legend": choices,
                "chances": chances,
            }

    return {"solutions": solutions}


# Choose the server and mannequin earlier than opening the digital camera.
parser = argparse.ArgumentParser(description=__doc__)
parser.add_argument("url", nargs="?", default="http://localhost:8060/v1")
parser.add_argument("mannequin", nargs="?", default="gemma-4-12b")
args = parser.parse_args()

# Point OpenCV's bundled Qt on the put in system fonts.
os.environ["QT_QPA_FONTDIR"] = "/usr/share/fonts/truetype/noto"

# Open the default Linux webcam with a small seize buffer.
digital camera = cv2.VideoCapture(0, cv2.CAP_V4L2)
if not digital camera.isOpened():
    elevate RuntimeError("Could not open /dev/video0")
digital camera.set(cv2.CAP_PROP_BUFFERSIZE, 1)
print(f"Webcam -> {args.mannequin}. Noul: sure %; rating: worth/max. Ctrl-C or Esc to cease.", flush=True)
print(f"{'time':<8}" + "".be a part of(f"{title:>10}" for title in knowledge["questions"]) + f"{'fps':>10}", flush=True)

# Preview repeatedly whereas a background employee scores one body at a time.
executor = concurrent.futures.ThreadPoolExecutor(max_workers=1)
pending = None
strive:
    whereas True:
        okay, body = digital camera.learn()
        if not okay:
            elevate RuntimeError("Could not learn a webcam body")
        cv2.imshow("Webcam", body)
        if cv2.waitKey(1) == 27 or cv2.getWindowProperty("Webcam", cv2.WND_PROP_VISIBLE) < 1:
            break

        # Print a accomplished outcome, then submit the newest body.
        if pending isn't None:
            if not pending.executed():
                proceed
            outcome = pending.outcome()
            columns = []
            for title in knowledge["questions"]:
                reply = outcome["answers"][name]
                if reply["type"] == "noul":
                    worth = f"{reply['noul']:.1%}"
                elif reply["type"] == "selection":
                    worth = reply["choice"]
                else:
                    worth = f"{reply['score']:.2f}/{len(knowledge['questions'][name]['criteria']) - 1}"
                columns.append(f"{worth:>10}")
            columns.append(f"{1 / (time.perf_counter() - began):>10.2f}")
            print(captured + "".be a part of(columns), flush=True)
        # Measure throughput for evaluated frames, together with picture encoding.
        began = time.perf_counter()
        captured = datetime.datetime.now().strftime("%H:%M:%S")
        okay, jpeg = cv2.imencode(".jpg", body)
        if not okay:
            elevate RuntimeError("Could not encode the webcam body")
        picture = "knowledge:picture/jpeg;base64," + base64.b64encode(jpeg.tobytes()).decode()
        knowledge["attachments"] = [image]
        pending = executor.submit(rating, knowledge, args.url, args.mannequin)
besides KeyboardInterrupt:
    print("nStopped.")
lastly:
    digital camera.launch()
    cv2.destroyAllWindows()
    executor.shutdown()
The script handles the API variations: llama.cpp makes use of Chat Completions and OpenAI makes use of Responses to get it to point out options.
I ran Gemma 4 12B QAT via llama.cpp. On Linux with NVIDIA drivers, curl, zstd, and uv put in:
# Model (~7 GB) and multimodal projector (~175 MB).
mkdir -p ~/fashions/gemma-4-12b/
cd ~/fashions/gemma-4-12b/
curl -fL -C - -o gemma-4-12b-it-qat-q4_0.gguf https://huggingface.co/google/gemma-4-12B-it-qat-q4_0-gguf/resolve/main/gemma-4-12b-it-qat-q4_0.gguf
curl -fL -C - -o mmproj-gemma-4-12b-it-qat-q4_0.gguf https://huggingface.co/google/gemma-4-12B-it-qat-q4_0-gguf/resolve/main/mmproj-gemma-4-12b-it-qat-q4_0.gguf

# Standalone llama.cpp binary for RTX 3090 (CUDA structure 86).
curl -fL -o llama.zst https://huggingface.co/buckets/ggml-org/install.sh/resolve/b11160/x86_64/linux/cuda/86/llama-app.zst
mkdir -p ~/bin/
zstd -d llama.zst -o ~/bin/llama
chmod +x ~/bin/llama
~/bin/llama serve --models-dir ~/fashions/ --port 8060
Save the Python instance as webcam.py. In one other terminal, from that listing:
uv run webcam.py http://localhost:8060/v1 gemma-4-12b
# Or use OpenAI, with OPENAI_API_KEY set in your surroundings.
uv run webcam.py https://api.openai.com/v1 gpt-6-luna