ShapeLearn-Lite Held Up. ShapeLearn Did Higher: Qwen 3.8 27B

We had been somewhat impatient.
Qwen 3.8 27B was launched on August 14, 2026. Four days later, on August 18, we printed our first set of GGUFs. We referred to as them ShapeLearn-Lite for a cause: they had been produced utilizing a a lot smaller optimization price range, fewer checks, and far much less ready.
Now the total ShapeLearn fashions are finished, and we’ve got benchmarked them alongside the unique Lite set and competing quants.
The excellent news: ShapeLearn-Lite held up fairly nicely. We will come again to that later in “ShapeLearn-Lite, in retrospect”.
The higher information: the total ShapeLearn fashions are even higher.
Quick begin with llama.cpp
The MTP draft head is bundled in each GGUF. DFlash2 makes use of a separate 1.1 GB draft mannequin. Both instructions use GPU-5. Swap the tag for every other mannequin within the launch.
MTP Embedded draft. Works with picture inputs.
llama-server
  -hf byteshape/Qwen3.8-27B-GGUF:Qwen3.8-27B-IQ4_XS-3.84bpw
  --mmproj-auto
  --spec-type draft-mtp --spec-draft-n-max 3
DFlash2 External draft. Fastest choice, textual content solely.
llama-server
  -hf byteshape/Qwen3.8-27B-GGUF:Qwen3.8-27B-IQ4_XS-3.84bpw
  -hfd incoai/Qwen3.8-27B-DFlash2-GGUF:Q4_K_M
  --spec-type draft-dflash --spec-draft-n-max 7
  --no-mmproj
DFlash2 wants llama.cpp b10658 or newer. Ready-to-run instructions for each mannequin, with the advisable sampling settings, are within the run tool and on the model card.
TL;DR
- Full ShapeLearn strikes the measured quality-speed frontier past Lite. All 5 fashions within the new launch sit on the frontier in every of our six GPU comparisons.
GPU-5is our default suggestion wherever it suits, reaching 99.63% of BF16’s mixture benchmark rating. If it doesn’t match with the context you want,GPU-4remains to be very aggressive: it reaches 98.72% of BF16 at a a lot smaller dimension (11.0 GB as a substitute of 13.1 GB), and it’s sooner.- ShapeLearn-Lite additionally carried out higher than its KLD rating steered: three of its six fashions sit on the frontier within the Lite-versus-Unsloth Dynamic v3 comparability.
- Speculative Decoding with MTP or DFlash2 will increase throughput throughout each ShapeLearn mannequin and GPU examined. DFlash2 is normally sooner however requires extra reminiscence and doesn’t help picture inputs with llama.cpp. Choose DFlash2 for max text-only throughput when reminiscence permits, and MTP when VRAM or multimodal help issues extra.
Full ShapeLearn strikes the frontier
We are releasing the total ShapeLearn run for Qwen 3.8 27B.
Within this launch, bigger fashions yield larger mixture scores, whereas smaller fashions ship larger throughput. That ordering holds throughout all six GPUs examined. Because it is a dense mannequin and reminiscence transfers are the bottleneck, decrease BPW interprets extra immediately into larger TPS than it does for MoEs.
The per-GPU comparisons additionally embrace AtomicChat, Bartowski, ISTA-DASLab, and Unsloth Dynamic v3. Bartowski’s newest fashions had been launched after our testing and usually are not included. Full ShapeLearn is labelled ByteShape within the figures.
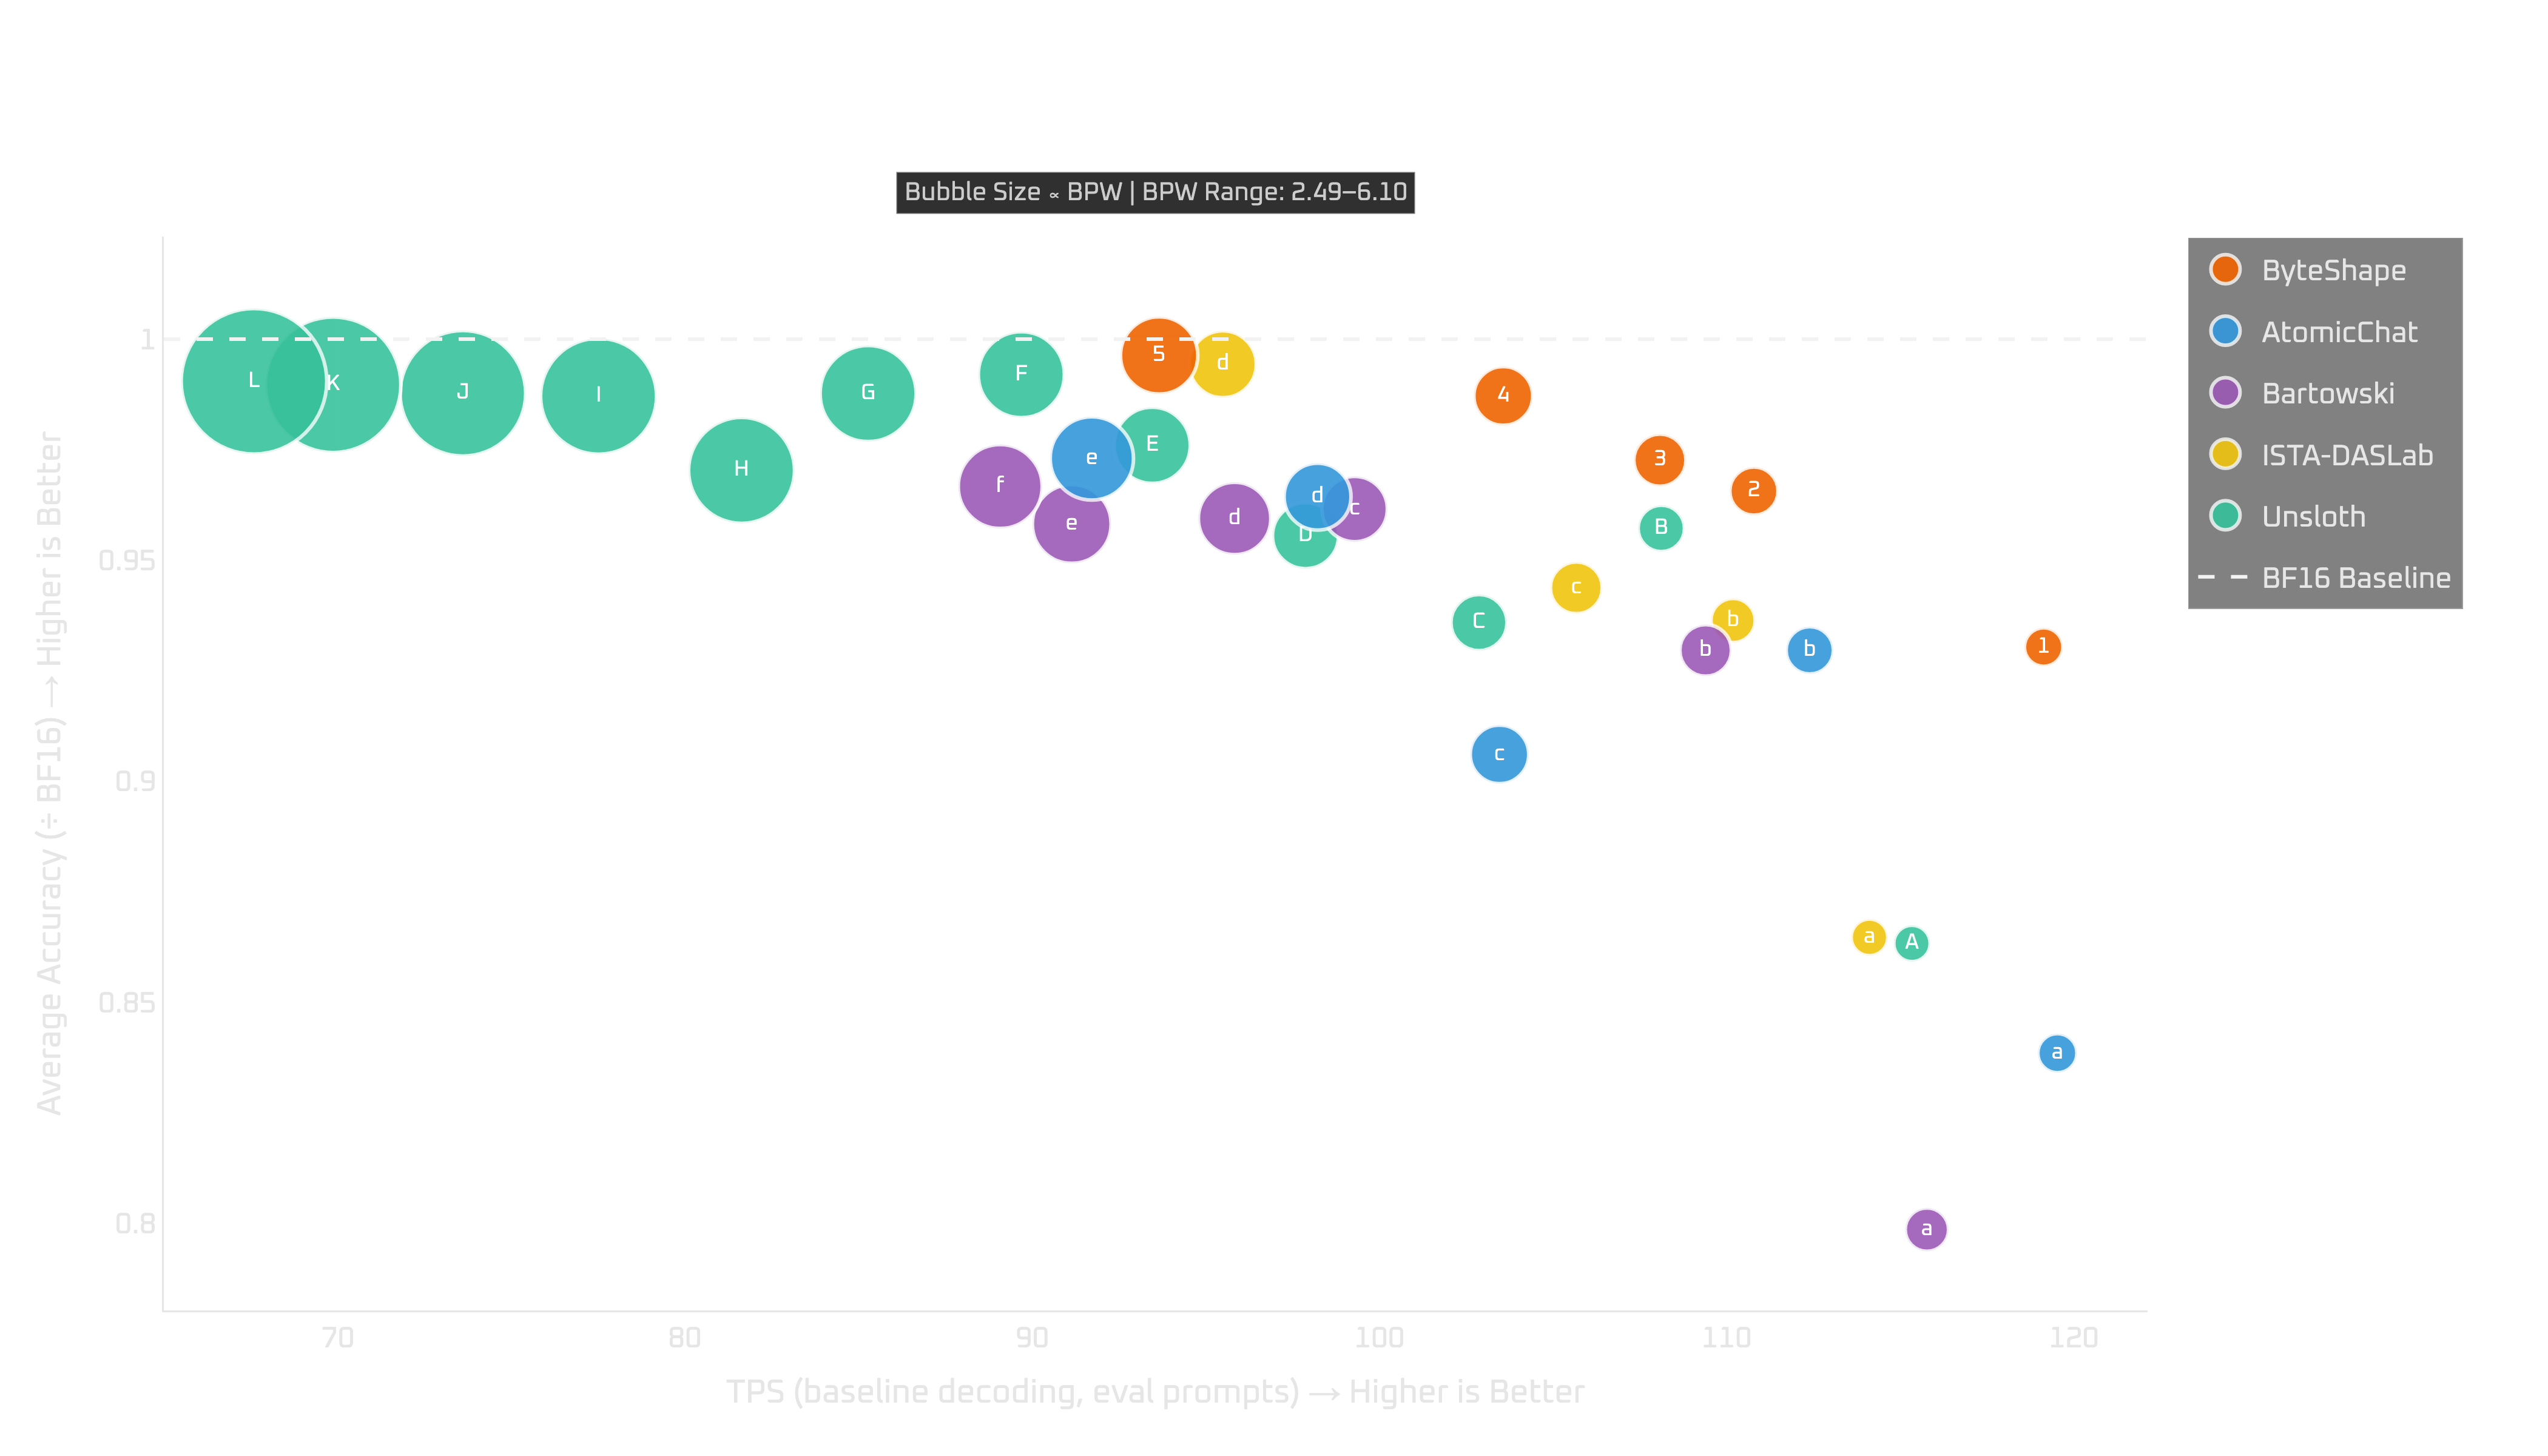
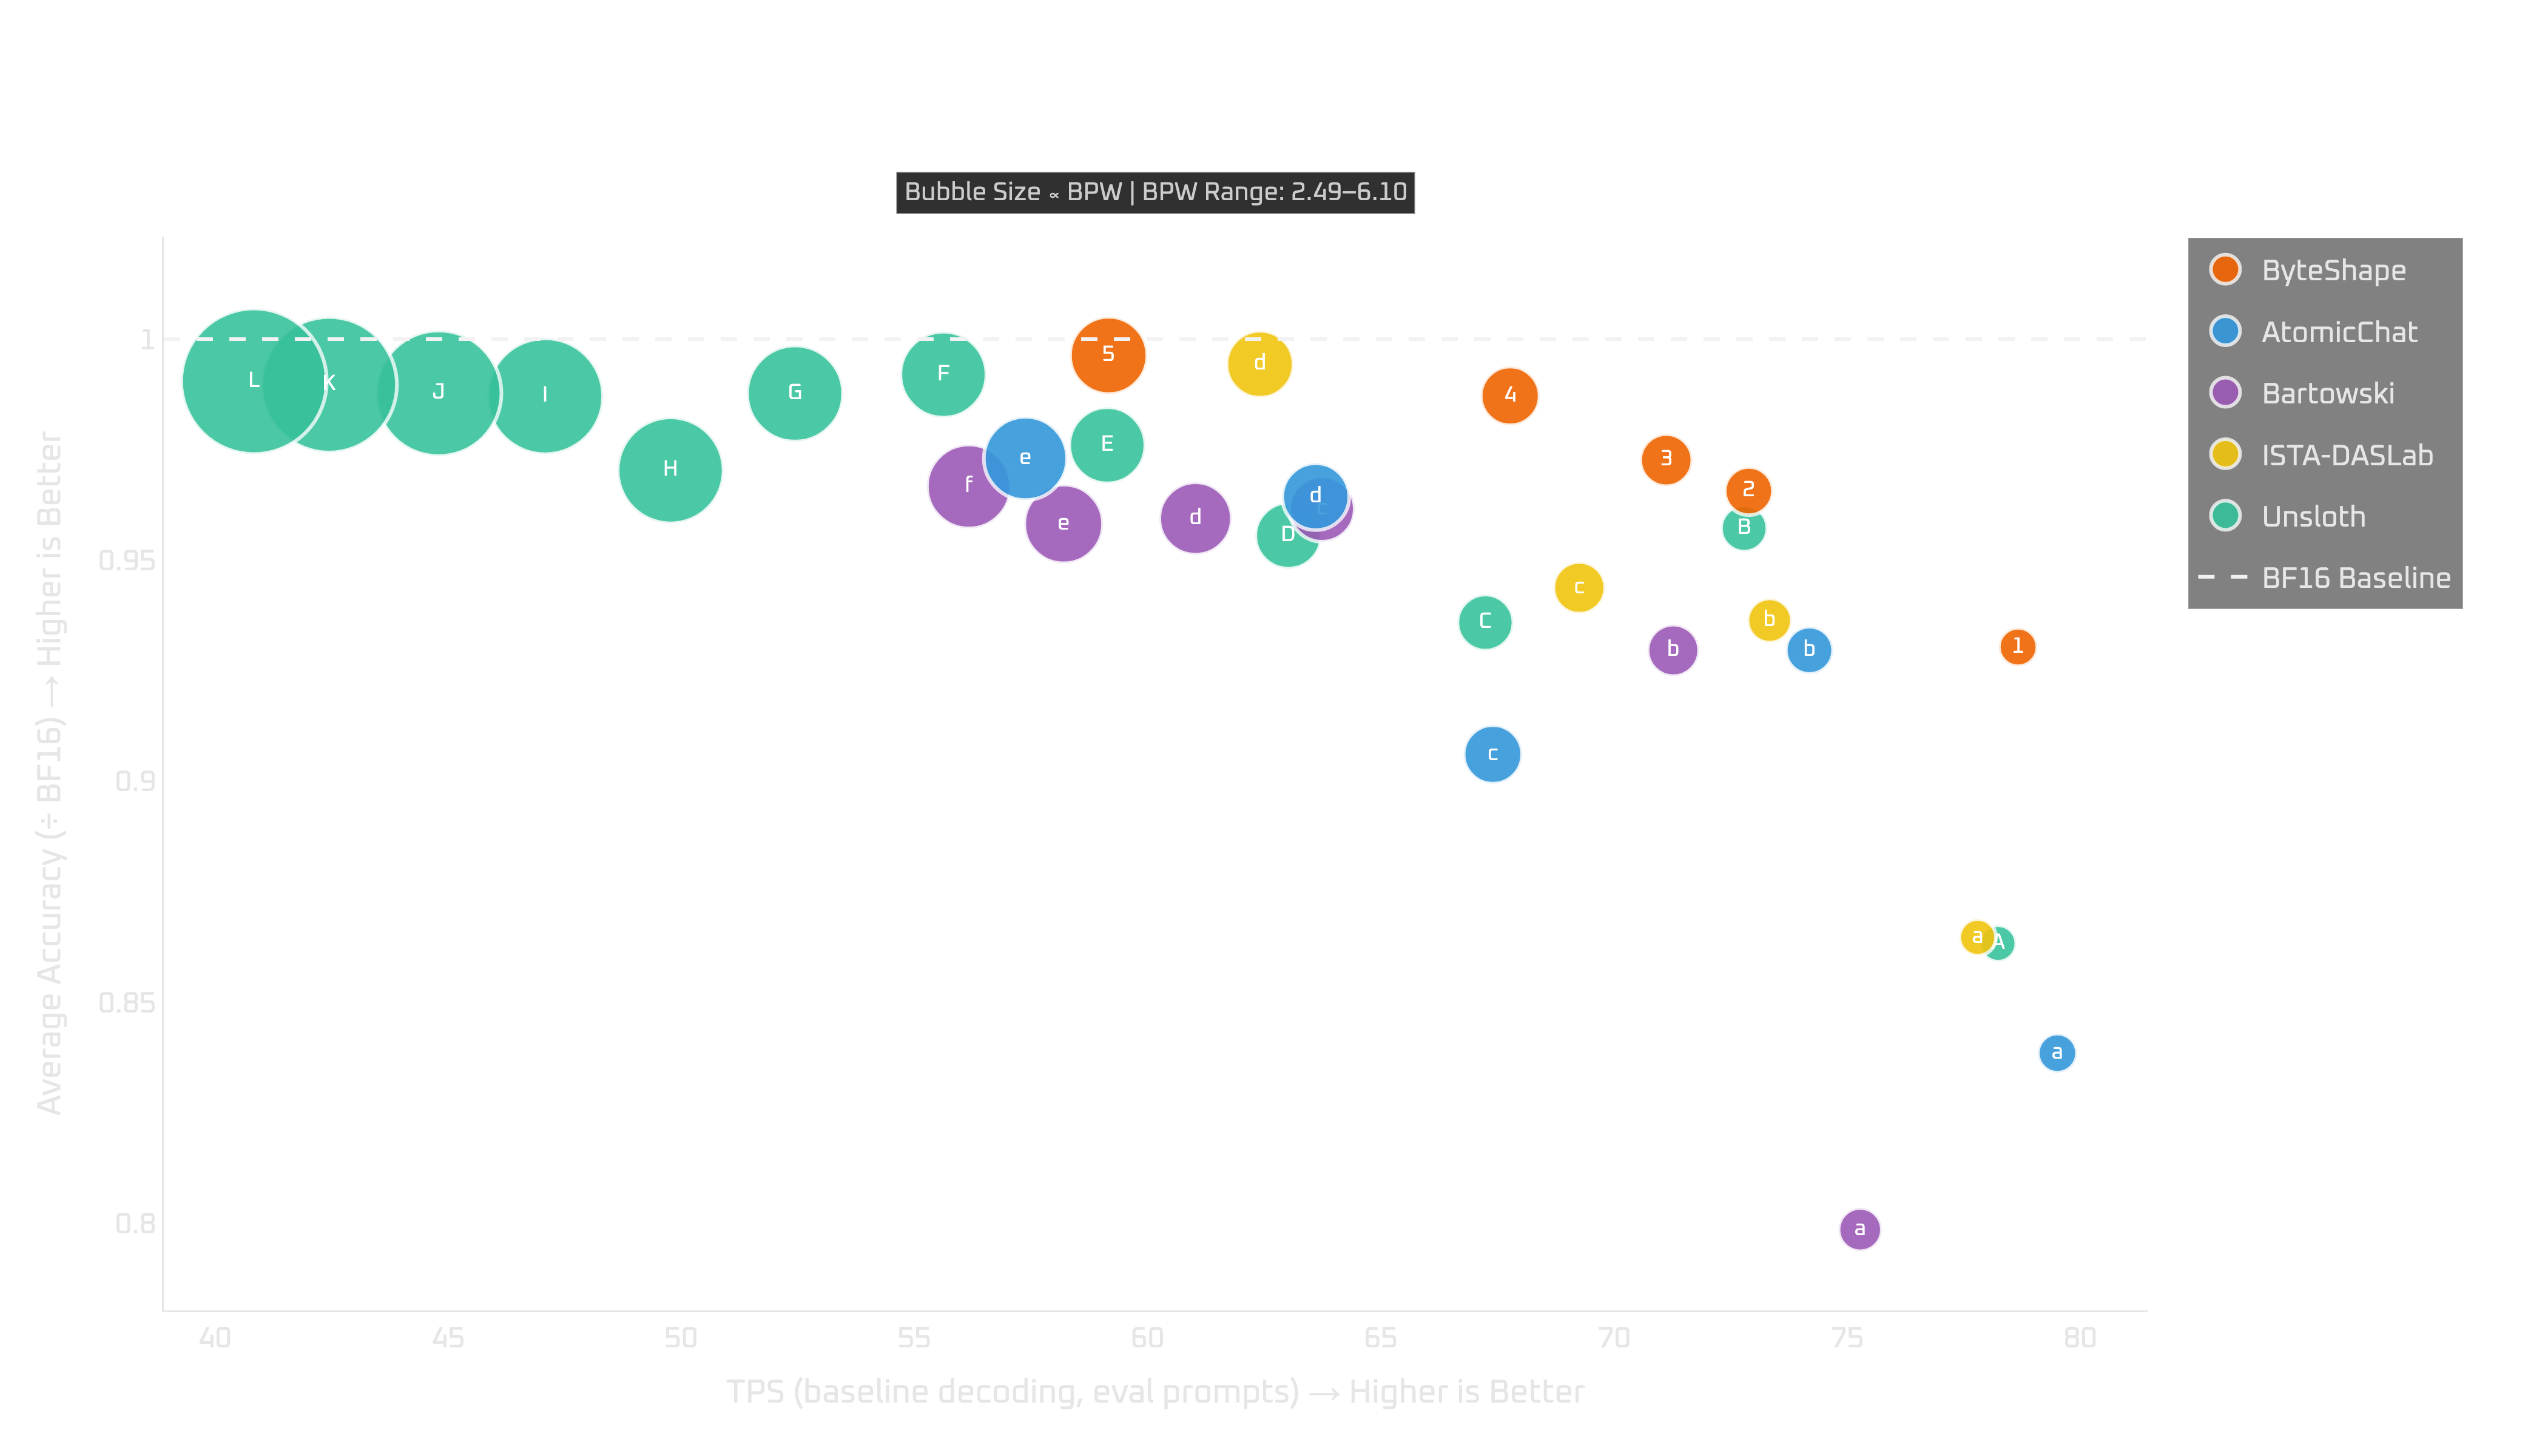
All 5 ShapeLearn fashions stay on the measured frontier, with GPU-5 attaining the very best mixture rating among the many plotted quants. Other groups additionally contribute aggressive factors. Notably, ISTA-DASLab’s glorious mannequin (the yellow “d” on the graph under) additionally sits on the frontier.
By “frontier,” we imply that no different plotted mannequin is each sooner and extra correct.
96 GB: RTX Pro 6000
RTX PRO 6000, the GPU with essentially the most reminiscence, lets us present the total vary of fashions examined.
Tap Show Legend under for mannequin particulars.
Hover over the bubbles, or click on Show Legend under, for mannequin particulars.
Show Legend
| # | Model | Acc | TPS | BPW |
|---|---|---|---|---|
| ByteShape | ||||
| GPU-1 | IQ2_XXS-2.56bpw | 0.9304 | 116.11 | 2.56 |
| GPU-2 | IQ3_XXS-2.88bpw | 0.9656 | 108.01 | 2.88 |
| GPU-3 | IQ3_XS-3.01bpw | 0.9726 | 105.44 | 3.01 |
| GPU-4 | IQ3_S-3.23bpw | 0.9872 | 101.11 | 3.23 |
| GPU-5 | IQ4_XS-3.84bpw | 0.9963 | 90.42 | 3.84 |
| Unsloth | ||||
| A | UD-IQ2_S | 0.8633 | 114.81 | 2.49 |
| B | UD-Q2_K_XL | 0.9572 | 106.95 | 2.82 |
| C | UD-IQ3_XXS | 0.9359 | 100.51 | 3.14 |
| D | UD-IQ3_S | 0.9555 | 95.53 | 3.47 |
| E | UD-Q3_K_XL | 0.9760 | 90.88 | 3.80 |
| F | UD-IQ4_XS | 0.9920 | 86.73 | 4.13 |
| G | UD-Q4_K_S | 0.9877 | 82.21 | 4.46 |
| H | UD-Q4_K_M | 0.9703 | 78.58 | 4.79 |
| I | UD-Q4_K_XL | 0.9871 | 74.75 | 5.12 |
| J | UD-Q5_K_S | 0.9878 | 71.00 | 5.44 |
| Okay | UD-Q5_K_M | 0.9897 | 67.71 | 5.77 |
| L | UD-Q5_K_XL | 0.9905 | 65.52 | 6.10 |
| ISTA-DASLab | ||||
| a | GSQ-RCO-IQ2_XS | 0.8647 | 112.77 | 2.50 |
| b | GSQ-RCO-IQ2_S | 0.9364 | 108.22 | 2.75 |
| c | GSQ-RCO-IQ3_XXS | 0.9438 | 103.39 | 3.00 |
| d | GSQ-RCO-IQ3_S | 0.9943 | 94.77 | 3.50 |
| Bartowski | ||||
| a | IQ2_XXS | 0.7986 | 112.21 | 2.72 |
| b | IQ2_S | 0.9296 | 106.33 | 2.99 |
| c | Q2_K | 0.9616 | 96.08 | 3.45 |
| d | IQ3_XXS | 0.9594 | 92.43 | 3.68 |
| e | IQ3_XS | 0.9582 | 88.36 | 3.89 |
| f | IQ3_M | 0.9667 | 86.17 | 4.06 |
| AtomicChat | ||||
| a | AD-IQ2_XXS | 0.8385 | 116.28 | 2.58 |
| b | AD-IQ2_XS | 0.9296 | 108.67 | 2.85 |
| c | AD-IQ2_S | 0.9061 | 100.28 | 3.22 |
| d | AD-IQ3_XXS | 0.9644 | 95.29 | 3.50 |
| e | AD-IQ3_S | 0.9730 | 88.52 | 4.04 |
GPU-5 is our default wherever you possibly can match it: it reaches 90.4 tok/s at 99.63% of the BF16 baseline.
32 GB: RTX 5090
The RTX 5090 tells an analogous story, resulting in the identical suggestions.
Tap Show Legend under for mannequin particulars.
Hover over the bubbles, or click on Show Legend under, for mannequin particulars.
Show Legend
| # | Model | Acc | TPS | BPW |
|---|---|---|---|---|
| ByteShape | ||||
| GPU-1 | IQ2_XXS-2.56bpw | 0.9304 | 119.13 | 2.56 |
| GPU-2 | IQ3_XXS-2.88bpw | 0.9656 | 110.78 | 2.88 |
| GPU-3 | IQ3_XS-3.01bpw | 0.9726 | 108.08 | 3.01 |
| GPU-4 | IQ3_S-3.23bpw | 0.9872 | 103.57 | 3.23 |
| GPU-5 | IQ4_XS-3.84bpw | 0.9963 | 93.66 | 3.84 |
| Unsloth | ||||
| A | UD-IQ2_S | 0.8633 | 115.34 | 2.49 |
| B | UD-Q2_K_XL | 0.9572 | 108.12 | 2.82 |
| C | UD-IQ3_XXS | 0.9359 | 102.87 | 3.14 |
| D | UD-IQ3_S | 0.9555 | 97.87 | 3.47 |
| E | UD-Q3_K_XL | 0.9760 | 93.46 | 3.80 |
| F | UD-IQ4_XS | 0.9920 | 89.69 | 4.13 |
| G | UD-Q4_K_S | 0.9877 | 85.28 | 4.46 |
| H | UD-Q4_K_M | 0.9703 | 81.63 | 4.79 |
| I | UD-Q4_K_XL | 0.9871 | 77.51 | 5.12 |
| J | UD-Q5_K_S | 0.9878 | 73.60 | 5.44 |
| Okay | UD-Q5_K_M | 0.9897 | 69.87 | 5.77 |
| L | UD-Q5_K_XL | 0.9905 | 67.59 | 6.10 |
| ISTA-DASLab | ||||
| a | GSQ-RCO-IQ2_XS | 0.8647 | 114.11 | 2.50 |
| b | GSQ-RCO-IQ2_S | 0.9364 | 110.19 | 2.75 |
| c | GSQ-RCO-IQ3_XXS | 0.9438 | 105.67 | 3.00 |
| d | GSQ-RCO-IQ3_S | 0.9943 | 95.49 | 3.50 |
| Bartowski | ||||
| a | IQ2_XXS | 0.7986 | 115.77 | 2.72 |
| b | IQ2_S | 0.9296 | 109.39 | 2.99 |
| c | Q2_K | 0.9616 | 99.29 | 3.45 |
| d | IQ3_XXS | 0.9594 | 95.83 | 3.68 |
| e | IQ3_XS | 0.9582 | 91.14 | 3.89 |
| f | IQ3_M | 0.9667 | 89.08 | 4.06 |
| AtomicChat | ||||
| a | AD-IQ2_XXS | 0.8385 | 119.53 | 2.58 |
| b | AD-IQ2_XS | 0.9296 | 112.39 | 2.85 |
| c | AD-IQ2_S | 0.9061 | 103.46 | 3.22 |
| d | AD-IQ3_XXS | 0.9644 | 98.22 | 3.50 |
| e | AD-IQ3_S | 0.9730 | 91.72 | 4.04 |
Once once more GPU-5 is our default selection, reaching 93.7 tok/s. Choose GPU-4 for barely extra context size or barely higher TPS.
24 GB: RTX 4090 and RTX 3090
Both 24 GB playing cards match all 5 ShapeLearn fashions. We plot them individually as a result of their throughput differs, however the ordering is similar on each.
RTX 4090
The RTX 4090 retains the identical sample: GPU-5 is the default, reaching 59.2 tok/s.
Tap Show Legend under for mannequin particulars.
Hover over the bubbles, or click on Show Legend under, for mannequin particulars.
Show Legend
| # | Model | Acc | TPS | BPW |
|---|---|---|---|---|
| ByteShape | ||||
| GPU-1 | IQ2_XXS-2.56bpw | 0.9304 | 78.67 | 2.56 |
| GPU-2 | IQ3_XXS-2.88bpw | 0.9656 | 72.89 | 2.88 |
| GPU-3 | IQ3_XS-3.01bpw | 0.9726 | 71.12 | 3.01 |
| GPU-4 | IQ3_S-3.23bpw | 0.9872 | 67.77 | 3.23 |
| GPU-5 | IQ4_XS-3.84bpw | 0.9963 | 59.16 | 3.84 |
| Unsloth | ||||
| A | UD-IQ2_S | 0.8633 | 78.23 | 2.49 |
| B | UD-Q2_K_XL | 0.9572 | 72.79 | 2.82 |
| C | UD-IQ3_XXS | 0.9359 | 67.24 | 3.14 |
| D | UD-IQ3_S | 0.9555 | 63.02 | 3.47 |
| E | UD-Q3_K_XL | 0.9760 | 59.13 | 3.80 |
| F | UD-IQ4_XS | 0.9920 | 55.62 | 4.13 |
| G | UD-Q4_K_S | 0.9877 | 52.44 | 4.46 |
| H | UD-Q4_K_M | 0.9703 | 49.77 | 4.79 |
| I | UD-Q4_K_XL | 0.9871 | 47.08 | 5.12 |
| J | UD-Q5_K_S | 0.9878 | 44.80 | 5.44 |
| Okay | UD-Q5_K_M | 0.9897 | 42.45 | 5.77 |
| L | UD-Q5_K_XL | 0.9905 | 40.84 | 6.10 |
| ISTA-DASLab | ||||
| a | GSQ-RCO-IQ2_XS | 0.8647 | 77.80 | 2.50 |
| b | GSQ-RCO-IQ2_S | 0.9364 | 73.34 | 2.75 |
| c | GSQ-RCO-IQ3_XXS | 0.9438 | 69.26 | 3.00 |
| d | GSQ-RCO-IQ3_S | 0.9943 | 62.41 | 3.50 |
| Bartowski | ||||
| a | IQ2_XXS | 0.7986 | 75.28 | 2.72 |
| b | IQ2_S | 0.9296 | 71.27 | 2.99 |
| c | Q2_K | 0.9616 | 63.74 | 3.45 |
| d | IQ3_XXS | 0.9594 | 61.03 | 3.68 |
| e | IQ3_XS | 0.9582 | 58.20 | 3.89 |
| f | IQ3_M | 0.9667 | 56.16 | 4.06 |
| AtomicChat | ||||
| a | AD-IQ2_XXS | 0.8385 | 79.51 | 2.58 |
| b | AD-IQ2_XS | 0.9296 | 74.19 | 2.85 |
| c | AD-IQ2_S | 0.9061 | 67.40 | 3.22 |
| d | AD-IQ3_XXS | 0.9644 | 63.60 | 3.50 |
| e | AD-IQ3_S | 0.9730 | 57.38 | 4.04 |
RTX 3090
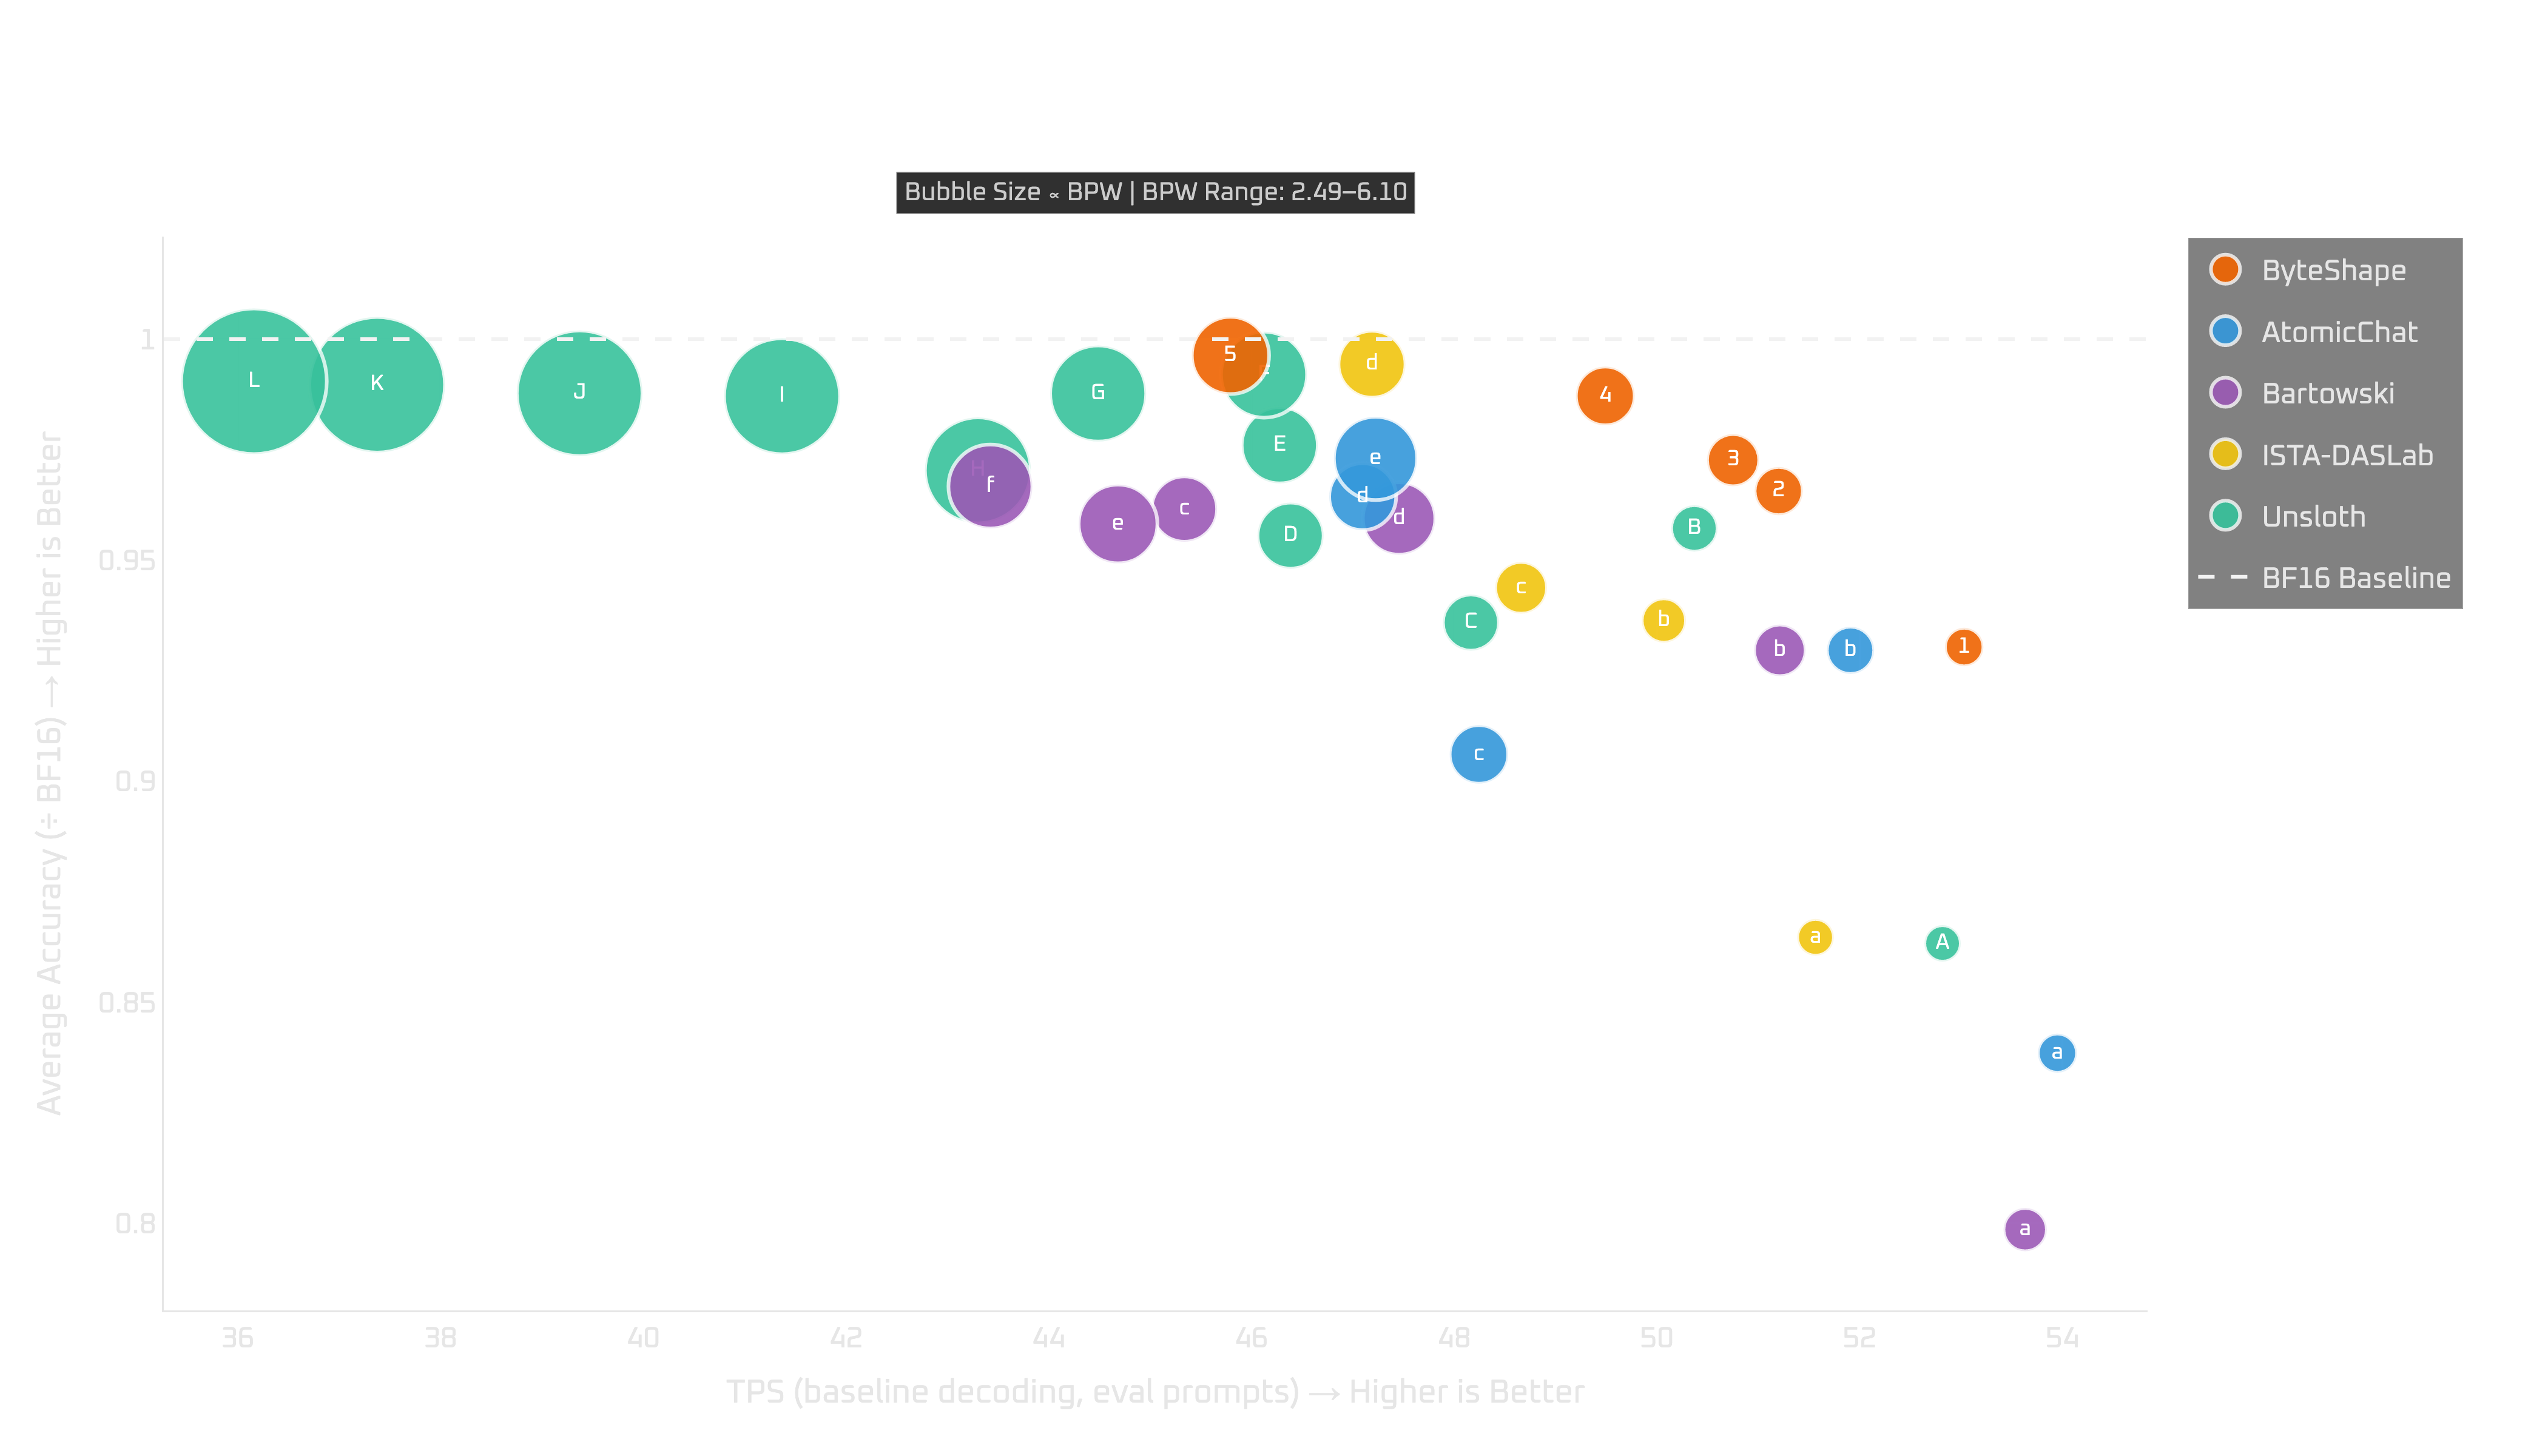
Older, however nonetheless quick in these measurements.
Tap Show Legend under for mannequin particulars.
Hover over the bubbles, or click on Show Legend under, for mannequin particulars.
Show Legend
| # | Model | Acc | TPS | BPW |
|---|---|---|---|---|
| ByteShape | ||||
| GPU-1 | IQ2_XXS-2.56bpw | 0.9304 | 53.03 | 2.56 |
| GPU-2 | IQ3_XXS-2.88bpw | 0.9656 | 51.20 | 2.88 |
| GPU-3 | IQ3_XS-3.01bpw | 0.9726 | 50.75 | 3.01 |
| GPU-4 | IQ3_S-3.23bpw | 0.9872 | 49.49 | 3.23 |
| GPU-5 | IQ4_XS-3.84bpw | 0.9963 | 45.79 | 3.84 |
| Unsloth | ||||
| A | UD-IQ2_S | 0.8633 | 52.82 | 2.49 |
| B | UD-Q2_K_XL | 0.9572 | 50.37 | 2.82 |
| C | UD-IQ3_XXS | 0.9359 | 48.16 | 3.14 |
| D | UD-IQ3_S | 0.9555 | 46.39 | 3.47 |
| E | UD-Q3_K_XL | 0.9760 | 46.28 | 3.80 |
| F | UD-IQ4_XS | 0.9920 | 46.12 | 4.13 |
| G | UD-Q4_K_S | 0.9877 | 44.49 | 4.46 |
| H | UD-Q4_K_M | 0.9703 | 43.30 | 4.79 |
| I | UD-Q4_K_XL | 0.9871 | 41.37 | 5.12 |
| J | UD-Q5_K_S | 0.9878 | 39.37 | 5.44 |
| Okay | UD-Q5_K_M | 0.9897 | 37.38 | 5.77 |
| L | UD-Q5_K_XL | 0.9905 | 36.16 | 6.10 |
| ISTA-DASLab | ||||
| a | GSQ-RCO-IQ2_XS | 0.8647 | 51.56 | 2.50 |
| b | GSQ-RCO-IQ2_S | 0.9364 | 50.07 | 2.75 |
| c | GSQ-RCO-IQ3_XXS | 0.9438 | 48.66 | 3.00 |
| d | GSQ-RCO-IQ3_S | 0.9943 | 47.19 | 3.50 |
| Bartowski | ||||
| a | IQ2_XXS | 0.7986 | 53.63 | 2.72 |
| b | IQ2_S | 0.9296 | 51.21 | 2.99 |
| c | Q2_K | 0.9616 | 45.34 | 3.45 |
| d | IQ3_XXS | 0.9594 | 47.46 | 3.68 |
| e | IQ3_XS | 0.9582 | 44.68 | 3.89 |
| f | IQ3_M | 0.9667 | 43.42 | 4.06 |
| AtomicChat | ||||
| a | AD-IQ2_XXS | 0.8385 | 53.95 | 2.58 |
| b | AD-IQ2_XS | 0.9296 | 51.91 | 2.85 |
| c | AD-IQ2_S | 0.9061 | 48.24 | 3.22 |
| d | AD-IQ3_XXS | 0.9644 | 47.10 | 3.50 |
| e | AD-IQ3_S | 0.9730 | 47.22 | 4.04 |
GPU-4 reaches 49.5 tok/s, in contrast with 45.8 tok/s for GPU-5. Moving to the bigger mannequin prices about 7.5% in throughput, whereas the mixture rating rises from 98.72% to 99.63% of BF16. That makes GPU-5 the default right here as nicely.
16 GB: RTX 4080 and RTX 5060 Ti
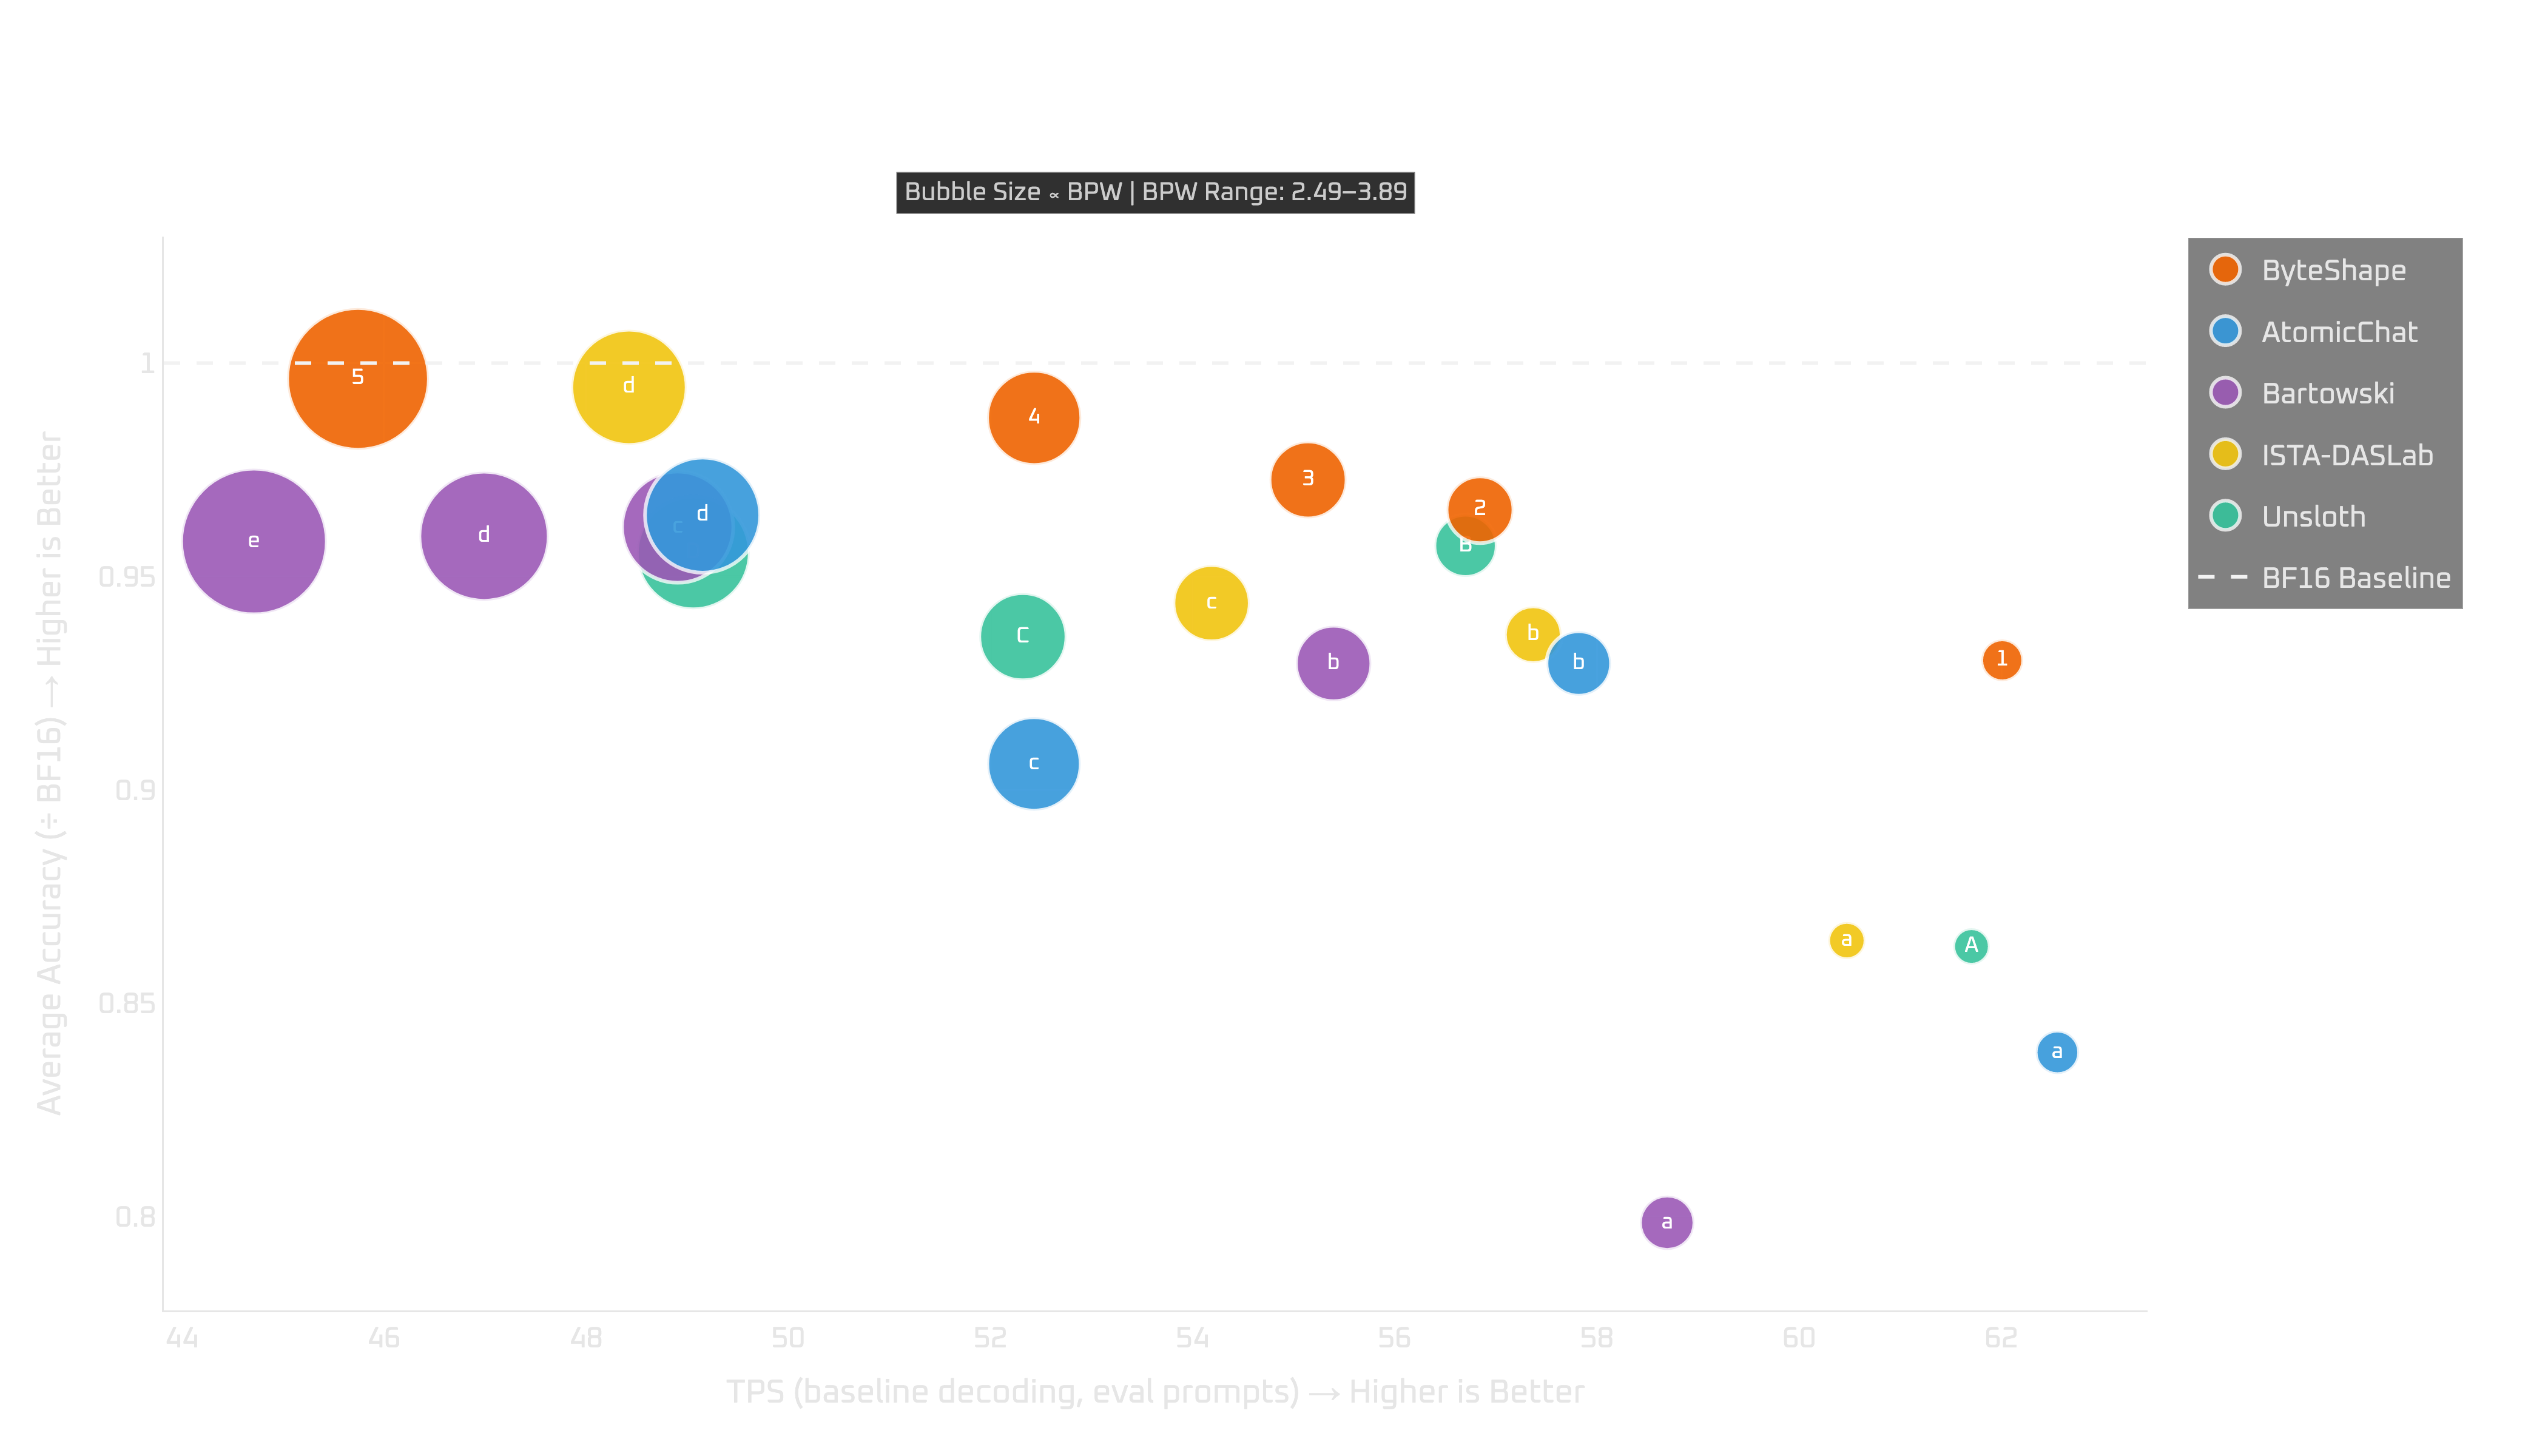
With a tighter VRAM price range, the pragmatic selection is to go away room for the context you want, not simply the mannequin weights. These plots include fewer competing configurations, however all 5 ShapeLearn fashions are represented.
RTX 4080
On the RTX 4080, GPU-4 reaches 52.4 tok/s, whereas GPU-5 reaches 45.7 tok/s.
Tap Show Legend under for mannequin particulars.
Hover over the bubbles, or click on Show Legend under, for mannequin particulars.
Show Legend
| # | Model | Acc | TPS | BPW |
|---|---|---|---|---|
| ByteShape | ||||
| GPU-1 | IQ2_XXS-2.56bpw | 0.9304 | 62.01 | 2.56 |
| GPU-2 | IQ3_XXS-2.88bpw | 0.9656 | 56.84 | 2.88 |
| GPU-3 | IQ3_XS-3.01bpw | 0.9726 | 55.14 | 3.01 |
| GPU-4 | IQ3_S-3.23bpw | 0.9872 | 52.43 | 3.23 |
| GPU-5 | IQ4_XS-3.84bpw | 0.9963 | 45.74 | 3.84 |
| Unsloth | ||||
| A | UD-IQ2_S | 0.8633 | 61.70 | 2.49 |
| B | UD-Q2_K_XL | 0.9572 | 56.70 | 2.82 |
| C | UD-IQ3_XXS | 0.9359 | 52.32 | 3.14 |
| D | UD-IQ3_S | 0.9555 | 49.06 | 3.47 |
| ISTA-DASLab | ||||
| a | GSQ-RCO-IQ2_XS | 0.8647 | 60.47 | 2.50 |
| b | GSQ-RCO-IQ2_S | 0.9364 | 57.37 | 2.75 |
| c | GSQ-RCO-IQ3_XXS | 0.9438 | 54.19 | 3.00 |
| d | GSQ-RCO-IQ3_S | 0.9943 | 48.42 | 3.50 |
| Bartowski | ||||
| a | IQ2_XXS | 0.7986 | 58.69 | 2.72 |
| b | IQ2_S | 0.9296 | 55.39 | 2.99 |
| c | Q2_K | 0.9616 | 48.91 | 3.45 |
| d | IQ3_XXS | 0.9594 | 46.99 | 3.68 |
| e | IQ3_XS | 0.9582 | 44.71 | 3.89 |
| AtomicChat | ||||
| a | AD-IQ2_XXS | 0.8385 | 62.55 | 2.58 |
| b | AD-IQ2_XS | 0.9296 | 57.82 | 2.85 |
| c | AD-IQ2_S | 0.9061 | 52.43 | 3.22 |
| d | AD-IQ3_XXS | 0.9644 | 49.15 | 3.50 |
RTX 5060 Ti
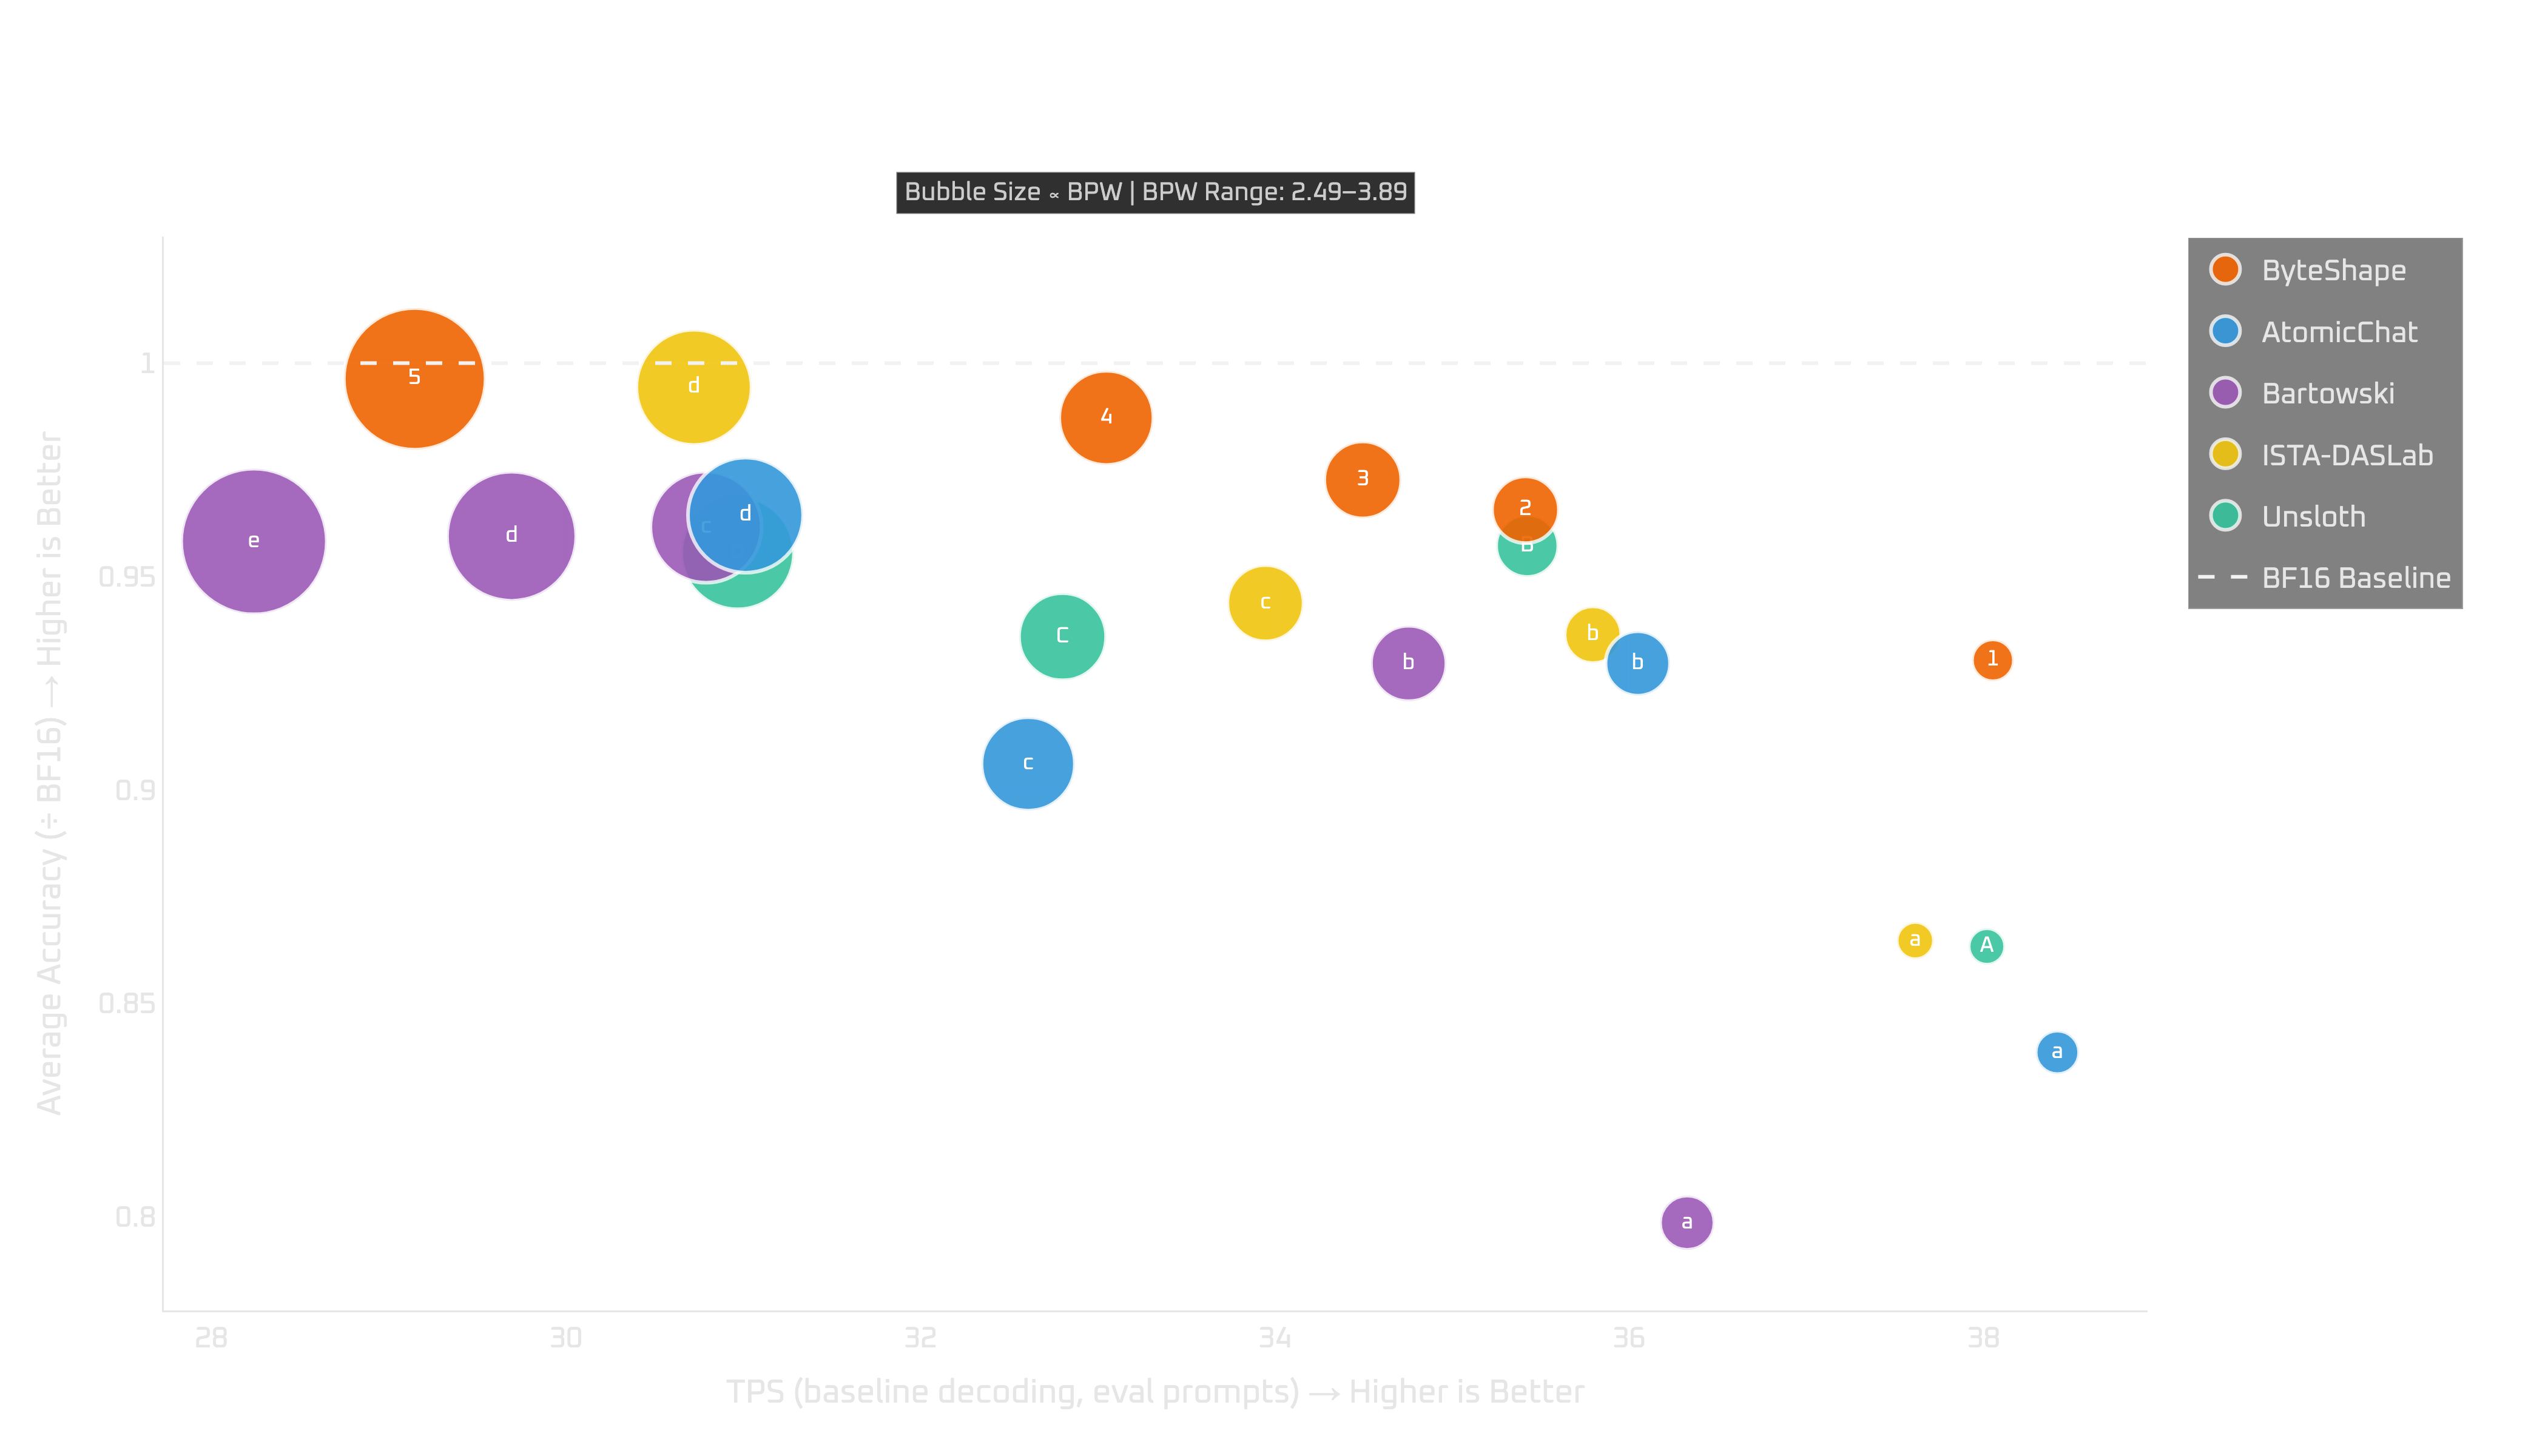
On the RTX 5060 Ti, the corresponding figures are 33.1 tok/s and 29.1 tok/s.
Tap Show Legend under for mannequin particulars.
Hover over the bubbles, or click on Show Legend under, for mannequin particulars.
Show Legend
| # | Model | Acc | TPS | BPW |
|---|---|---|---|---|
| ByteShape | ||||
| GPU-1 | IQ2_XXS-2.56bpw | 0.9304 | 38.05 | 2.56 |
| GPU-2 | IQ3_XXS-2.88bpw | 0.9656 | 35.41 | 2.88 |
| GPU-3 | IQ3_XS-3.01bpw | 0.9726 | 34.50 | 3.01 |
| GPU-4 | IQ3_S-3.23bpw | 0.9872 | 33.05 | 3.23 |
| GPU-5 | IQ4_XS-3.84bpw | 0.9963 | 29.15 | 3.84 |
| Unsloth | ||||
| A | UD-IQ2_S | 0.8633 | 38.02 | 2.49 |
| B | UD-Q2_K_XL | 0.9572 | 35.42 | 2.82 |
| C | UD-IQ3_XXS | 0.9359 | 32.80 | 3.14 |
| D | UD-IQ3_S | 0.9555 | 30.97 | 3.47 |
| ISTA-DASLab | ||||
| a | GSQ-RCO-IQ2_XS | 0.8647 | 37.62 | 2.50 |
| b | GSQ-RCO-IQ2_S | 0.9364 | 35.80 | 2.75 |
| c | GSQ-RCO-IQ3_XXS | 0.9438 | 33.95 | 3.00 |
| d | GSQ-RCO-IQ3_S | 0.9943 | 30.72 | 3.50 |
| Bartowski | ||||
| a | IQ2_XXS | 0.7986 | 36.33 | 2.72 |
| b | IQ2_S | 0.9296 | 34.76 | 2.99 |
| c | Q2_K | 0.9616 | 30.79 | 3.45 |
| d | IQ3_XXS | 0.9594 | 29.69 | 3.68 |
| e | IQ3_XS | 0.9582 | 28.24 | 3.89 |
| AtomicChat | ||||
| a | AD-IQ2_XXS | 0.8385 | 38.42 | 2.58 |
| b | AD-IQ2_XS | 0.9296 | 36.05 | 2.85 |
| c | AD-IQ2_S | 0.9061 | 32.61 | 3.22 |
| d | AD-IQ3_XXS | 0.9644 | 31.01 | 3.50 |
GPU-5 stays the default on each playing cards when the mannequin, KV cache, and runtime buffers match inside your reminiscence price range. When they don’t, GPU-4 remains to be very aggressive: virtually 99% of BF16 at a a lot smaller dimension, and sooner. A mannequin showing in these measurements doesn’t set up that each context size or serving configuration will match.
ShapeLearn-Lite, looking back
ShapeLearn-Lite makes use of a smaller optimization price range than full ShapeLearn. It allow us to get Qwen 3.8 27B onto 12 GB to 24 GB GPUs inside a couple of days.
We launched after focused sanity checks and began the total analysis afterwards. The full ShapeLearn fashions had been prepared earlier than the benchmarking was completed. Evaluating each units, together with the competing fashions, is what took more often than not.
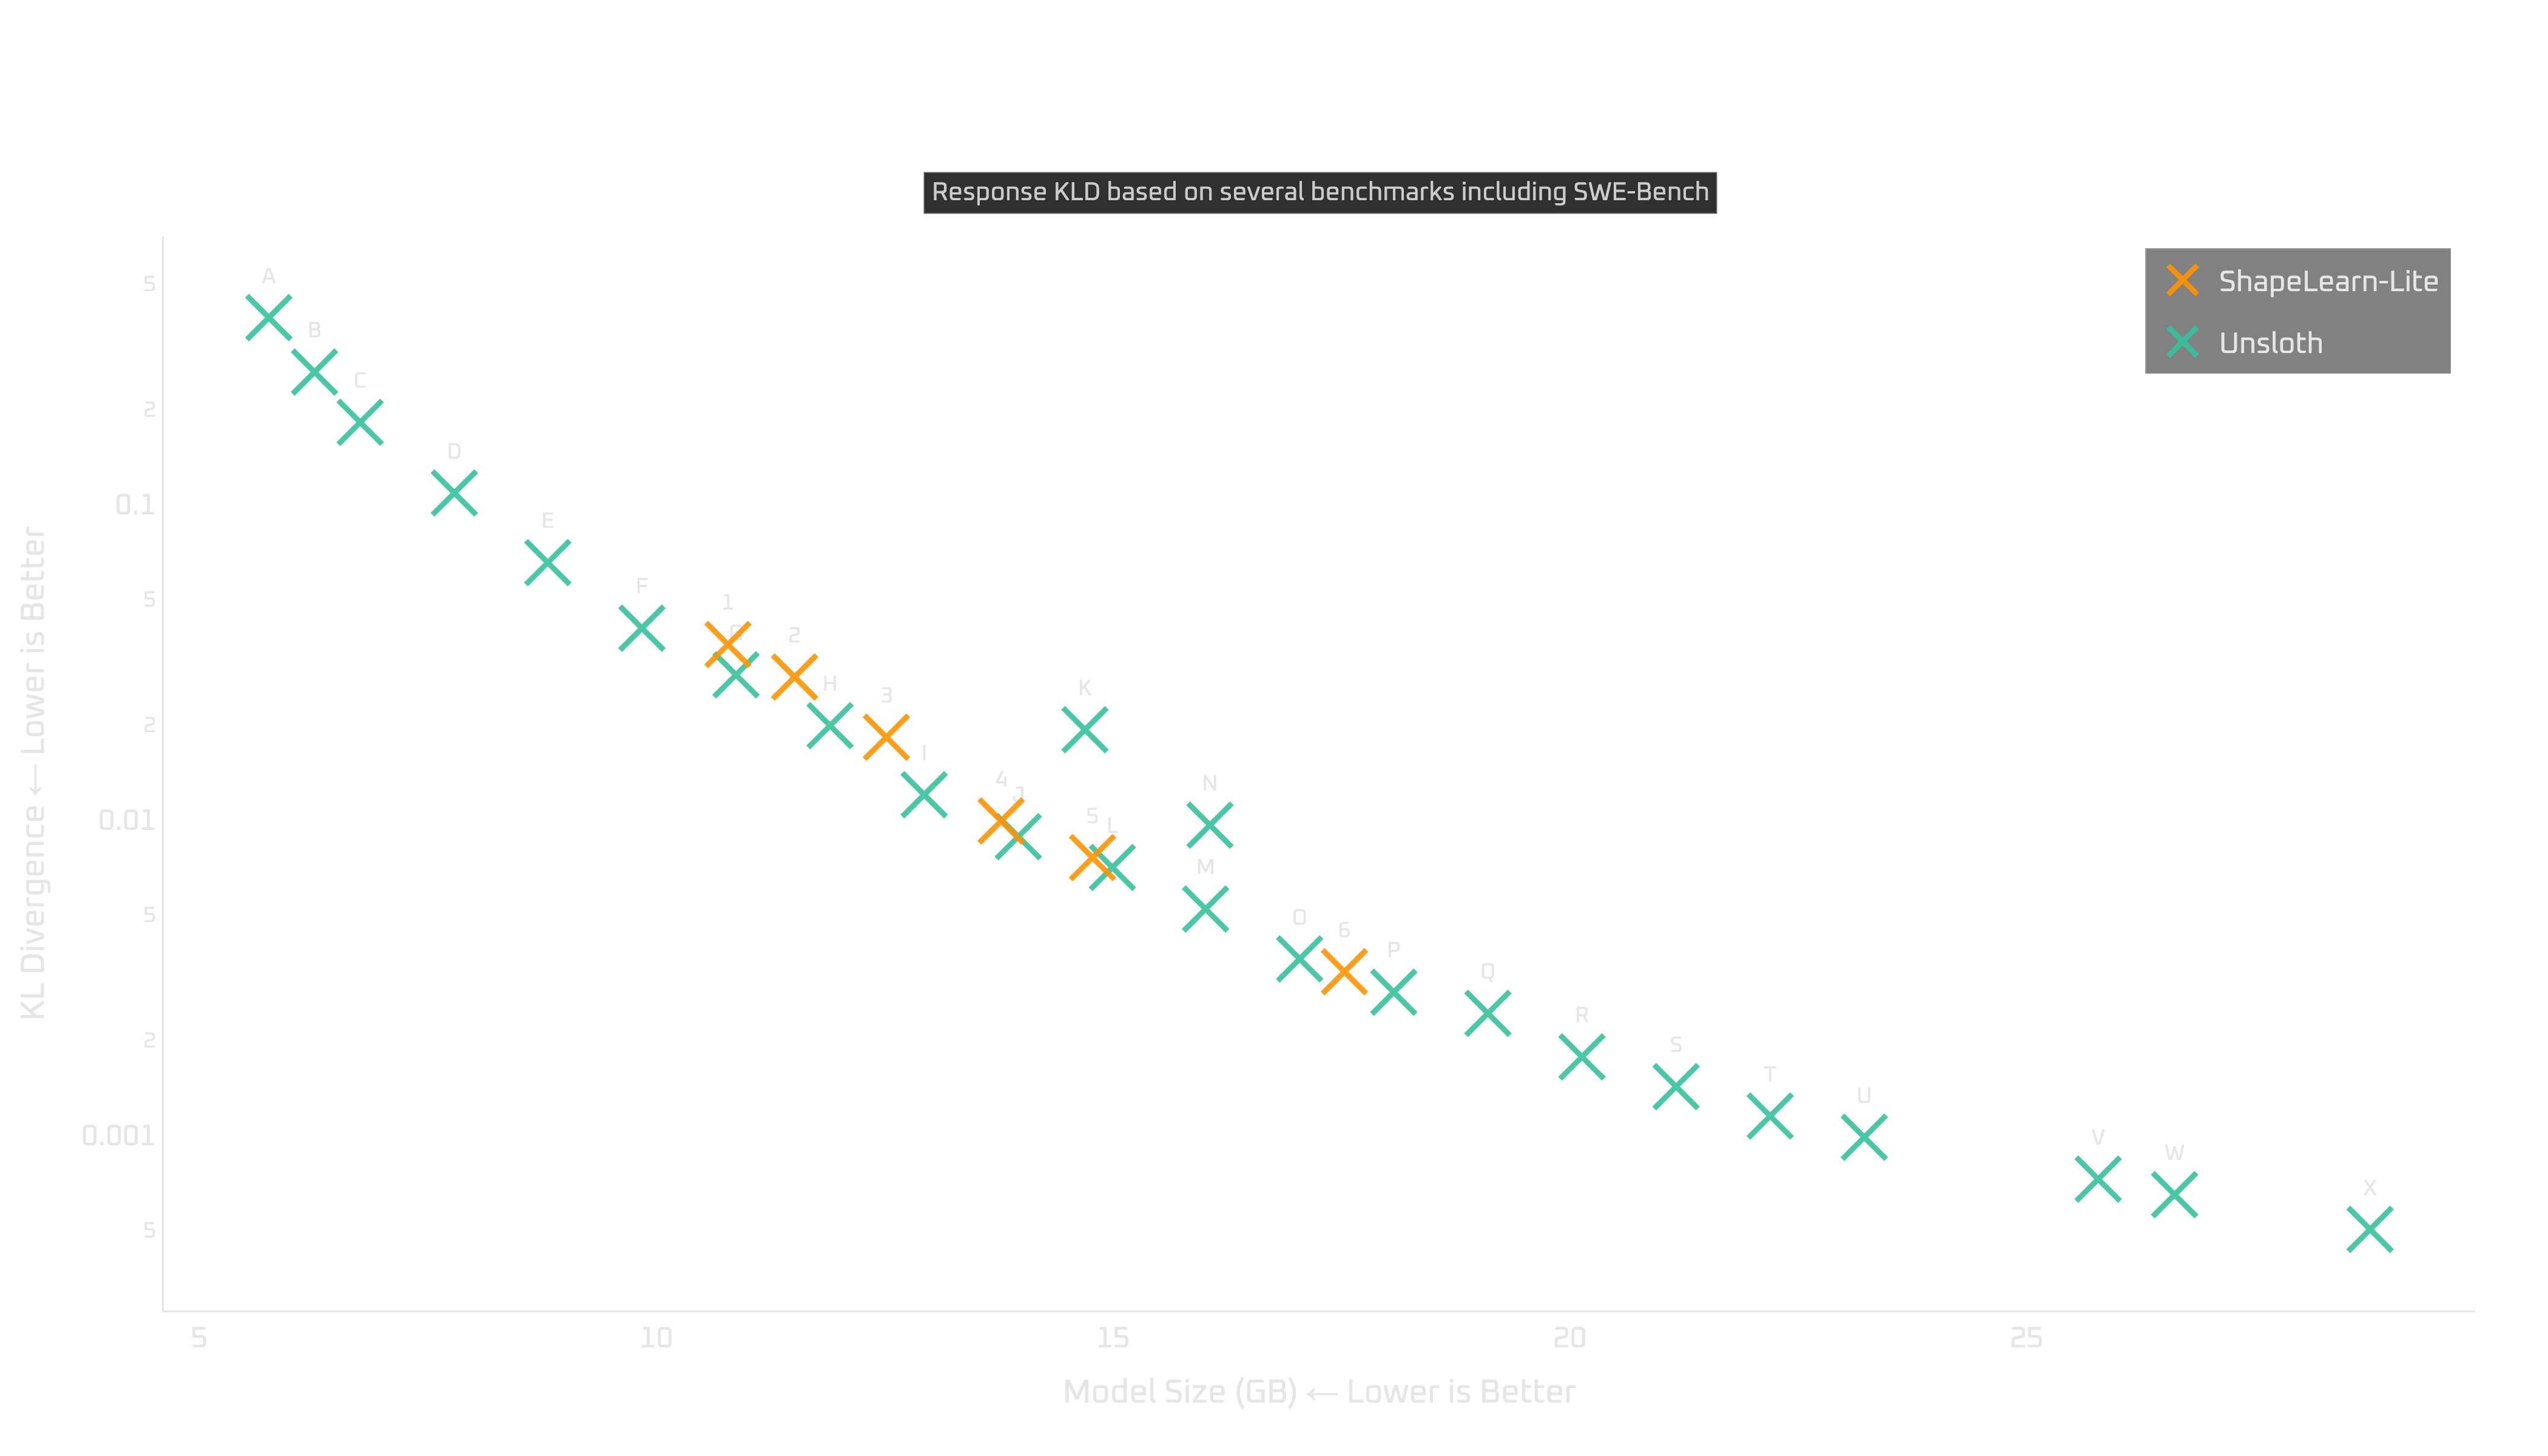
Then Unsloth launched its Dynamic v3 fashions. At comparable sizes, a number of had decrease KLD than Lite in our measurements. On KLD alone, Lite seemed much less aggressive.
KLD seemed decisive
KLD measures divergence between a quantized mannequin’s predicted token distributions and the BF16 reference underneath a selected analysis setup. It is helpful for diagnosing substantial modifications, however decrease divergence doesn’t robotically imply higher job efficiency.
We measure KLD on a dataset of about 5 million tokens of immediate and response pairs, drawn from a number of benchmarks, together with long-context and agentic duties. We additionally modified how KLD is computed, in order that it’s nearer to what we count on KLD to measure:
- KLD is measured on response tokens solely, not on immediate tokens. We don’t wish to measure how nicely a mannequin can generate prompts.
- KLD solely considers the tokens which have an opportunity of being sampled throughout era, the top-20, top-40, or top-60 tokens at every place. The tail tokens by no means get sampled, so they don’t contribute.
- Requests have clear boundaries. Each immediate and response pair is scored as its personal request, not as a part of one lengthy concatenated stream.
Tap Show Legend under for mannequin particulars.
Hover over the bubbles, or click on Show Legend under, for mannequin particulars.
Show Legend
| # | Model | KLD | Size (GB) | BPW |
|---|---|---|---|---|
| ShapeLearn-Lite | ||||
| Lite-1 | IQ3_S-3.44bpw | 0.035875 | 10.79 | 3.44 |
| Lite-2 | IQ4_XS-3.67bpw | 0.028296 | 11.51 | 3.68 |
| Lite-3 | IQ4_XS-4.00bpw | 0.018249 | 12.52 | 4.00 |
| Lite-4 | IQ4_XS-4.40bpw | 0.009901 | 13.78 | 4.40 |
| Lite-5 | Q5_K_S-4.72bpw | 0.007578 | 14.78 | 4.72 |
| Lite-6 | Q5_K_M-5.60bpw | 0.003297 | 17.53 | 5.60 |
| Unsloth | ||||
| i | UD-IQ1_S | 0.389550 | 5.76 | 1.84 |
| ii | UD-IQ1_M | 0.261876 | 6.26 | 2.00 |
| iii | UD-IQ2_XXS | 0.181493 | 6.76 | 2.16 |
| iv | UD-IQ2_S | 0.108374 | 7.79 | 2.49 |
| v | UD-Q2_K_XL | 0.065200 | 8.81 | 2.81 |
| vi | UD-IQ3_XXS | 0.040407 | 9.84 | 3.14 |
| vii | UD-IQ3_S | 0.028759 | 10.87 | 3.47 |
| viii | UD-Q3_K_XL | 0.019844 | 11.90 | 3.80 |
| ix | UD-IQ4_XS | 0.011992 | 12.93 | 4.13 |
| x | UD-Q4_K_S | 0.008827 | 13.96 | 4.46 |
| xi | Q4_0 | 0.019264 | 14.69 | 4.69 |
| xii | UD-Q4_K_M | 0.007054 | 14.99 | 4.79 |
| xiii | UD-Q4_K_XL | 0.005210 | 16.01 | 5.11 |
| xiv | Q4_1 | 0.009603 | 16.06 | 5.13 |
| xv | UD-Q5_K_S | 0.003619 | 17.04 | 5.44 |
| xvi | UD-Q5_K_M | 0.002839 | 18.07 | 5.77 |
| xvii | UD-Q5_K_XL | 0.002432 | 19.10 | 6.10 |
| xviii | UD-Q6_K | 0.001771 | 20.13 | 6.43 |
| xix | UD-Q6_K_M | 0.001426 | 21.16 | 6.76 |
| xx | UD-Q6_K_L | 0.001150 | 22.19 | 7.09 |
| xxi | UD-Q6_K_XL | 0.000985 | 23.22 | 7.42 |
| xxii | UD-Q8_K_L | 0.000726 | 25.78 | 8.23 |
| xxiii | Q8_0 | 0.000648 | 26.62 | 8.50 |
| xxiv | UD-Q8_K_XL | 0.000503 | 28.76 | 9.19 |
For instance, Unsloth’s UD-IQ3_S (vii) has about 20% decrease KLD than the equally sized smallest Lite mannequin (Lite-1): 0.028759 versus 0.035875. Yet its mixture benchmark rating is decrease: 95.55% versus 97.33% of BF16.
If decrease KLD had been adequate to rank these fashions by job efficiency, the benchmark ordering ought to have adopted it.
It didn’t.
The level is just not that KLD is ineffective. It is {that a} constancy rating is just not a task-performance rating. This is the excellence explored in our KLD evaluation blog. Our related paper on KLD and quantization fidelity metrics was additionally not too long ago accepted to the EMNLP Industry Track.
Lite held up
Naturally, we made extra plots.
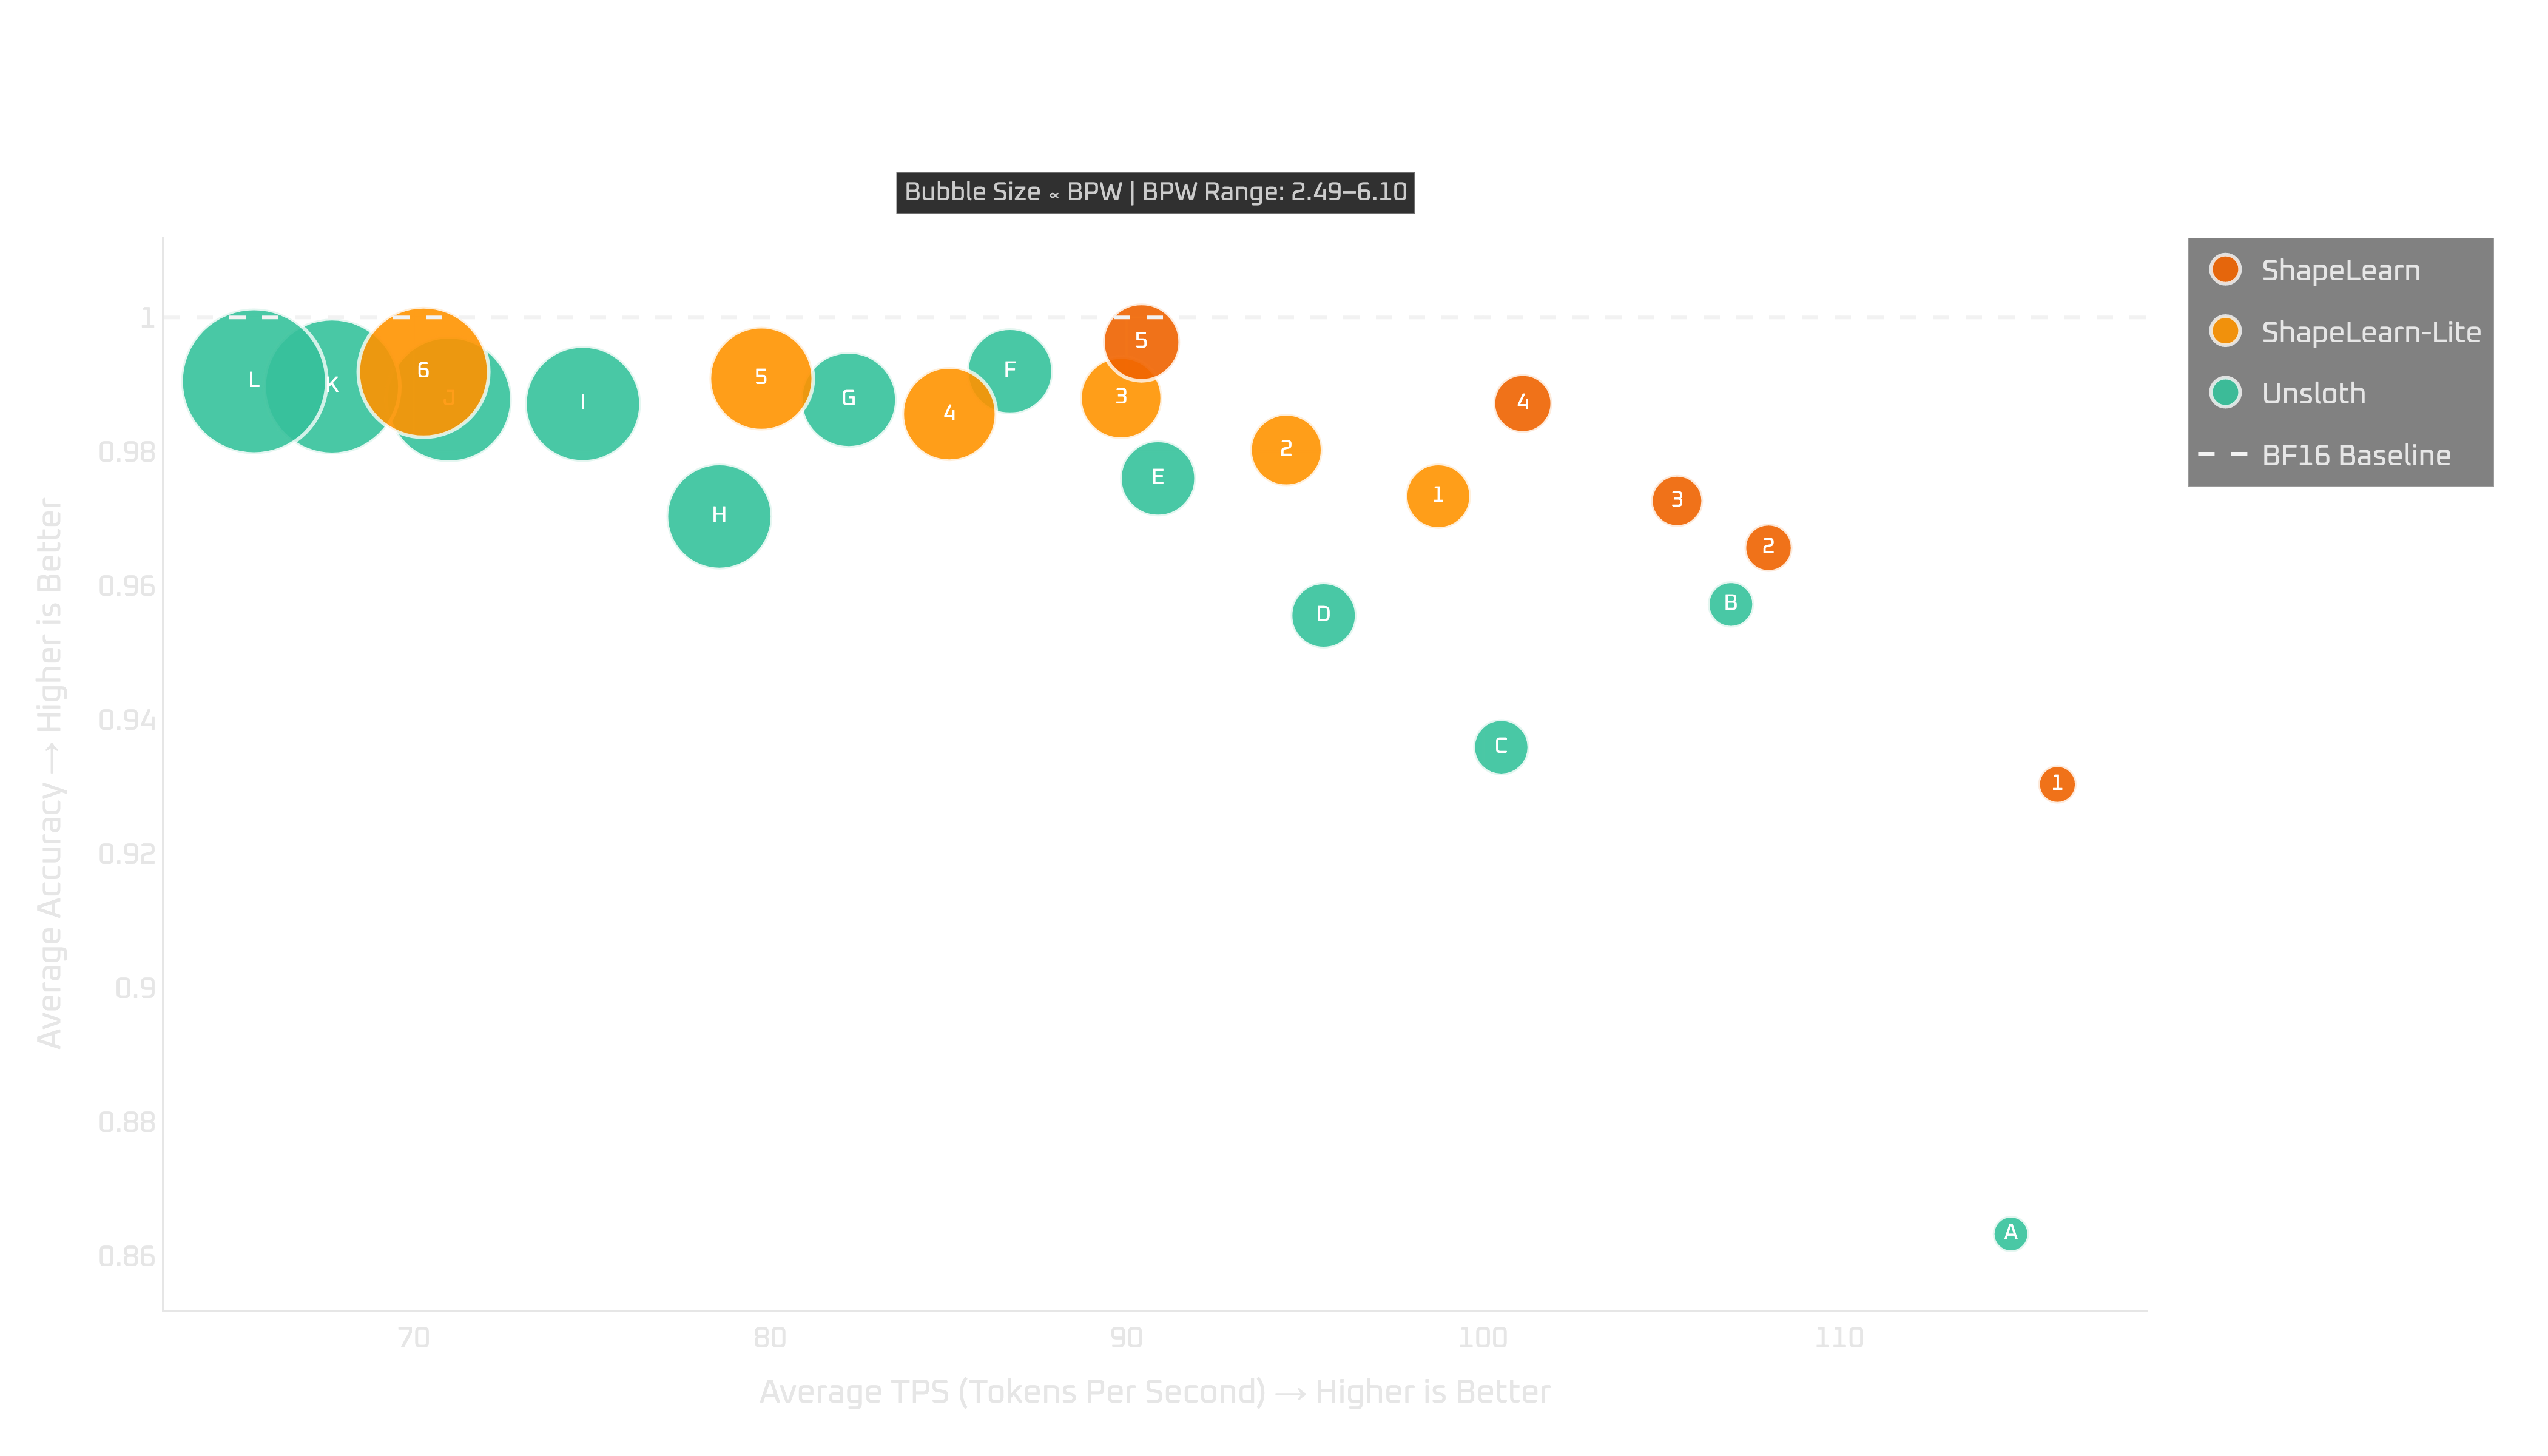
Here, we present the RTX Pro 6000 as a result of it may possibly accommodate the total comparability. Each mannequin’s benchmark rating is reused throughout the GPU plots; the measured throughput and the set of displayed fashions change.
Tap Show Legend under for mannequin particulars.
Hover over the bubbles, or click on Show Legend under, for mannequin particulars.
Show Legend
| # | Model | Acc | TPS | BPW |
|---|---|---|---|---|
| ShapeLearn (this launch) | ||||
| GPU-1 | IQ2_XXS-2.56bpw | 0.9304 | 116.11 | 2.56 |
| GPU-2 | IQ3_XXS-2.88bpw | 0.9656 | 108.01 | 2.88 |
| GPU-3 | IQ3_XS-3.01bpw | 0.9726 | 105.44 | 3.01 |
| GPU-4 | IQ3_S-3.23bpw | 0.9872 | 101.11 | 3.23 |
| GPU-5 | IQ4_XS-3.84bpw | 0.9963 | 90.42 | 3.84 |
| ShapeLearn-Lite | ||||
| Lite-1 | IQ3_S-3.44bpw | 0.9733 | 98.74 | 3.45 |
| Lite-2 | IQ4_XS-3.67bpw | 0.9802 | 94.48 | 3.68 |
| Lite-3 | IQ4_XS-4.00bpw | 0.9880 | 89.85 | 4.00 |
| Lite-4 | IQ4_XS-4.40bpw | 0.9856 | 85.03 | 4.40 |
| Lite-5 | Q5_K_S-4.72bpw | 0.9909 | 79.75 | 4.72 |
| Lite-6 | Q5_K_M-5.60bpw | 0.9919 | 70.28 | 5.60 |
| Unsloth | ||||
| A | UD-IQ2_S | 0.8633 | 114.81 | 2.49 |
| B | UD-Q2_K_XL | 0.9572 | 106.95 | 2.82 |
| C | UD-IQ3_XXS | 0.9359 | 100.51 | 3.14 |
| D | UD-IQ3_S | 0.9555 | 95.53 | 3.47 |
| E | UD-Q3_K_XL | 0.9760 | 90.88 | 3.80 |
| F | UD-IQ4_XS | 0.9920 | 86.73 | 4.13 |
| G | UD-Q4_K_S | 0.9877 | 82.21 | 4.46 |
| H | UD-Q4_K_M | 0.9703 | 78.58 | 4.79 |
| I | UD-Q4_K_XL | 0.9871 | 74.75 | 5.12 |
| J | UD-Q5_K_S | 0.9878 | 71.00 | 5.44 |
| Okay | UD-Q5_K_M | 0.9897 | 67.71 | 5.77 |
| L | UD-Q5_K_XL | 0.9905 | 65.52 | 6.10 |
Leaving the total ShapeLearn fashions apart for a second, three of the six ShapeLearn-Lite fashions sit on the Lite-versus-Unsloth frontier: the three smallest Lite fashions, the lighter orange bubbles labelled 1-3.
Of the twelve Unsloth v3 fashions proven, three additionally sit on that frontier: UD-IQ2_S (A), UD-Q2_K_XL (B), and UD-IQ4_XS (F). UD-IQ4_XS (F) is a robust higher-quality level, whereas Lite earns its locations in the midst of the vary.
Add the 5 full ShapeLearn fashions again in (the darker orange bubbles), and so they take over the complete frontier.
Lite was by no means meant to be the ultimate consequence. It nonetheless held its personal the place it mattered.
Speculative Decoding
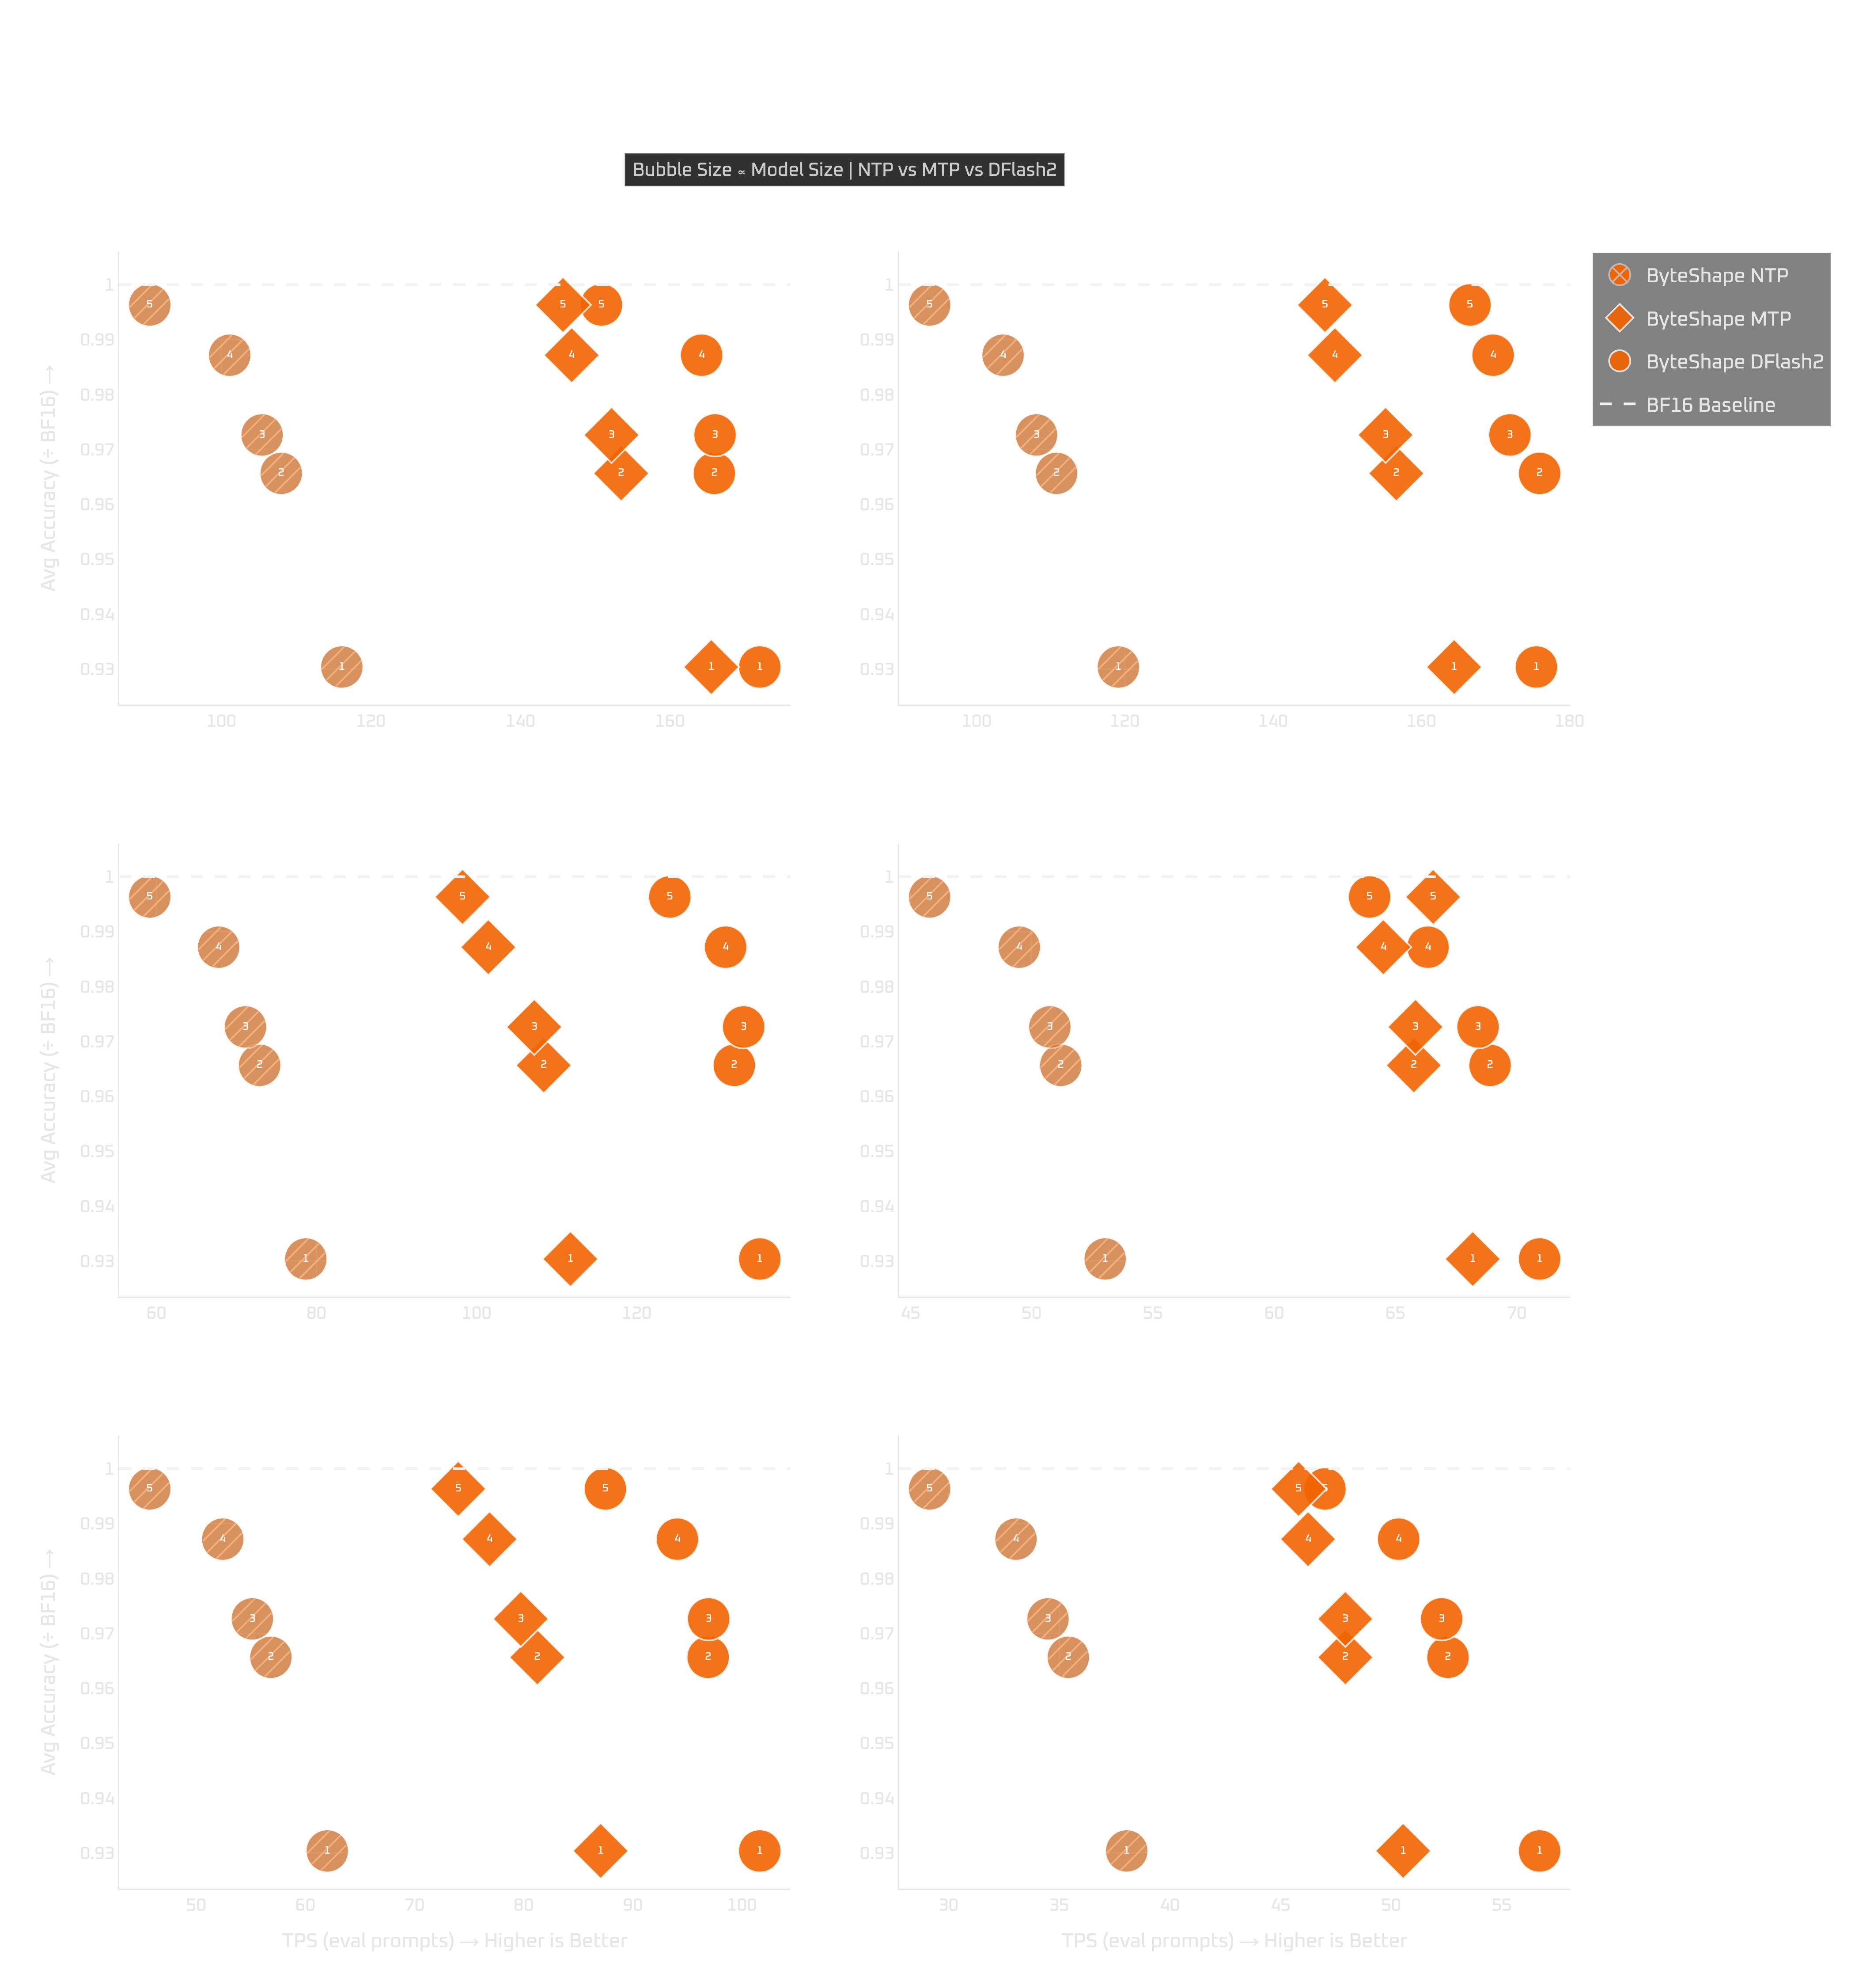
We additionally evaluated MTP and DFlash2 with the brand new fashions, utilizing 3 draft tokens for MTP and seven draft tokens for DFlash2. Both strategies elevated throughput for all 5 ShapeLearn fashions on all six GPUs examined.
DFlash2 was sooner than MTP in virtually all circumstances. Across the total lineup, DFlash2 reached 1.34-2.10x the baseline next-token prediction (NTP) throughput, whereas MTP reached 1.28-1.66x.
We measured with the sampling parameters Qwen recommends for pondering mode, over a various set of agentic coding, arithmetic, and general-knowledge requests. The speedups would possible be bigger underneath grasping decoding, however temperature-based sampling higher displays actual utilization.
The determine under exhibits NTP, MTP, and DFlash2 throughput for every GPU. The high quality axis is the target-model benchmark rating reported above. These plots don’t independently set up high quality equivalence between decoding strategies.
Tap Show Legend under for mannequin particulars.
Hover over the bubbles, or click on Show Legend under, for mannequin particulars.
Show Legend
| # | Model | Acc | NTP TPS | MTP TPS | DFlash2 TPS | BPW |
|---|---|---|---|---|---|---|
| RTX Pro 6000 (96 GB) | ||||||
| GPU-1 | IQ2_XXS-2.56bpw | 0.9304 | 116.11 | 165.52 (1.43x) | 172.01 (1.48x) | 2.56 |
| GPU-2 | IQ3_XXS-2.88bpw | 0.9656 | 108.01 | 153.48 (1.42x) | 165.94 (1.54x) | 2.88 |
| GPU-3 | IQ3_XS-3.01bpw | 0.9726 | 105.44 | 152.19 (1.44x) | 166.03 (1.57x) | 3.01 |
| GPU-4 | IQ3_S-3.23bpw | 0.9872 | 101.11 | 146.85 (1.45x) | 164.24 (1.62x) | 3.23 |
| GPU-5 | IQ4_XS-3.84bpw | 0.9963 | 90.42 | 145.69 (1.61x) | 150.83 (1.67x) | 3.84 |
| RTX 5090 (32 GB) | ||||||
| GPU-1 | IQ2_XXS-2.56bpw | 0.9304 | 119.13 | 164.44 (1.38x) | 175.53 (1.47x) | 2.56 |
| GPU-2 | IQ3_XXS-2.88bpw | 0.9656 | 110.78 | 156.63 (1.41x) | 175.97 (1.59x) | 2.88 |
| GPU-3 | IQ3_XS-3.01bpw | 0.9726 | 108.08 | 155.19 (1.44x) | 171.97 (1.59x) | 3.01 |
| GPU-4 | IQ3_S-3.23bpw | 0.9872 | 103.57 | 148.34 (1.43x) | 169.69 (1.64x) | 3.23 |
| GPU-5 | IQ4_XS-3.84bpw | 0.9963 | 93.66 | 147.00 (1.57x) | 166.57 (1.78x) | 3.84 |
| RTX 4090 (24 GB) | ||||||
| GPU-1 | IQ2_XXS-2.56bpw | 0.9304 | 78.67 | 111.73 (1.42x) | 135.39 (1.72x) | 2.56 |
| GPU-2 | IQ3_XXS-2.88bpw | 0.9656 | 72.89 | 108.40 (1.49x) | 132.20 (1.81x) | 2.88 |
| GPU-3 | IQ3_XS-3.01bpw | 0.9726 | 71.12 | 107.21 (1.51x) | 133.38 (1.88x) | 3.01 |
| GPU-4 | IQ3_S-3.23bpw | 0.9872 | 67.77 | 101.47 (1.50x) | 131.12 (1.93x) | 3.23 |
| GPU-5 | IQ4_XS-3.84bpw | 0.9963 | 59.16 | 98.25 (1.66x) | 124.15 (2.10x) | 3.84 |
| RTX 3090 (24 GB) | ||||||
| GPU-1 | IQ2_XXS-2.56bpw | 0.9304 | 53.03 | 68.19 (1.29x) | 70.94 (1.34x) | 2.56 |
| GPU-2 | IQ3_XXS-2.88bpw | 0.9656 | 51.20 | 65.76 (1.28x) | 68.90 (1.35x) | 2.88 |
| GPU-3 | IQ3_XS-3.01bpw | 0.9726 | 50.75 | 65.82 (1.30x) | 68.40 (1.35x) | 3.01 |
| GPU-4 | IQ3_S-3.23bpw | 0.9872 | 49.49 | 64.50 (1.30x) | 66.34 (1.34x) | 3.23 |
| GPU-5 | IQ4_XS-3.84bpw | 0.9963 | 45.79 | 66.55 (1.45x) | 63.93 (1.40x) | 3.84 |
| RTX 4080 (16 GB) | ||||||
| GPU-1 | IQ2_XXS-2.56bpw | 0.9304 | 62.01 | 87.06 (1.40x) | 101.63 (1.64x) | 2.56 |
| GPU-2 | IQ3_XXS-2.88bpw | 0.9656 | 56.84 | 81.25 (1.43x) | 96.90 (1.70x) | 2.88 |
| GPU-3 | IQ3_XS-3.01bpw | 0.9726 | 55.14 | 79.74 (1.45x) | 96.95 (1.76x) | 3.01 |
| GPU-4 | IQ3_S-3.23bpw | 0.9872 | 52.43 | 76.88 (1.47x) | 94.09 (1.79x) | 3.23 |
| GPU-5 | IQ4_XS-3.84bpw | 0.9963 | 45.74 | 74.01 (1.62x) | 87.49 (1.91x) | 3.84 |
| RTX 5060 Ti (16 GB) | ||||||
| GPU-1 | IQ2_XXS-2.56bpw | 0.9304 | 38.05 | 50.54 (1.33x) | 56.71 (1.49x) | 2.56 |
| GPU-2 | IQ3_XXS-2.88bpw | 0.9656 | 35.41 | 47.94 (1.35x) | 52.57 (1.48x) | 2.88 |
| GPU-3 | IQ3_XS-3.01bpw | 0.9726 | 34.50 | 47.93 (1.39x) | 52.28 (1.52x) | 3.01 |
| GPU-4 | IQ3_S-3.23bpw | 0.9872 | 33.05 | 46.25 (1.40x) | 50.34 (1.52x) | 3.23 |
| GPU-5 | IQ4_XS-3.84bpw | 0.9963 | 29.15 | 45.82 (1.57x) | 47.01 (1.61x) | 3.84 |
There can also be a reminiscence tradeoff between the 2 approaches. The embedded quantized MTP weights add solely about 250 MB to the mannequin, and if MTP is just not used, these weights usually are not loaded into GPU reminiscence. In comparability, the 4-bit DFlash2 draft mannequin is about 1.1 GB, so enabling DFlash2 requires roughly 1.1 GB of extra GPU reminiscence.
Packaging MTP as a separate GGUF file would largely get rid of this benefit. The standalone mannequin would want its personal MTP embedding and output layers, that are by far its largest tensors, bringing its reminiscence footprint to roughly 1 GB as nicely.
In addition, DFlash2 in llama.cpp presently doesn’t help picture inputs, which is a crucial consideration for multimodal use circumstances.
Benchmarking Methodology
We consider all reported fashions throughout a set of instruct and pondering benchmarks.
Instruct benchmarks:
- GSM8K for math
- IFEval for instruction following
- MMLU for normal data
- LiveCodeBench V6* for coding
- Multi-IF for multi-turn and multilingual instruction following
- ACEBench for device use and agentic duties
Thinking benchmarks:
- ACEBench for device use and agentic duties
- Multiple HumanEval for coding
- BFCL V4* for device calling and agentic duties
For the pondering benchmarks, we used Qwen 3.8’s medium pondering setting.
For every benchmark, the rating of a quantized mannequin is normalized by the rating of the corresponding BF16 mannequin. The general reported rating is the common of those normalized benchmark scores.
Our LiveCodeBench V6* analysis contains issues from January 1, 2024 onward, excluding the 2023 issues. We discovered the 2023 issues to be comparatively straightforward for present fashions, with most fashions attaining very excessive scores on them. As a consequence, they supply restricted discrimination between fashions whereas including substantial analysis time.
For BFCL V4*, we consider the next eight subsets:
live_simplelive_parallellive_parallel_multiplelive_relevancemulti_turn_basemulti_turn_miss_funcmulti_turn_miss_parammulti_turn_long_context
All evaluations had been run with llama.cpp b10430. For each instruct and pondering experiments, we use the sampling parameters advisable by Qwen for the corresponding mode.
Conclusion
ShapeLearn-Lite did what it was designed to do. It obtained helpful Qwen 3.8 27B quants onto 12 to 24 GB GPUs rapidly, and it held up higher than its KLD rating steered.
Full ShapeLearn goes additional. It improves the measured quality-speed trade-offs over Lite and contributes 5 frontier fashions throughout all six examined GPUs.
GPU-5 is our default suggestion wherever it suits, reaching 99.63% of BF16’s mixture benchmark rating. When reminiscence is tight, GPU-4 remains to be very aggressive: virtually 99% of BF16 at a a lot smaller dimension, and sooner.
KLD stays helpful, however it isn’t a task-performance leaderboard. Fidelity metrics inform us how a lot the mannequin’s distributions modified underneath a selected measurement. Benchmarks inform us whether or not these modifications matter on the duties we examined.
We had been impatient. This time, it labored out fairly nicely.