The scourge of x86 emulation – FEX-Emu – A quick linux usermode x86 and x86-64 emulator

Welcome to the primary characteristic article on our website. We’re going to cowl an ongoing downside with x86 emulation that impacts each software that we
emulate. This comes right down to a single over-arching time period that has wide-reaching ramifications; Emulating the x86 Total Store Ordering memory model
(x86-TSO).
The issues with emulating this reminiscence mannequin on the weak ordering memory model
that ARM defines is multi-faceted and covers a number of points. We’re going to go over all the issues that we will encounter and the methods we clear up
(or in some circumstances can’t clear up) on this article. Get your self a snack and a heat drink to get pleasure from, that is going to be a protracted one.
Before diving in to how we work across the x86 reminiscence mannequin downside, we have to first focus on precisely what it’s. A reminiscence mannequin is a algorithm
for the way reminiscence accesses in a system behave in relation to one another. The guidelines will dictate how masses and shops work together in a single-threaded or a
multi-threaded atmosphere. There’s a handful of widespread reminiscence reminiscence fashions applied in numerous types of {hardware}, however the two we care about
as we speak is ARM’s relaxed (or weak) consistency mannequin, and the x86 variant of Total-Store-Ordering consistency mannequin. These two fashions are principally the
two extremes of the spectrum; the place ARM is essentially the most relaxed, permitting important {hardware} optimizations; and x86 is essentially the most strict, imposing a really
sturdy coherency mannequin that doesn’t enable quite a lot of room for optimization. One factor to watch out about when discussing reminiscence fashions is the
distinction between consistency and atomicity. While these are associated, they aren’t the identical nor assured in all circumstances.
The greatest method to clarify how the variations in reminiscence fashions work is to begin with how x86 handles this. With TSO being very strict in the way it
operates, the programmer can assume that when a reminiscence retailer happens, that this might be coherently seen to all different processors within the system.
This moreover implies that when a reminiscence load happens, all shops earlier than it “logically” may have been accomplished, or no less than seen. This matches
programmer expectations, you write to reminiscence, it turns into seen as on the level of writing, as that is intuitive to consider when programming. The
shops are successfully ordering the visibility of the masses, thus the identify of the mannequin. There’s a little bit of nuance with how this operates however isn’t
strictly vital to know.
The weak reminiscence mannequin that ARM has is a bit much less intuitive about the way it operates. By default the common reminiscence masses and shops that ARM makes use of aren’t
strictly coherent throughout processors in your system, permitting the CPU to function extra effectively more often than not. When a retailer instruction
executes, that piece of reminiscence (the cacheline) isn’t instantly seen to different processors within the system. Saving on treasured energy and effectivity
as a result of it’s costly in {hardware} to invalidate different core’s cachelines, or enable them to snoop
one other processor’s caches. Relatedly if a processor is loading knowledge from reminiscence that one other processor has written to, it’s not assured that this
load will even see this up to date reminiscence. This feels like it might trigger some important issues in a multi-threaded software proper? Older
variations of ARM (ARMv7 and older) used a reminiscence barrier instruction to make sure ordering, which had important efficiency implications.
To get round this limitation of consistency, ARM additionally launched load-acquire, and store-release reminiscence directions. In C++ parlance this maps to
std::atomic’s memory_order_acquire and memory_order_release definitions respectively. In ARM’s terminology, these directions additionally aren’t
technically thought of to be atomic operations, however programmers conflate the 2. FEX has used the phrases atomic-load and atomic-store to imply
the identical factor! The distinction often doesn’t matter, however when discussing these subjects it might be higher to be pedantic about it.
The main use case for these directions is to pressure reminiscence ordering between these class of directions. ARM calls this the “Release Consistency
sequentially constant (RCsc)” mannequin. Without getting too far in to the weeds about how this mannequin operates, the essential gist is that the load-acquire
directions have to be noticed sequentially with out reordering, and the store-release directions should as effectively whereas fulfilling
“barrier-ordered-before” semantics. Removing the pricey reminiscence barrier instruction required in older ARM structure variations.
This is the premise of the place we begin in ARMv8.0-a once we’re emulating the x86-TSO reminiscence mannequin. We make all x86 reminiscence masses flip in to ARM’s
load-acquire directions, and x86 reminiscence shops flip in to store-release directions. This offers FEX successfully the identical reminiscence semantics
as x86, though we are literally being extra strict than what is critical. This is as a result of we had no middle-ground which precisely matches behaviour.
As one would possibly suppose, it’s exceedingly pricey to emulate TSO wth this directions and we now have microbenchmarks that may present this.
As ARM CPUs weren’t designed to have these comparatively uncommon purchase/launch directions immediately develop into the overwhelming majority of directions executed.
First let’s begin with one thing straightforward and use a microbenchmark that’s pretty good to the {hardware}. No difficult edge-cases, simply accessing reminiscence in in
the widespread case. This offers us some baseline numbers for what the best-case scenario needs to be.
Let’s break down this graph because it tells us just a few fascinating tales. The Load and Store columns of every machine is representing our baseline
efficiency quantity that our {hardware} needs to be making an attempt to attain. These aren’t making an attempt to max out the reminiscence bandwidth of every system, however do the
identical quantity of labor for every sort of operation. If we flip our consideration to the acquire-load outcomes, we will see that out of the
5 CPUs checks, three of them have their efficiency hindered fairly a bit through the use of acquire-loads! Additionally we will see that the AmpereOne CPU has
release-store directions which might be strikingly low in comparison with the opposite outcomes, and the M1 Acquire/LRCPC load directions are fairly a bit decrease than the baseline as effectively.
The AmpereOne leads to specific showcase how dangerous this legacy path can get. These directions had been by no means designed to be
used this manner. Using acquire-release semantics for each load for x86 emulation really imposes some actually strict limitations on ARM CPUs in that
the load directions can now not be ordered round one another in any respect. So when you may have thousands and thousands of them in flight per second, the efficiency isn’t
actually anticipated to be good. But as a result of these are the one directions we had with ARMv8.0-a, it’s what we had to make use of. While Cortex-X4 and
Cortex-X925 have superb efficiency for these, you may see how the Oryon-3 has deprioritized their significance.
Where will we go from right here?
Let’s take a better take a look at the LRCPC-load directions, which is necessary since ARMv8.3. This extension provides a bunch of recent load directions to the ARM ISA and provides a brand new reminiscence mannequin on high of
ARM’s RCsc mannequin from earlier than. This new “Release Consistency processor constant (RCpc)” reminiscence mannequin is what we’ve been wanting! This extension is
designed across the necessities that x86 emulation requires, and is anticipated to get utilized closely on {hardware} that implements it. As you may see from the
graph, virtually all the platforms have their LRCPC-loads matching their common masses in efficiency.
With this new extension that’s mandated by newer ARM variations, we principally get solved
reminiscence efficiency. At least based on this microbenchmark that appears to be the case. Once FEX detects this extension we cease utilizing Acquire-Load directions
fully and swap over to LRCPC-Load as a substitute. But what’s occurring with that Apple M1 outcome..?
This is the place we have to commend Apple’s path in direction of fixing this downside. With their Apple Silicon processors they straight added assist for the
x86-TSO reminiscence mannequin. When the CPU characteristic is toggled, their common load/retailer ARM directions change behaviour to match what x86 requires. They went
this route understanding that they are going to want a excessive efficiency resolution for his or her {hardware} when switching to the ARM ecosystem solely.
This is why on their {hardware} the LRCPC-load directions are literally aliases of their acquire-load directions, as a result of their x86
emulator doesn’t even use these directions! Because they implement the x86-memory mannequin, they simply use common load/retailer directions, which may be seen in our
microbench outcomes as indiscernable efficiency overhead. To be truthful to the opposite platforms, this thread-wide TSO mode toggle does have some
efficiency affect, we simply don’t see it right here. When FEX detects this CPU characteristic from Asahi Linux we will even allow this
and get the “free” efficiency enchancment. A possible concern is that when leaping between x86 emulation and ARM code, that the ARM code
can pay pointless overhead as a result of all its accesses being TSO now. While this can be a affordable concern, the quantity of ARM native code executing beneath
emulation approaches 0%. As a developer, you don’t care about 1% of reminiscence accesses turning into 10% slower, you care about 99% of accesses turning into 15% of
the “splendid” (As proven in AmpereOne outcomes).
As a notice, we predict a TSO mode is the most effective path ahead for guaranteeing excessive efficiency x86 emulation on the platform. Because this ensures that each reminiscence
entry instruction behaves how we wish or anticipate. This is proven with the official FEAT_LRCPC extension really having three variations that
apply bandages to the implementation every time.
- FEAT_LRCPC – Adds fundamental GPR TSO load directions
- FEAT_LRCPC2 – Adds small offset fast to TSO load directions
- FEAT_LRCPC3 – Adds fundamental vector and stack-based TSO load & retailer directions
Even with these three extensions, there may be edge-case behaviour that may’t be emulated as properly as if we had a TSO {hardware} toggle.
We expect there to be extra extensions variations as time goes on, making an attempt to repair a few of the extra issues we’ll focus on
later within the article.
In the earlier part, we had been being good to the ARM {hardware} and enjoying together with the underlying {hardware}’s alignment necessities to get a
baseline for what the efficiency ought to appear to be. When emulating x86 though, we run face first in to a obtrusive downside proper from the beginning. Your
favorite x86 purposes don’t care about alignment! They’ll entry reminiscence nonetheless they please, crossing cacheline granularities, doing atomics that
aren’t aligned. You consider the alignment issues, these video games are doing it. This downside is so dangerous that we now have a time period related to it, known as split-locks.
These are such a giant deal that even the Linux kernel will seize when these happen and decelerate video games once they do it! Causing many avid gamers to tinker
with kernel choices to keep away from the slowdown!
But we aren’t going to speak about full on split-locks but, let’s get began with simply load-store directions in an atmosphere that doesn’t care
about alignment. x86 makes sure ensures to the programmer; if you happen to do a load-store and it’s within a cacheline then that load-store might be each atomic and nonetheless match the coherency mannequin as described earlier than. However, to be a
little bit good to the {hardware} builders, if the load-store does cross a cacheline, the information isn’t atomic and different threads can and can see it
tear. So the programmer must be cautious as a fundamental load-store shouldn’t be a split-lock.
The downside with emulating these fundamental accesses with load-acquire/store-release is that ARMv8.0 requires what is called pure alignment.
This implies that for no matter dimension of knowledge being accessed, the offset in reminiscence should match the scale. So for an 8-byte entry, it have to be at offsets; 0,
8, 16, 24, and many others. This works effectively for native ARM purposes, however what occurs once we don’t obey pure alignment necessities? For ARM, this implies
the instruction with elevate an alignment fault.
The {hardware} validates that the alignment necessities are fulfilled and if they aren’t then the CPU will fault. This often leads to a crash however
FEX does particular dealing with.
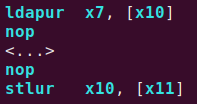
Inside of FEX’s JIT mechanism we maintain monitor of reminiscence load-store directions which might be emulating the
x86 load-stores. When we all know {that a} load-store could cause an alignment fault we now have what is called a patchpoint within the code. For load-store
directions, this exhibits up as a NOP instruction both earlier than or after the load-store. When a alignment fault happens as one among these patchpoints, FEX
will seize the fault, patch the code from a load-acquire/store-release instruction to a fundamental equal load-store, and wraps the instruction
in a knowledge reminiscence barrier. Then it continues executing!
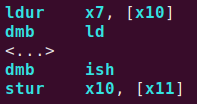
Before then after patching
That total dialogue from earlier than about how ARMv8.0-a added these new fancy load-acquire, store-release directions? We instantly fall
again to the basic reminiscence barrier instruction as a substitute when alignment behaviour doesn’t match. Our earlier chart didn’t present this dangerous case, so let’s
herald some recent knowledge.
Oh, that’s quite a lot of knowledge to sift via. While once more good to see how distant the {hardware} is from the “optimum” path whereas emulating TSO, it’s not what we care about right here.
It is fascinating to notice that this microbench doesn’t showcase a lot of a distinction between aligned and unaligned for normal load/shops so we simply
calculated a median between the 2.
We’ll be eradicating the x86 CPU and the common load-store knowledge from the ARM columns, as these aren’t the widespread FEX paths. This method we’ll have a extra
focused view about how badly unaligned reminiscence accesses damage beneath emulation.
Now that we now have a way more affordable graph of knowledge, let’s stroll from left to proper on this and focus on what’s going on.
AmpereOne
This one is fairly fascinating, each the aligned and unaligned load directions are roughly equal and fall inside noise. This implies that even
although the unaligned masses are getting hit with a knowledge reminiscence barrier penalty,
the CPU simply handles it. This is perhaps the case that the benchmark is bottlenecked by different issues, contemplating how a lot decrease the efficiency is
in comparison with different platforms.
Meanwhile the shop aspect shouldn’t be trying to be in a good condition even with out unaligned. It almost isn’t seen on the chart! When hitting
unaligned shops we’re ~8.5% of a efficiency hit, however as a result of we’re already beginning so low it’s onerous to note. This can also be in stark
distinction to common retailer directions getting ~28GB/s on this bench.
The solely conclusion we will come to right here is that Ampere is optimizing for some server class workload and doesn’t actually match shopper {hardware}
behaviour. It’s an fascinating datapoint, however our customers aren’t usually working video games on this class of {hardware}.
Cortex-X4
This is a extremely widespread CPU core that’s dwelling contained in the Qualcomm Snapdragon 8 Gen 3. We solely examined
this one core from the SoC to not overwhelm the chart with knowledge. Quite numerous handhelds ship with this so it’s an fascinating
goal. This CPU really does surprisingly effectively contemplating it’s the one cellphone SoC on this record. Overall this core type of falls in line
with what we’d anticipate from it and the graph tendencies observe with the next-generation Cortex in that chart.
The primary subjects for this CPU are that its aligned masses and shops are moderately highly effective, getting round 11.5GB/s and
6.7GB/s respectively. What’s fascinating is the efficiency falloff when it must take care of unaligned loadstores, hitting the DMB directions
penalizes the core roughly evenly between masses and shops at round 50% on this benchmark.
This appears to indicate that the CPU can maintain a good variety of LRCPC-release loadstores in flight so the DMB directions damage extra when they’re
encountered, nevertheless it isn’t inflicting world-ending efficiency. Just {that a} 50% efficiency hit as a result of alignment isn’t a tremendous outcome.
Cortex-X925
Following up the X4, let’s cease by the DGX Spark and its X925 cores. Not solely is that this
a more recent CPU core from ARM, it’s working on a system with dramatically extra reminiscence bandwidth. 273GB/s within the platform versus the earlier 76.8GB/s. This
implies that we get pretty comparable outcomes to the X4 even, simply the graph scales just a little larger. Interestingly sufficient, the efficiency penalty for
unaligned accesses roughly match the X4 even. Although it appears to be like just like the shops can get better just a little sooner, possible as a result of sooner reminiscence serving to
out. No surprises right here, simply constantly matching efficiency throughout the generations.
Oryon-3
This CPU core design is sizzling off the presses from Qualcomm. Linux assist continues to be within the means of arising nevertheless it already has a robust exhibiting.
The most fascinating outcome from this really comes from the truth that aligned LRCPC-load directions are matching the
efficiency of normal masses! That means within the case of a well-behaved software we will usually anticipate full efficiency. This continues onward to
the release-store directions being fairly succesful, though it doesn’t fairly match common shops with solely 68% of the bandwidth. Not a foul exhibiting
within the slightest.
This CPU can also’t escape from the penalty of unaligned LRCPC-release loadstores. The load aspect is roughly matching the ~70% efficiency penalty of
the Cortex-X925, possible as a result of the Snapdragon X2 Elite additionally has tons of bandwidth. But the shop aspect really will get off just a little worse at ~43% of the
efficiency. Even with these efficiency hits of unaligned accesses, this platform is definitely sooner than the aligned accesses from the Cortex
choices.
One of the bizarre issues about this platform is that it was marketed to have “Fully coherent 96KB 6-way L1 cache with 64B coherency granules.” Which
to our studying implied that unaligned accesses ought to have dramatically much less of a efficiency affect. Interesting… maintain that in thoughts.
Apple M1
This is the massive one we have to discuss. This is the one which was a sport changer, it was the “Apple second.” It confirmed everybody that ARM was
not solely possible, it could possibly be sooner. These numbers on this chart are superb and it’s the results of Apple sticking the TSO reminiscence
mannequin straight in to their {hardware}. Instead of utilizing LRCPC-release accesses for this one, we simply enabled their TSO characteristic and the aligned
variations principally match the unaligned model. Maybe a 5% efficiency hit on the shops? Compared to each different machine on that chart, it’s
successfully nothing. This primarily comes right down to unaligned accesses now not requiring DMB directions to be backpatched in to the code, because the
{hardware} simply handles it straight.
For us, that is what it means to take x86 emulation critically on ARM and it actually exhibits that Apple cared that their clients would have an excellent
expertise working software program each natively and emulated. They noticed the issue and simply solved it, making it go away.
That stated, when the TSO mode is enabled, you do get a efficiency hit. Comparing to the earlier graph it’s solely getting 76% of the common
retailer efficiency, and the load efficiency principally matches; that’s rather more tolerable to bear when every part is a lot sooner.
Wrapping up unaligned LRCPC/launch accesses
Wrapping up this part, we have to discuss one of many efficiency enhancements that every one of those distributors really assist. This is an
extension that ARM whipped up known as FEAT_LSE2 which all of those examined platforms implement. We beforehand talked about how purchase/LRCPC/launch
reminiscence accesses require pure alignment to be able to not incur the wrath of the CPU elevating alignment faults. ARM really considered
this downside and applied this extension which helps x86 emulation (and doubtless different workloads). This extension loosens the alignment
necessities of not solely purchase/LRCPC/launch load retailer directions, it additionally loosens the requirement for read-modify-write atomics!
That sounds all effectively and good, however right here’s the kick to the tooth: which means it solely supplies marginal efficiency good points for x86 emulation. This
extension solely loosens the alignment necessities to permit unaligned reminiscence accesses within a 16-byte granule. Any entry that crosses that 16-byte
granule nonetheless receives an alignment fault. x86 purposes don’t actually care in regards to the alignment of their reminiscence accesses, so we get
unaligned accesses throughout your entire cacheline. It’s solely read-modify-write atomics that attempt to keep away from crossing a cacheline on x86!
So thanks for the try, it’s good to see, nevertheless it doesn’t actually transfer the needle. Since we’re already speaking about it, let’s dive in to these RMW
atomics lets?
Like most trendy instruction units, x86 helps atomic reminiscence operations. These are directions that execute an ALU operation on knowledge in reminiscence
atomically, permitting no intermediate state to be seen. In x86 phrases this operates on reminiscence that’s each atomic and coherent, whereas ARM permits you to
select to be solely atomic or each atomic and coherent. We touched on this briefly earlier than however there may be really a distinction between working on knowledge
atomically, and coherency of that knowledge. What distinction does it make?
For all the earlier x86 reminiscence mannequin dialogue we now have been speaking in regards to the coherency implications of masses and shops being seen to different
processors within the system. What we fully glossed over is the atomicity necessities of those reminiscence accesses. In the global community of x86 a load or retailer
often completes atomically even when unaligned. This implies that if you happen to’re storing 8-bytes of knowledge, and one other thread is loading these 8-bytes in
a race situation it can by no means immediately see a mixture of the information from earlier than the shop and after the shop. In ARM these atomicity ensures are
considerably weaker, which means if you happen to do an unaligned retailer instruction the specification of the ISA has zero ensures about studying a tear in
the information. Thankfully for naturally aligned load-store directions, ARM has a specification known as “single-copy atomicity” which ensures
you don’t get a tear for these accesses. Also excellent news; that FEAT_LSE2 extension from earlier than? It really extends the
single-copy atomicity ensures to any unaligned entry within a 16-byte granule! The draw back is that x86 has single-copy atomicity
ensures throughout a full cacheline, so as soon as once more the extension nonetheless didn’t clear up something utterly, simply diminished the variety of occurences.
Enough in regards to the variations in atomicity and coherency. Where’s the precise atomic directions? What do they do? Starting in ARMv8.1-a, our ISA
has gained directions that principally matches x86 atomic directions in behaviour. Let’s simply give the complete record to point out how they map straight in our
JIT.
| x86 | ARMv8.1-a |
|---|---|
| LOCK DEC | ldaddal |
| LOCK INC | ldaddal |
| LOCK NEG | ??? |
| LOCK NOT | ldeoral |
| LOCK ADC | ldaddal |
| LOCK ADD | ldaddal |
| LOCK AND | ldclral |
| LOCK OR | ldsetal |
| LOCK SBB | ldaddal |
| LOCK SUB | ldaddal |
| LOCK XADD | ldaddal |
| LOCK XOR | ldeoral |
| LOCK BTC | ldclralb |
| LOCK BTR | ldeoralb |
| LOCK BTS | ldsetalb |
| LOCK CMPXCHG | casal |
| CMPXCHG8B | caspal |
| CMPXCHG16B | caspal |
Well would you take a look at that, we now have a full record of the 18 atomic RMW operations and so they principally map on to some ARM directions. Ignore the questionable
one because it’s not utilized in actual workloads and we’d get far too in to the weeds speaking about it. We have a reasonably clear 1:1 mapping between the
architectures, job’s executed proper? That’s the humorous factor about x86 emulation, simply because we now have these directions doesn’t imply we get to wire them
up with out issues. We spent all this time speaking about how unaligned accesses can actually damage efficiency of normal masses and shops, this identical
downside additionally applies to RMW atomics!
With this graph, we’re a single atomic instruction with its reminiscence deal with touchdown someplace inside a cacheline. If we included all the
knowledge for all 18 atomic operations then this knowledge can be much more overwhelming than it already is. All these atomic operations behave roughly
equal so it might be redundant and wouldn’t matter for what we’re discussing right here anyway. This can also be the primary graph on this publish that’s
really utilizing logarithmic scaling, so when studying it make sure that to know that the efficiency distinction from the quickest to slowest result’s
on the dimensions of round 1000x.
Starting with the x86 Zen processor on this graph; these are the outcomes that our emulation needs to be striving to attain. As we will see, if the entry is
absolutely contained inside a cacheline then the latency of the instruction is identical at 1.44ns. This may be defined by x86 having “atomic cachelines”
or “coherent cachelines”, the place so long as an unaligned atomic operation stays inside a cacheline then it roughly prices the identical. This is a very
highly effective characteristic of x86 that has been supported for many years at this level so video games find yourself counting on this closely with out even realizing it. The
stand-out outcome for x86 is the ultimate outcome that’s crossing a 64-byte granule and taking ~660ns! That’s an amazingly gradual outcome at ~458x slower
in comparison with the opposite outcomes as a result of that is lastly the {hardware} utilizing split-locks.
We must take a second right here to shout out an article that Chips and Cheese wrote
whereas we had been getting ready to write down our article. They do a terrific deep dive in to why these split-locks are so dramatically slower and is well worth the
learn if you happen to’re unaware of how they work. Specifically we have to point out that x86 split-locks keep the atomicity and coherency necessities of
x86-TSO and can by no means tear the information even when crossing a cacheline. This is type of nuts and we’ll clarify this extra later.
Now for our ARM processors, let’s begin with the pure alignment latency numbers. As we will see, all of our platforms carry out pretty effectively however even
the newest cores don’t get wherever close to x86. Even our quickest ARM platform is ~3x the latency in comparison with x86; This straight impacts efficiency of
video games however often isn’t the direct bottleneck so it’s onerous to measure precisely how a lot. Continuing onward to the subsequent knowledge level, we will really
mix the outcomes for 16-byte granule and 64-byte granule crossing with most of our ARM platforms. Due to how the ARM specification defines how
unaligned atomics work, each of those outcomes are roughly equal and FEX treats them the identical because the x86 split-lock downside.
We maintain citing this split-lock downside however how precisely does FEX emulate them and what makes it so gradual? “I believed Apple M1 added x86-TSO assist
within the {hardware}, why is it nonetheless gradual?” If you recall how we introduced up earlier than that FEAT_LSE2 launched assist for unaligned reminiscence accesses inside
a 16-byte granule; these split-lock operations find yourself hitting the identical alignment issues as earlier than however are dramatically slower. FEX
can’t backpatch any of those directions to only do a DMB operation, so we trigger an alignment-fault each time one will get executed. This implies that
we do a kernel -> userspace sign handler -> kernel -> unique code dance. each—single—time one among this split-lock operations execute.
Jumping between kernel-space and userspace is gradual on each platform and whenever you’re executing 1000’s of those per second it provides up in a short time.
This is why the emulation of those characteristic is so terribly gradual on ARM.
One ARM platform as we speak really partially resolved this downside though. The Oryon-3 CPU cores launched what they marketed as “coherent
cachelines” and we will see this in our microbenchmark outcomes right here. Just like with x86, if the atomic reminiscence entry in wherever within the 64-byte
cacheline, the efficiency matches the pure alignment model! This is an amazing enchancment which means the CPU is on par with x86 in
characteristic assist till the purpose it tries to cross a cacheline. We must applaud Qualcomm on implementing this characteristic, because it resolves a significant
efficiency and correctness downside round split-locks for x86 emulation. The {hardware} nonetheless doesn’t assist 64-byte split-locks so we nonetheless fall
down the FEX emulated path in that occasion though.
Continuing on to the Apple outcome; although they added x86-TSO reminiscence accesses to their {hardware} for some motive they uncared for to implement full
cacheline unaligned atomics like Oryon did. It looks as if they need to have anticipated this edge case to floor and implement it however that’s simply hypothesis.
This is why you may see the cross 16-byte granule behaving the identical as different platforms even with the TSO {hardware} toggle enabled.
You may need additionally observed one other little knowledge quirk within the graph. We have an asterisk on the Cortex-X4 outcome on this benchmark and the efficiency
of the unaligned atomics are dramatically sooner than considerably newer CPUs. It is by some means managing to have solely
~209ns latency, whereas the X925 is latency is 1060ns; that’s a 5x perf enchancment! How can this probably be the case? This is definitely some enjoyable
“particular sauce” that’s delivery on the platform we’re testing on, which is after all the Valve Steam
Frame. Because Valve cares in regards to the efficiency of their current gaming catalogue, they’re delivery a
kernel patch that one of many FEX builders whipped up. This permits
the Linux kernel itself to deal with the unaligned atomic with out that gradual dance with FEX and userspace, permitting it to be dramatically sooner. If different
platforms wish to ship this patch within the kernel then we suggest selecting it up as and FEX will robotically begin utilizing it.
Speaking of kernel intervention, we have to discuss how split-lock emulation shouldn’t be really fairly right beneath FEX as a result of limitations within the
{hardware}. In order to implement this necessary characteristic of x86 accurately, any time we do a 16-byte or 64-byte split-lock, the one method to
deal with it’s to have the kernel implement the characteristic. Right now FEX implements this as a “best-effort” try that may really tear the information in
some circumstances. You’ll recall that earlier than we stated split-locks on x86 won’t ever tear proper? Not even the Oryon-3 with its “coherent cachelines” have resolved
this downside but.
Implementing split-lock emulation with as we speak’s ARM {hardware} in a performant matter is definitely actually troublesome to do. A naive implementation is to
use a worldwide mutex and every time a split-lock happens we’ll guarantee to accumulate the mutex earlier than doing the operation. This implies that any
taking part split-lock operation will funnel via this mutex. This is right apart from the difficulty that any aligned atomic operation
isn’t a split-lock and gained’t take part. Due to the split-lock emulation code wanted to be applied as two 64-bit compare-exchange
operations with every half straddling the granularity boundary, we will get a tear with a non-participating atomic nonetheless. A trivial instance is one
thread consistently modifying an atomic in the course of the cacheline, after which one other thread modifying solely the integer on one half. This would possibly sound
like a contrived instance initially, however there are lock-less linked-list implementations that behave precisely like this!
Depending on which half the aligned thread is modifying, both the primary or second CAS within the split-lock code will fail. If the primary CAS fails, then
that’s secure and the code can retry, if the second CAS fails which means the information has torn and we will do nothing however hope it doesn’t corrupt knowledge and
crash. This will fully rely on the algorithm that the visitor software is utilizing so we don’t management it.
An various strategy that’s utterly untenable is to have the kernel monitor all processes and threads which might be sharing reminiscence with one another,
then when a thread must emulate a split-lock the kernel can halt each course of that’s sharing reminiscence with that course of, do the split-lock
in isolation, after which restart the global community. The efficiency implications of this strategy aren’t viable. Applications and video games can find yourself doing 1000’s or extra
split-locks per second and halting the global community may have an intractable efficiency hit that’s dramatically worse than even x86 native.
If we wish to guarantee correctness within the emulation of split-locks FEX must have {hardware} assist in some kind to assist these. Although we’re not
saying that every one atomic operations ought to now assist split-locks like x86, that will additionally not be viable. The excellent news is that ARM really has an
extension for this that does precisely what we wish. ARM has an extension name Transactional Memory
Extension that would clear up our downside. This extension permits our code to do some variety of
operations within a transactional area, then commit that work atomically; if the commit operation fails, then we will merely retry. The draw back
of this extension? ARM has formally deprecated the extension and nobody ever shipped it. This is probably going for the most effective because the x86 model of the
extension has had an abundance of issues that precipitated it to be disabled on many platforms.
So we’d like one thing else to emulate split-locks accurately. For an answer that we imagine works for each FEX wants and ARM vendor wants, we now have come
up with the concept that a 128-bit CASP instruction may be given the power to have every half of the CASP completely straddle
the atomic granule boundary, 64-bits on the decrease half, and 64-bits on the higher half. Then solely in that case does the instruction not elevate an
alignment-fault and tries to do the CAS operation. This works as a result of x86 solely has as much as 64-bit unaligned atomic operations, so each halves of the
operation can all the time be absolutely enclosed by our single operation.
But chances are you’ll be asking your self, “how is that this any higher than the {hardware} simply supporting split-locks?” That’s an excellent thought and we must be
cautious with the how precisely we describe this operation. For x86 their atomic operations should all the time succeed with out tear. For our emulated
strategy, we will have this ARM CASP instruction fail safely after which we will attempt once more. This is among the advantages of CAS is that
the operation can fail for any motive and it have to be tried once more. The instruction then additionally returns the information that it loaded from reminiscence in that point
so this system has the newest updated reminiscence. This is a vital distinction since which means FEX can retry the CAS operations infinite instances
till it inevitably succeeds! This is a good thing about ARM LL/SC structure that principally permits this to work. A difficult factor is that the {hardware} does
want to ensure ahead progress at some level nevertheless it already has assist for that for different causes so it’s utterly viable! The solely newly
added failure mode to the CAS instruction is solely if one of many two cachelines bought acquired by one other core earlier than it may do the complete operation.
Even if the {hardware} nonetheless requires up to a few thousand cycles to ensure ahead progress, that principally matches x86 behaviour.
We suppose this is able to be one of the best ways ahead for x86 emulation of split-locks on ARM platforms, however we’re not {hardware} architects so all we will do is
complain and hope somebody solves it for us. We’ll go away the split-lock dialogue there for now so we will transfer on to a different fascinating downside.
Before we get in to this matter we have to speak in regards to the time period “uncached” as a result of it will possibly imply a few issues relying in your view of the
global community. For the needs of this text, we’re utilizing Vulkan terminology as a result of we care about video games primarily. In Vulkan phrases we now have
VK_MEMORY_HOST_CACHED_BIT which implies that the host CPU caches this reminiscence. The lack of this bit is what we care about right here, and what we discuss with as
“uncached.” As for what this implies to the reminiscence subsystem, it will get just a little extra difficult than you’ll suppose. In specific when the reminiscence is
dwelling on a GPU, probably over PCIe, when the reminiscence is “uncached” it can additionally usually (however not all the time!) additionally achieve the flag
VK_MEMORY_HOST_COHERENT. This implies that due to the uncacheable property of the reminiscence, the CPU and GPU all the time have a coherent global community reminiscence view
with one another.
For the CPU this usually means the reminiscence may be mapped as much as 3 ways. When asking for “cached” reminiscence, this usually has a reminiscence sort of
Write-back which can also be what common reminiscence mapping sorts are. “uncached” mapping
may be both Write-Combine or “Strong Uncacheable”. The “Strong Uncacheable”
implementation is principally non-existant for userspace purposes so we will ignore that for as we speak’s dialogue. This limits us to successfully WB
(cached) and WC (uncached) reminiscence sorts. Cached is what video games usually use for staging buffers, after which uncached is what we use when passing knowledge straight
to the GPU.
This is code-ified in lots of sport engines that if you happen to don’t expose assist for uncached buffer sorts then some don’t work. This comes right down to a
behaviour element across the variations of UMA methods like APUs and PCIe GPUs. UMA
methods will usually expose the power to allocate reminiscence that’s cached, coherent, and GPU seen. Where PCIe GPUs can’t assure that behaviour
so sport builders must both use a staging buffer and an async copy of the information over to the GPU, or use “uncached” reminiscence to very rigorously
shuffle the information over to the GPU via PCIe. Because of how ubiquitous PCIe is with PC gaming, some engines gained’t even do UMA particular code
paths and can do the uncached strategy regardless!
With that little introduction out of the way in which for what uncached means for us. Let’s convey up a benchmark for how briskly cached reminiscence is on some UMA
Snapdragon methods. This will allow us to get a baseline for the way the efficiency needs to be recurrently.
For each the Steam Frame and Snapdragon X2 Elite these are some actually good outcomes. As we’d anticipate, the Oryon-3 platform has extra reminiscence
bandwidth so it is ready to scale larger within the chart, however each are hitting dozens of gigabytes per second of their outcomes. This graph units an excellent
baseline for what “regular” write-back reminiscence can obtain. Let’s now present uncached outcomes to see the efficiency variations.
There’s some unusual issues occurring right here so we had to make use of logarithmic once more on this graph. Let’s speak in regards to the good first that has proven up.
Due to uncached reminiscence buffers being write-combine, we will see that the common shops for our ARM platforms match the cached benchmark
outcomes. This comes right down to write-combine reminiscence utilizing what’s coined as write combine buffers
that truly very quickly maintain round a cacheline of knowledge in order that write-combine can burst a cacheline of reminiscence at a time. Interestingly sufficient
it appears to be like just like the Zen 4’s WCB can’t fairly sustain with cached, however contemplating that is anticipated to be going over a PCIe bus it’s most likely advantageous.
Now let’s get in to the actually ugly outcomes that we now have right here. Starting off with the better to clarify is the load bandwidth from write-combined
reminiscence is abysmal on all platforms examined. If we’re utilizing Zen as our baseline for efficiency, then our common load directions are ARM are successful,
however the LRCPC masses are worse. What’s occurring right here? This is a quirk of how write-combined reminiscence operates, as a result of it’s uncached our load
directions are required to exit to system reminiscence for each single entry to take care of semantics. Then once we add LRCPC-loads on high of that, it
simply compounds the issue even additional. But the worst case out of all of that is simply how badly the shop efficiency is, in contrast
to the efficiency that Zen will get on the shops, that is principally a showstopper. Up to 816x worse bandwidth! We had video games like Hollow
Knight: Silksong and Subnautica
2 run at lower than 1FPS due to this efficiency cliff.
As we had been saying above, when there are PCIe GPUs within the combine then video games might want to use uncached reminiscence to move knowledge to the GPU. When emulating x86
video games on platforms with a devoted PCIe GPU then we’re in an unwinnable scenario and we’re assured to run dramatically slower. Remember how ARM
has added the household of FEAT_LRCPC1/2/3 extensions from earlier than to enhance x86 reminiscence mannequin emulation? This is what occurs once we hit an
edge-case that isn’t supported. All of those extensions add new directions to deal with loading reminiscence utilizing x86-TSO reminiscence mannequin semantics however none of
them clear up storing to write-combine reminiscence with x86-TSO semantics. All the way in which from ARMv8.0-a our retailer directions use the common store-release
directions whatever the backing reminiscence sort. The solely method for FEX to work round this downside is to selectively disable TSO-emulation when it
turns into a difficulty, so x86 emulation platforms with PCIe GPUs will all the time be a worse expertise than UMA. At least till we get one other FEAT_LRCPC4
or just like resolve the difficulty.
For customers on UMA methods then rejoice, there’s a workaround for gaming that we use to enhance efficiency. Because we all know when a platform helps
cache-coherent CPU and GPU mixtures, we will have the video driver all the time use cached buffers and by no means encounter this downside.
NVIDIA already does this on their Tegra platforms, Snapdragon has been supporting this since no less than Adreno 600 class GPUs, and there are numerous
Mali platforms the place that is additionally the case. We have a Adreno Turnip patch that
ensures when FEX is working, we by no means hit uncached reminiscence for platforms that assist it. A humorous factor is that since Asahi customers have a {hardware} TSO
bit, they simply naturally don’t encounter this downside within the wild, however getting a PCIe GPU on to that platform is a distinct story altogether. There’s
additionally a enjoyable quirk the place Radeon GPUs on ARM platforms conceal all write-combine reminiscence to as a substitute be write-back however we’ll discuss that one other time.
After that marathon of an article we hope you may have a greater understanding of a few of the challenges that emulating the x86-TSO reminiscence mannequin brings.
Where we began with ARMv8.0 at least spec and the place the {hardware} has supplied dramatic enhancements over time in nothing in need of
astounding. While not all the edge-cases are but resolved on the structure stage, it appears to be like like there’s a real dedication throughout the
ecosystem for making an attempt to enhance the worst circumstances. We have numerous distributors fixing some elements of the issue and transferring the needle ahead for higher
compatibility. Maybe in one other decade as we glance again right now we’ll giggle in regards to the issues we had been encountering now, whereas having fun with some high quality
x86 video games that can by no means see a port to ARM {hardware}. Keeping the legacy of the PC gaming ecosystem alive, no matter the place we’d find yourself enjoying
it.